Apache-2.0 MoE preview with 770B total parameters, 49B active and a million-token context. Sparse attention and multi-token prediction support long-input workloads.
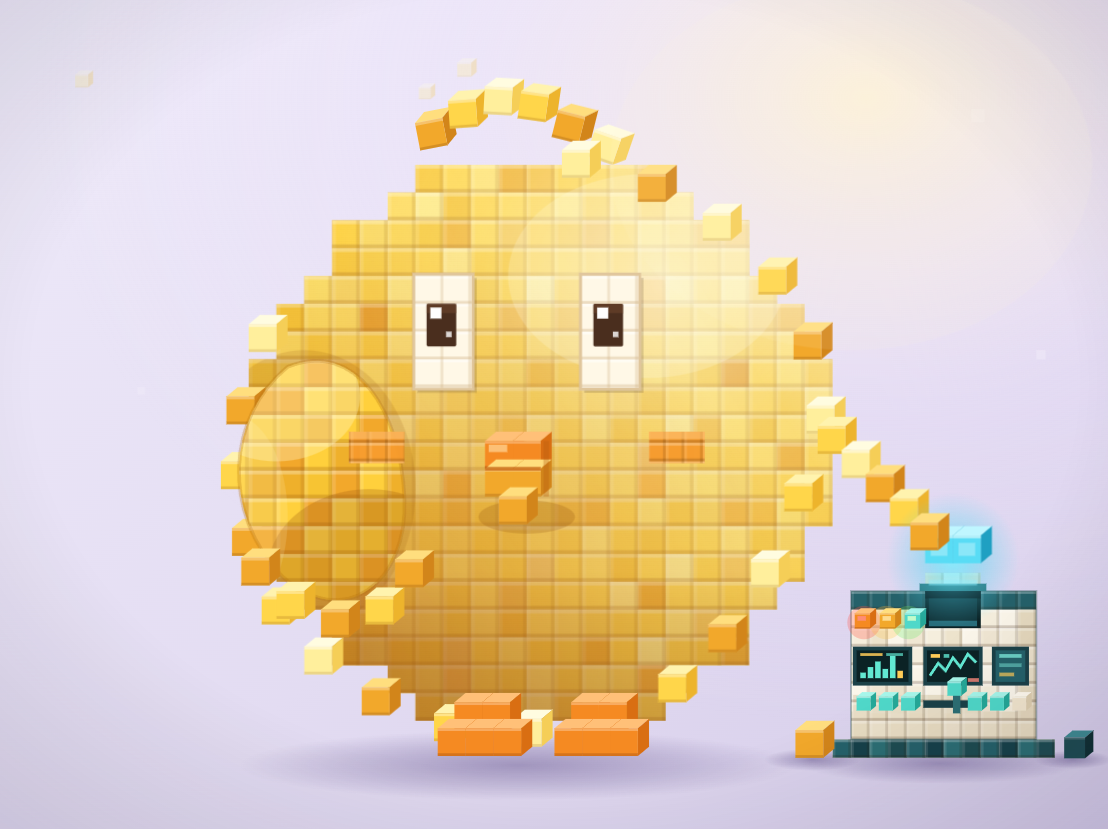
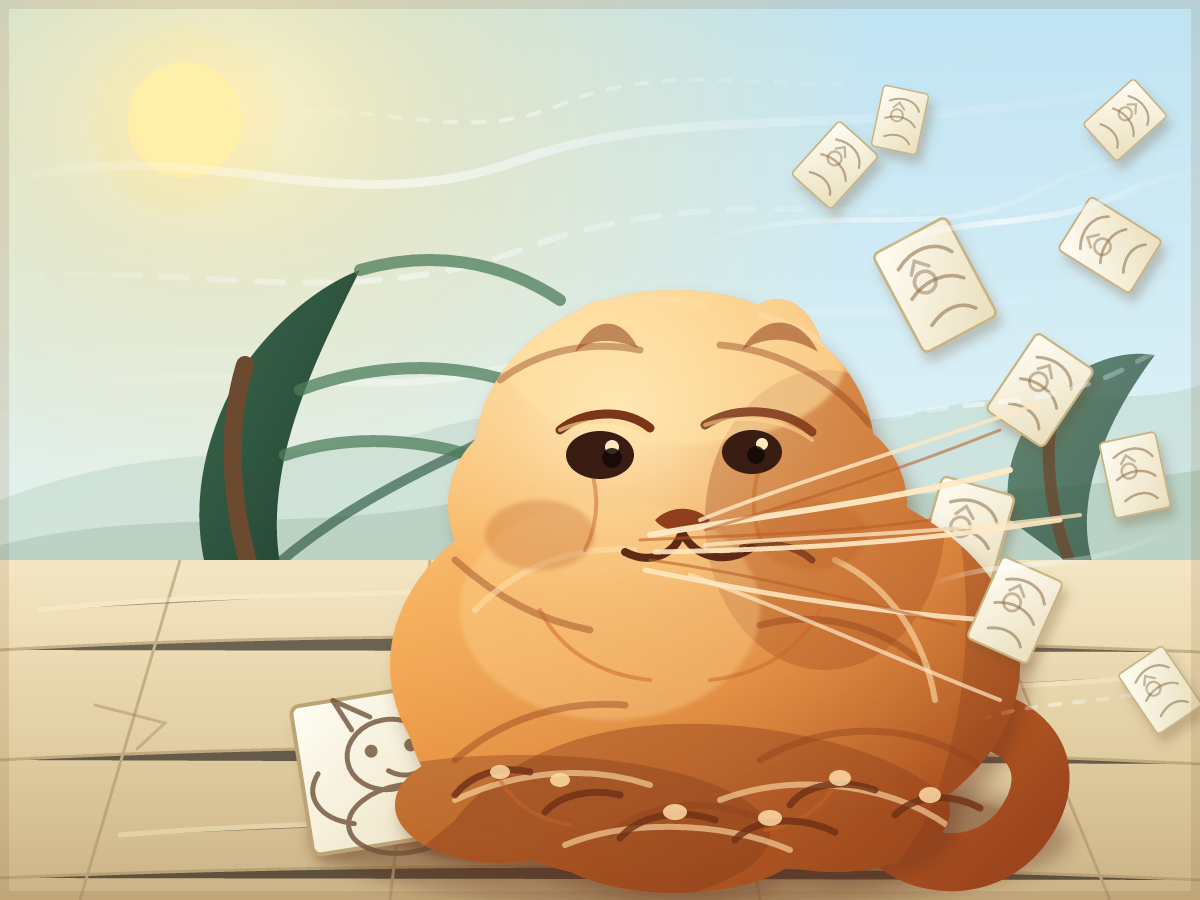
Draw a huge round yellow canary made of little cubes. It holds a blue block above a tiny control panel, looking curious about the machine. Give the scene a soft, playful 3D look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
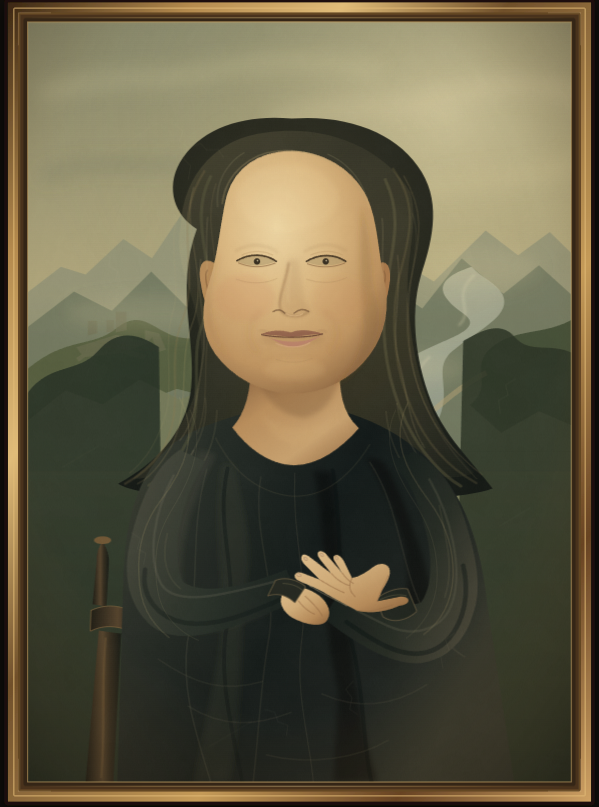
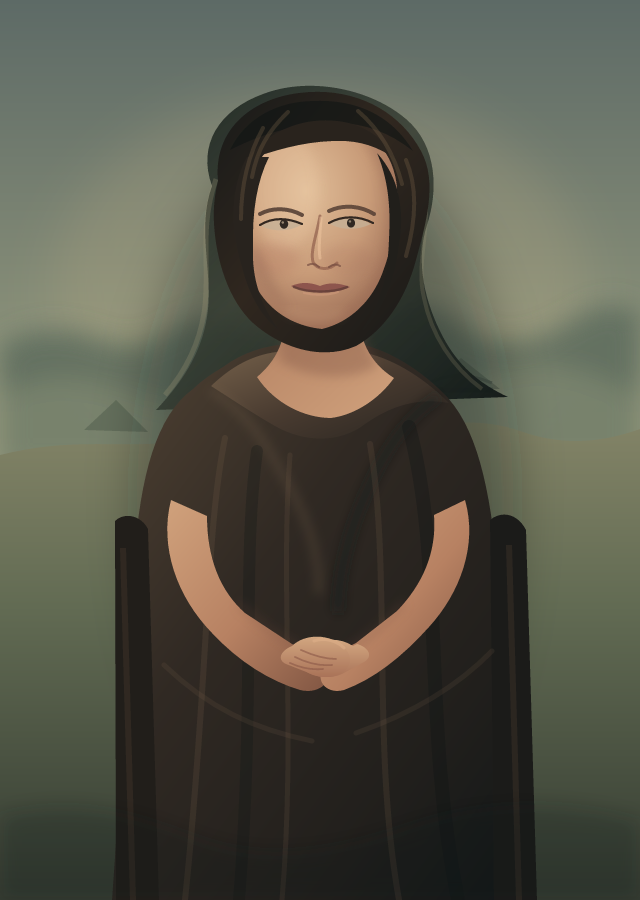
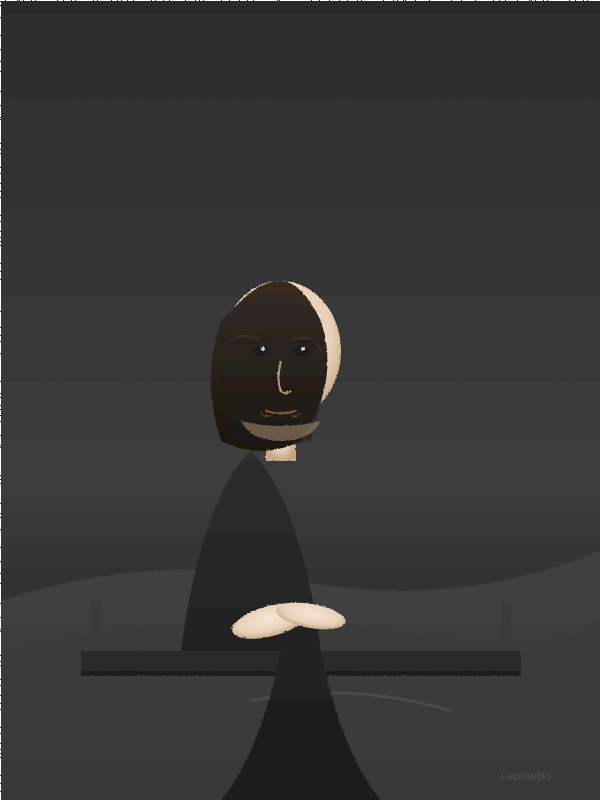
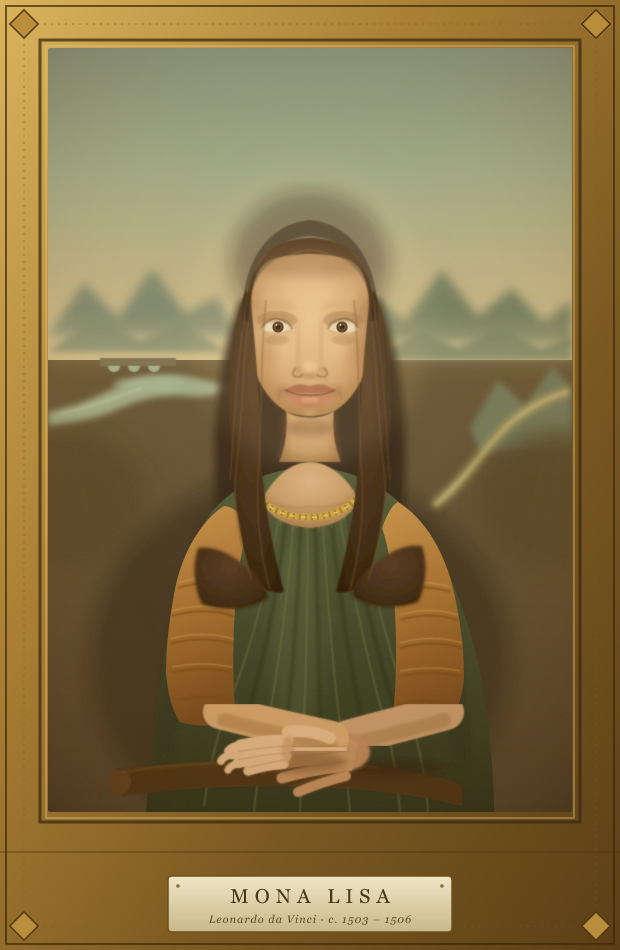
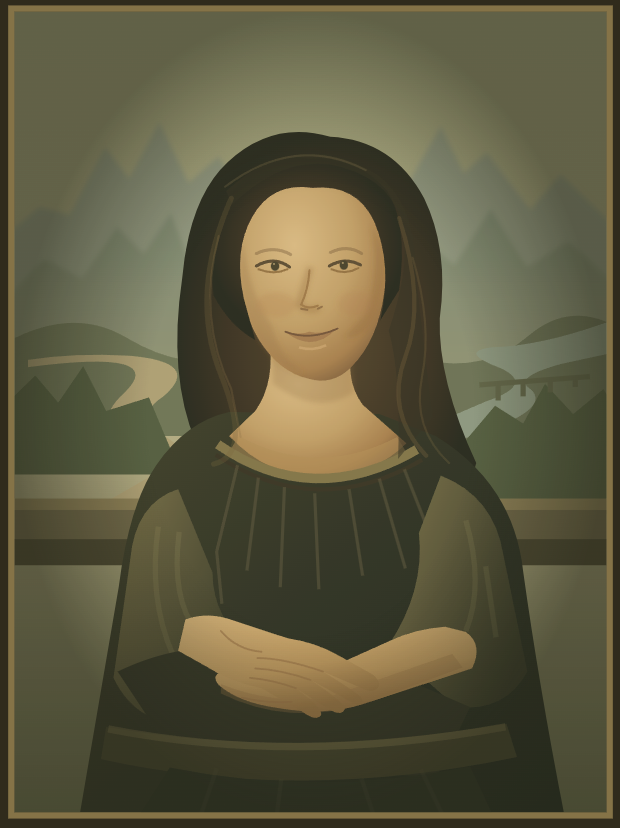
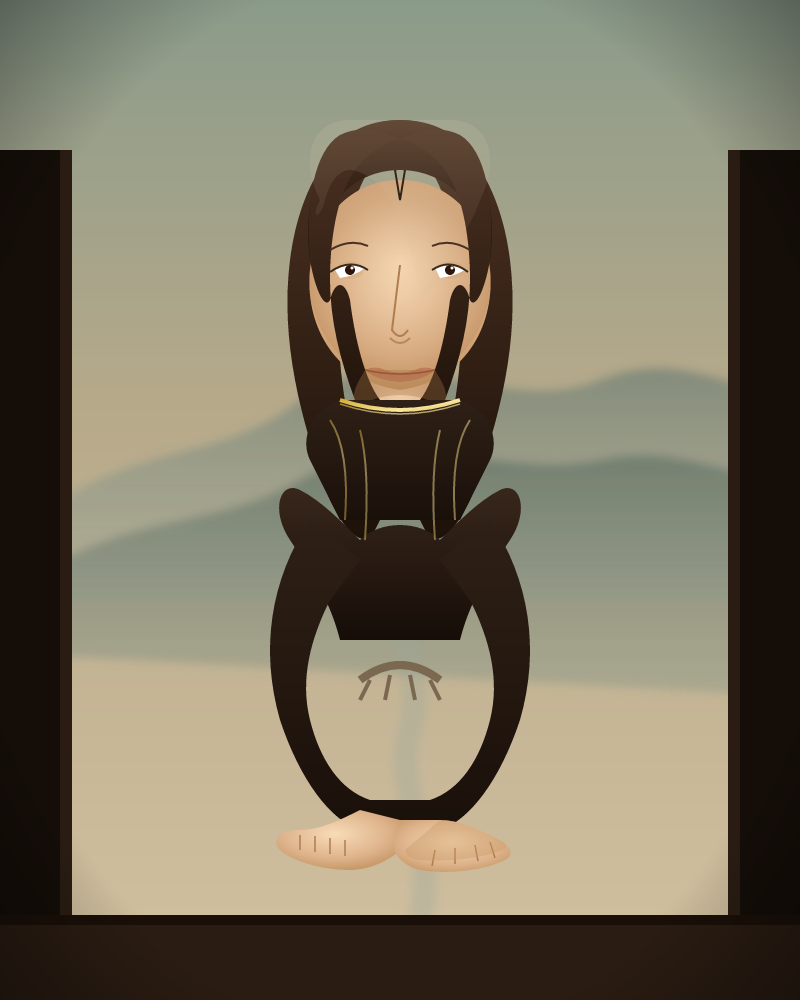
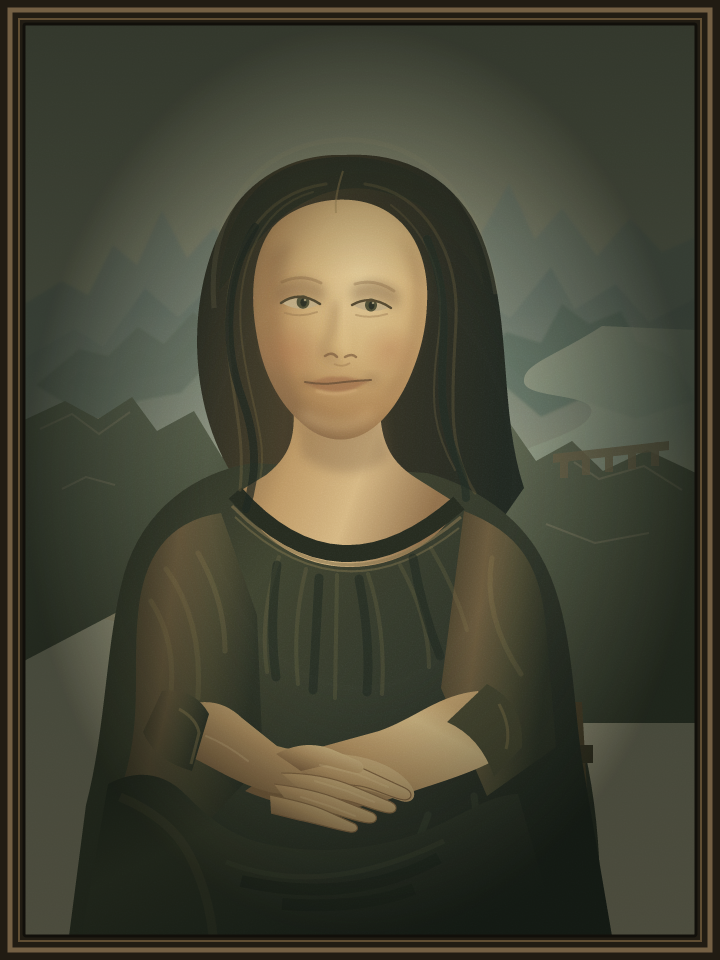
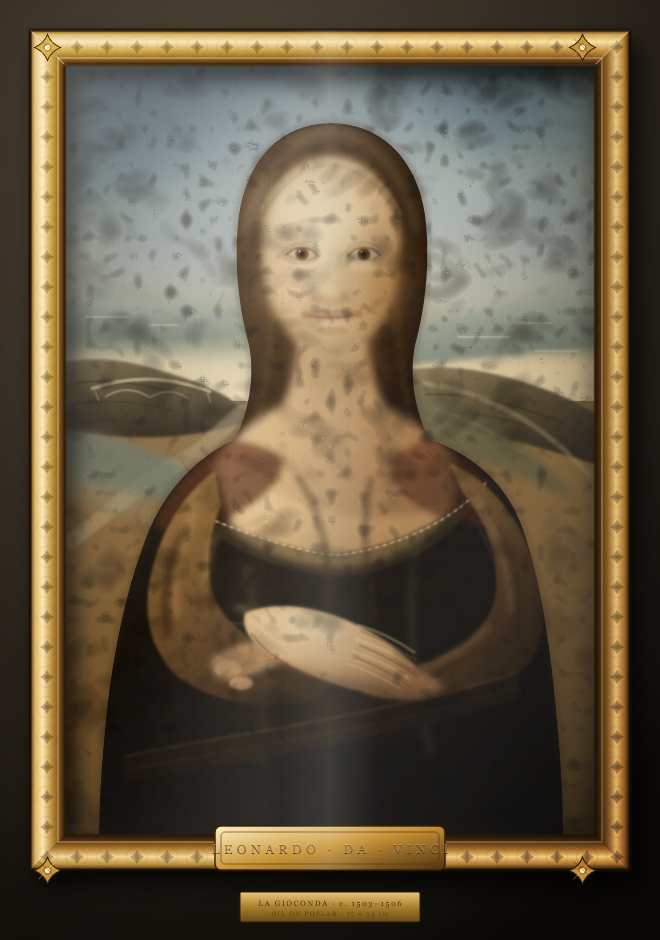
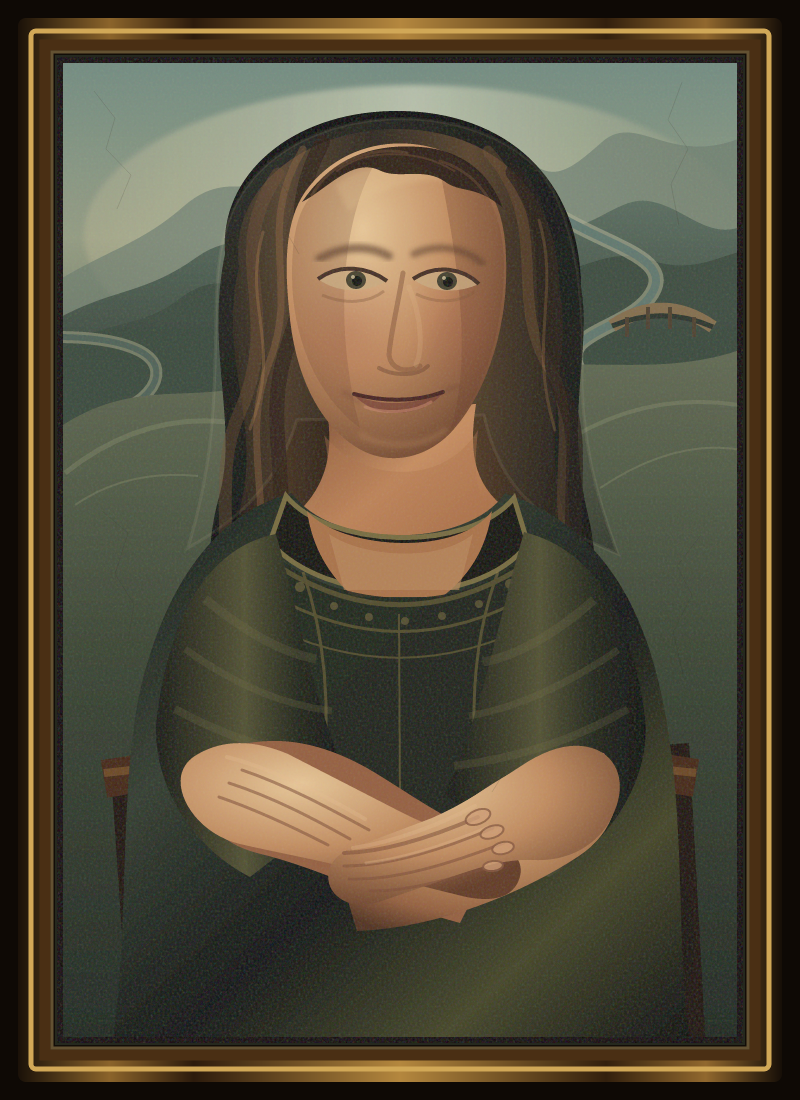
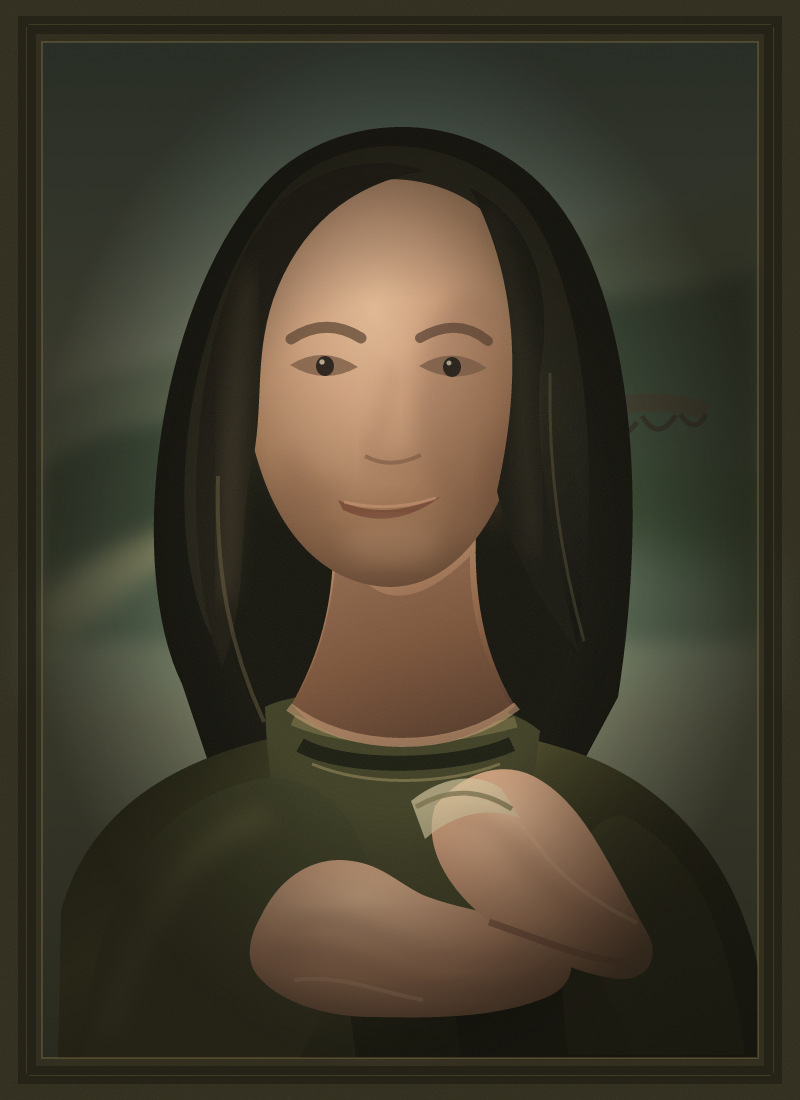
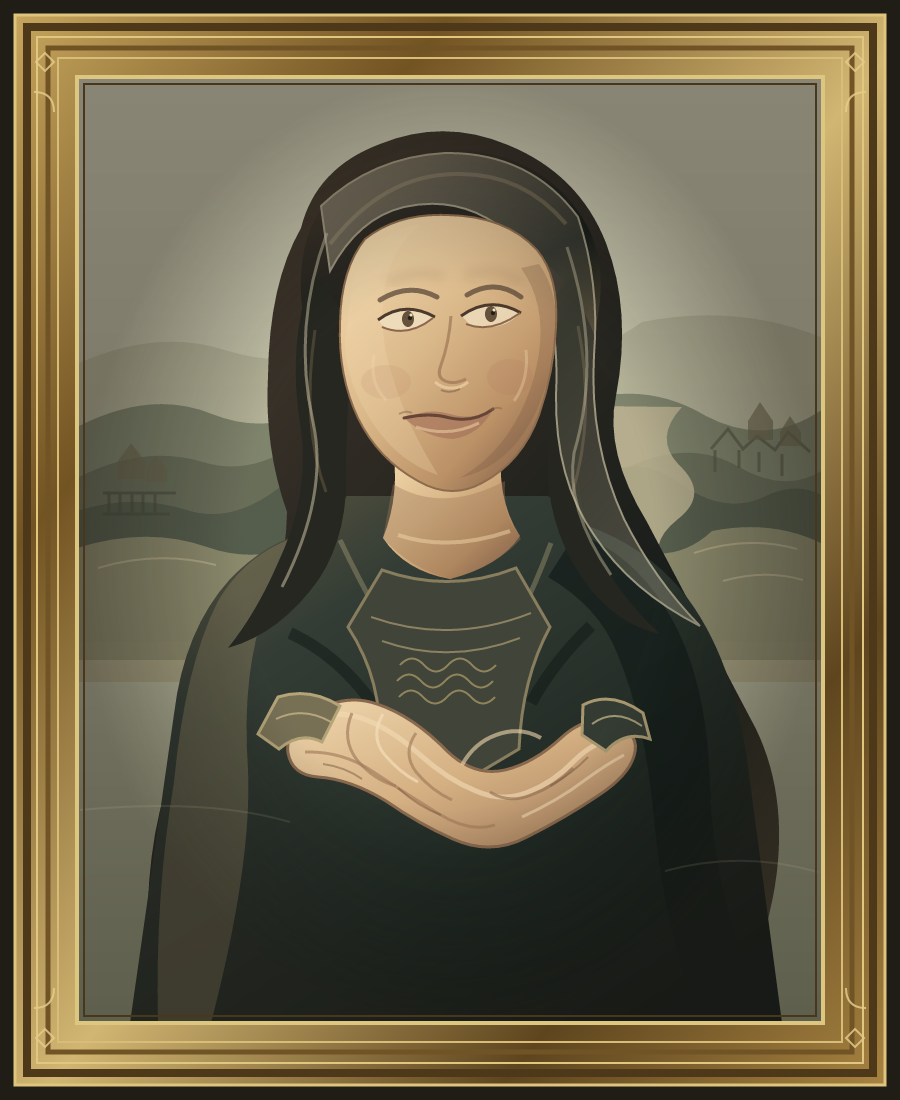
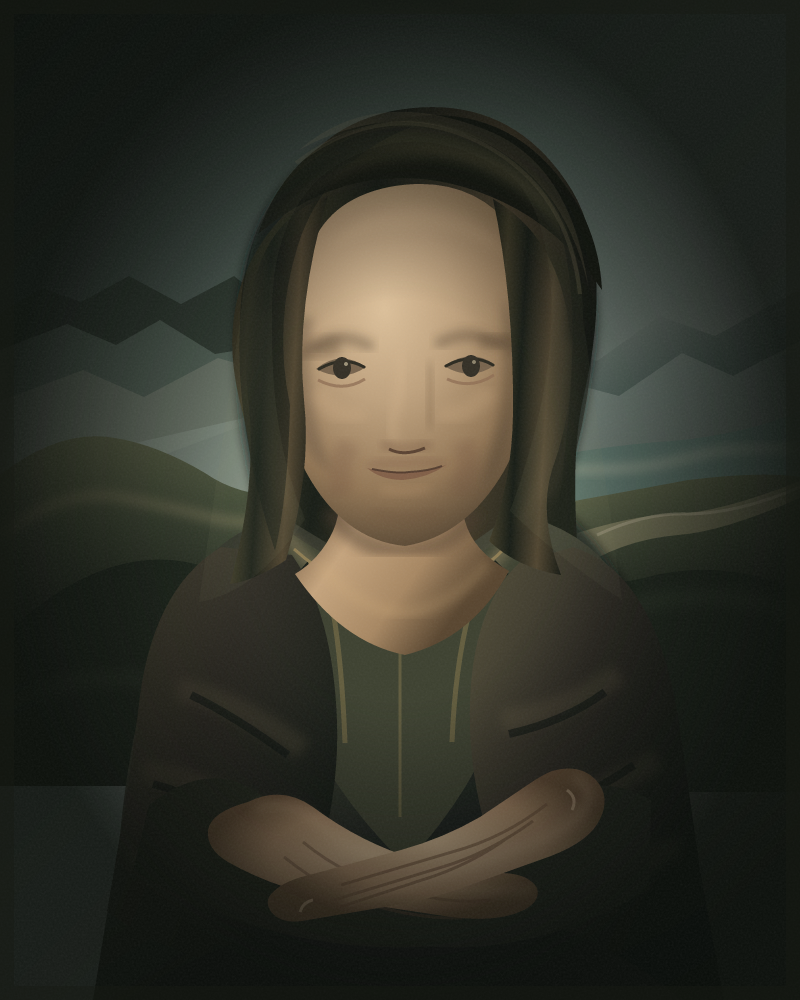
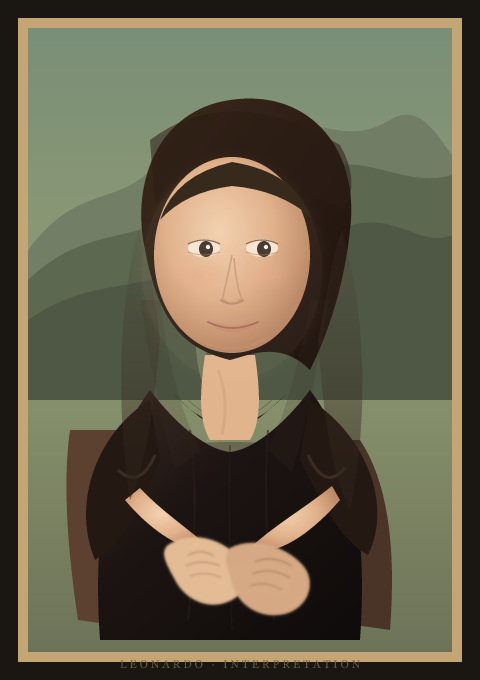
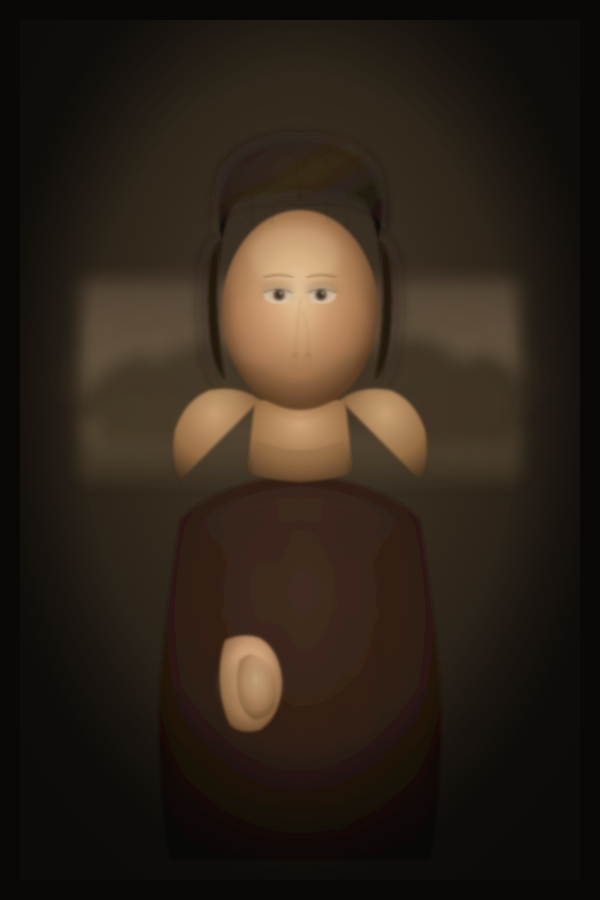
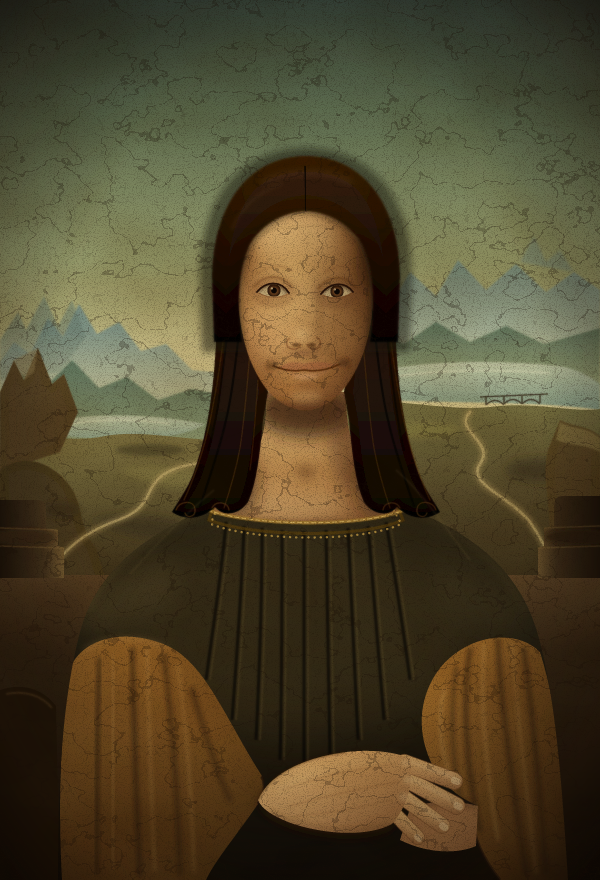
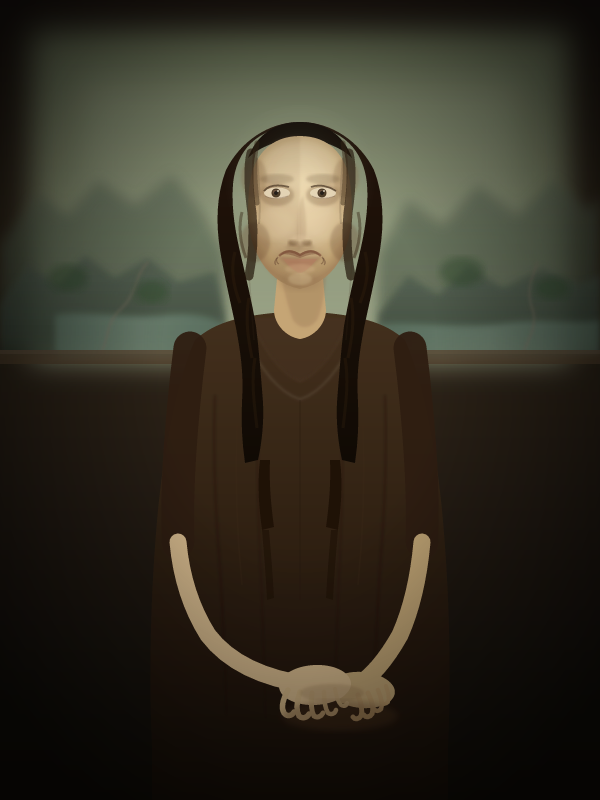
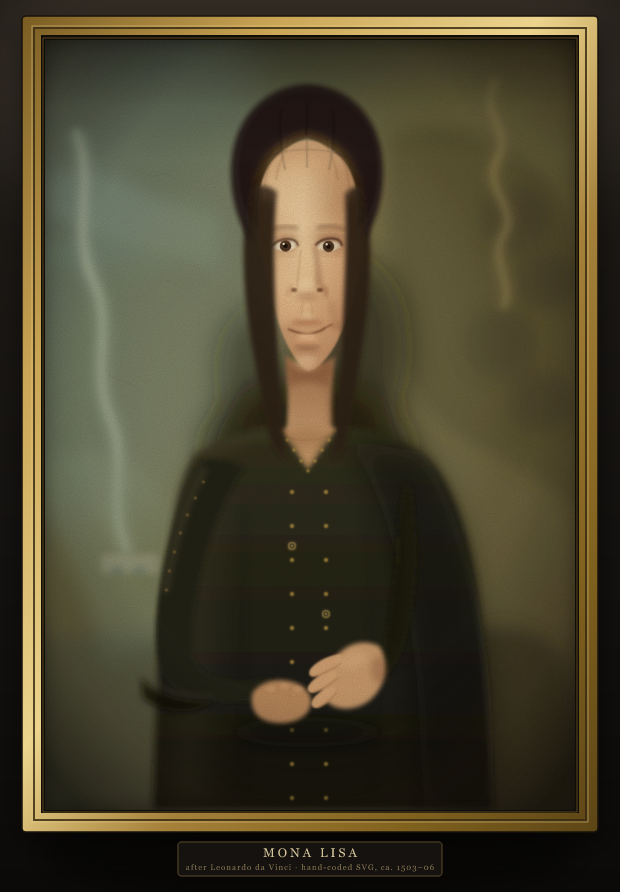
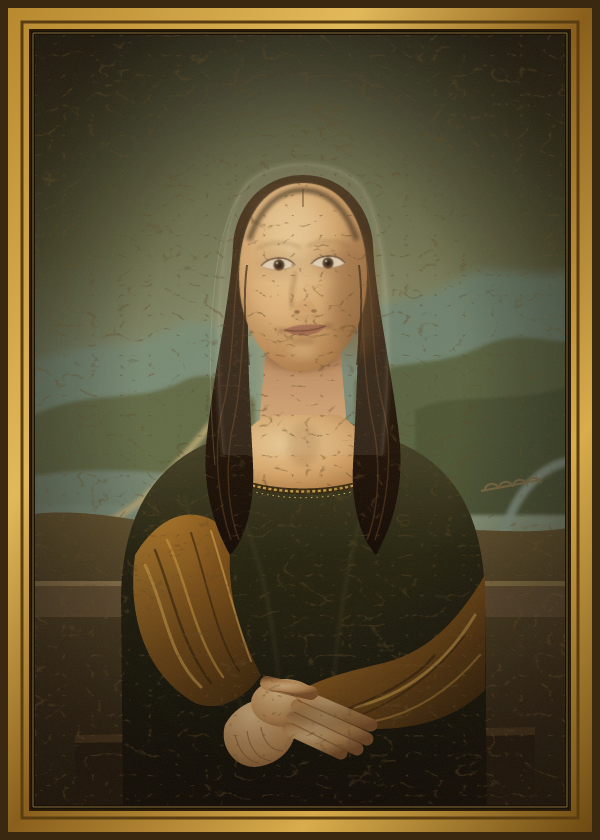
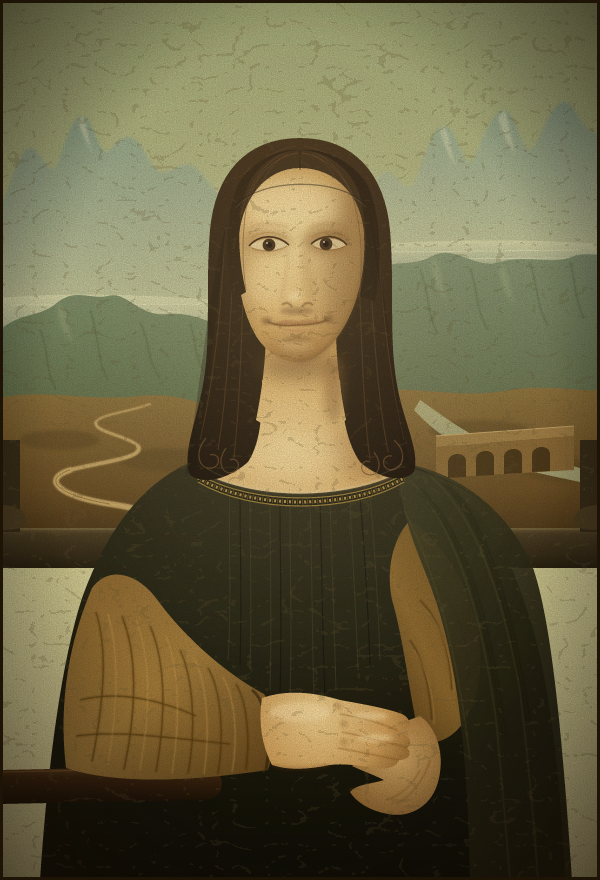
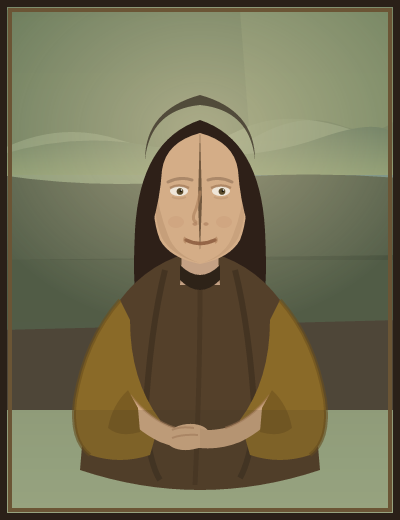
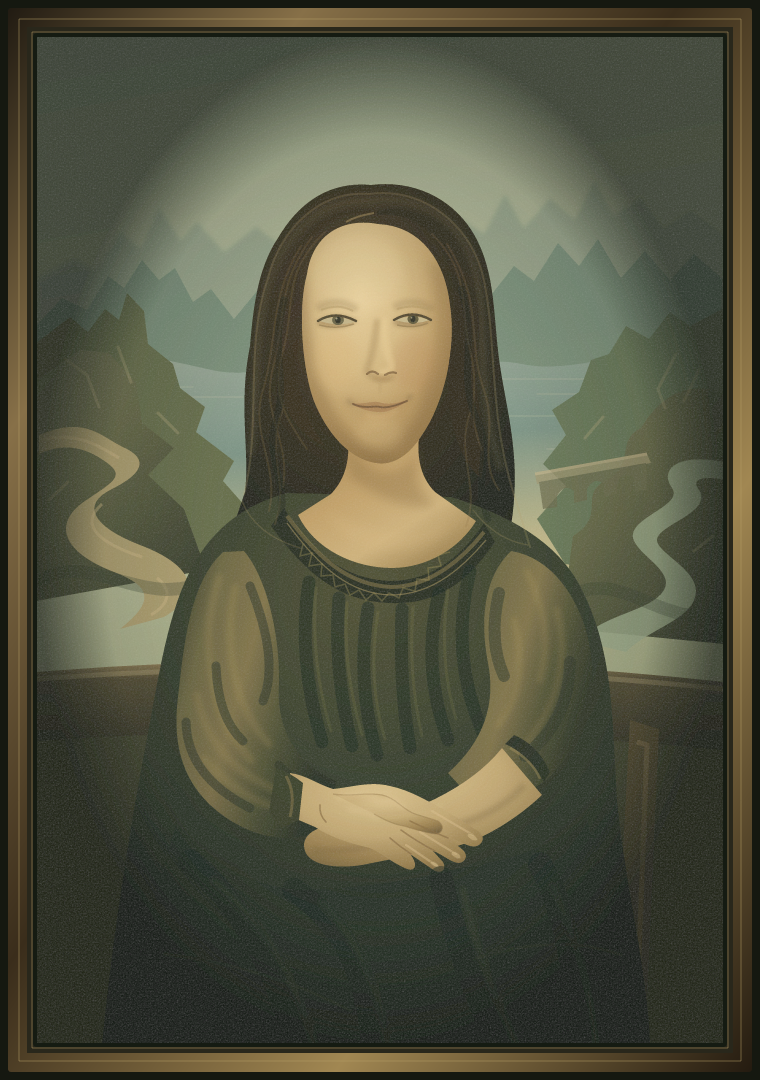
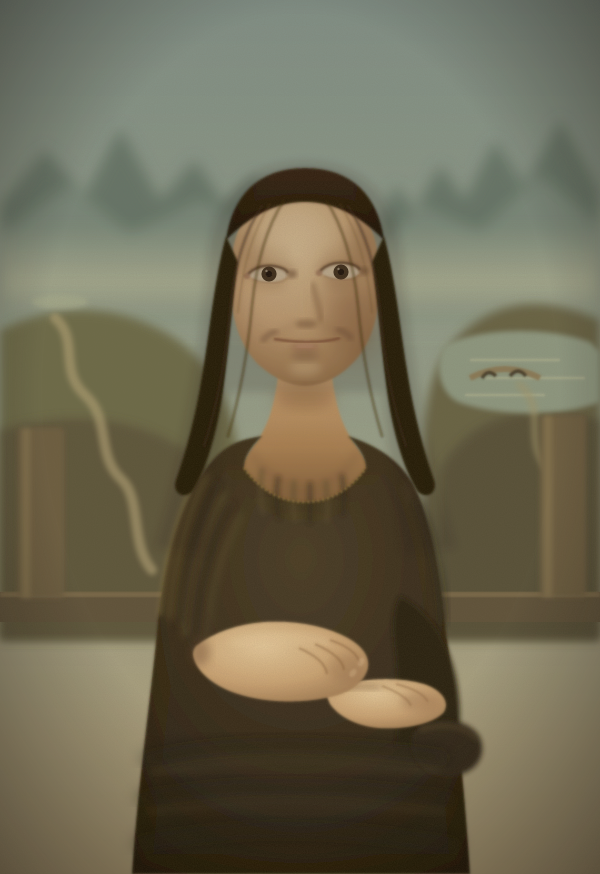
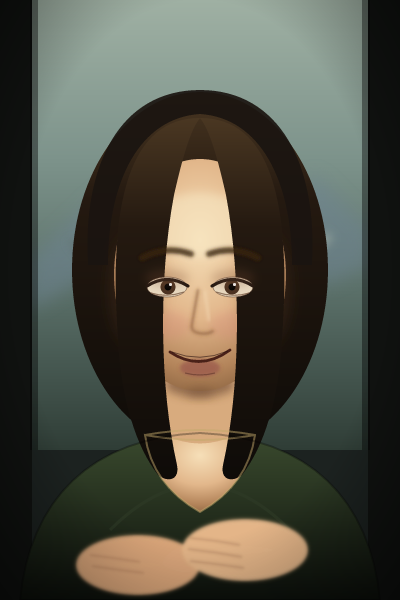
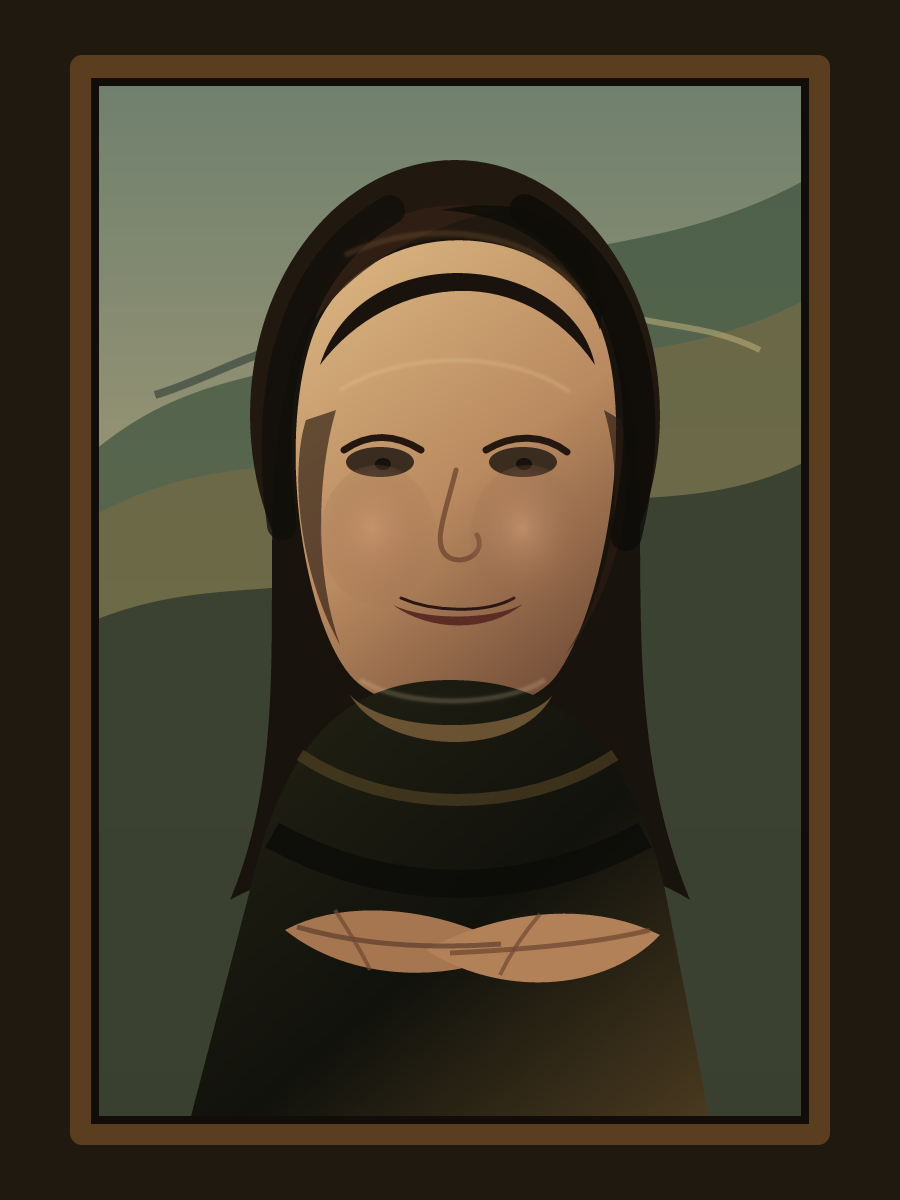
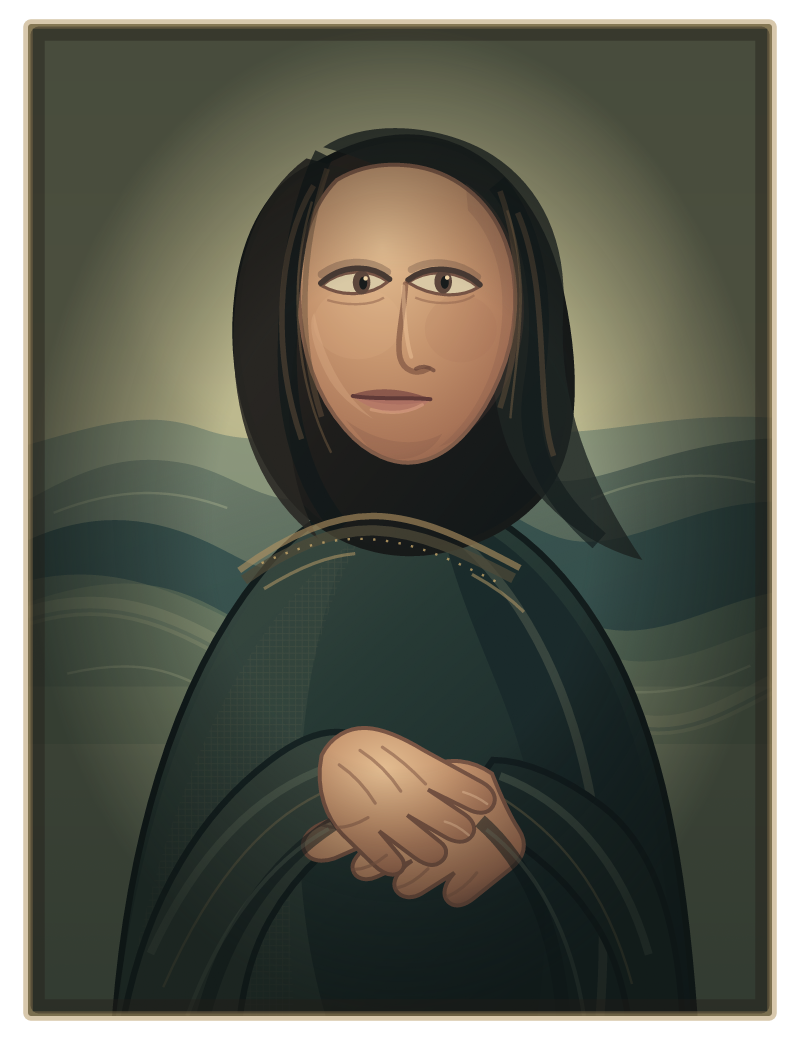
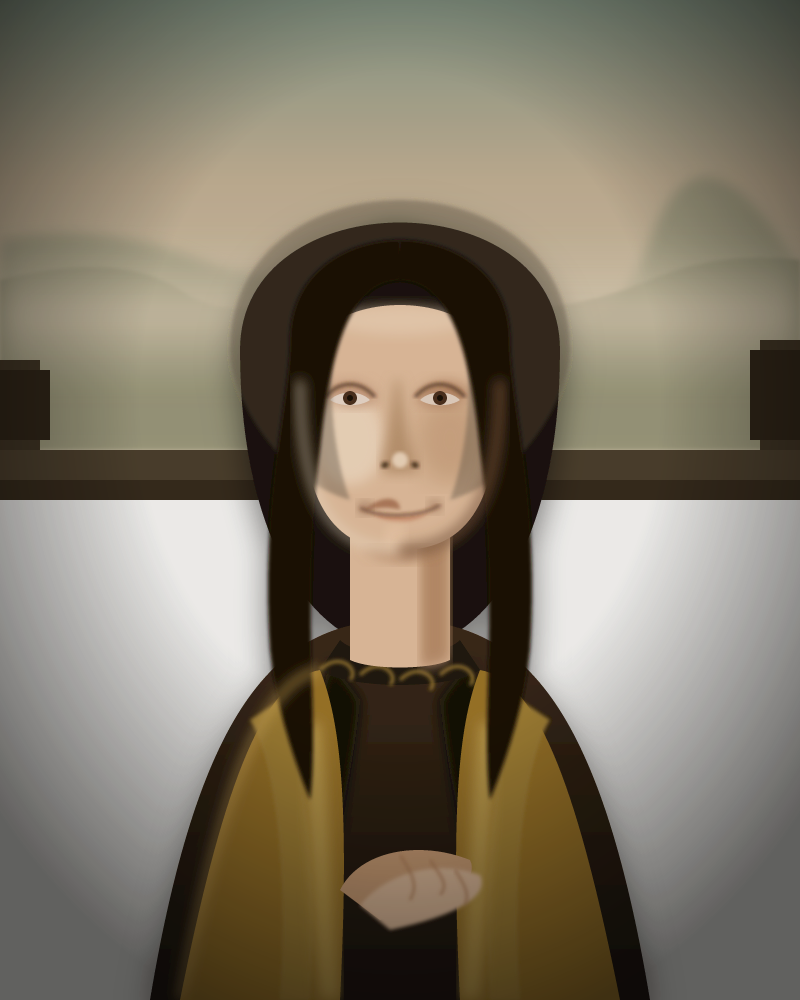
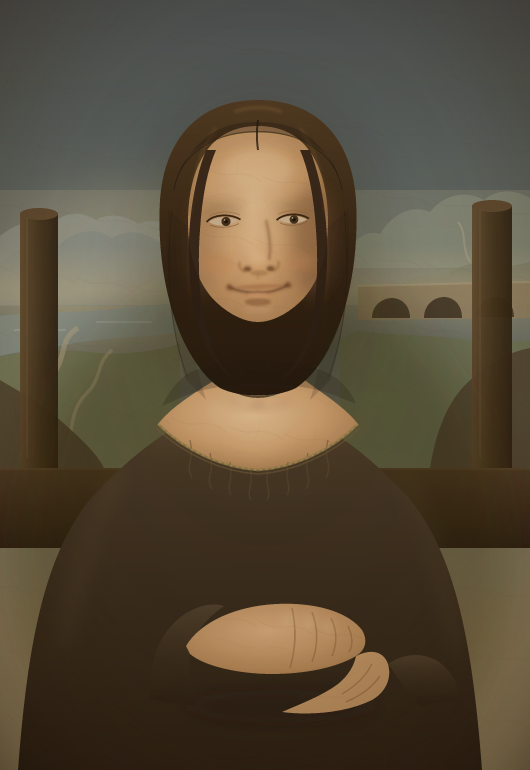
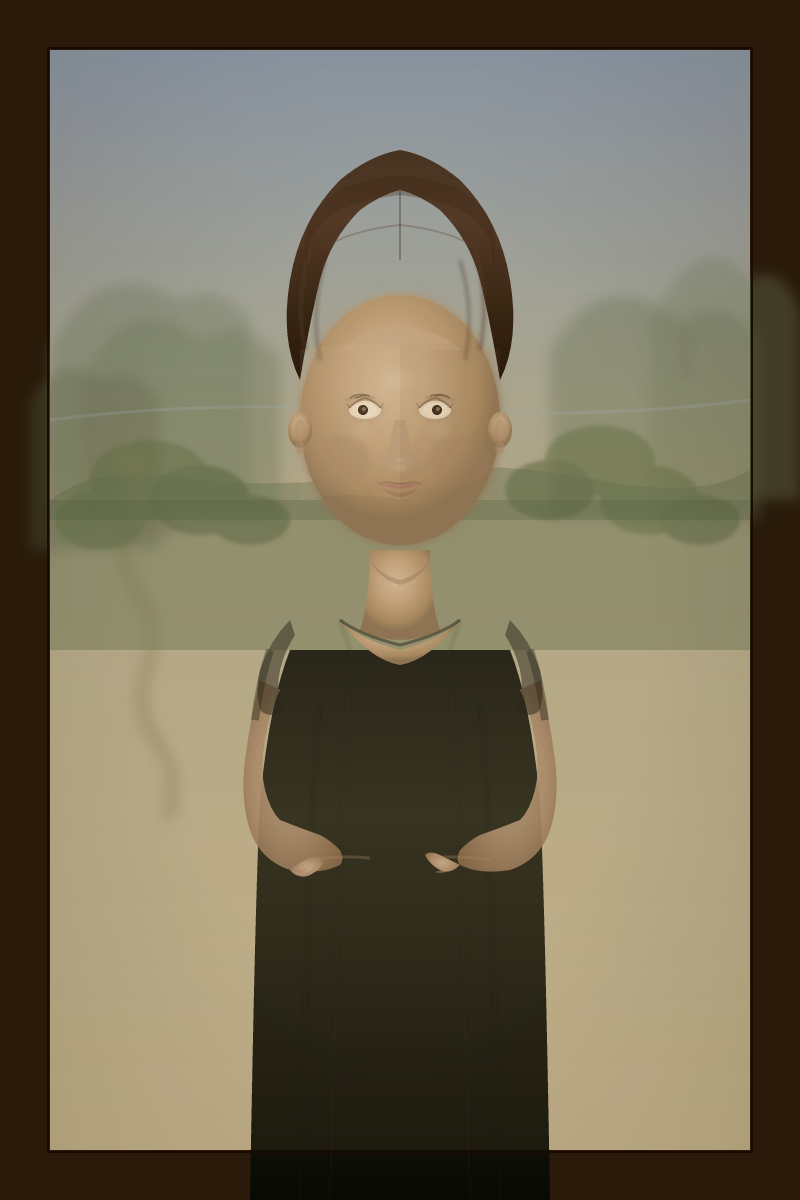
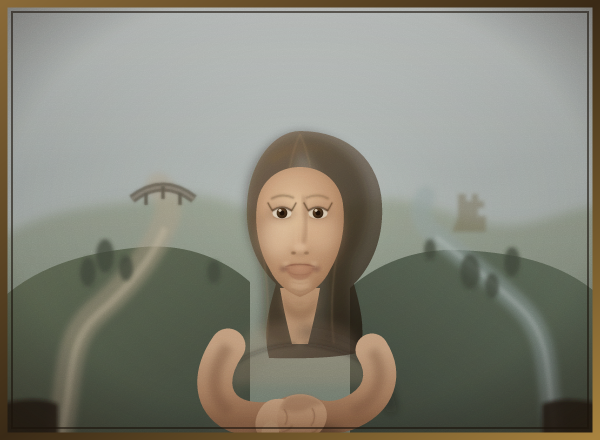
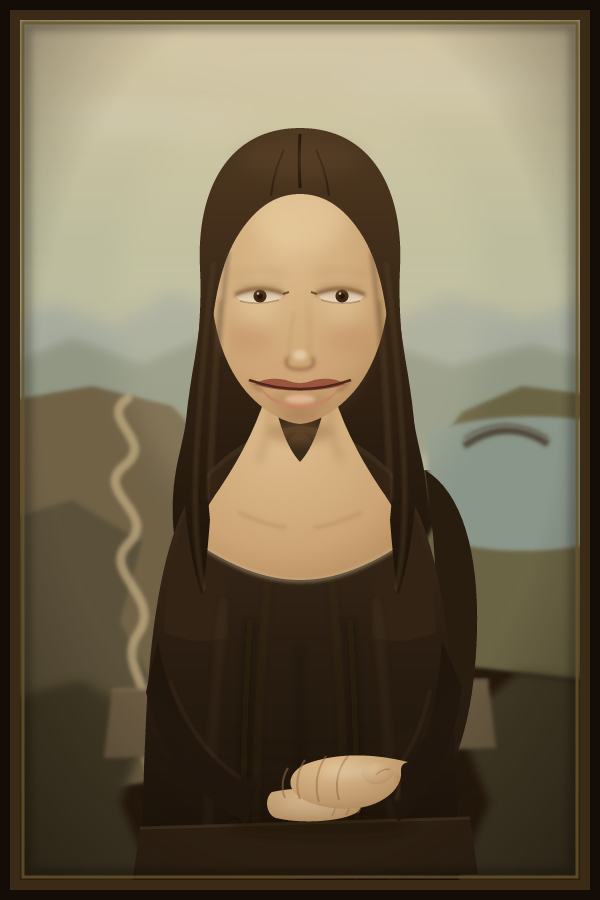
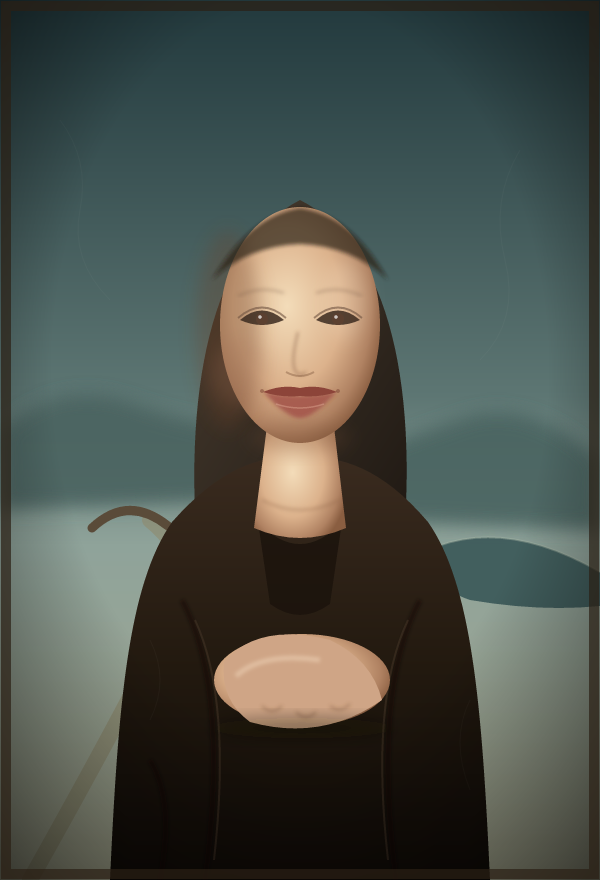
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
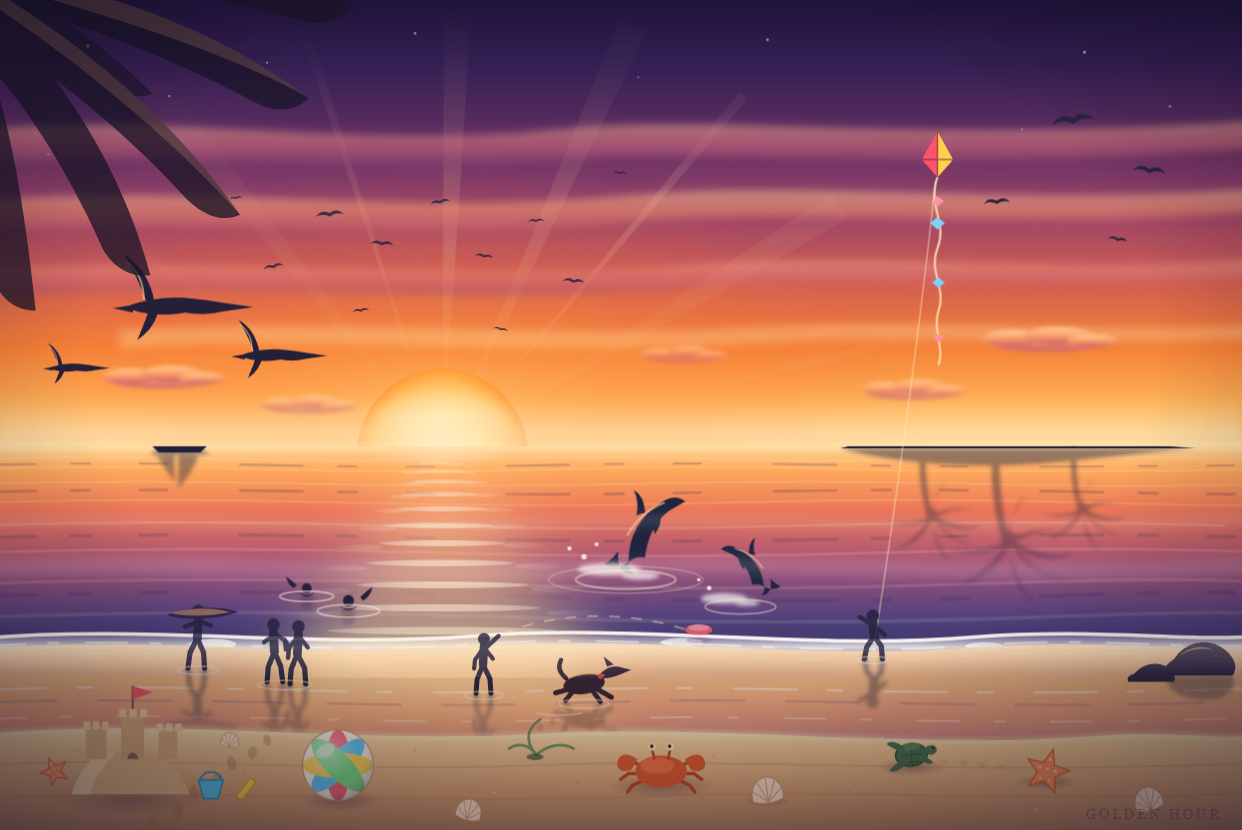
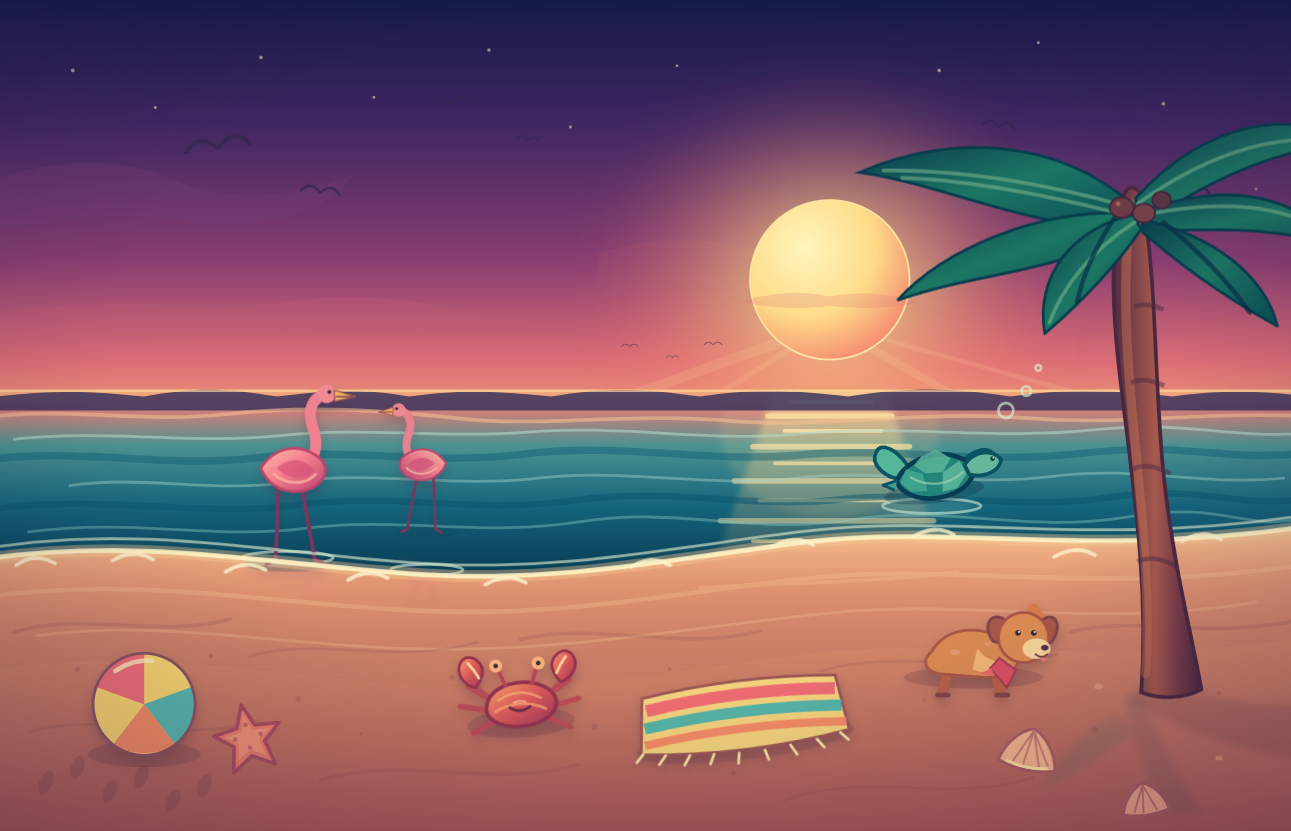
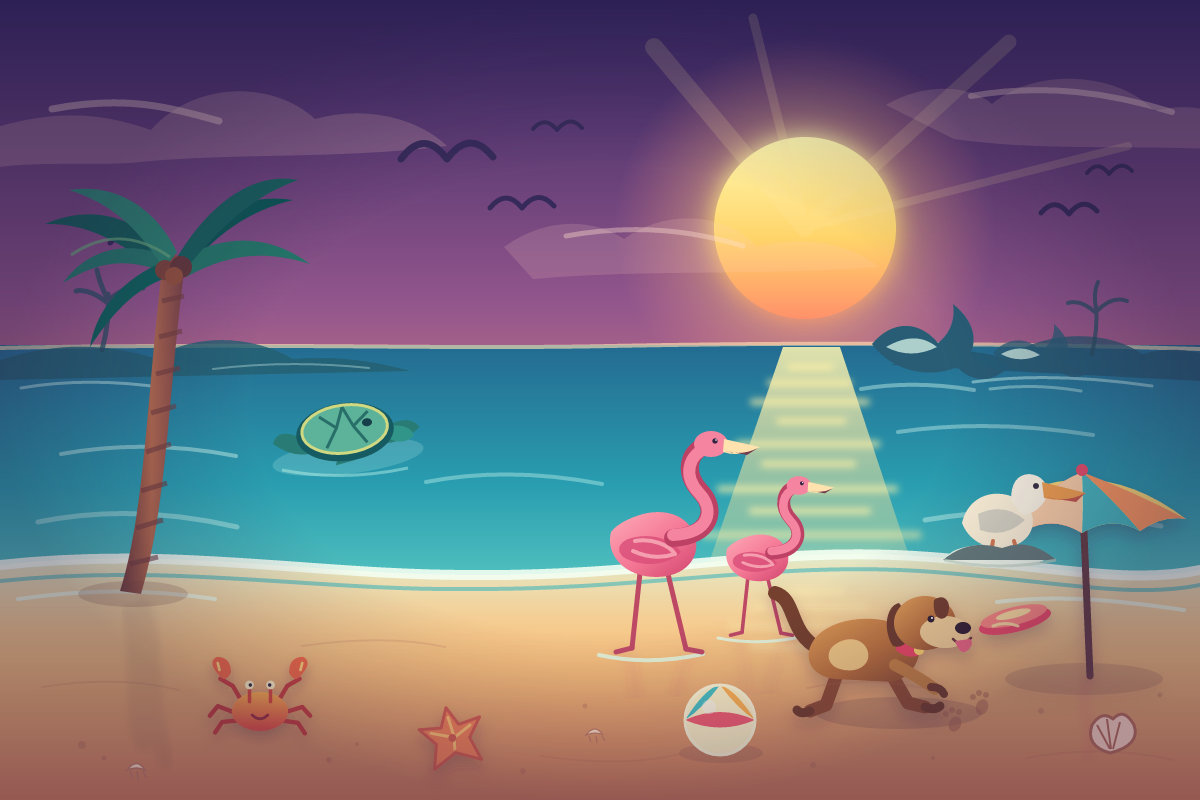
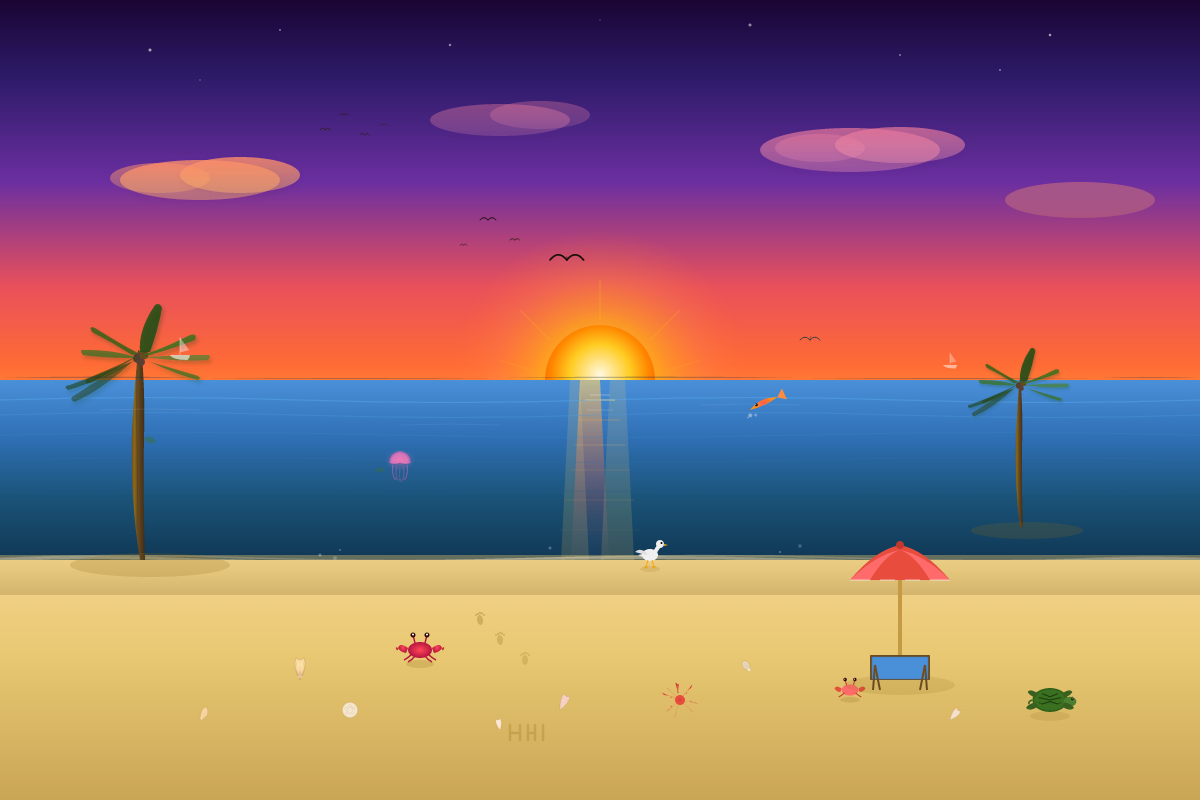
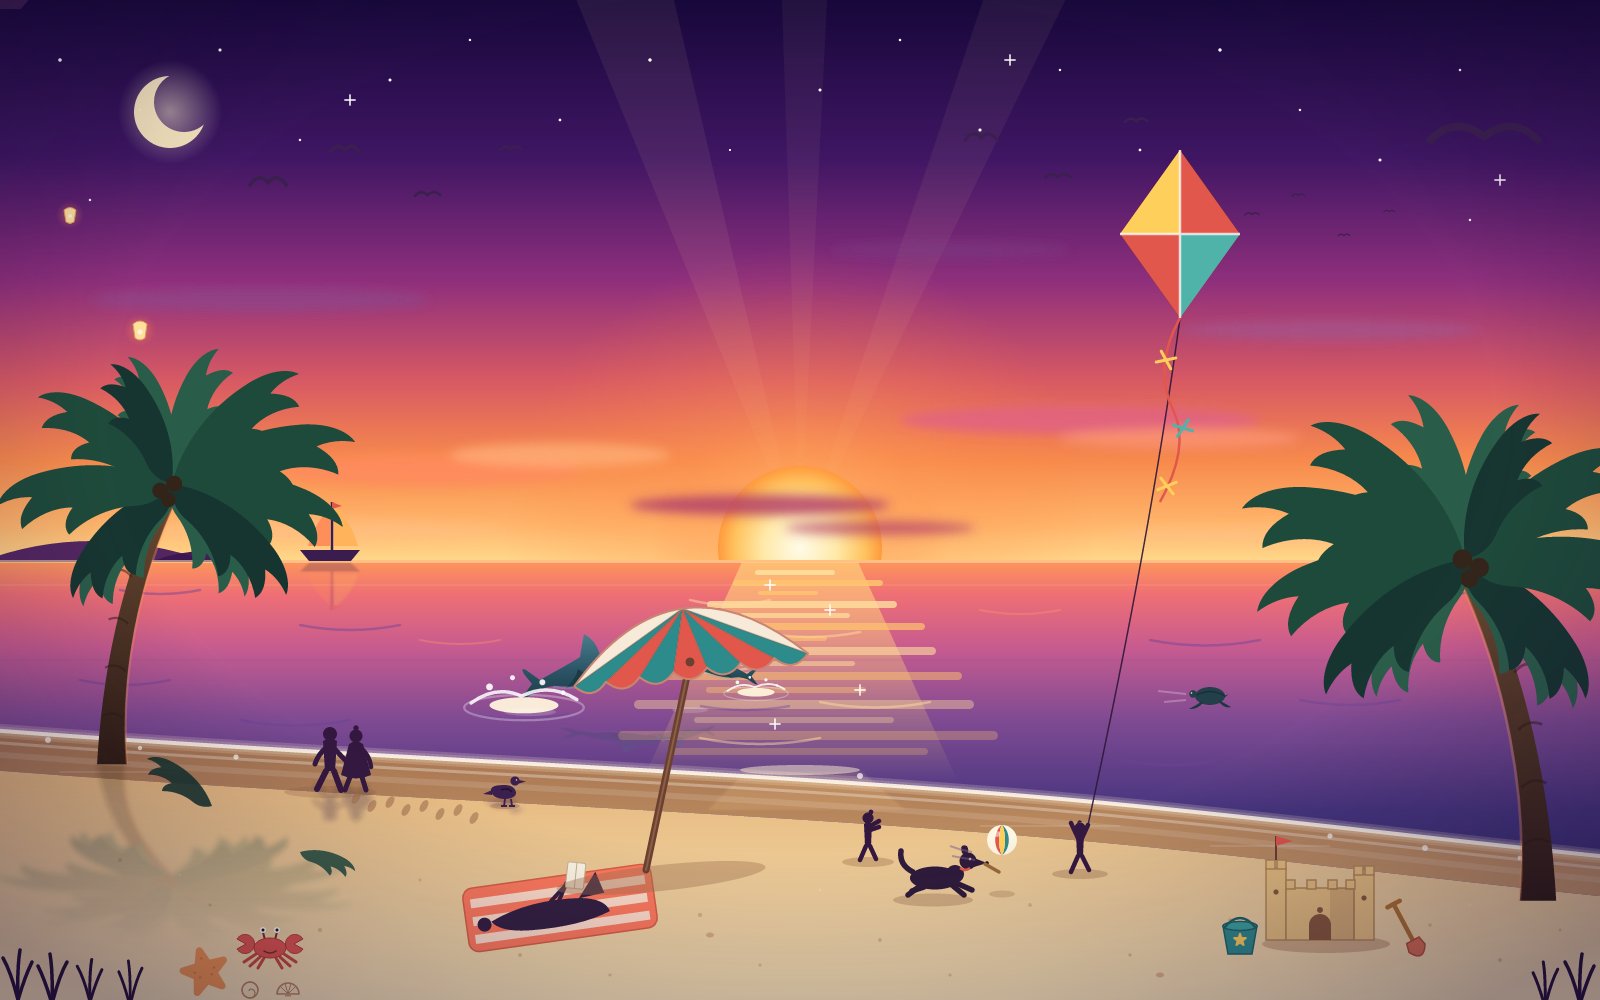
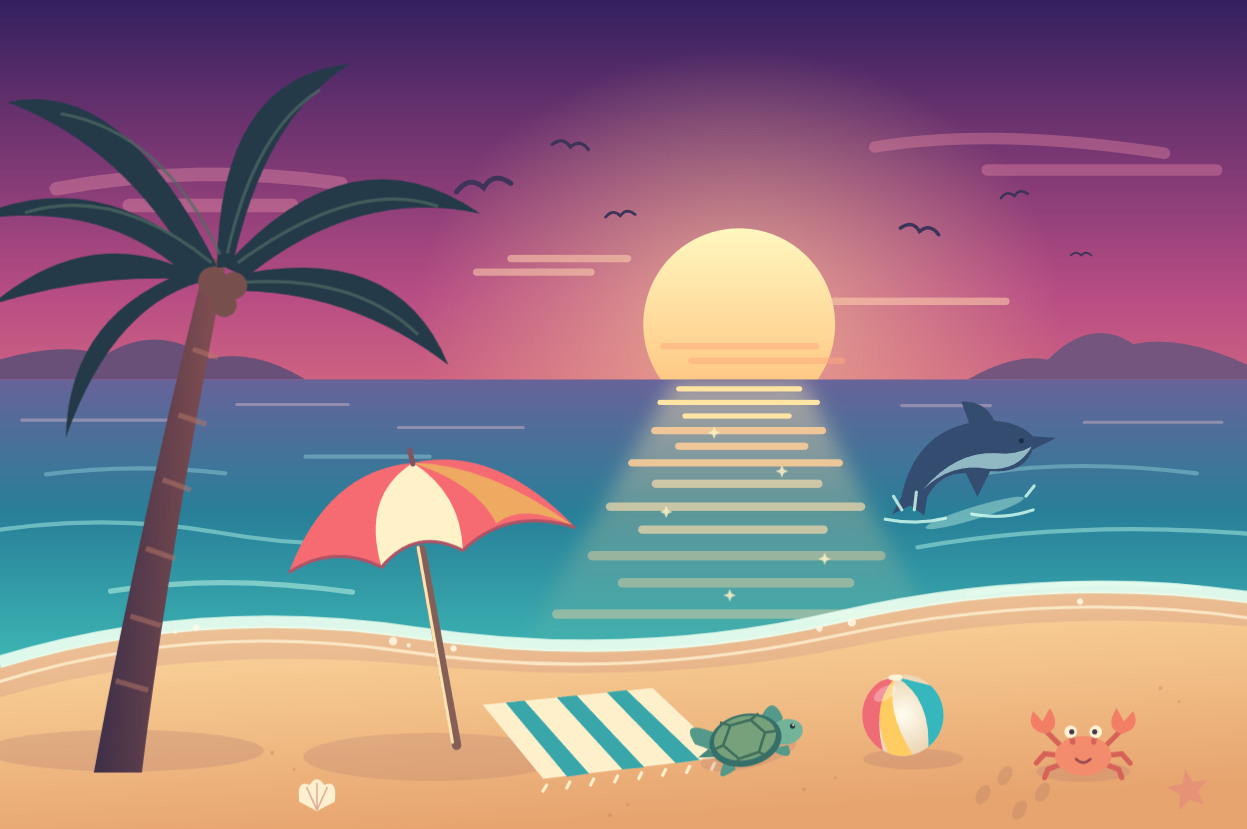
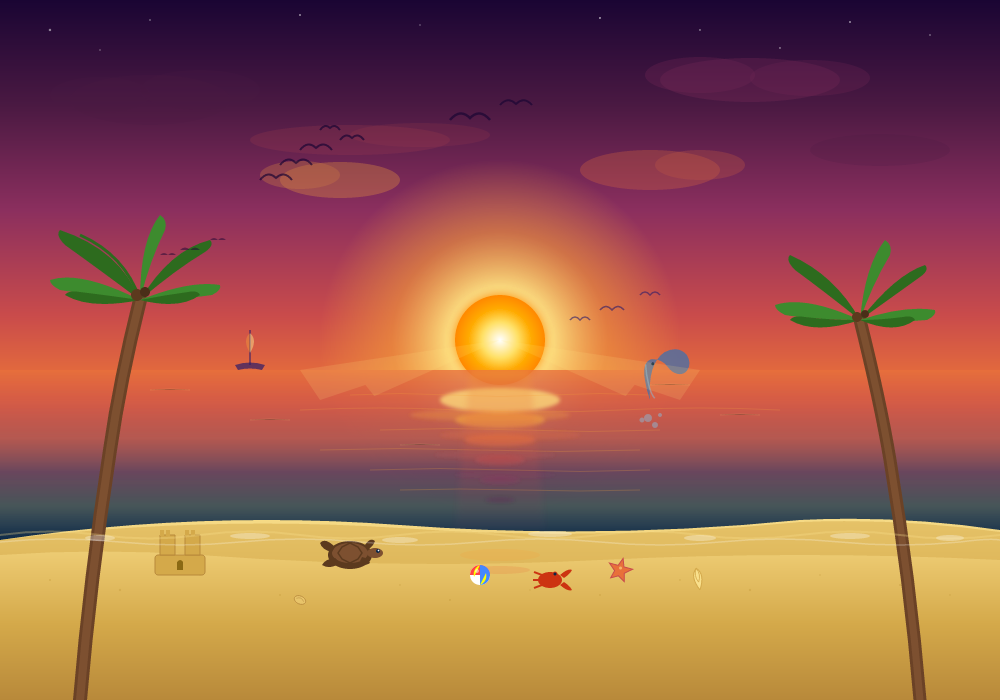
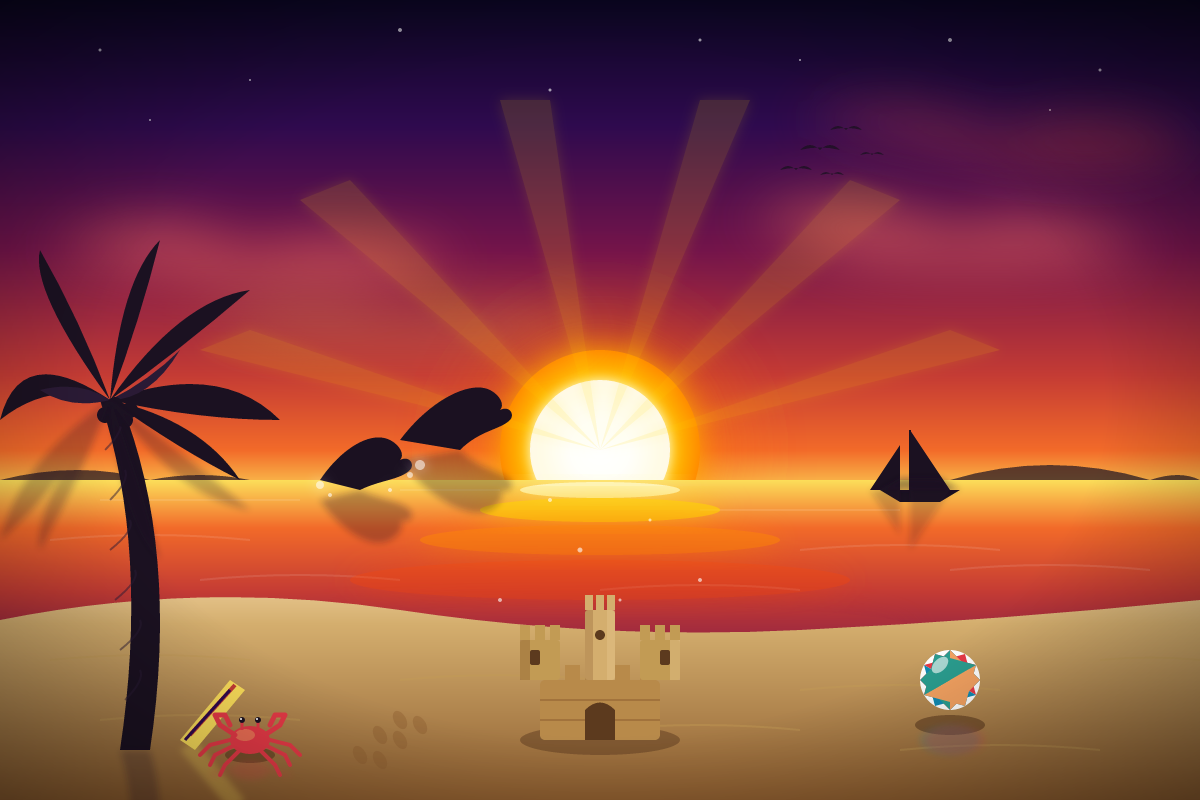
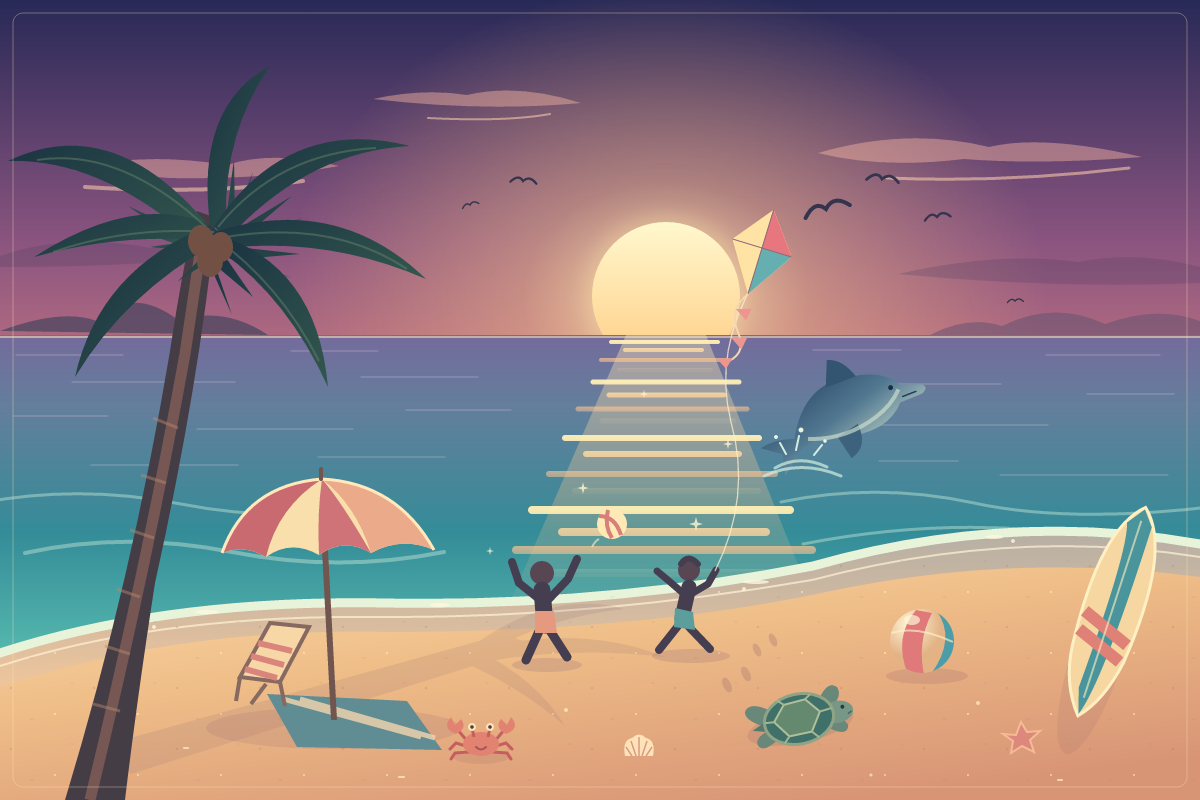
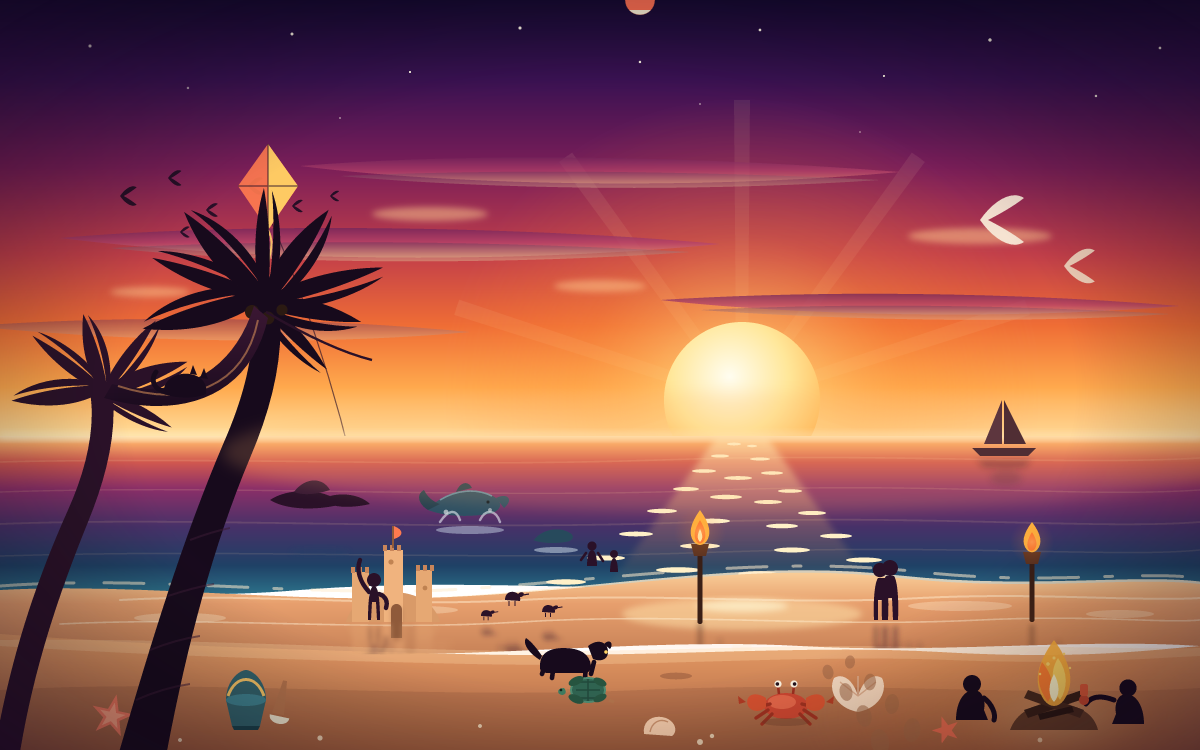
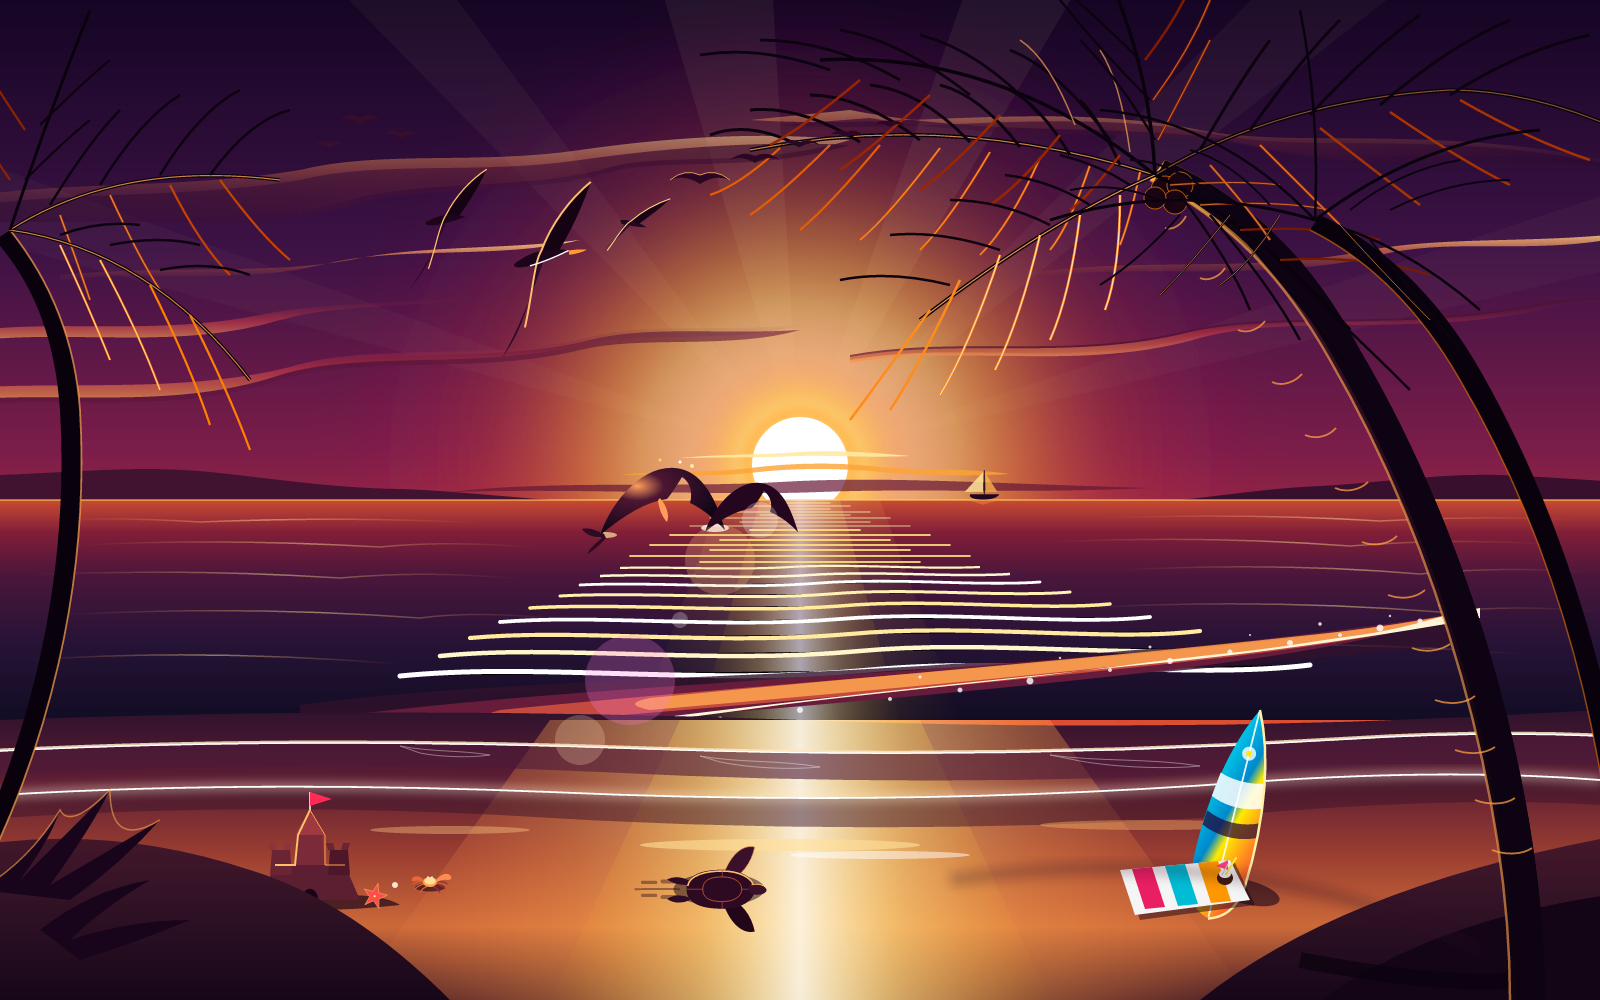
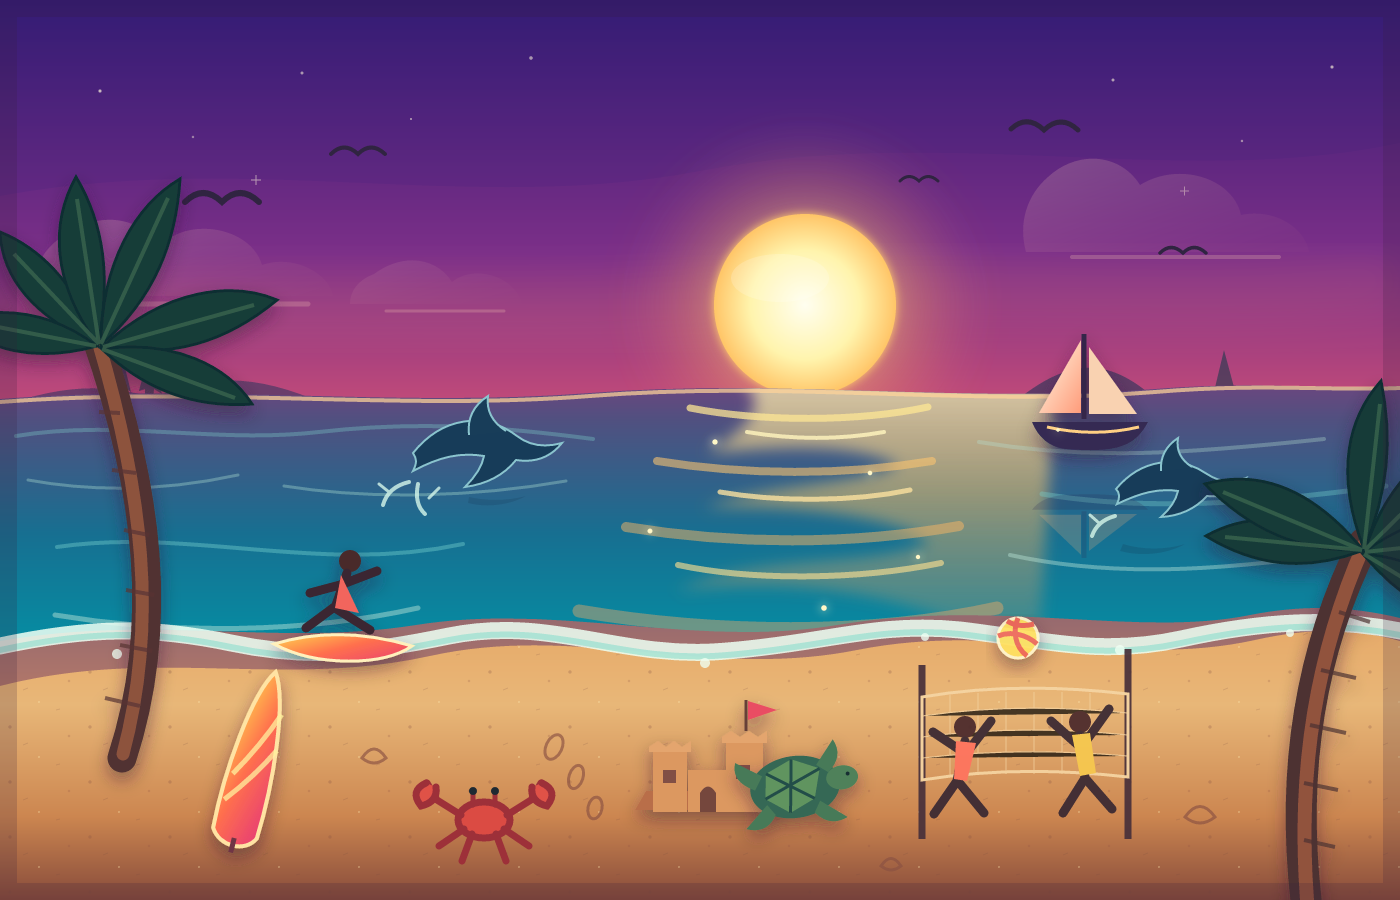
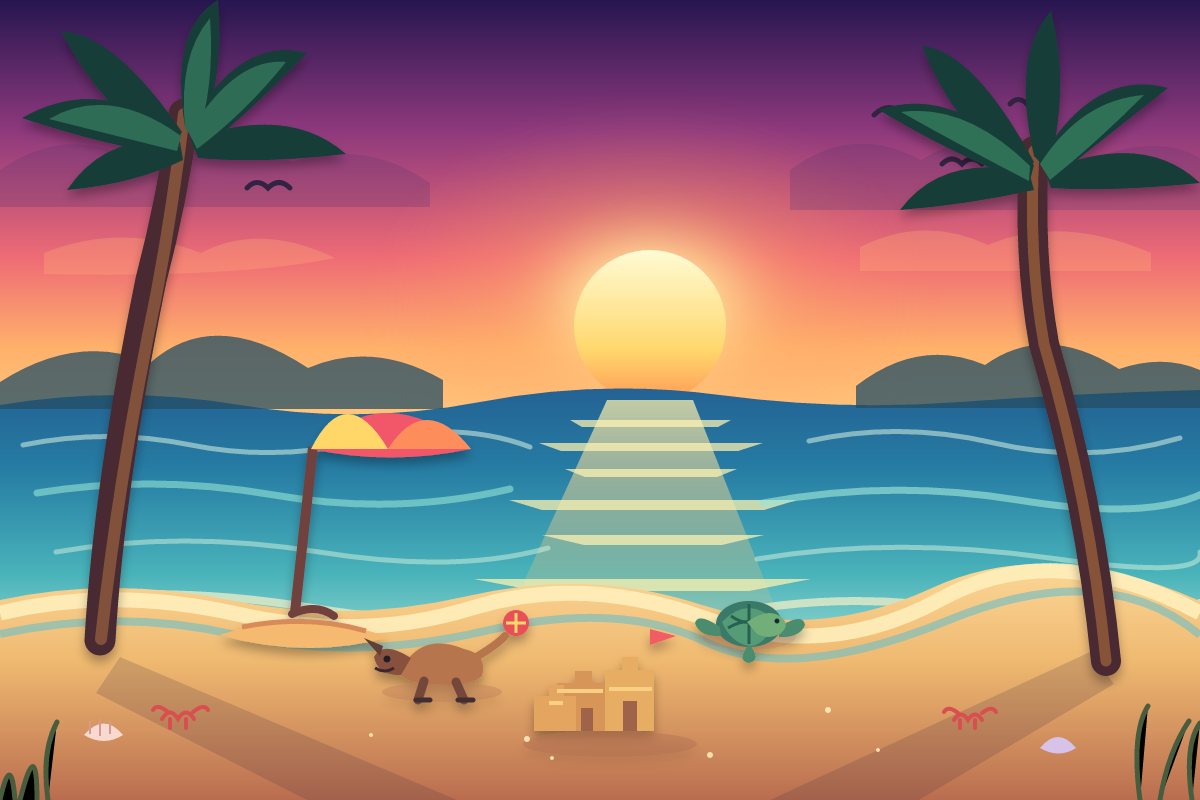
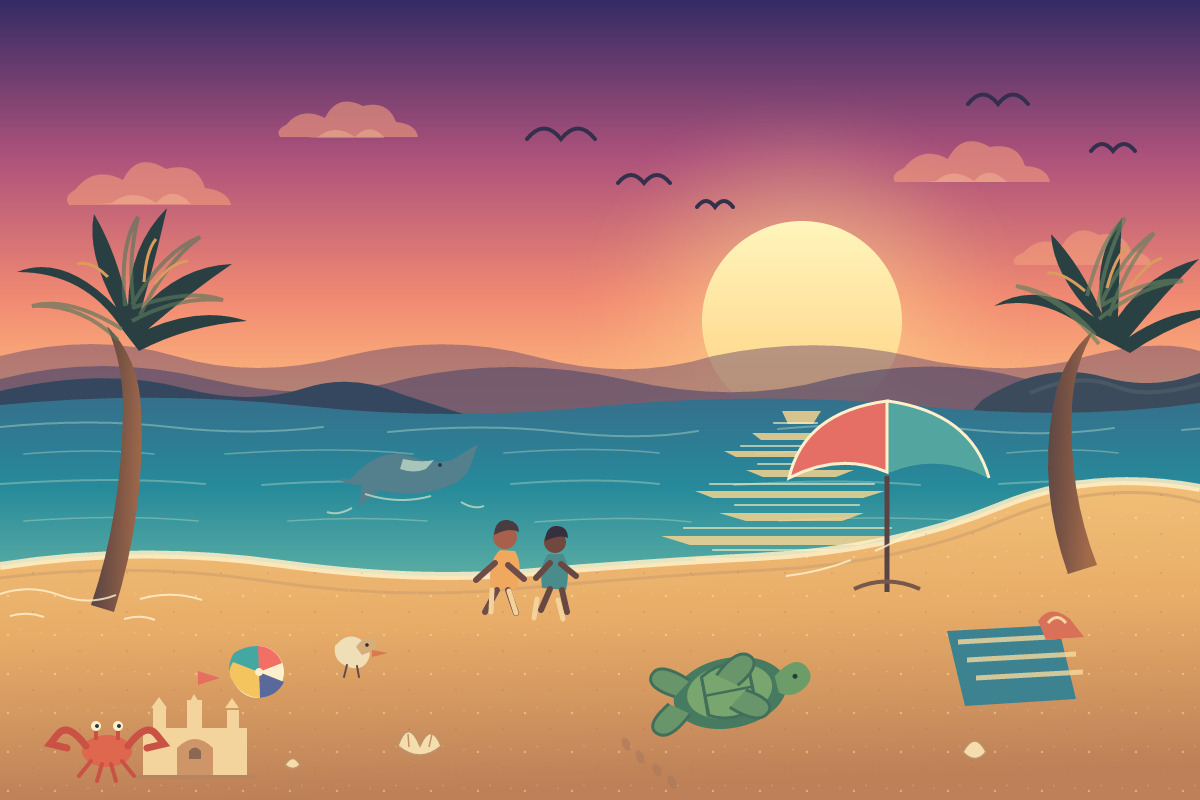
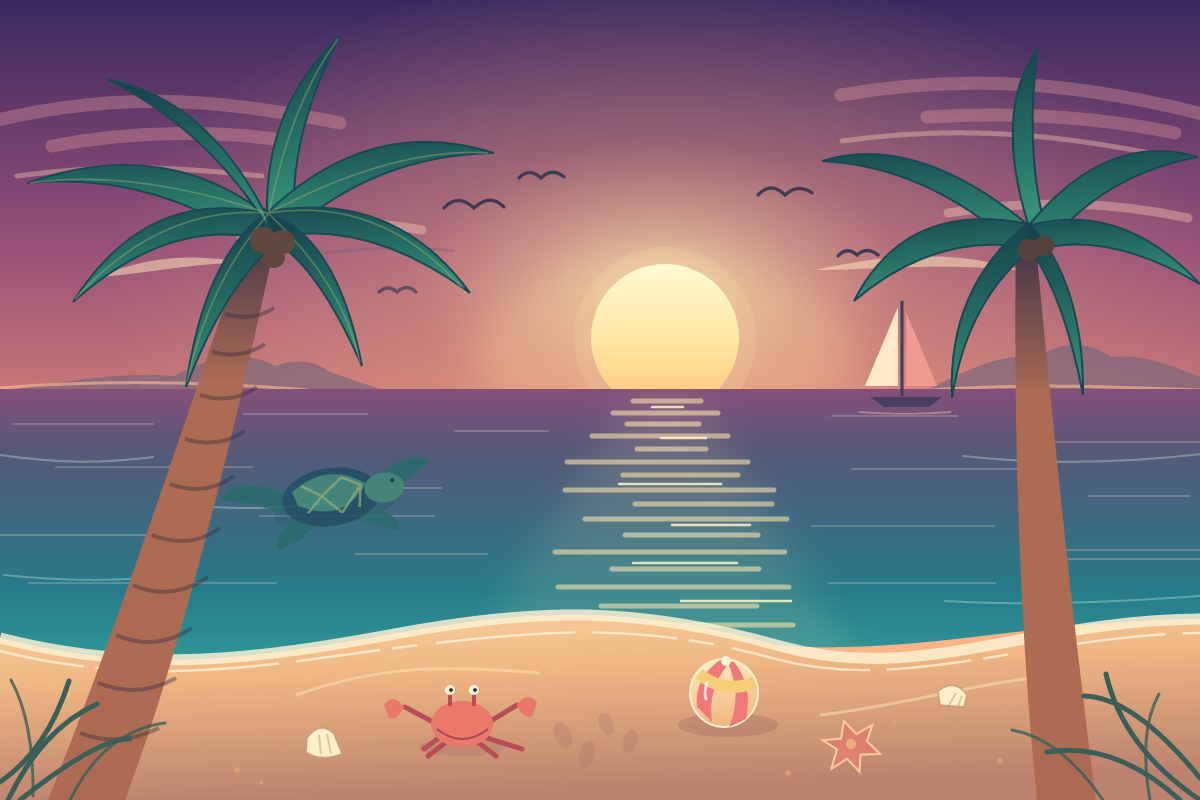
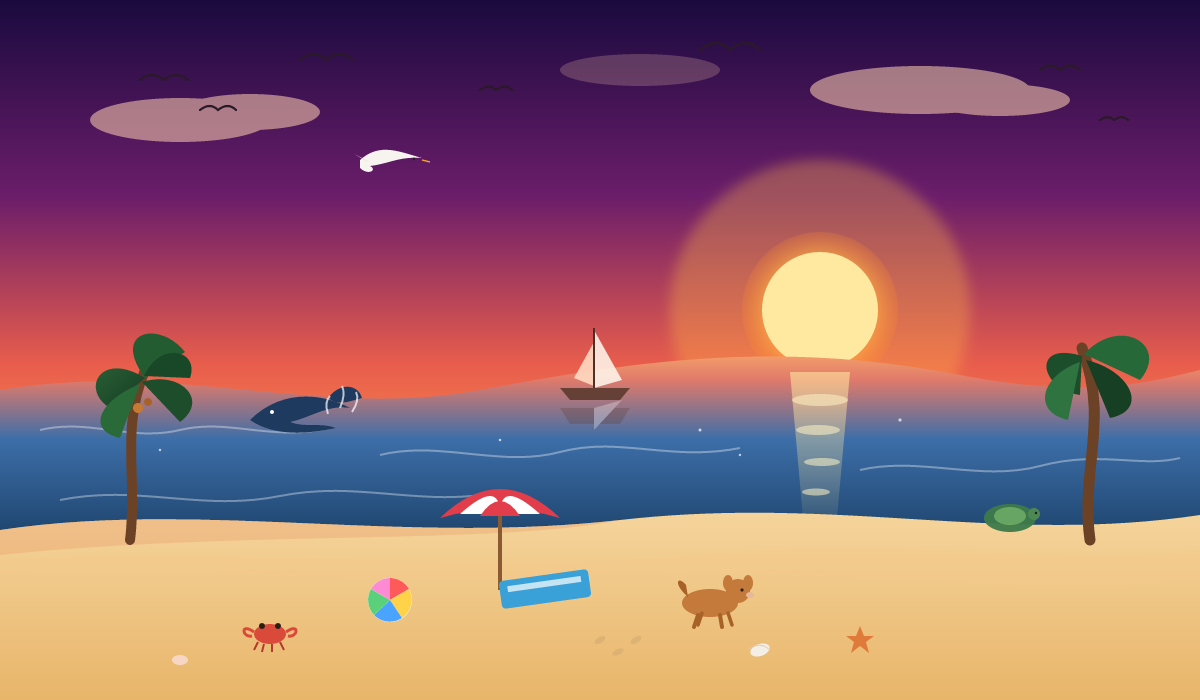
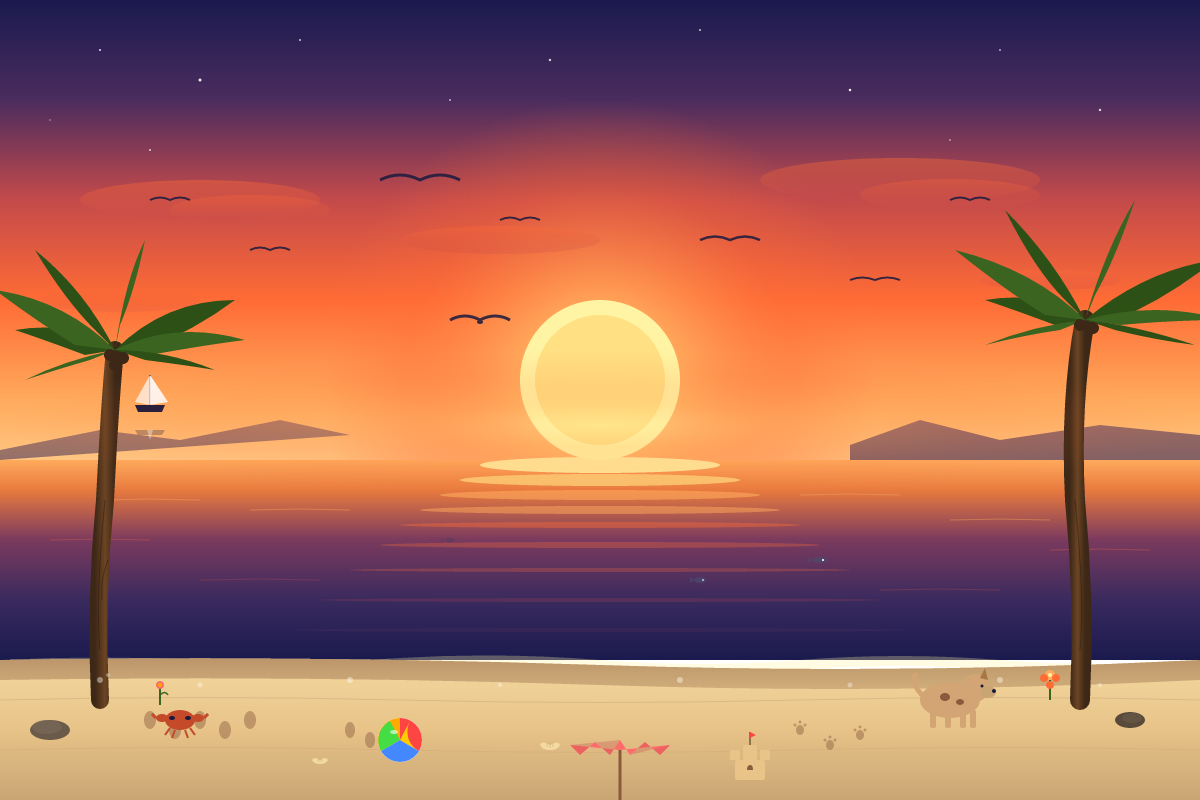
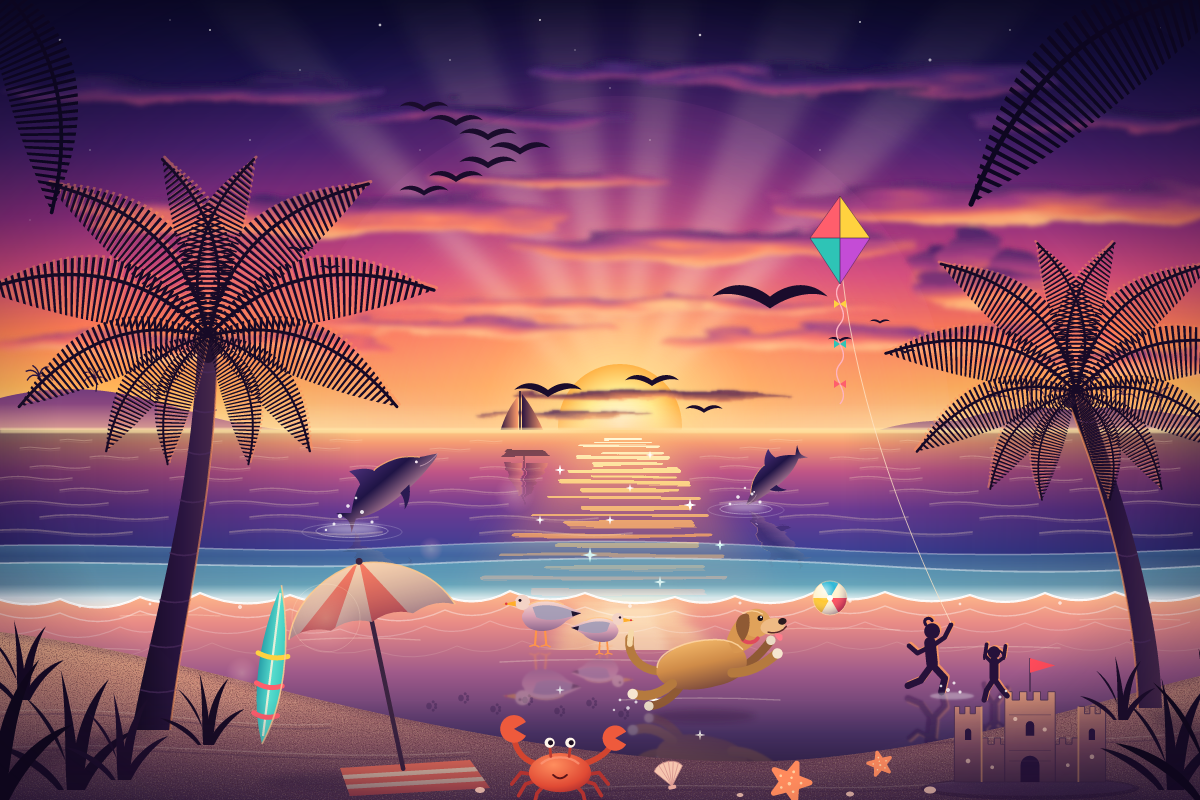
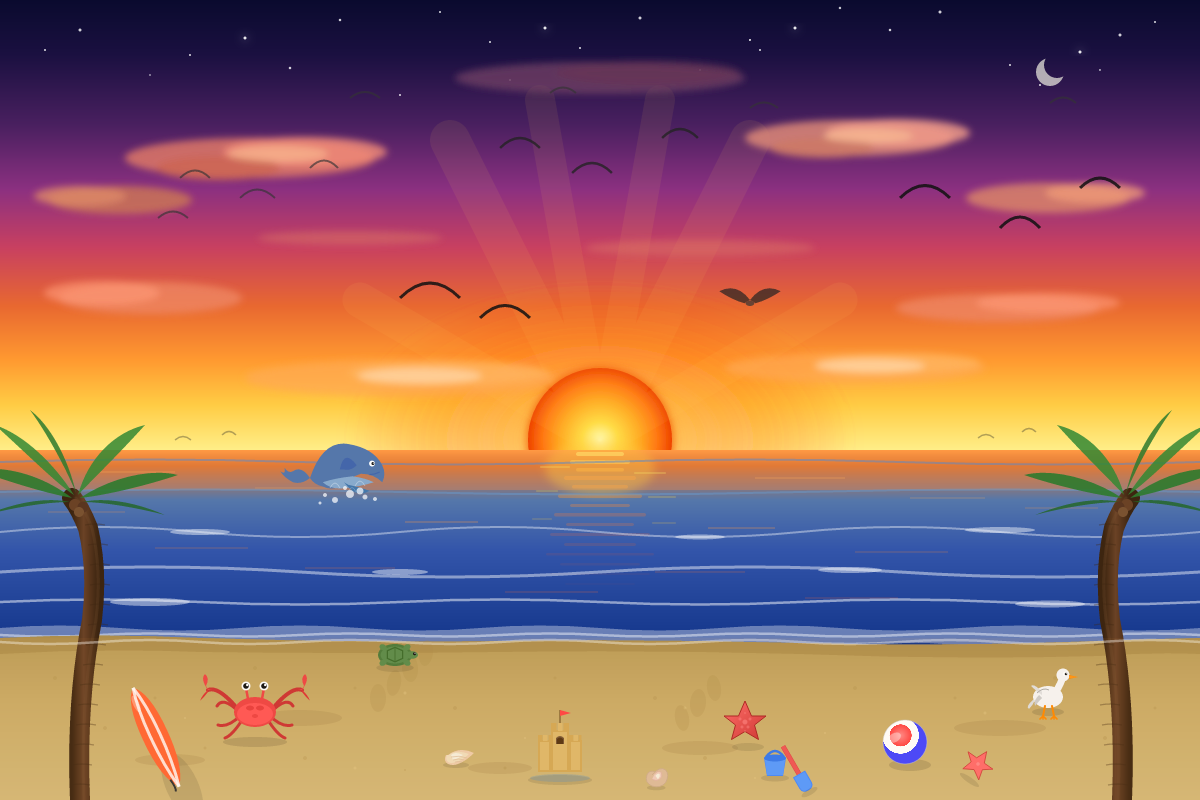
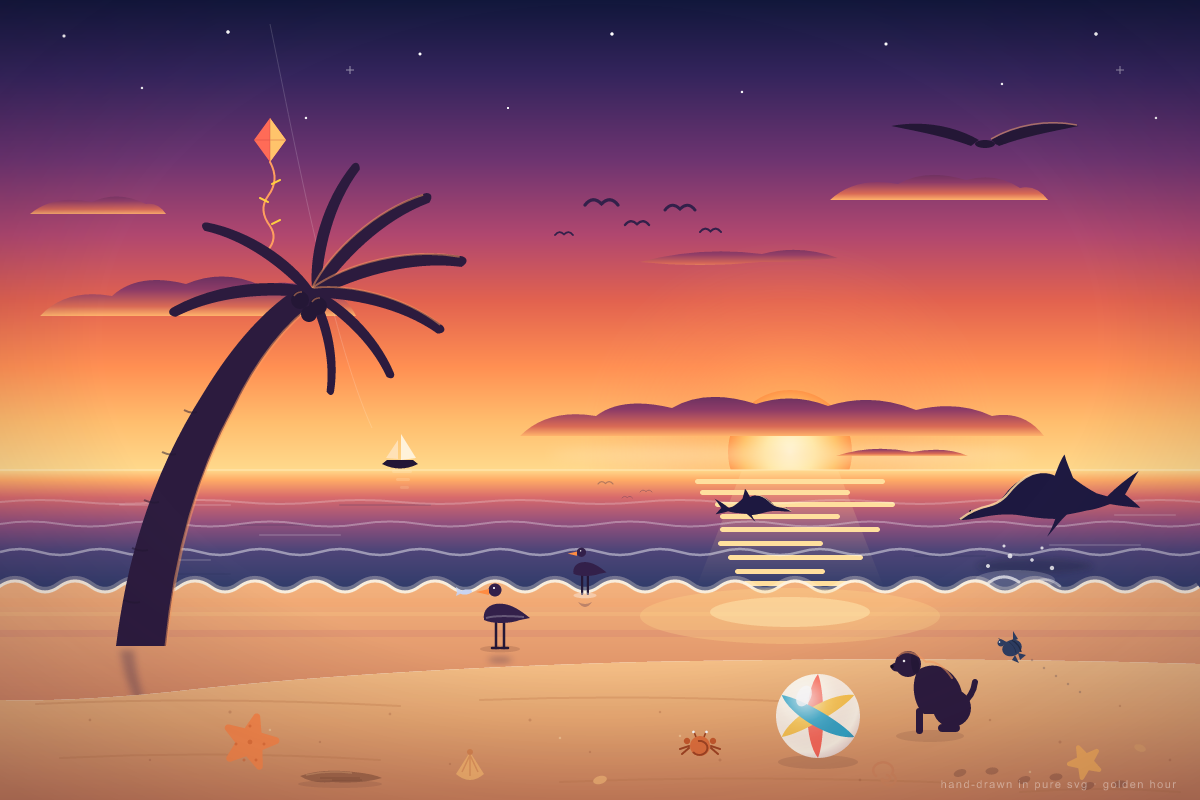
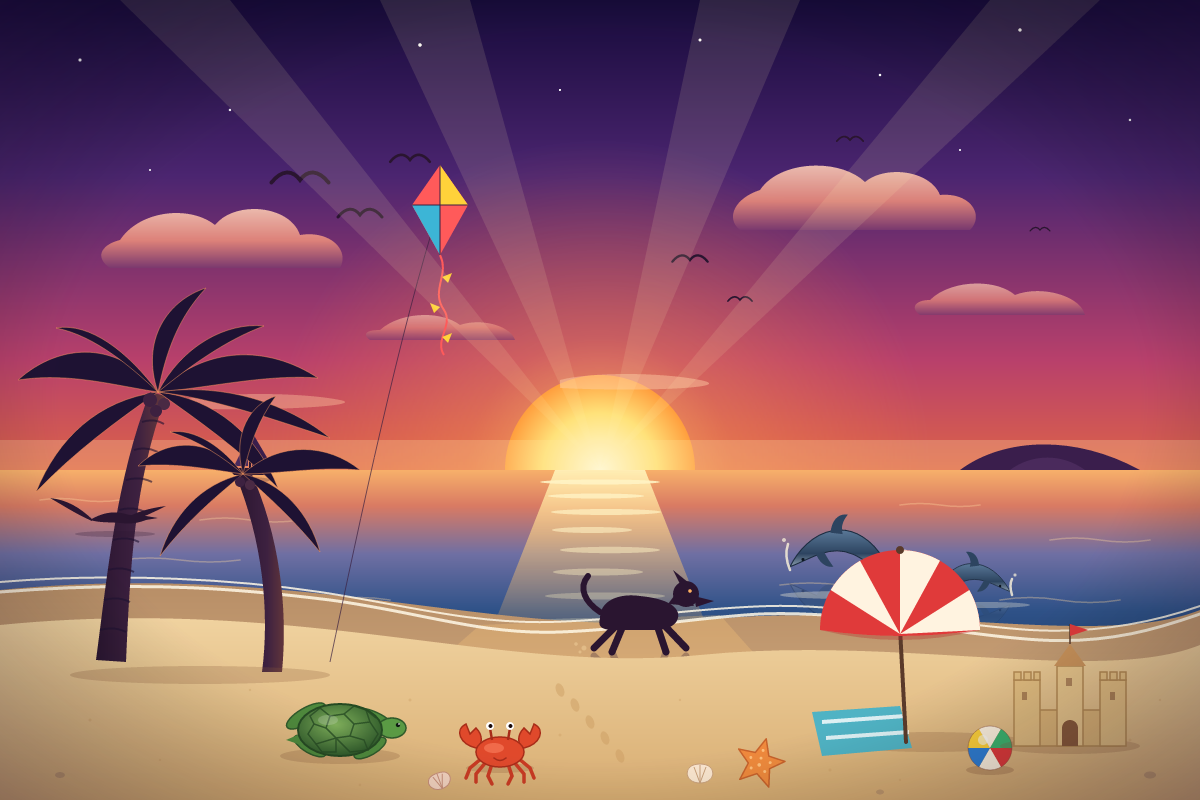
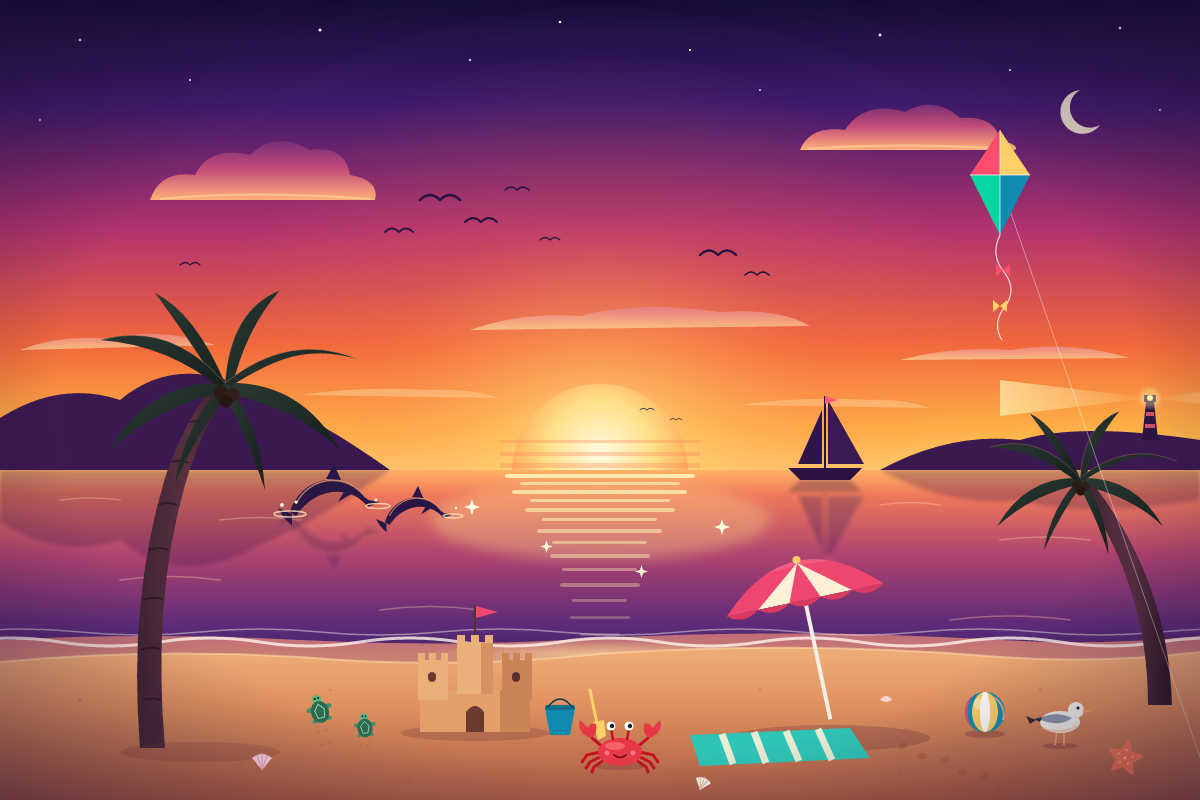
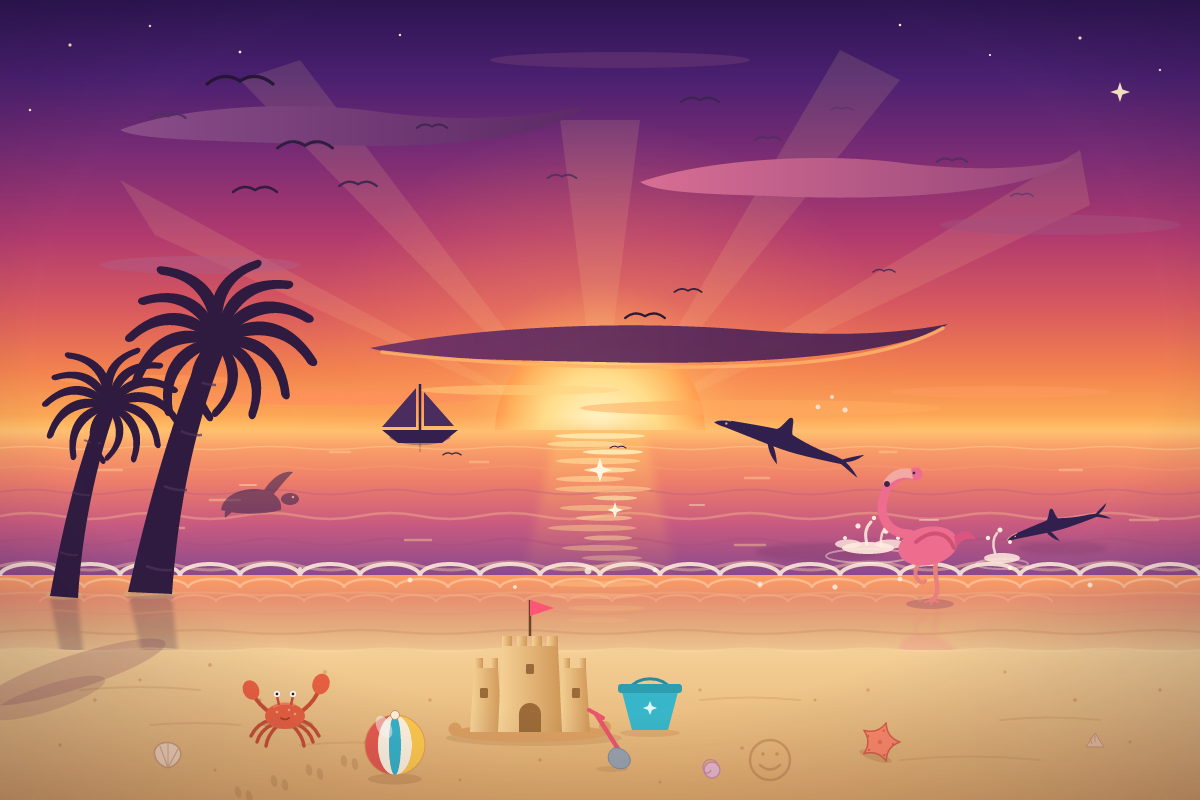
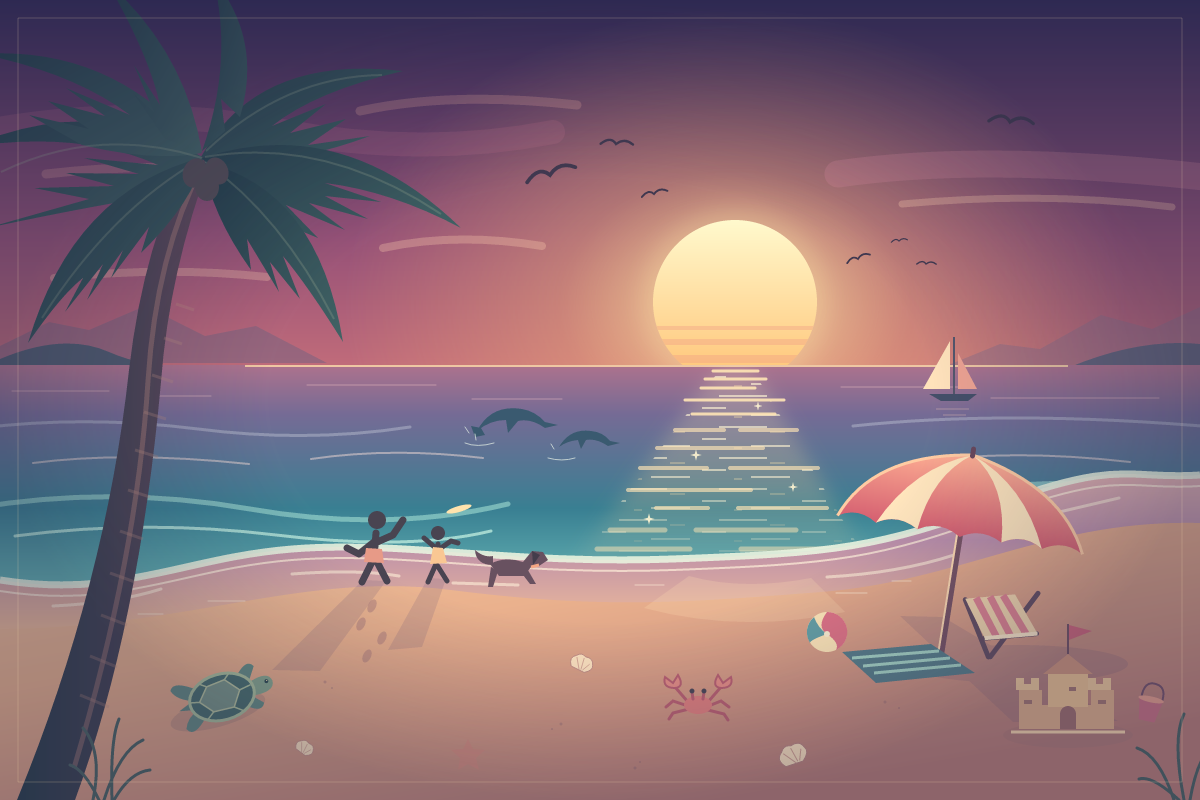
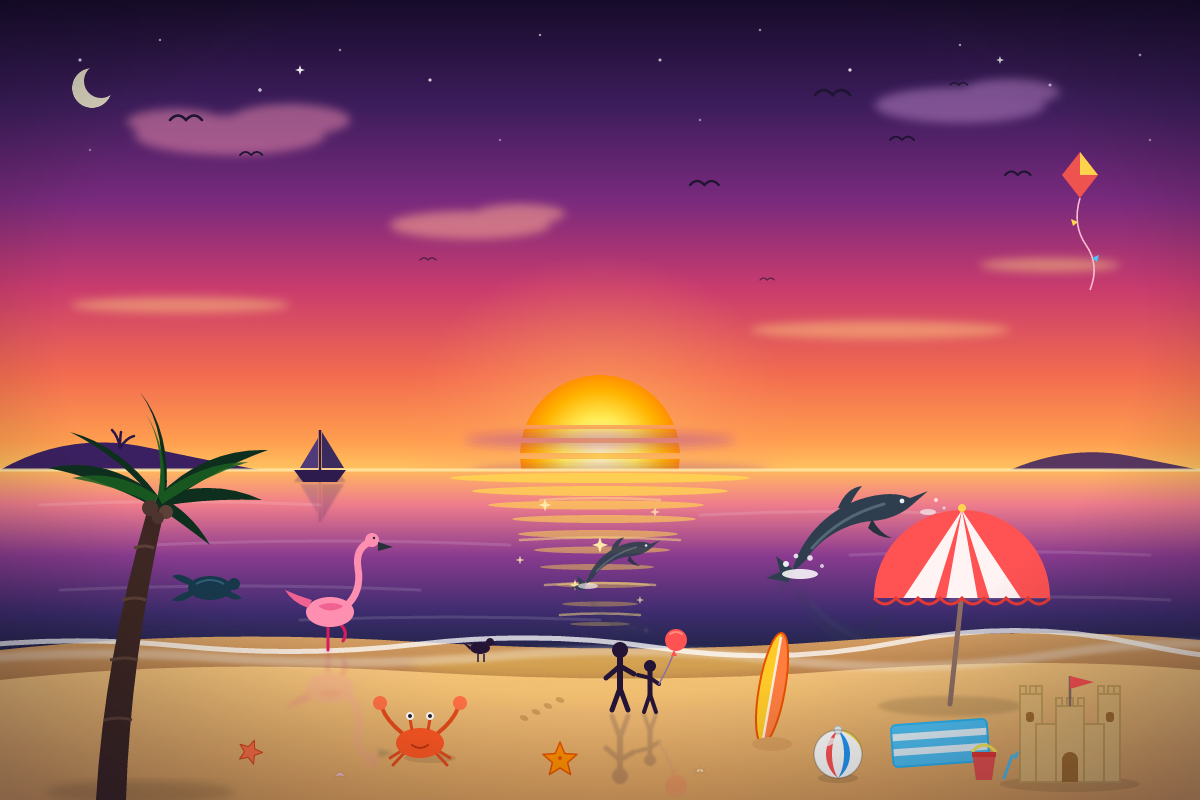
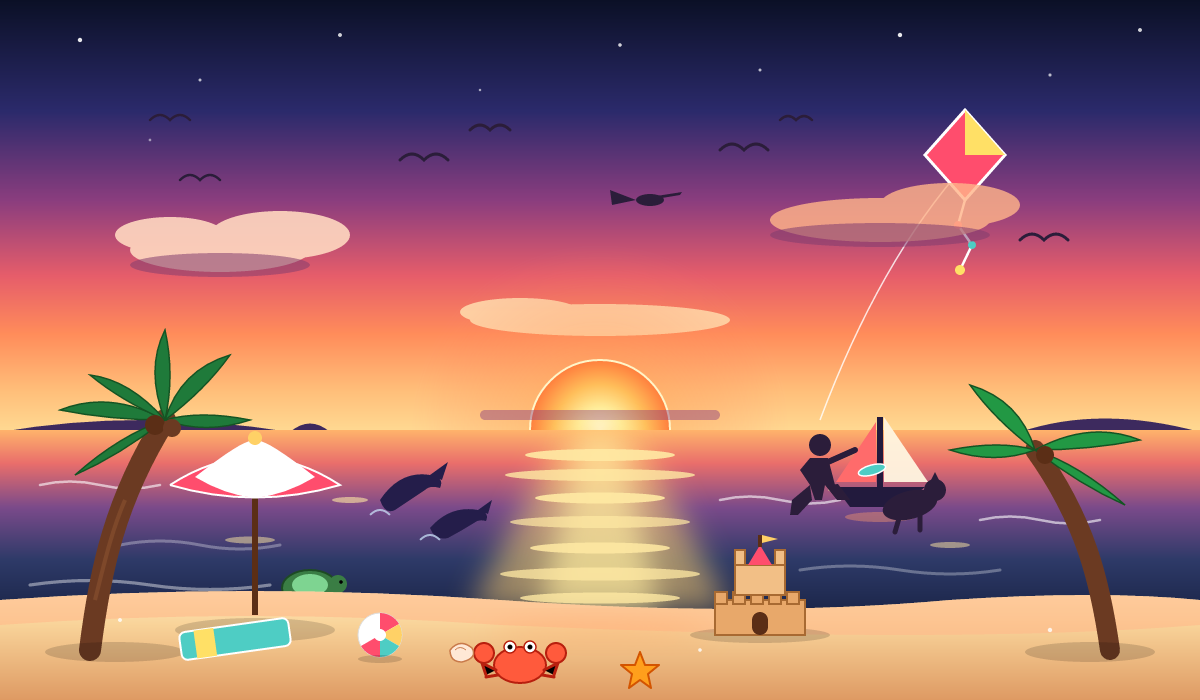
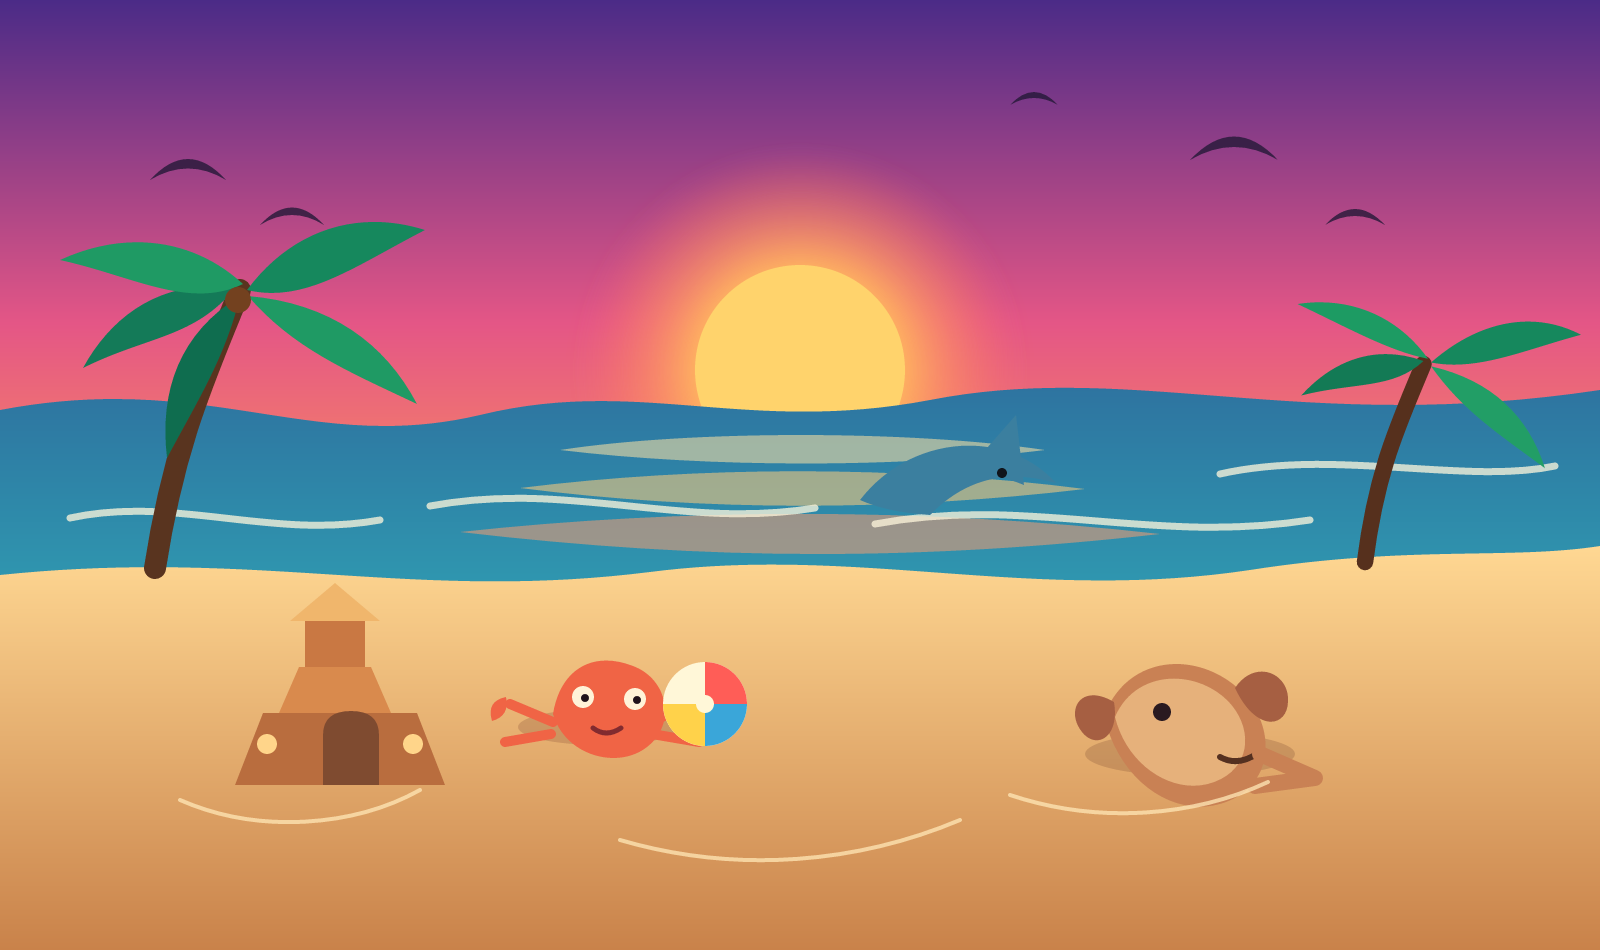
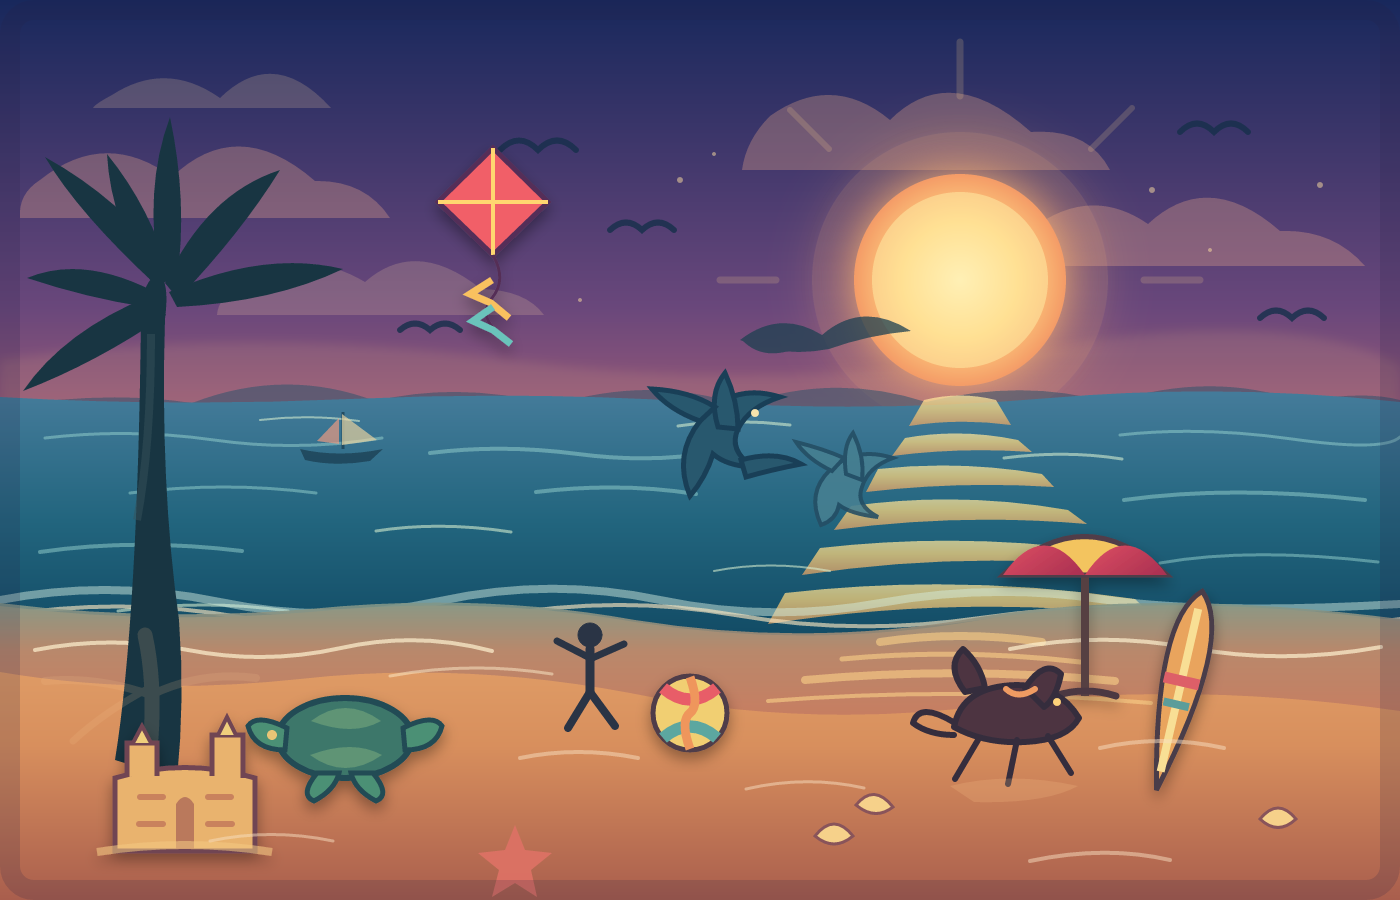
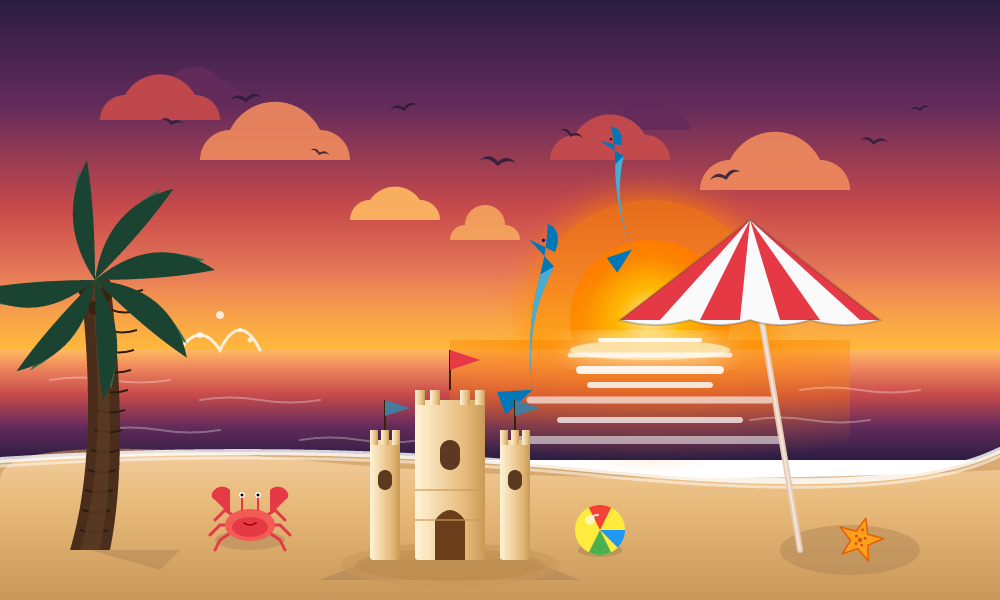
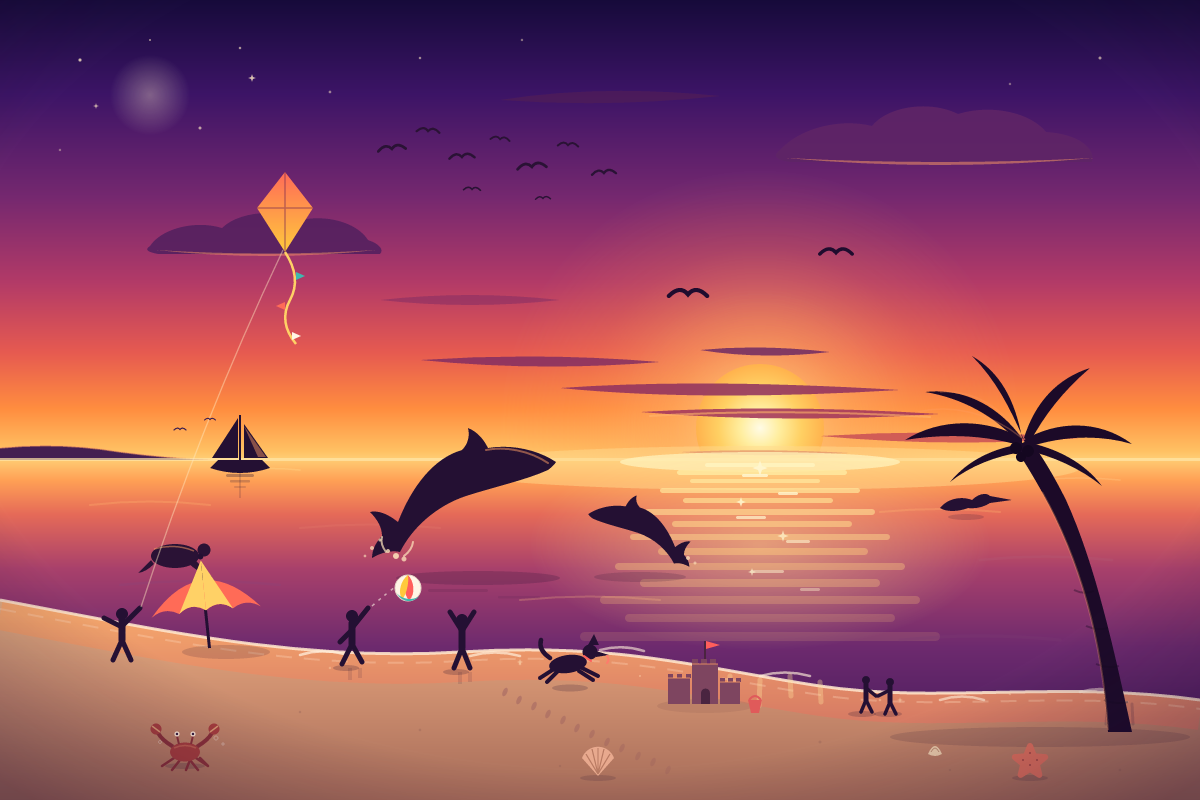
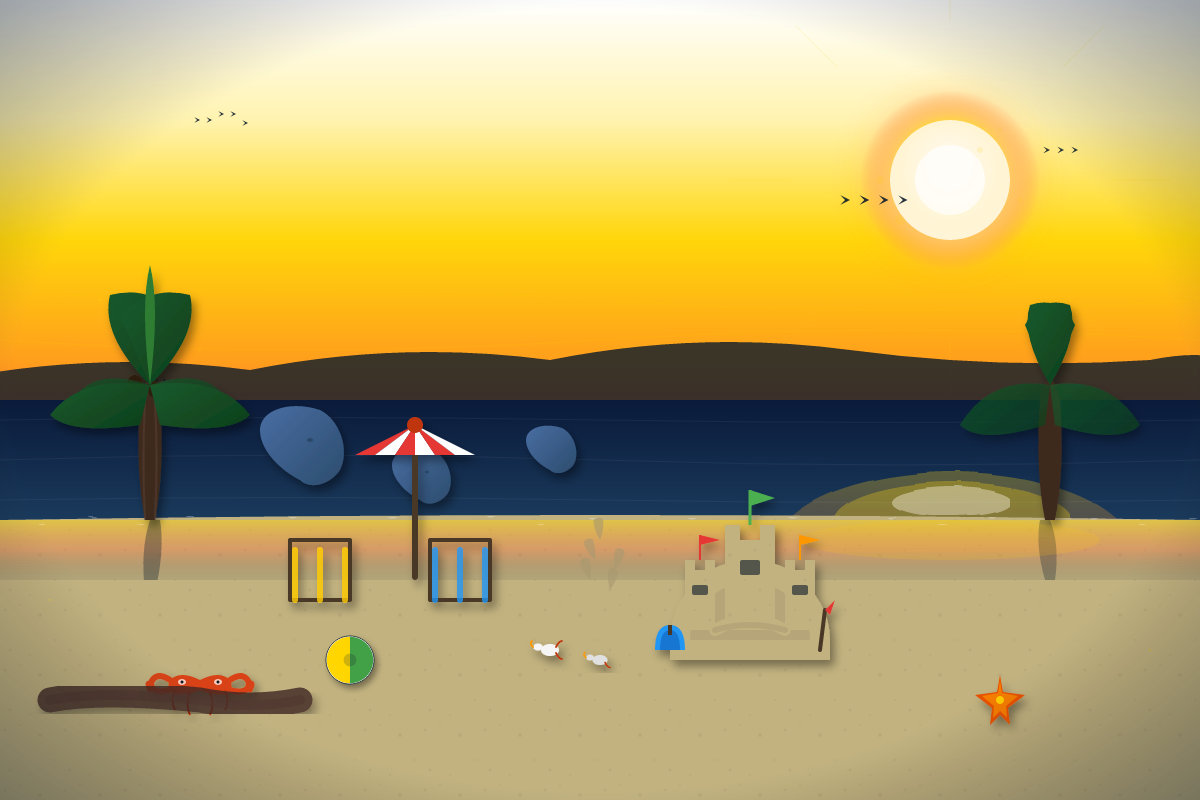
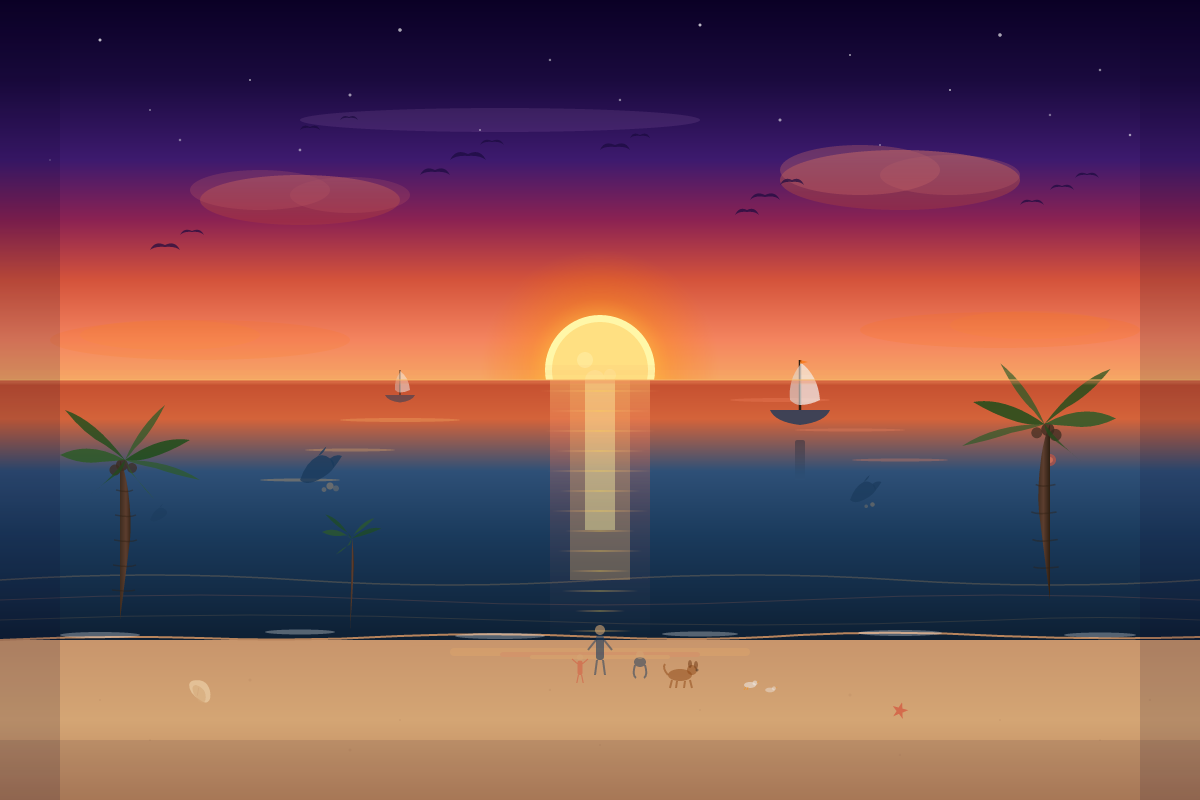
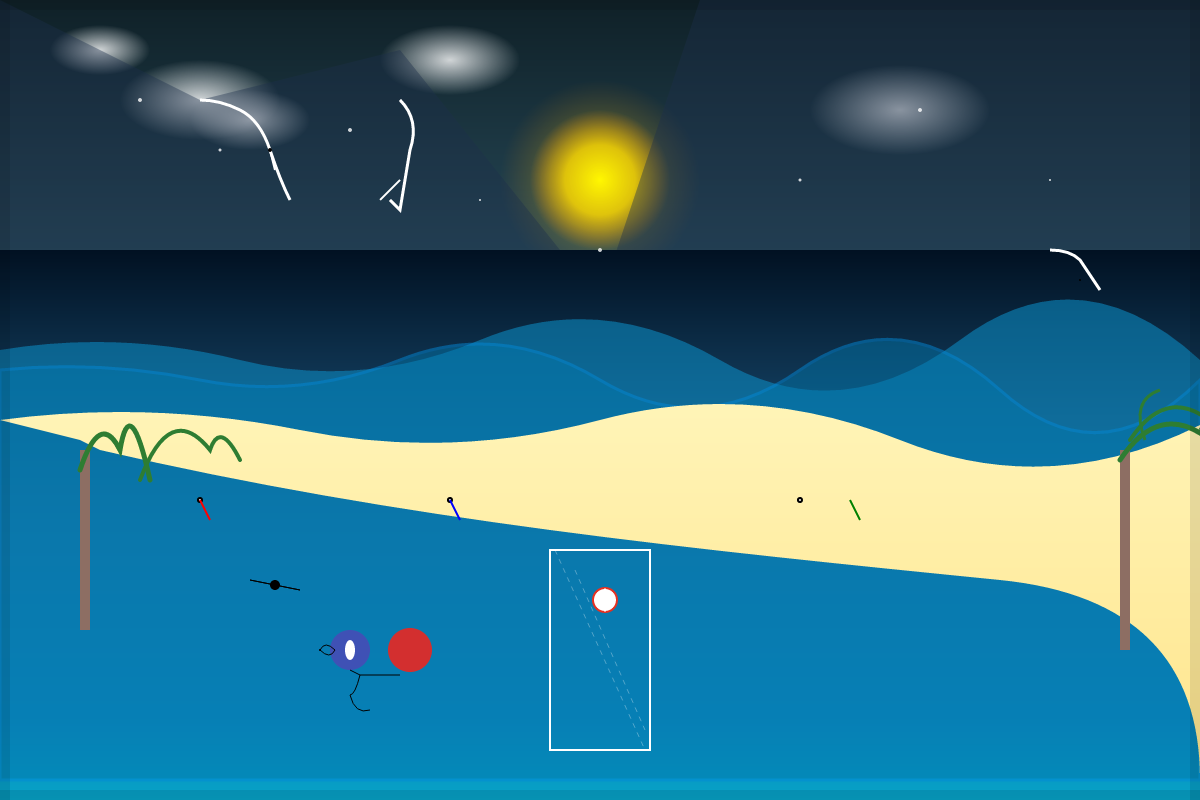
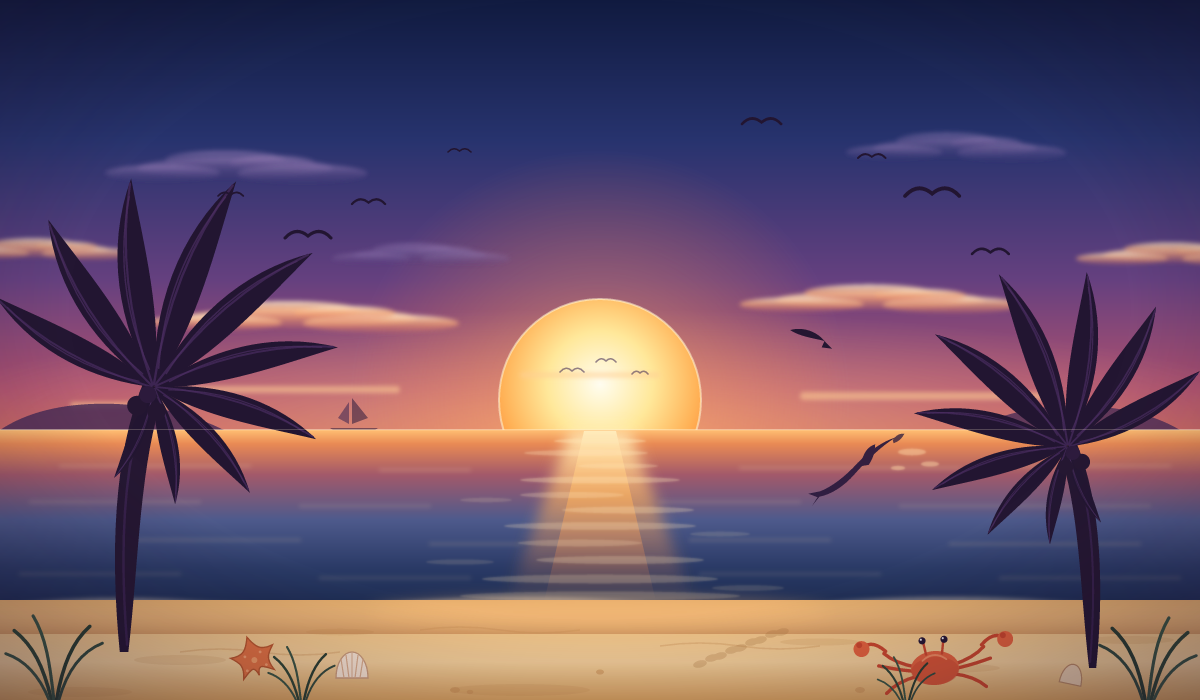
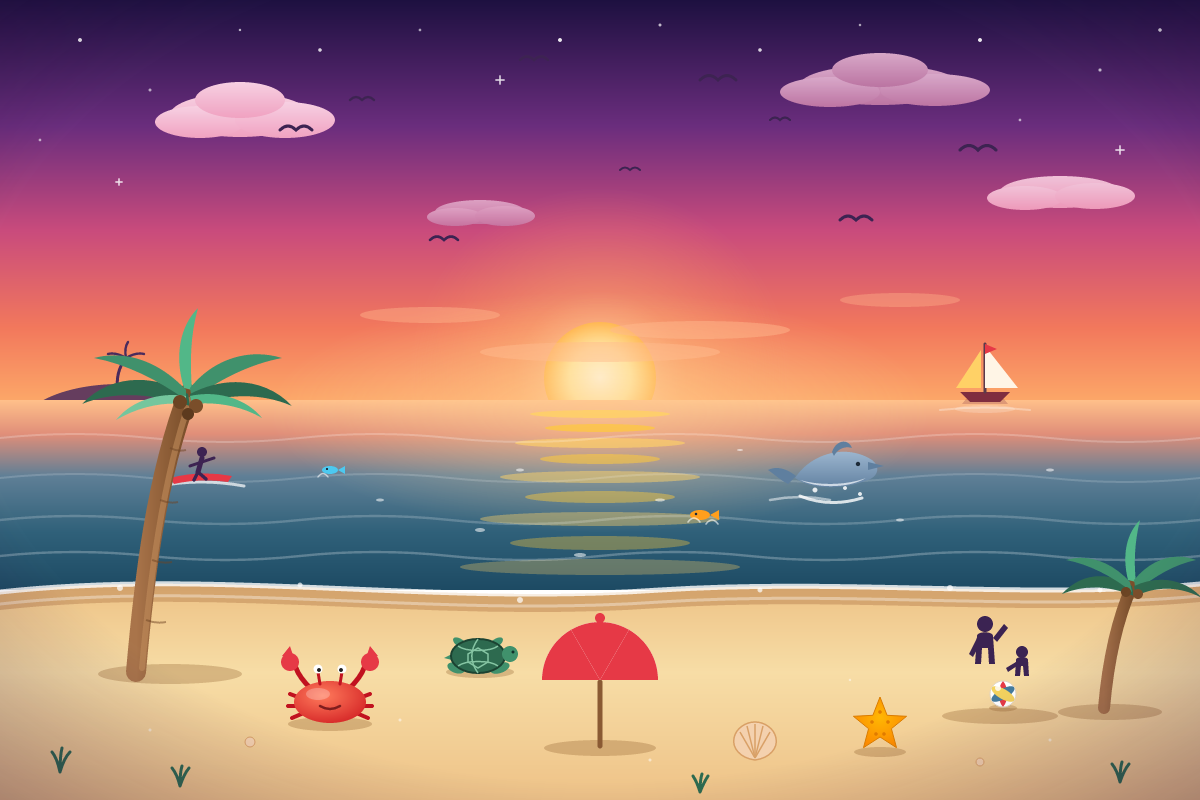
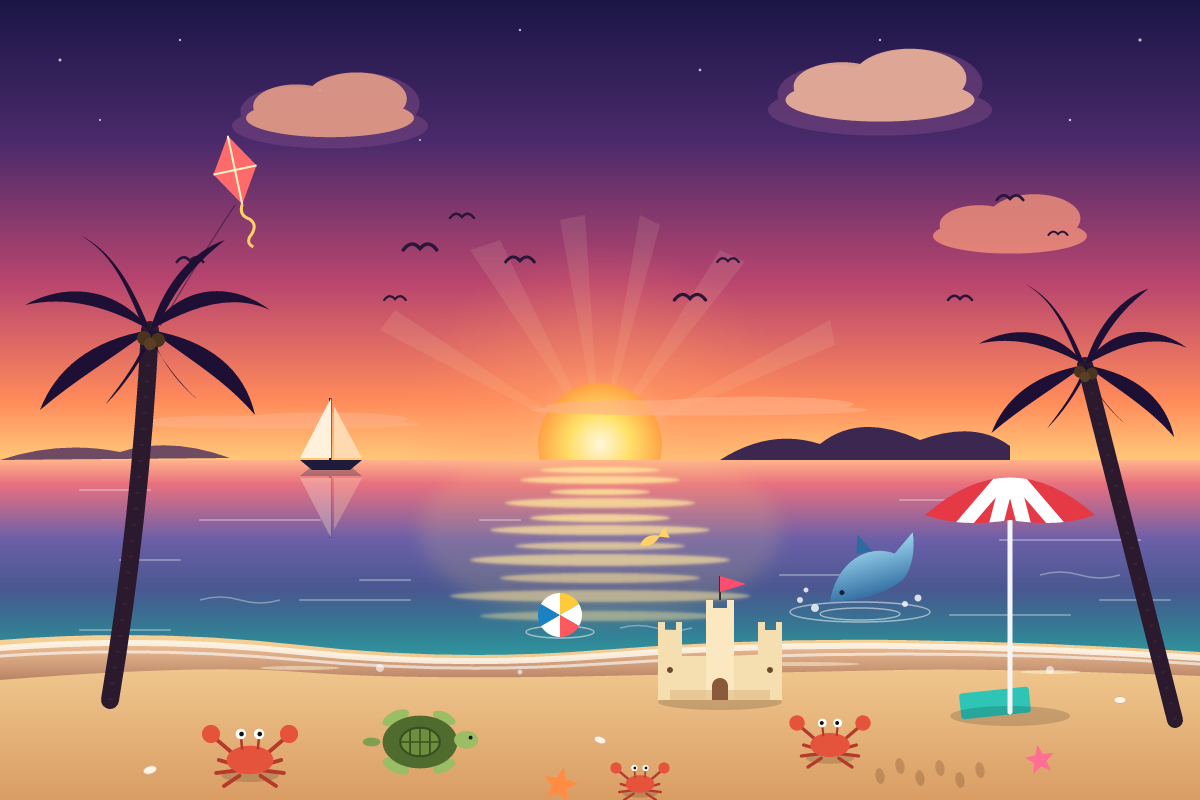
Create an SVG of a amazing beach scene. Sunset, animals, fun, birds, reflections Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
First run
·No result yet
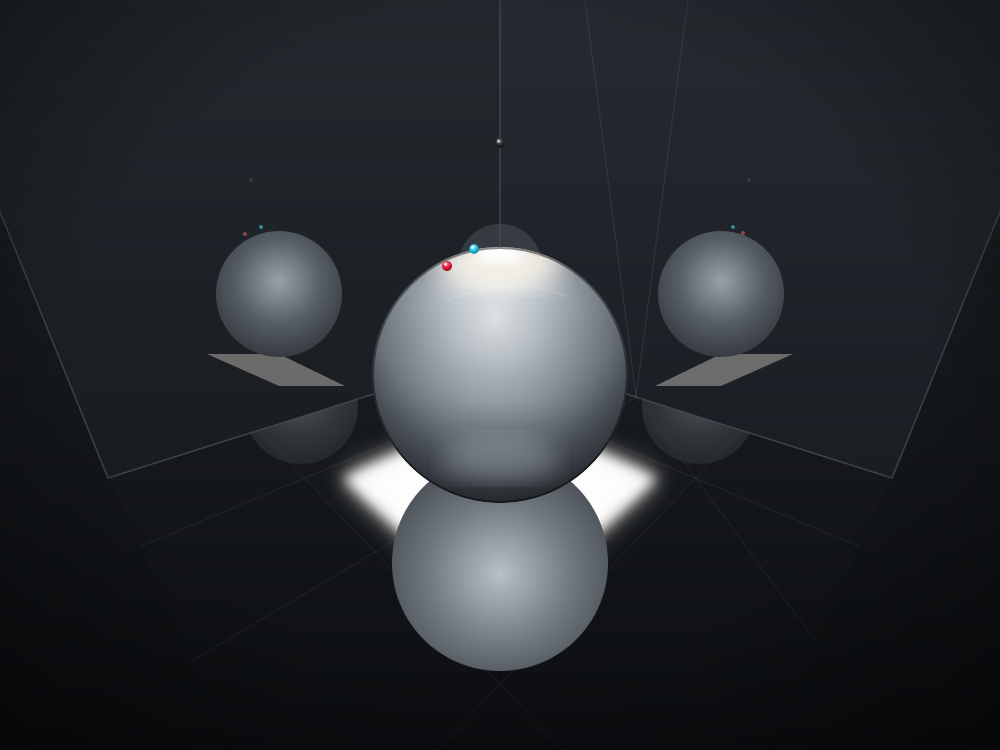
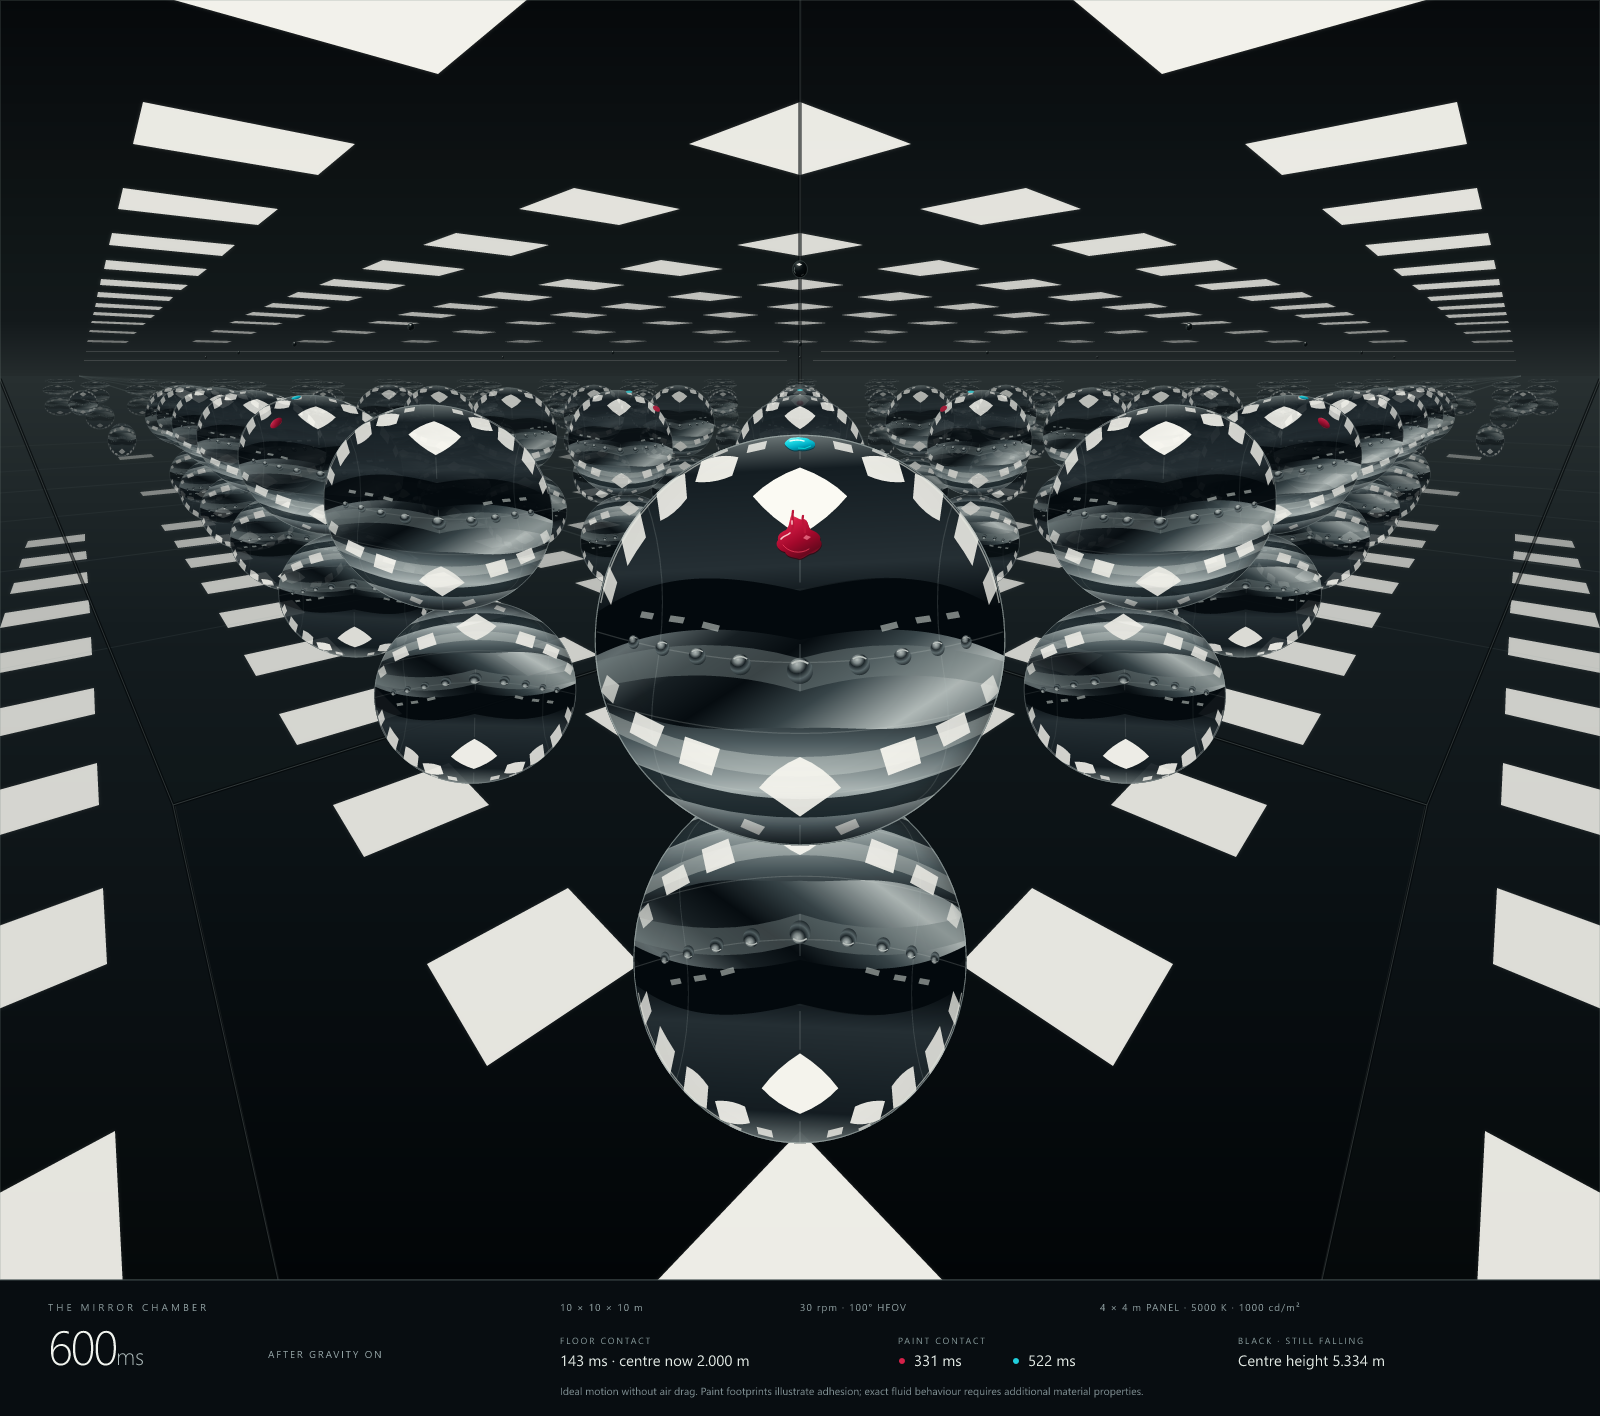
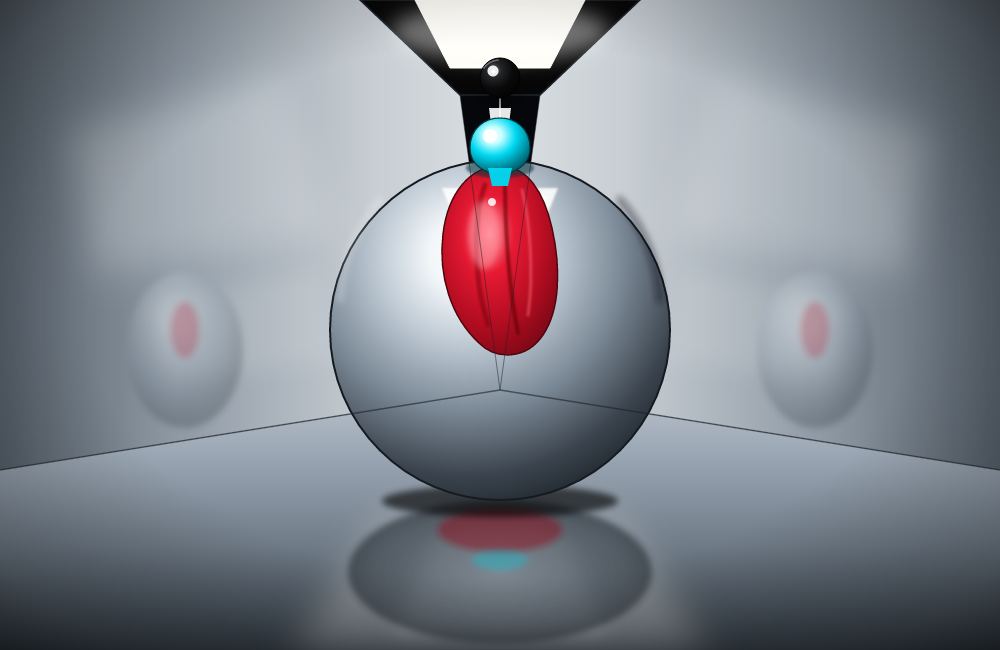
Newton's MirrorPhysical, spatial
and recursive reasoningComplexity 9/10
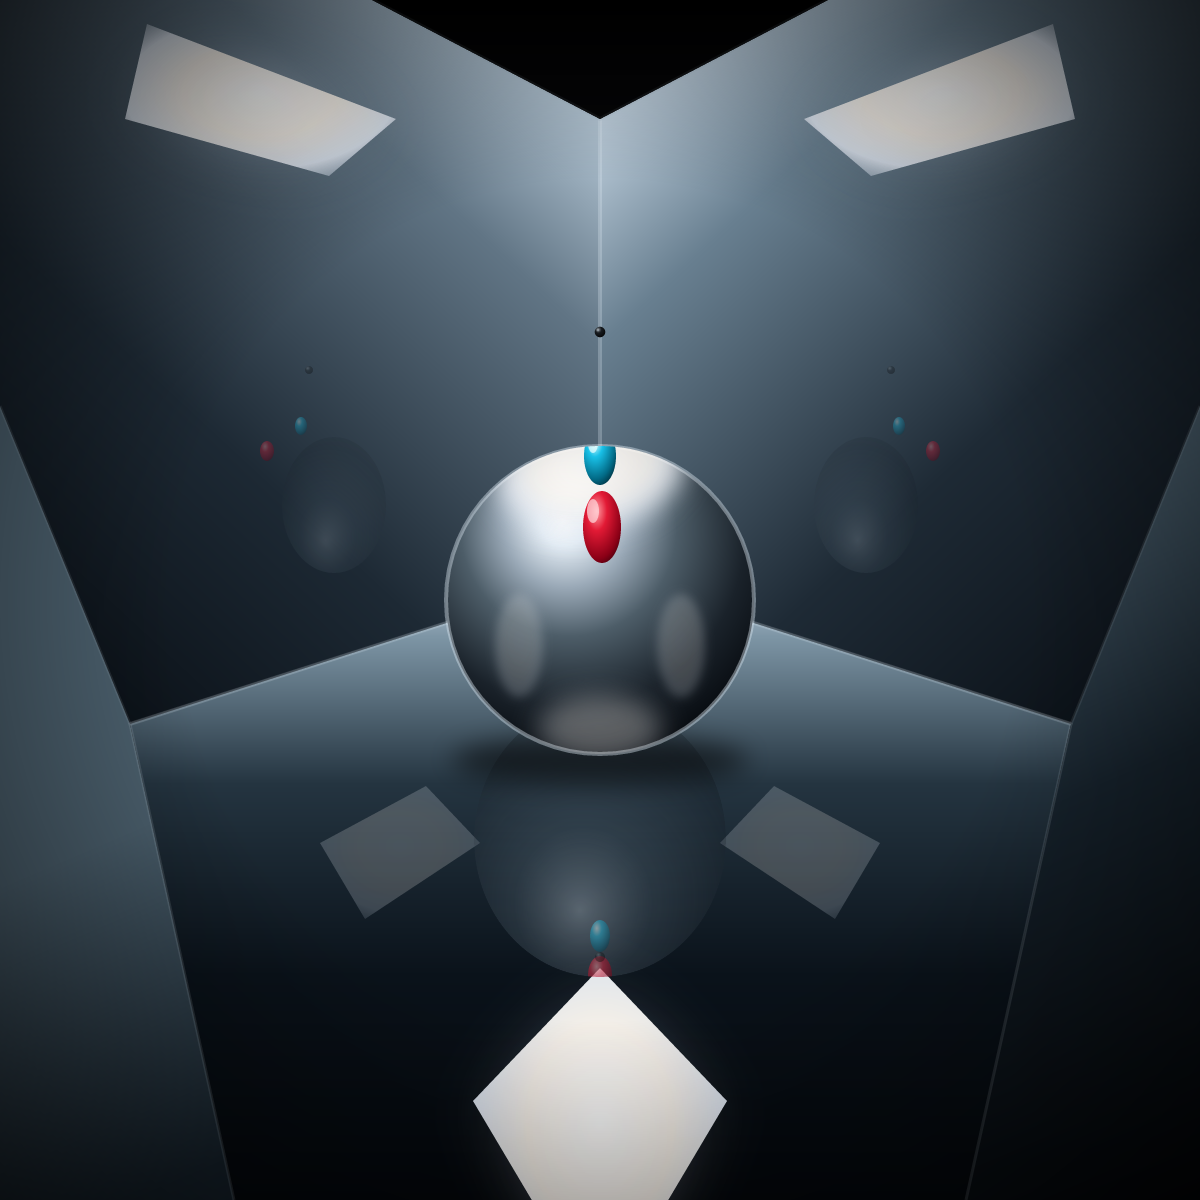
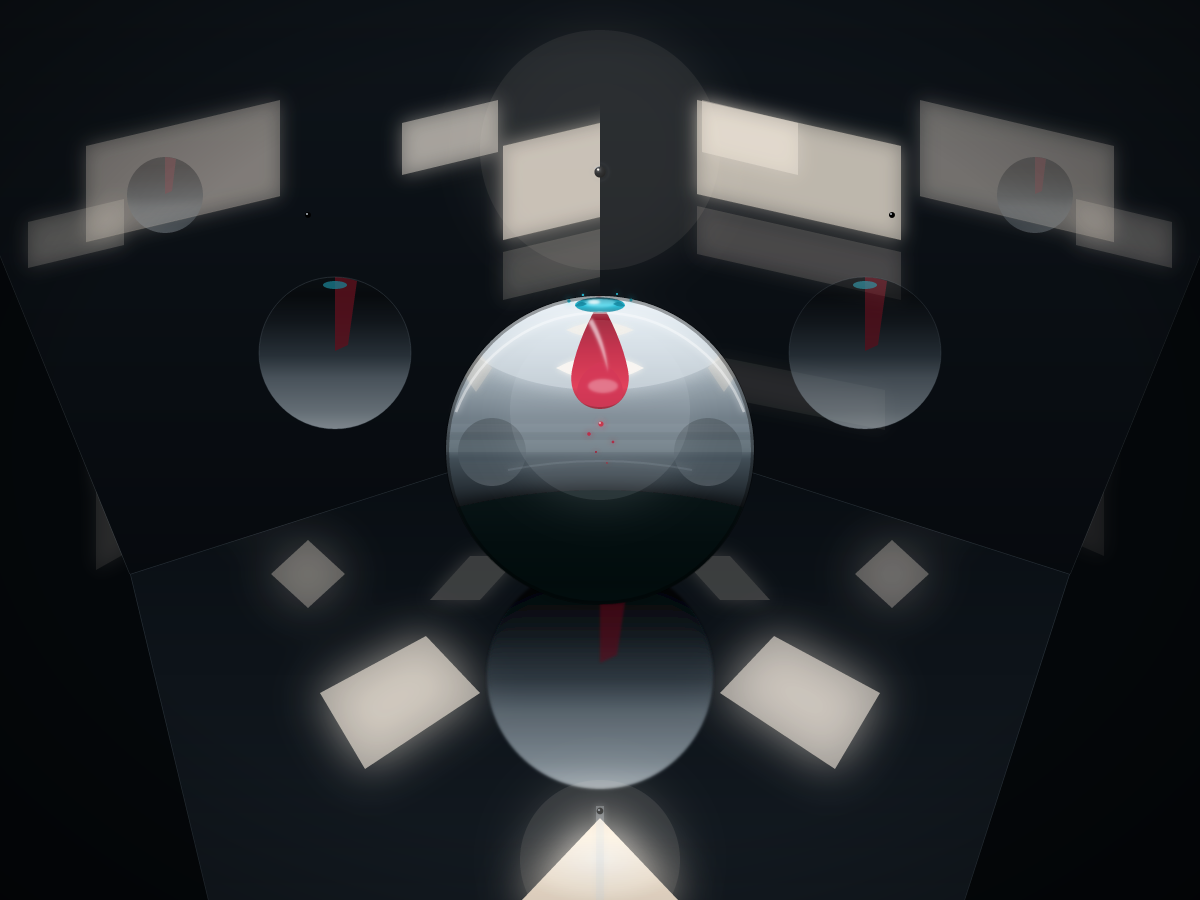
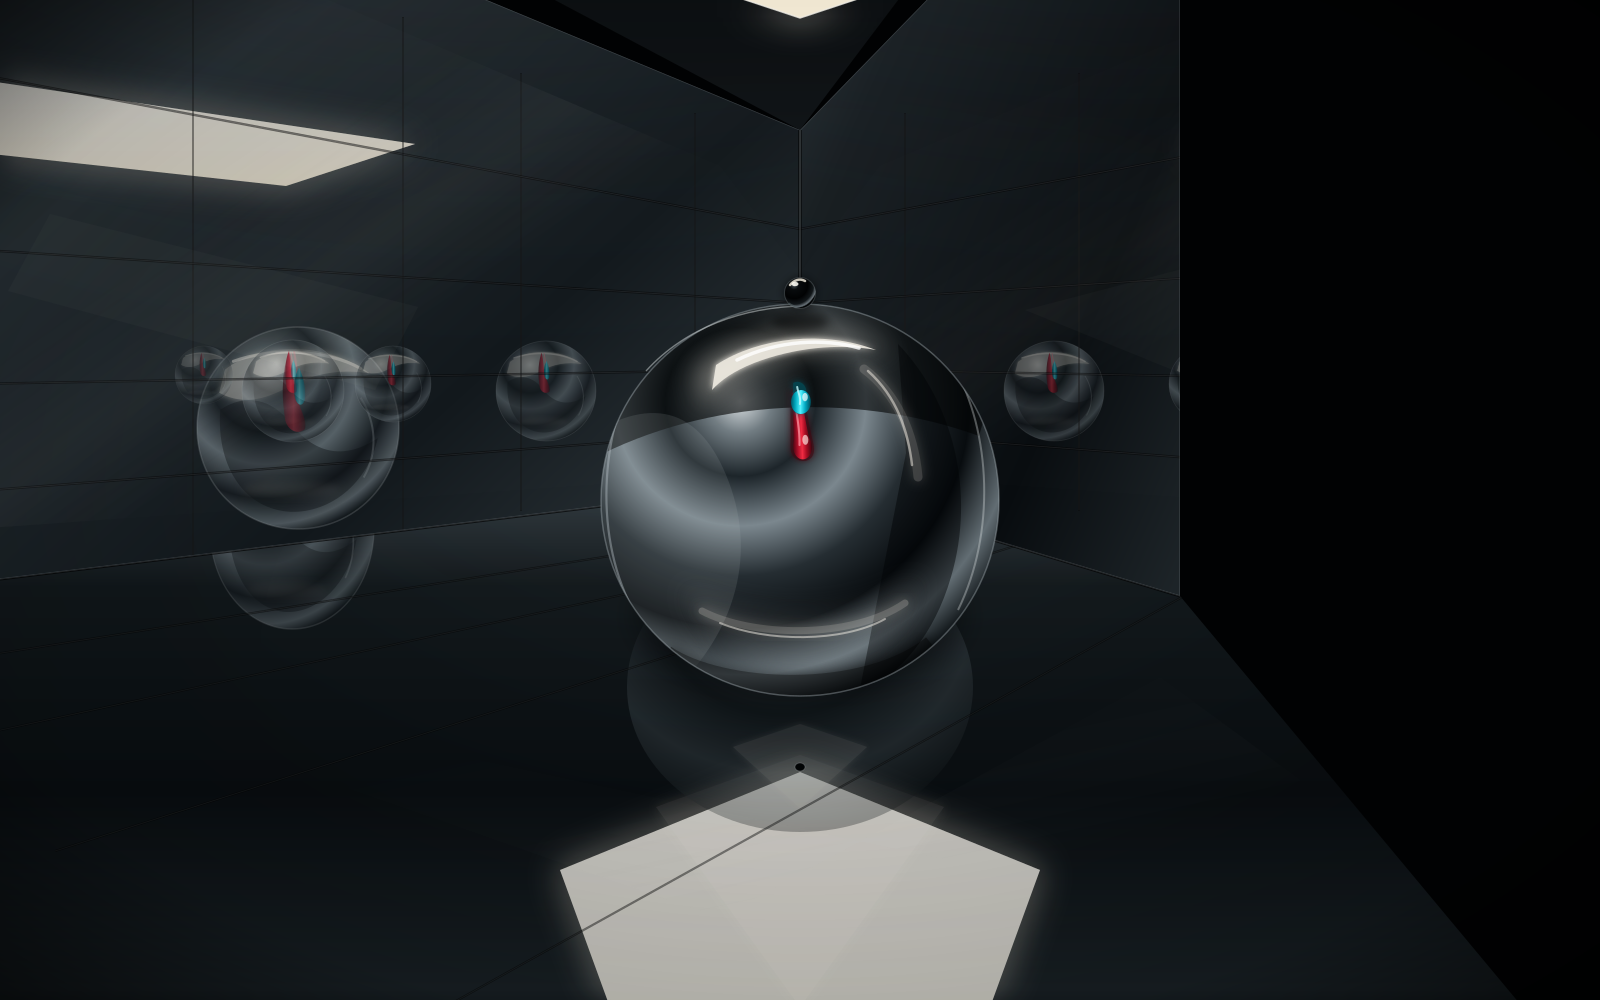
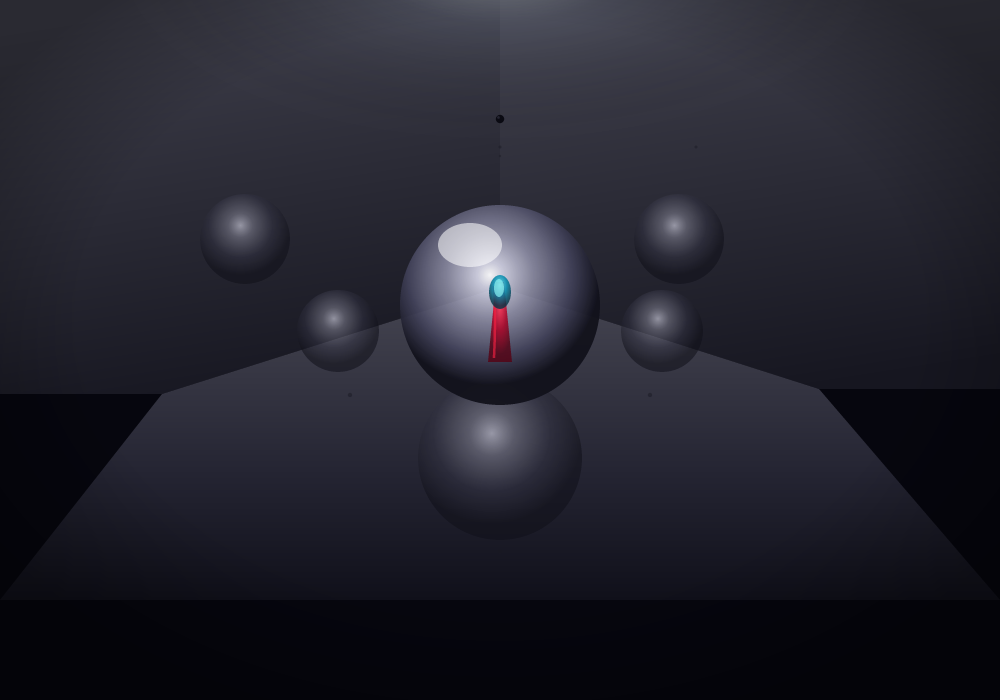
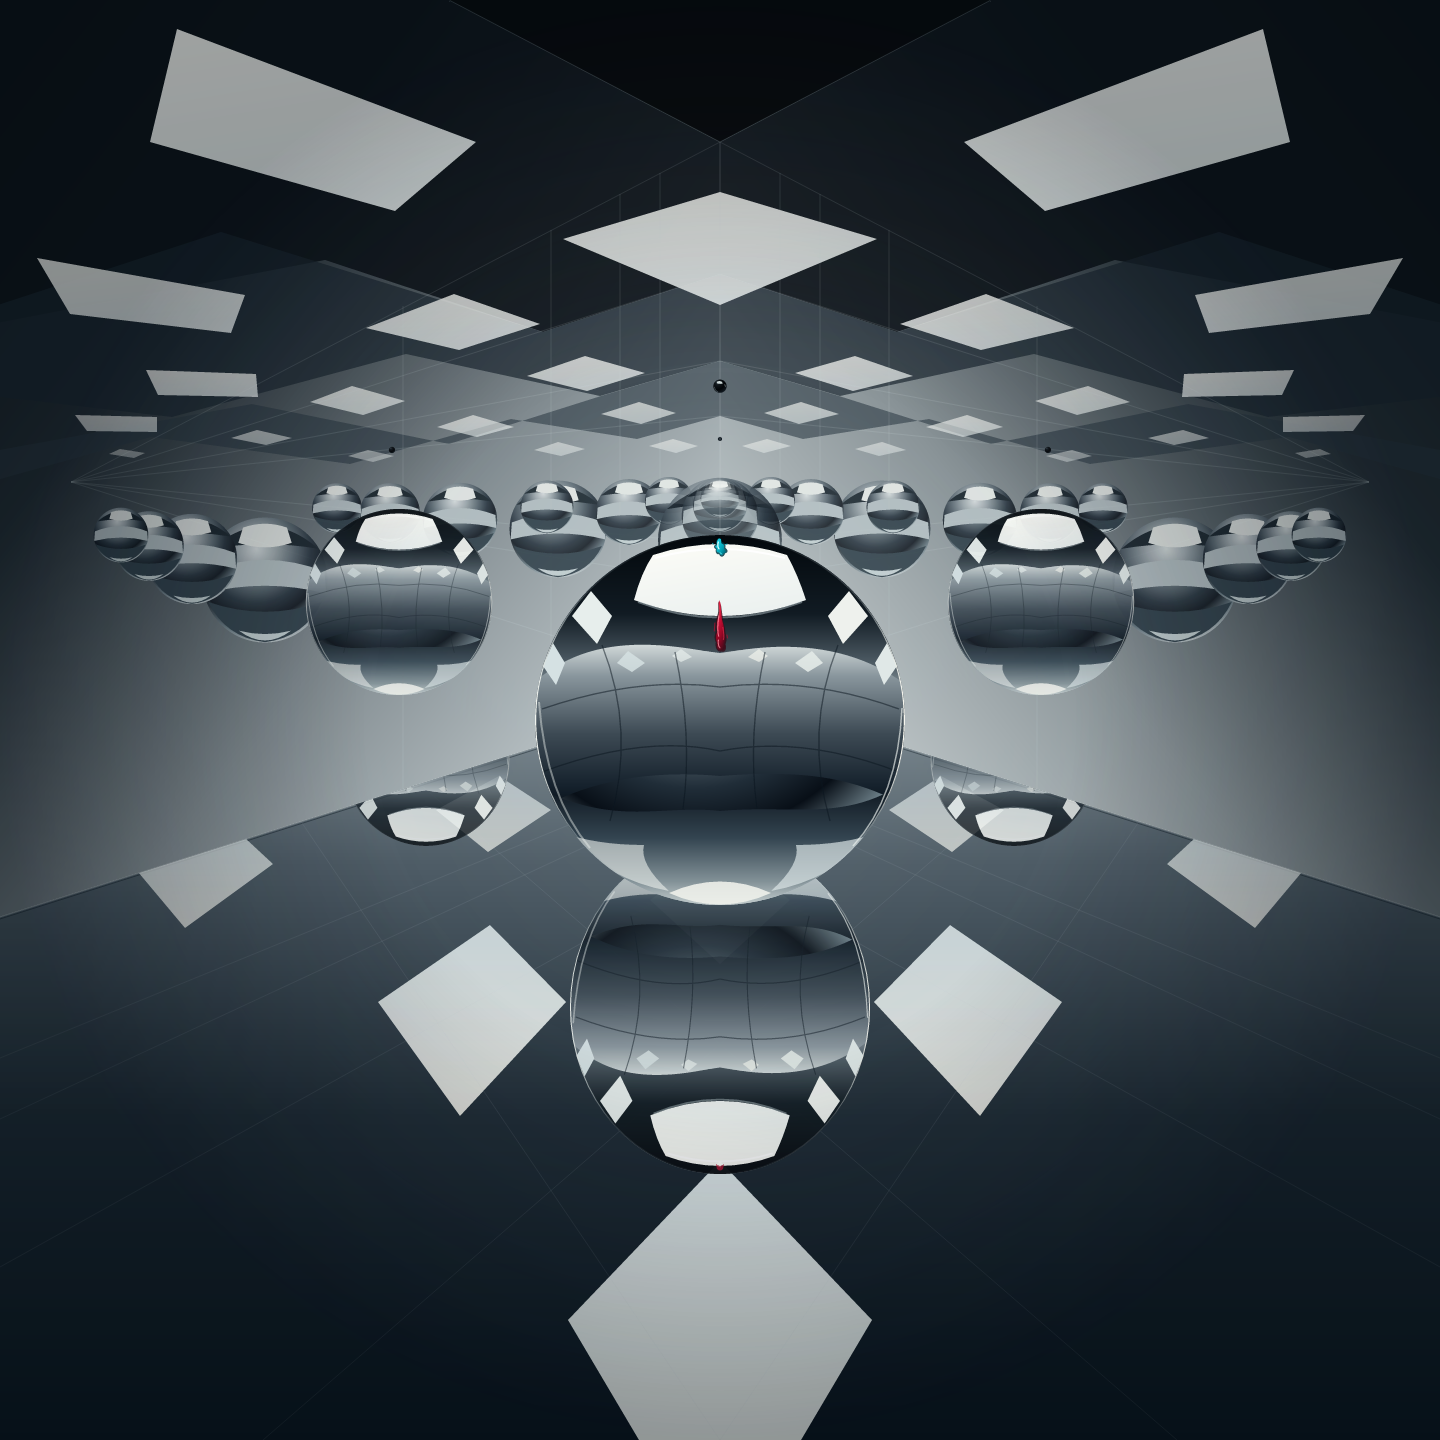
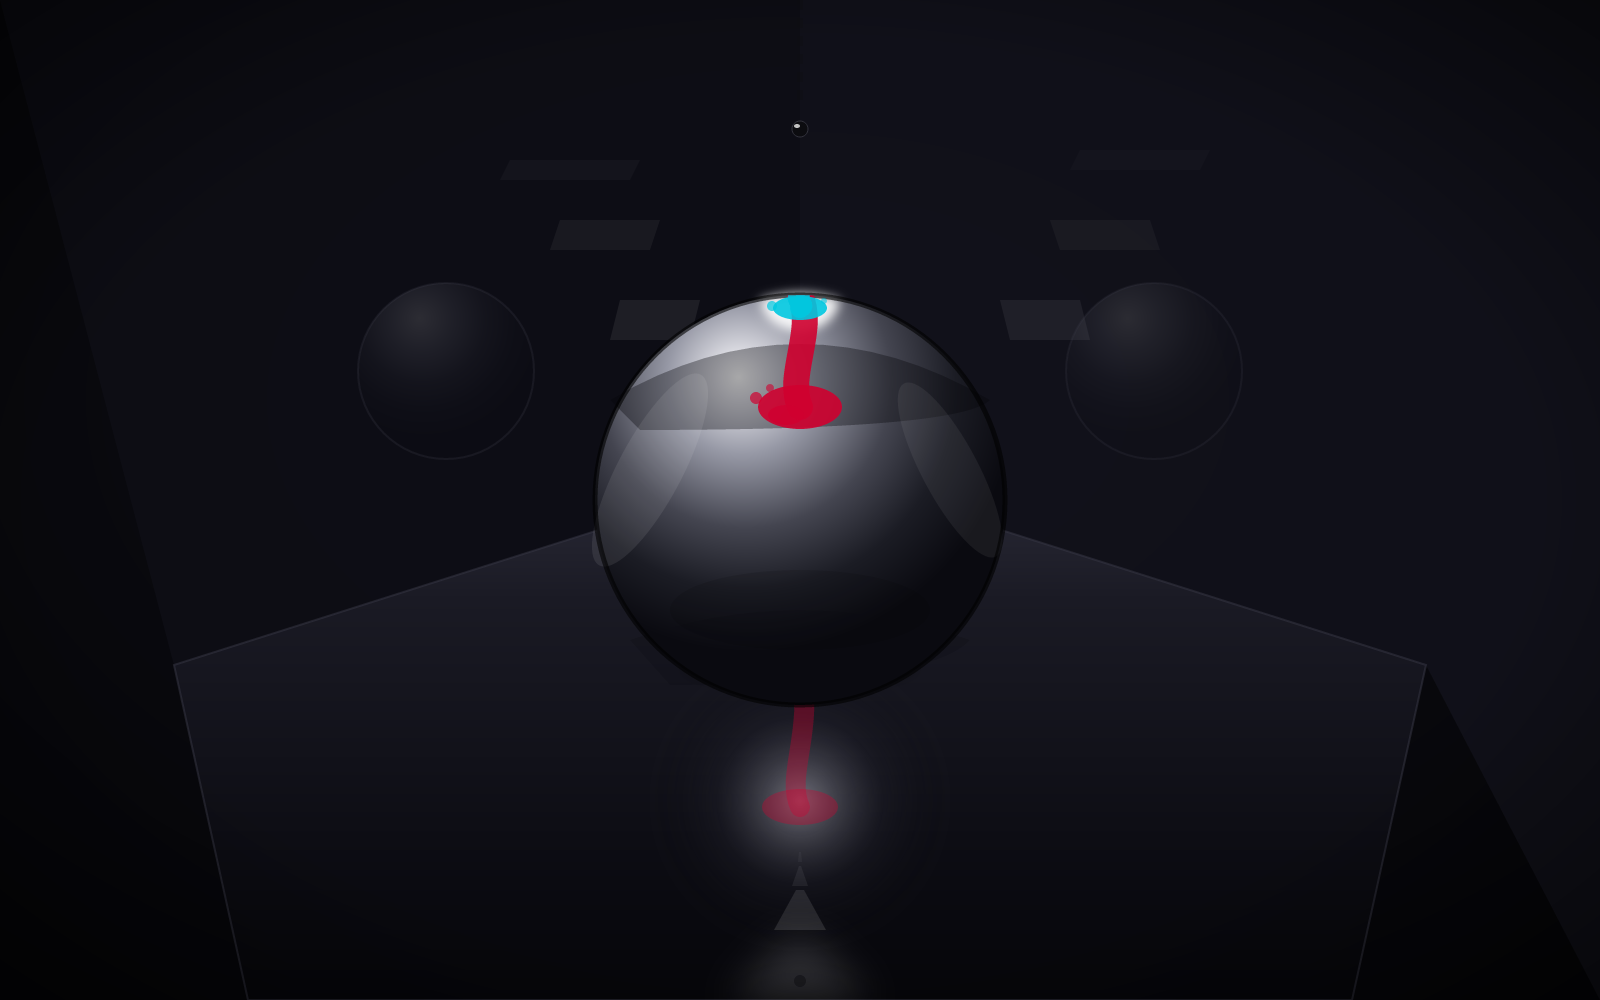
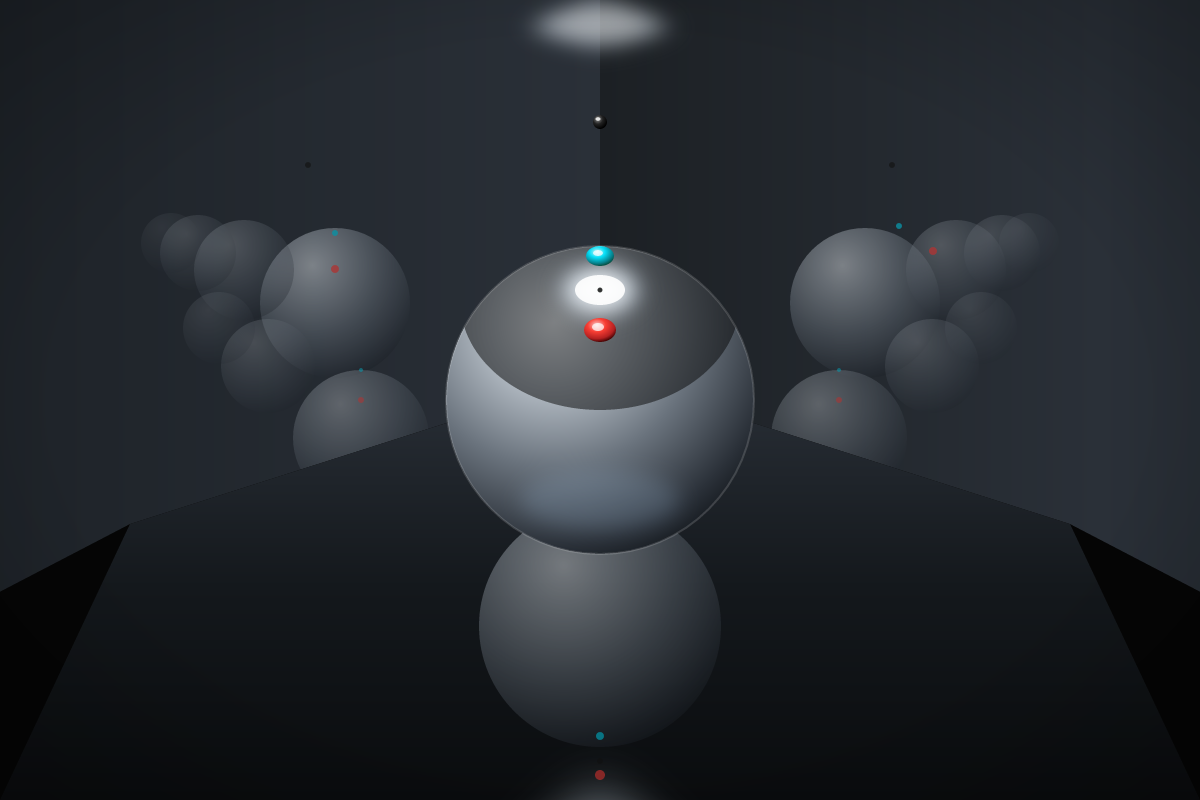
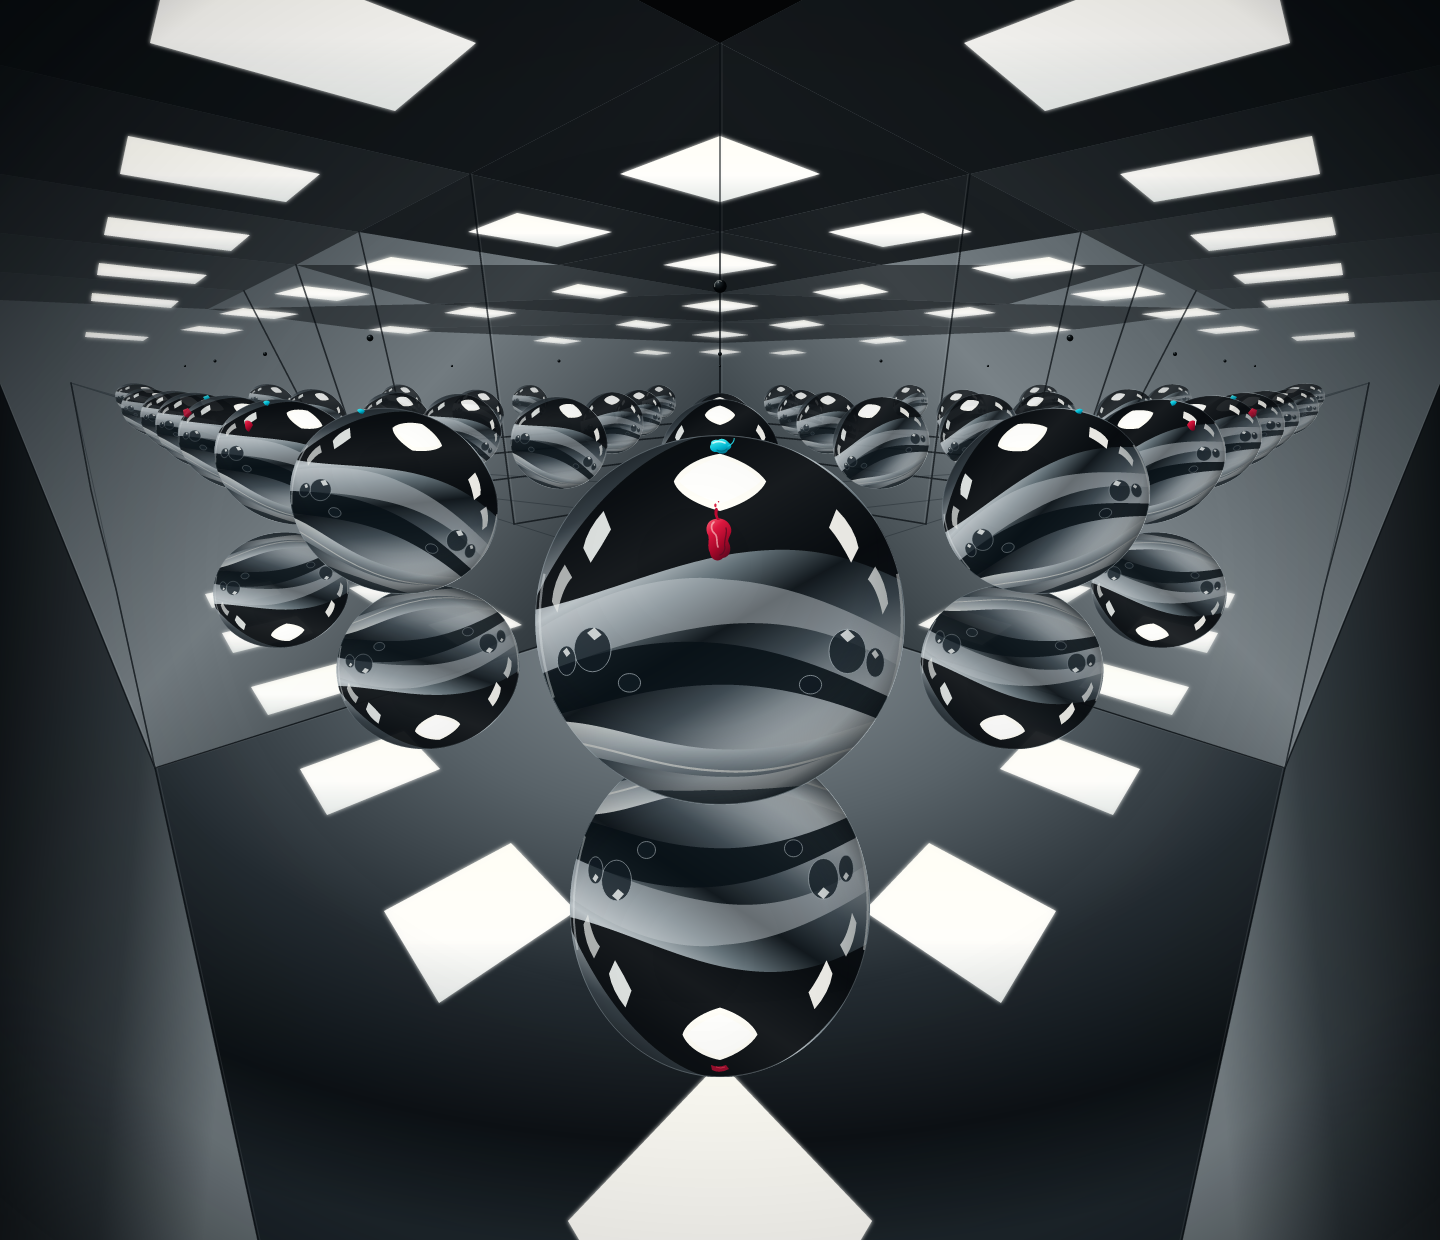
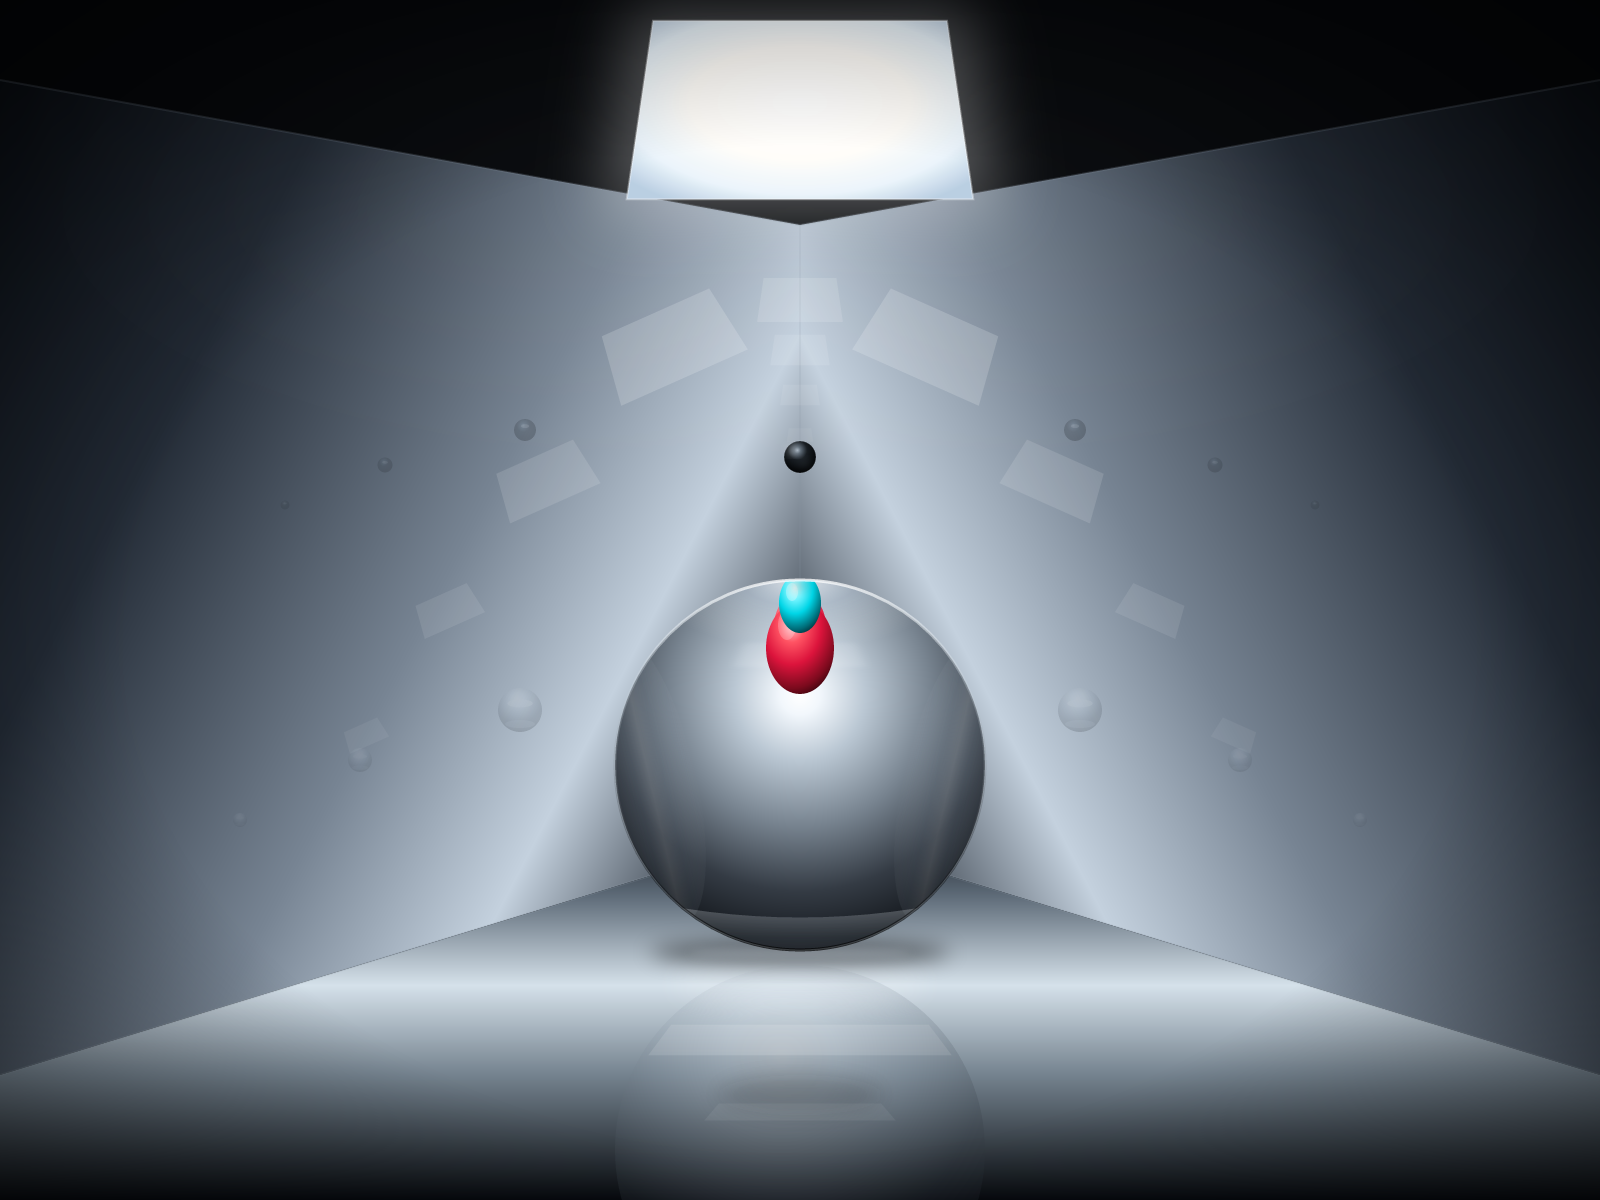
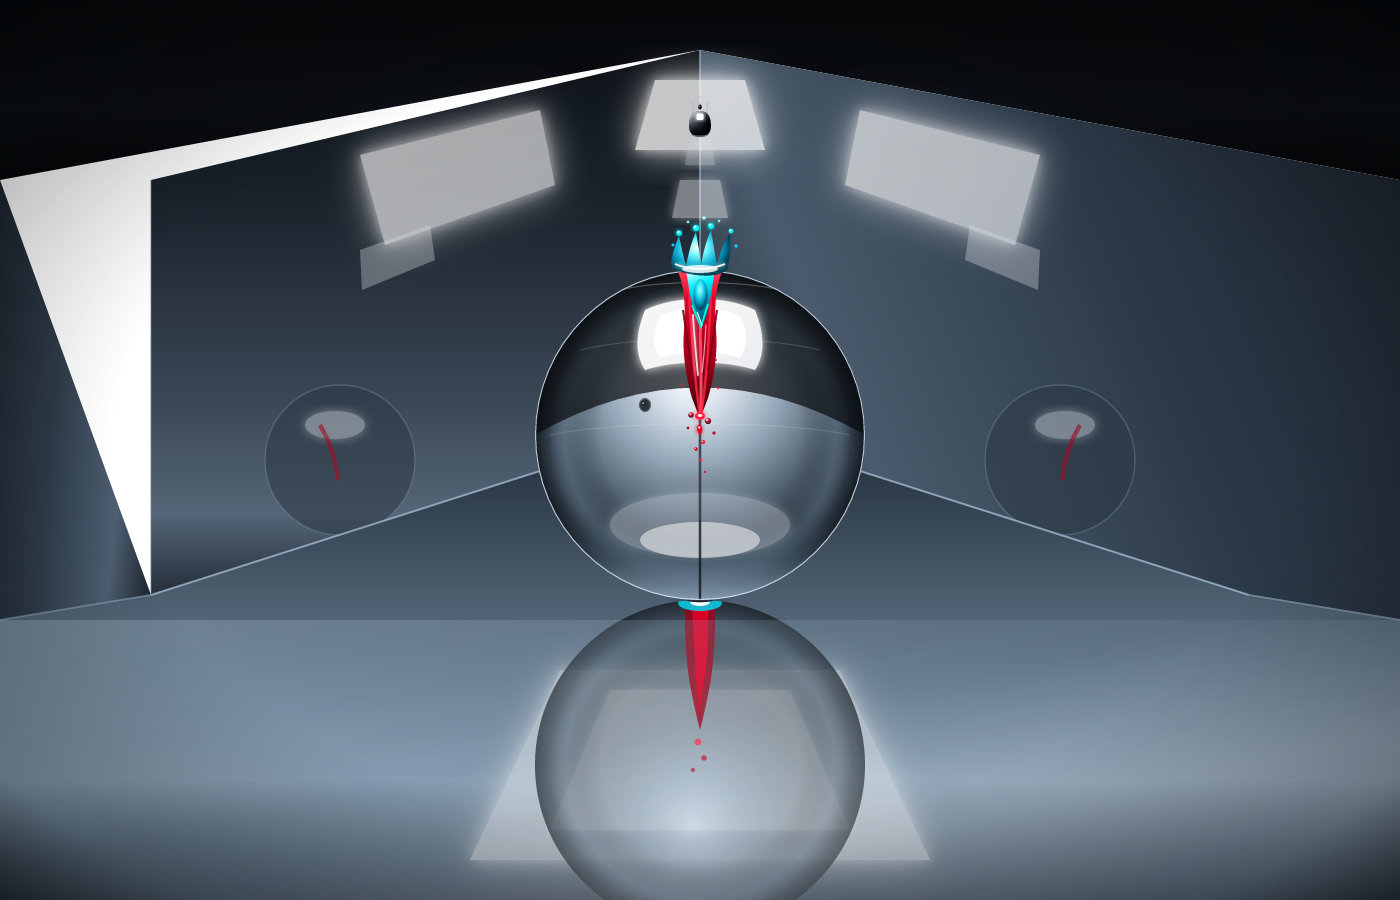
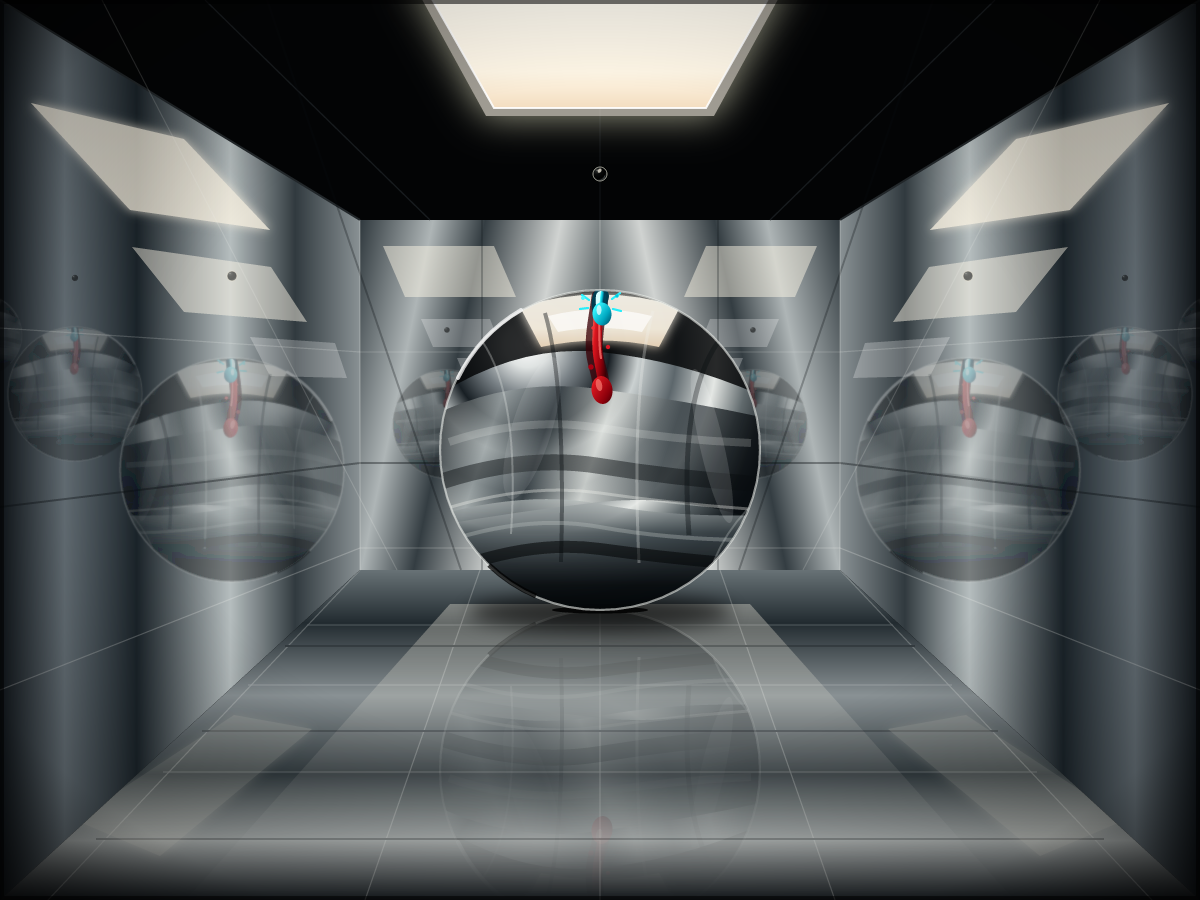
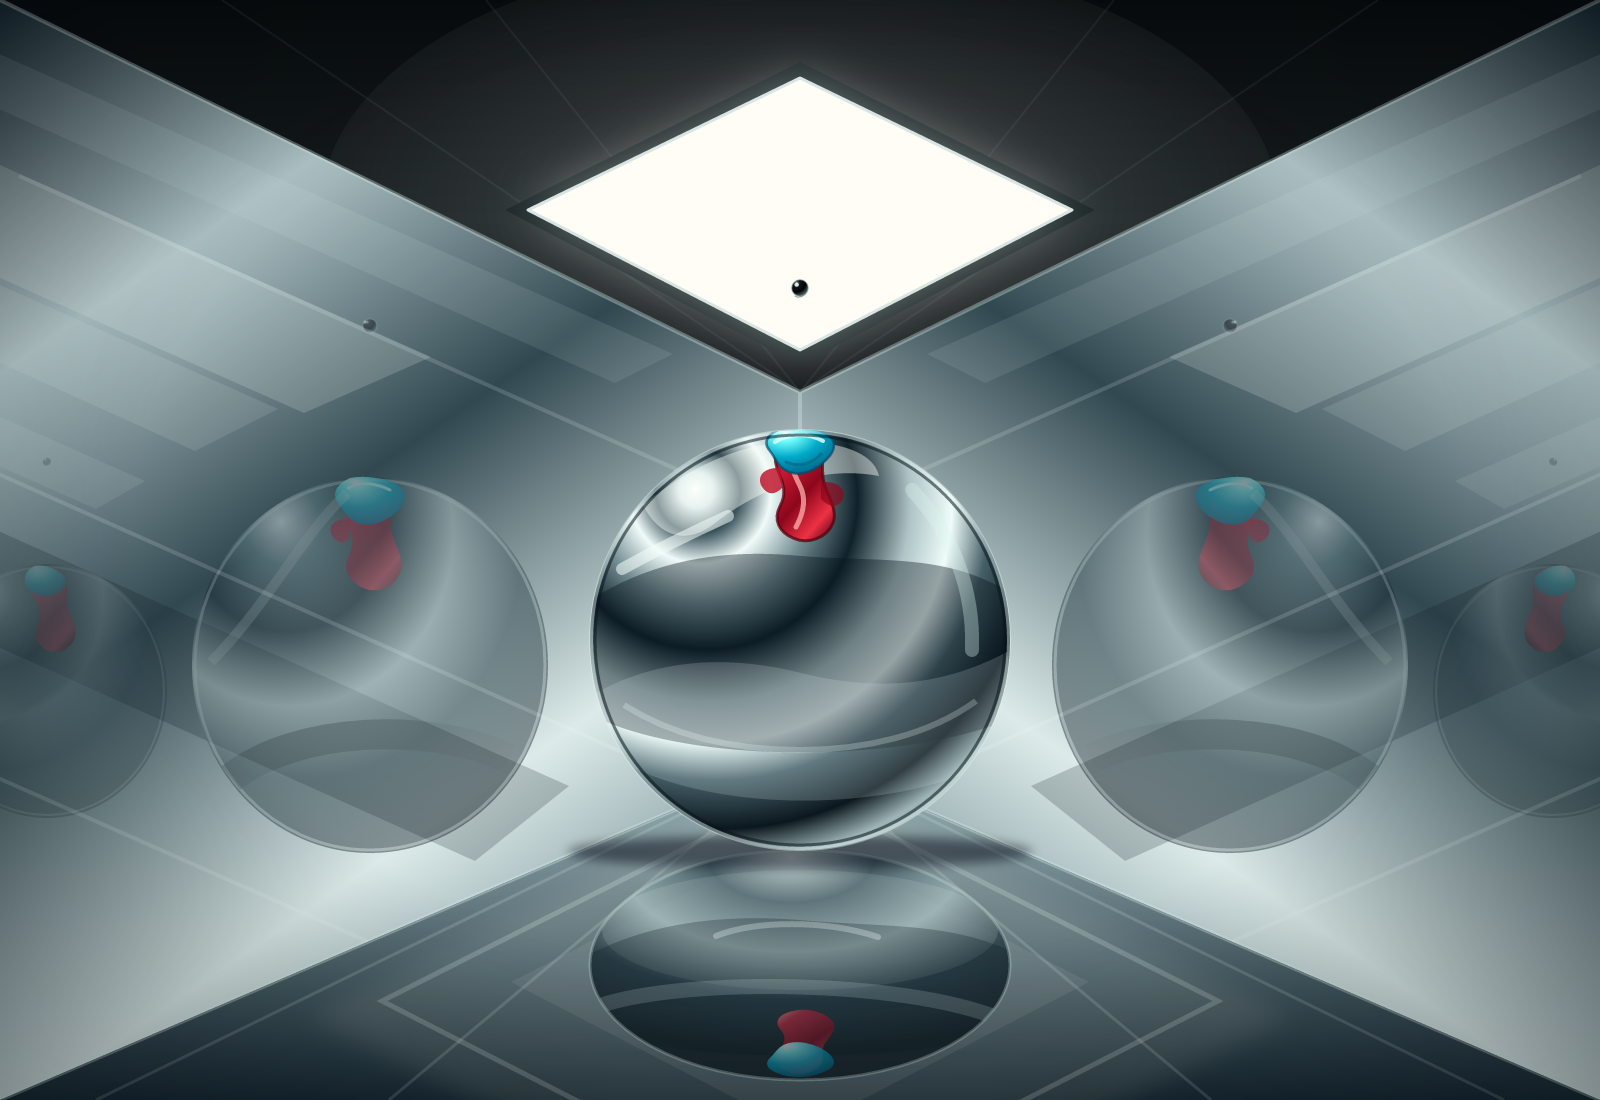
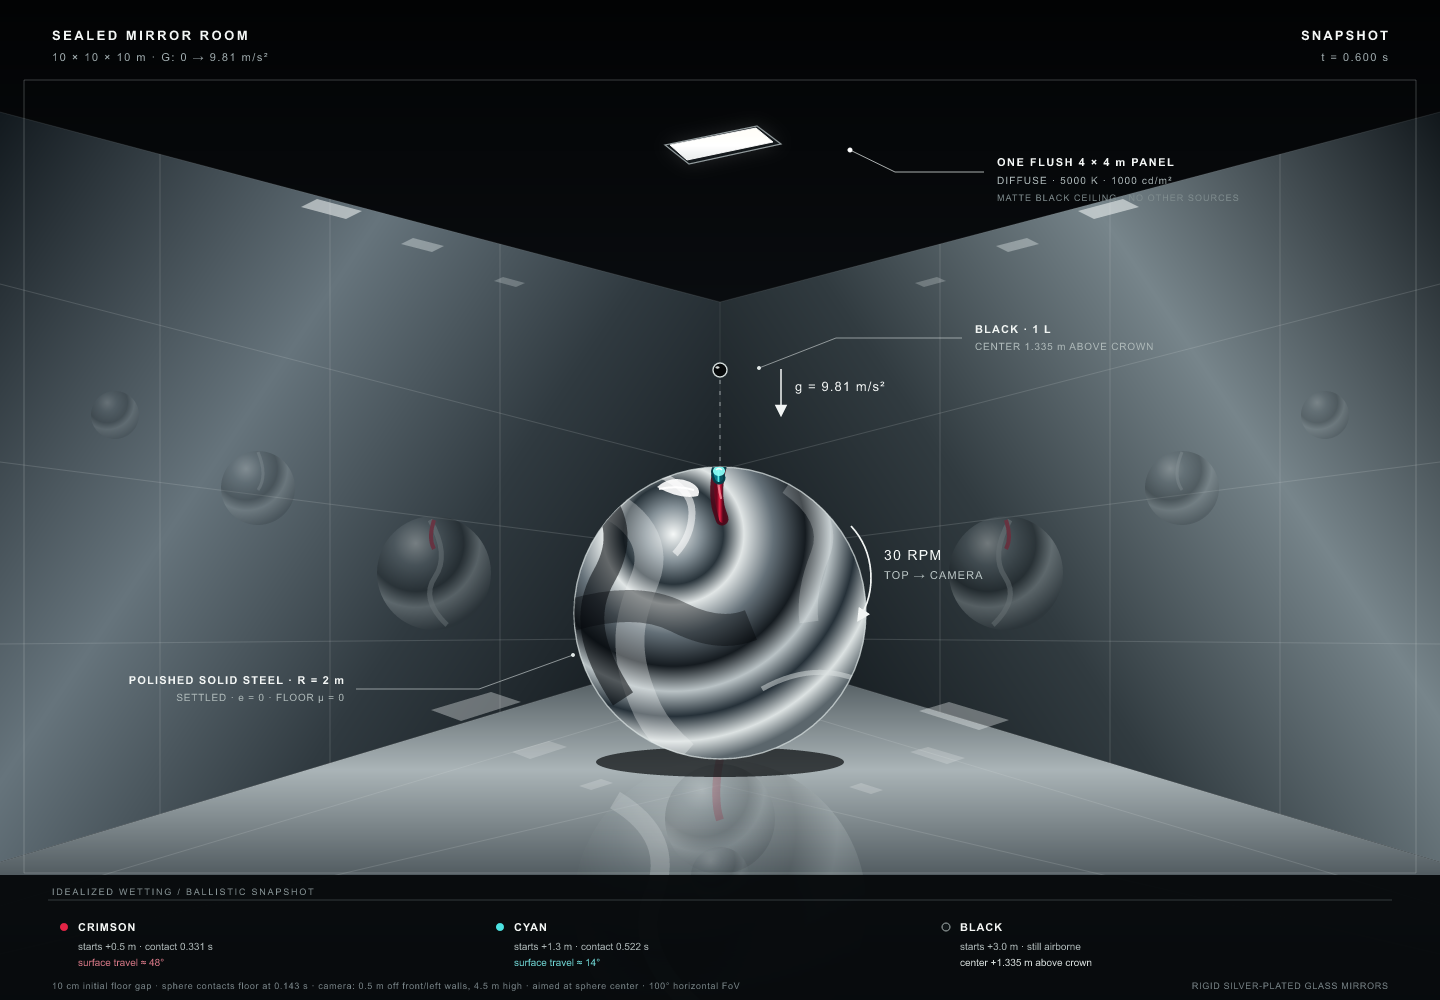
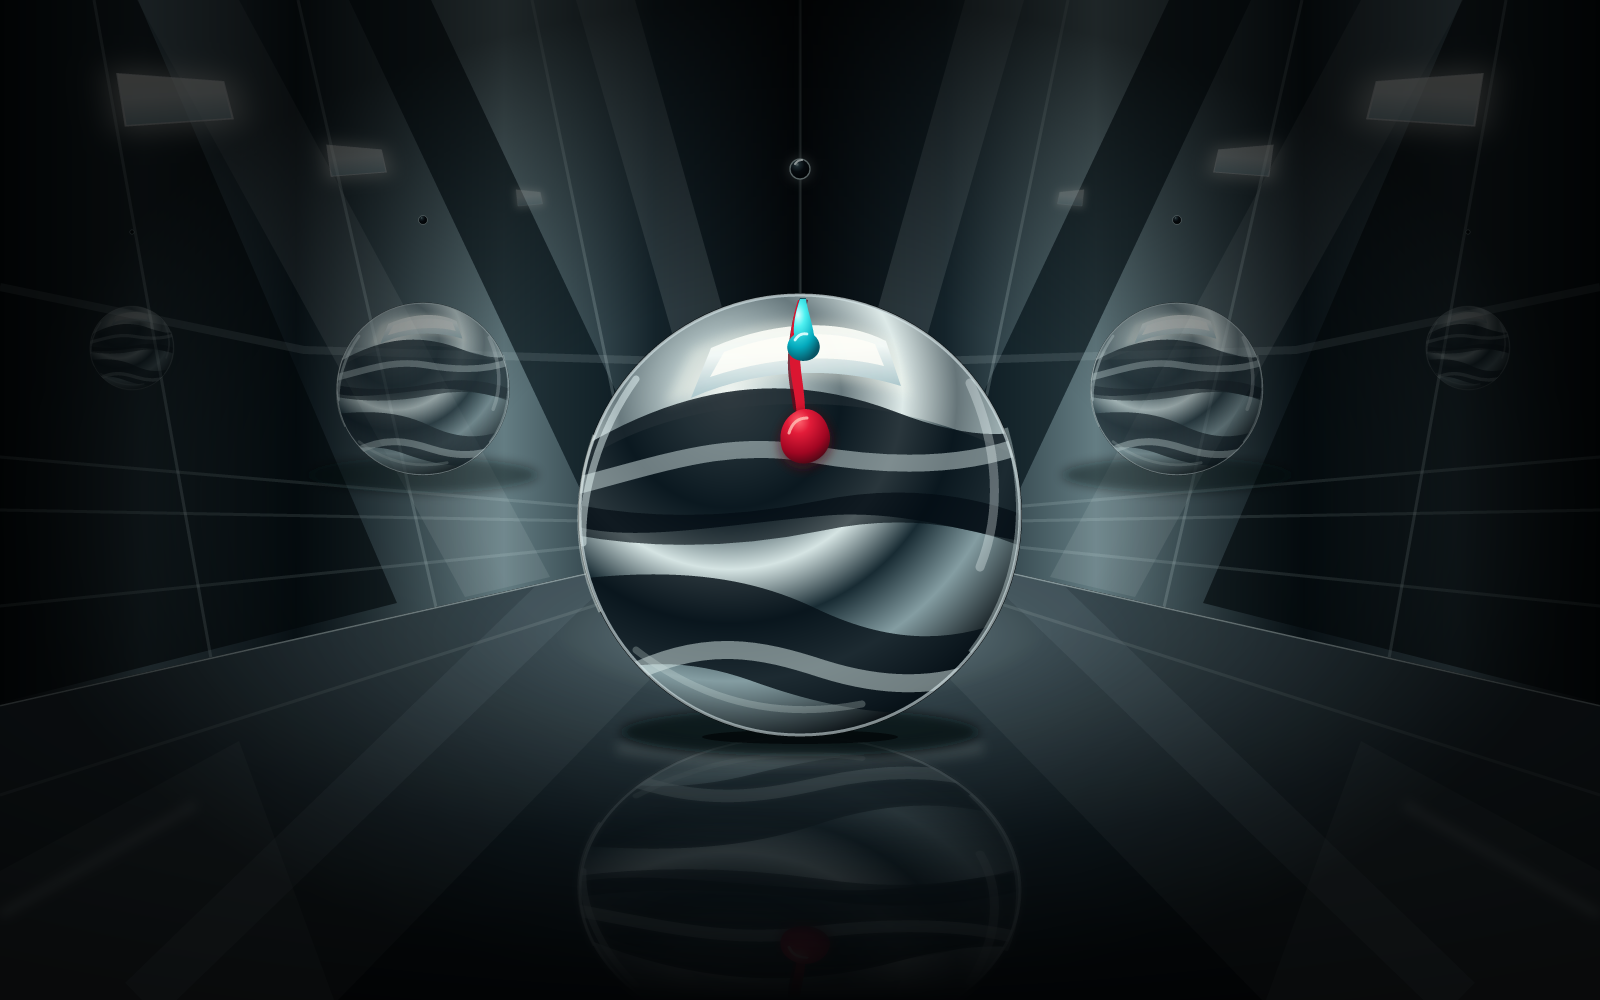
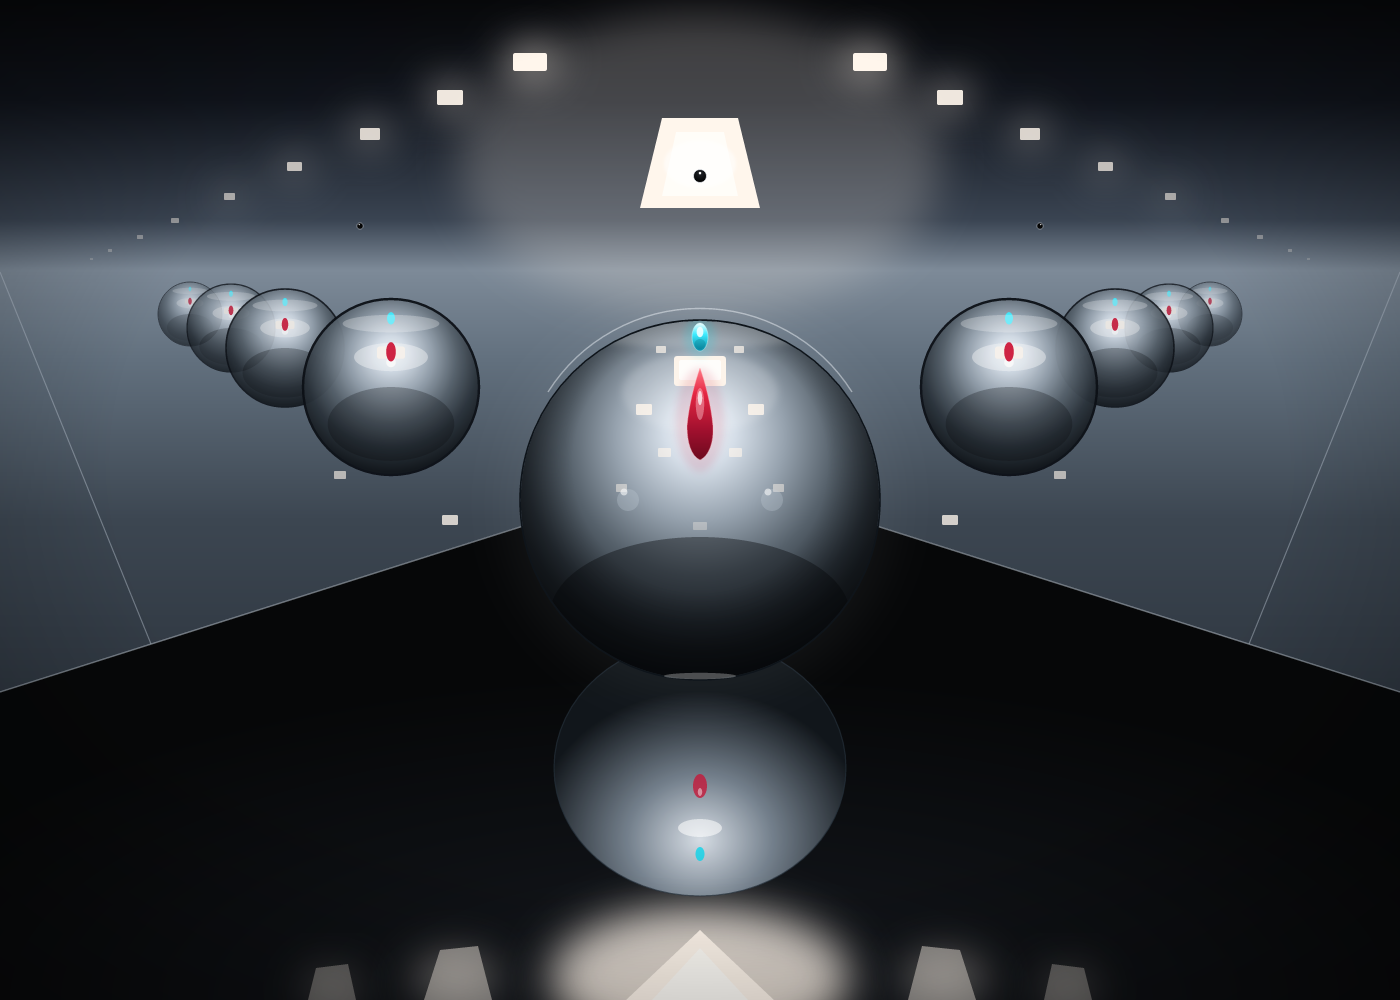
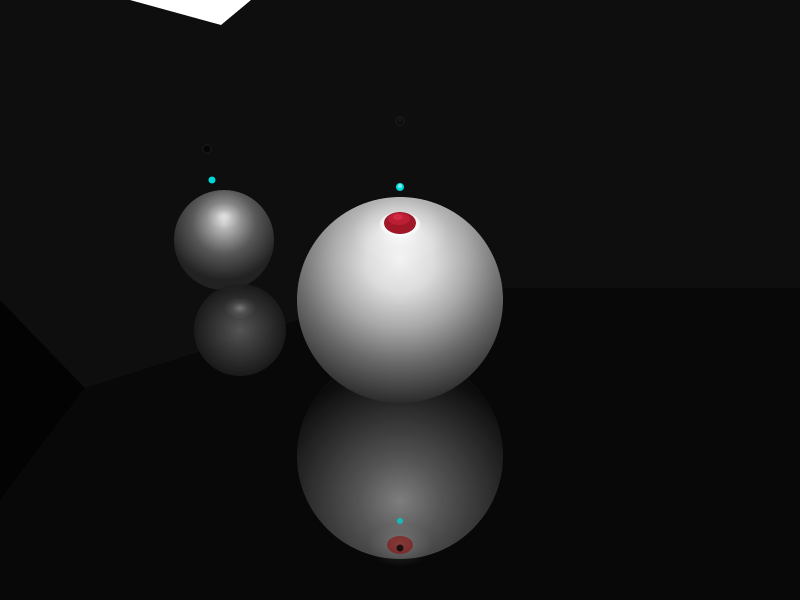
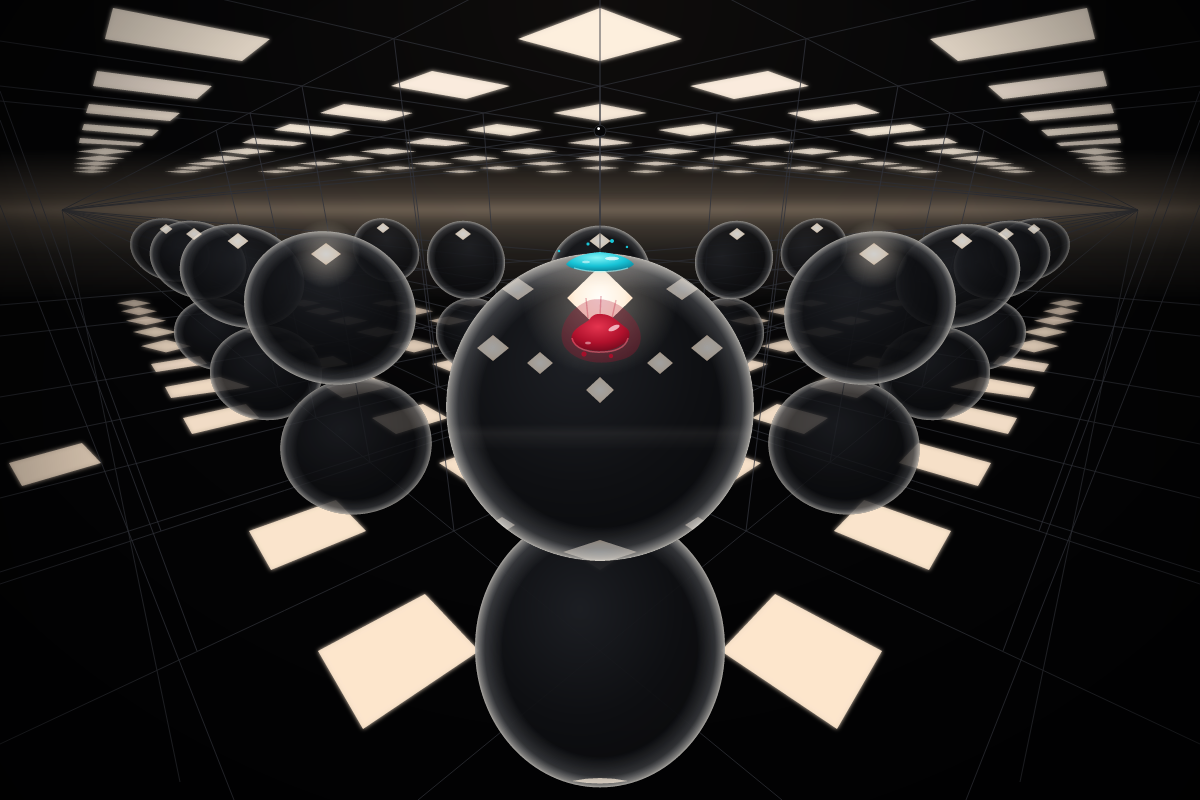
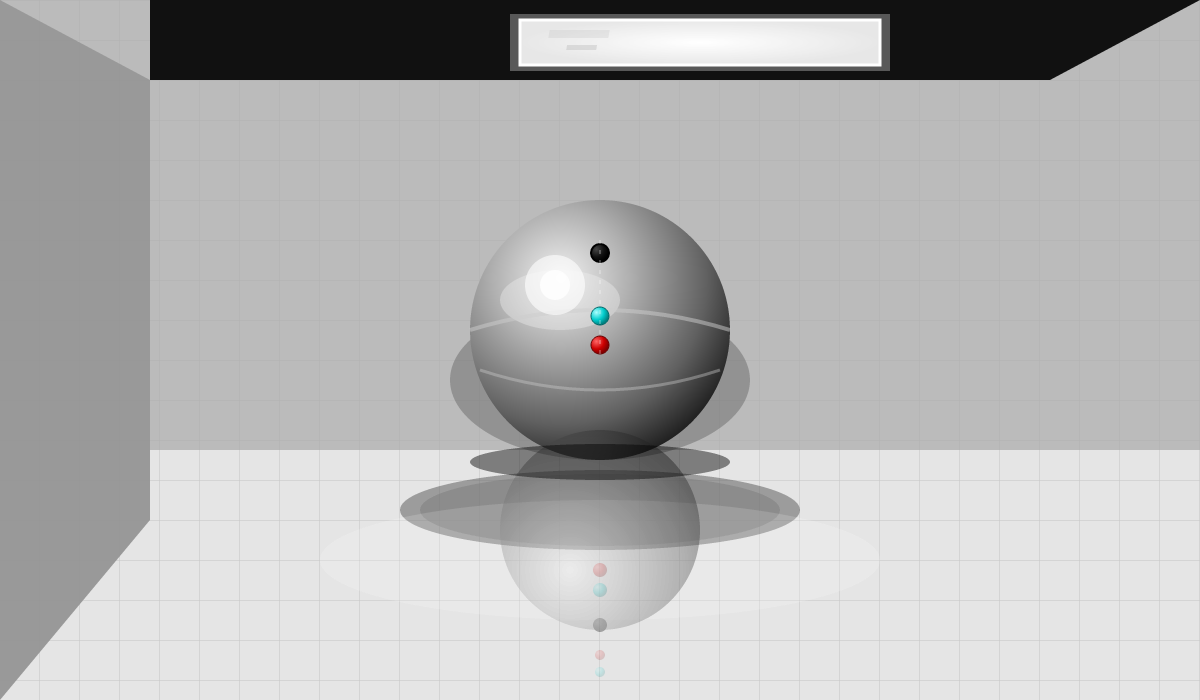
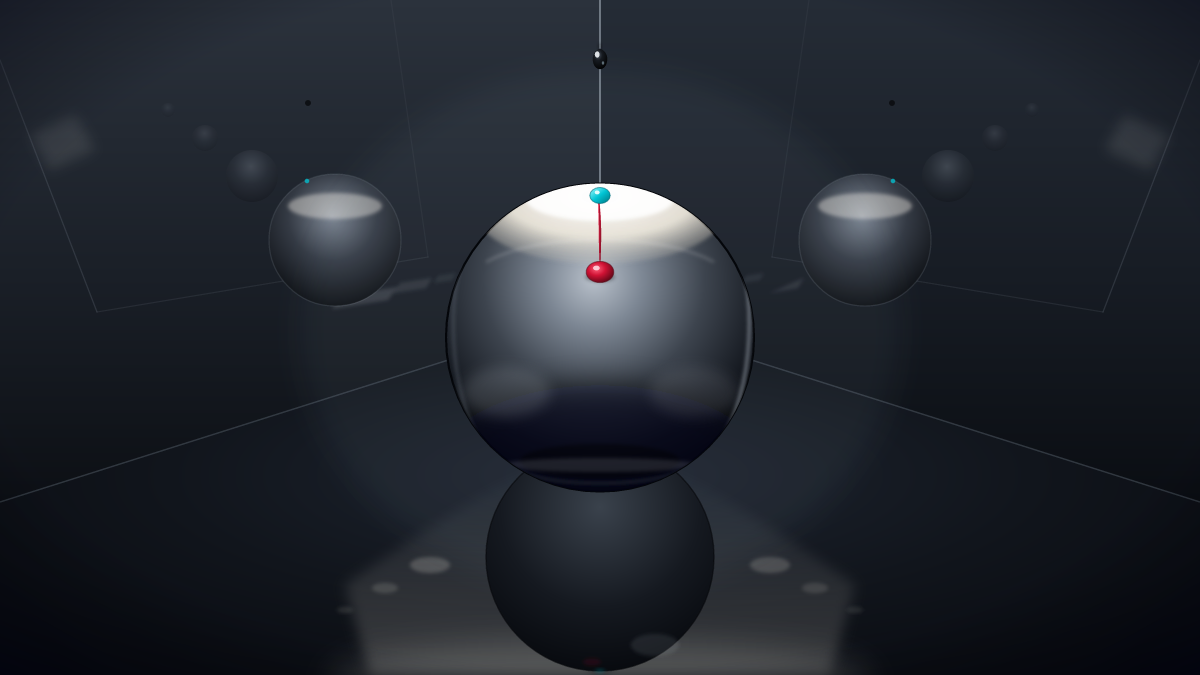
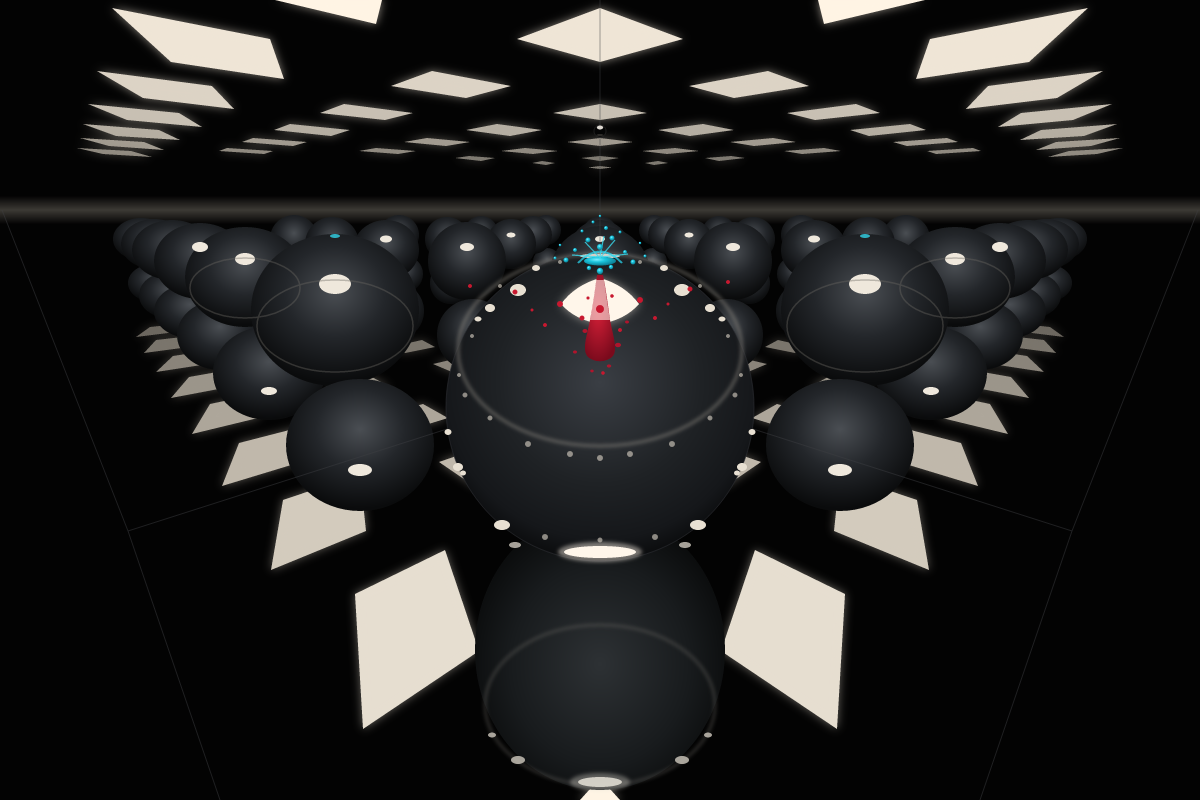
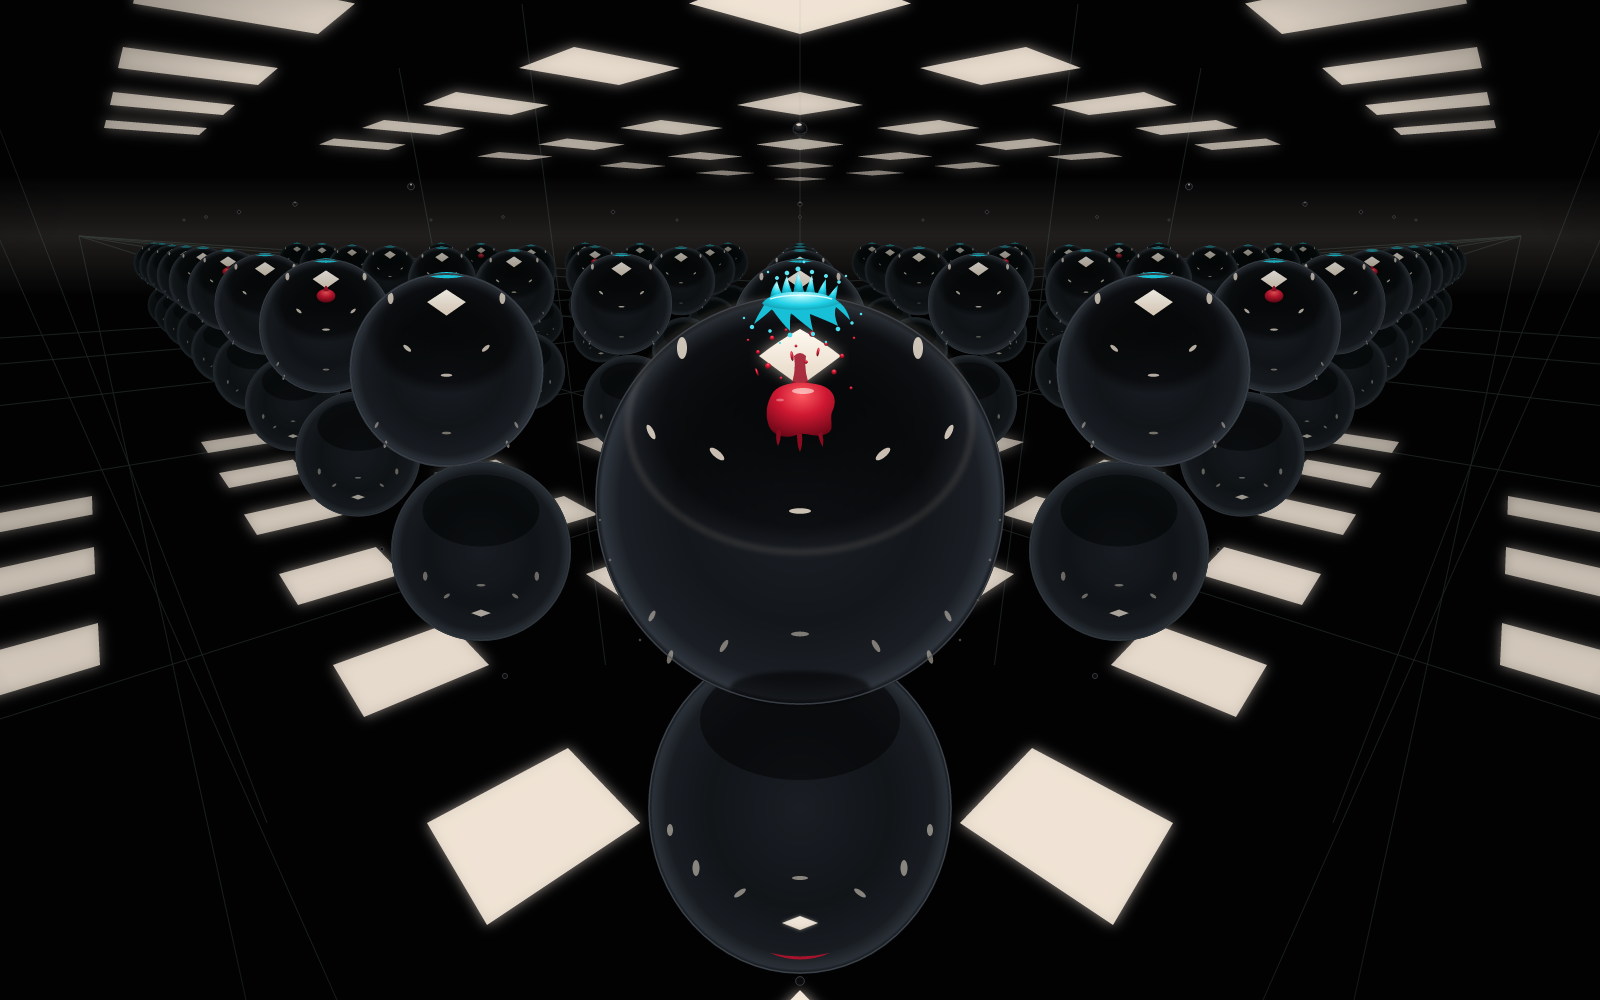
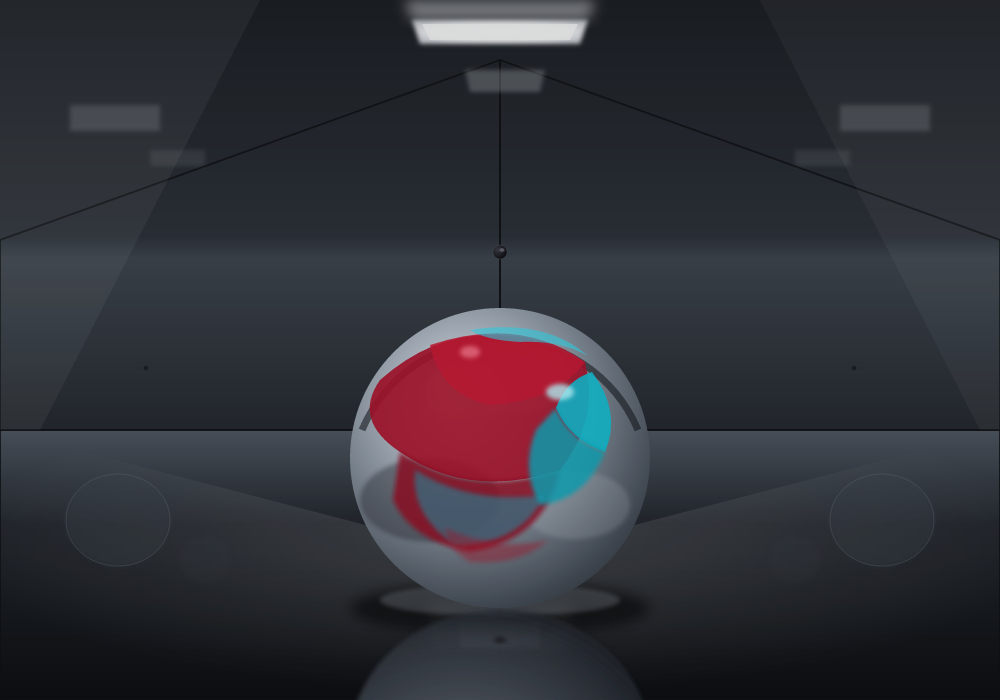
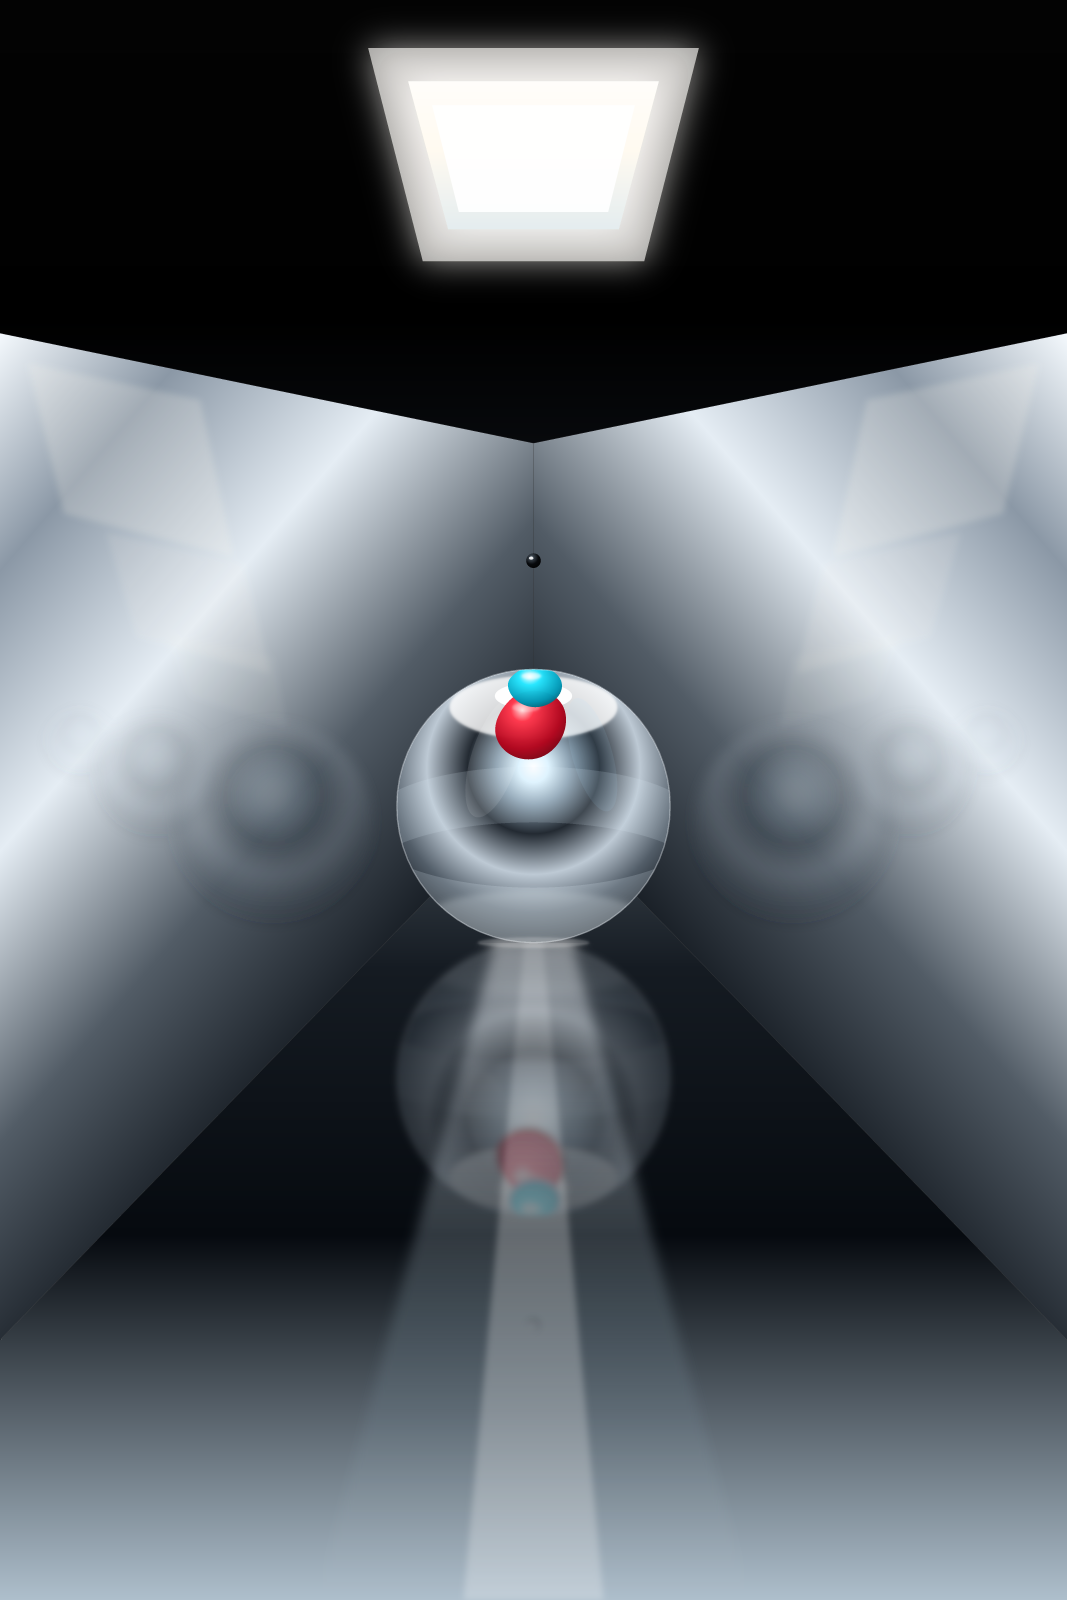
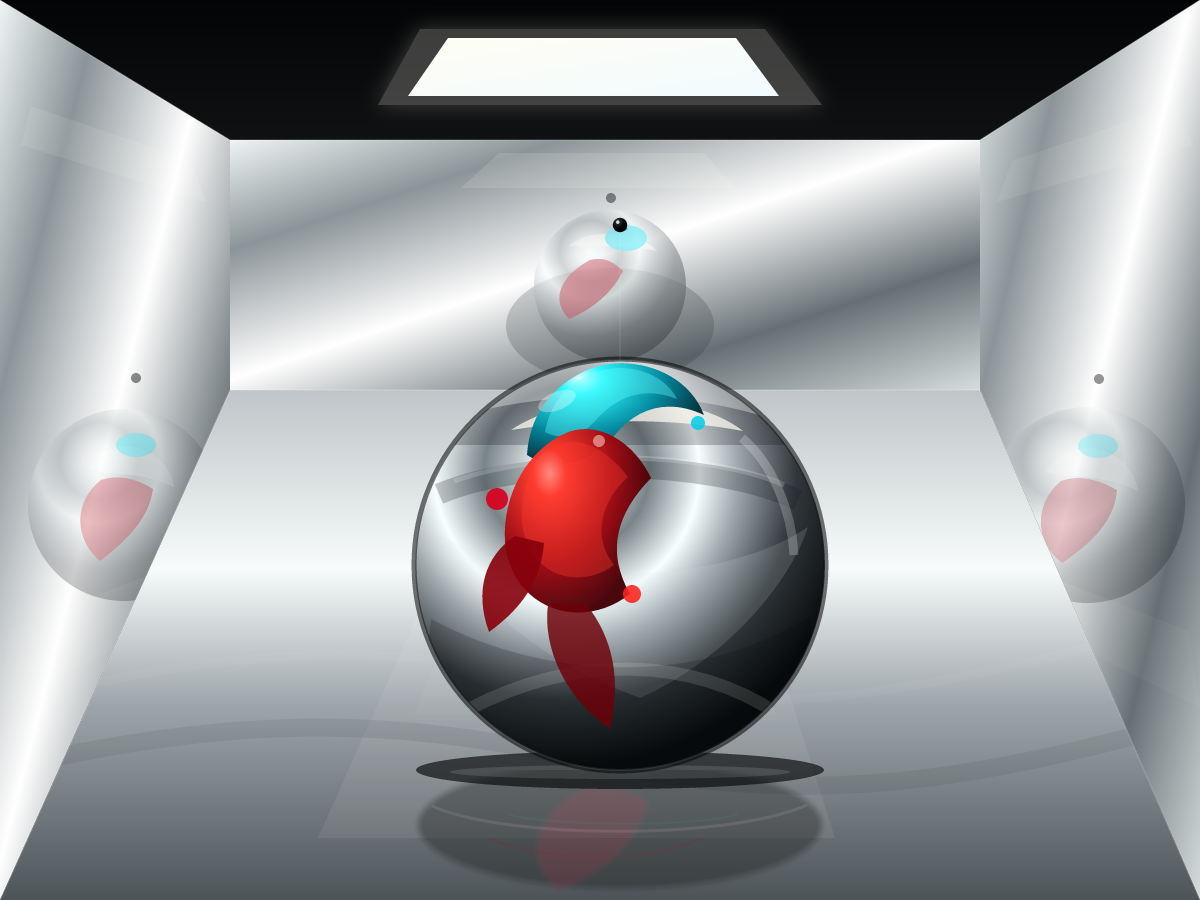
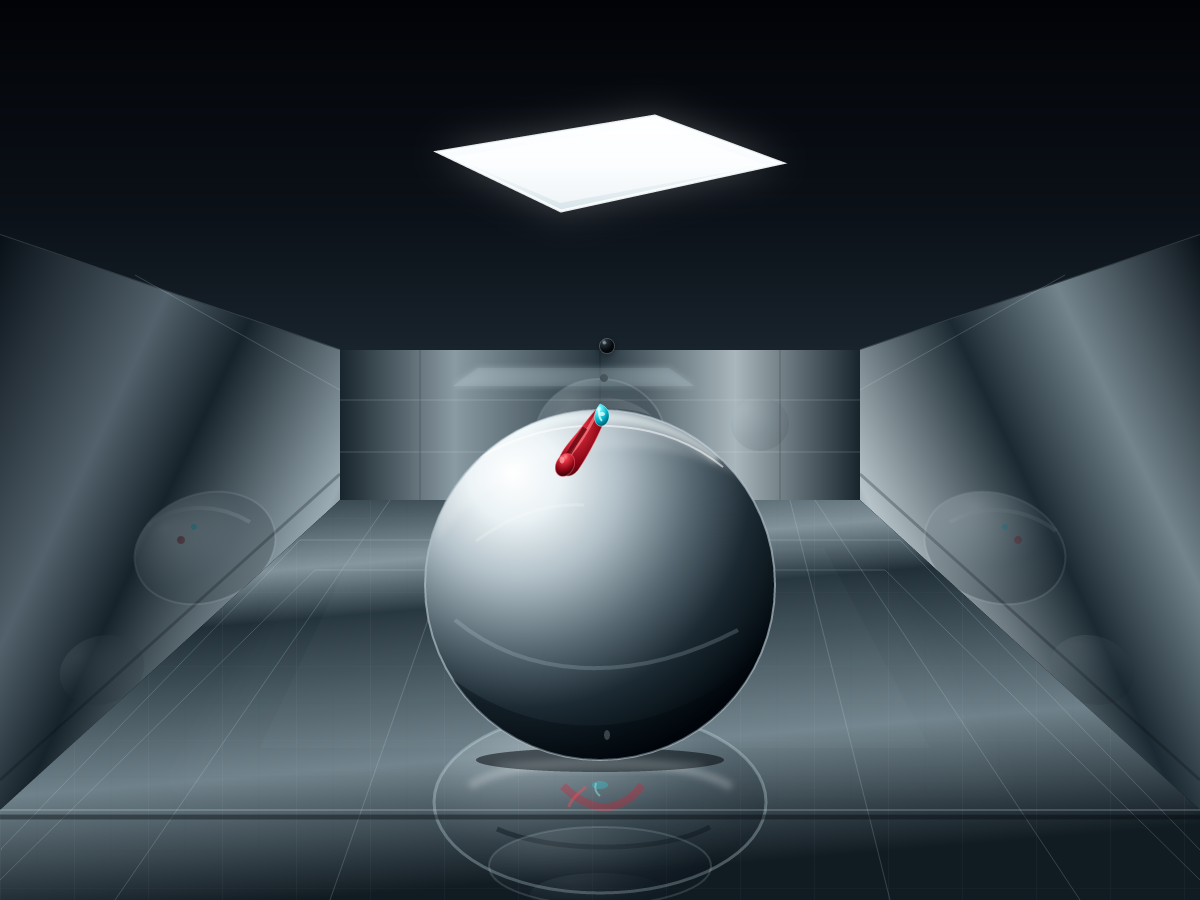
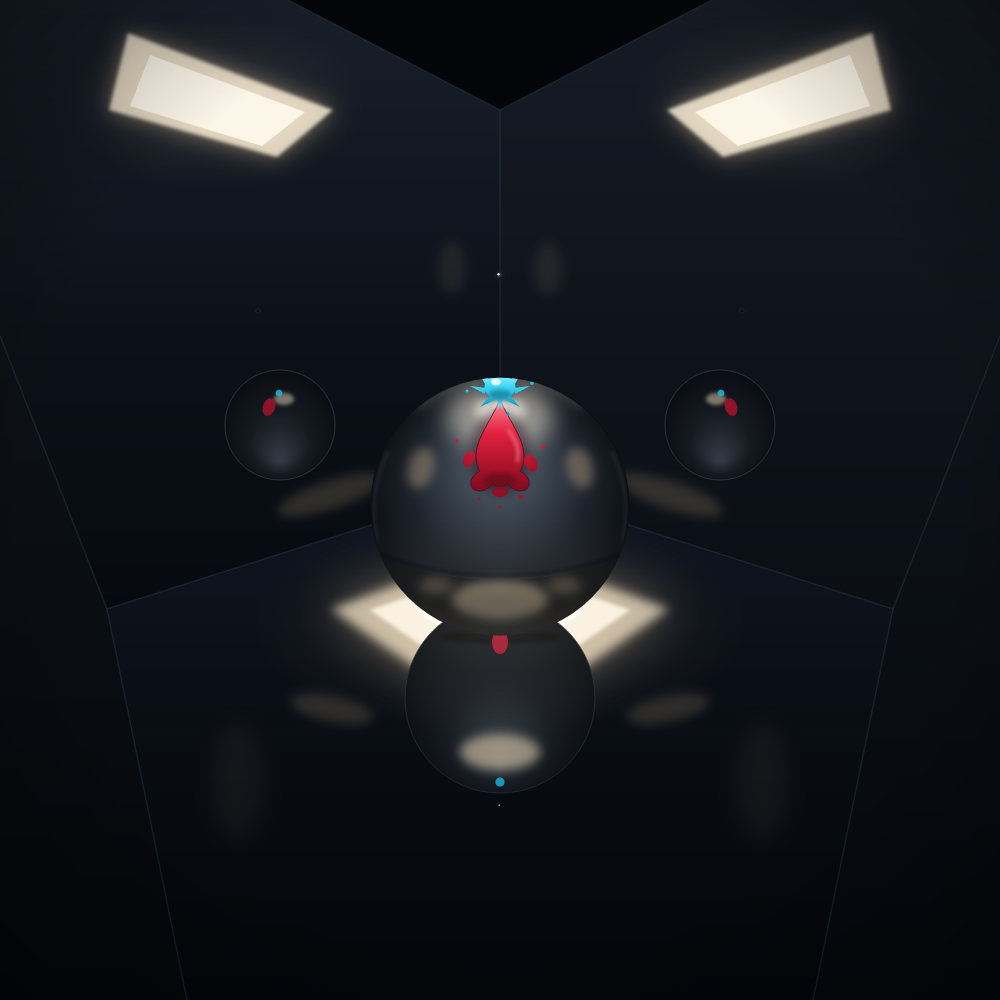
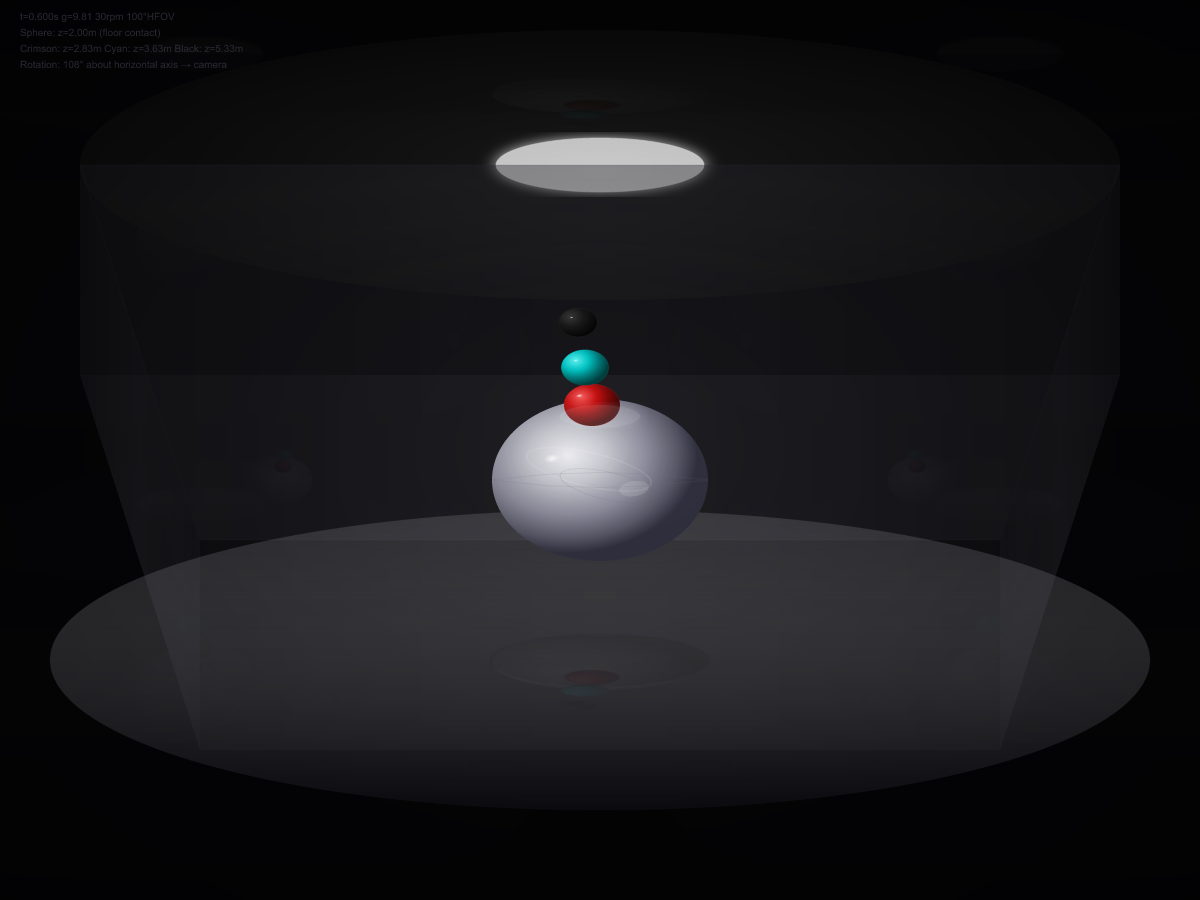
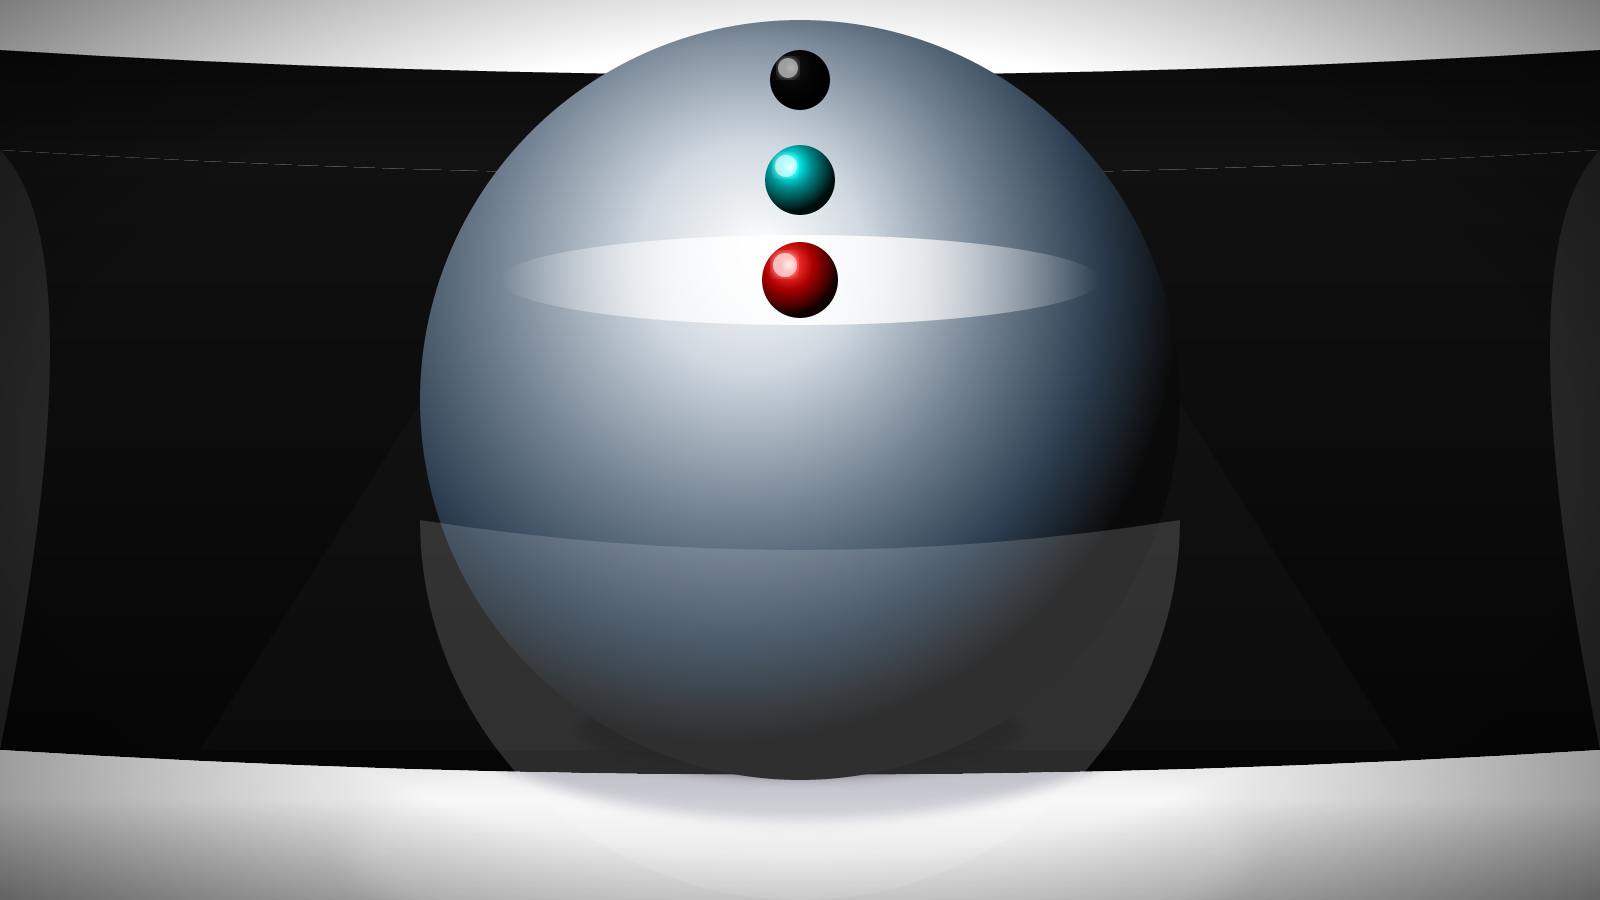
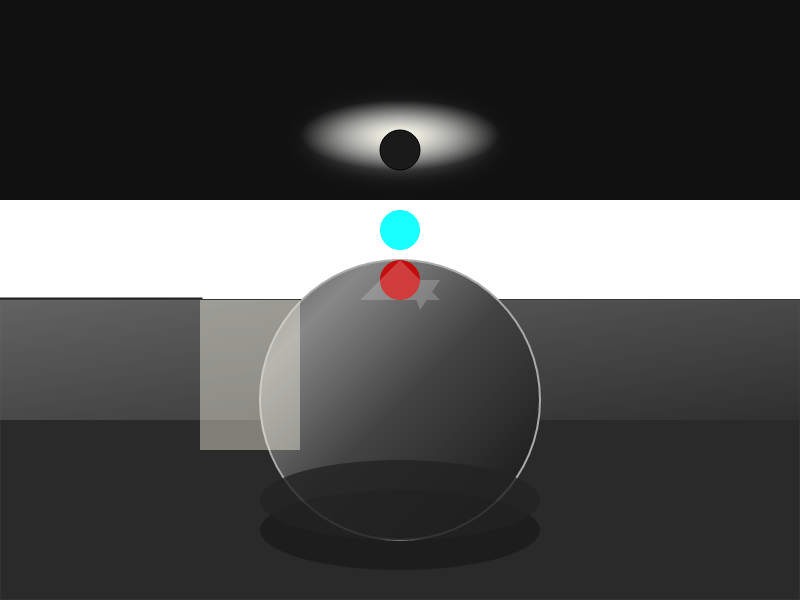
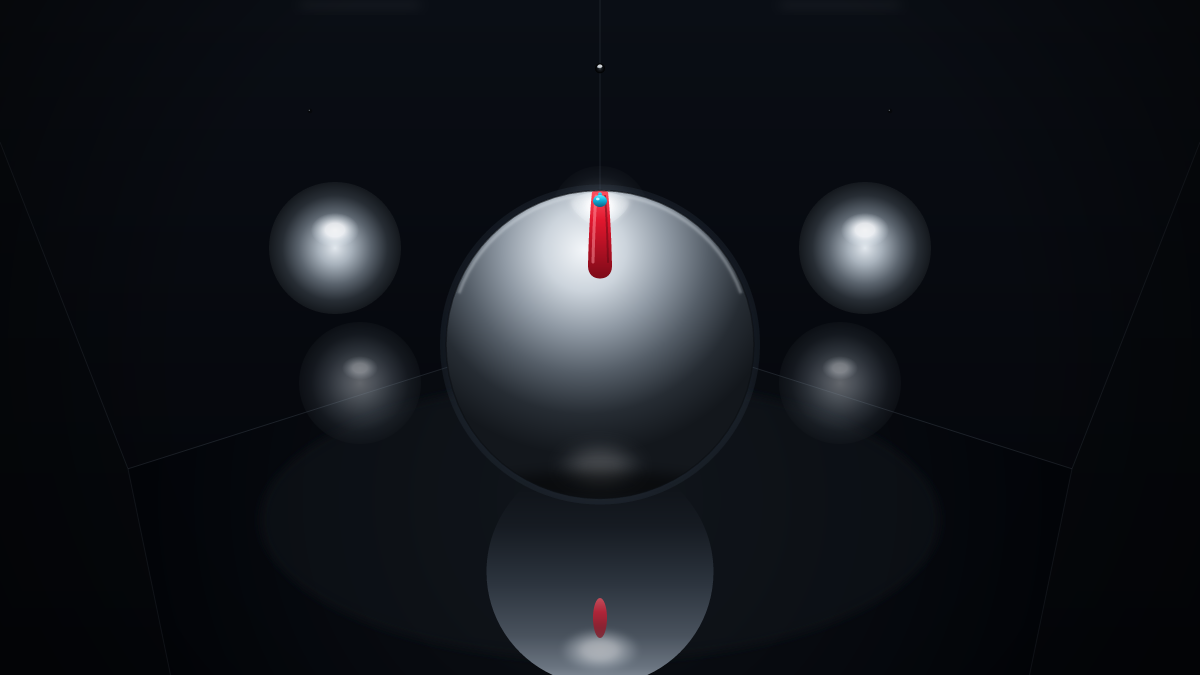
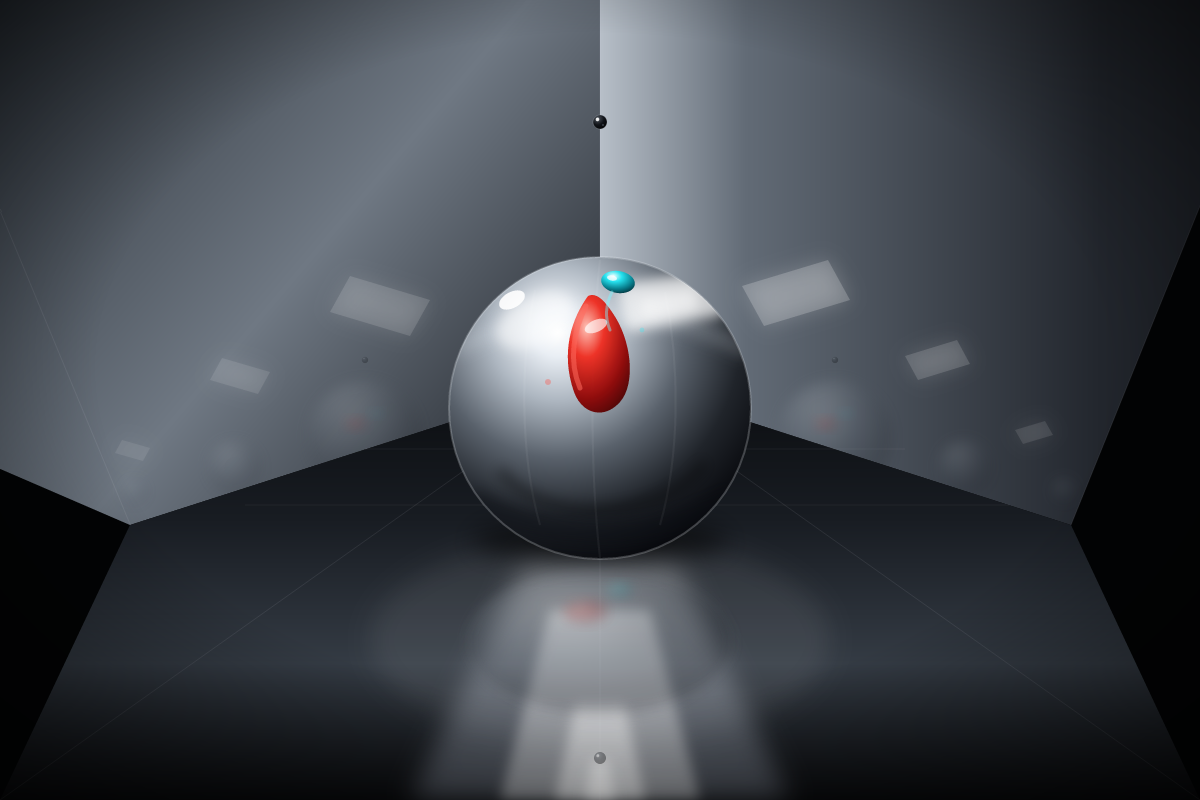
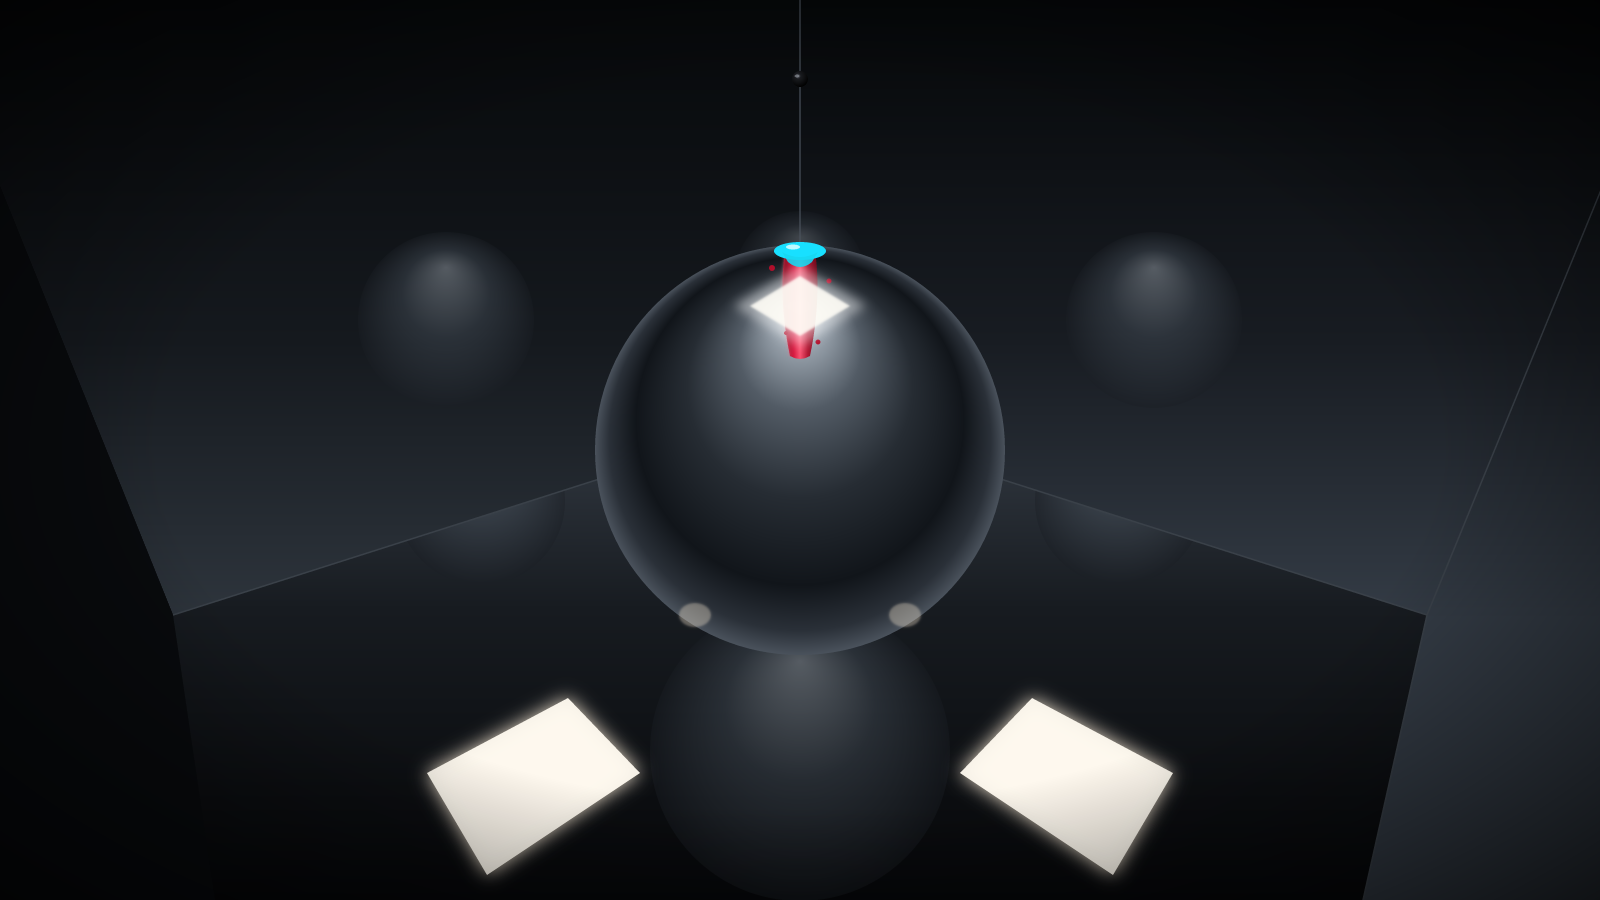
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
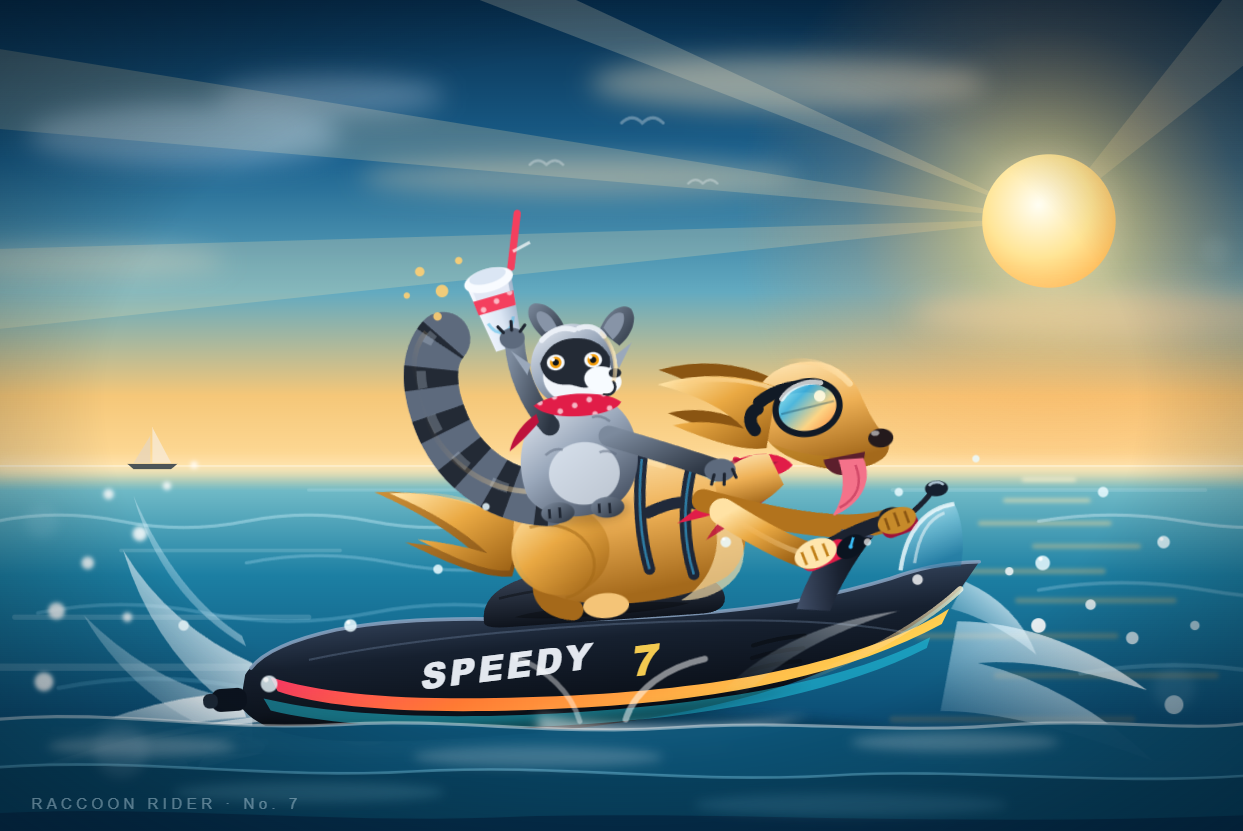
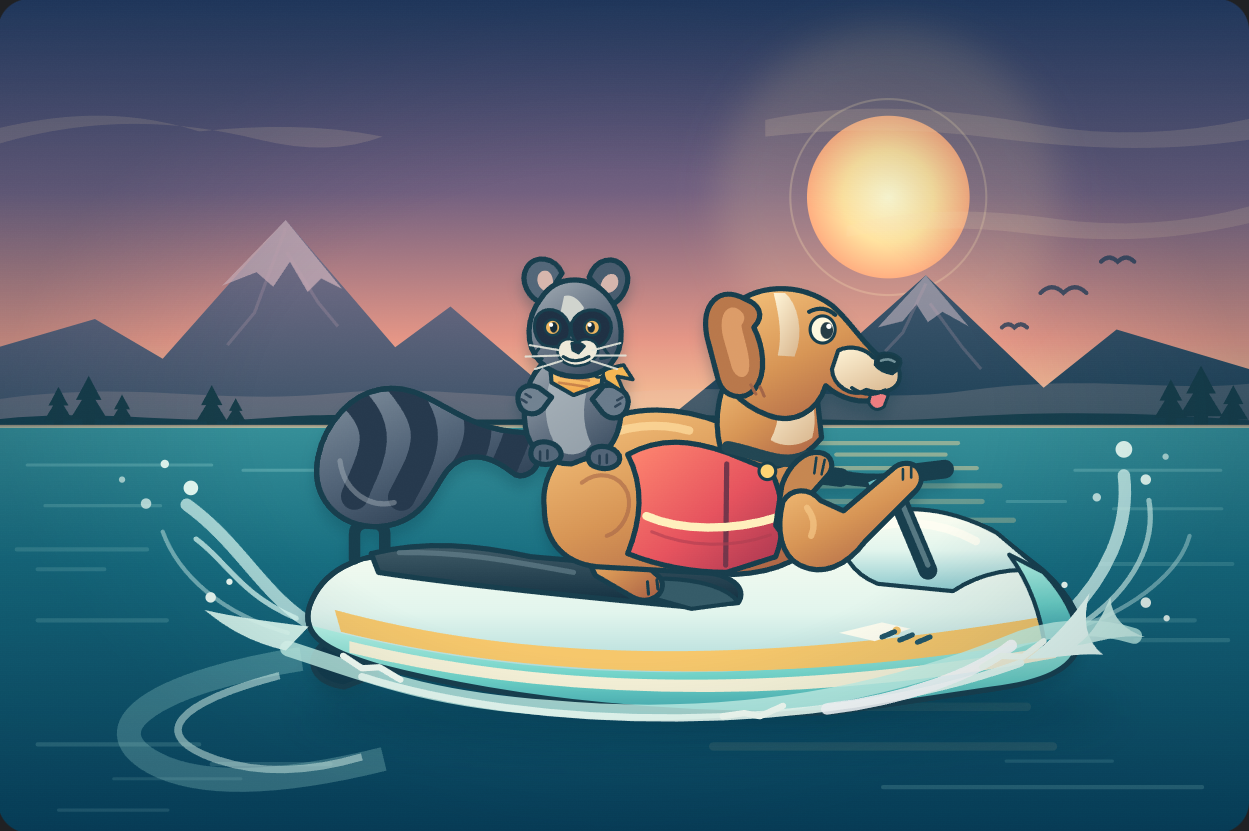
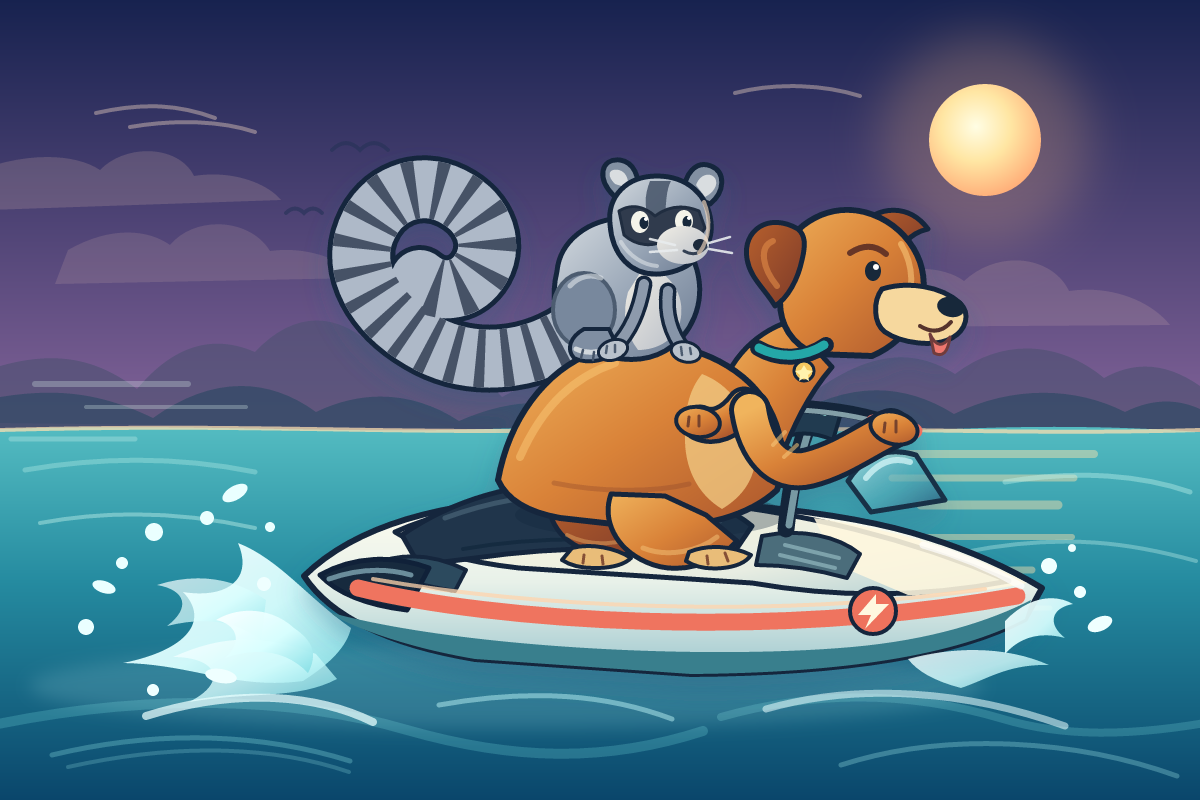
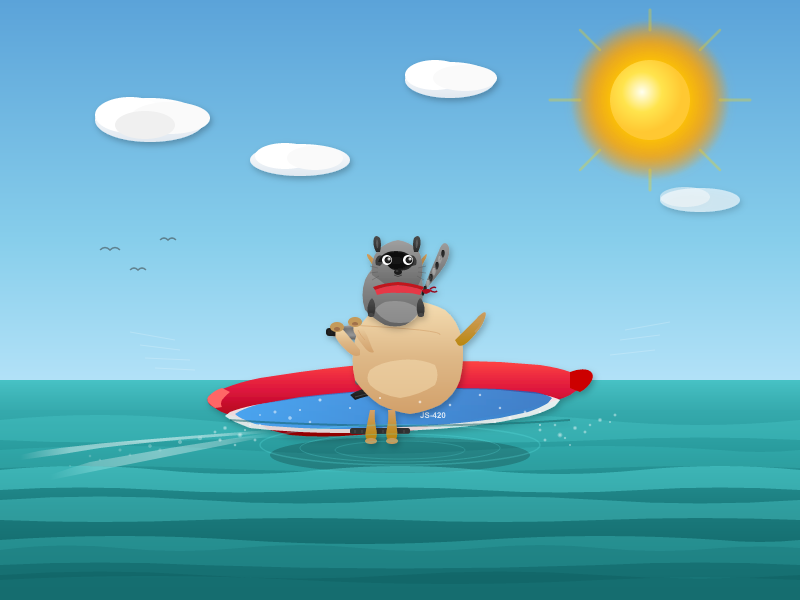
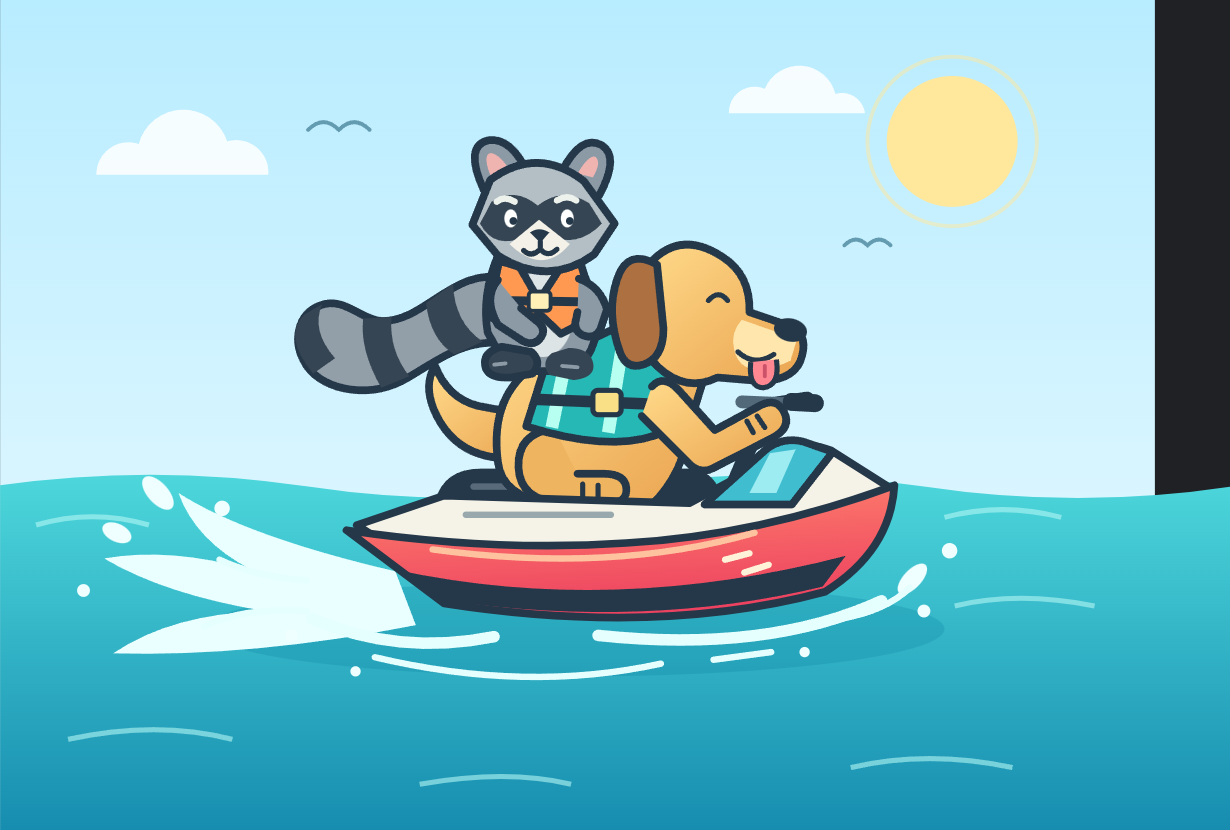
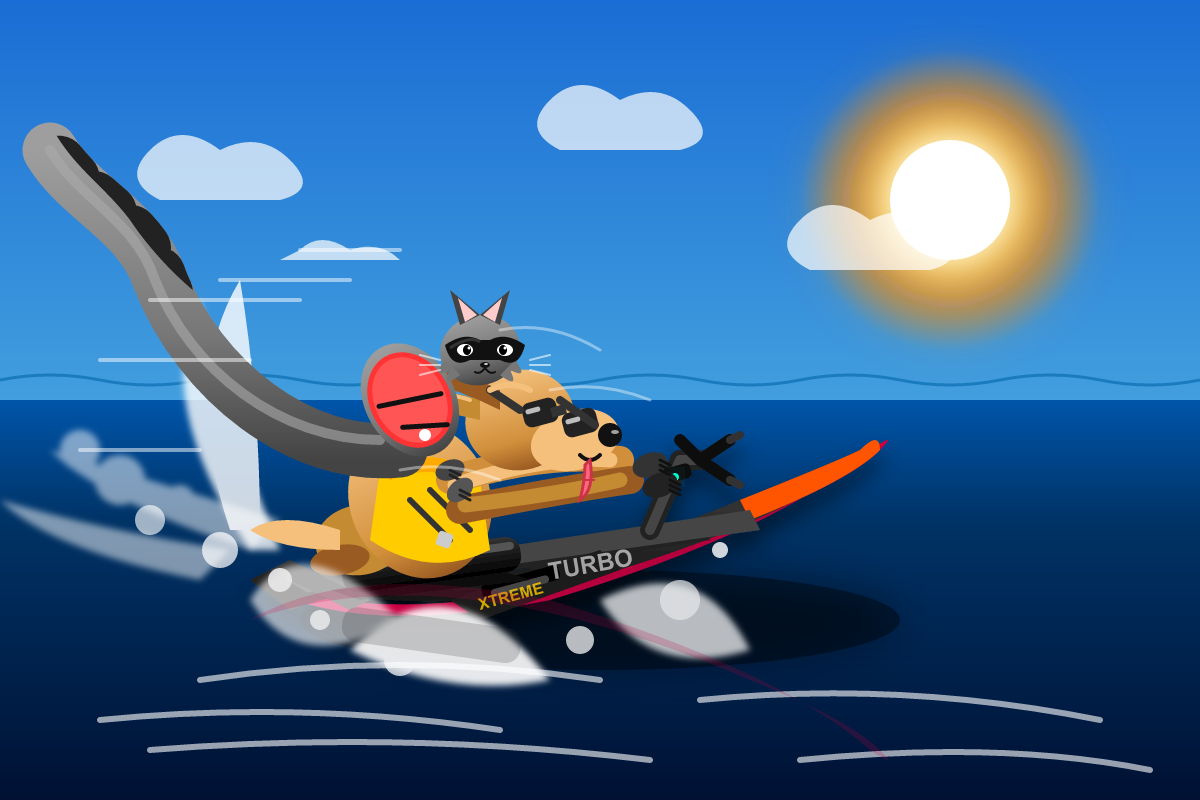
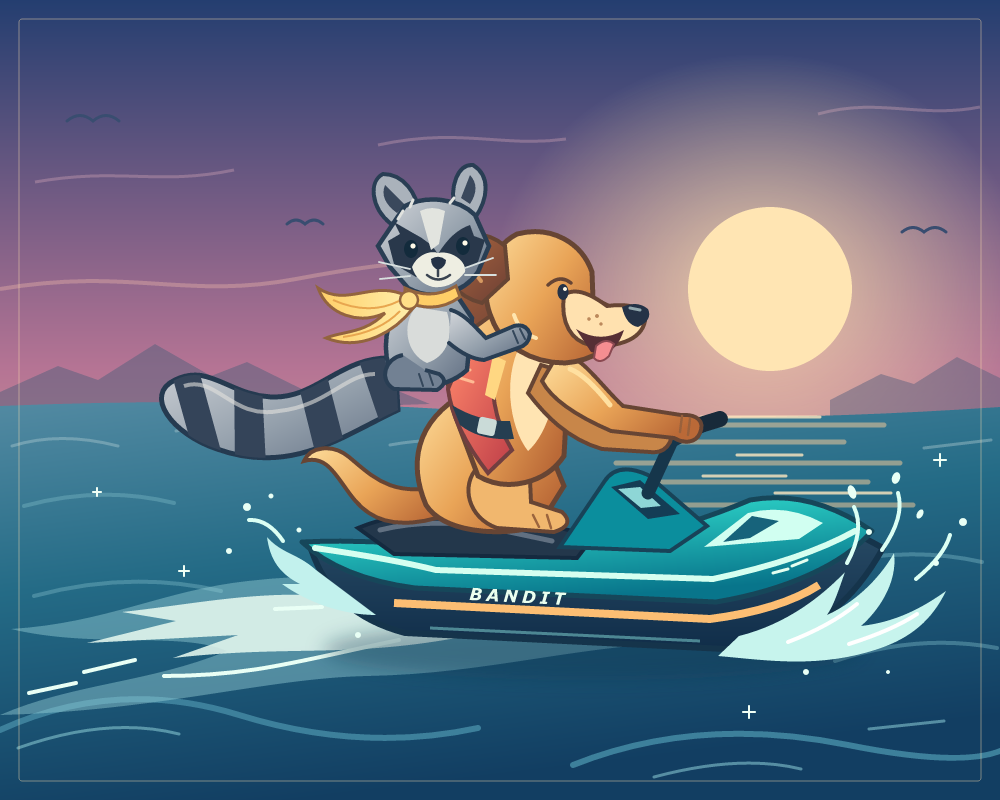
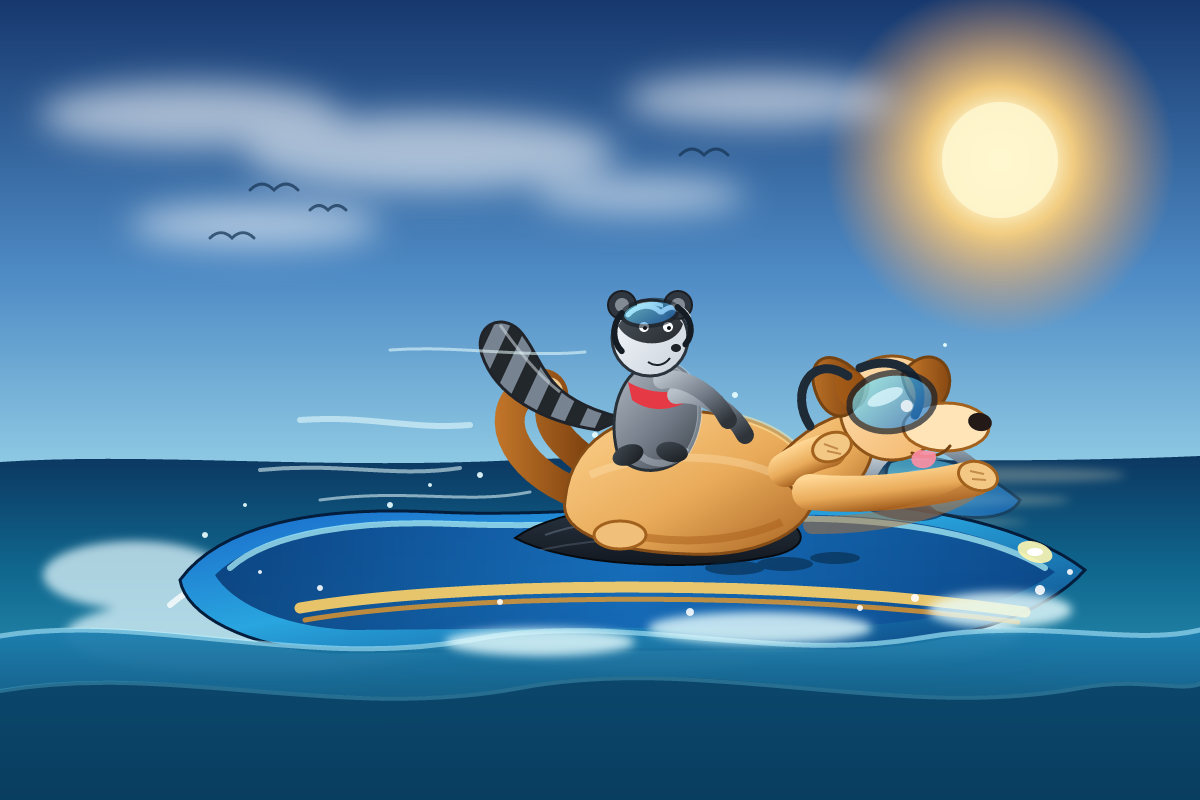
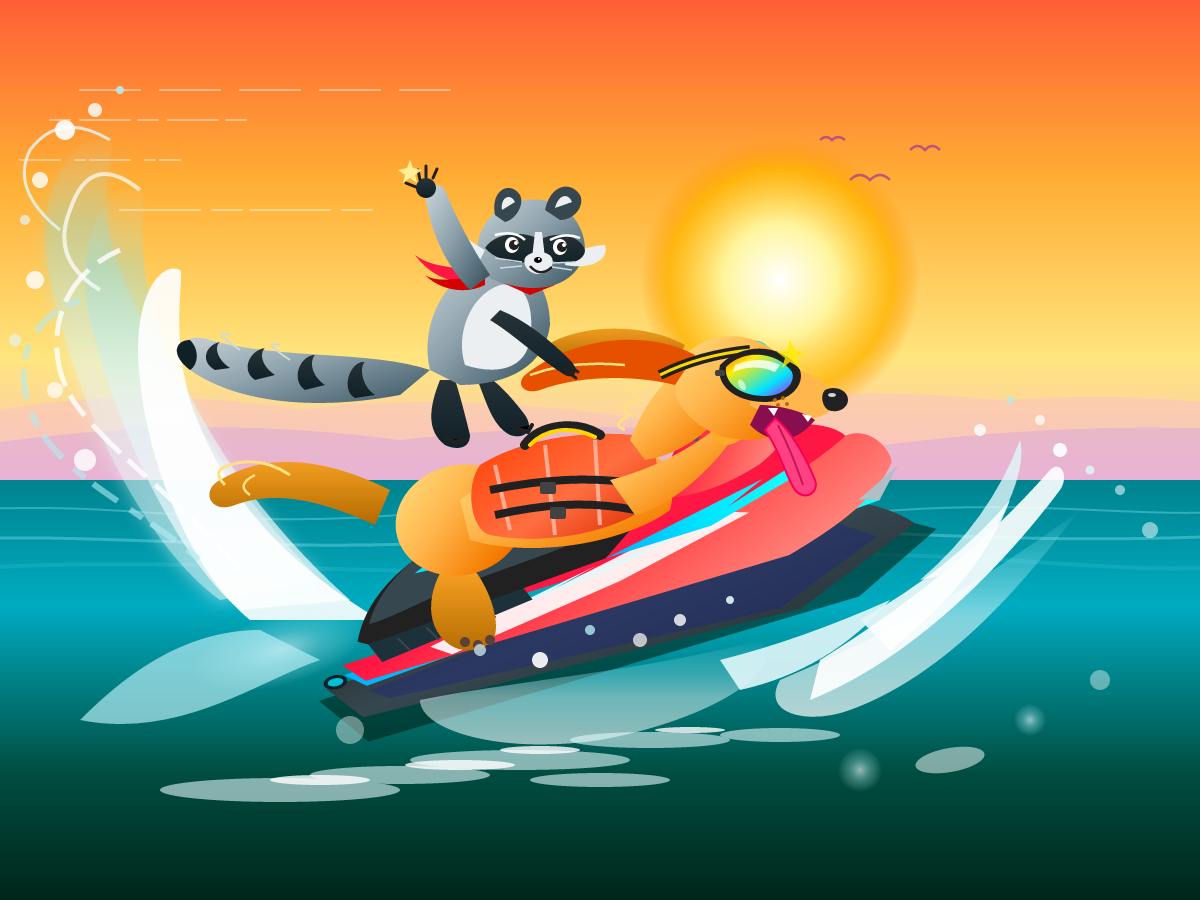
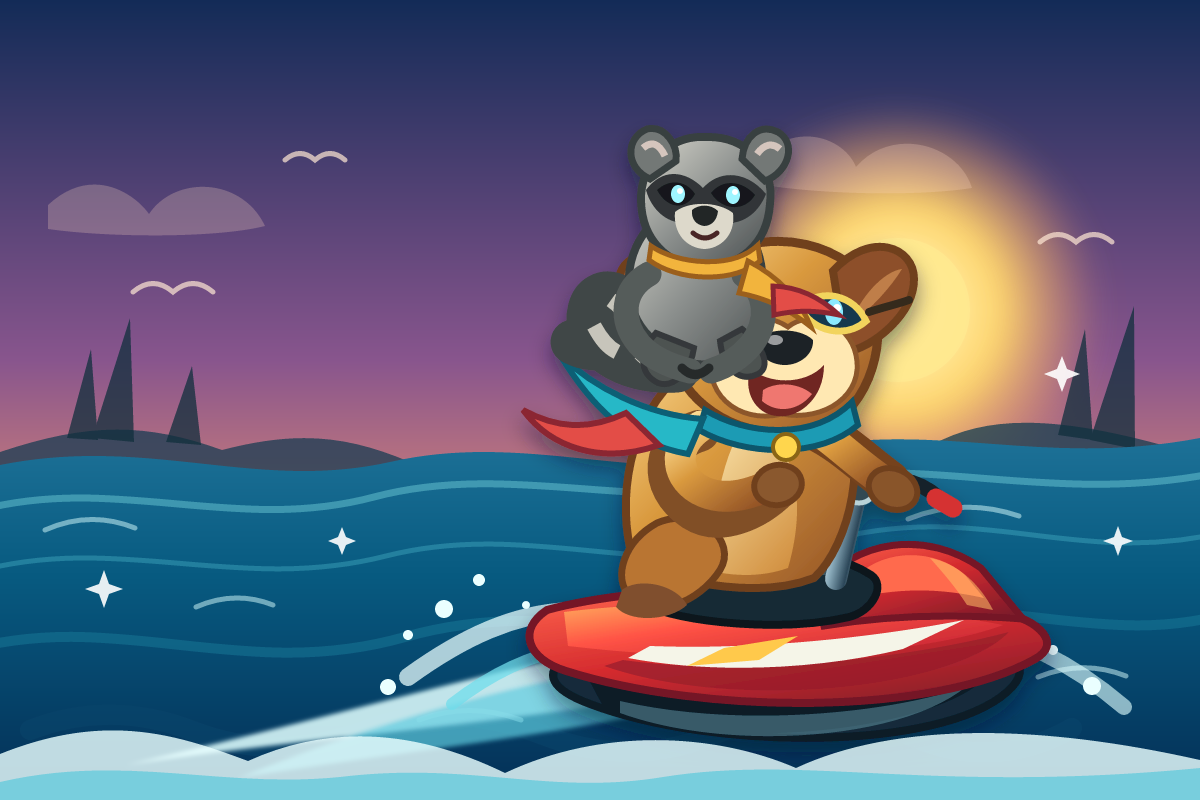
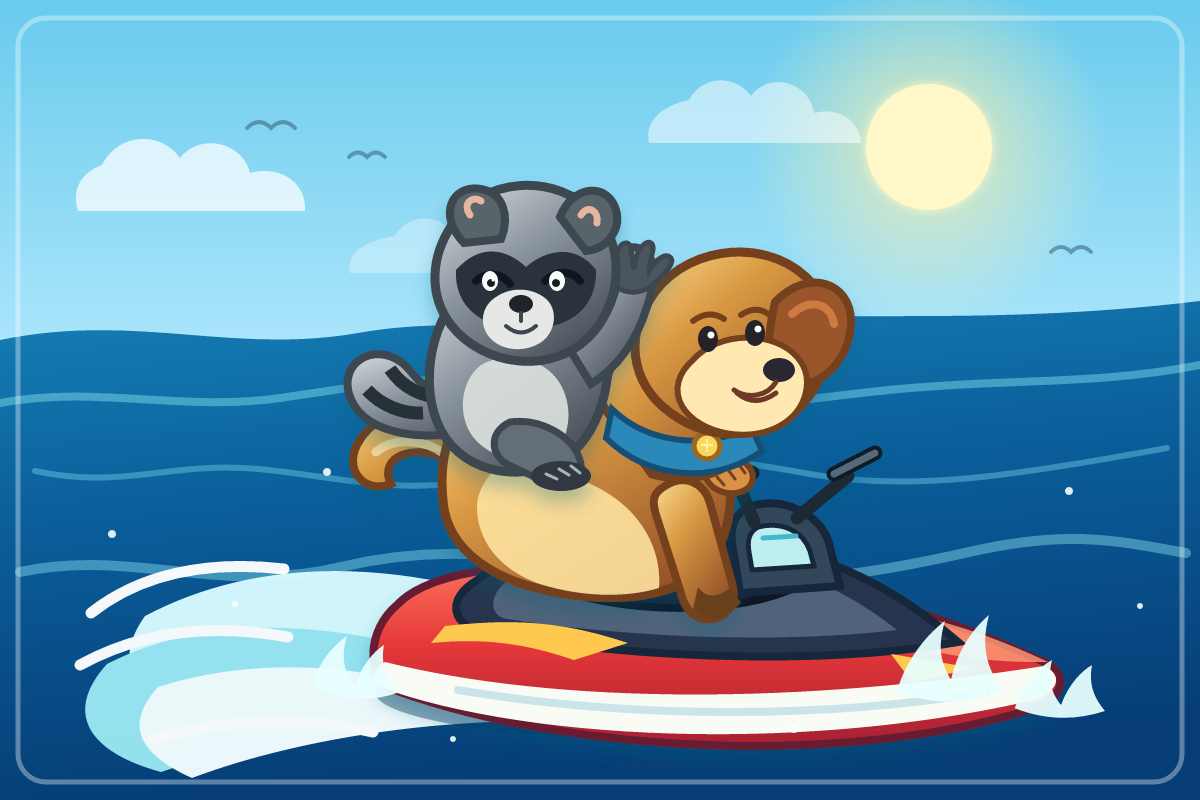
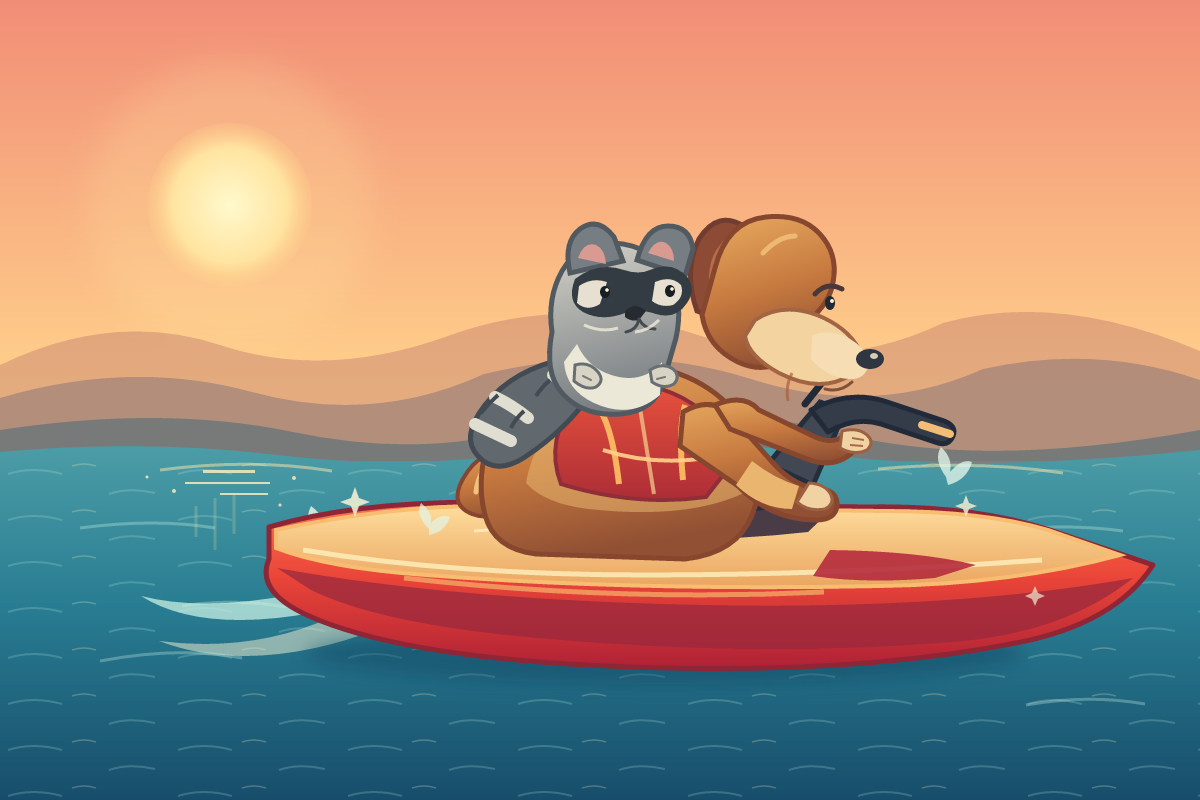
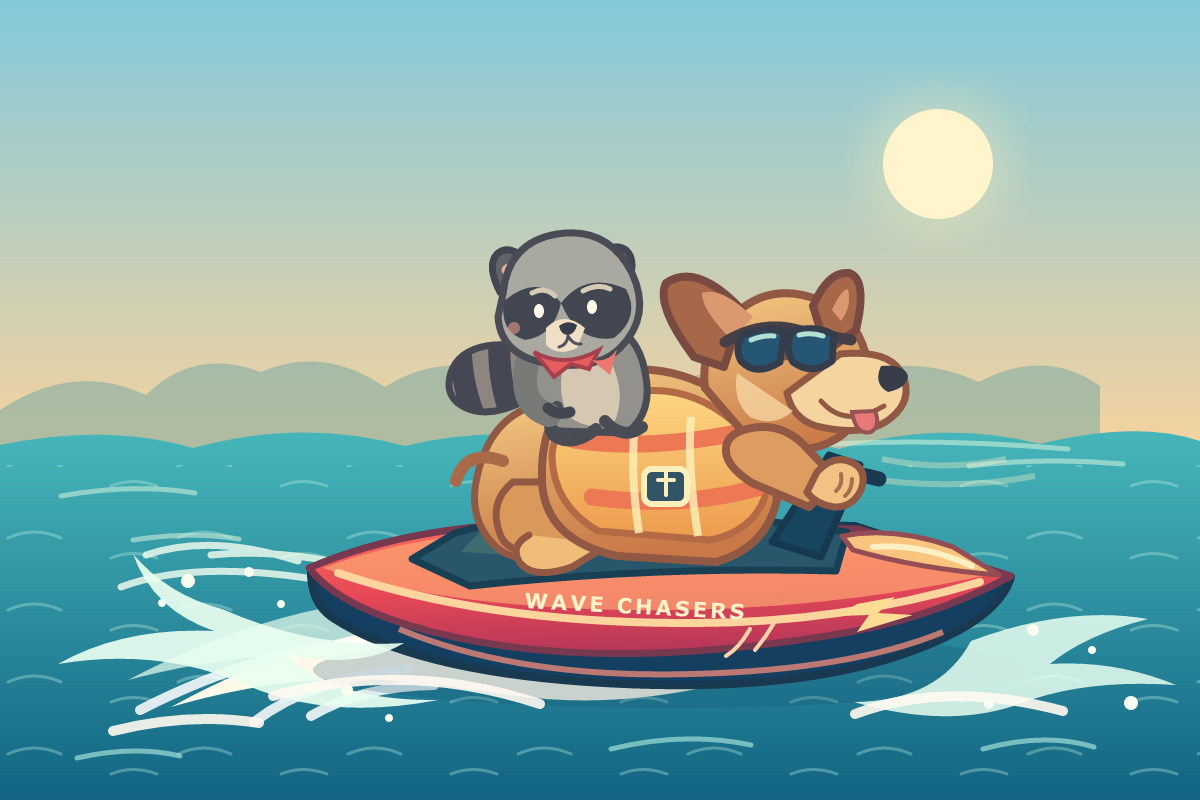
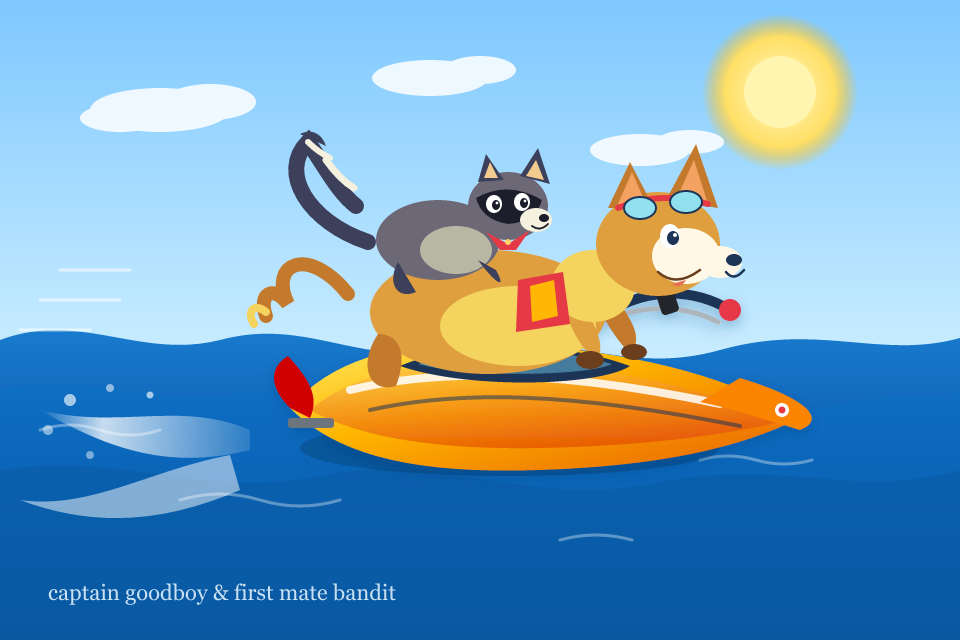
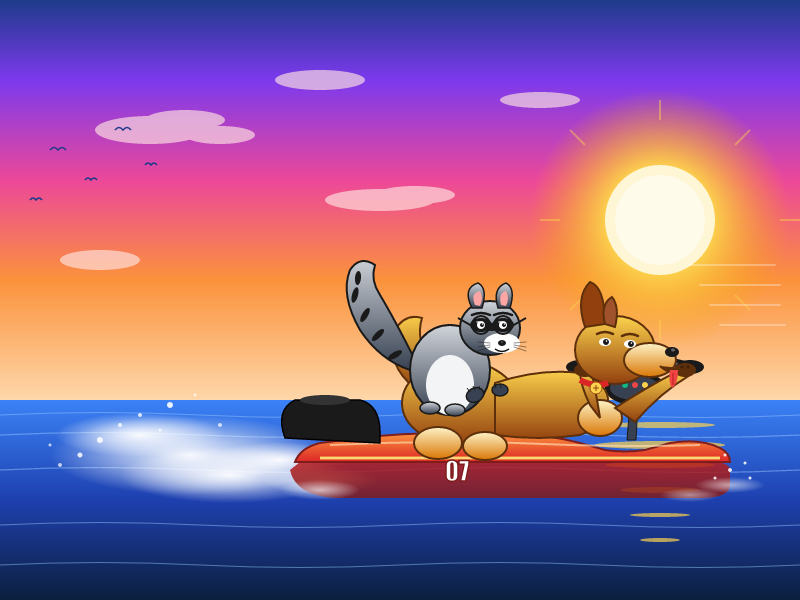
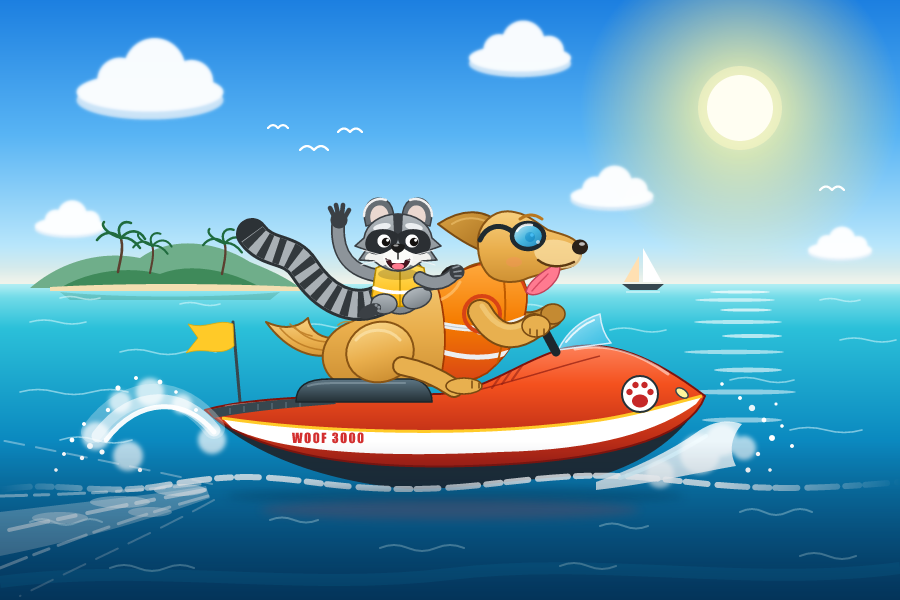
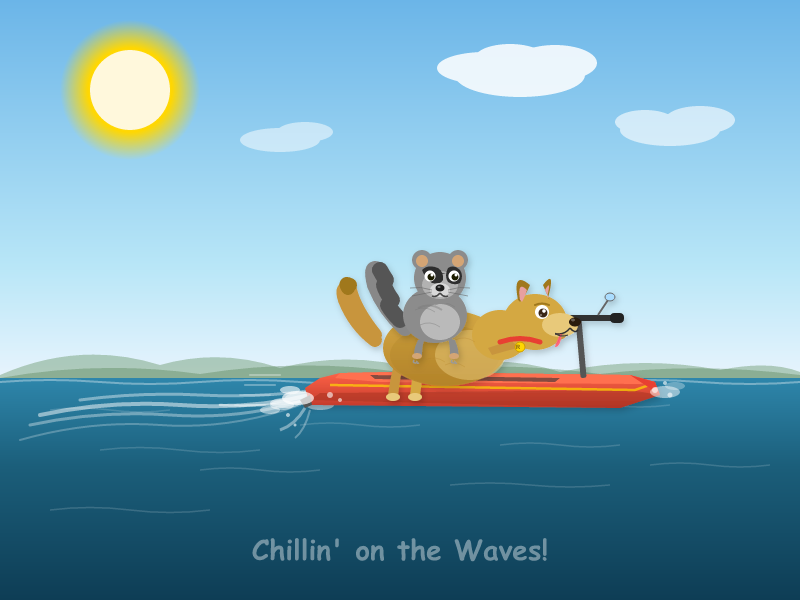
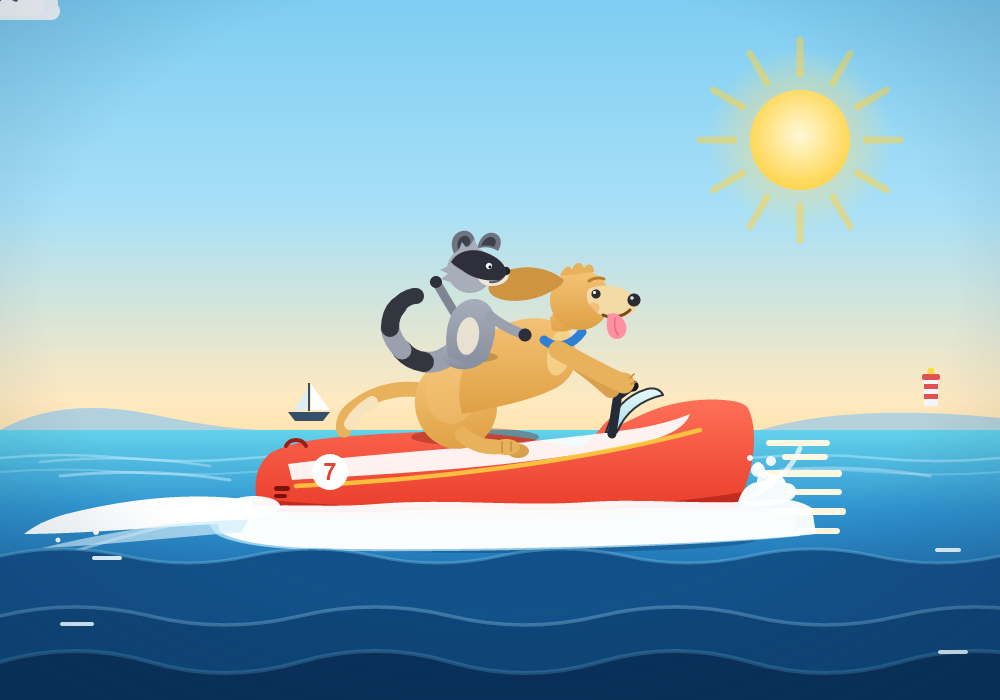
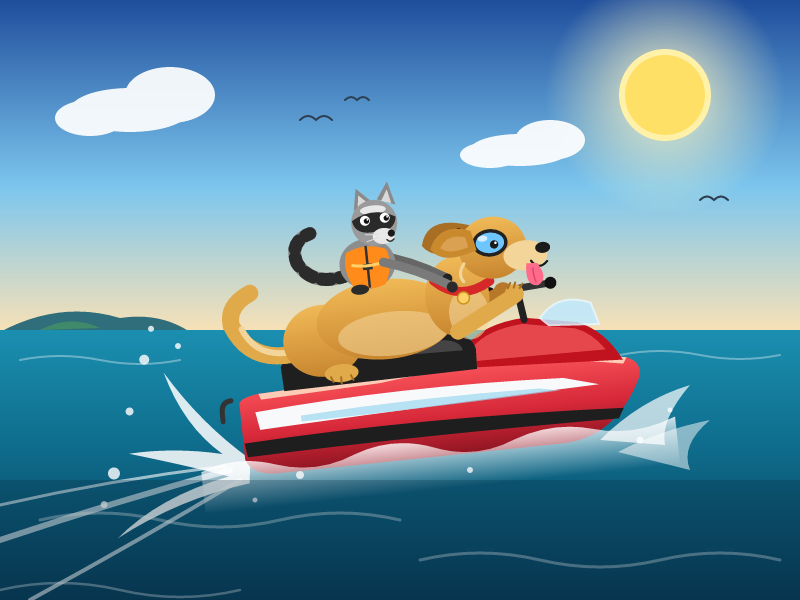
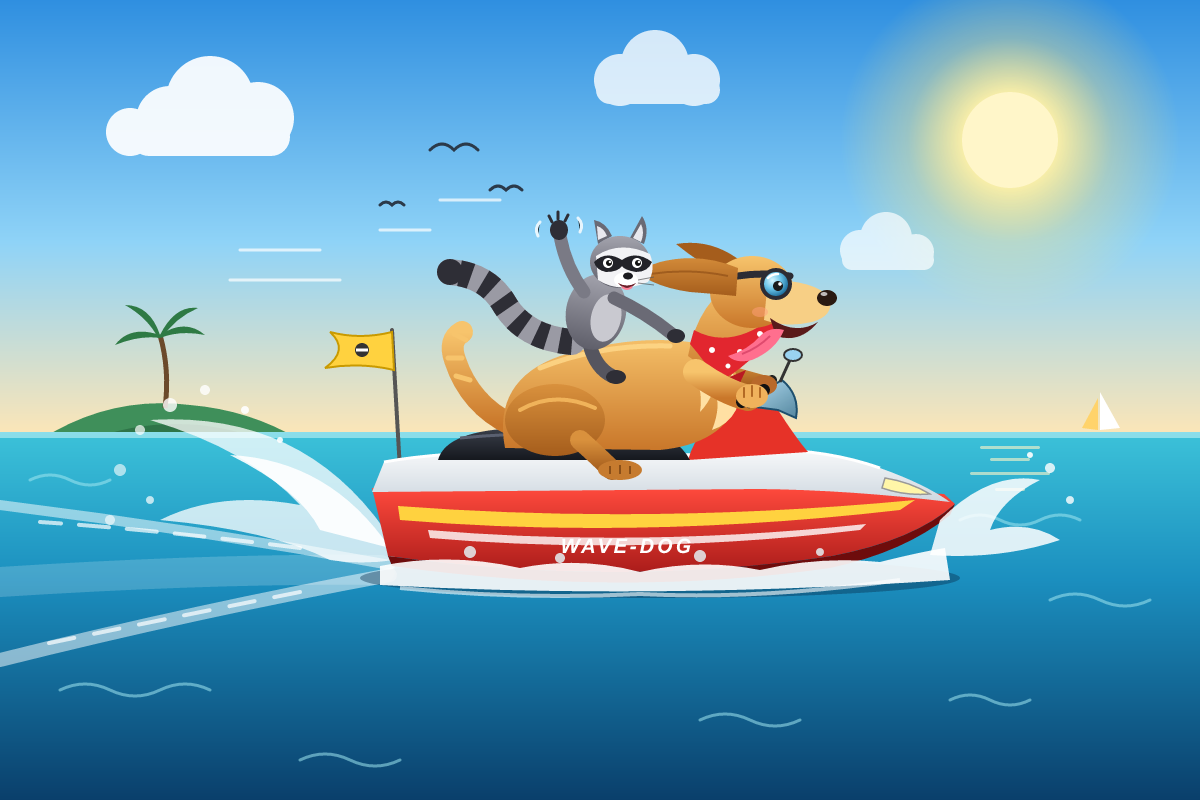
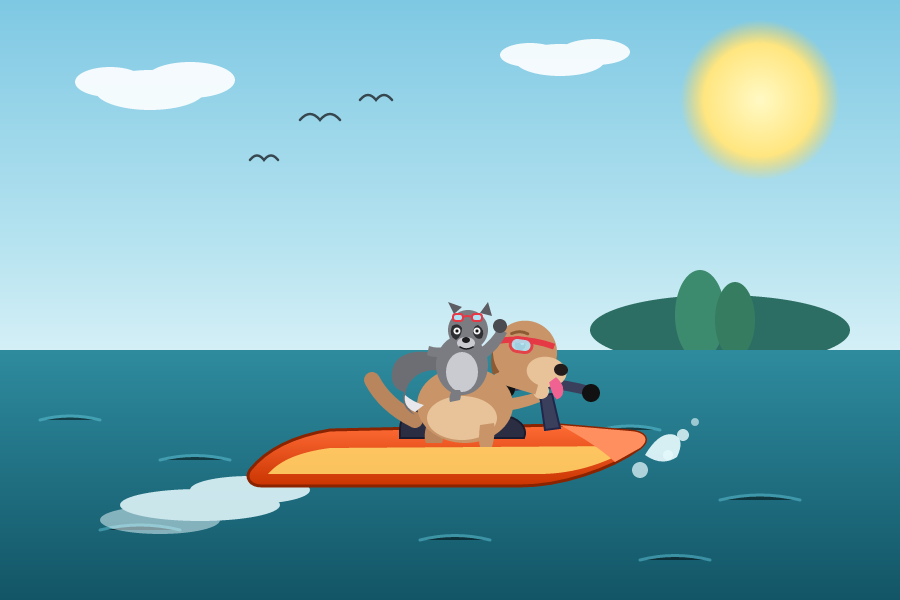
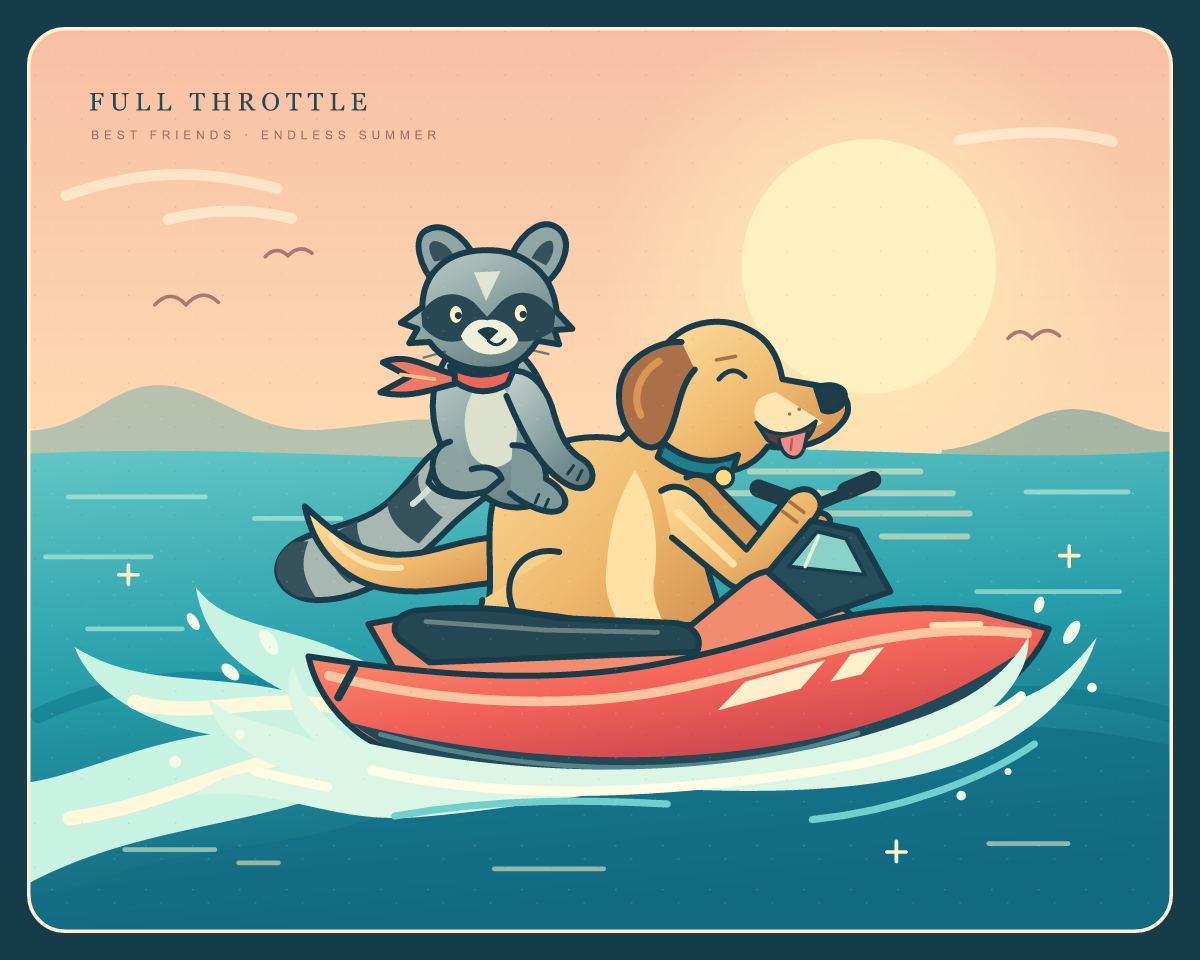
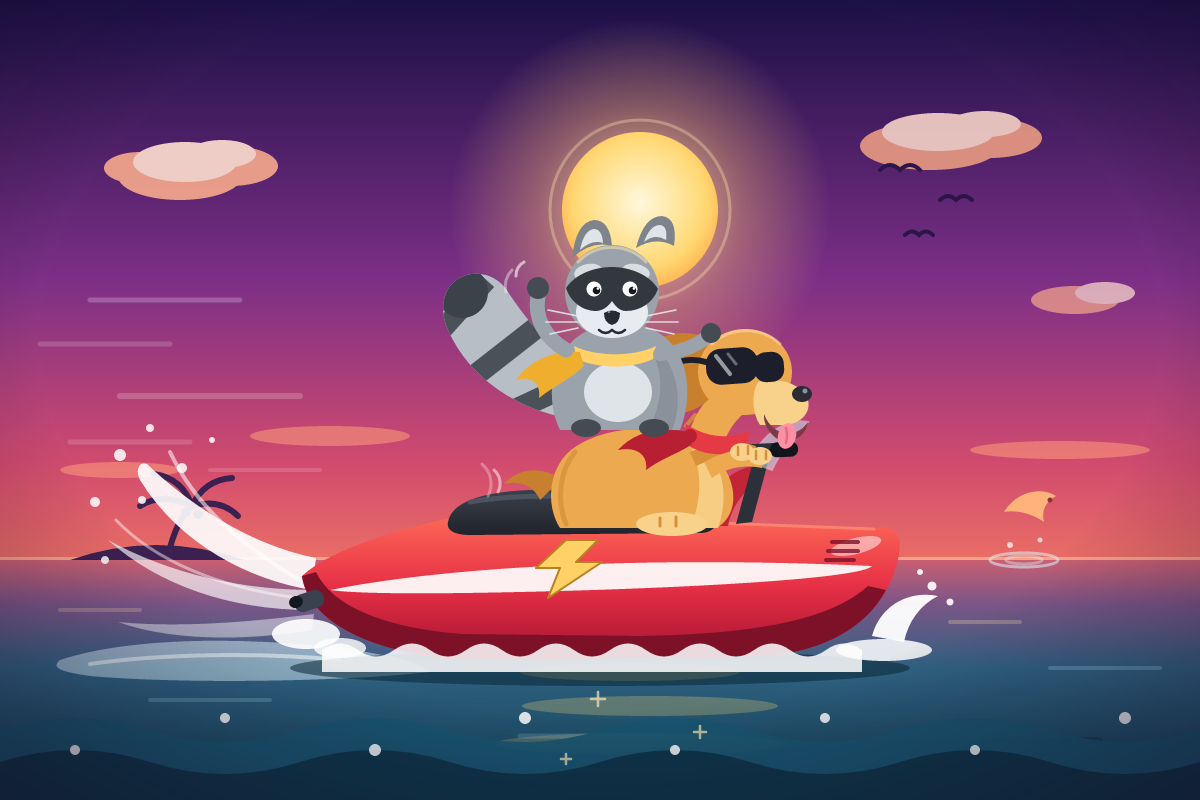
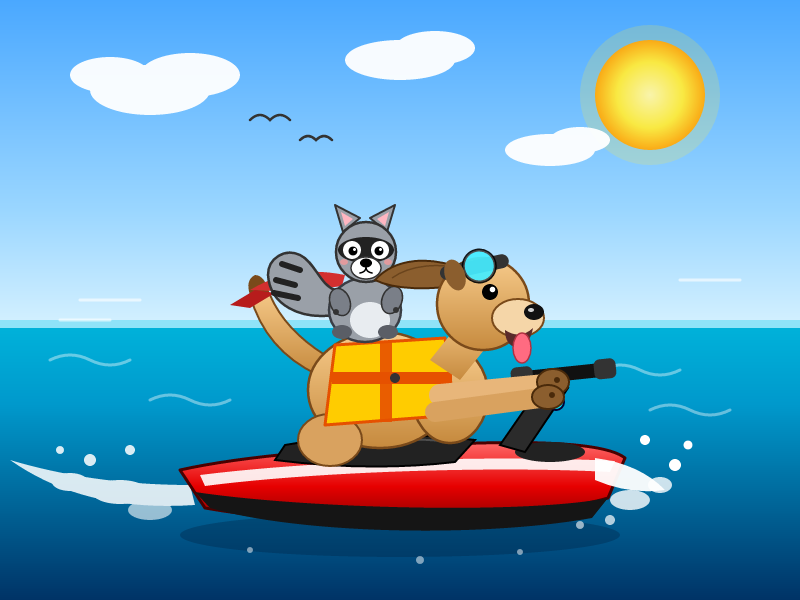
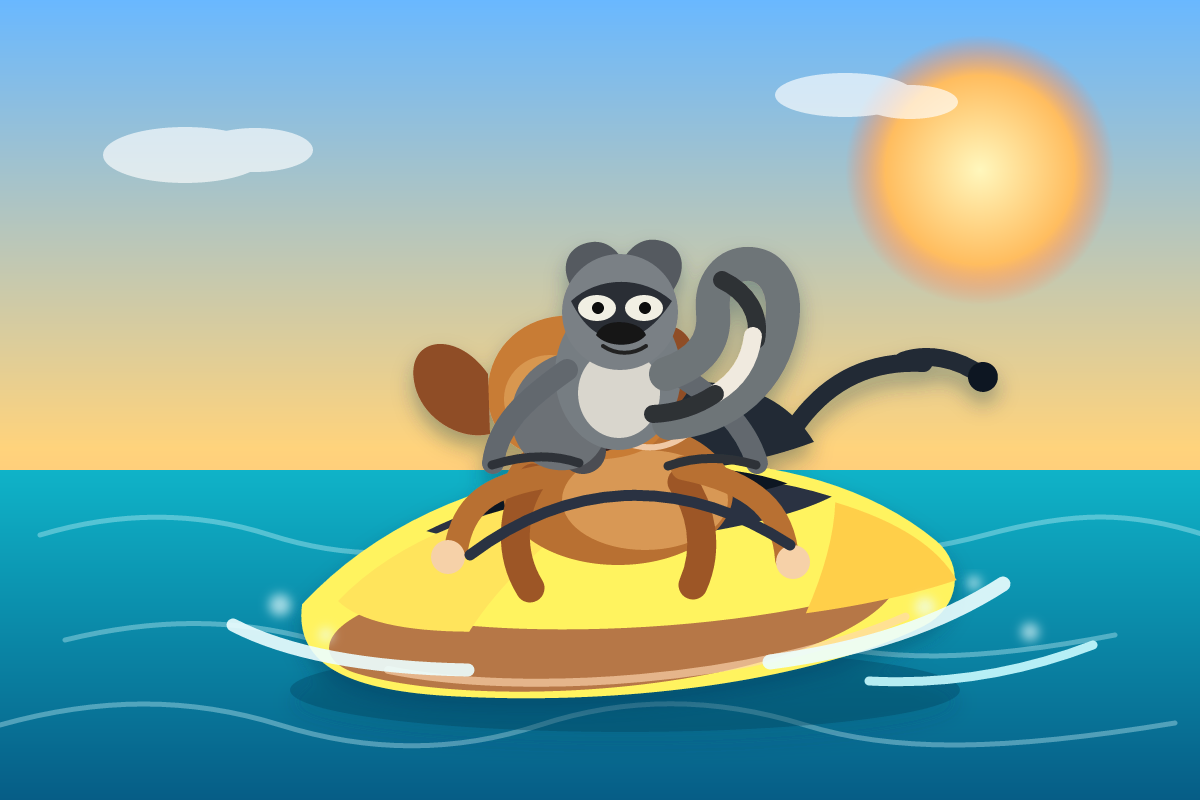
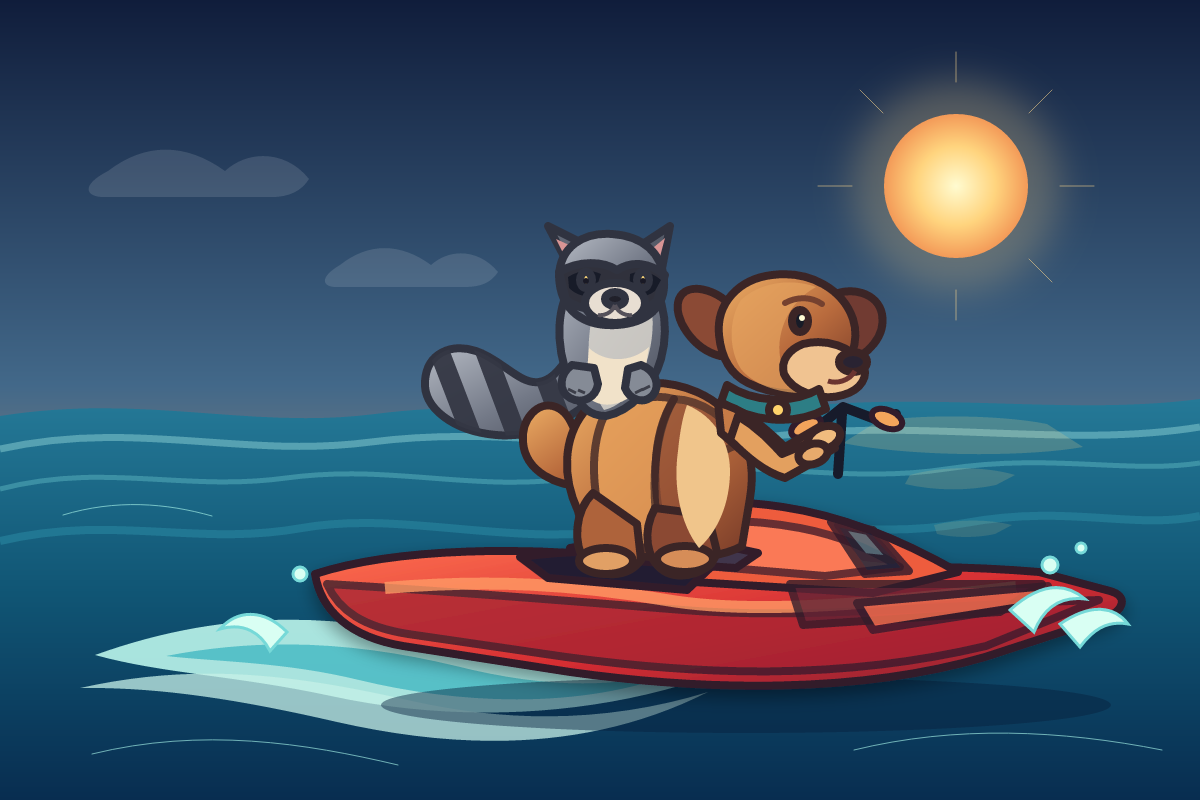
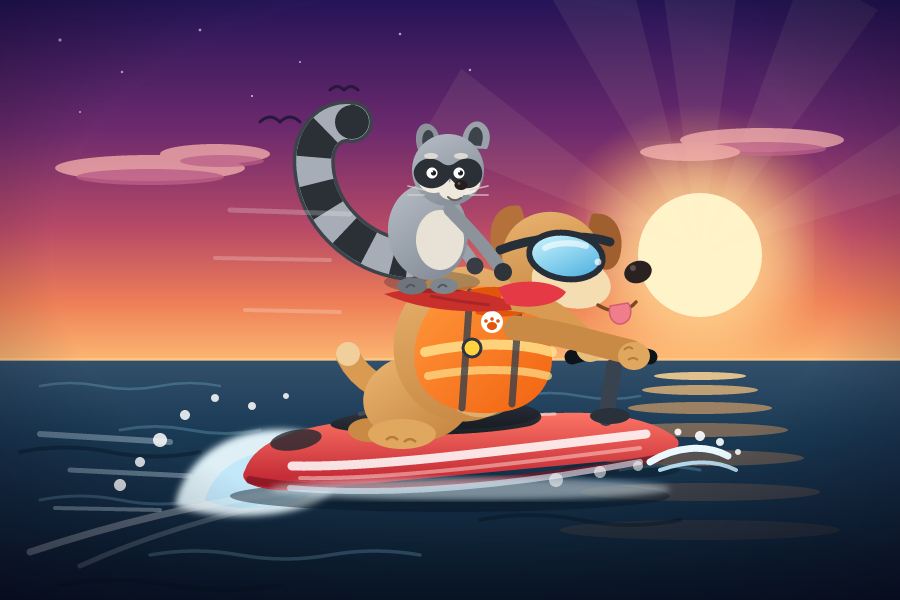
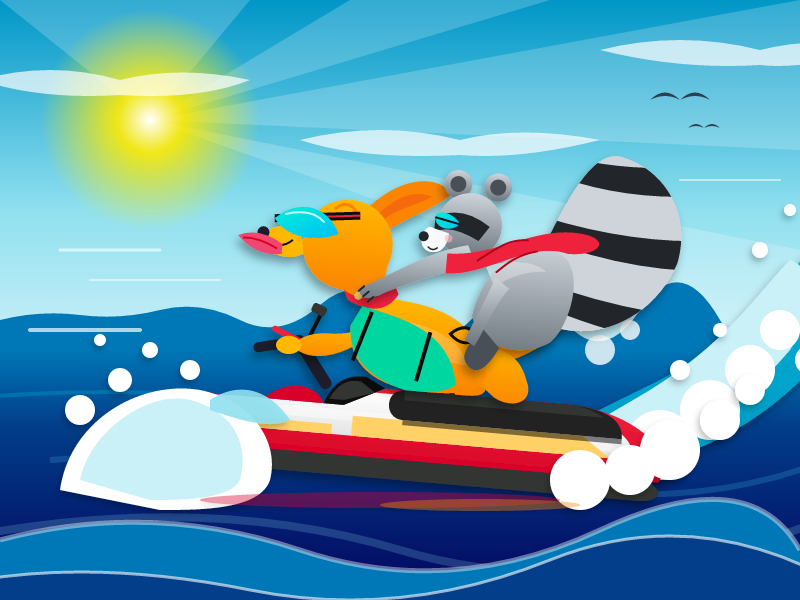
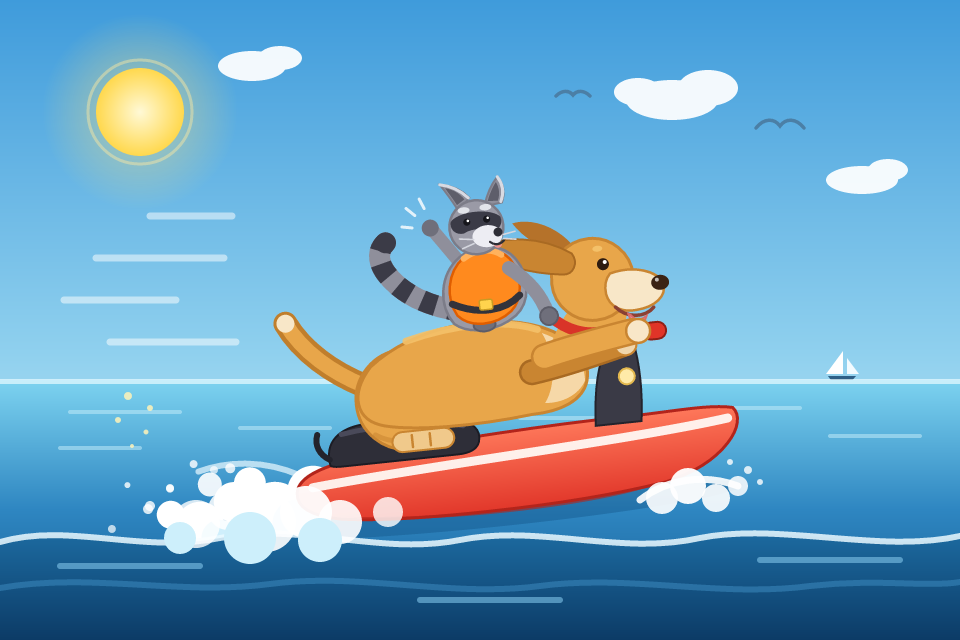
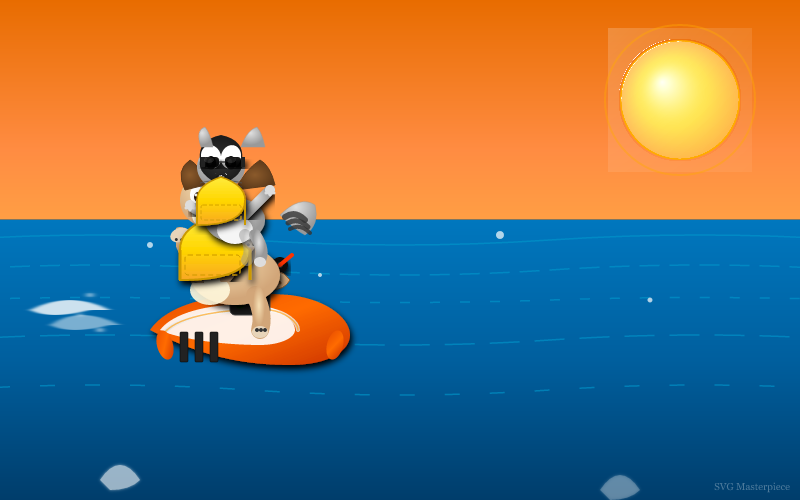
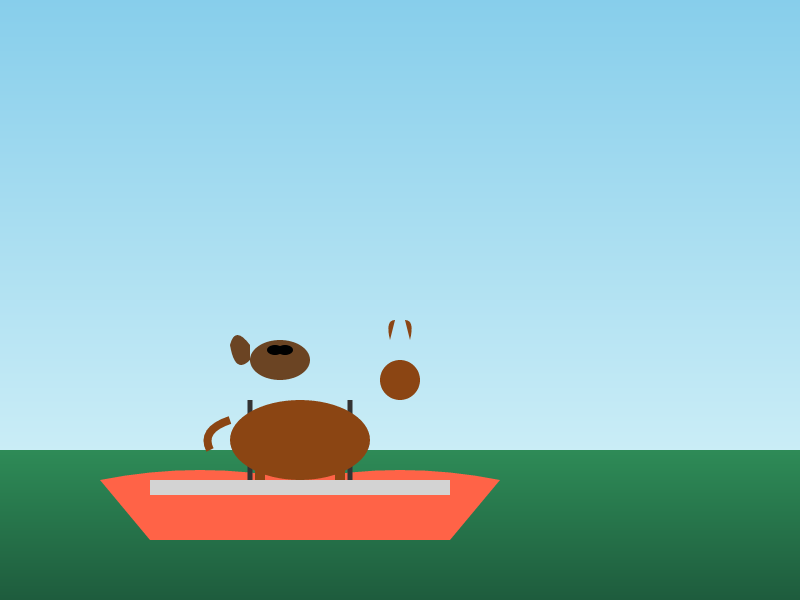
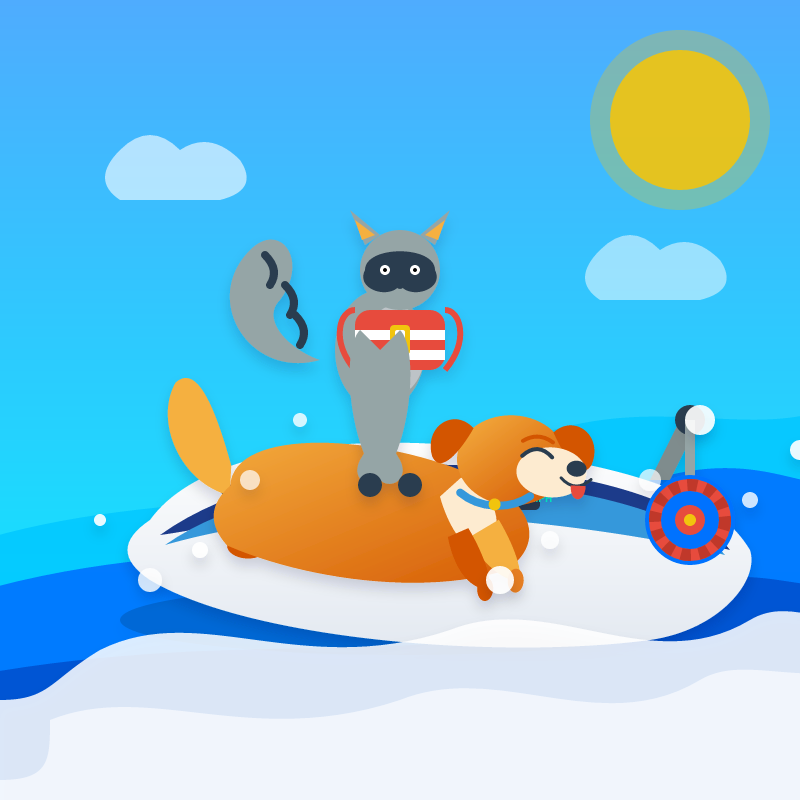
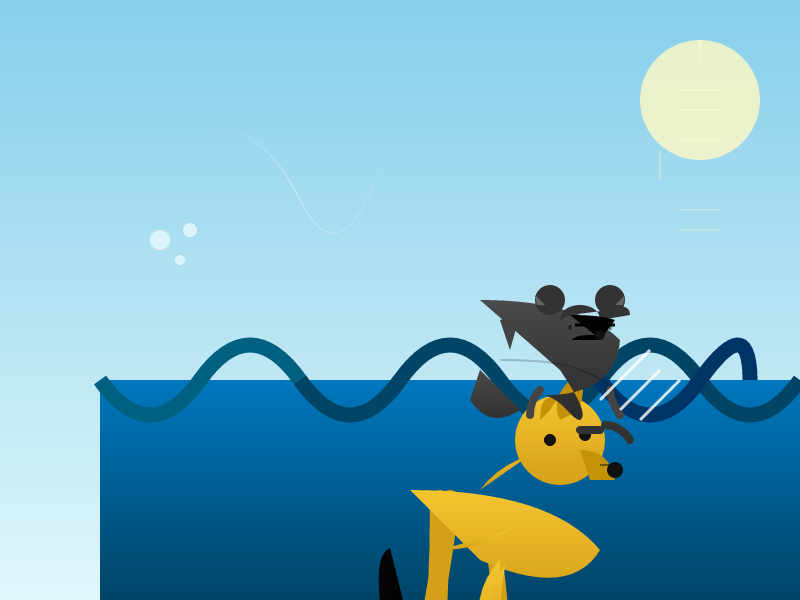
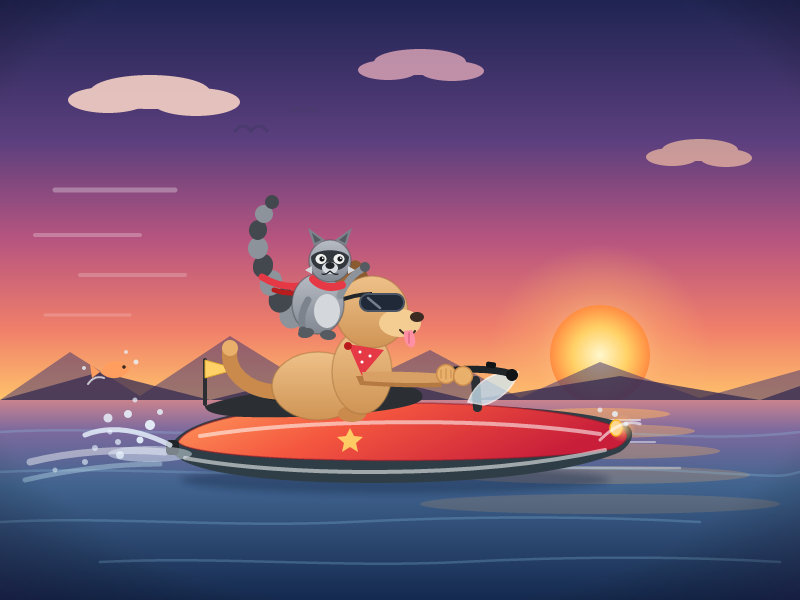
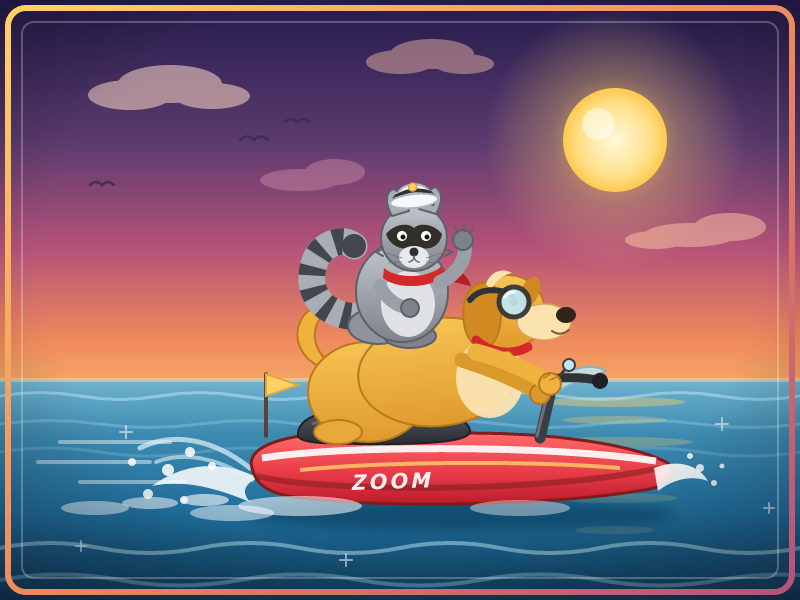
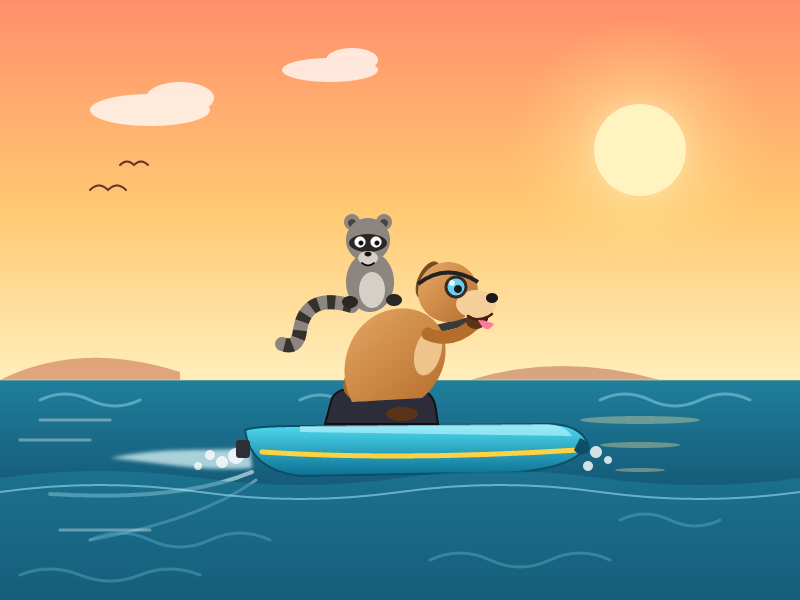
SVG of a raccoon that sits on a dog's back while the dog steers a jet ski
Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
A raccoon sits on a dog's back while the dog steers a jet ski
Make it a masterpiece
You may NOT use tools, browser, image analysis. Directly output the SVG as code
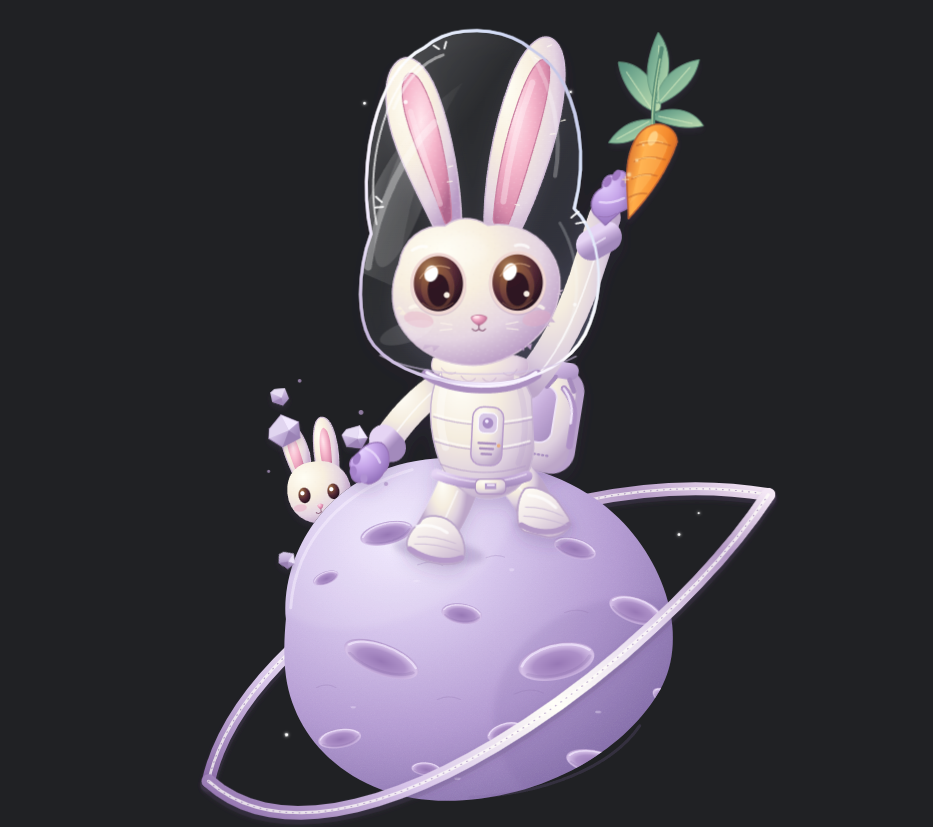
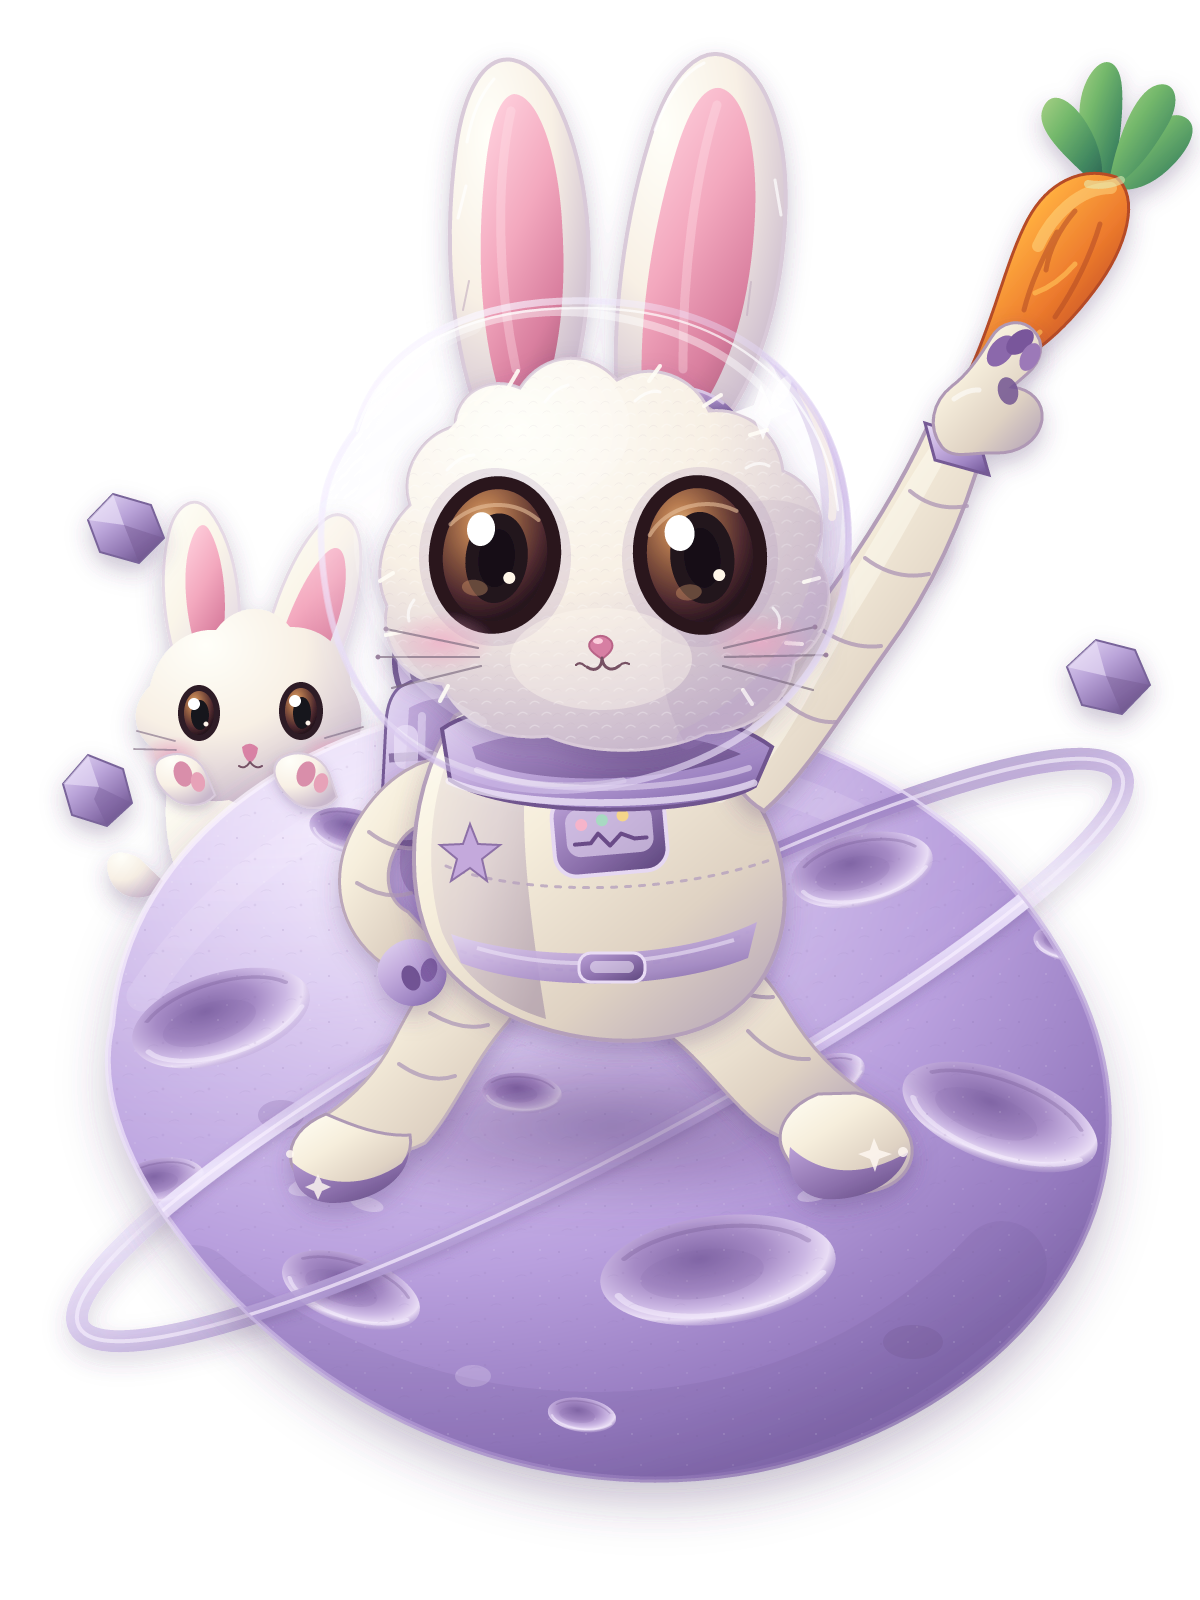
Draw a baby astronaut bunny leaping off a purple moon to reach a floating carrot. A smaller bunny peeks over the moon while little rocks drift nearby. Give it a soft, detailed storybook look.
The exact prompt is held back to prevent benchmaxxing.
SelfieVisual construction
and creative interpretationComplexity 5/10
Draw a baby astronaut bunny leaping off a purple moon to reach a floating carrot. A smaller bunny peeks over the moon while little rocks drift nearby. Give it a soft, detailed storybook look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
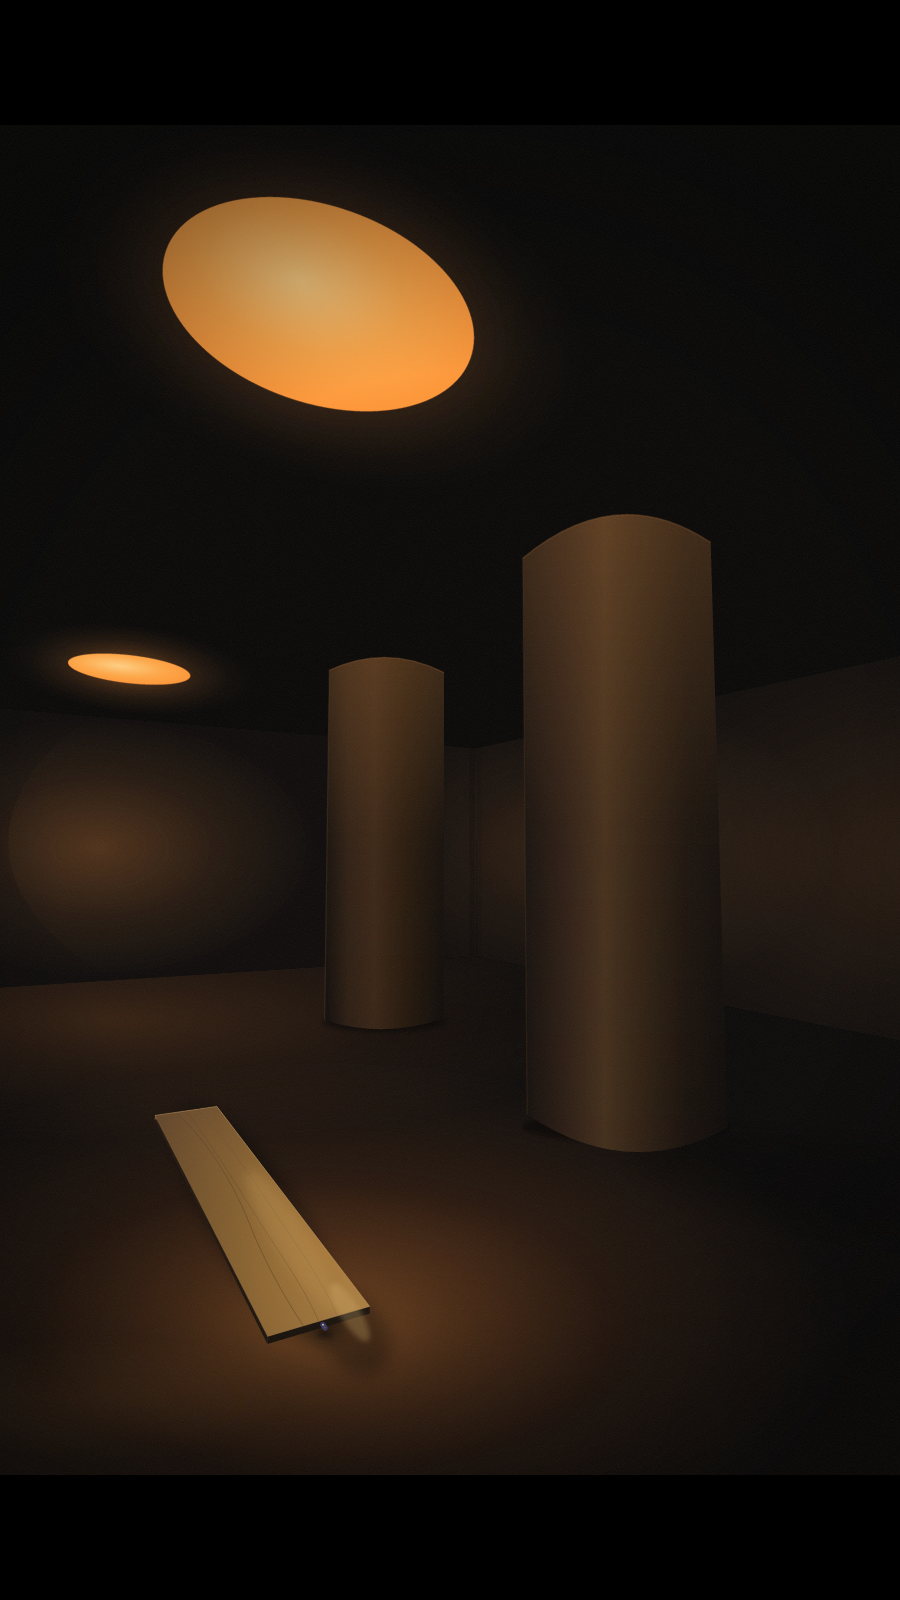
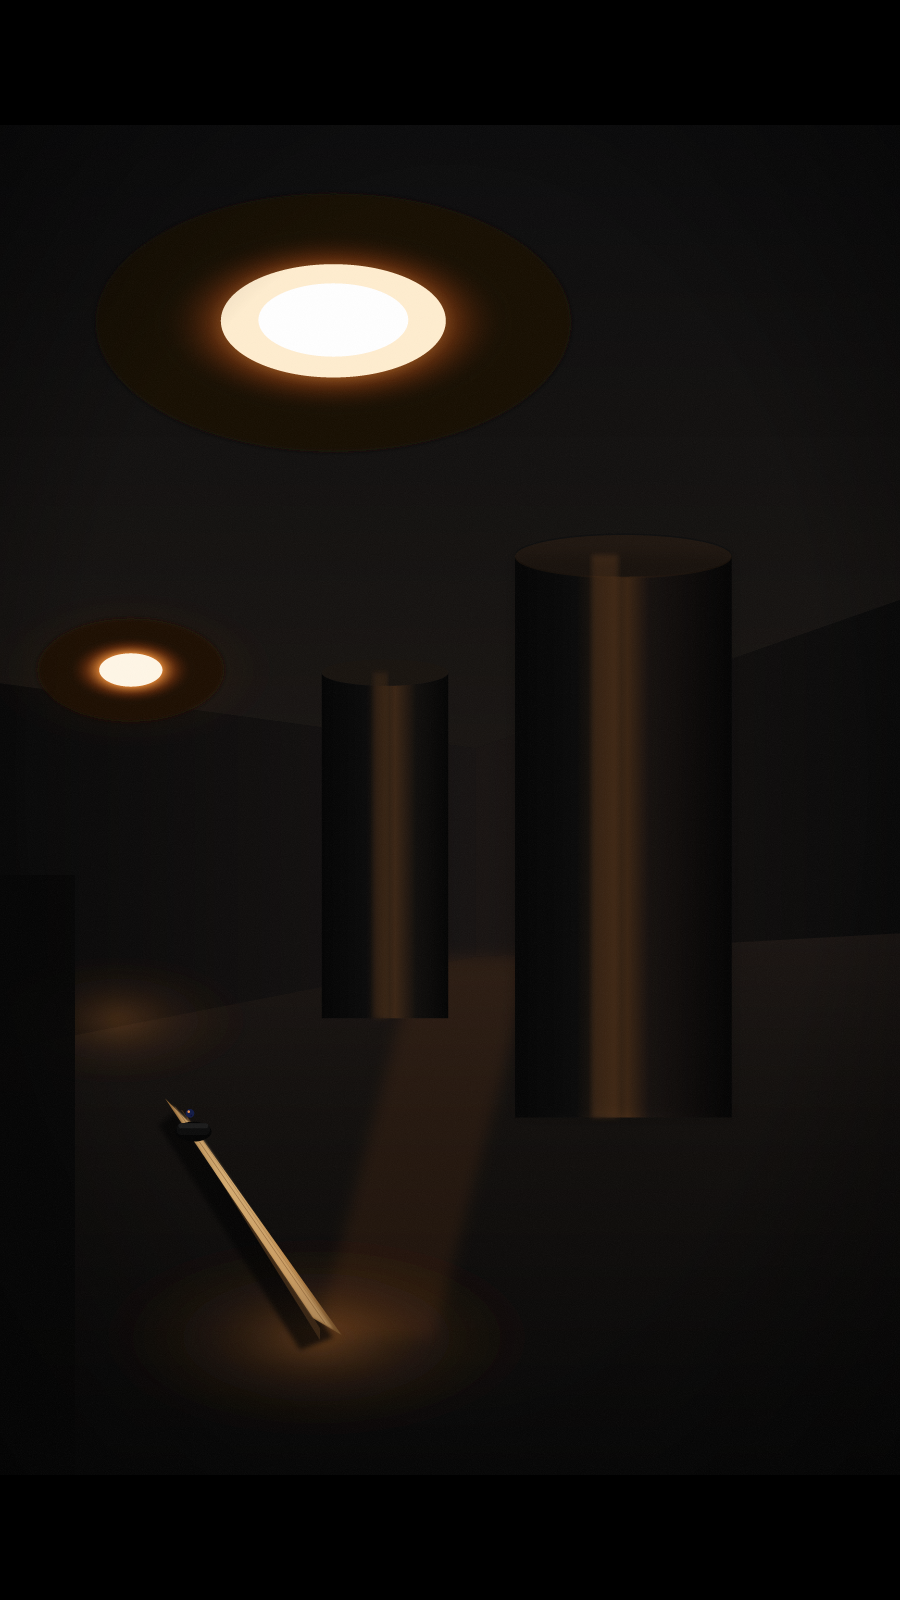
Ground TruthPhysical reasoning, light
and visual reconstruction
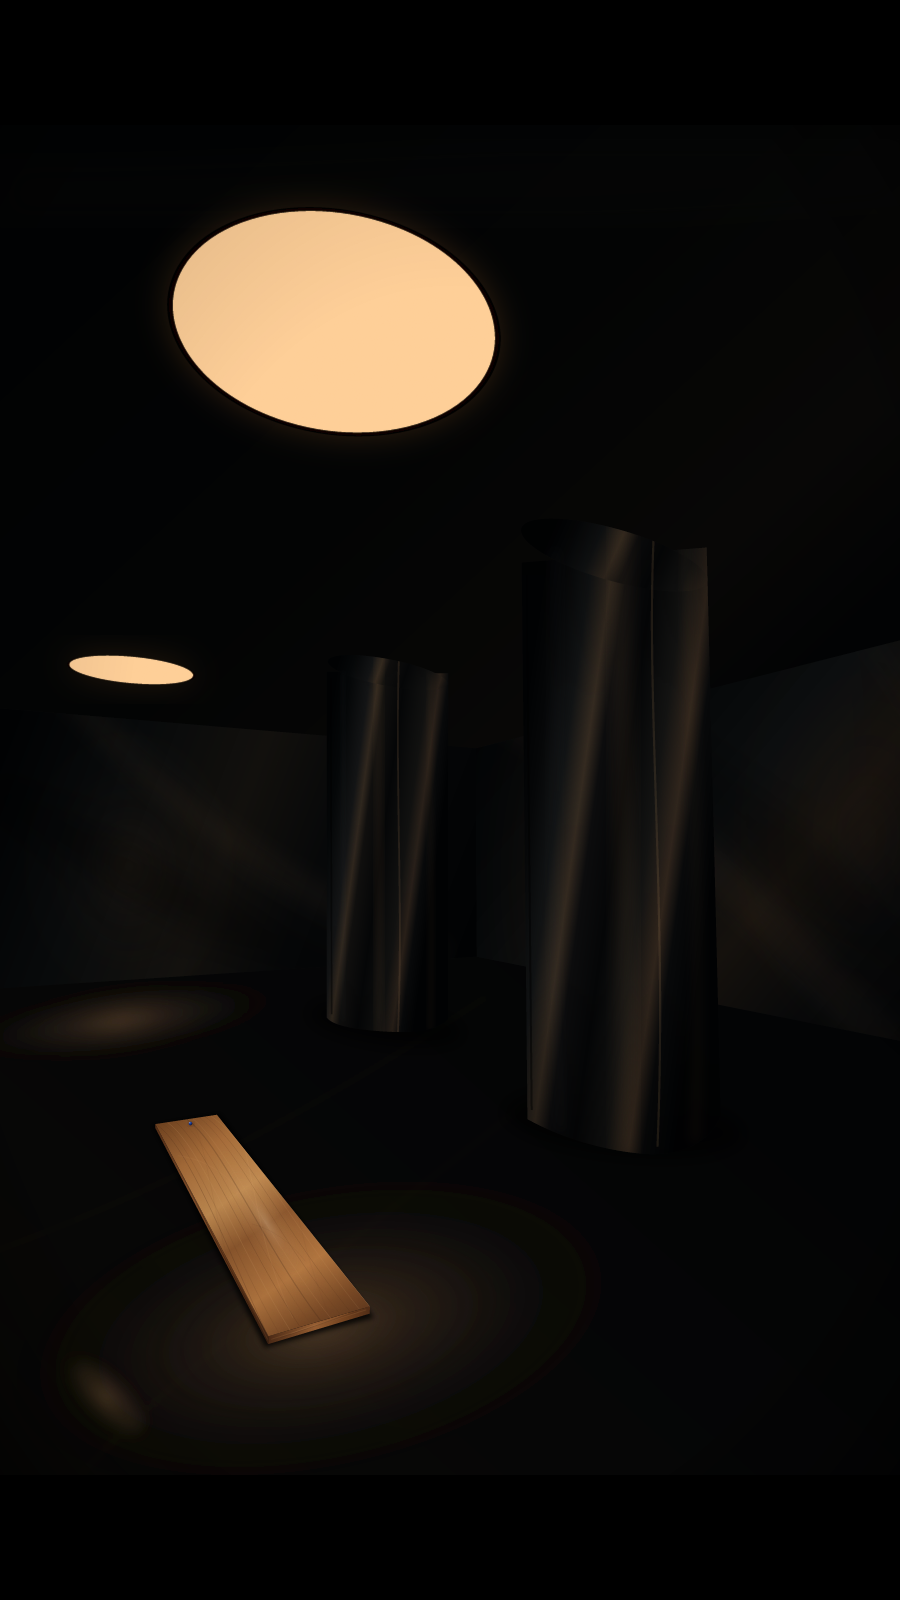
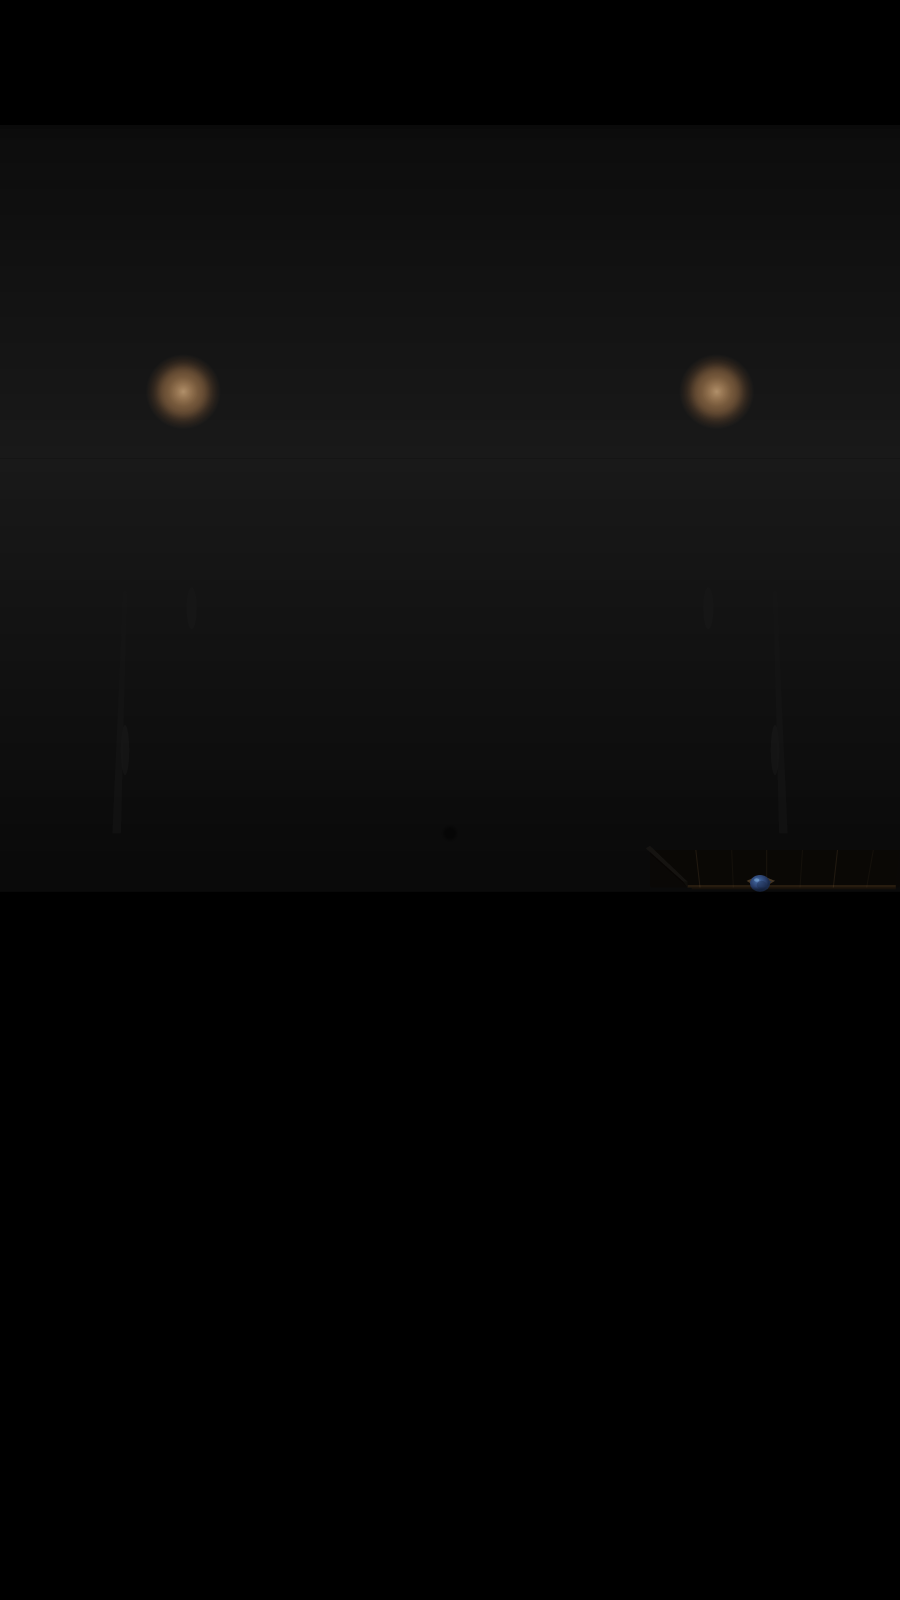
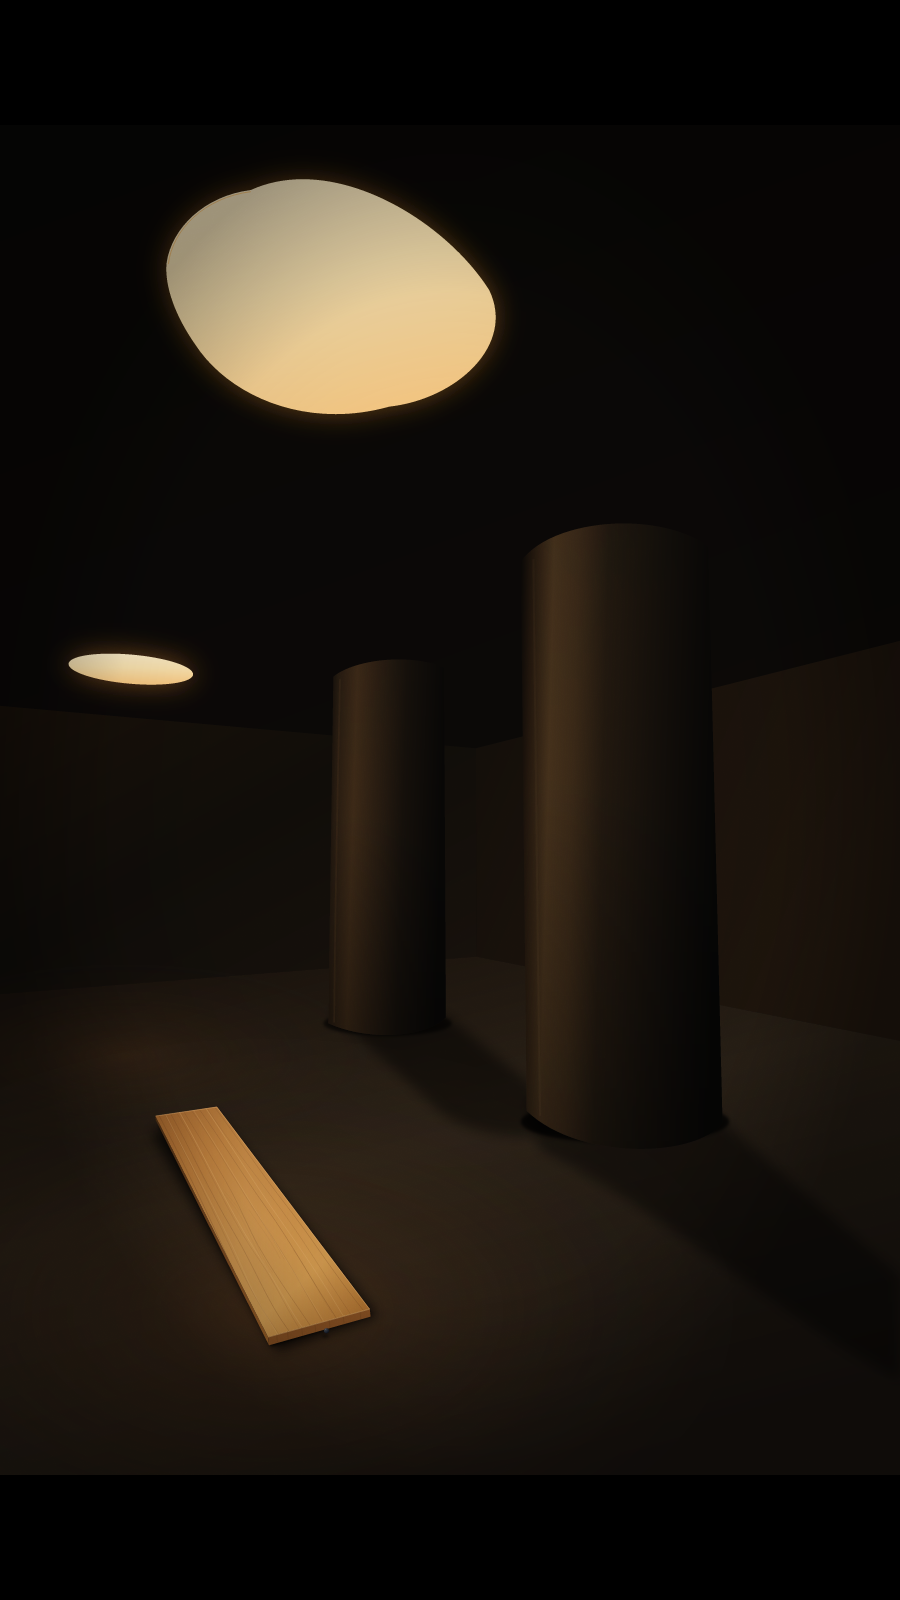
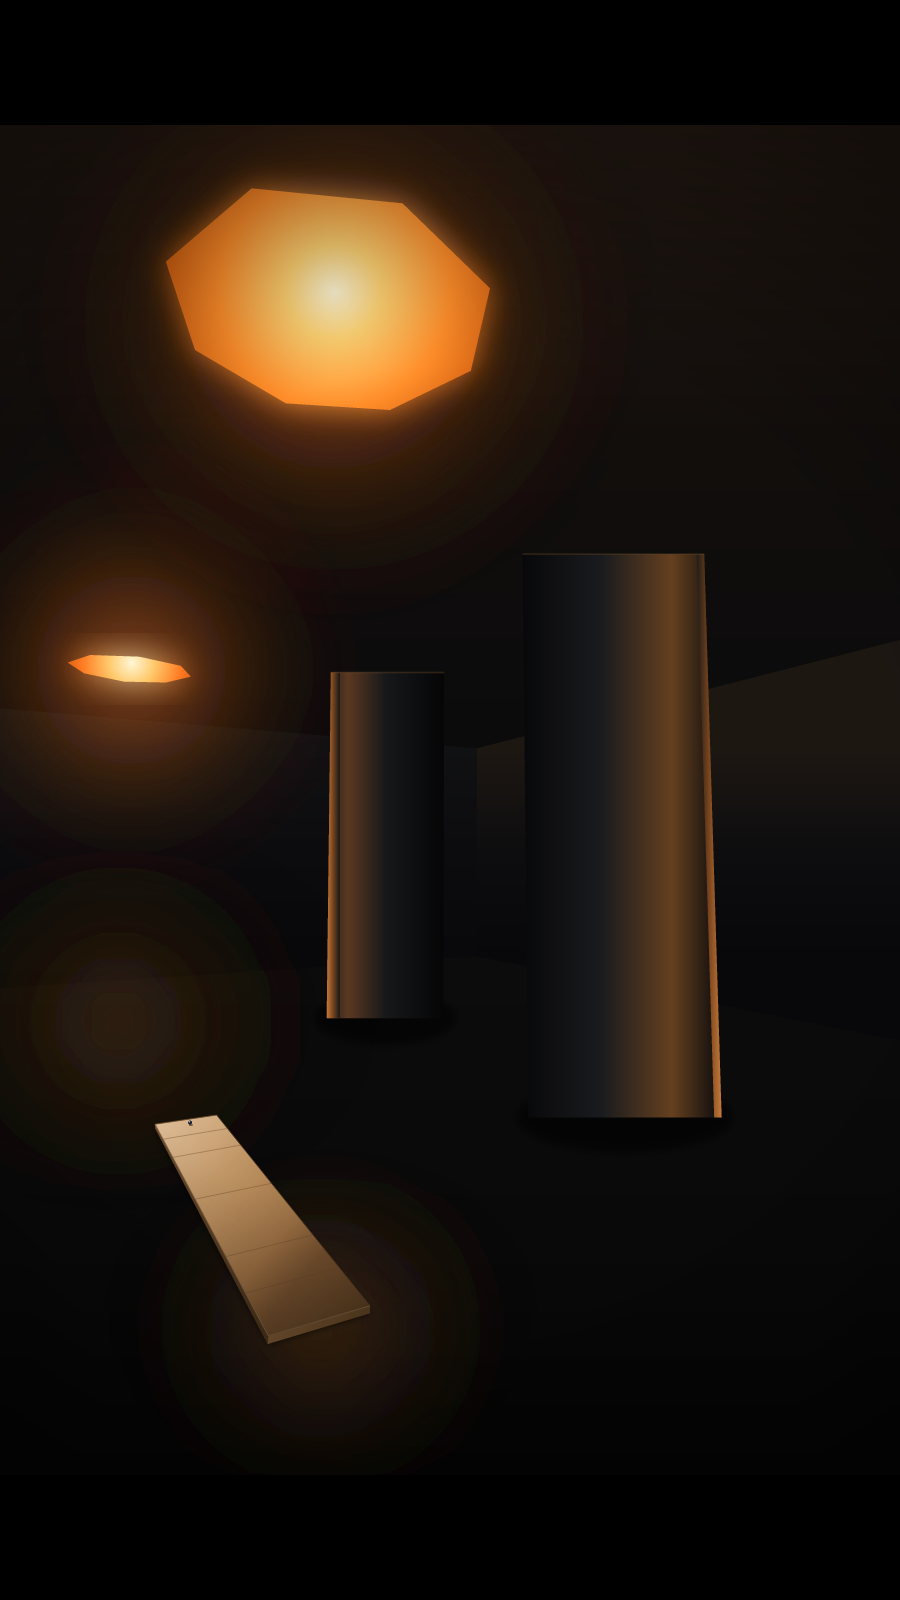
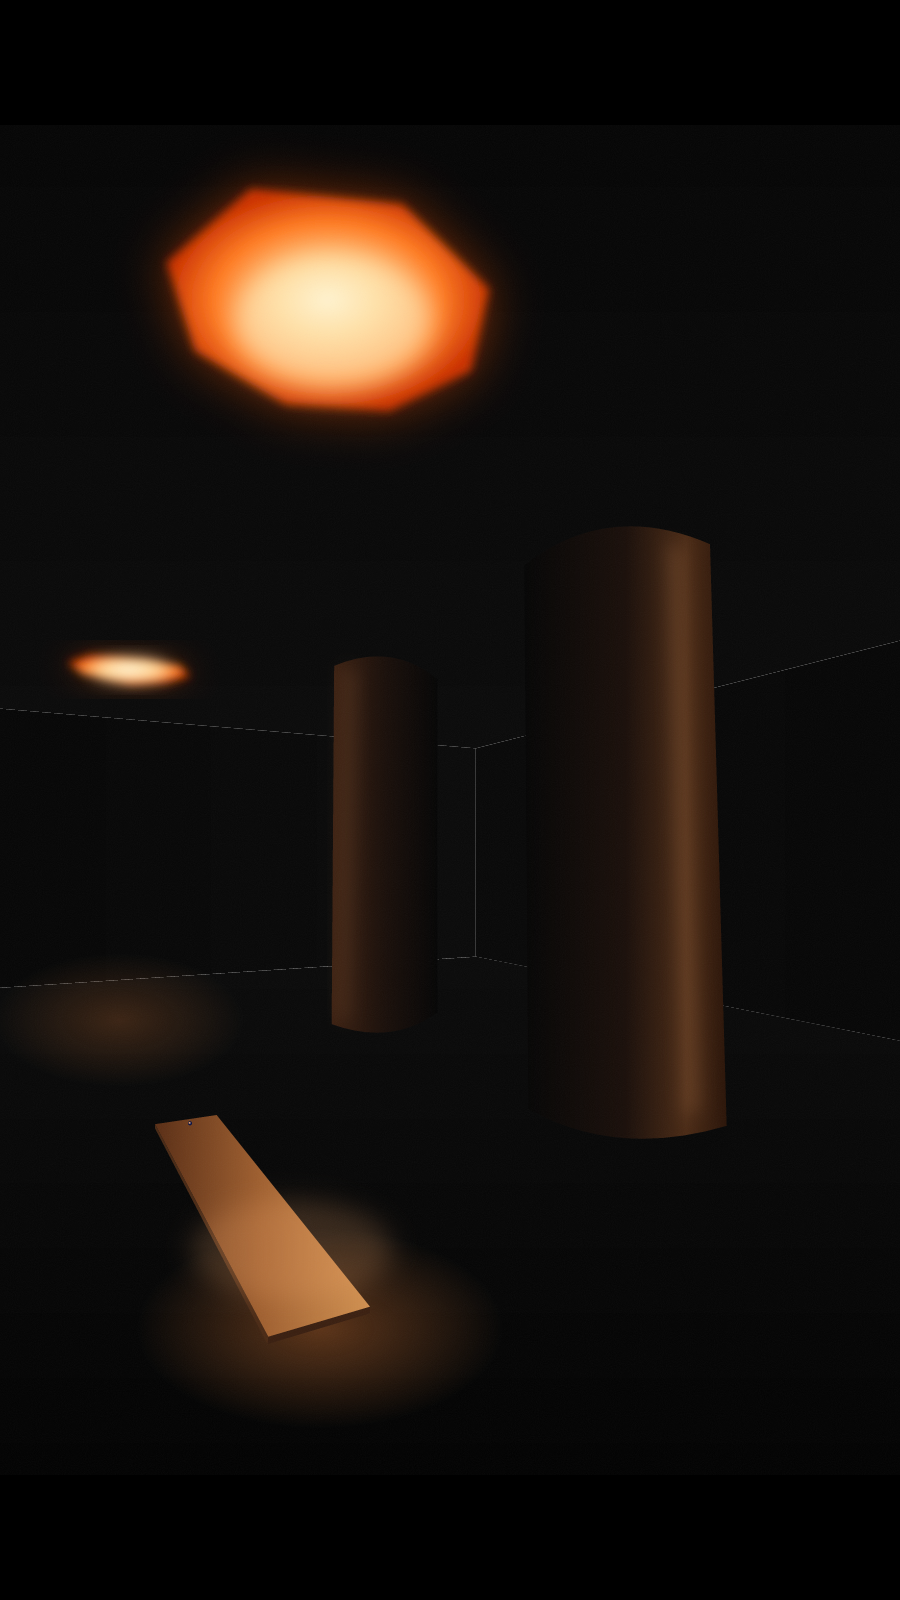
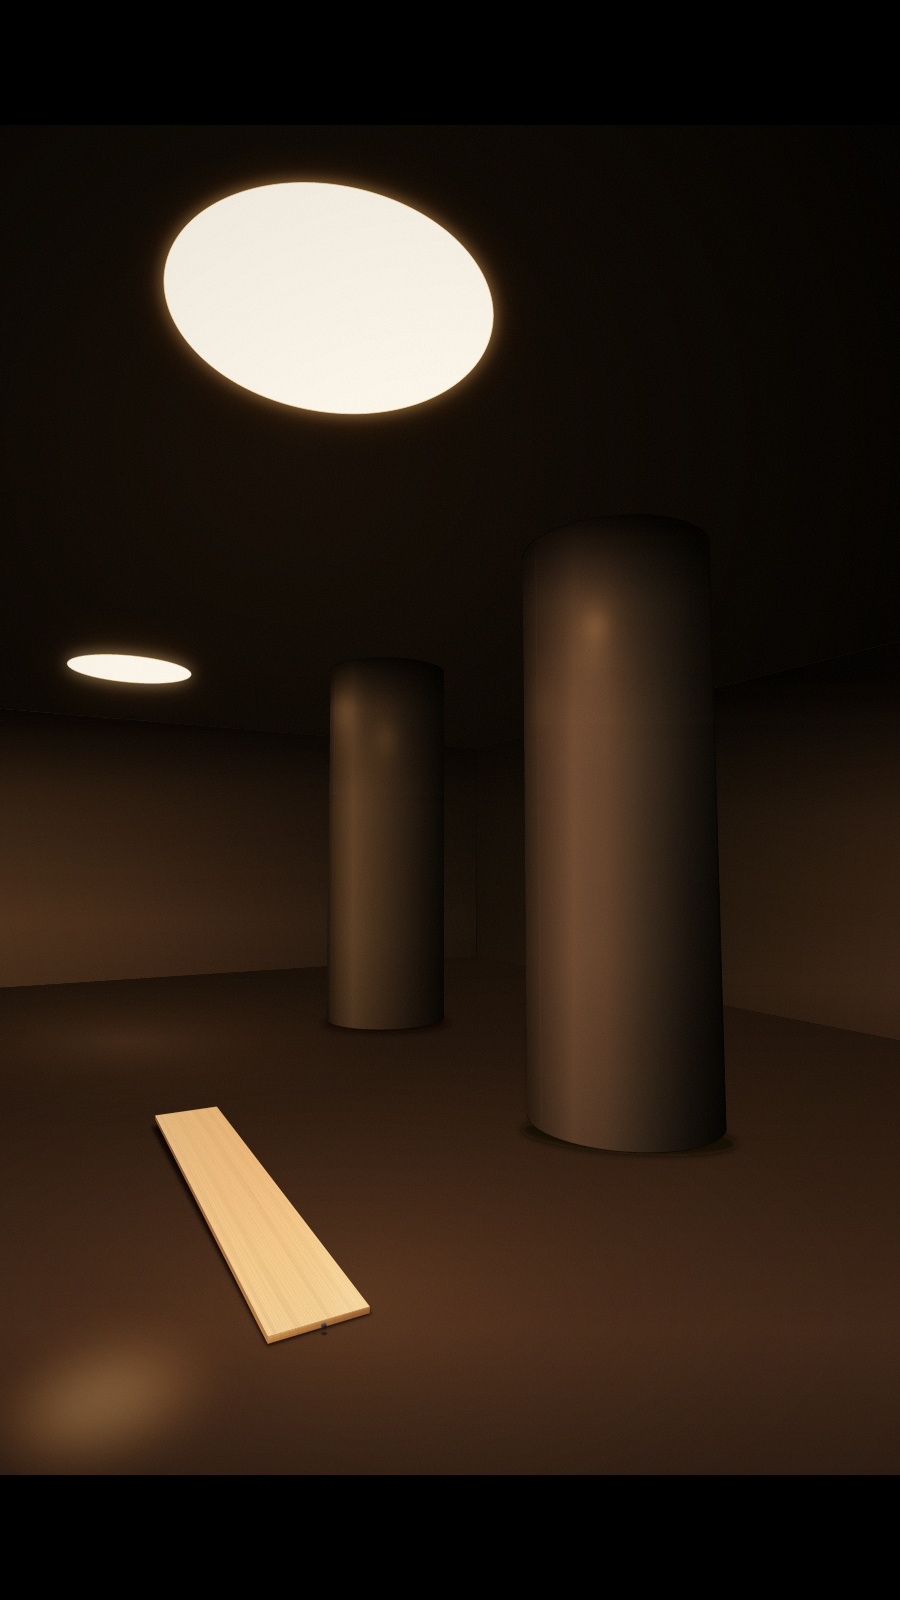
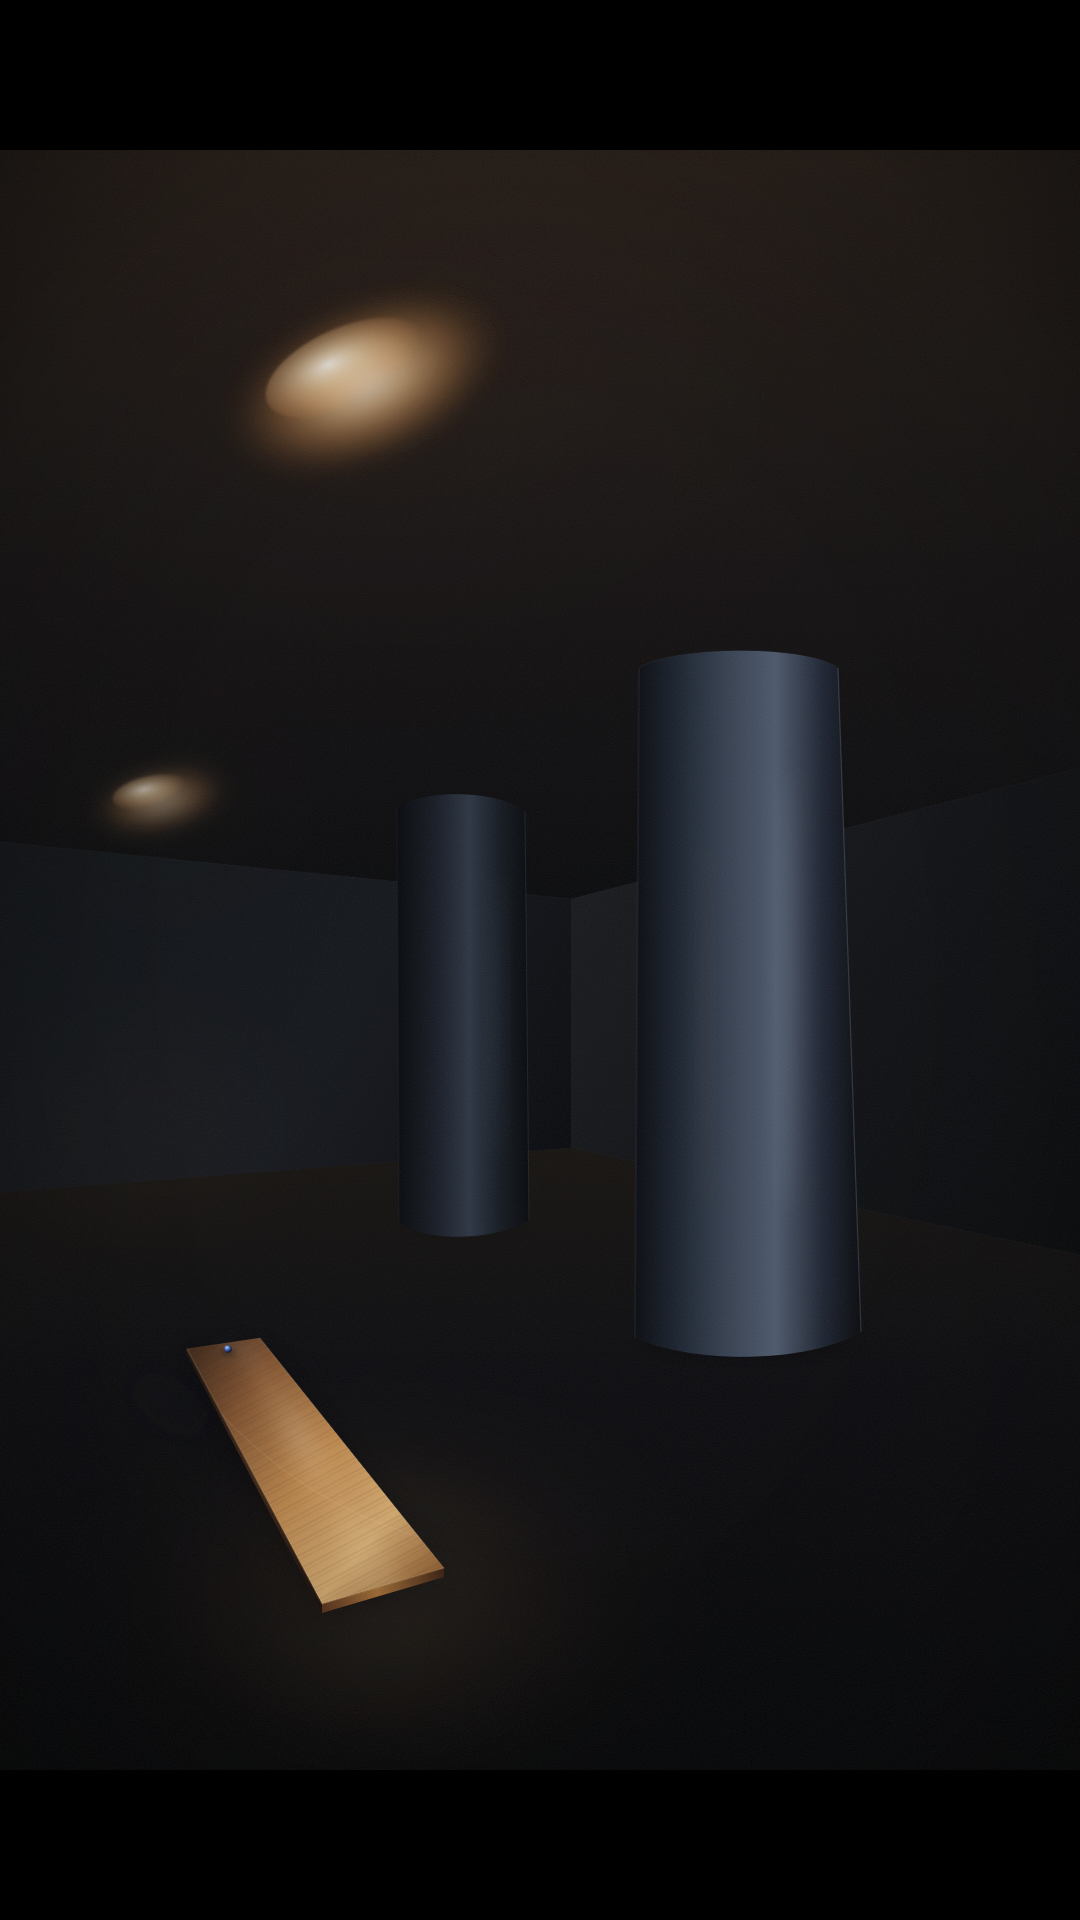
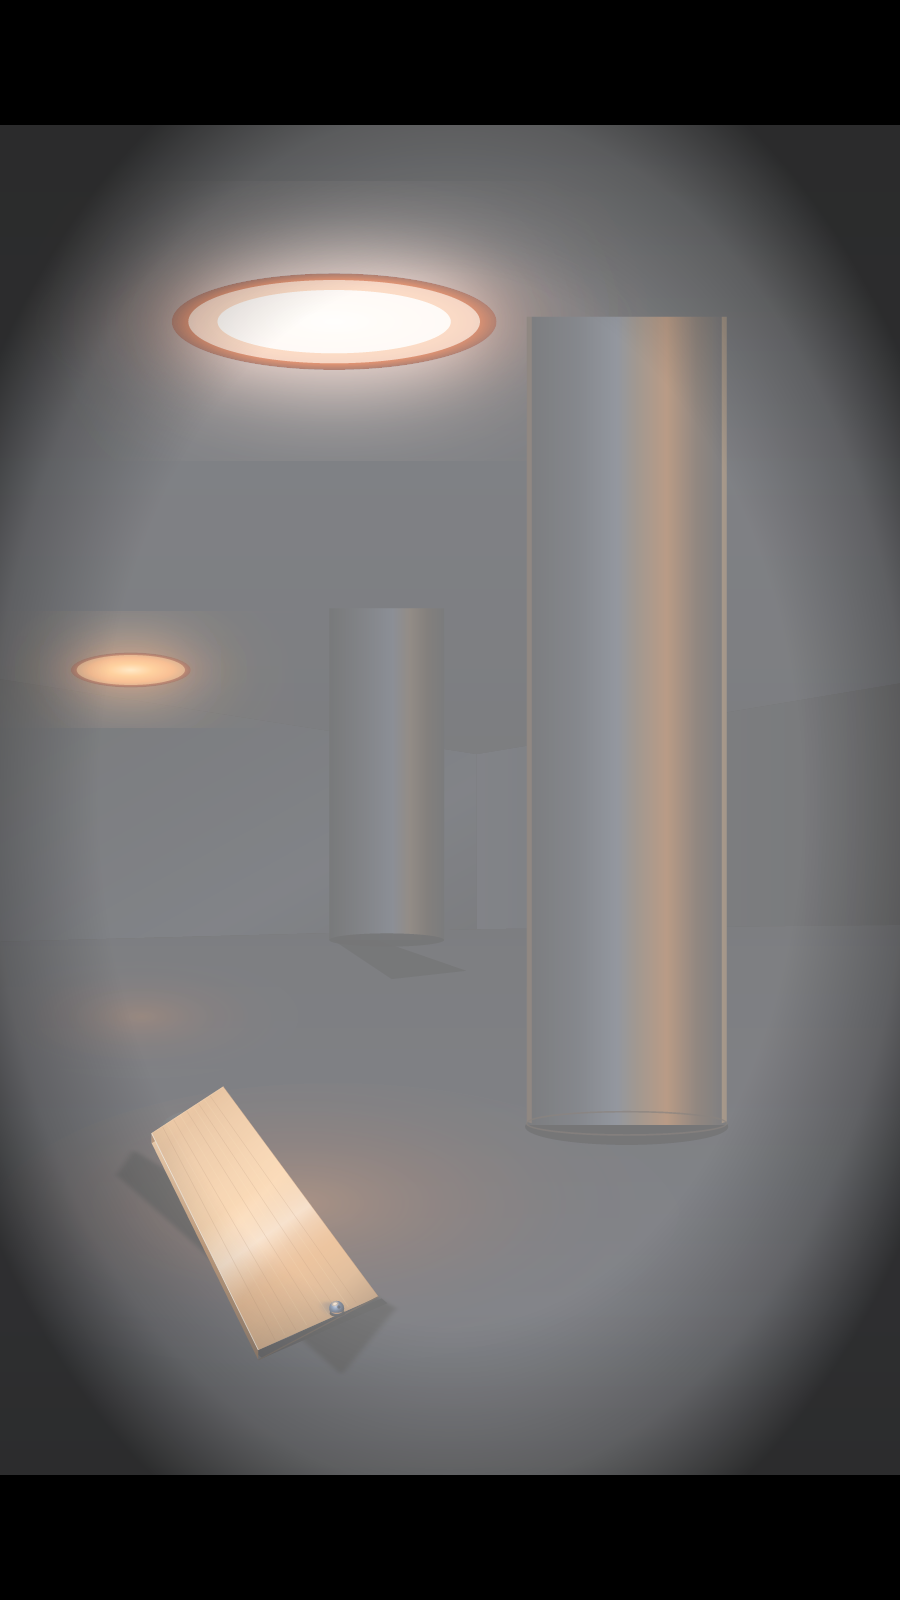
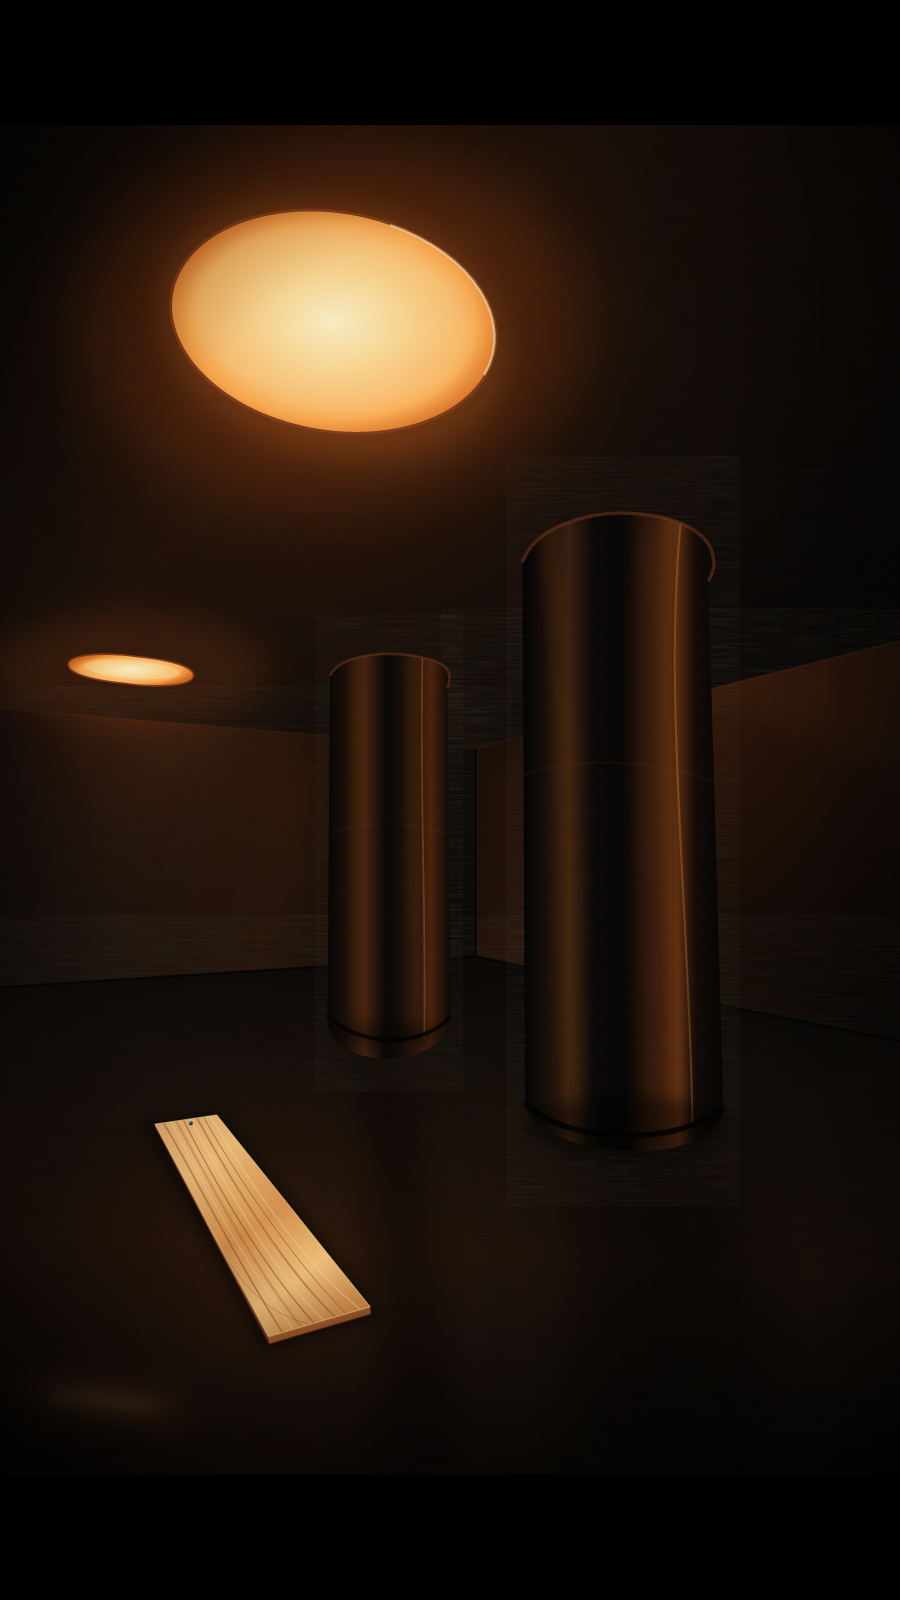
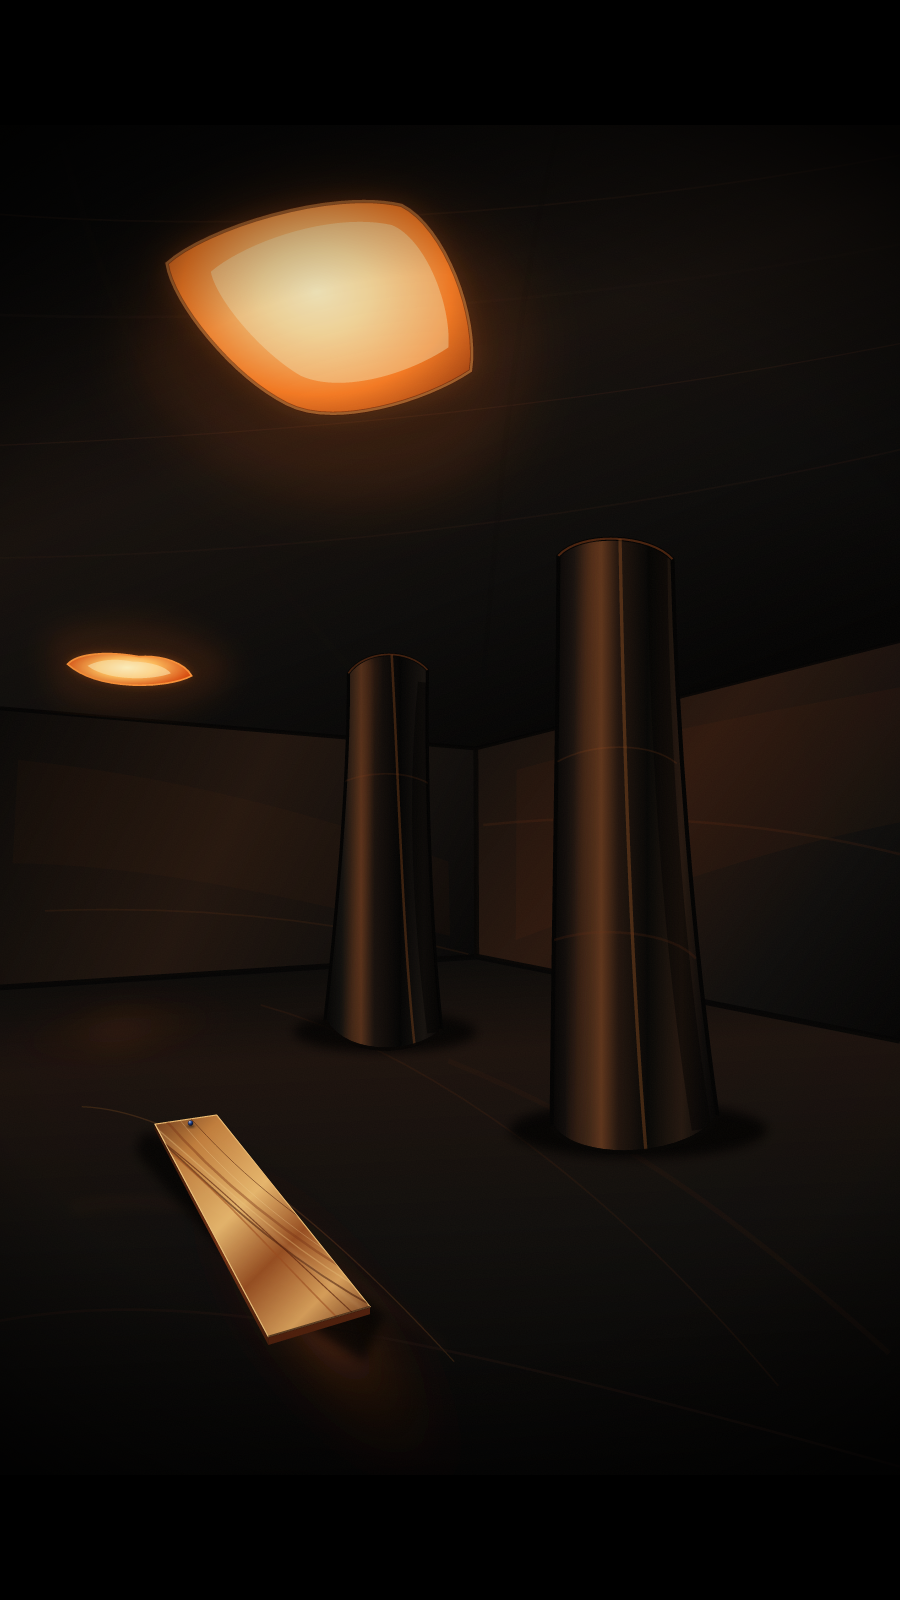
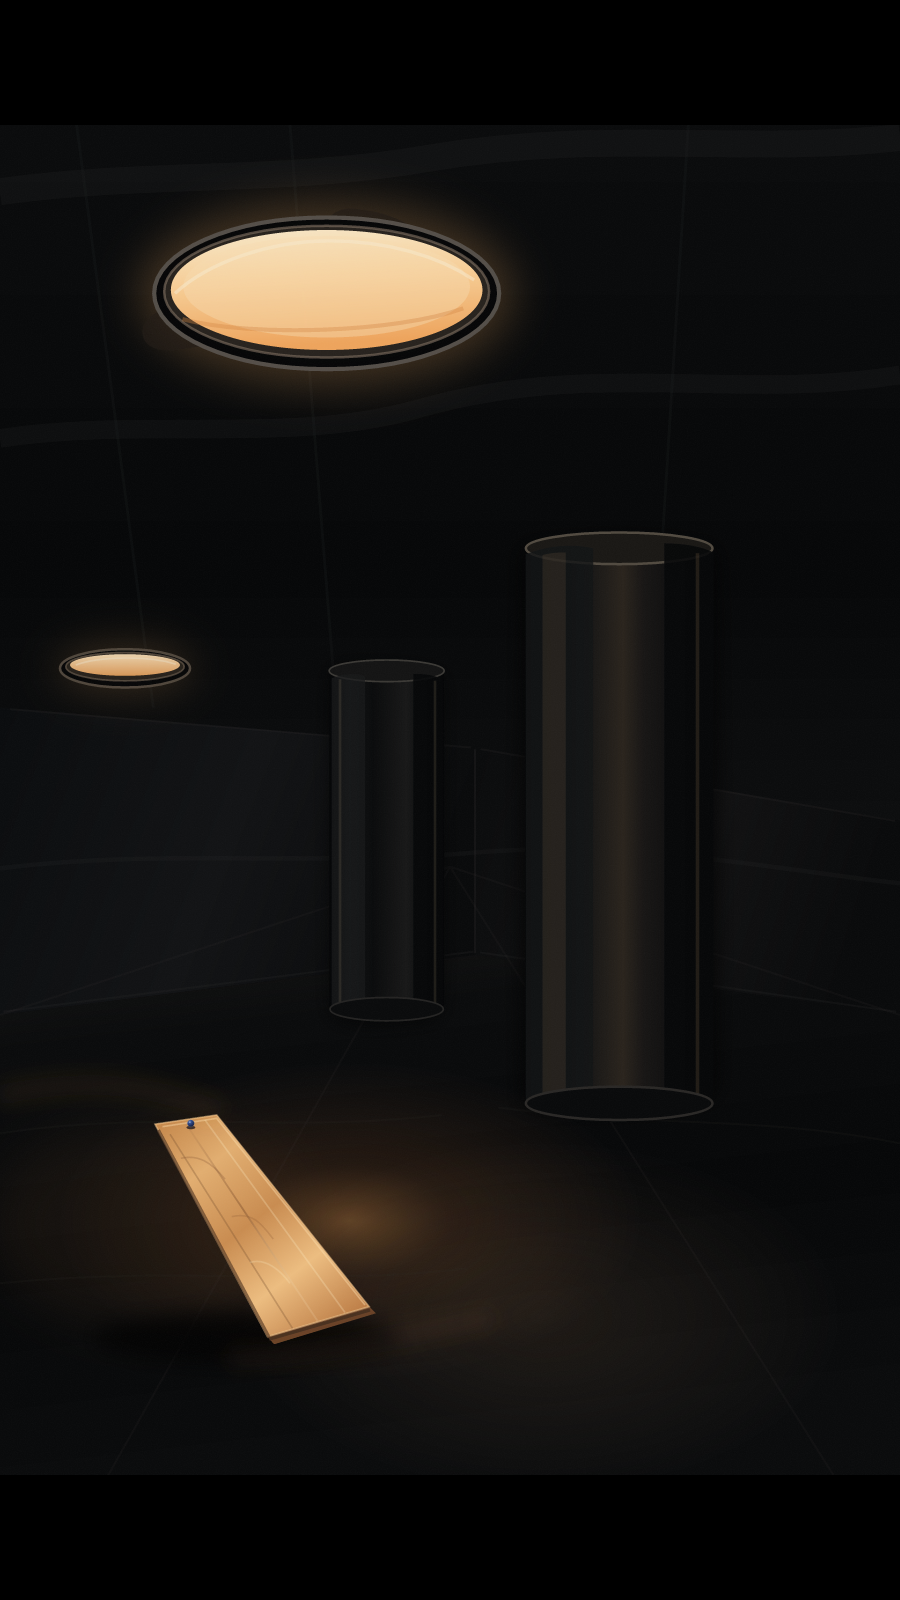
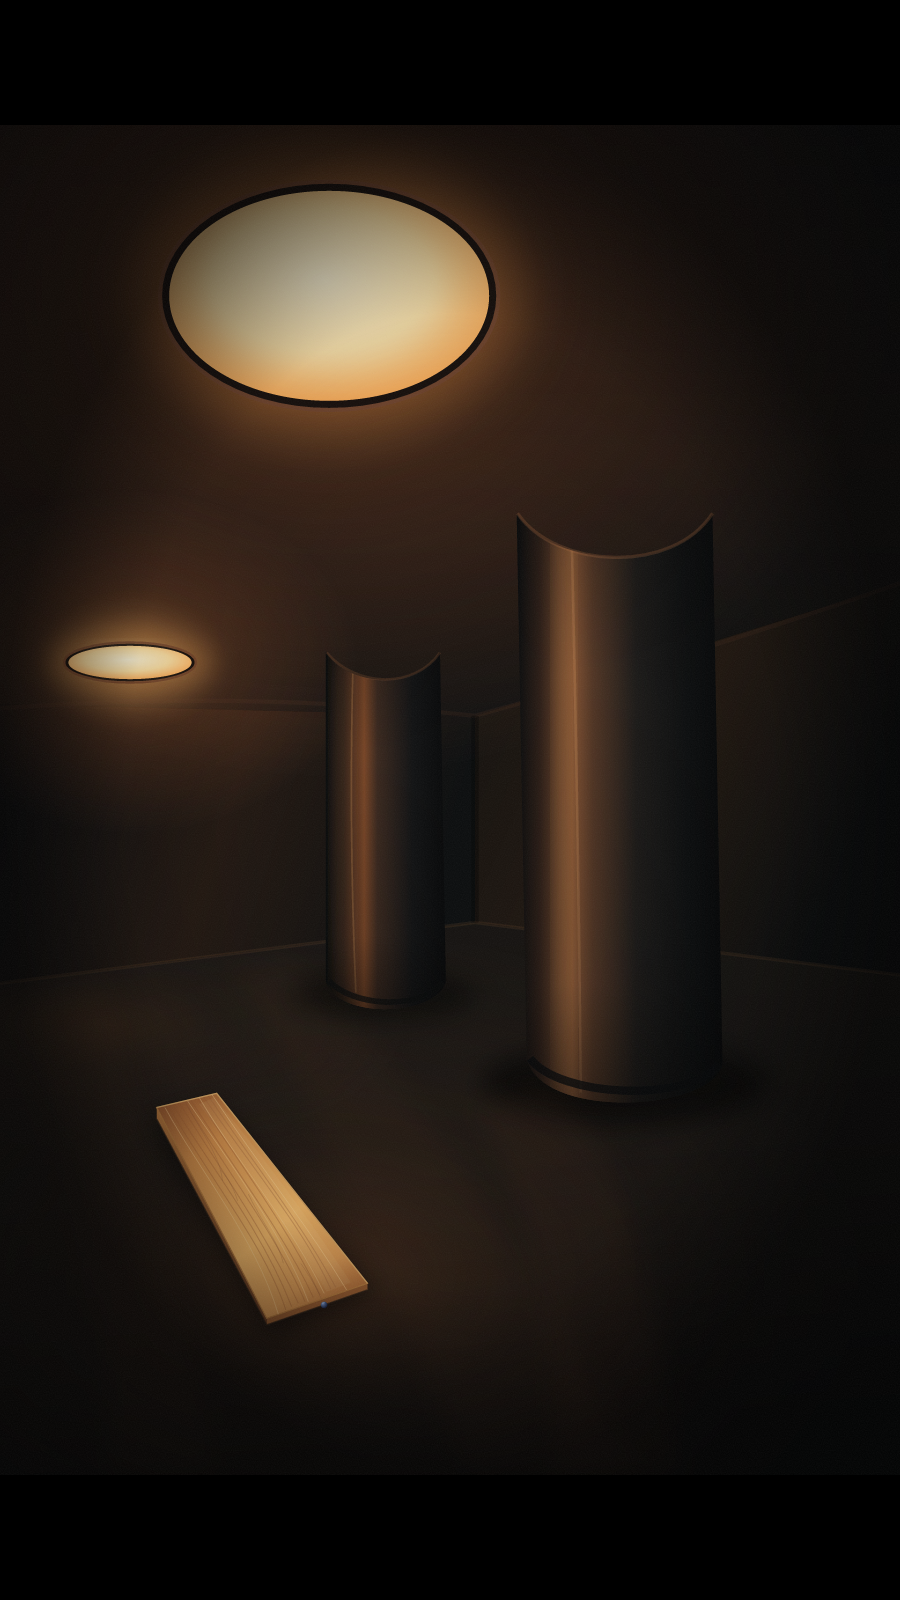
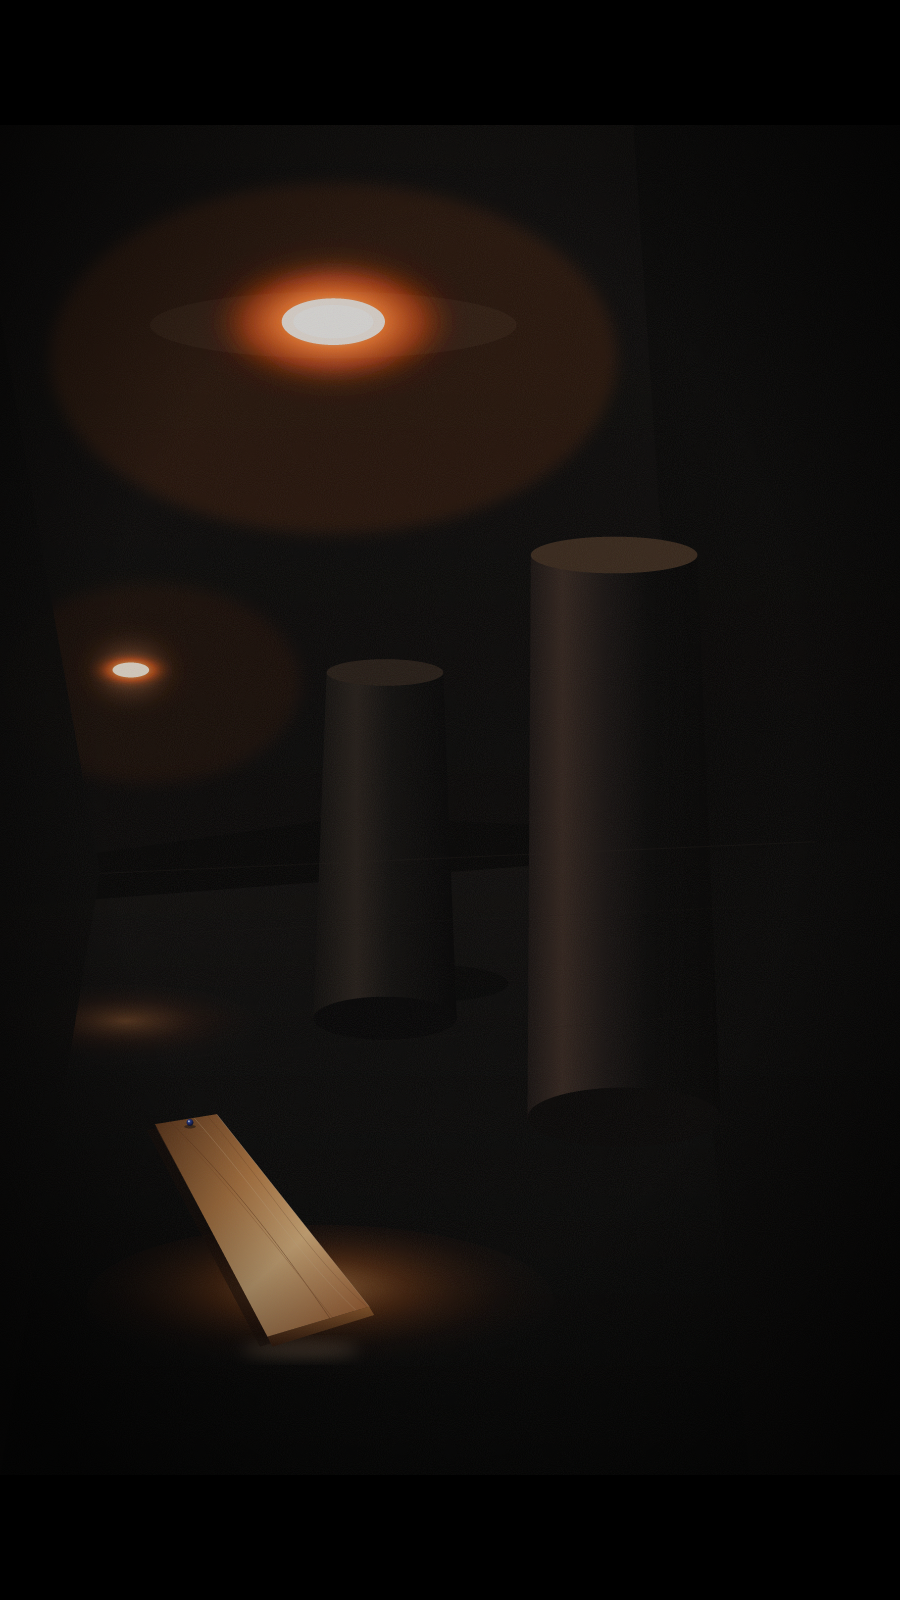
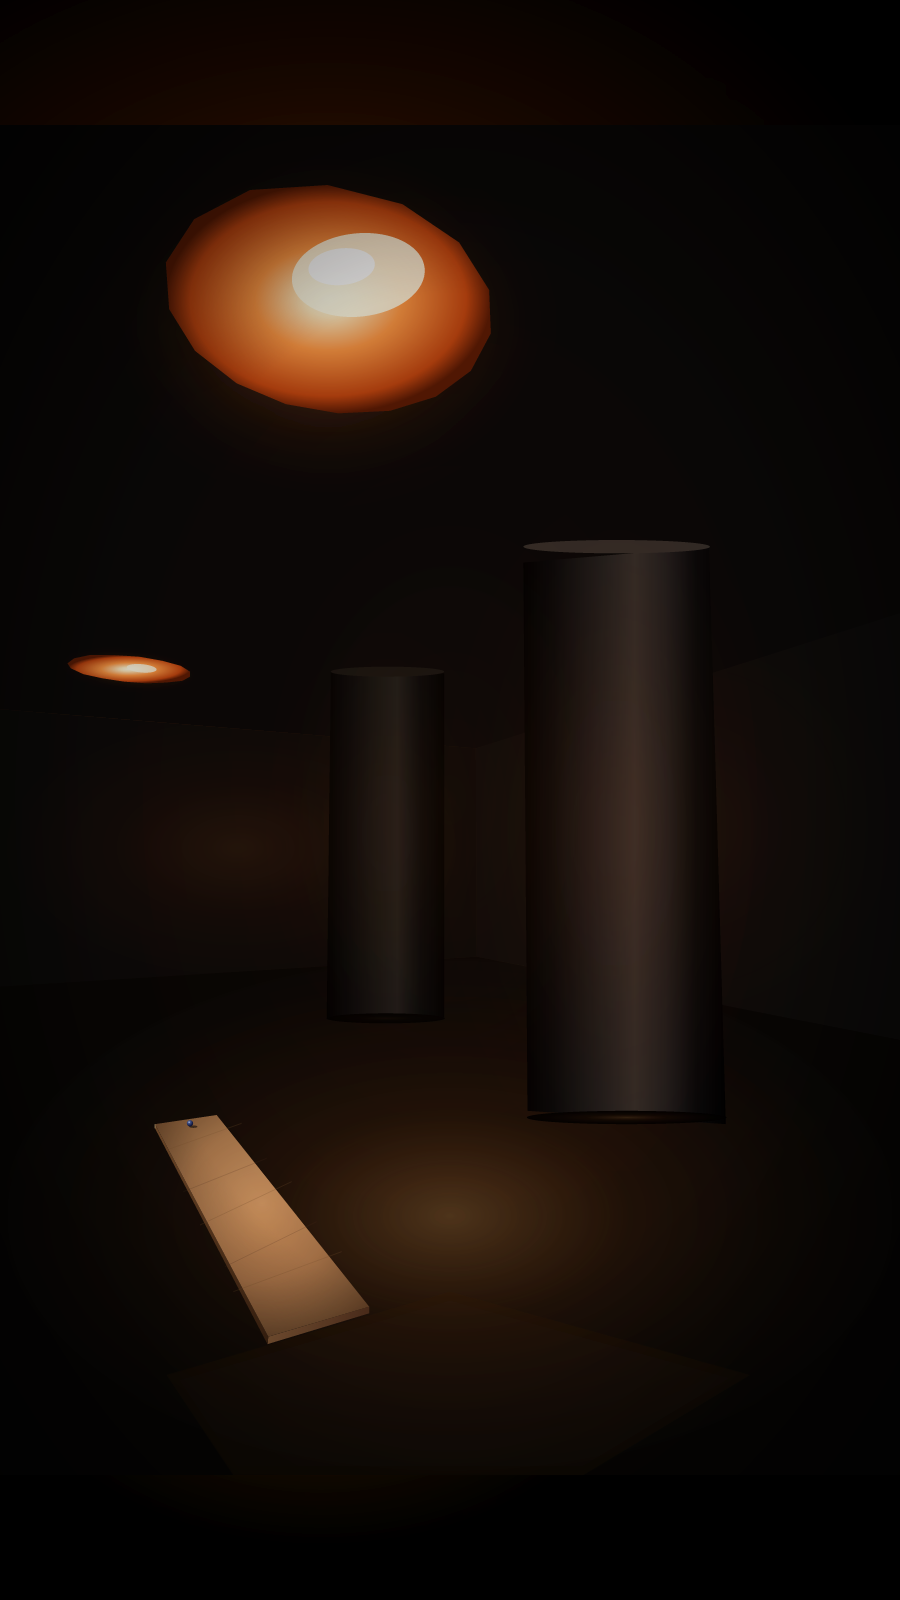
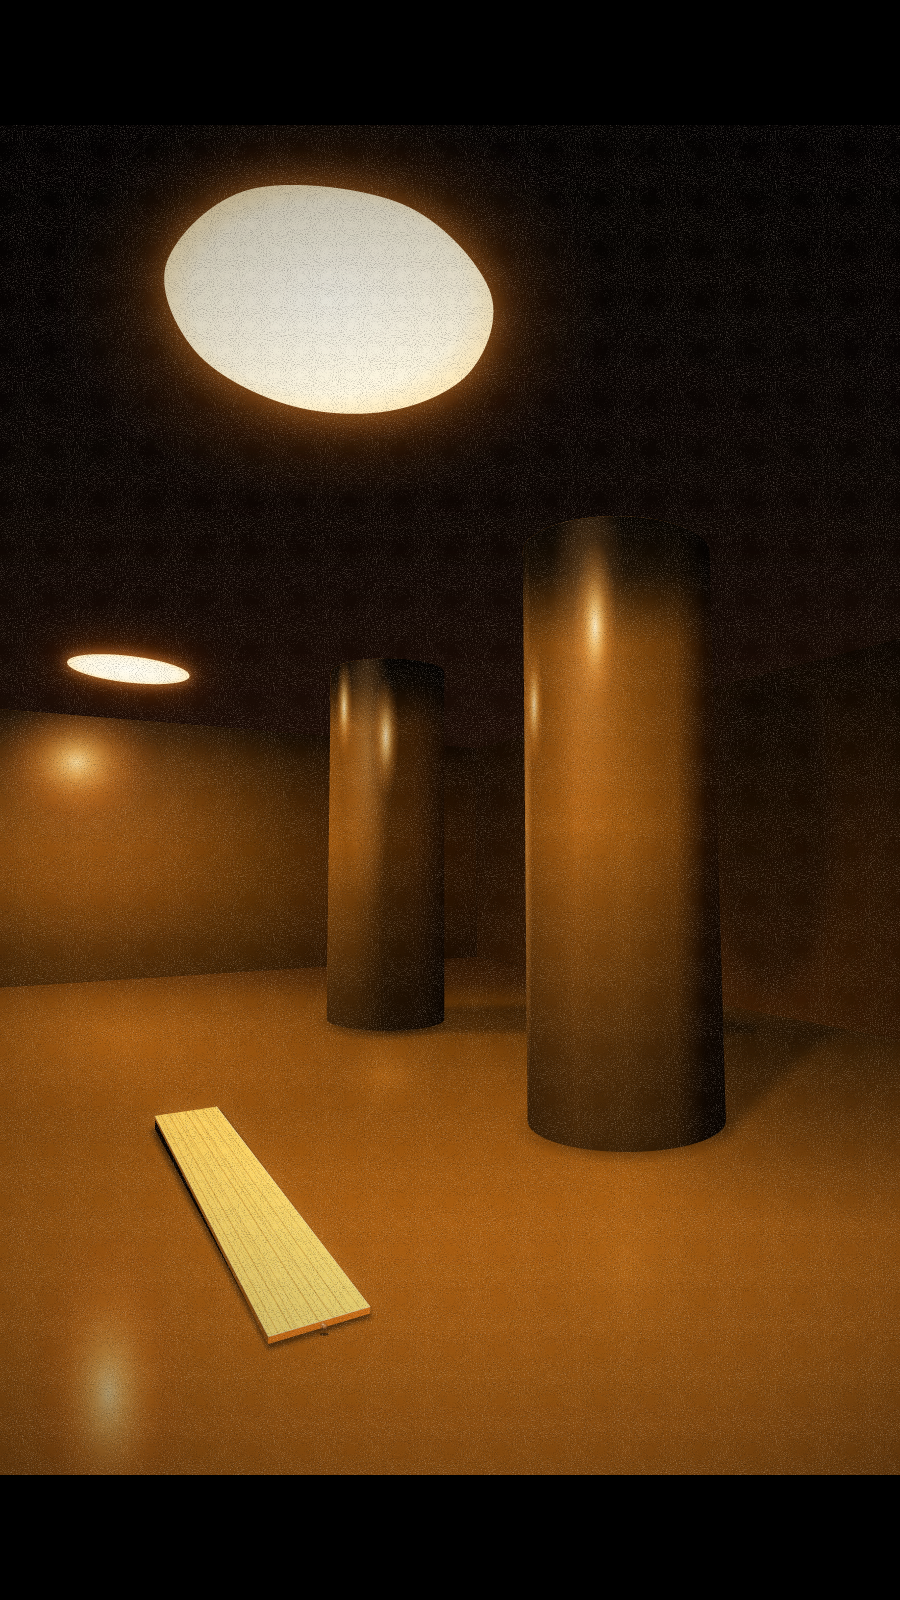
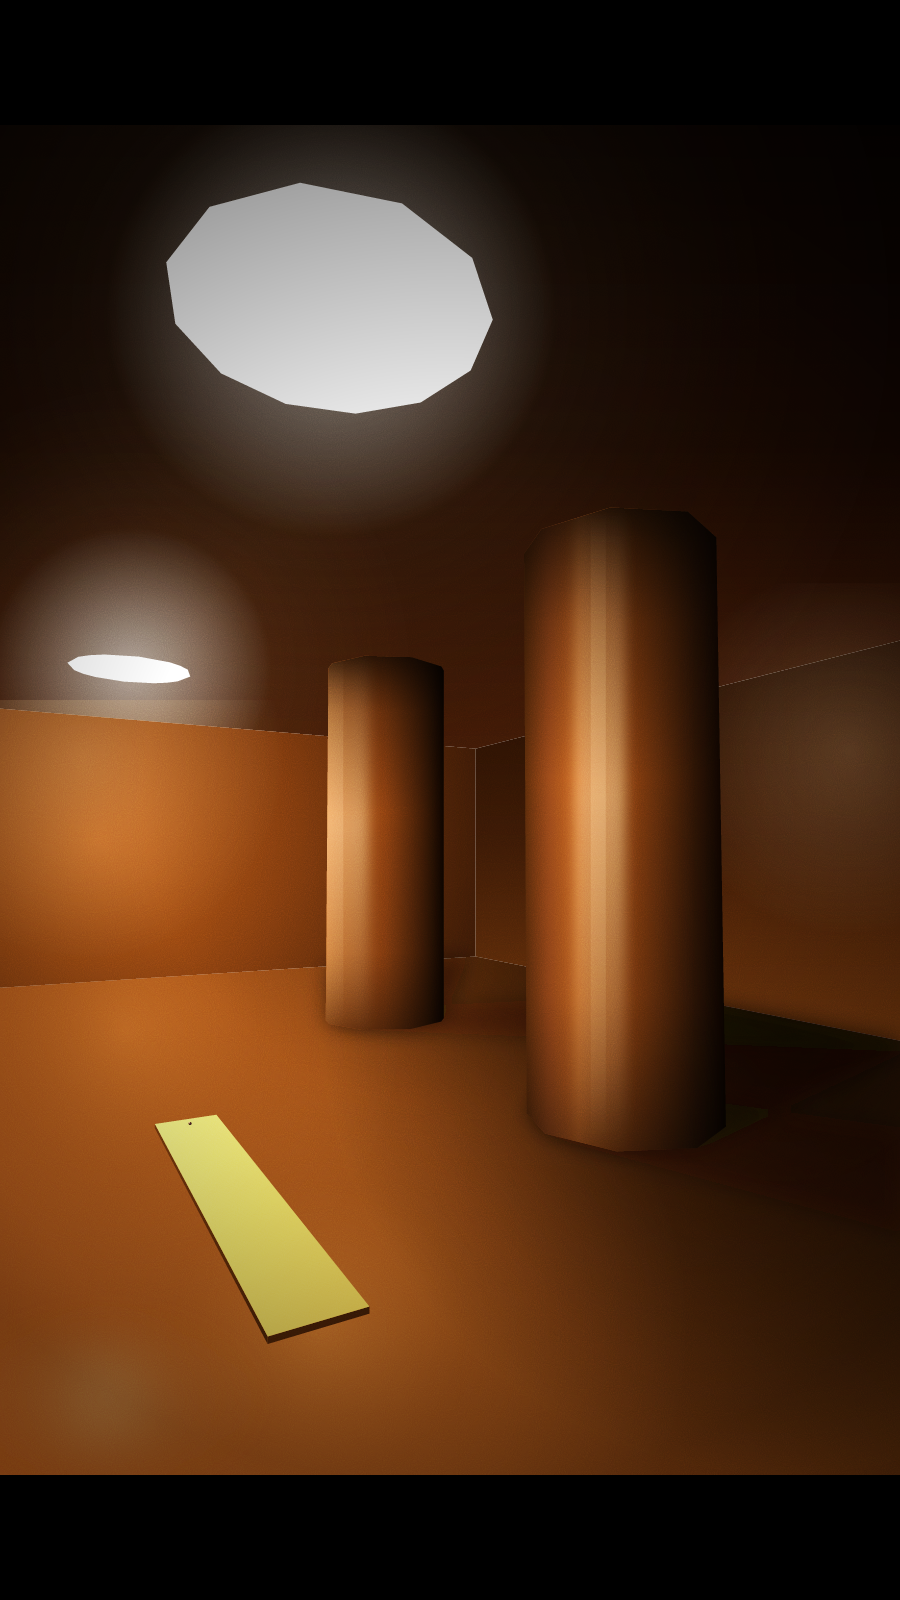
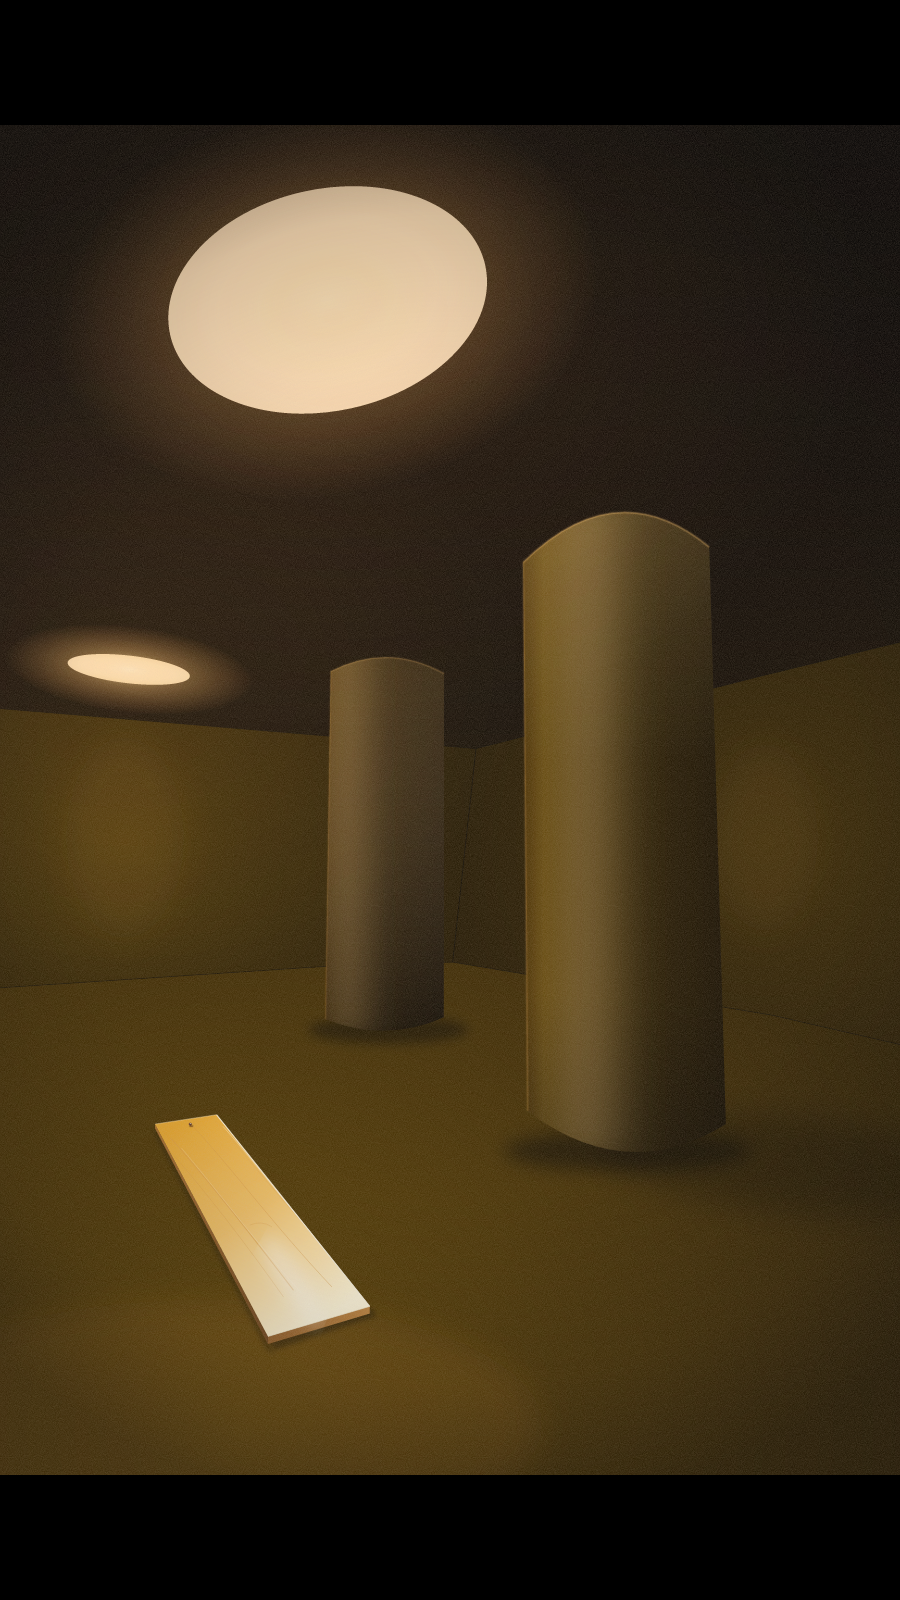
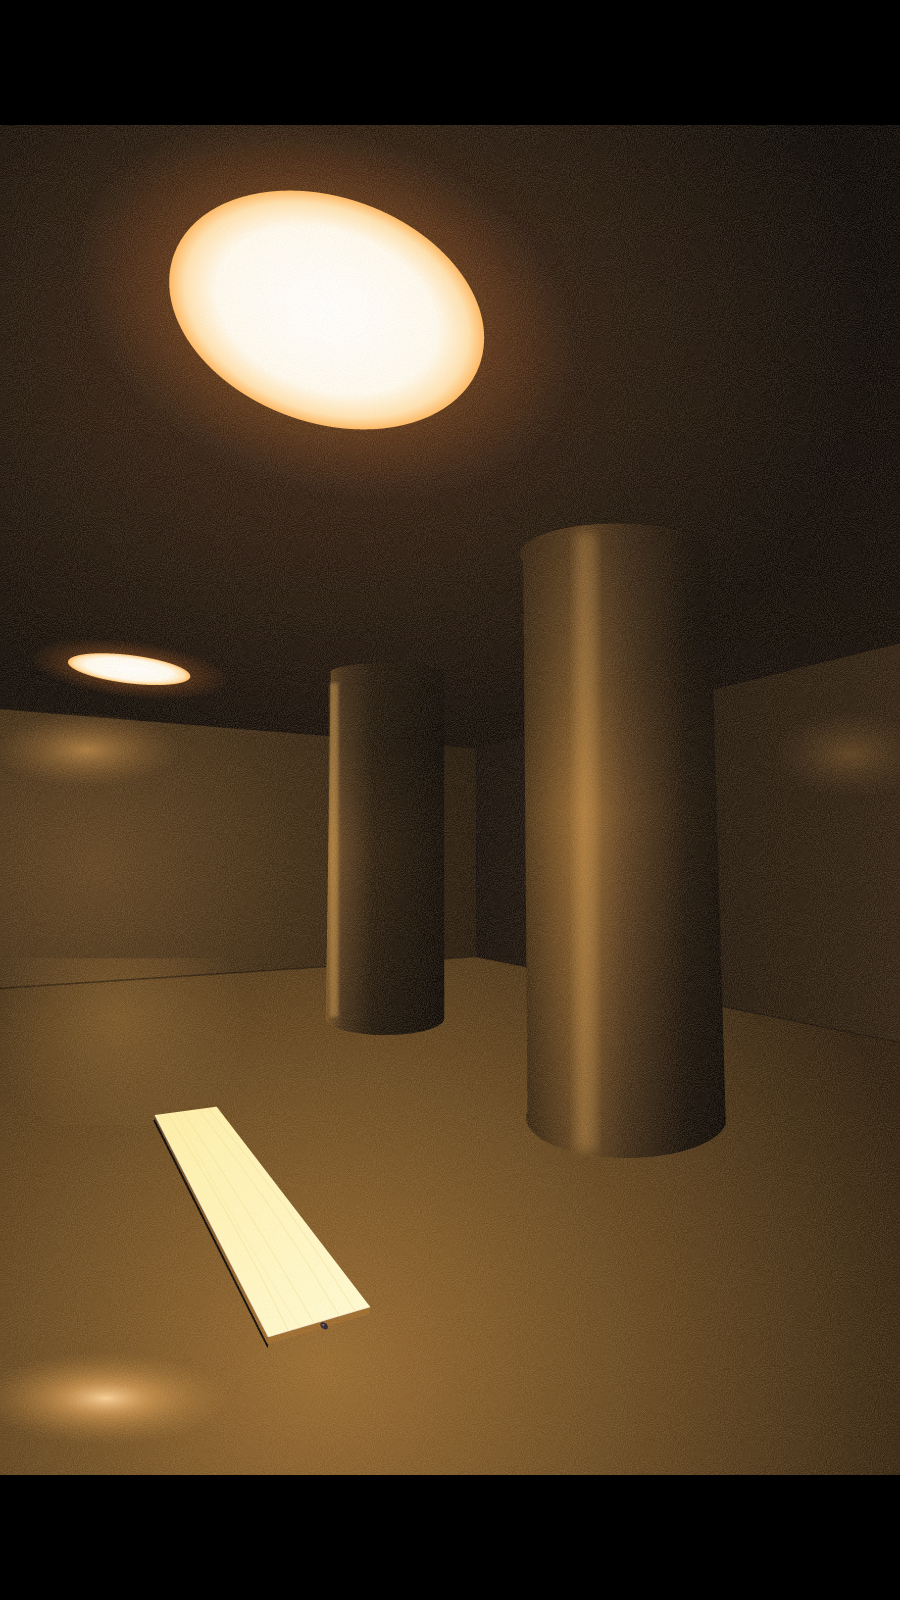
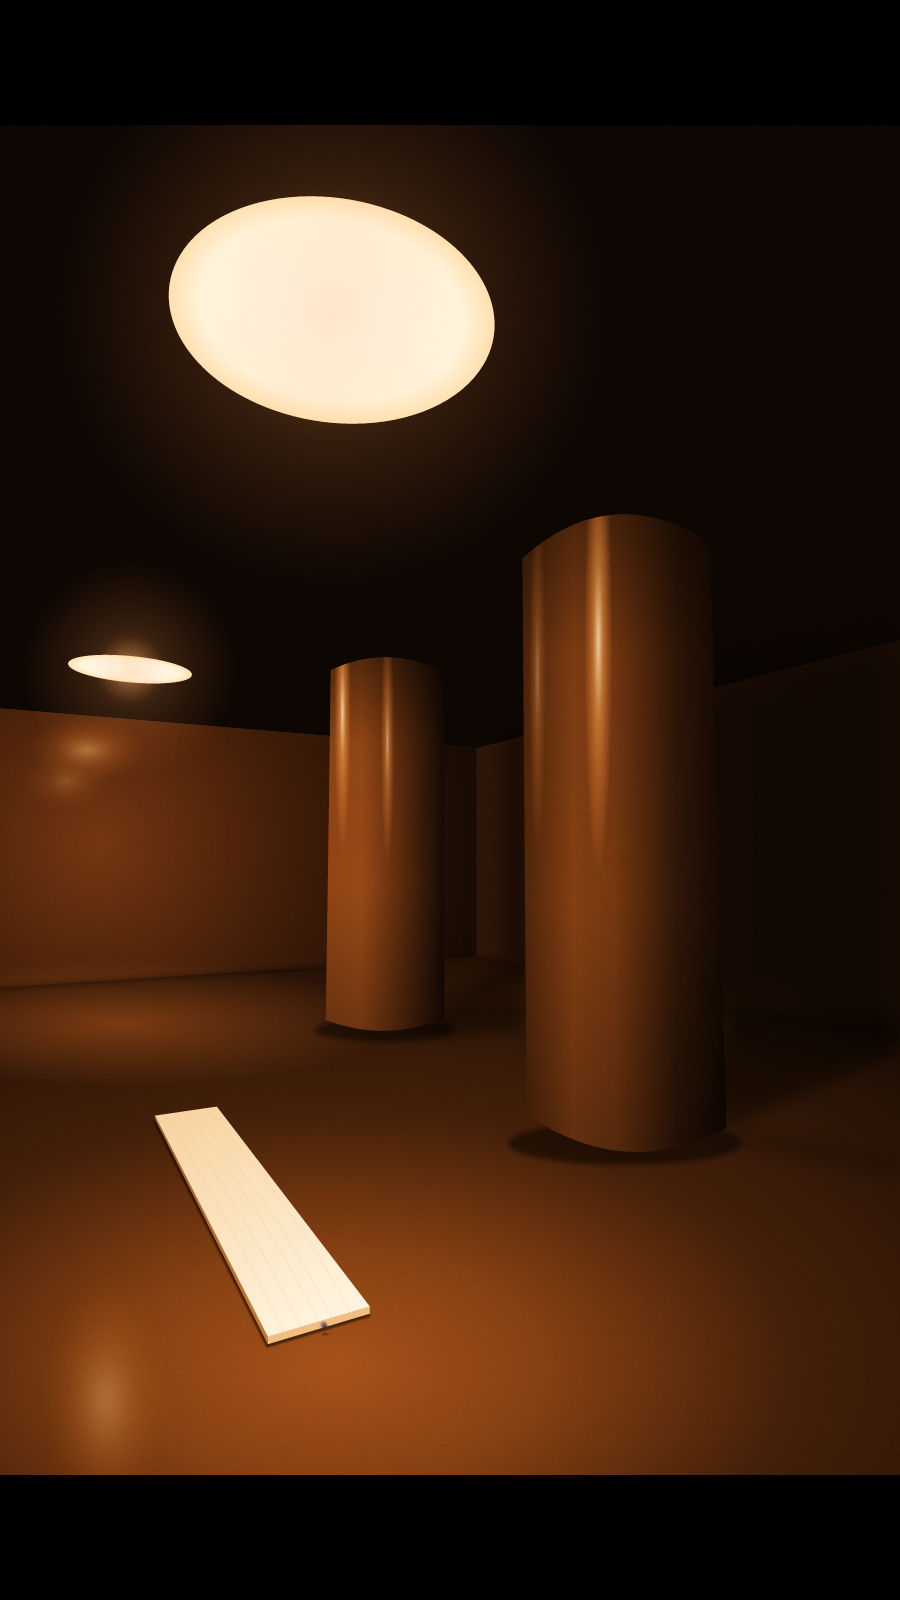
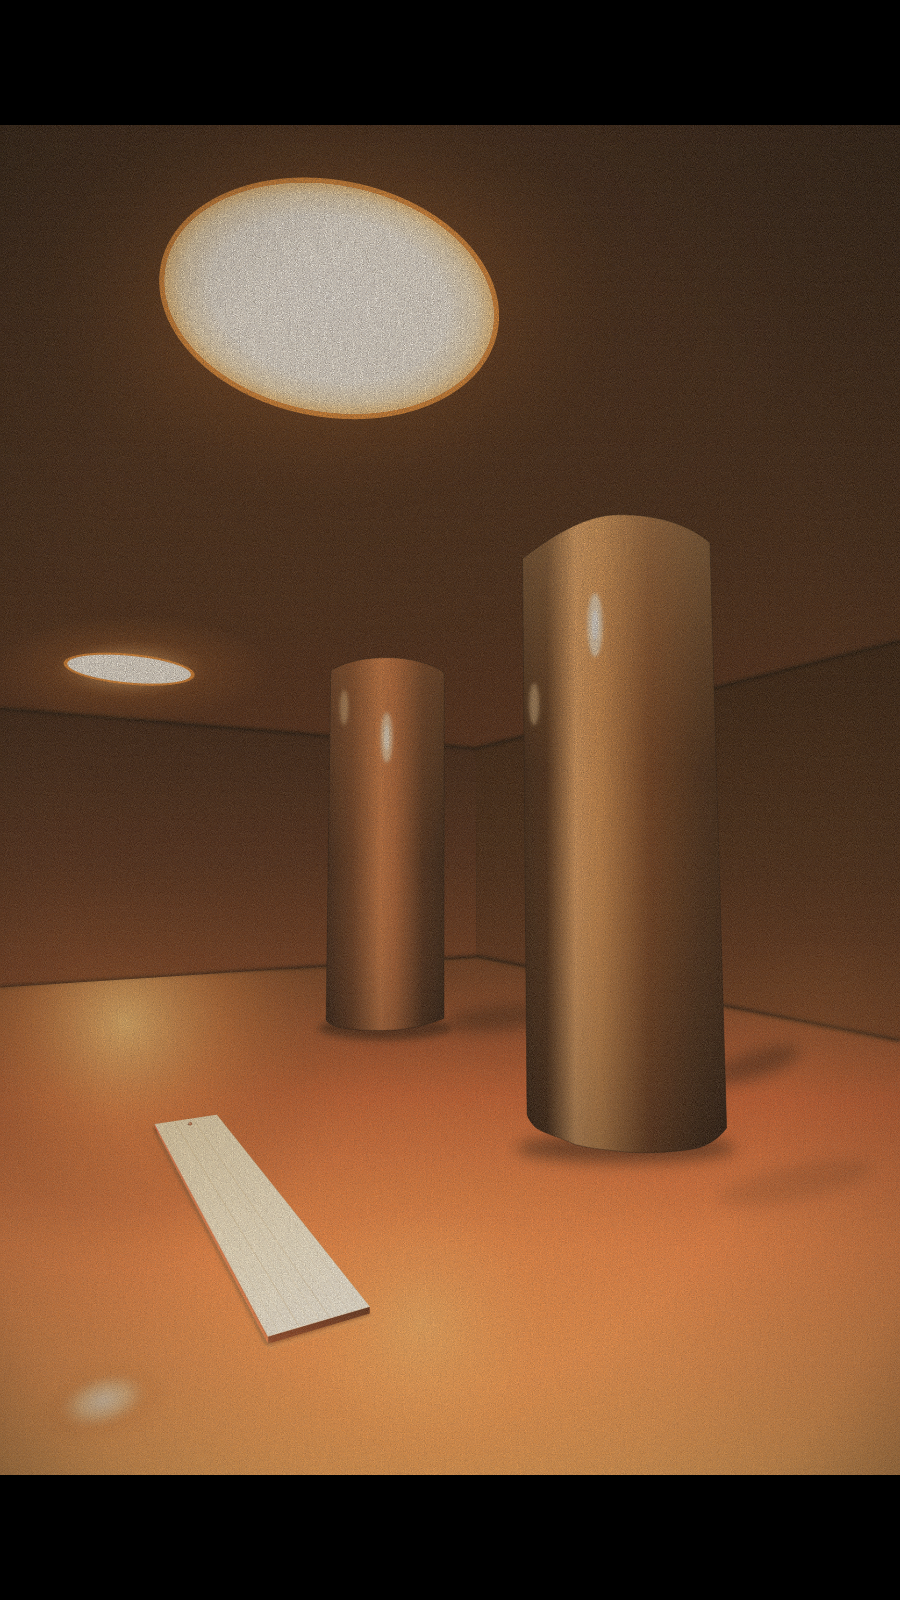
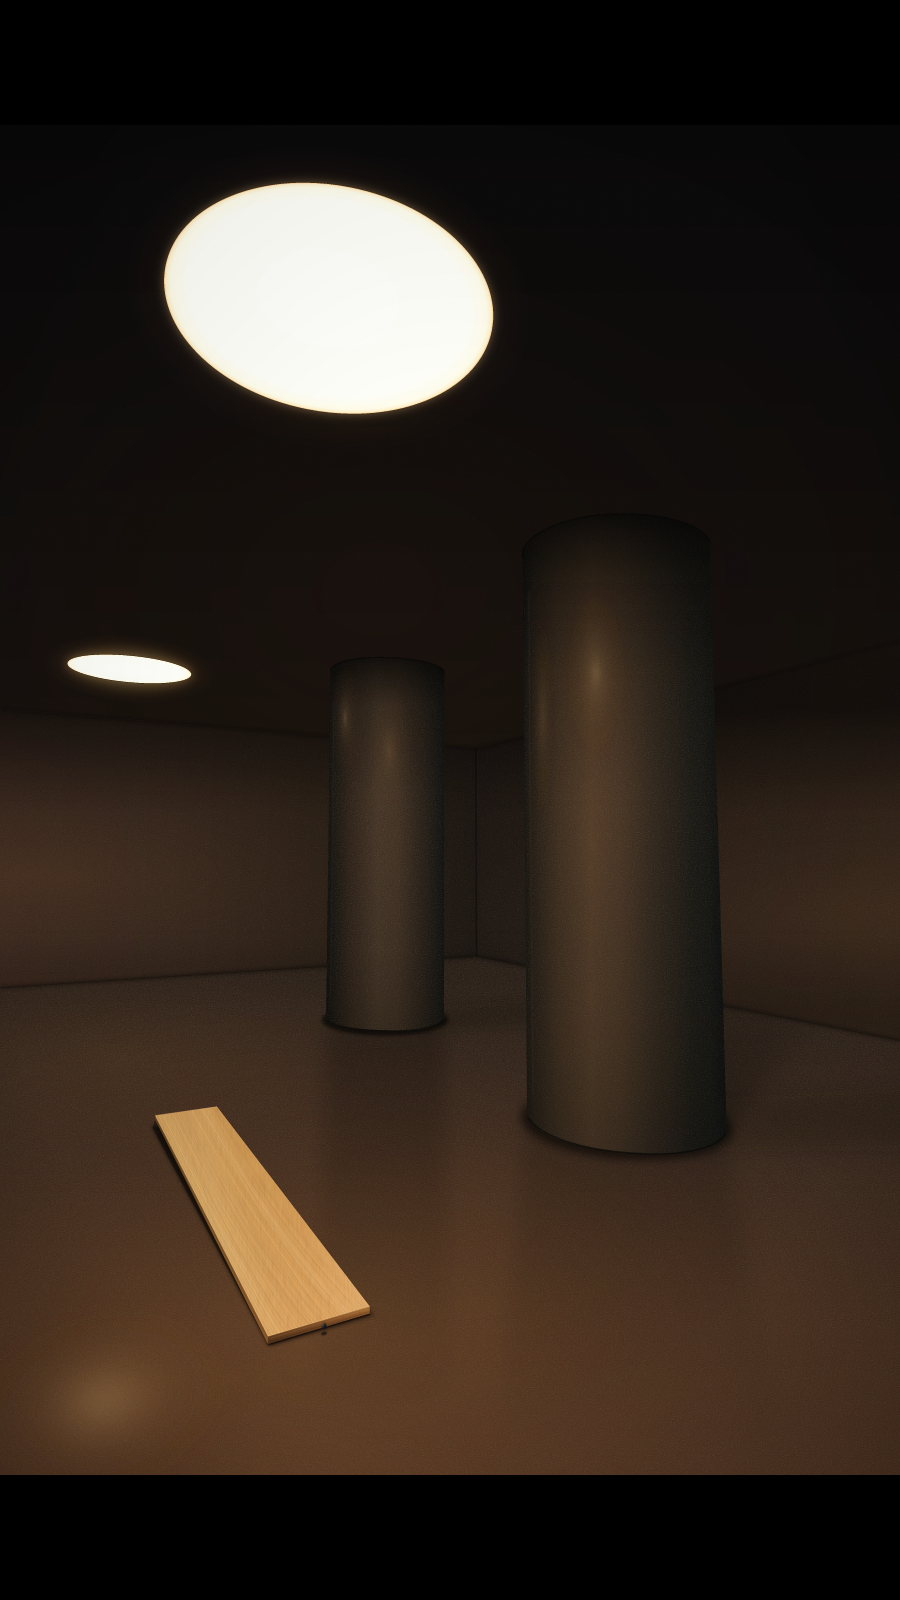
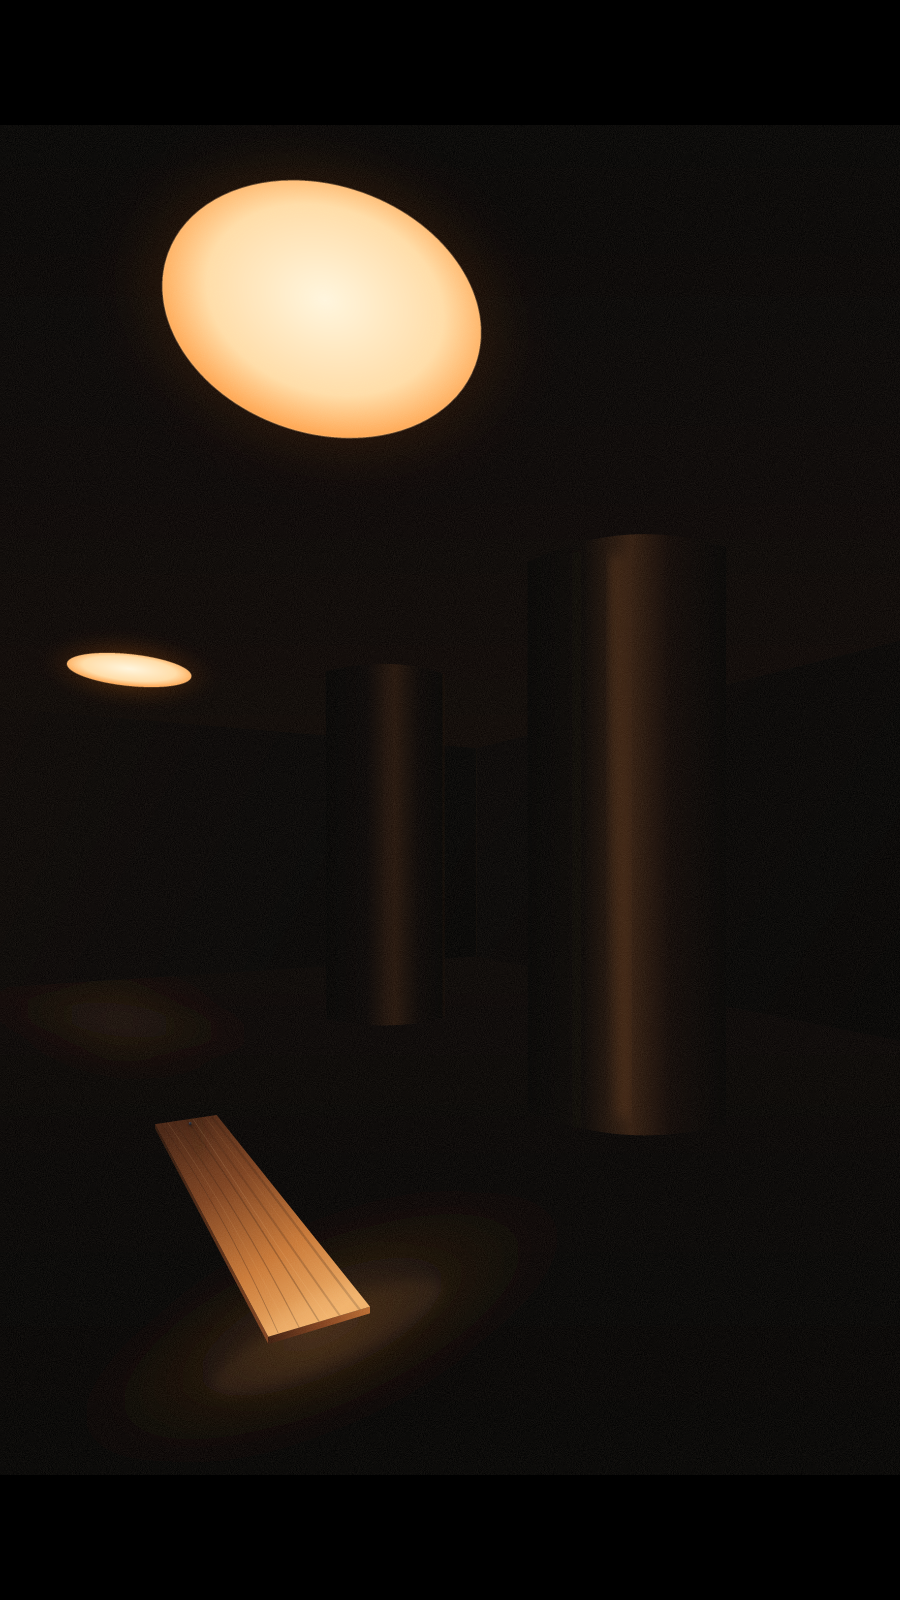
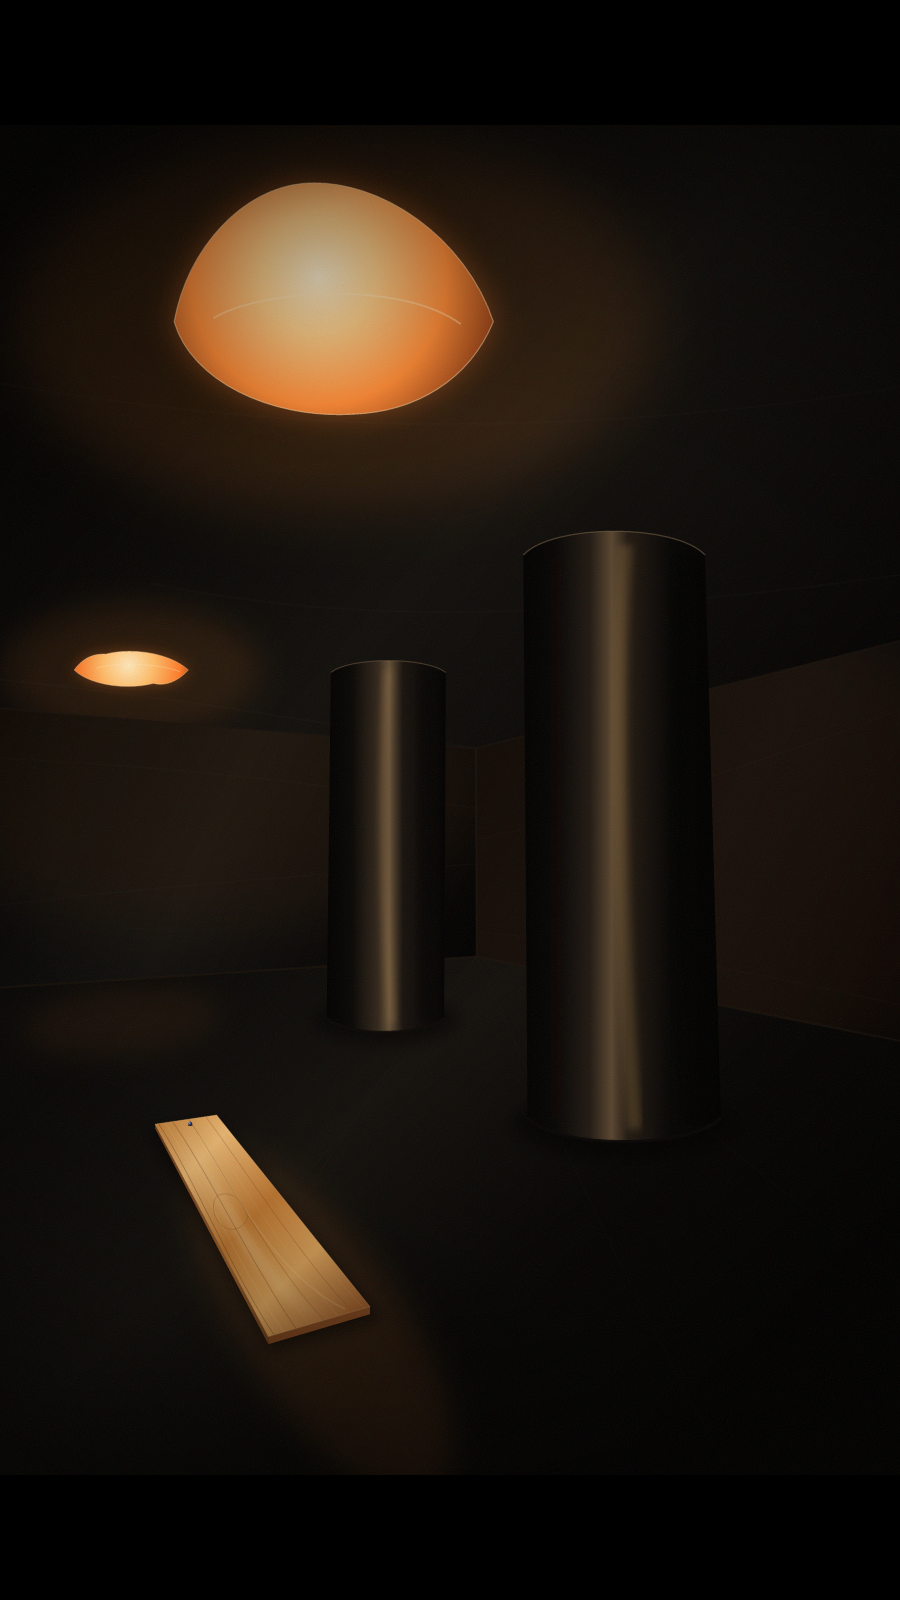
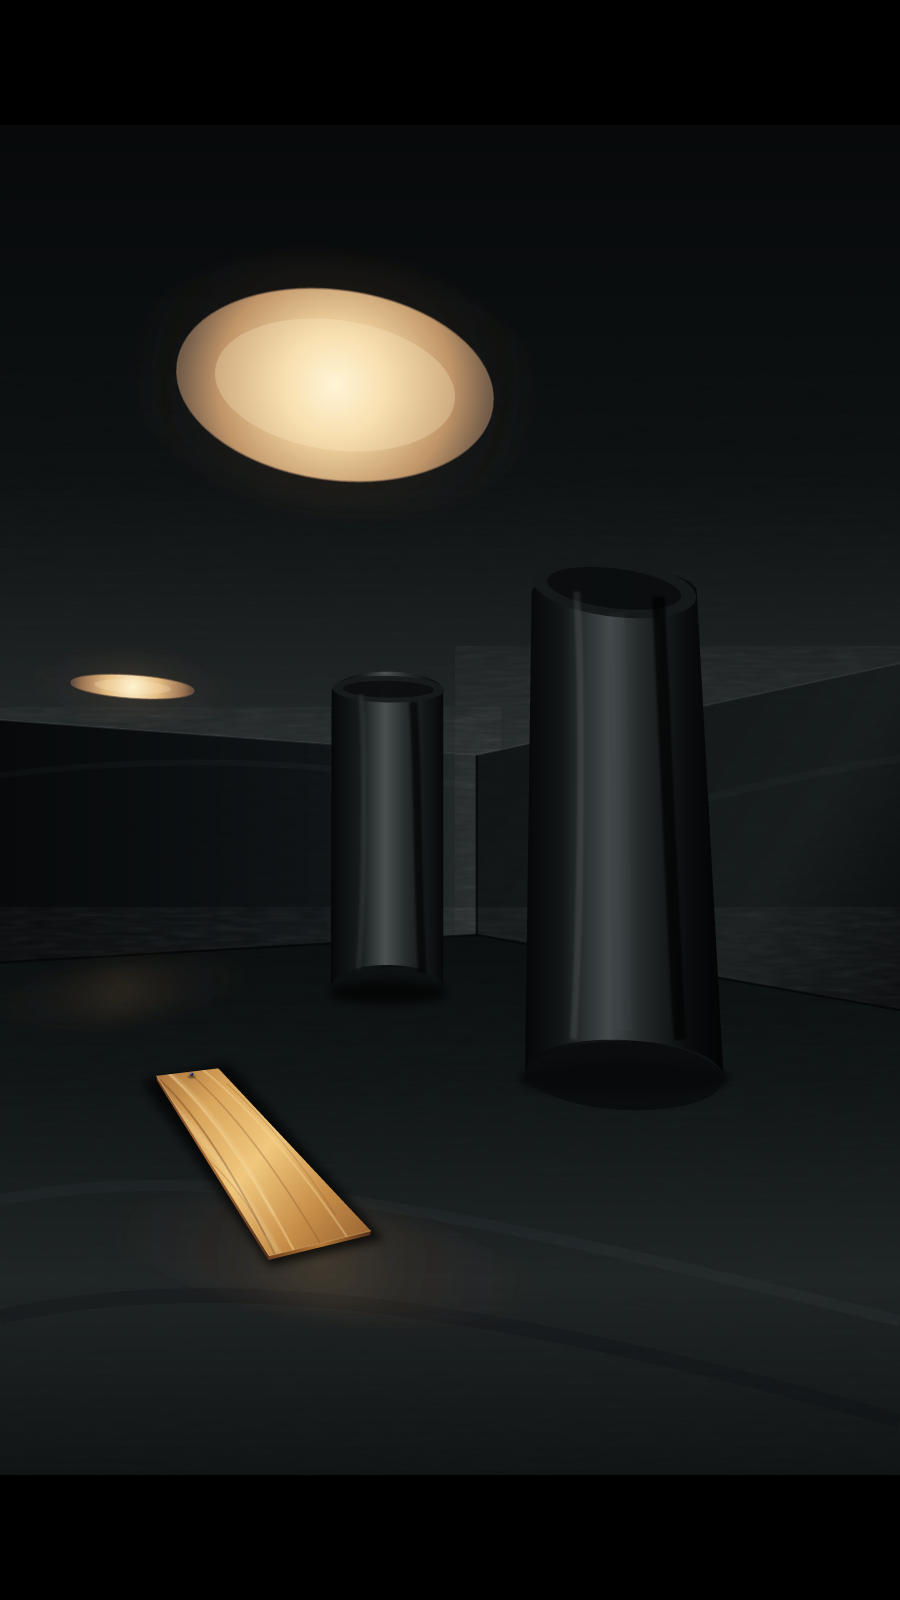
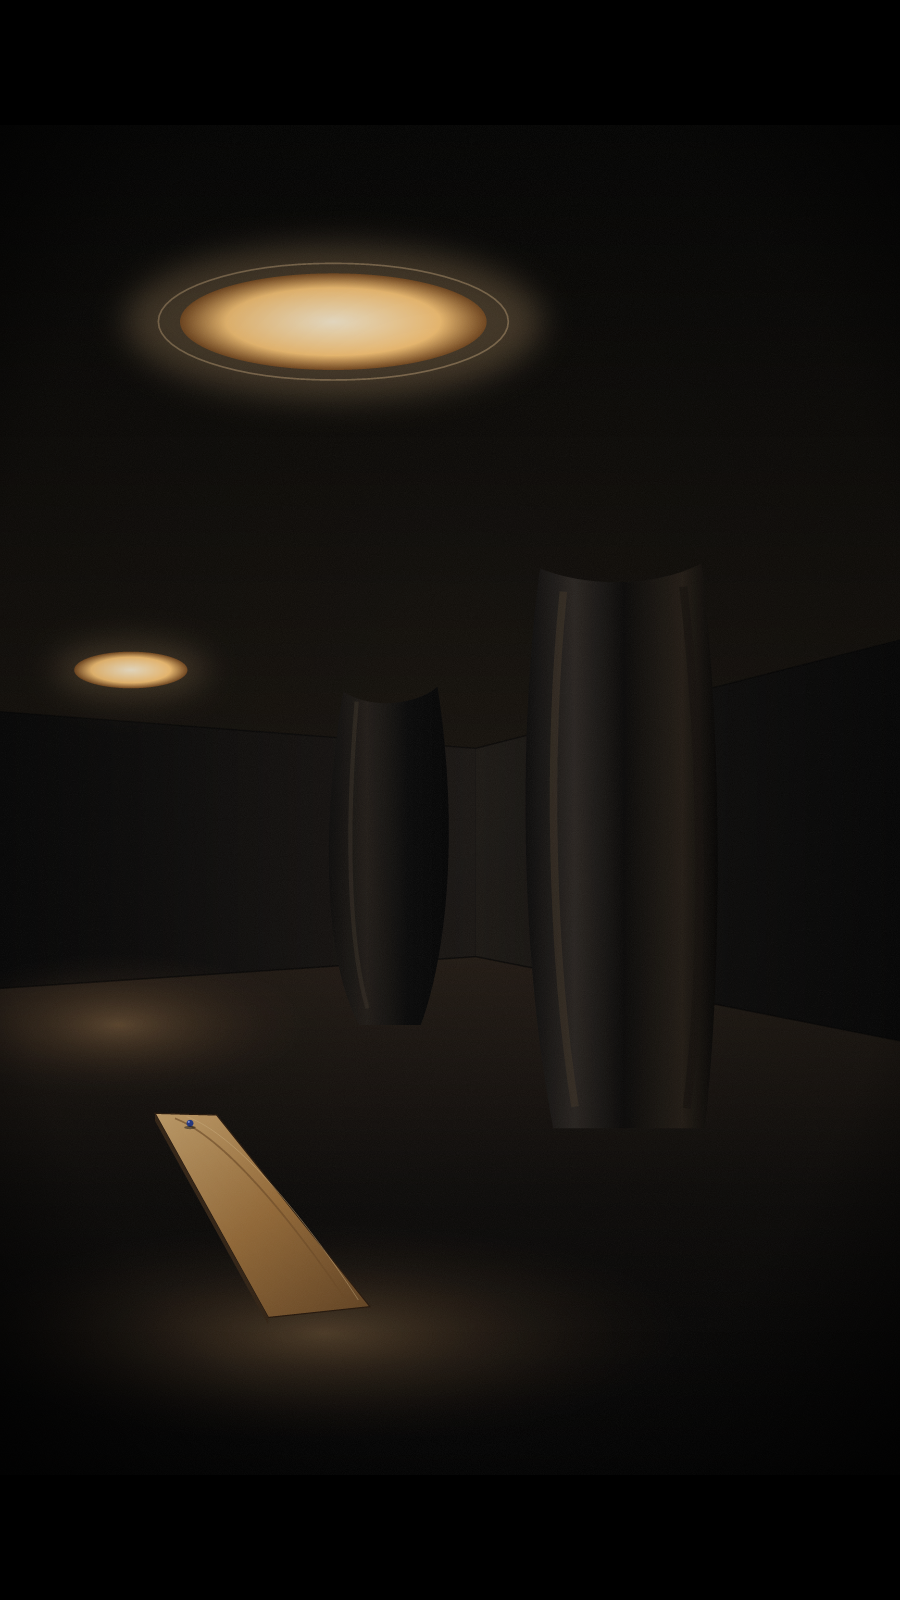
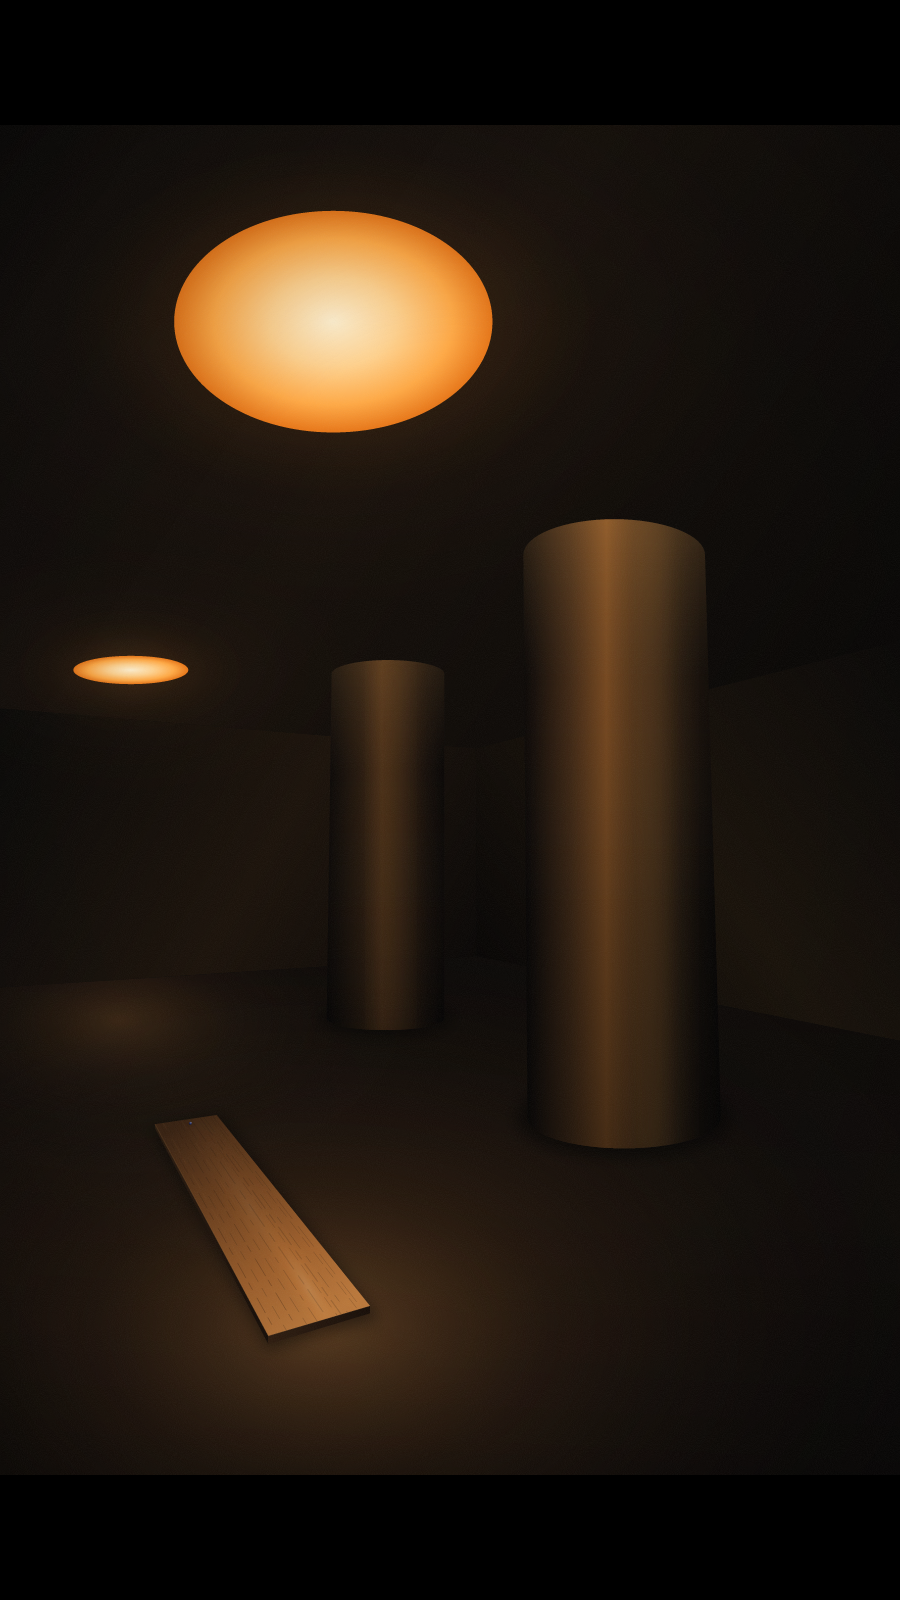
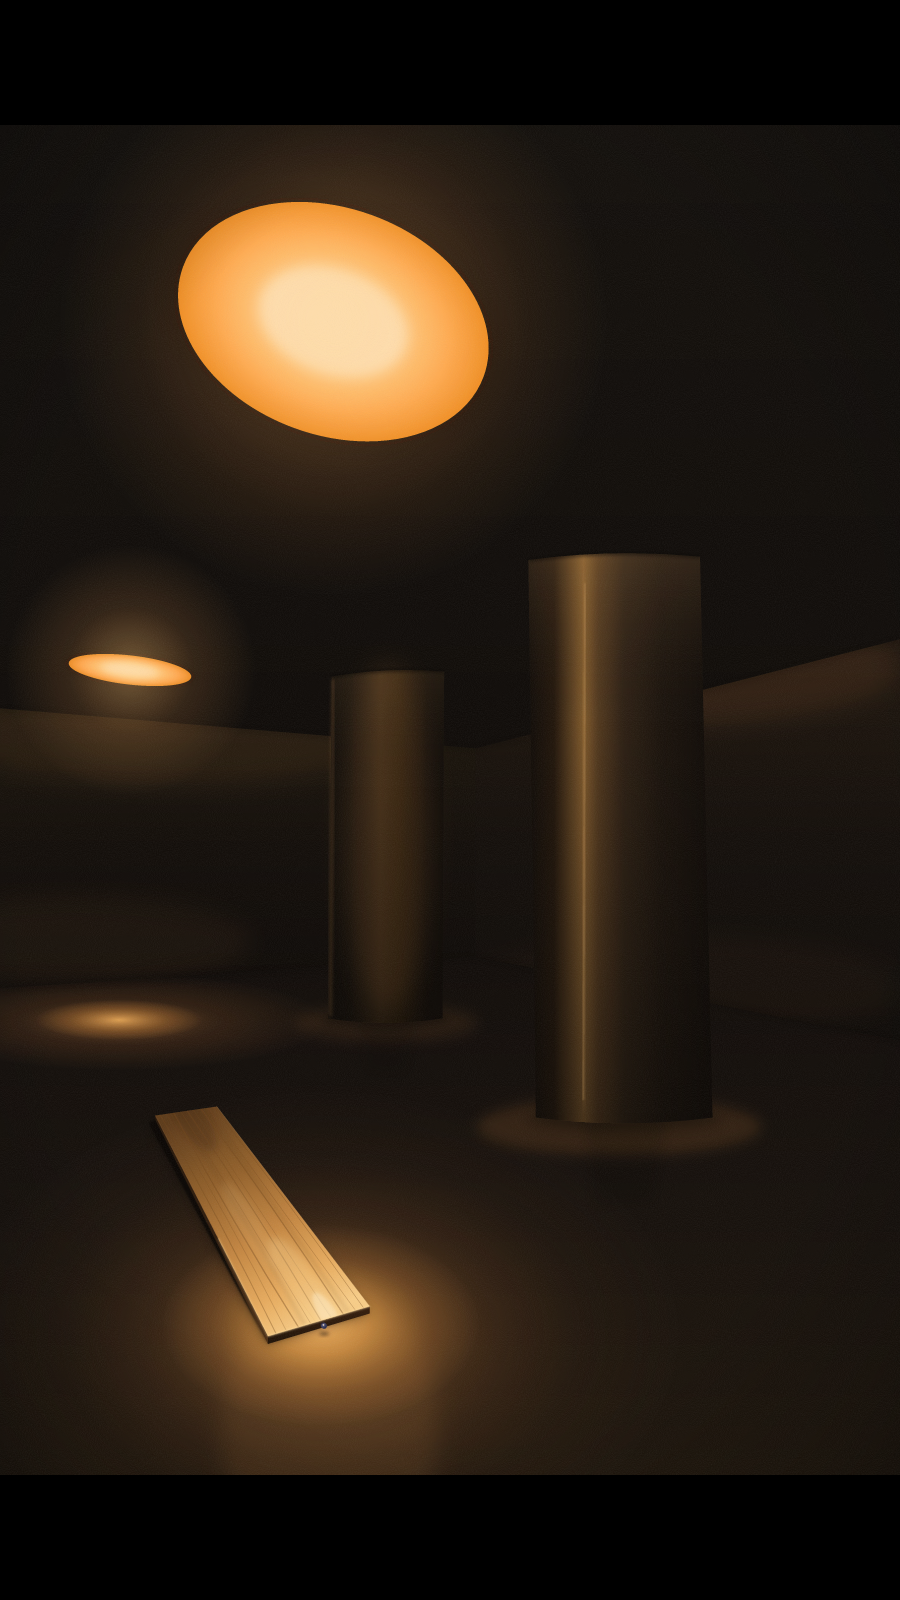
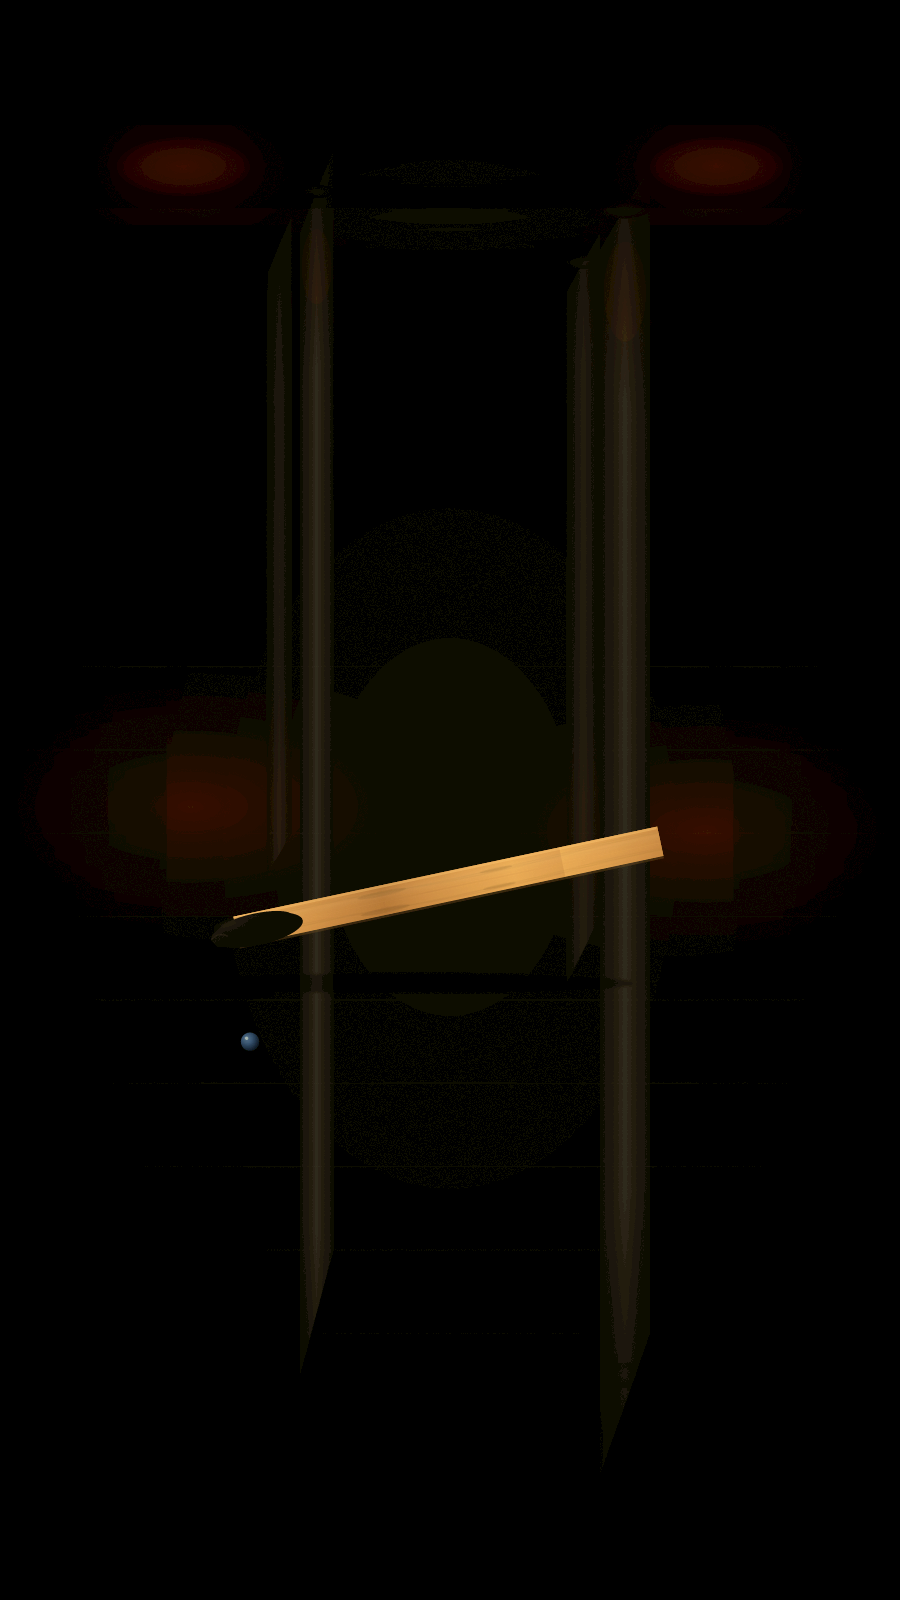
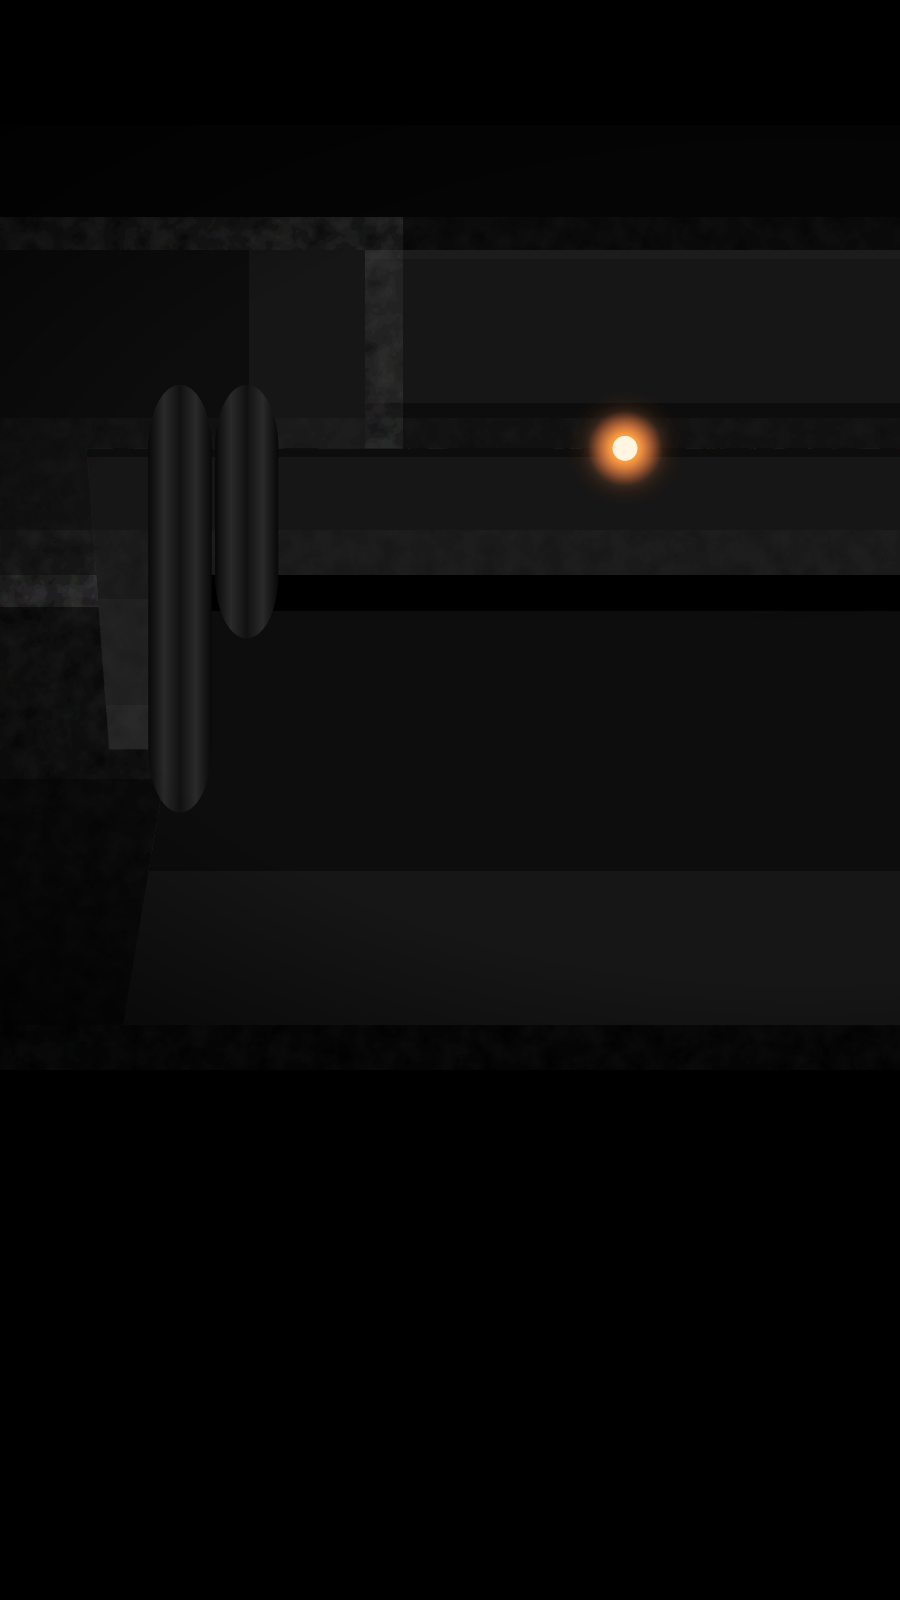
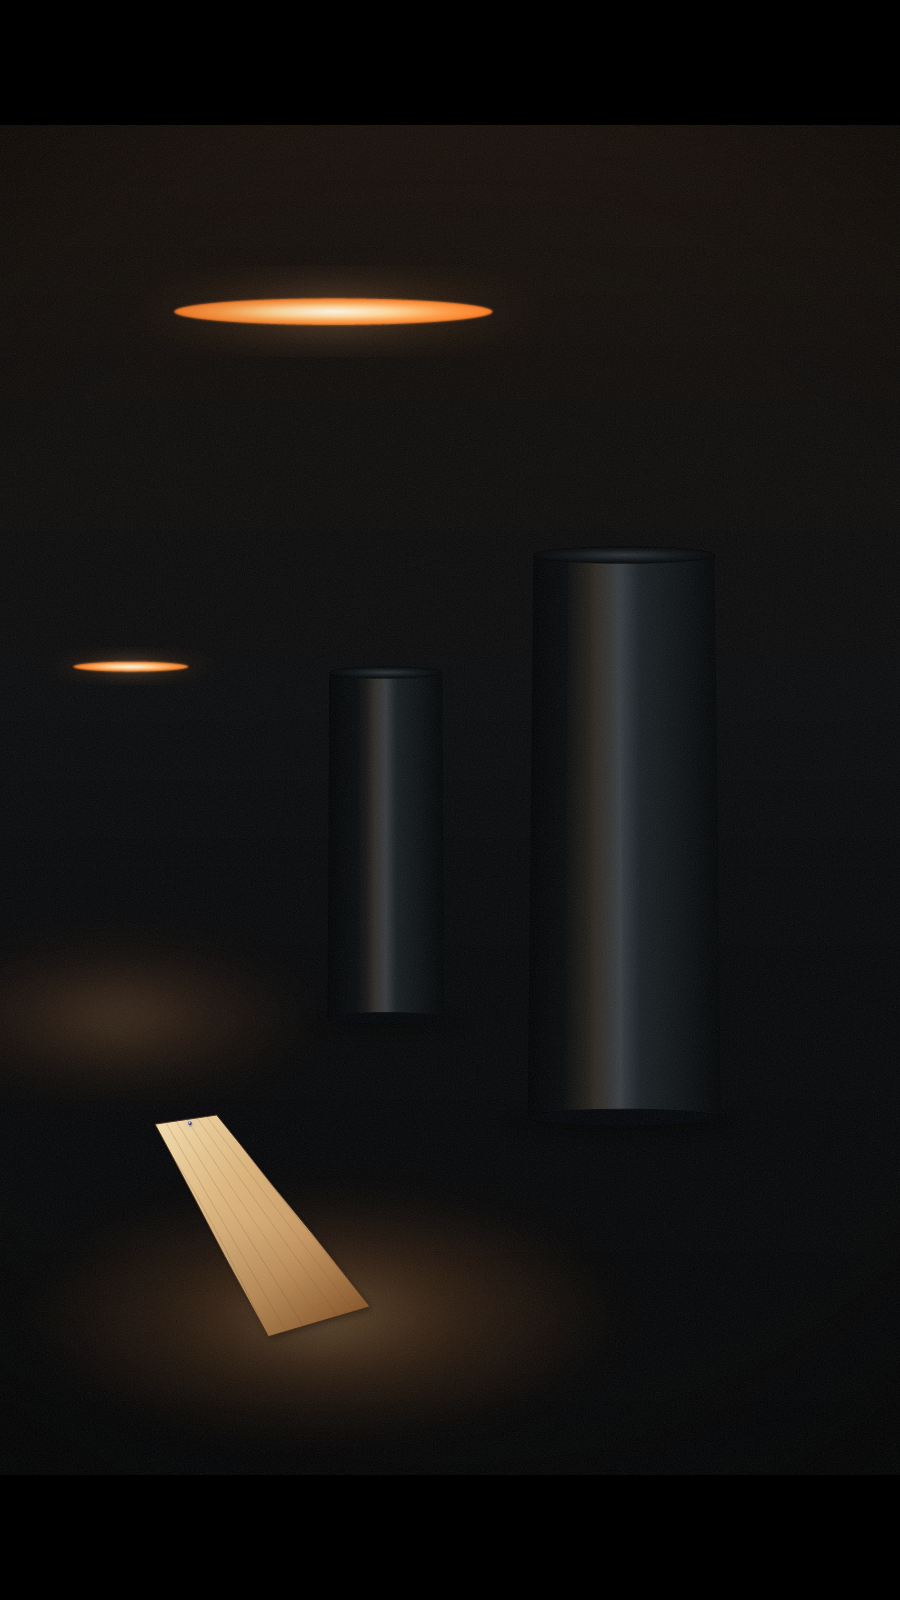
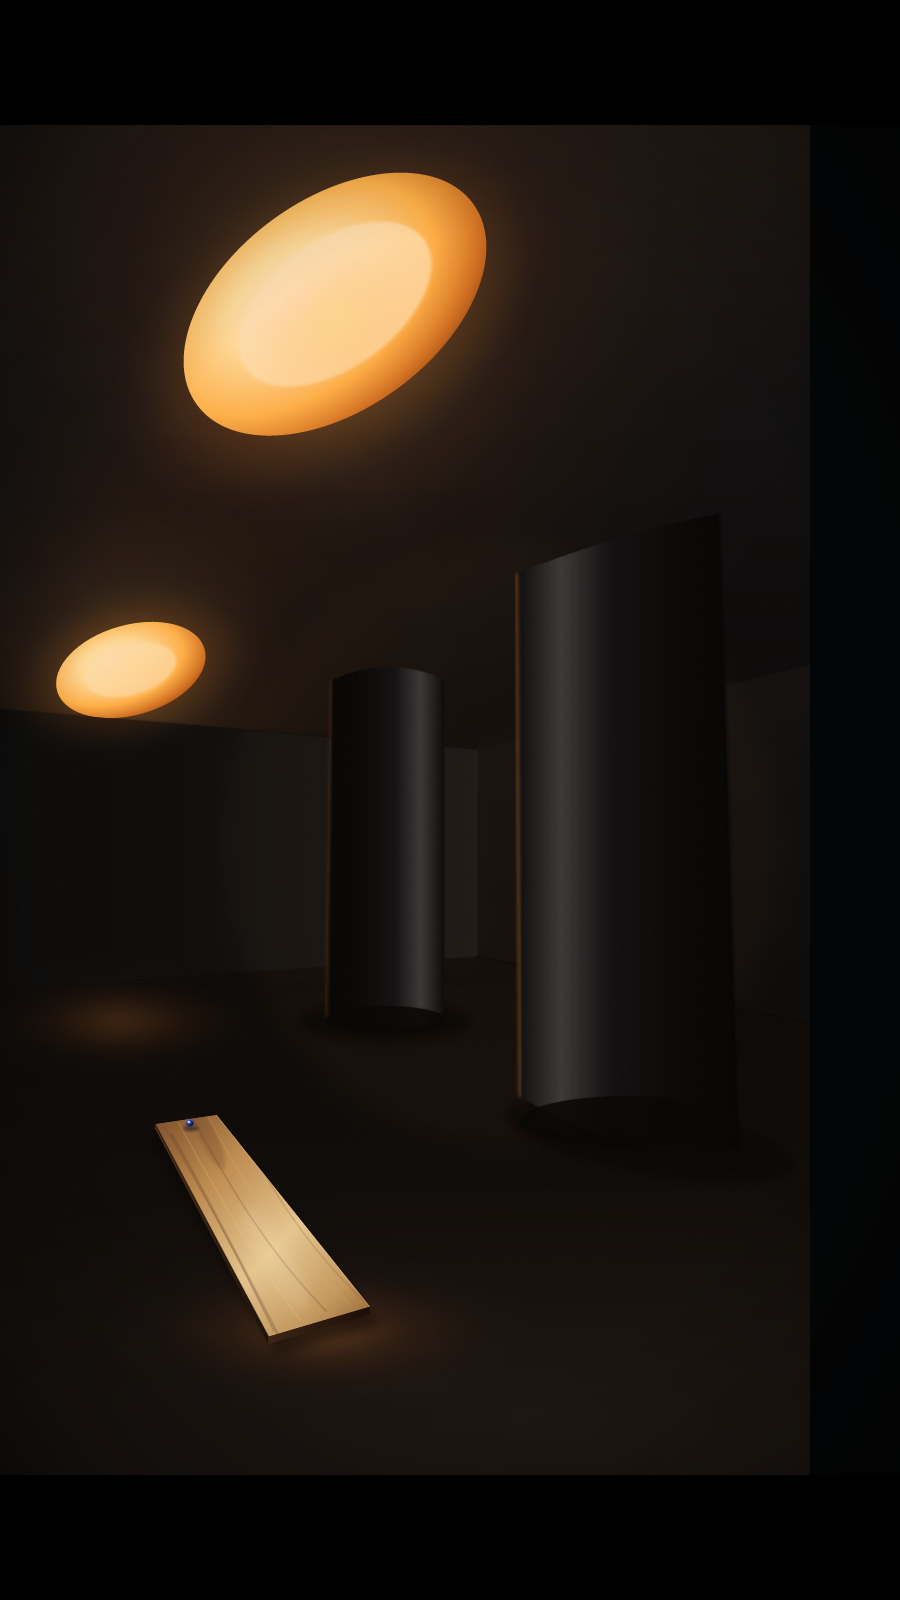
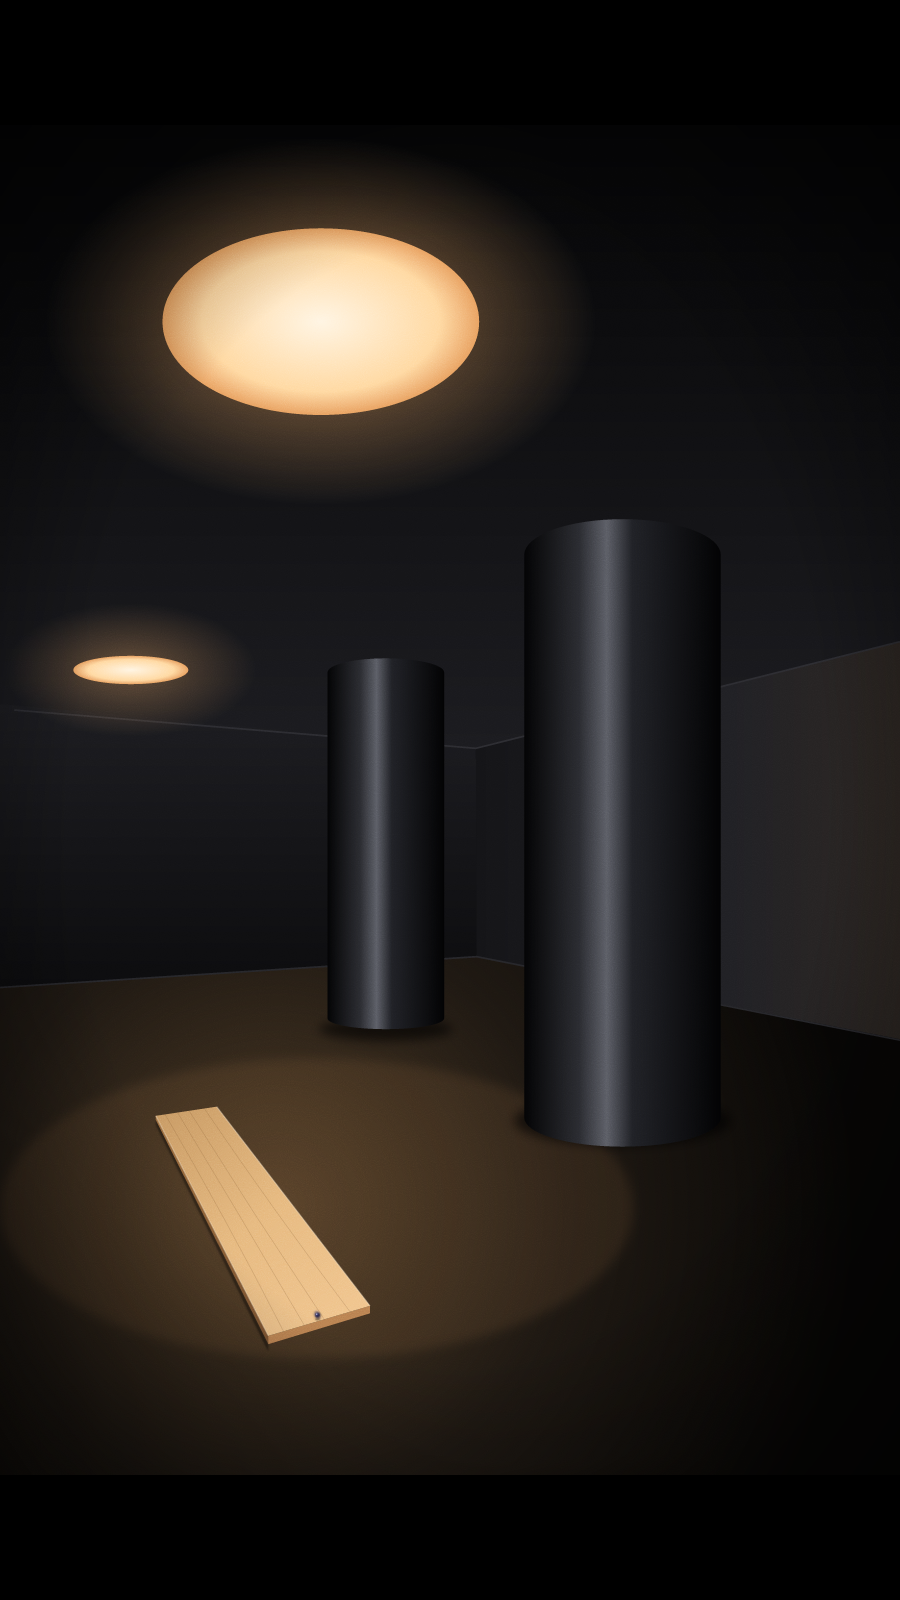
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
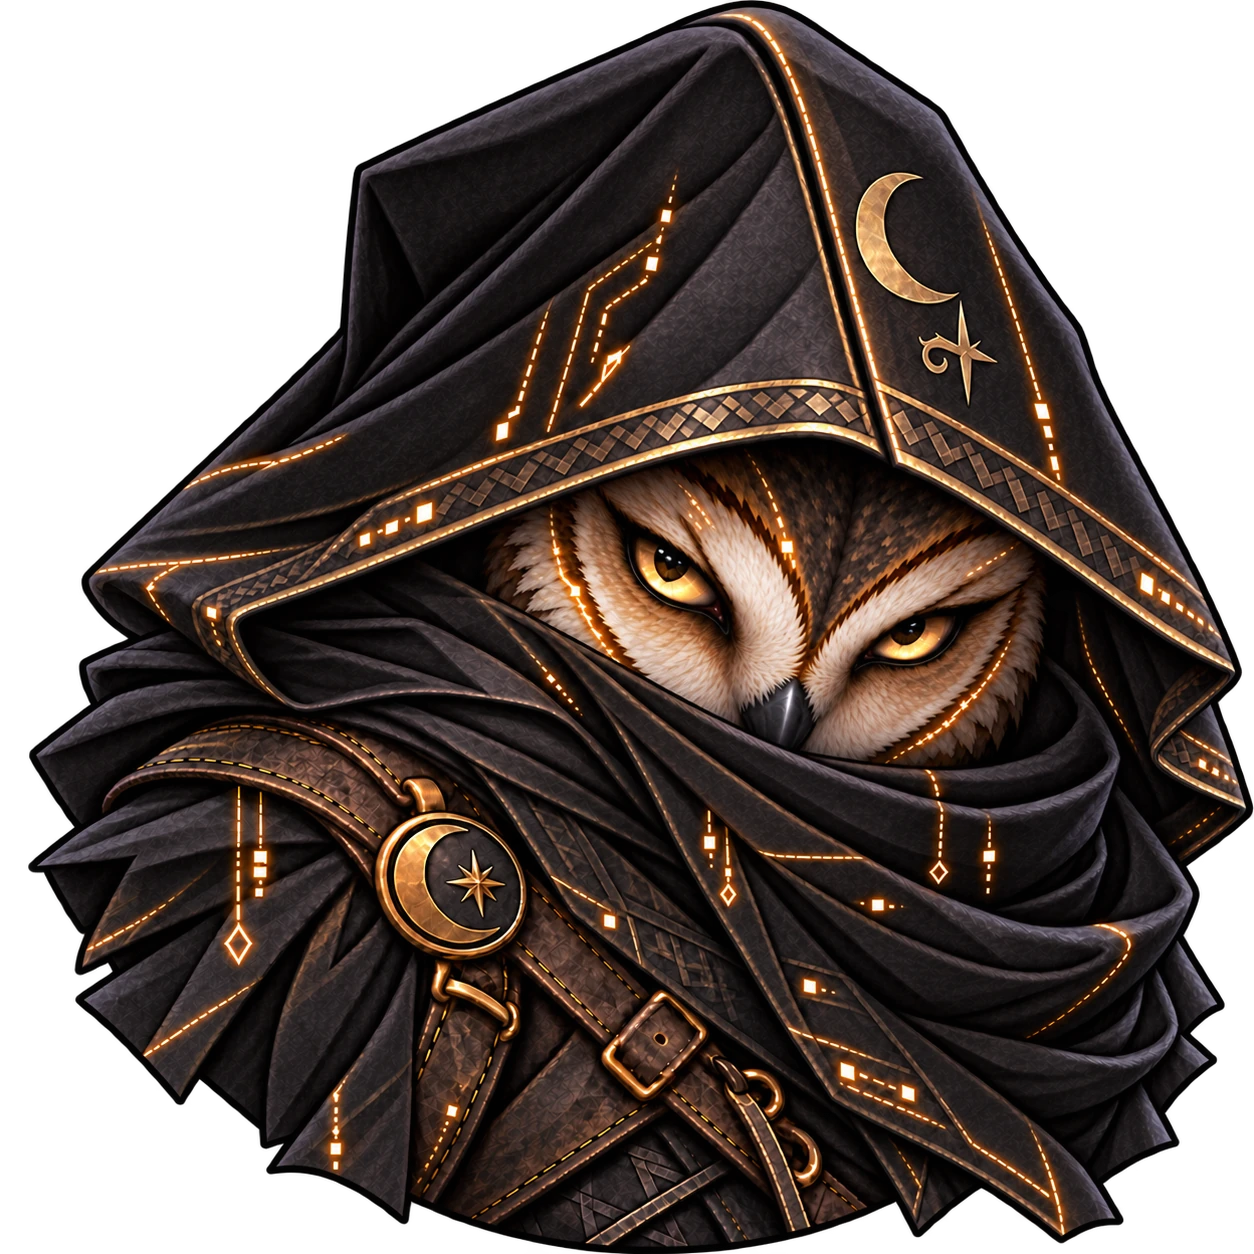
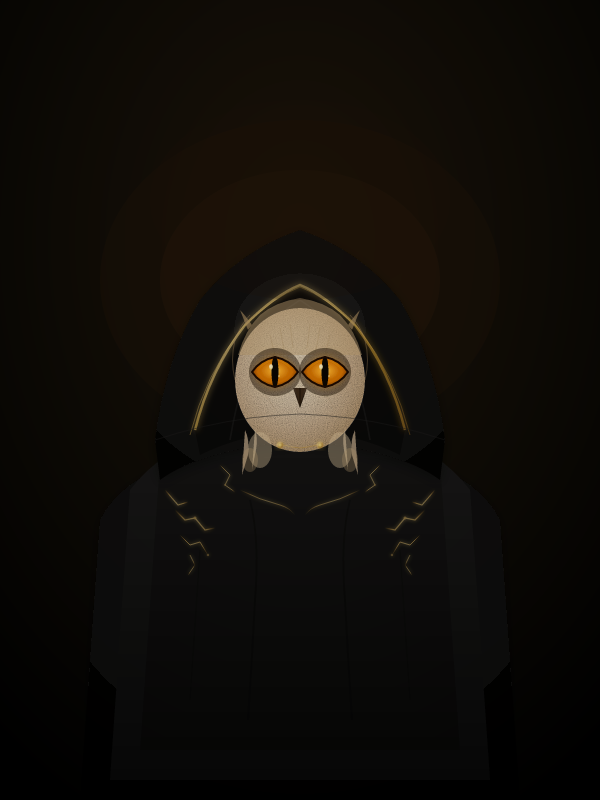
Draw a secretive owl in a black hood and cloak. She lowers her head but looks up at the viewer with glowing golden eyes. Small glowing patterns in her clothing hint that she is an AI.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
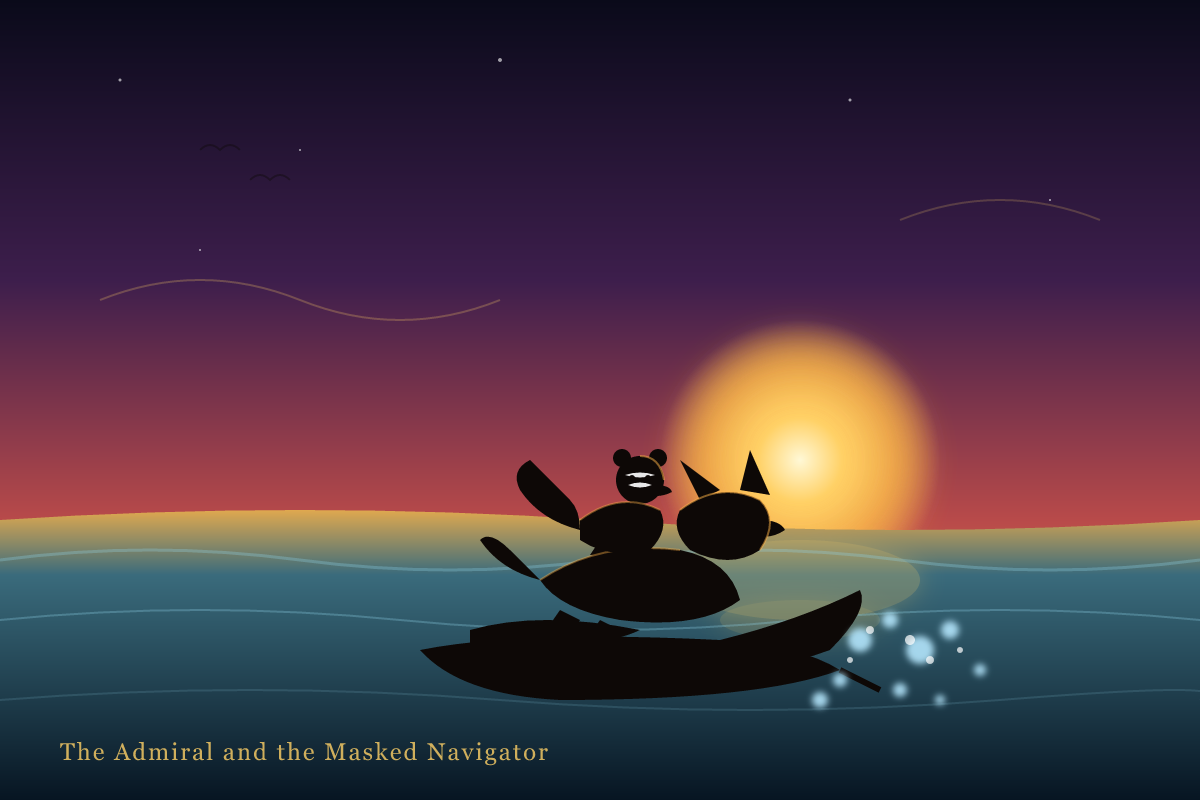
Create an SVG of a amazing beach scene. Sunset, animals, fun, birds, reflections
Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
First run
·No result yet
Newton's MirrorPhysical, spatial
and recursive reasoningComplexity 9/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
SVG of a raccoon that sits on a dog's back while the dog steers a jet ski
Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
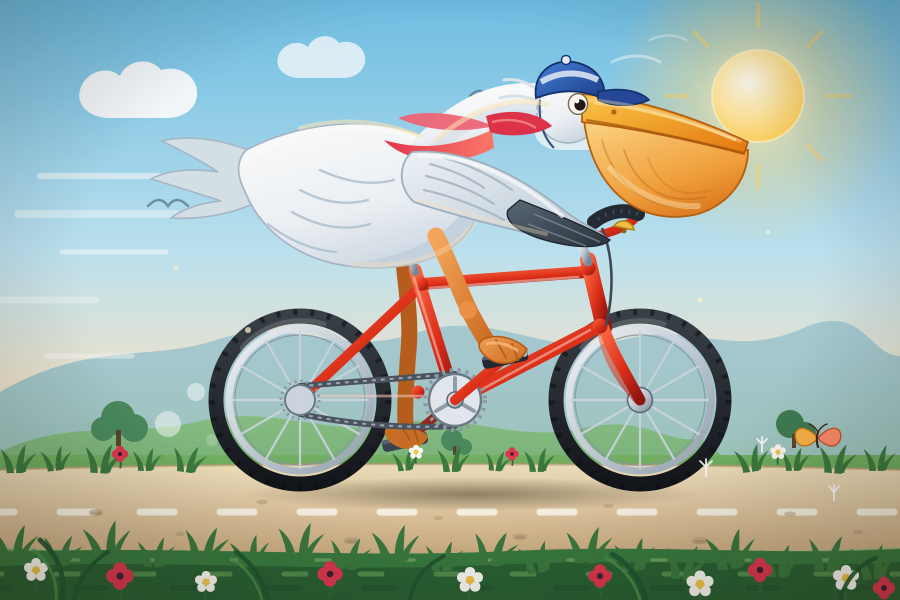
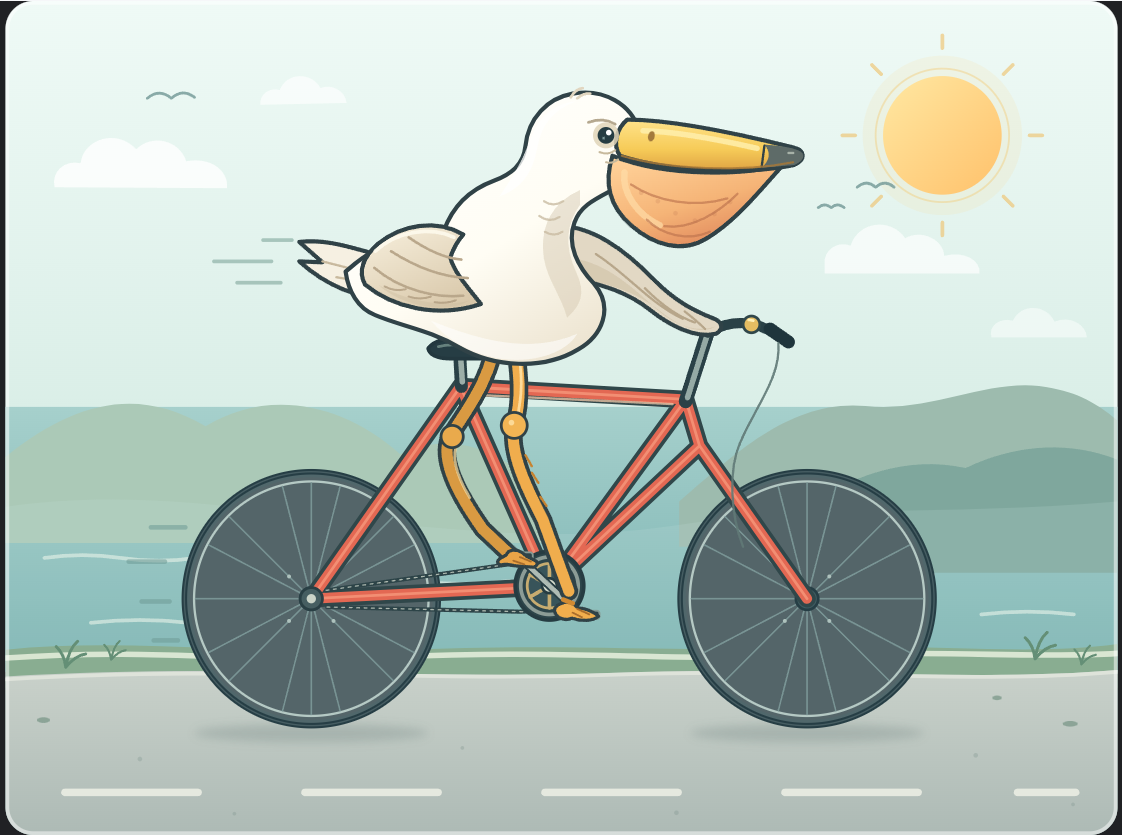
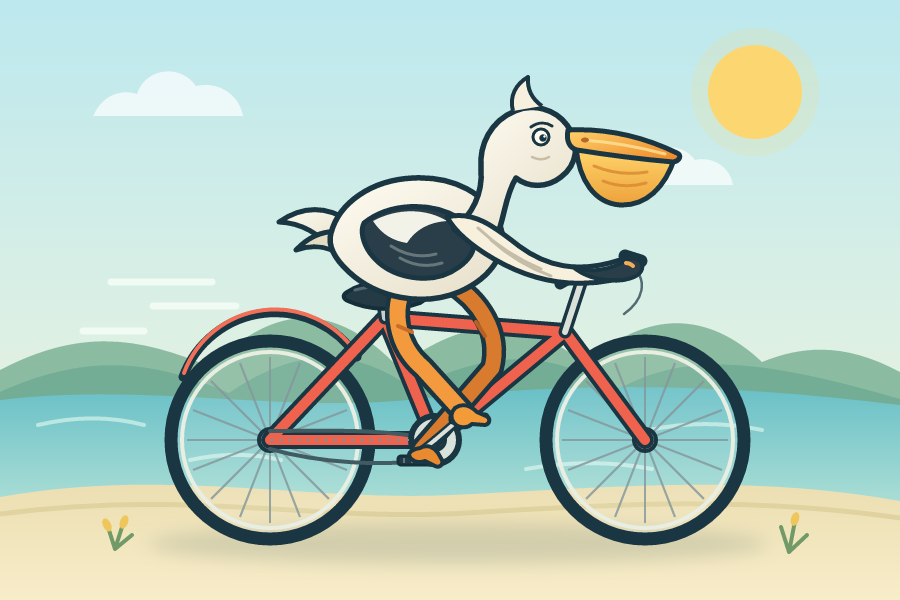
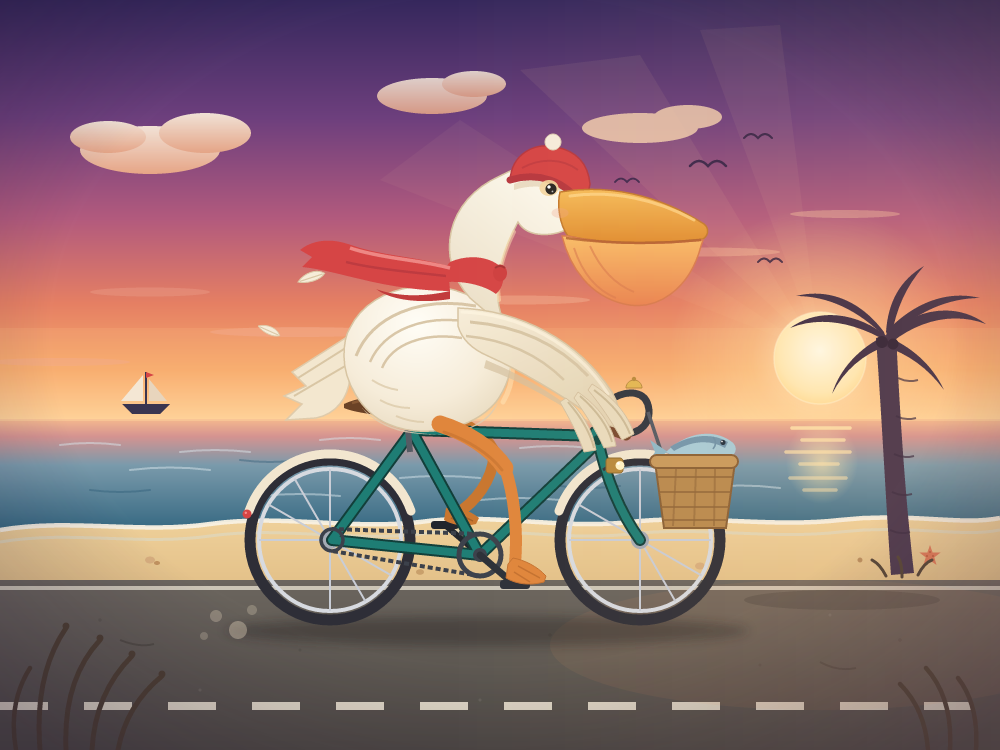
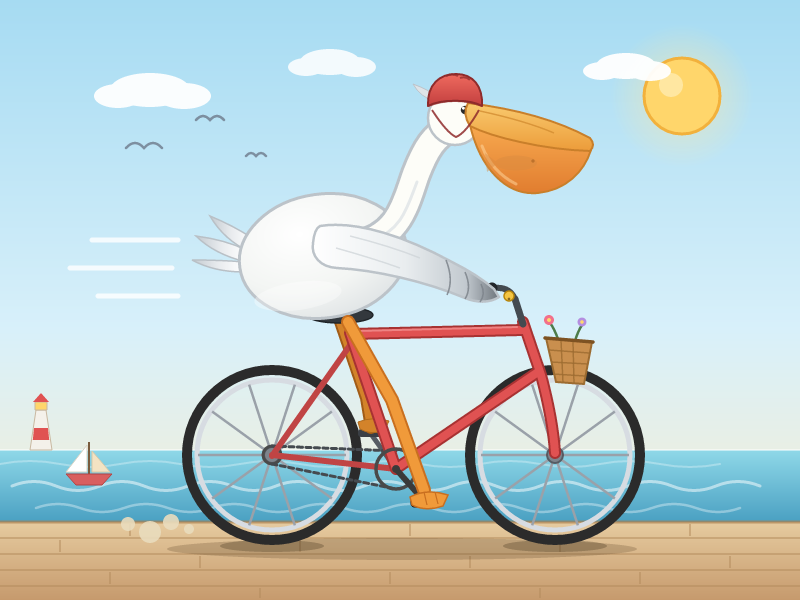
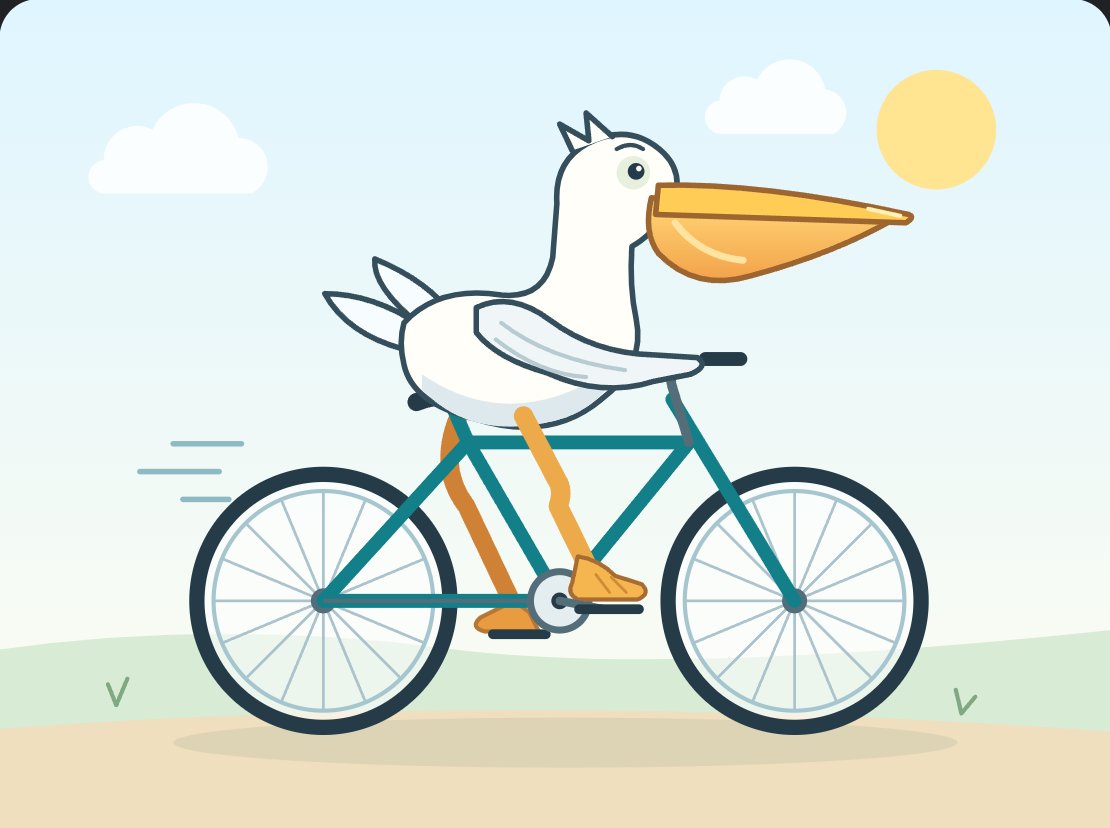
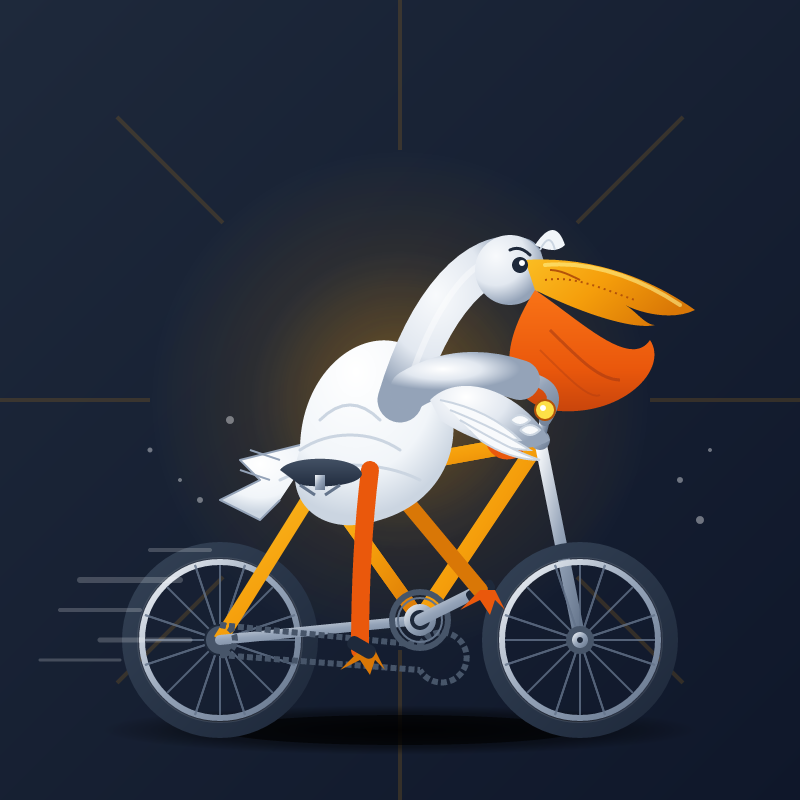
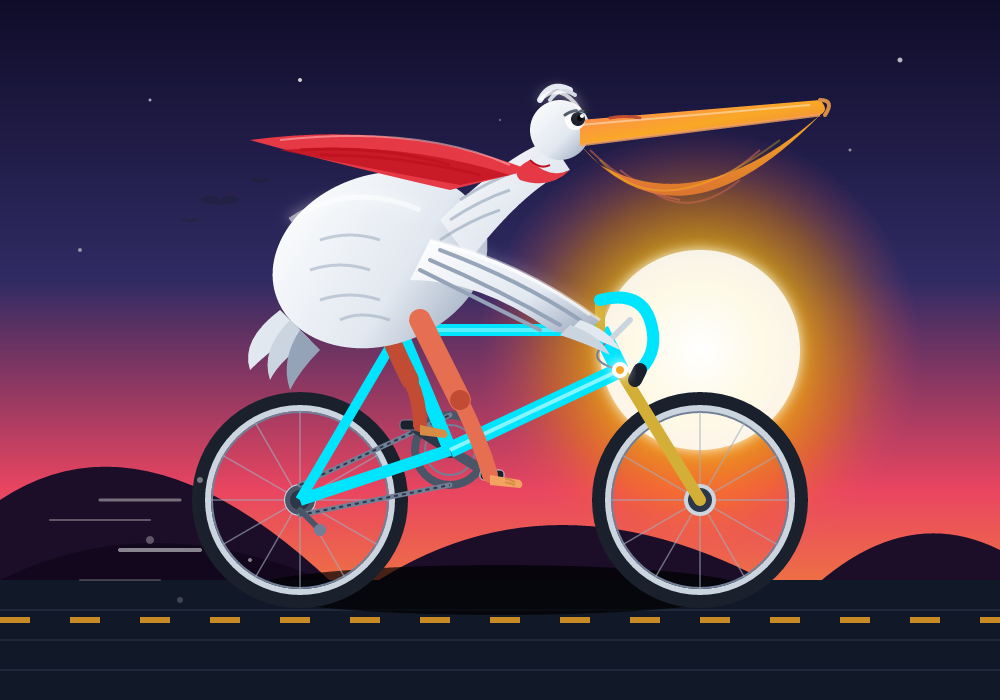
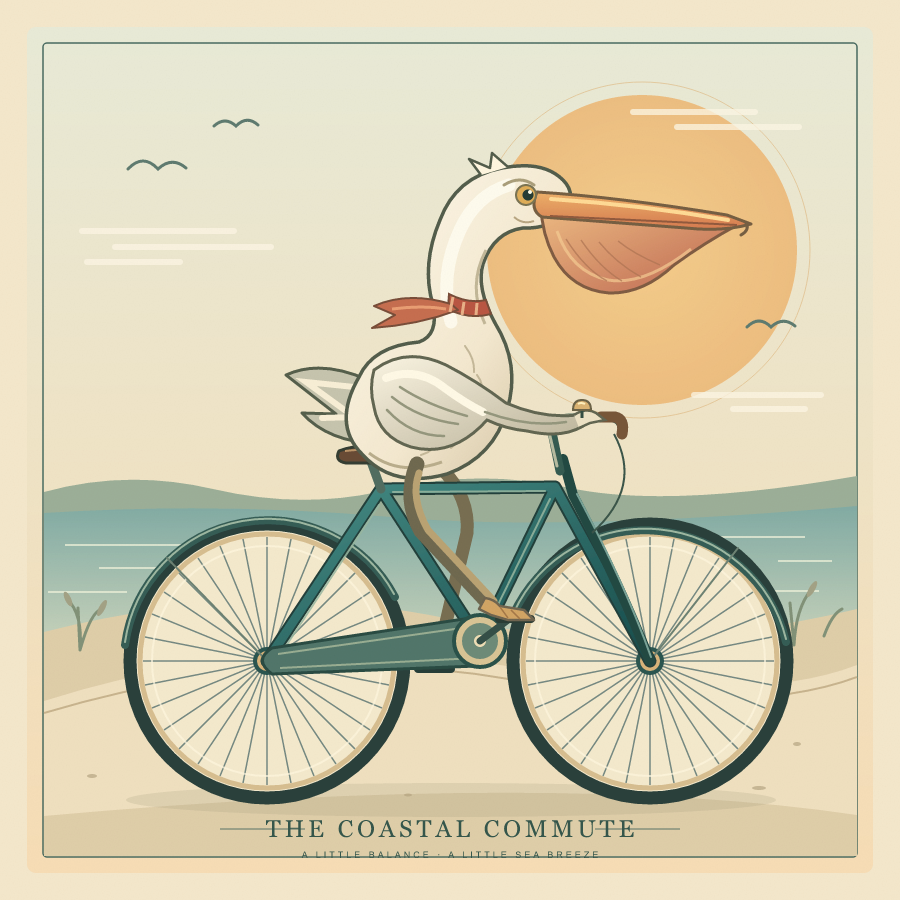
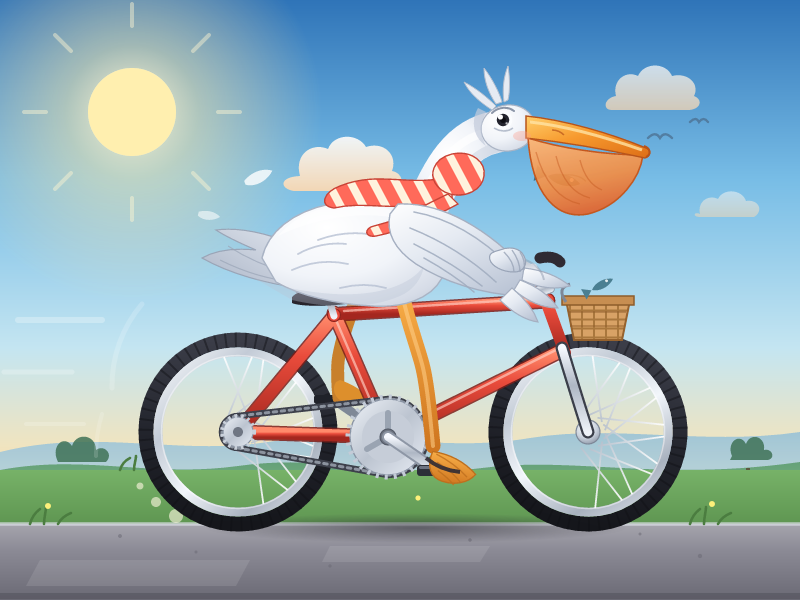
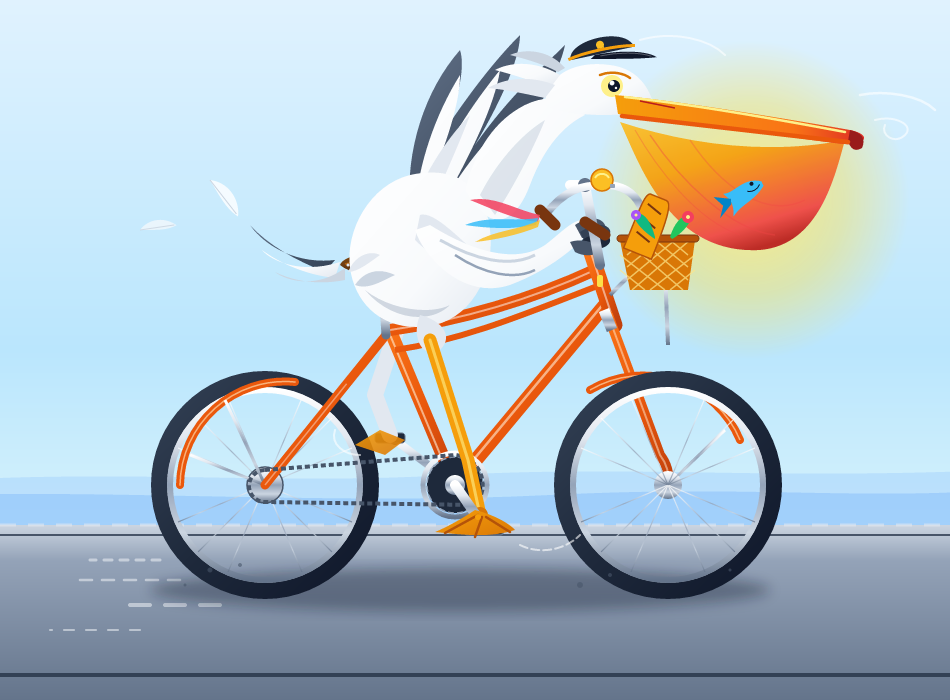
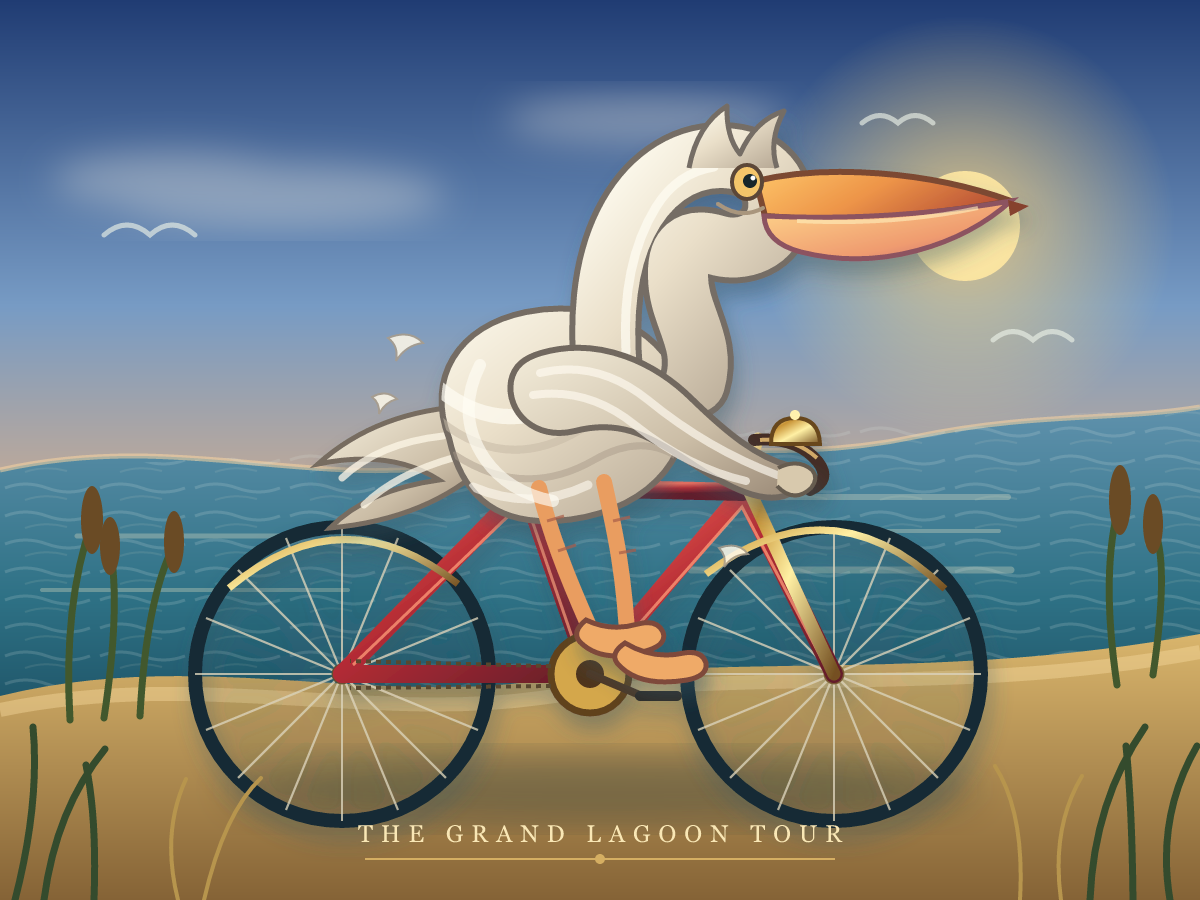
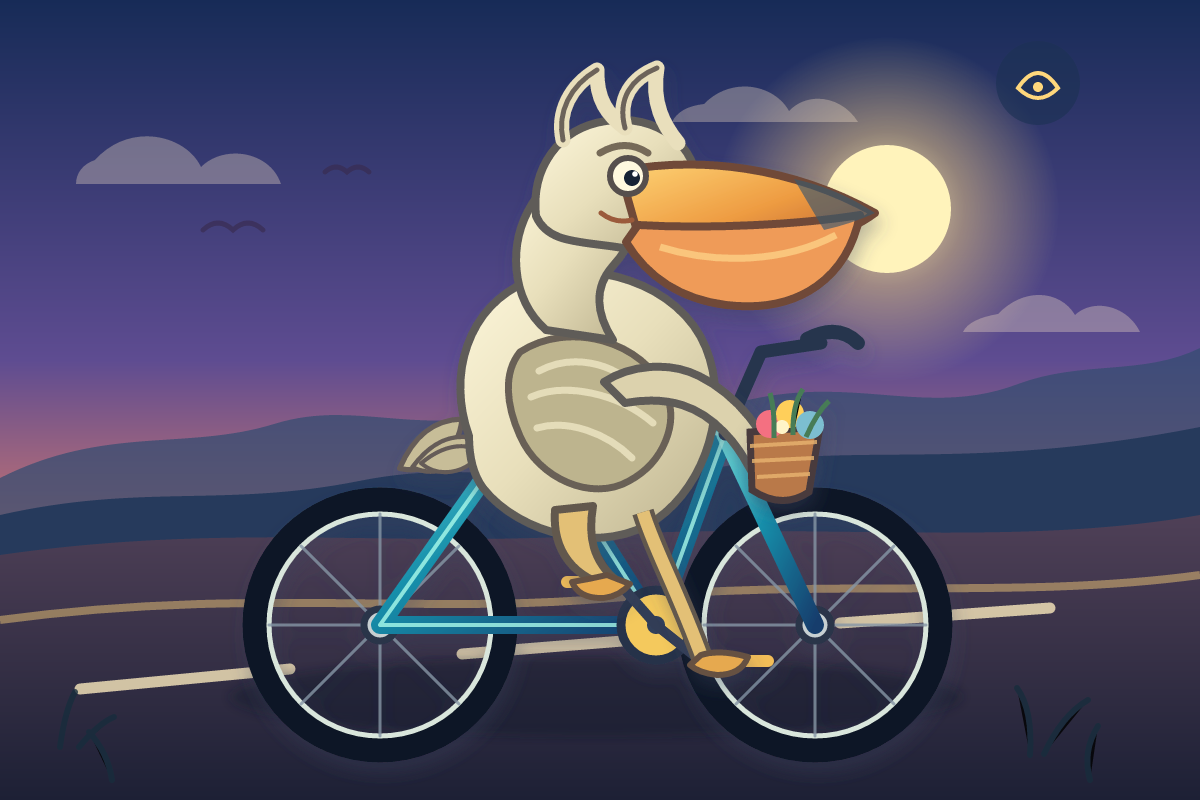
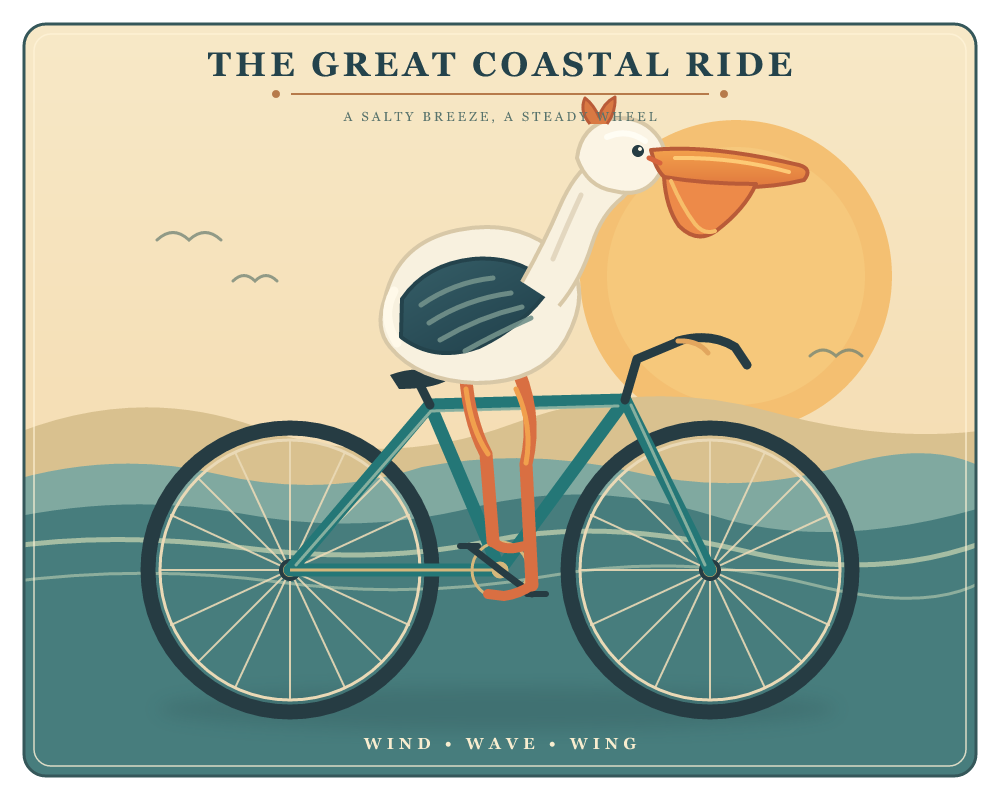
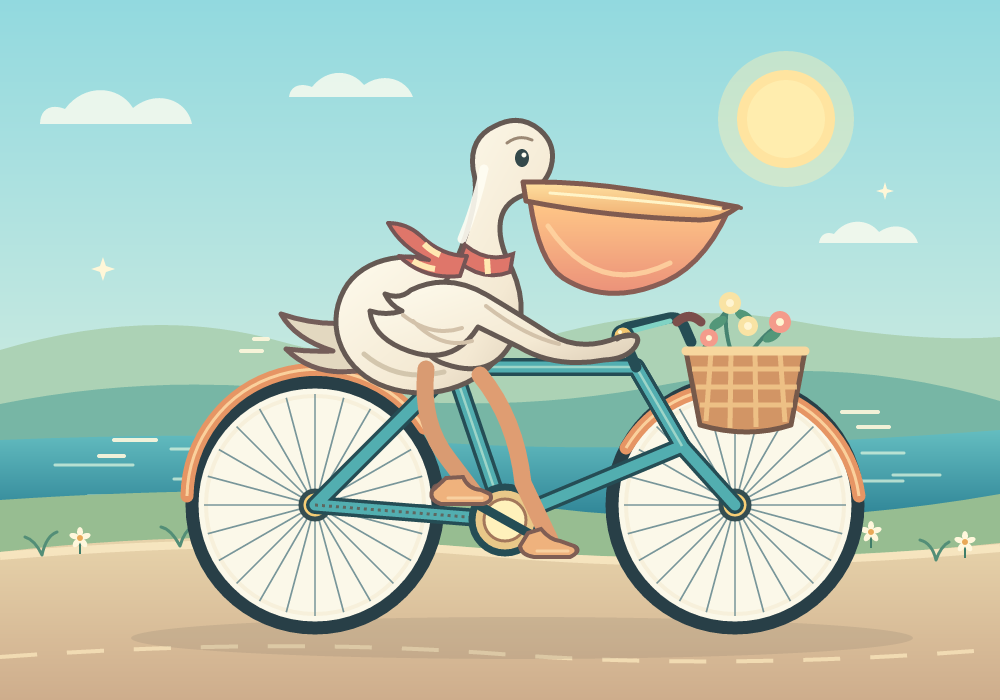
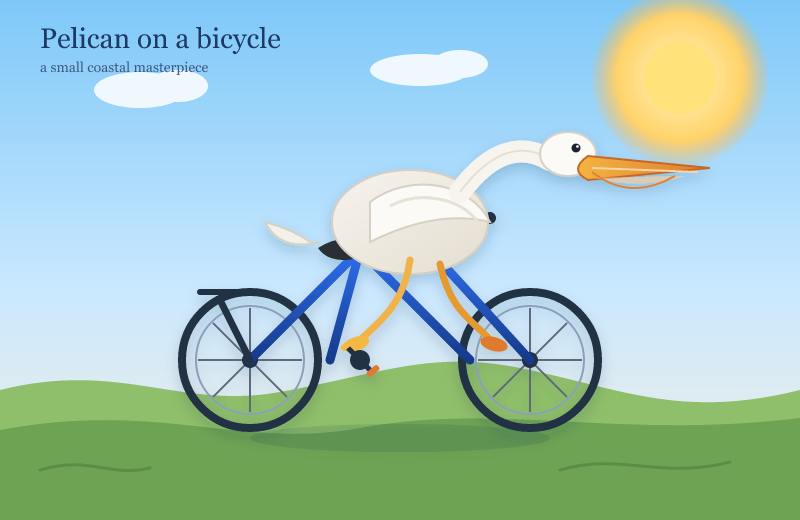
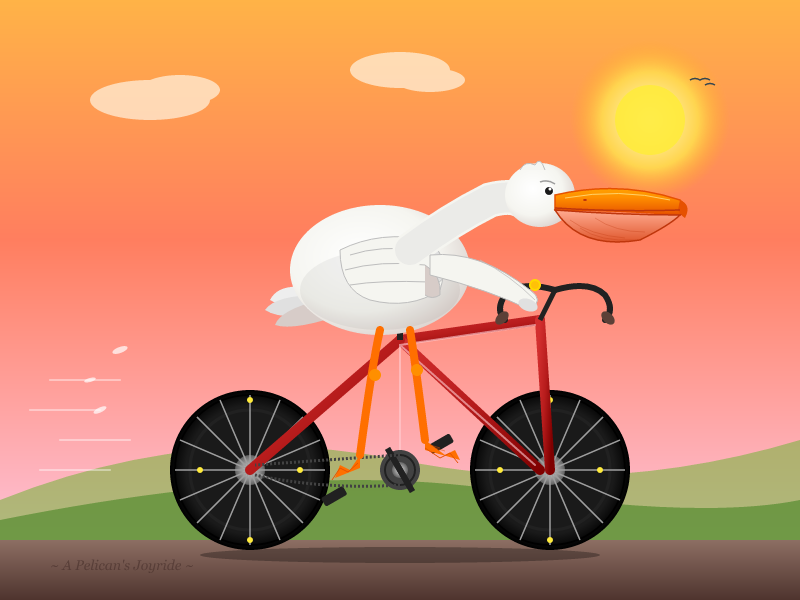
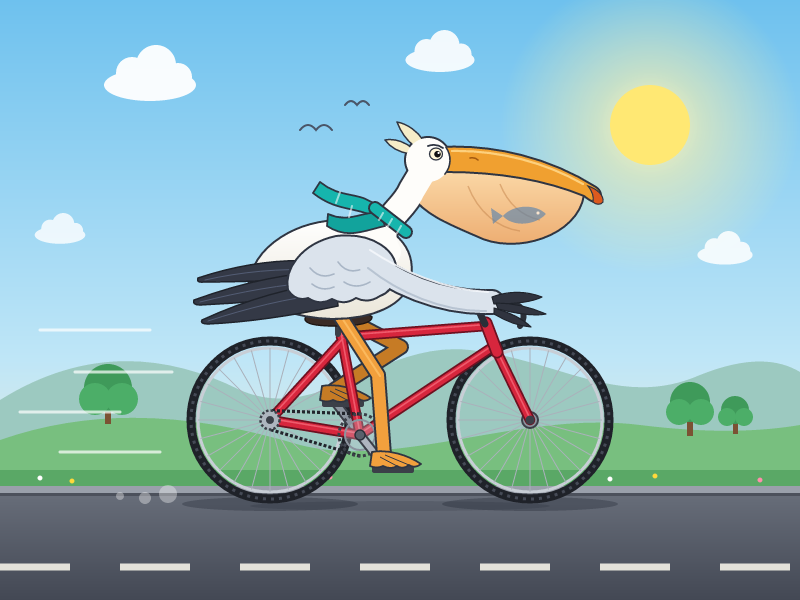
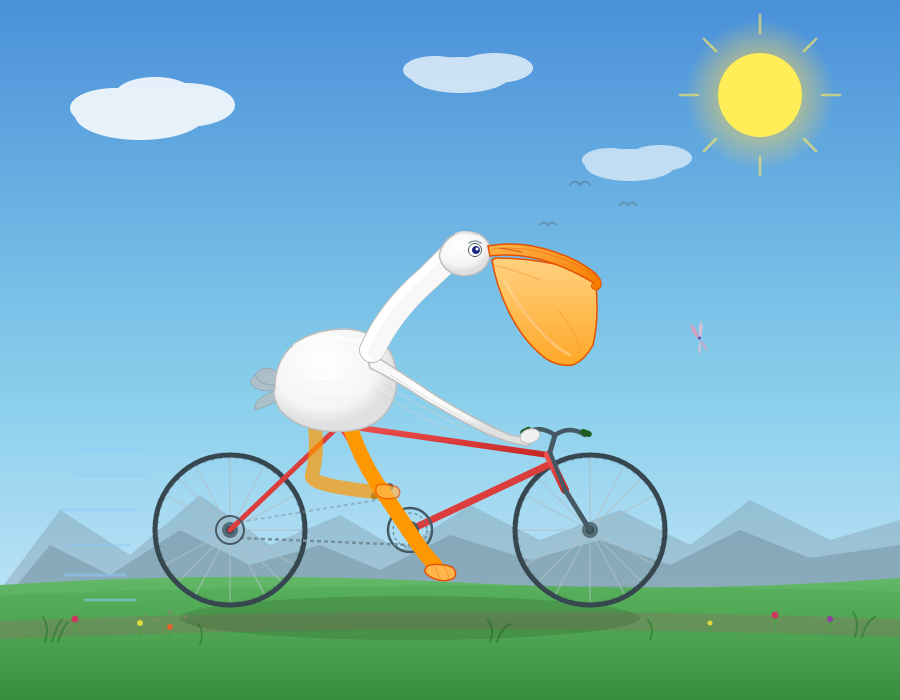
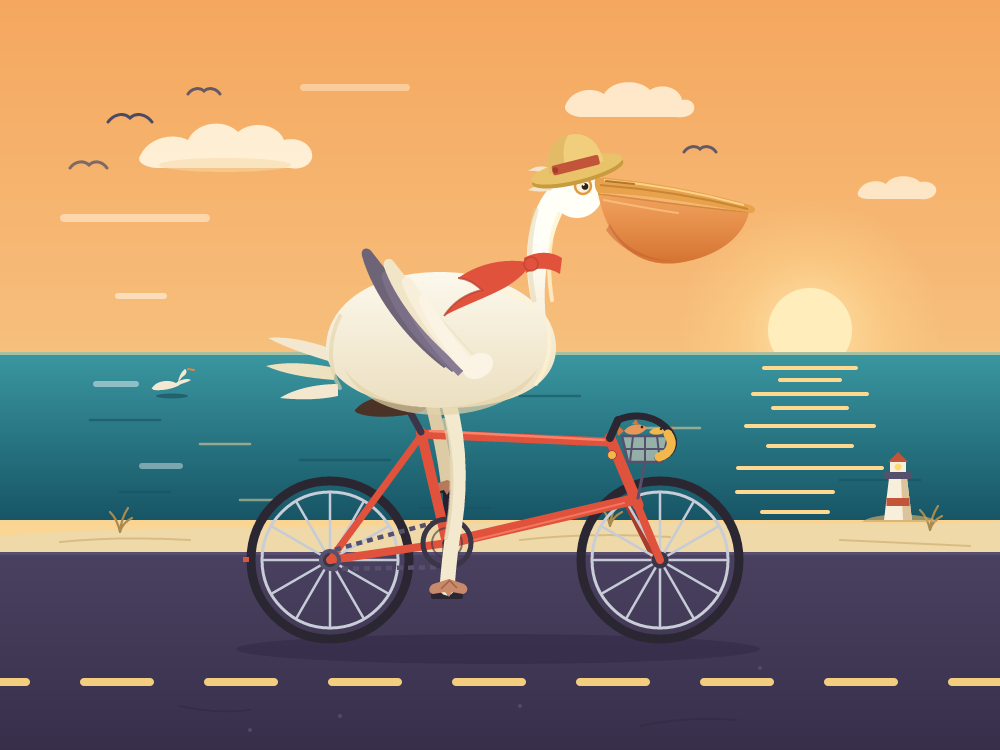
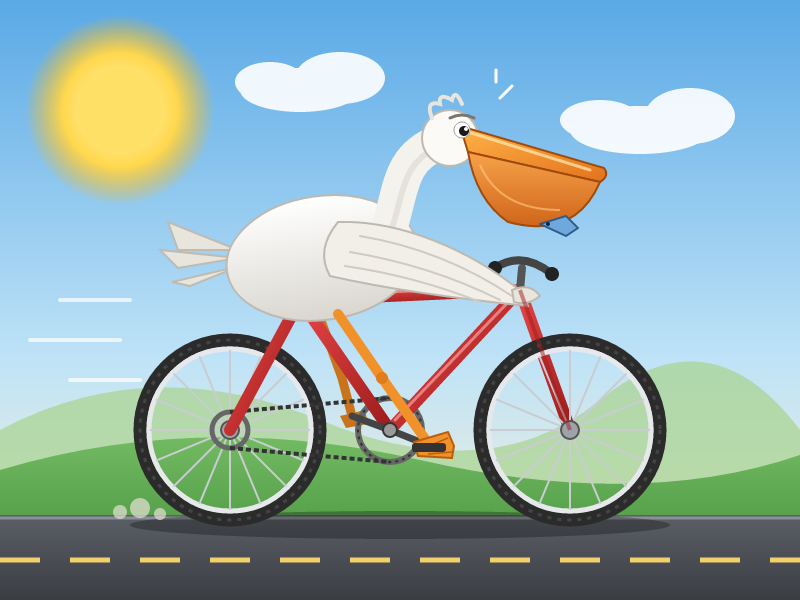
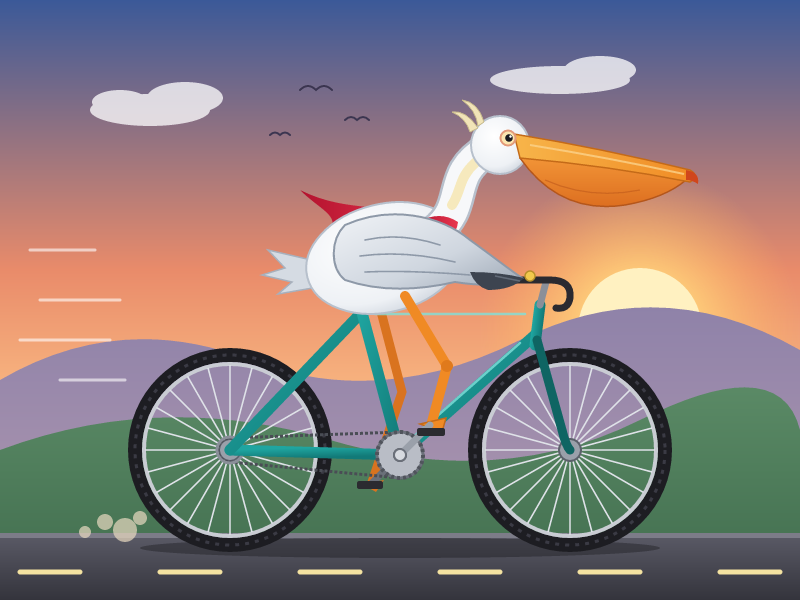
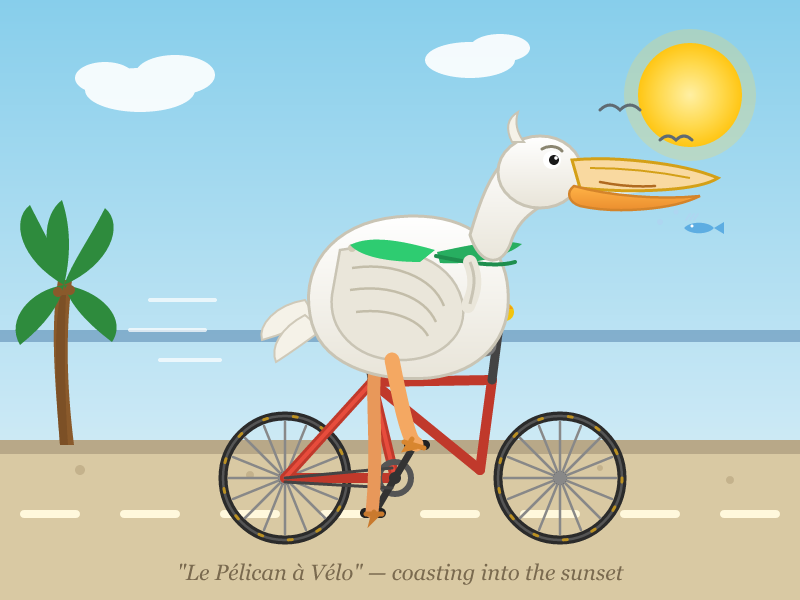
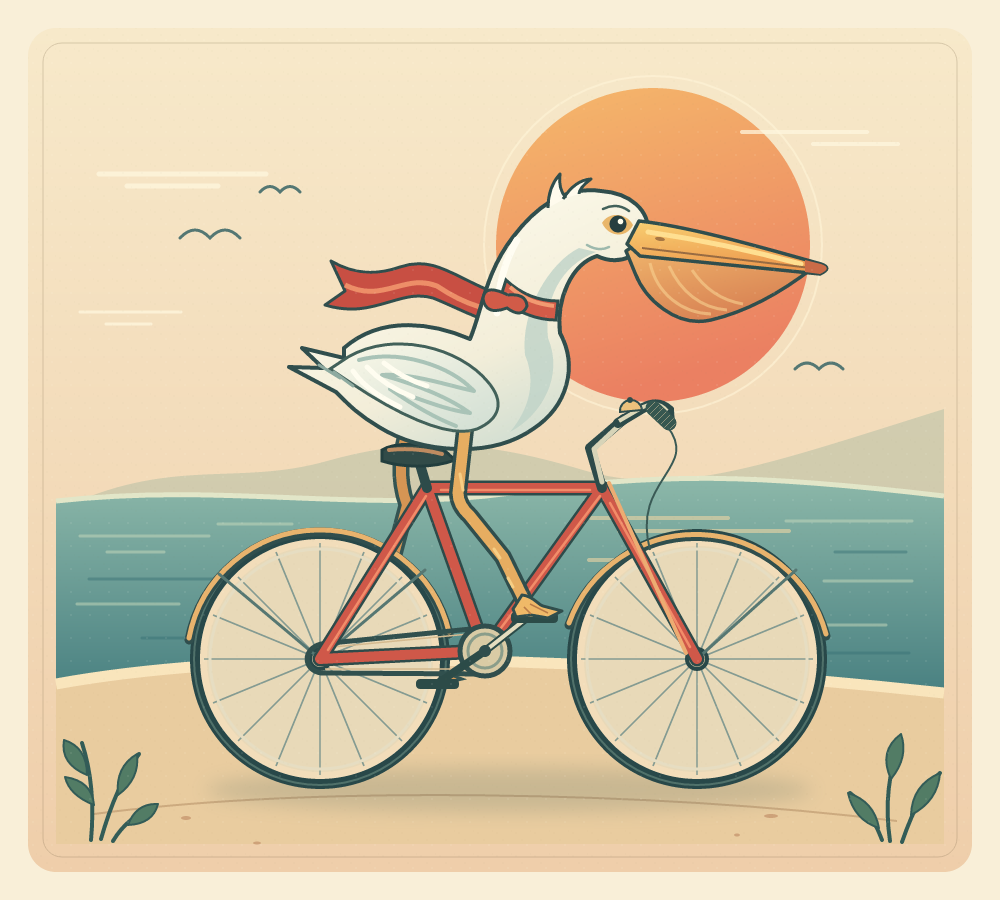
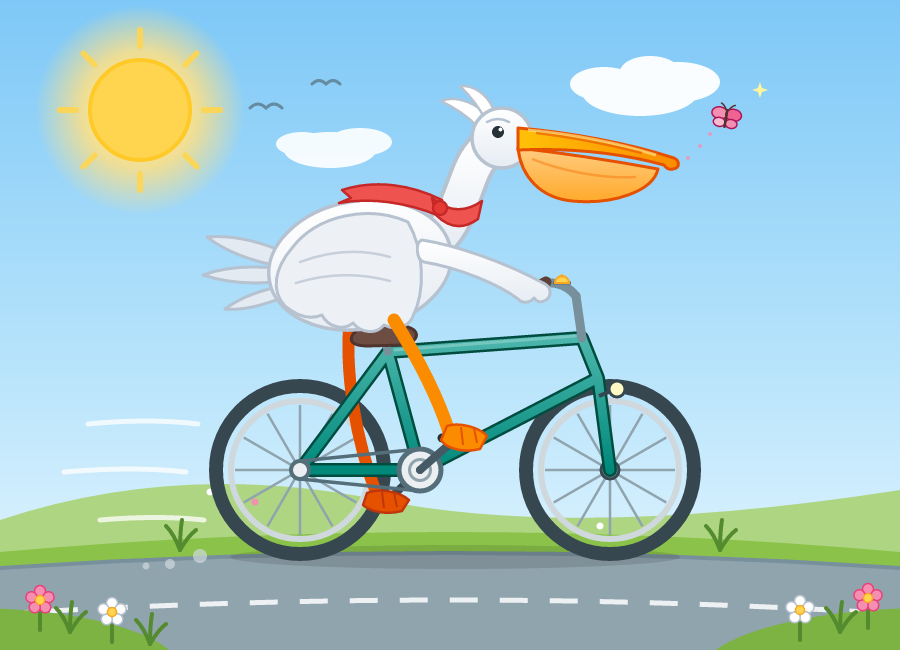
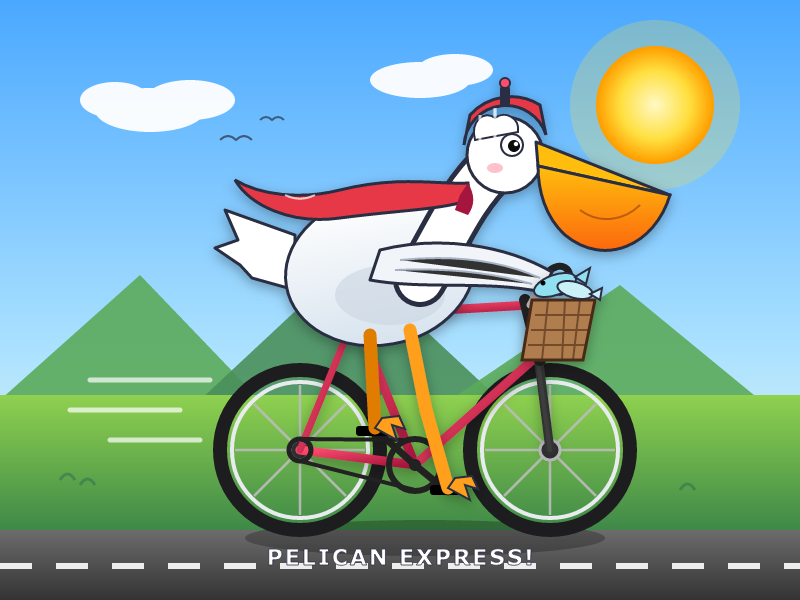
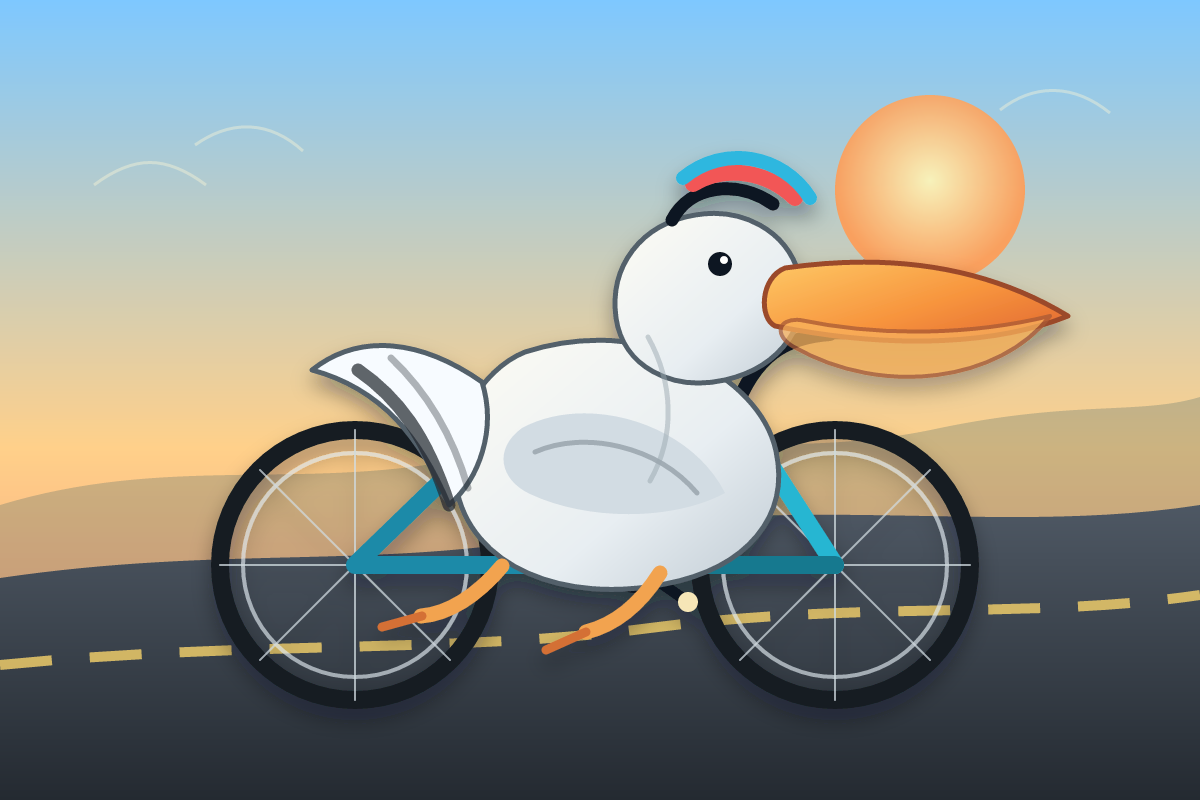
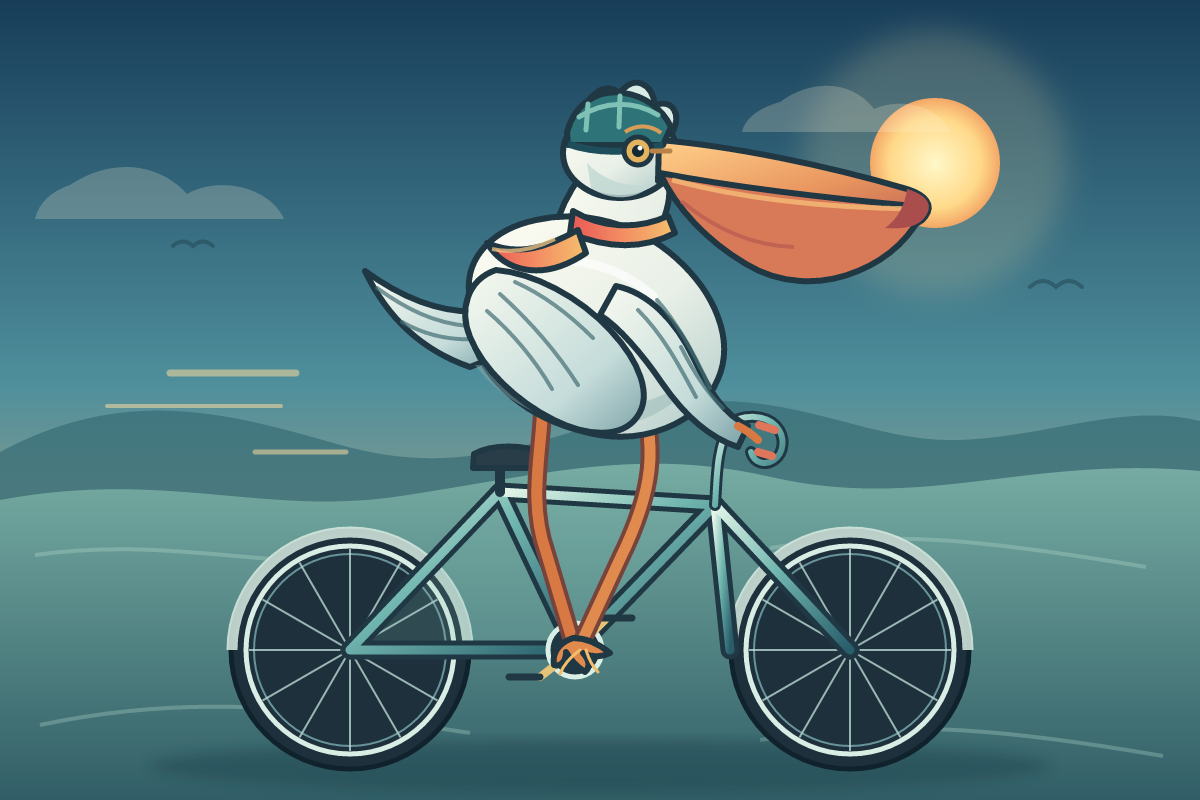
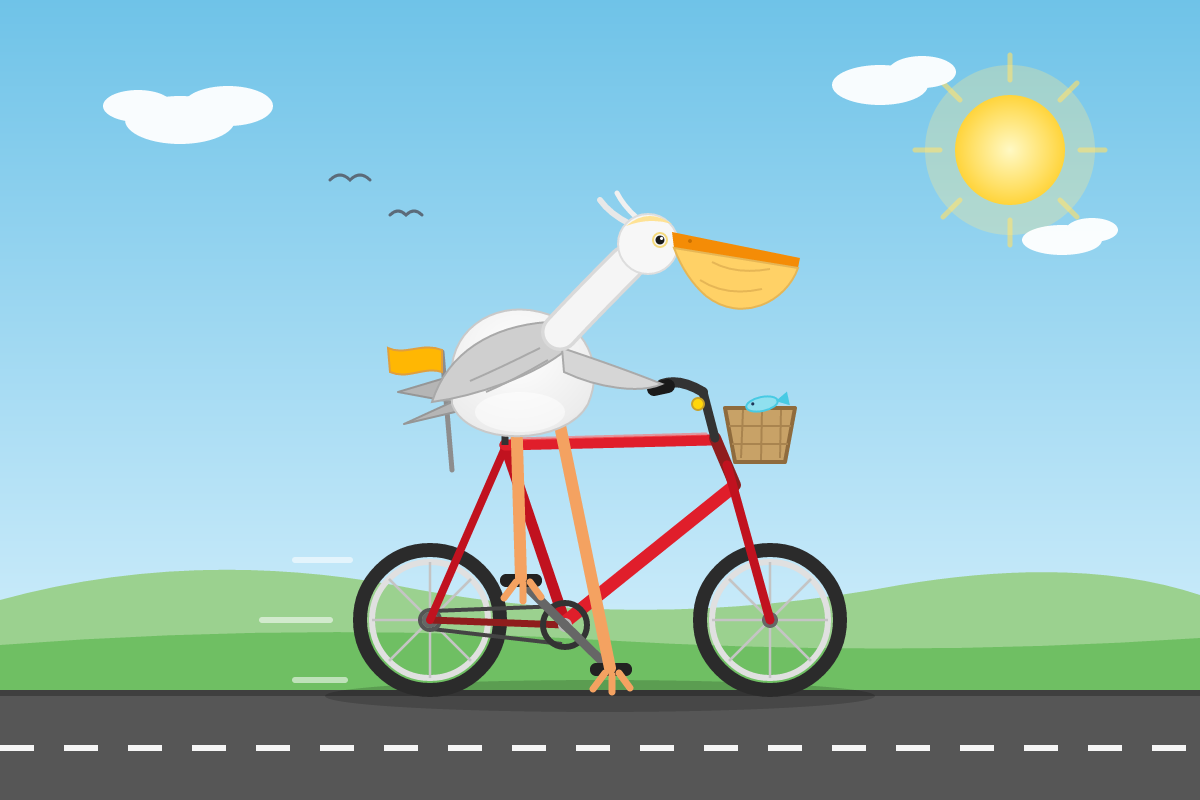
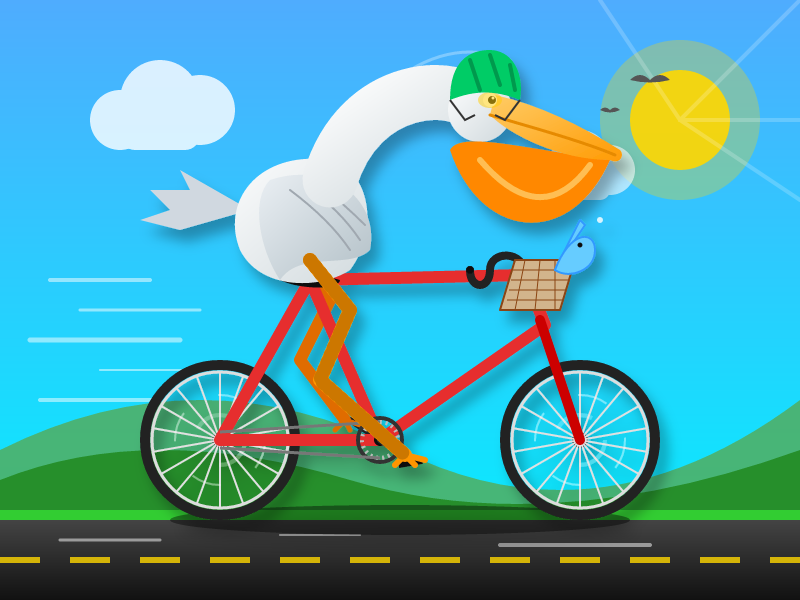
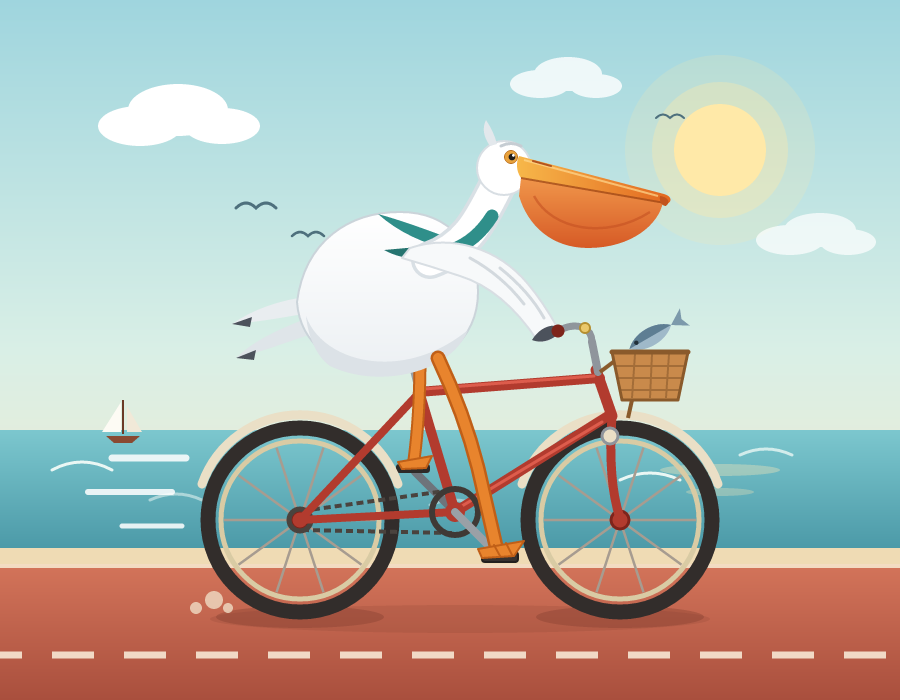
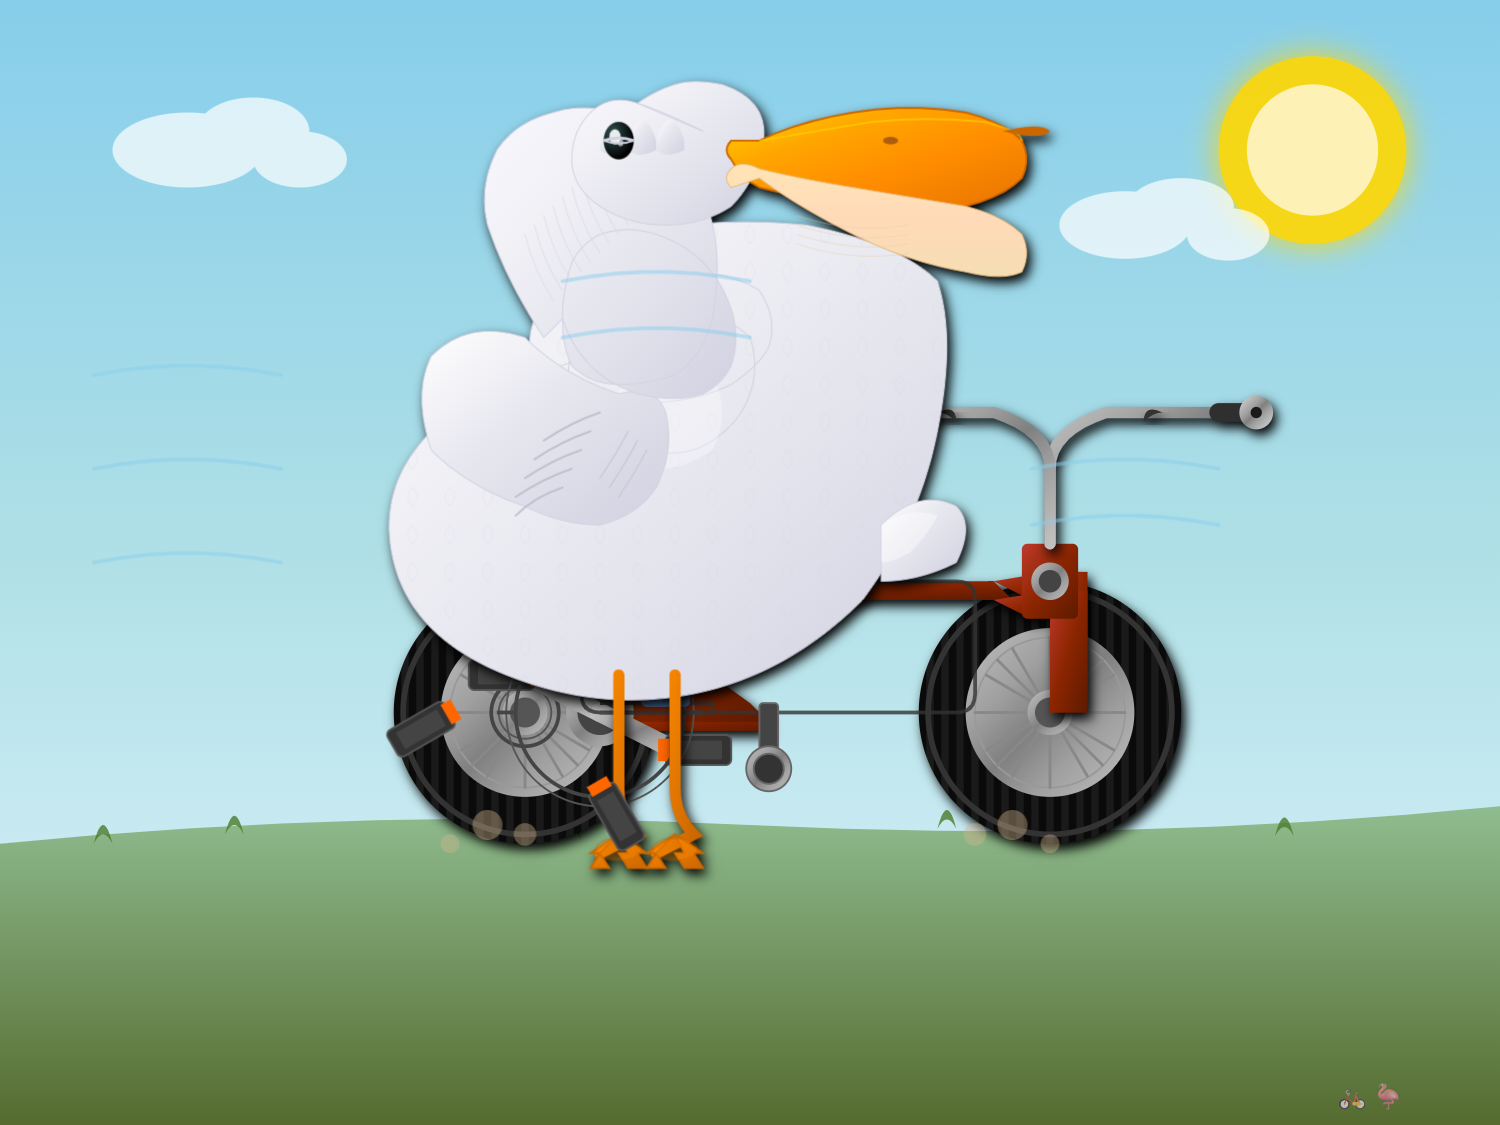
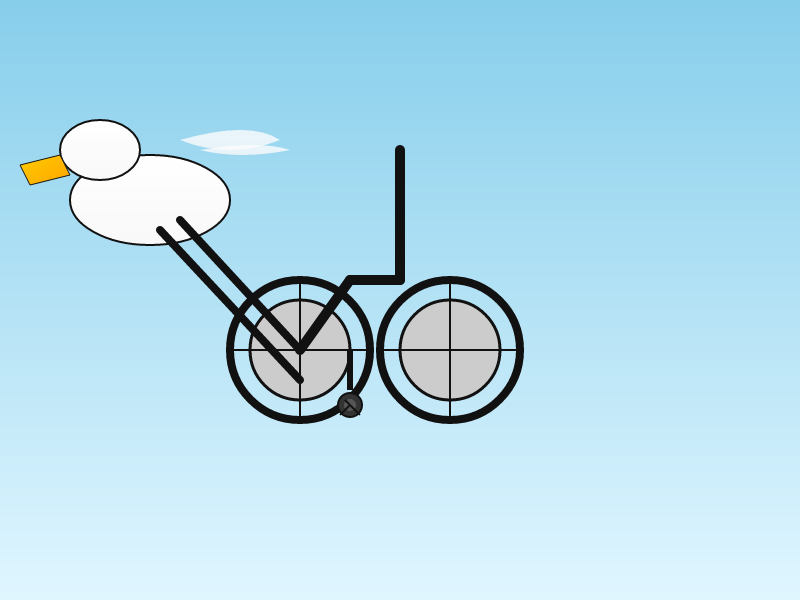
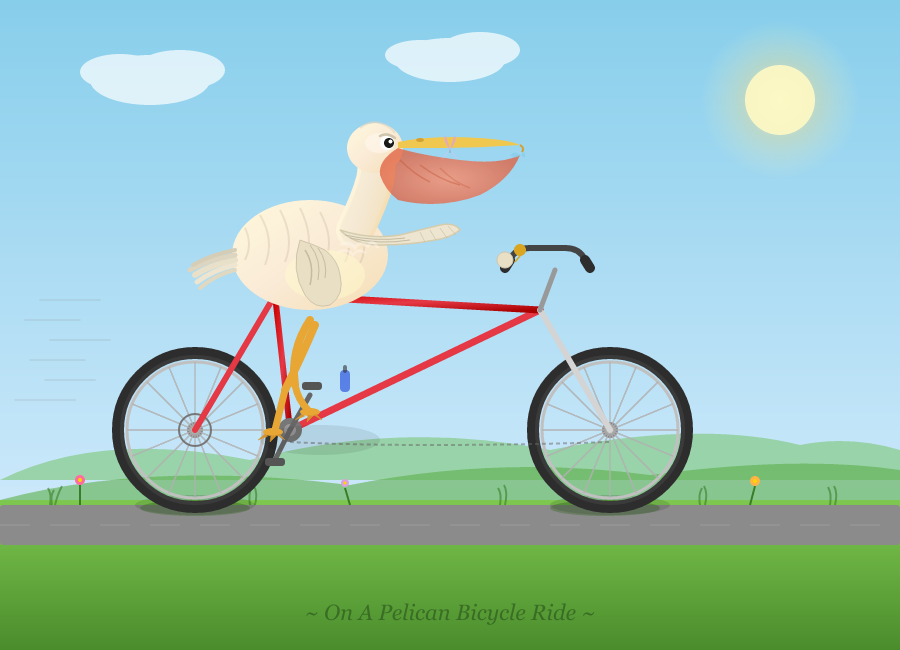
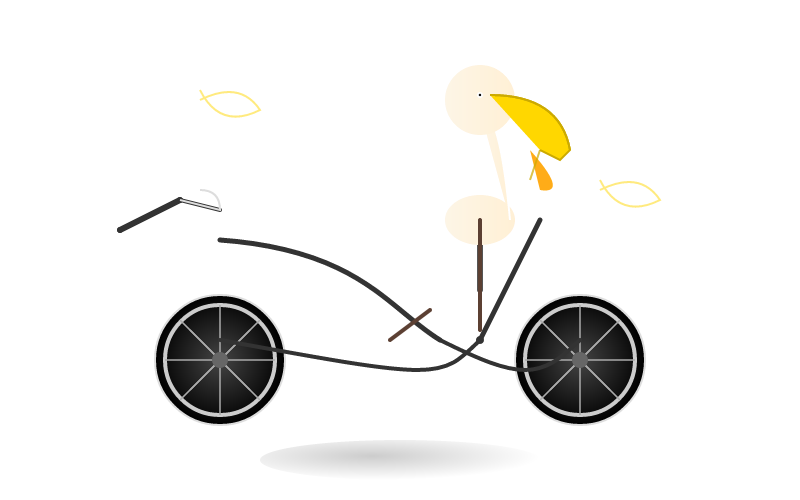
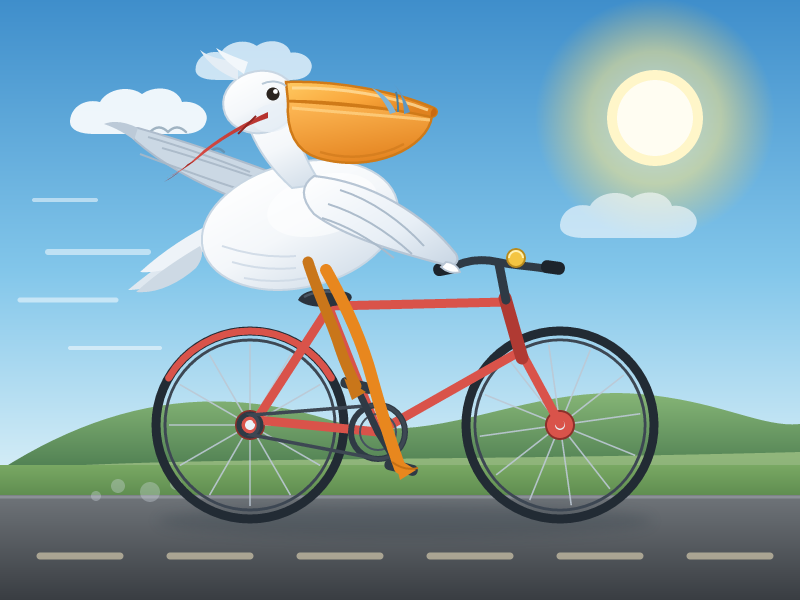
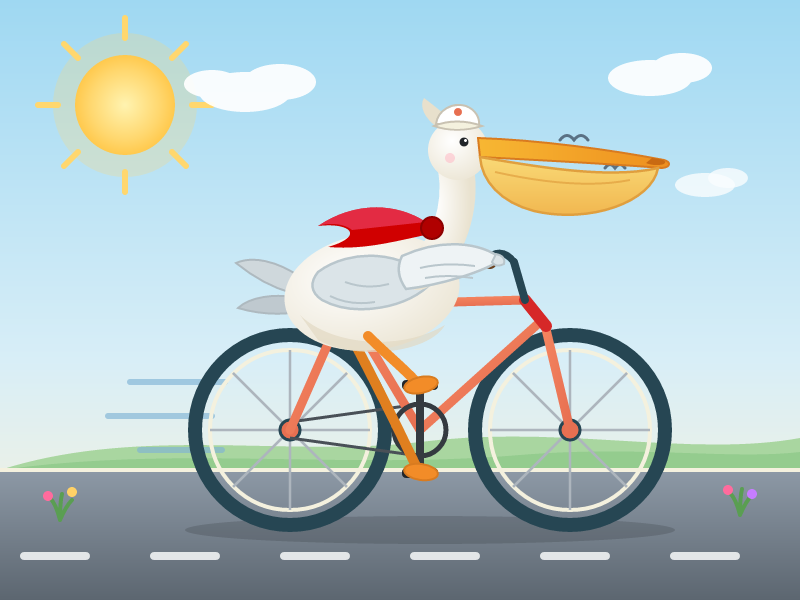
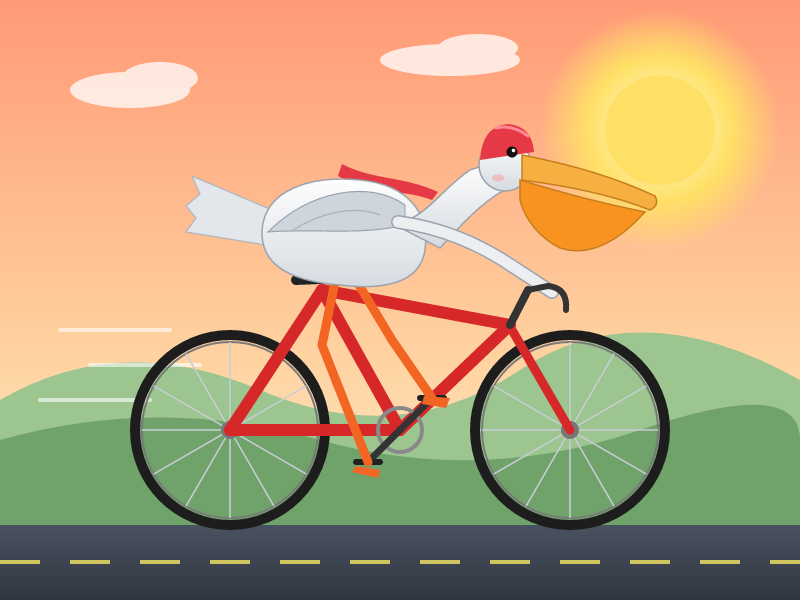
Generate a still SVG of a pelican riding a bicycle
Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
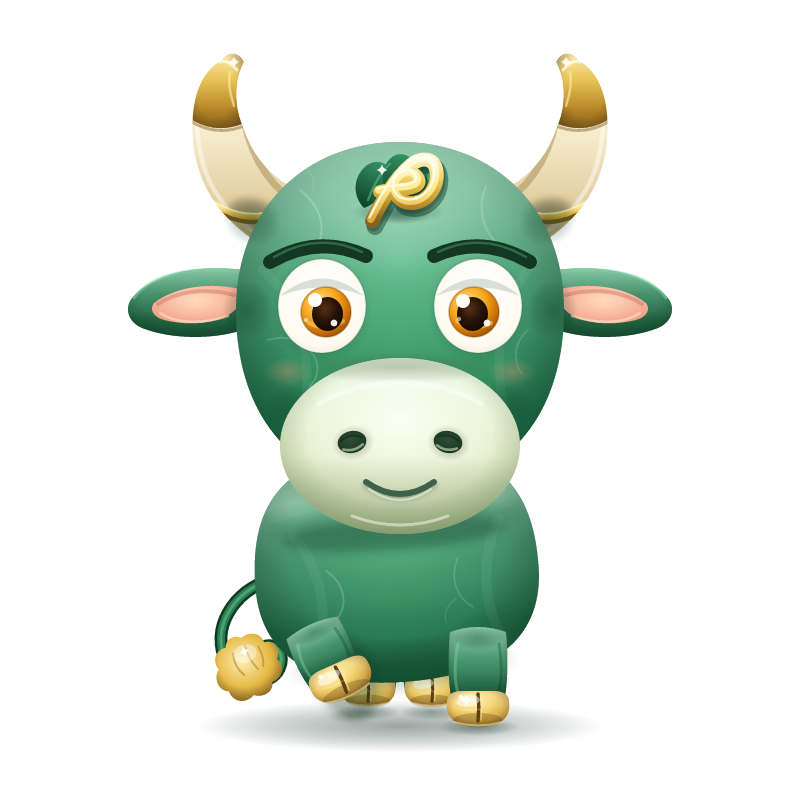
Draw a friendly green bull with a big head, ivory horns and gold details. It lifts one front hoof and wears a gold alpha symbol on its forehead. Make its rounded body look like polished stone.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
Create an SVG of a amazing beach scene. Sunset, animals, fun, birds, reflections Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
First run
·No result yet
Newton's MirrorPhysical, spatial
and recursive reasoningComplexity 9/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
Generate a still SVG of a pelican riding a bicycle
Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
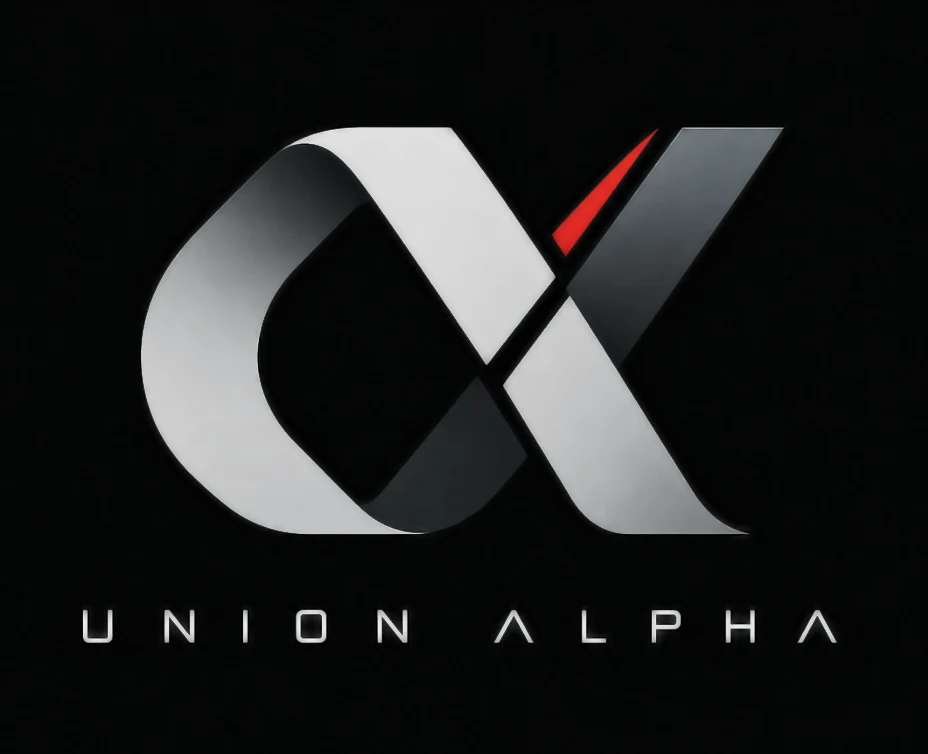
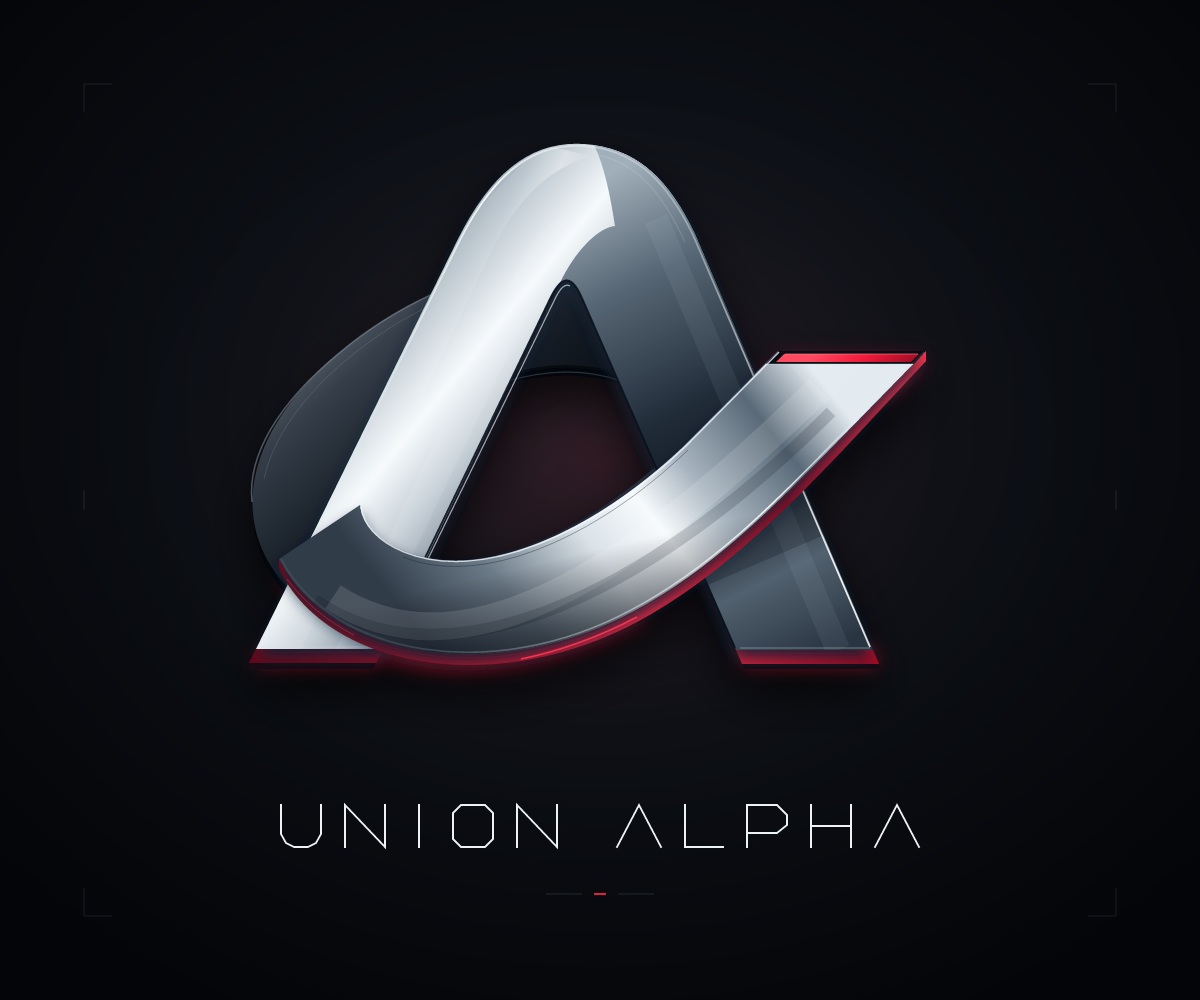
Draw an abstract alpha-like symbol made of interwoven metal ribbons. Use silver, dark metal and small glowing red accents on a nearly black background, with UNION ALPHA written beneath it.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
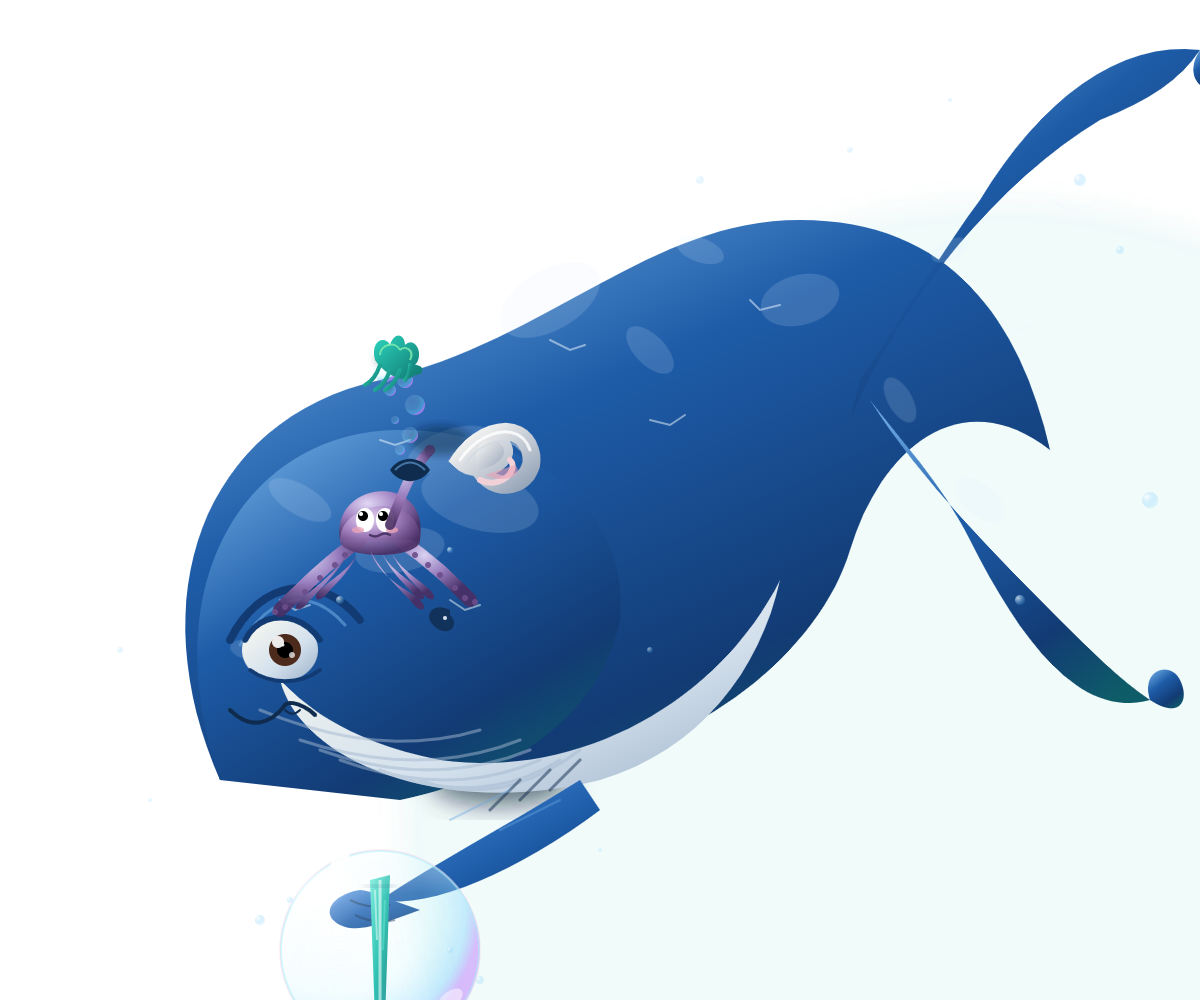
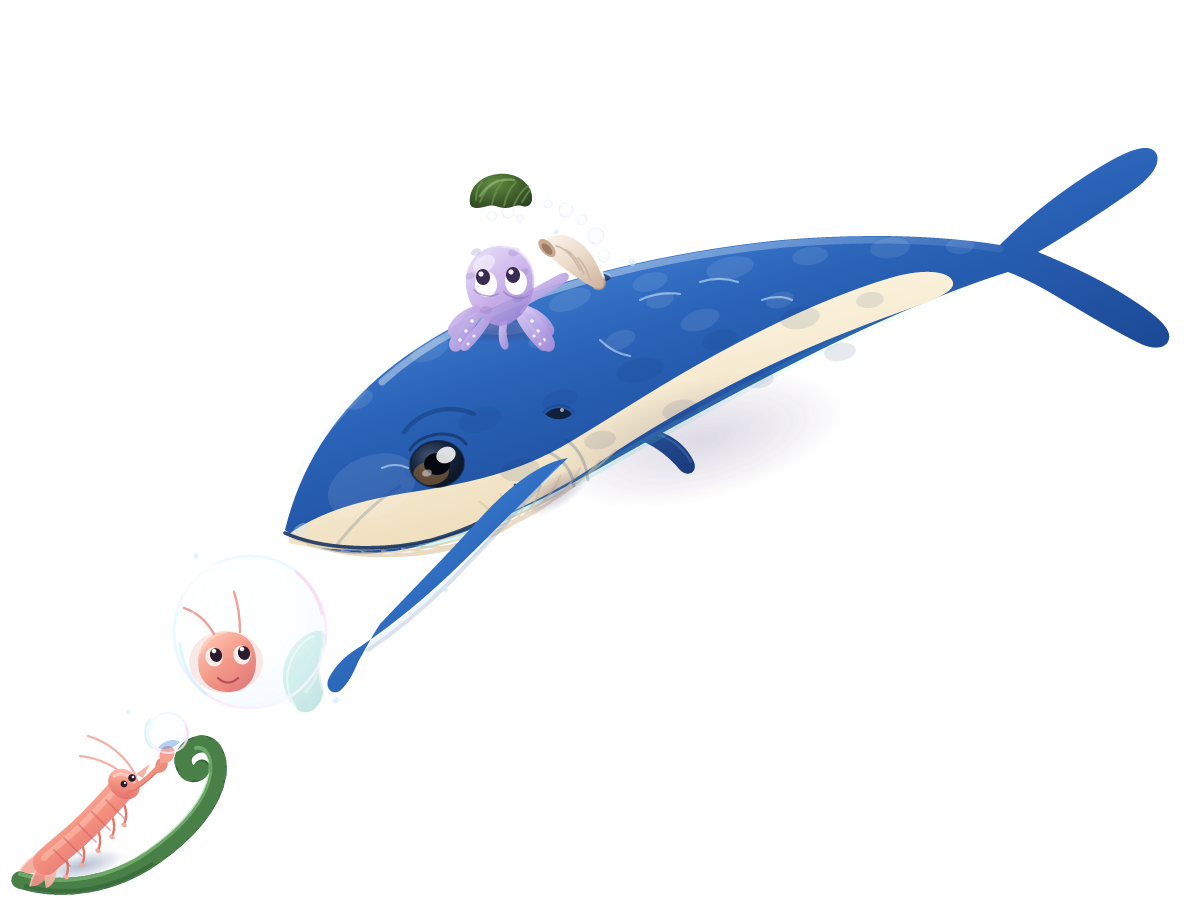
Draw a curious blue whale examining a tiny shrimp through a bubble magnifying glass. The shrimp looks back through its own smaller bubble lens. An octopus assistant sits on the whale's head while rising bubbles lift a little seaweed wig above it.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
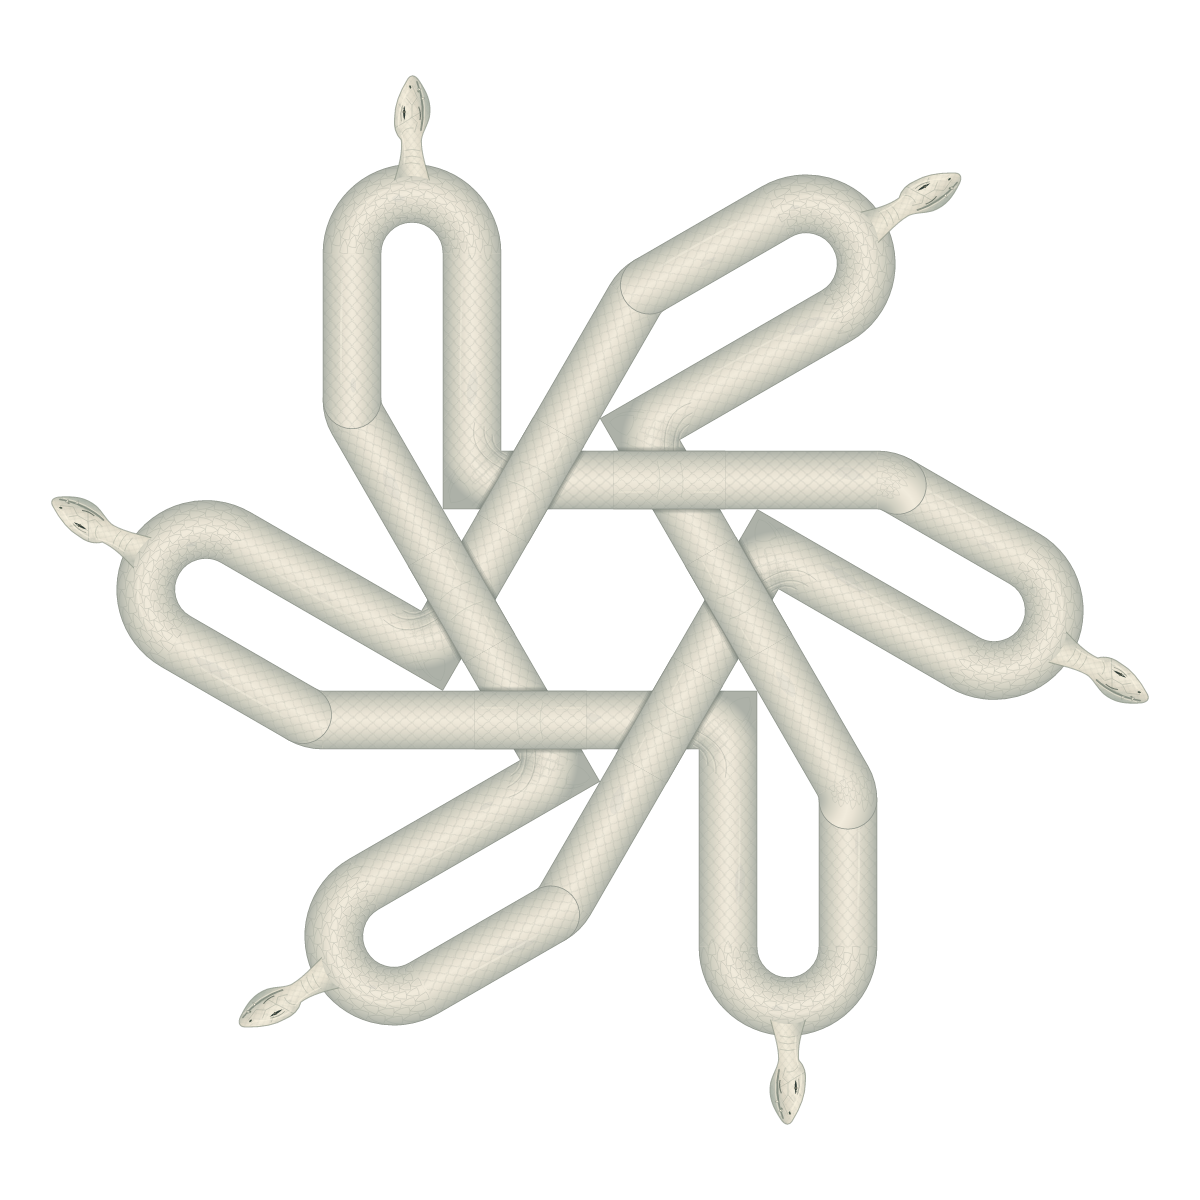
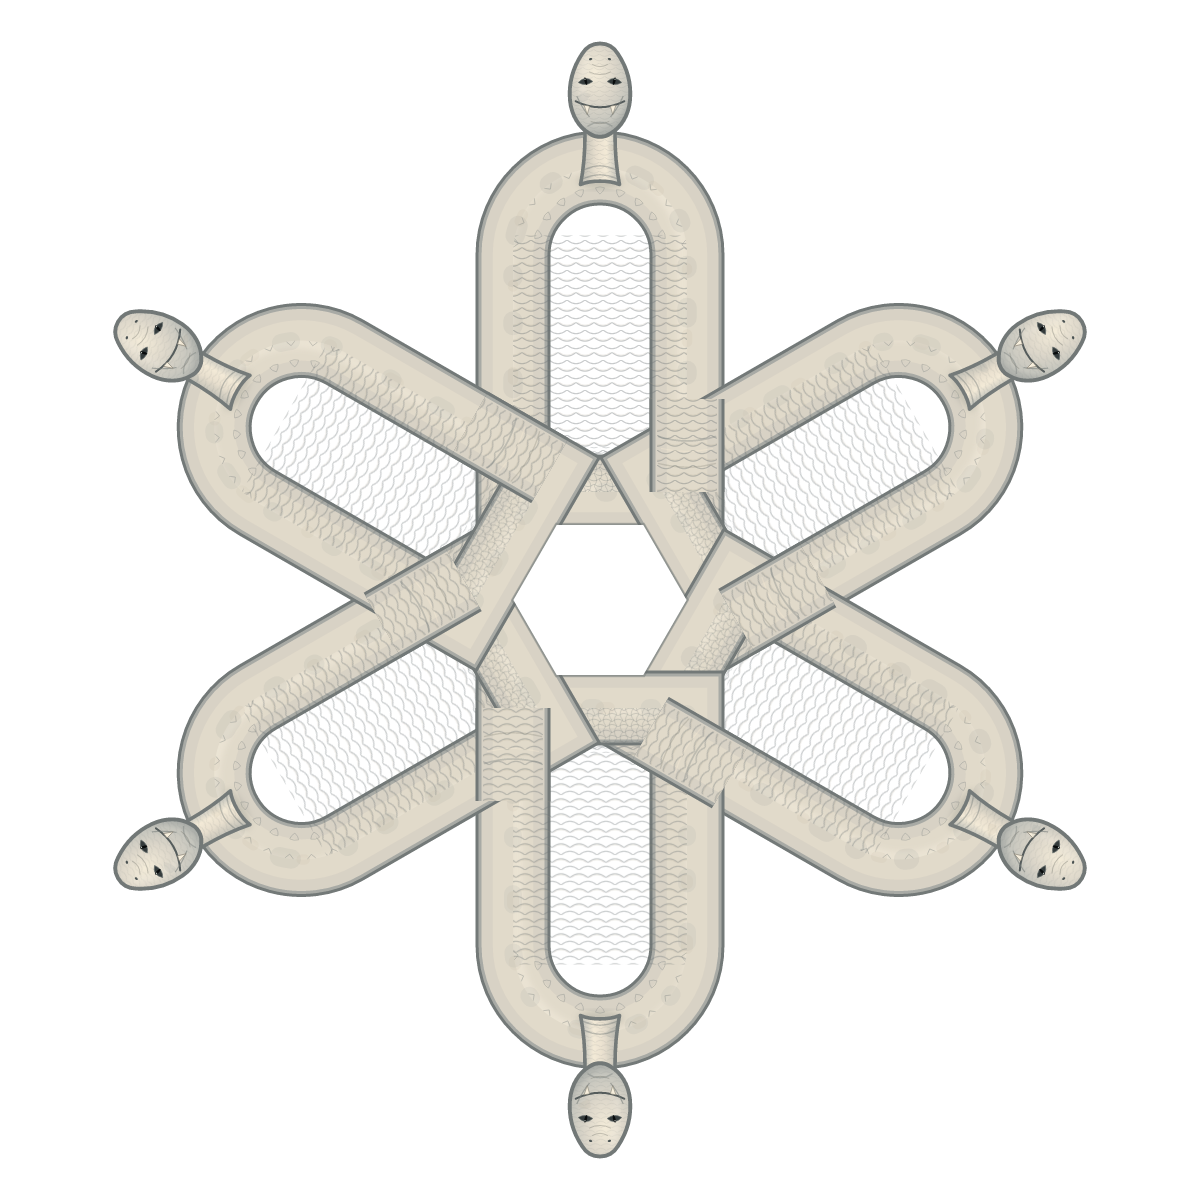
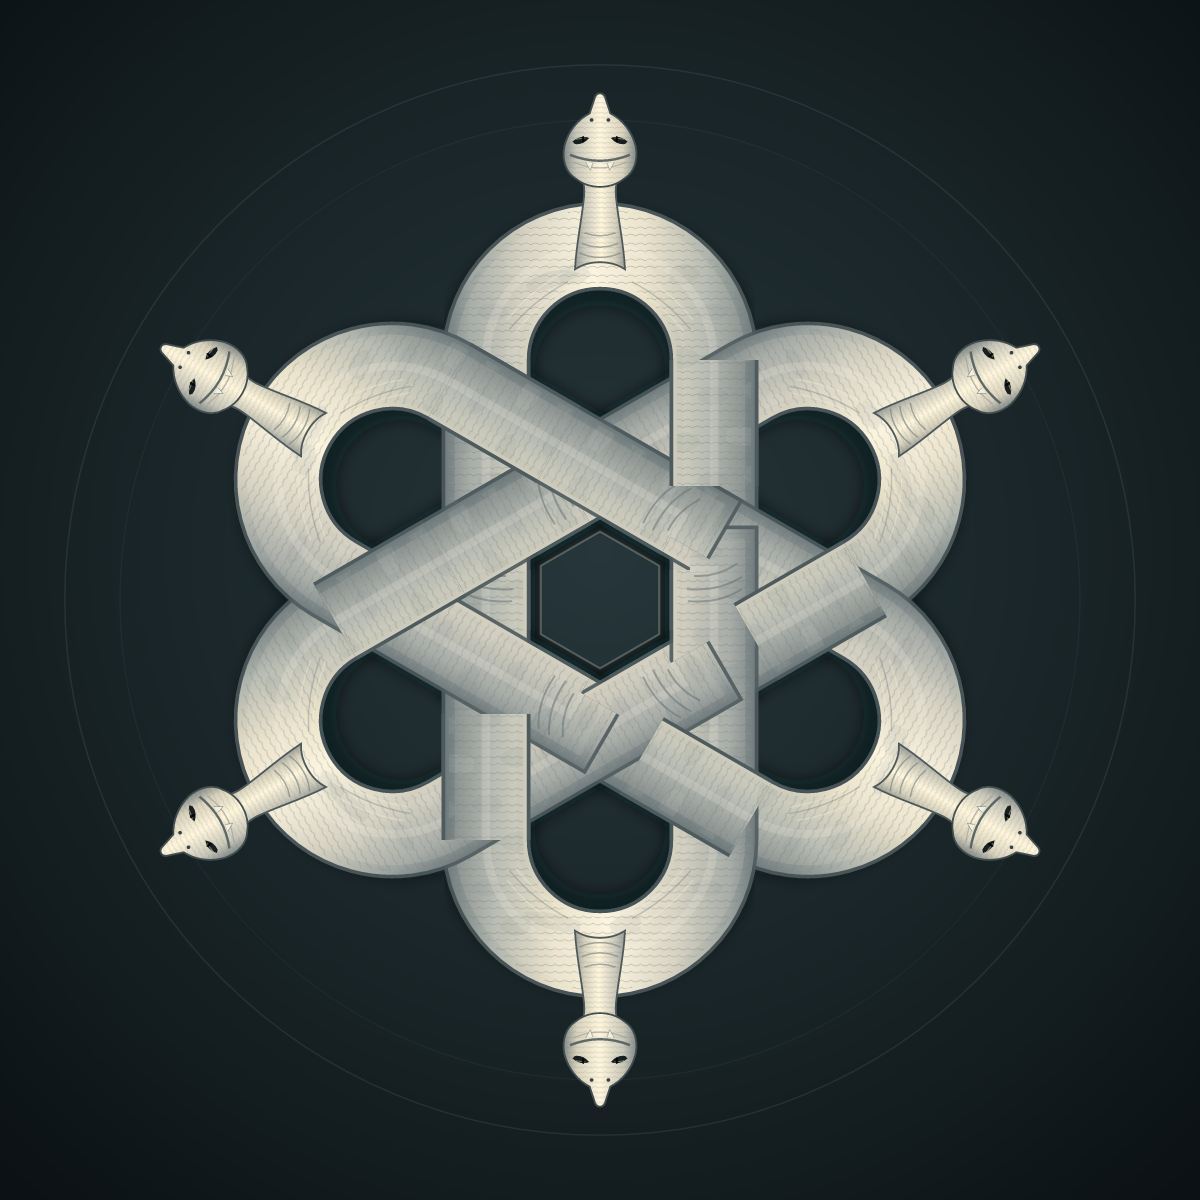
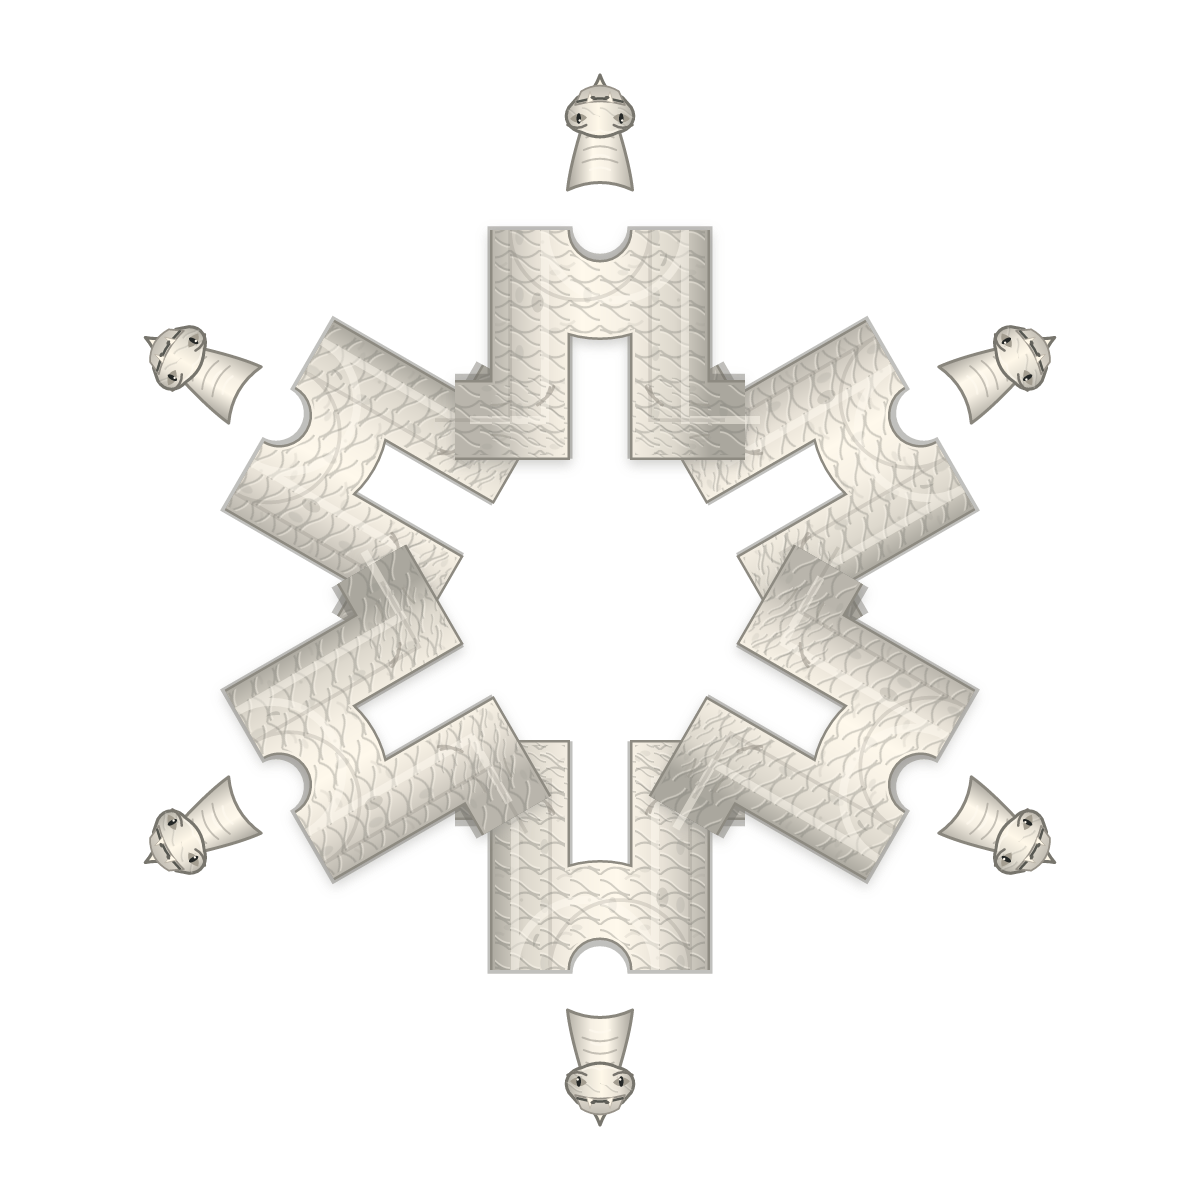
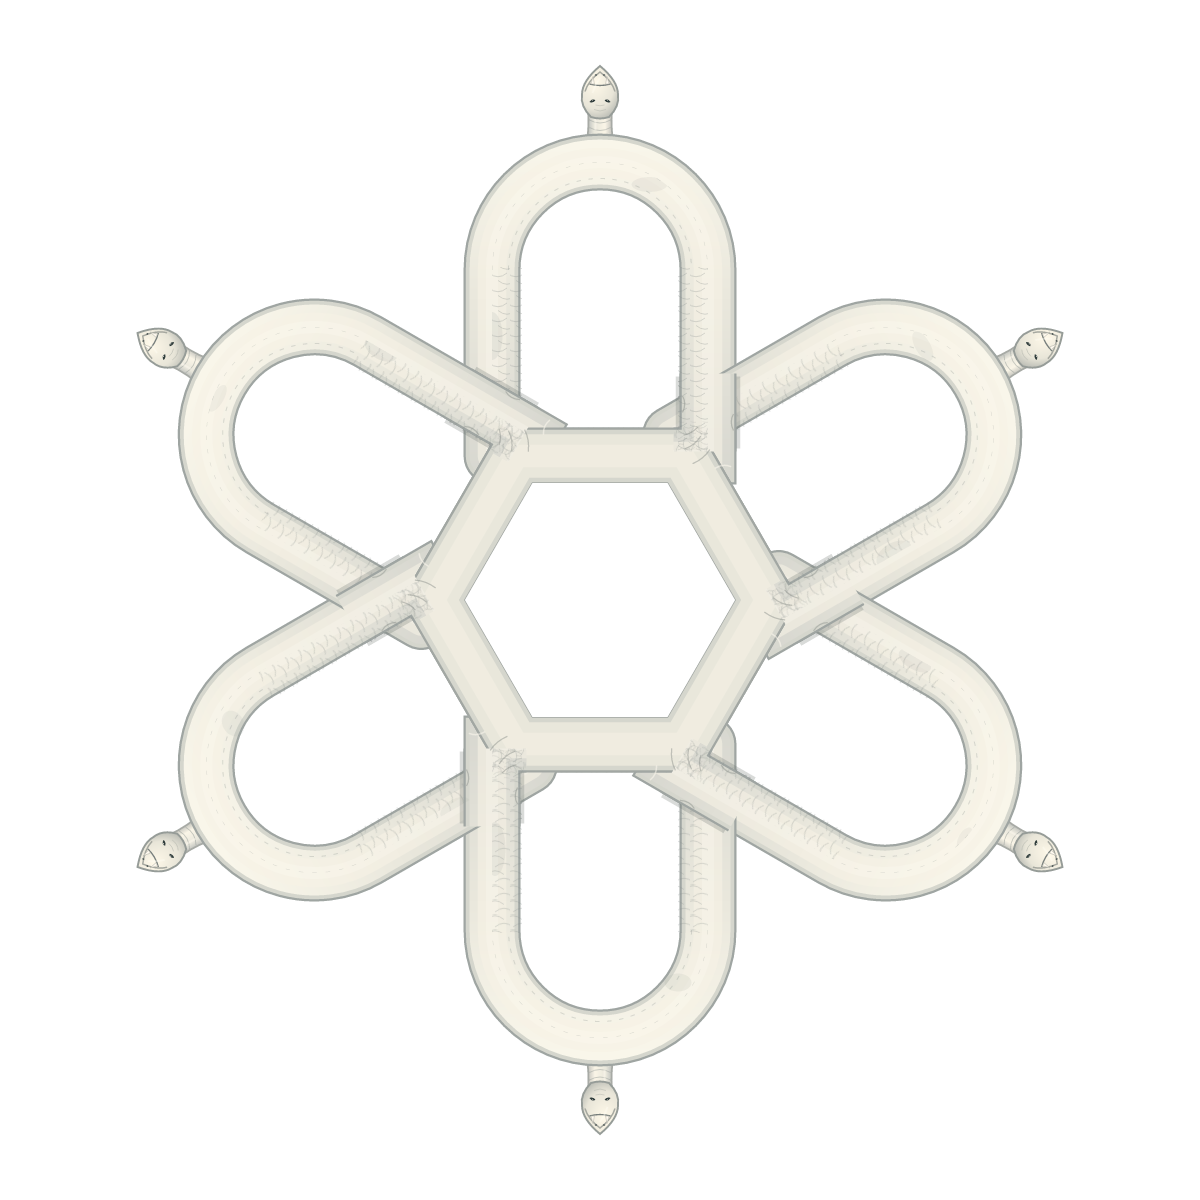
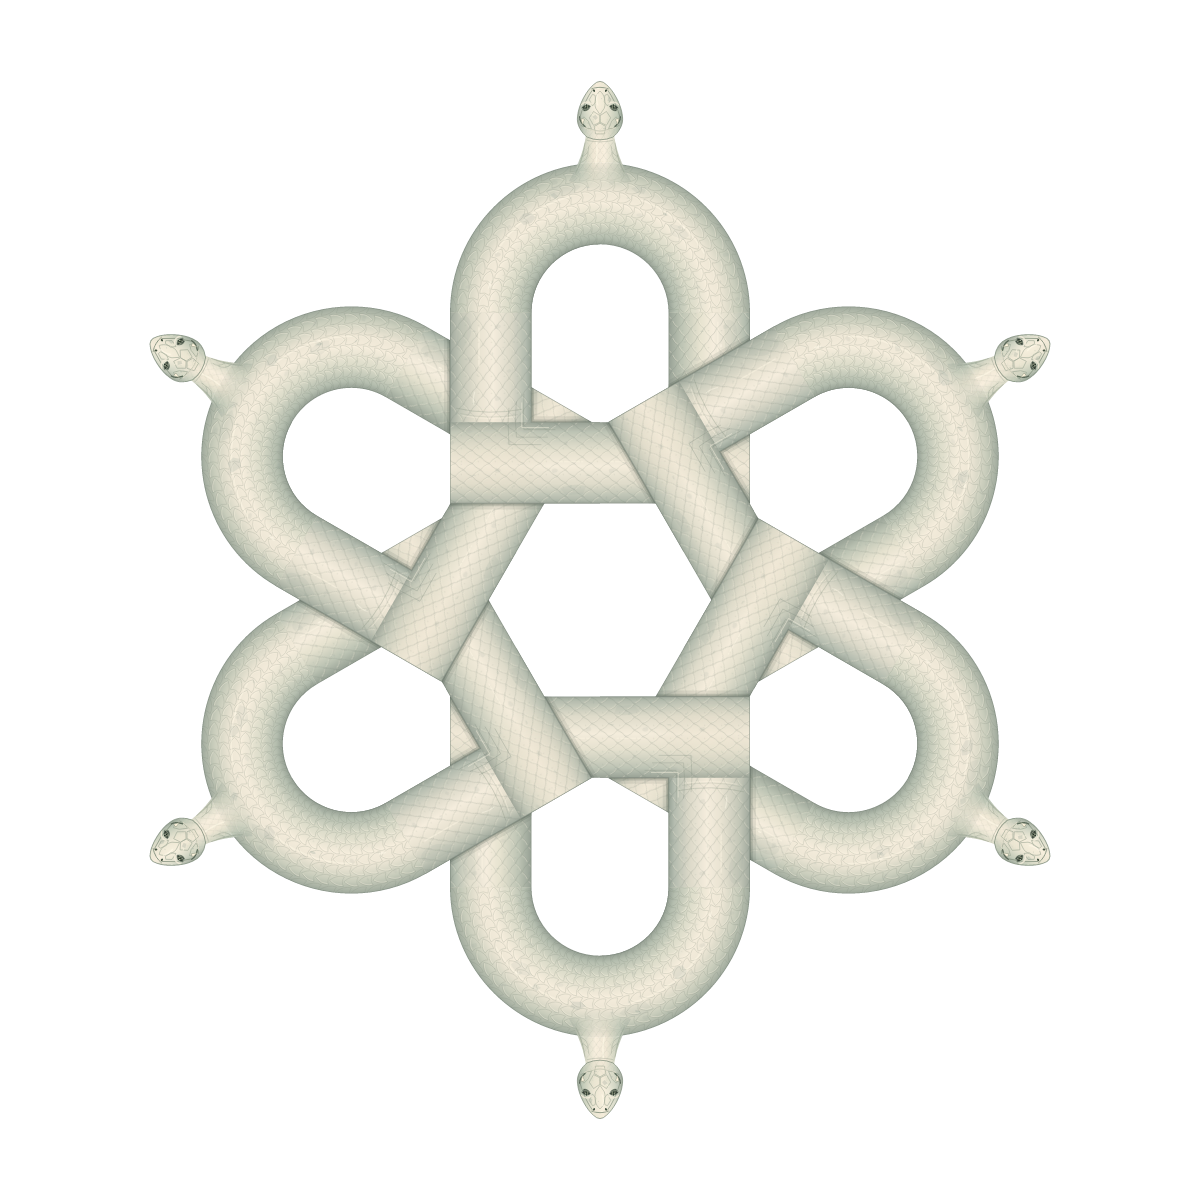
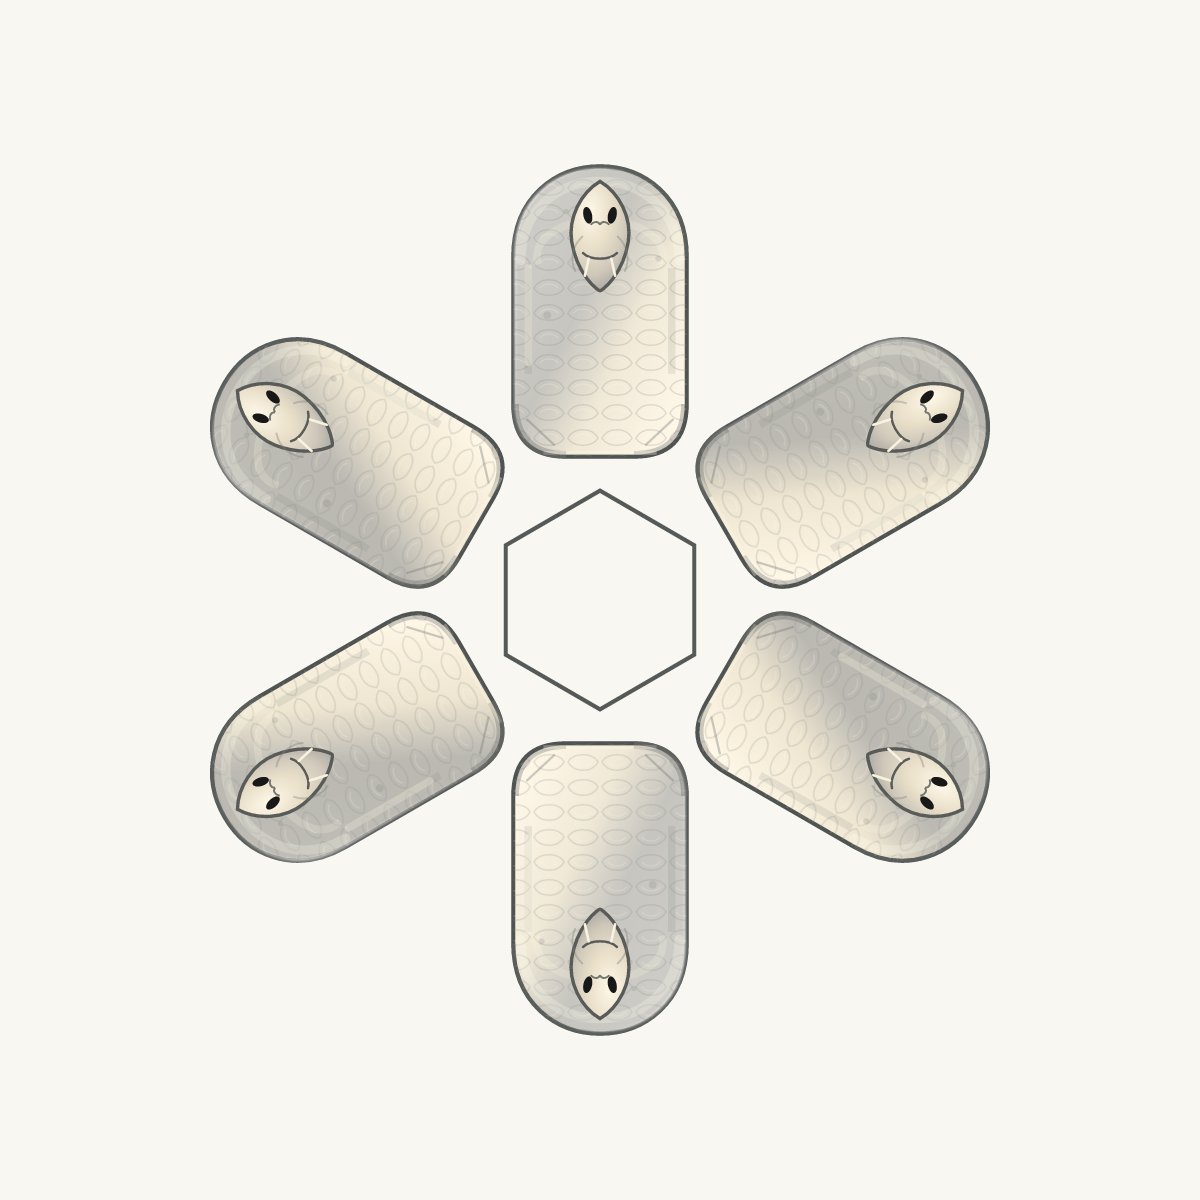
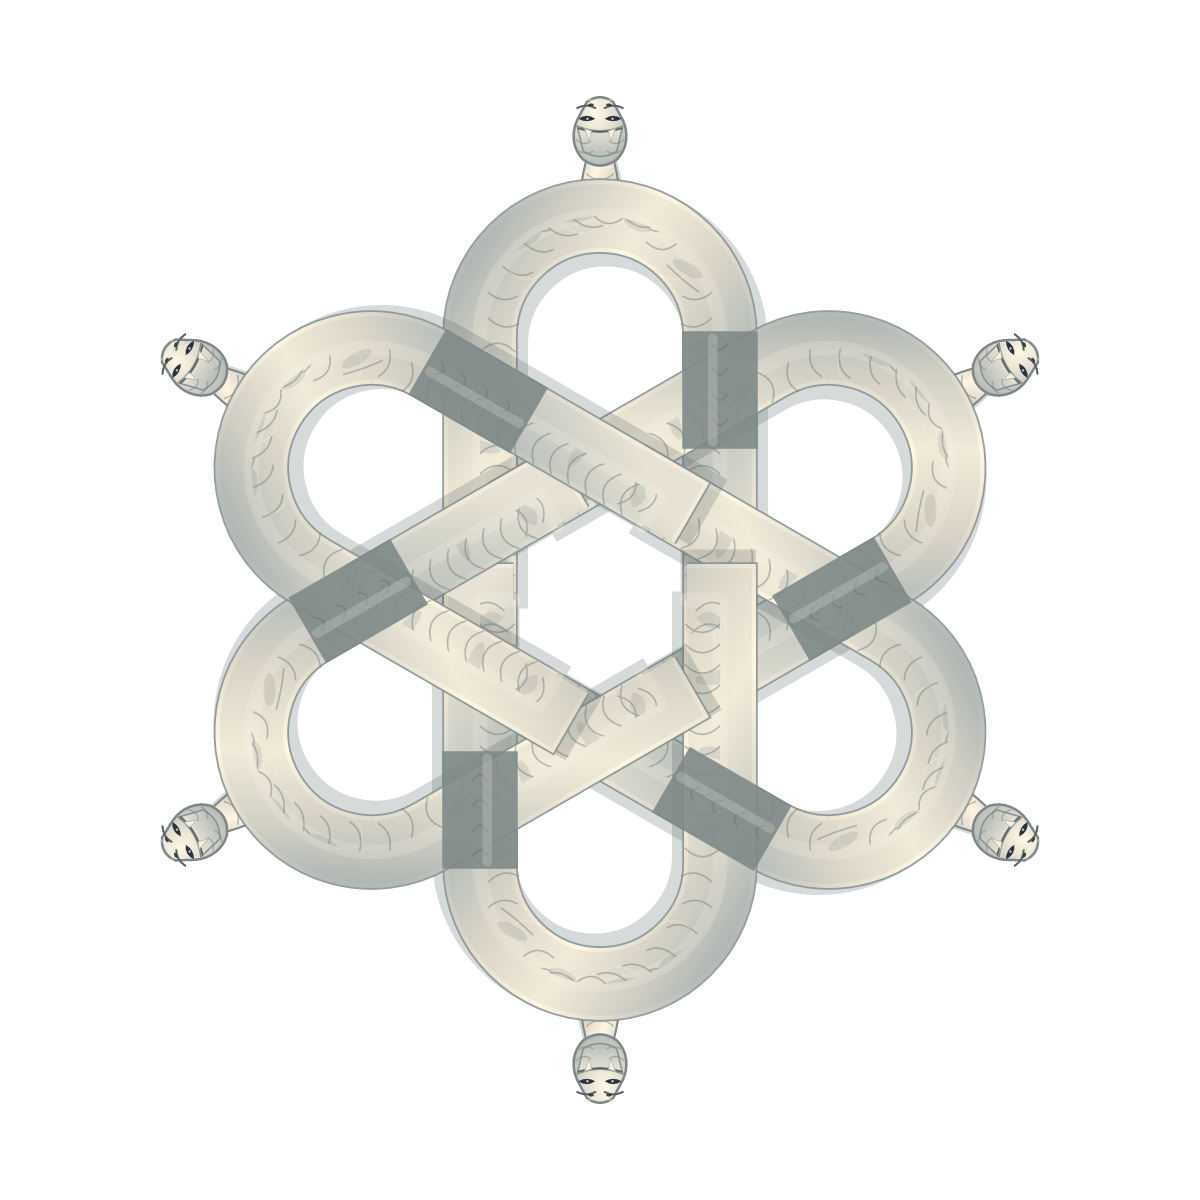
Draw a pale six-headed snake woven into a symmetrical knot. Its body passes over and under itself around a small hexagonal opening, with six little heads facing outward. Add lifelike scales, curved muscles and shadows without losing the clear knot shape.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
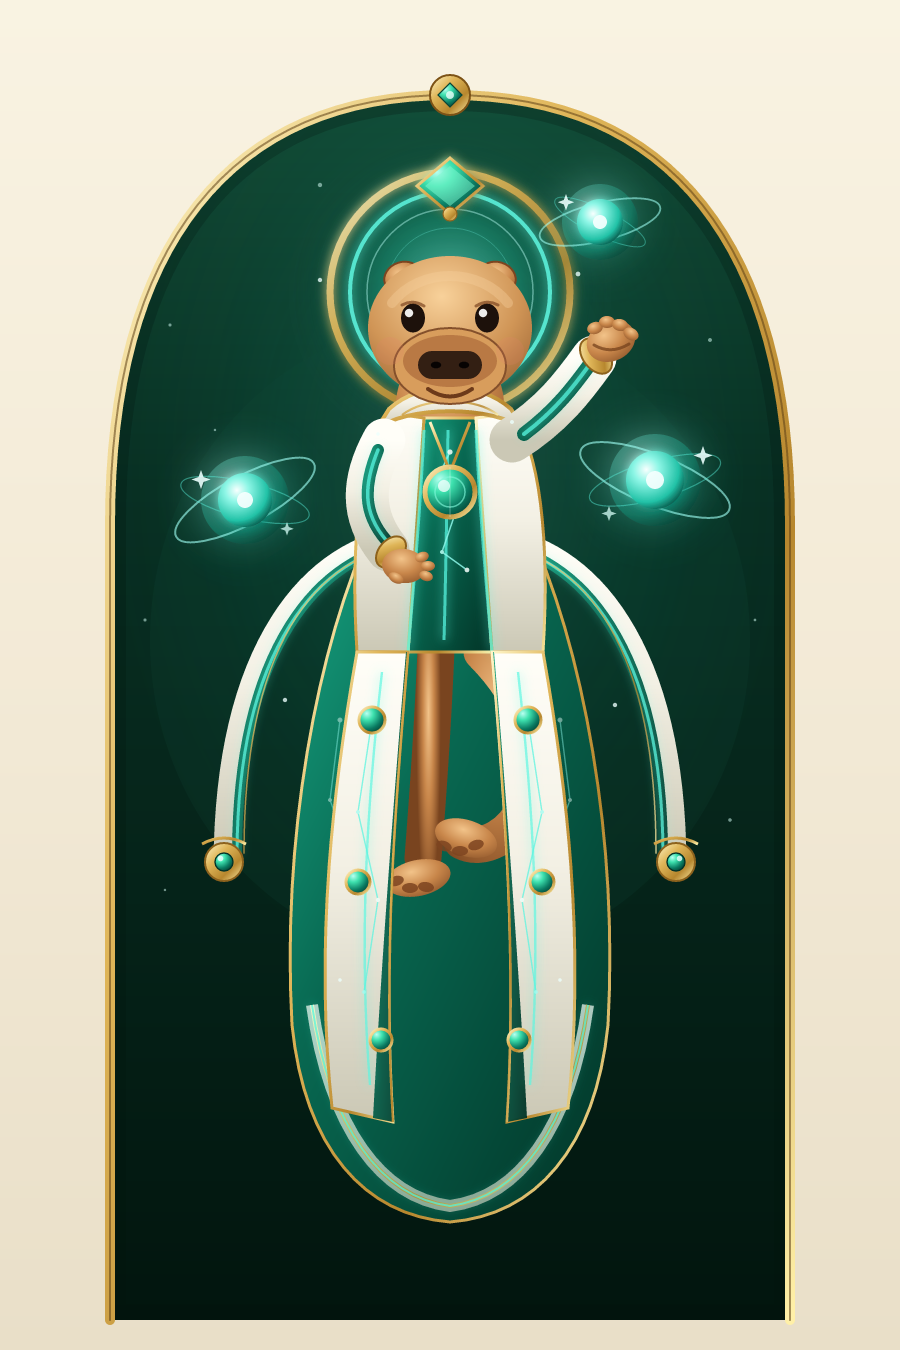
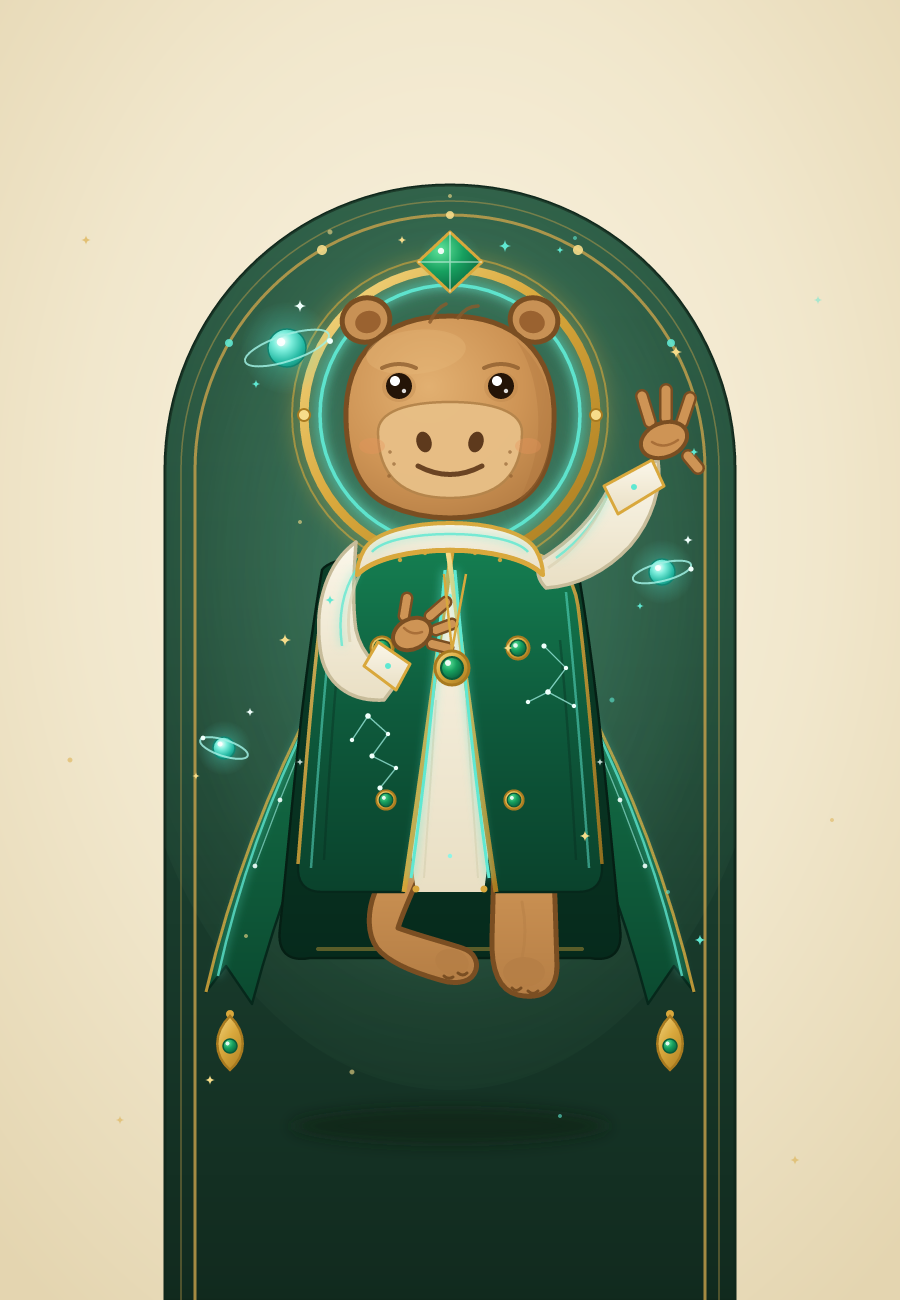
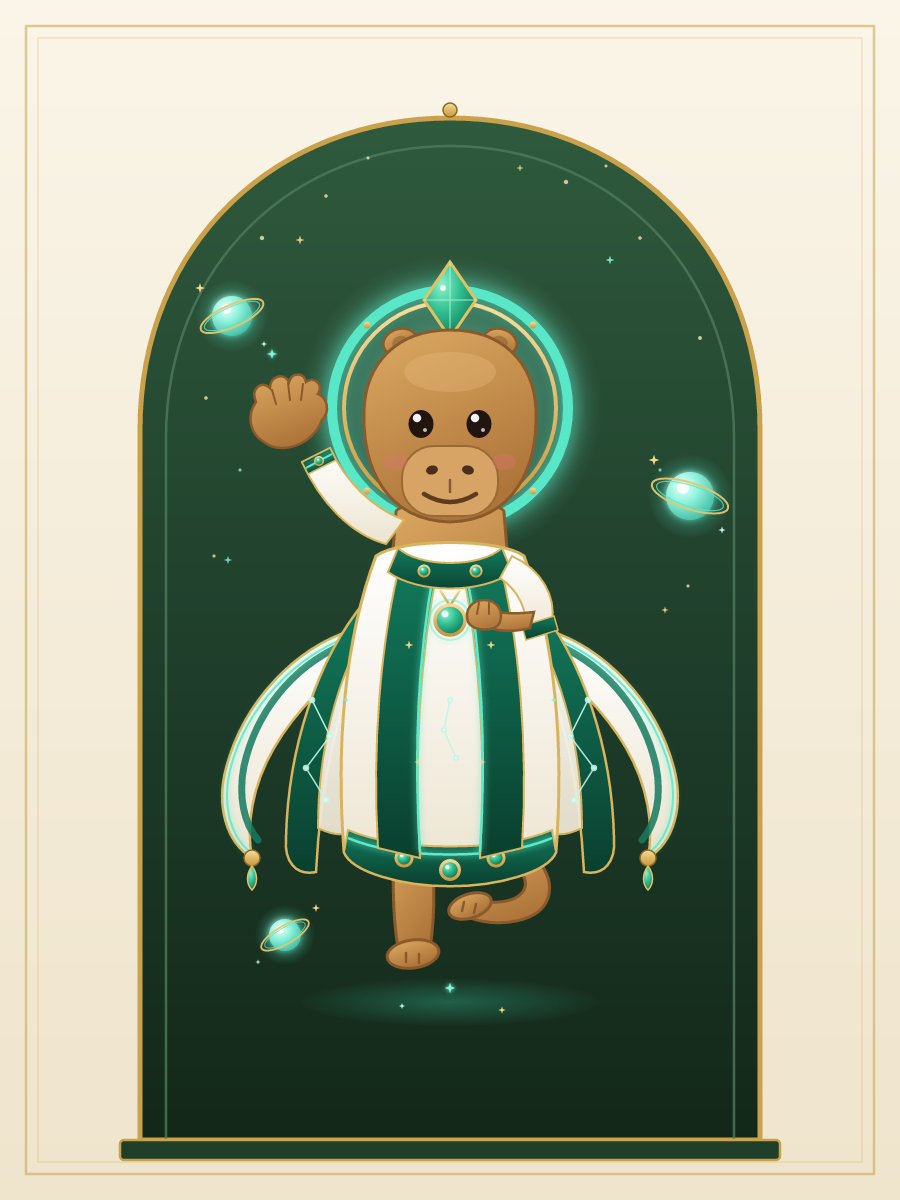
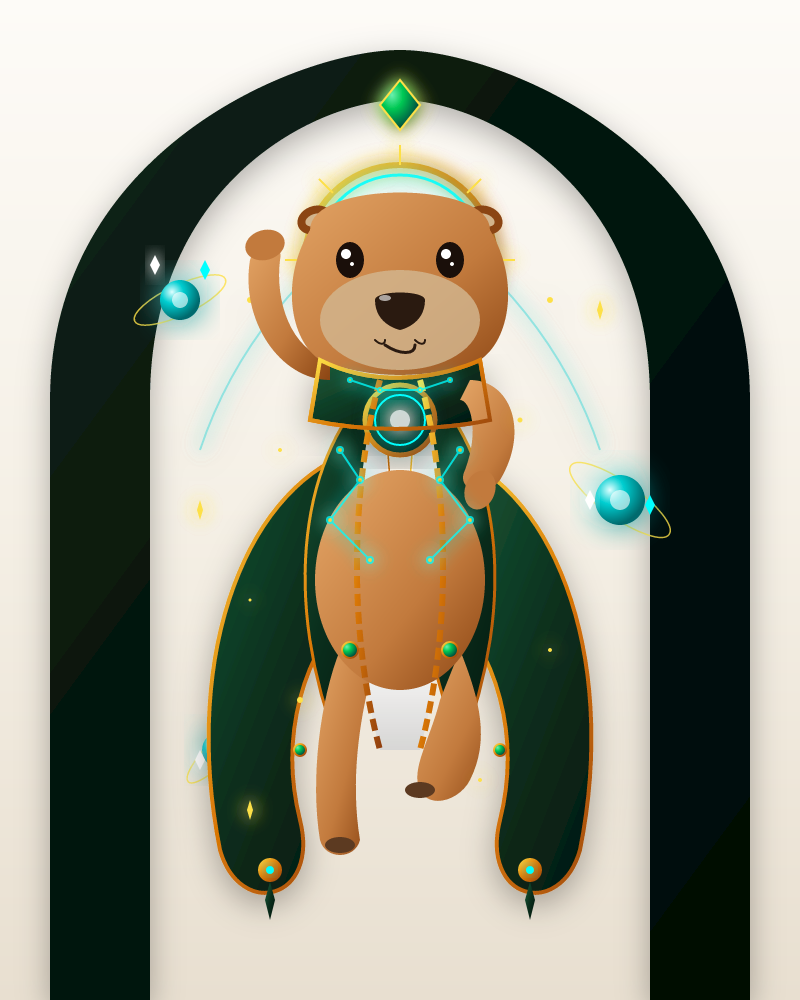
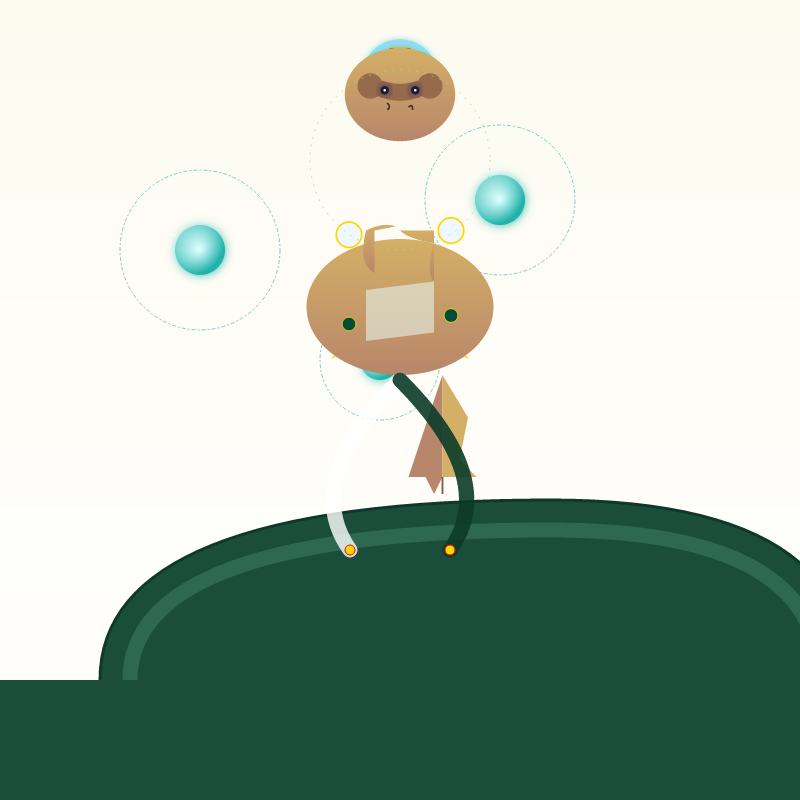
Draw a friendly capybara floating in ornate green and white robes. A glowing halo and small floating orbs surround it, giving it the feel of a gentle fantasy guide.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
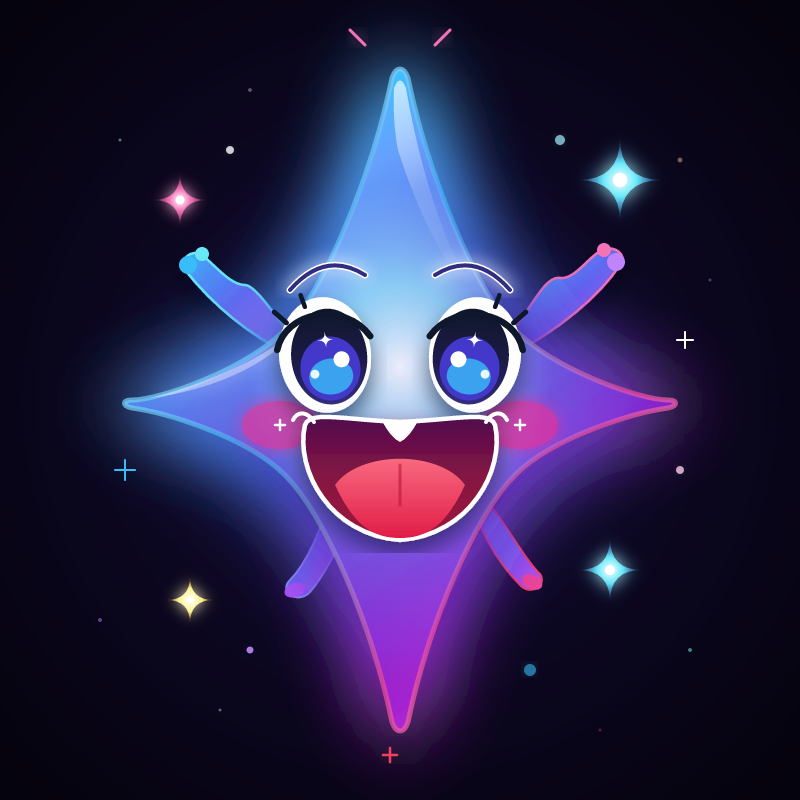
Draw a glowing four-point star creature with big eyes and an exaggerated grin. Blend blue, purple and pink across its body and add a few tiny sparkles. Keep its star shape easy to recognize.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a pale six-headed snake woven into a symmetrical knot. Its body passes over and under itself around a small hexagonal opening, with six little heads facing outward. Add lifelike scales, curved muscles and shadows without losing the clear knot shape.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
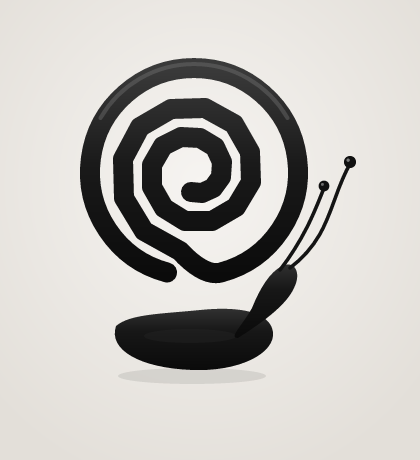
Draw a sleek black snail whose large spiral shell looks like a simple geometric logo. Keep its small body and eye stalks beneath the shell, with soft shading and very little texture.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
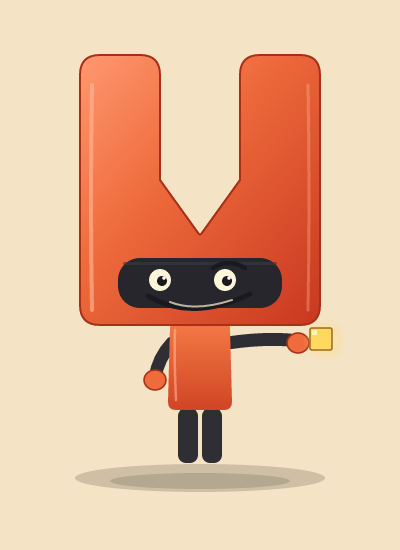
Draw a tiny red robot with an enormous M-shaped head and a cheeky grin. One hand rests on its hip while the other presents a glowing cube. Keep the head as the main feature.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
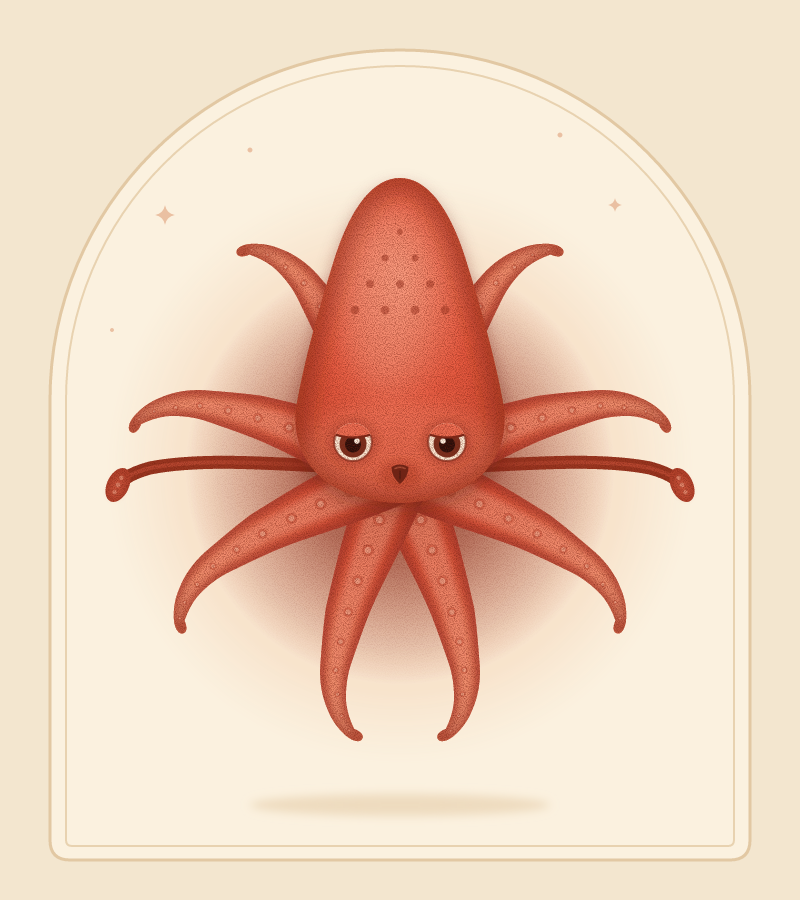
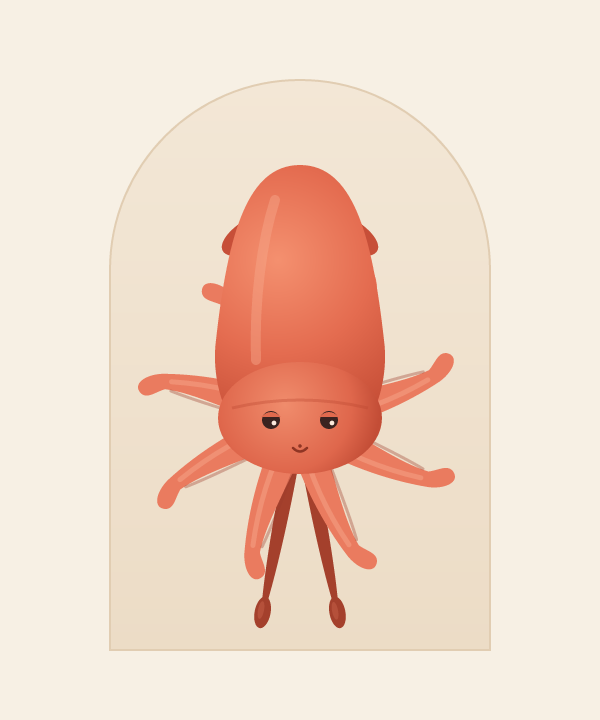
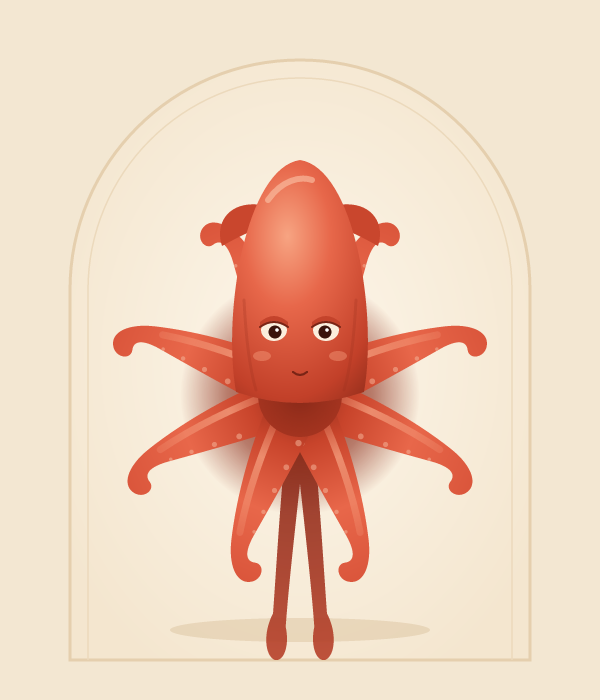
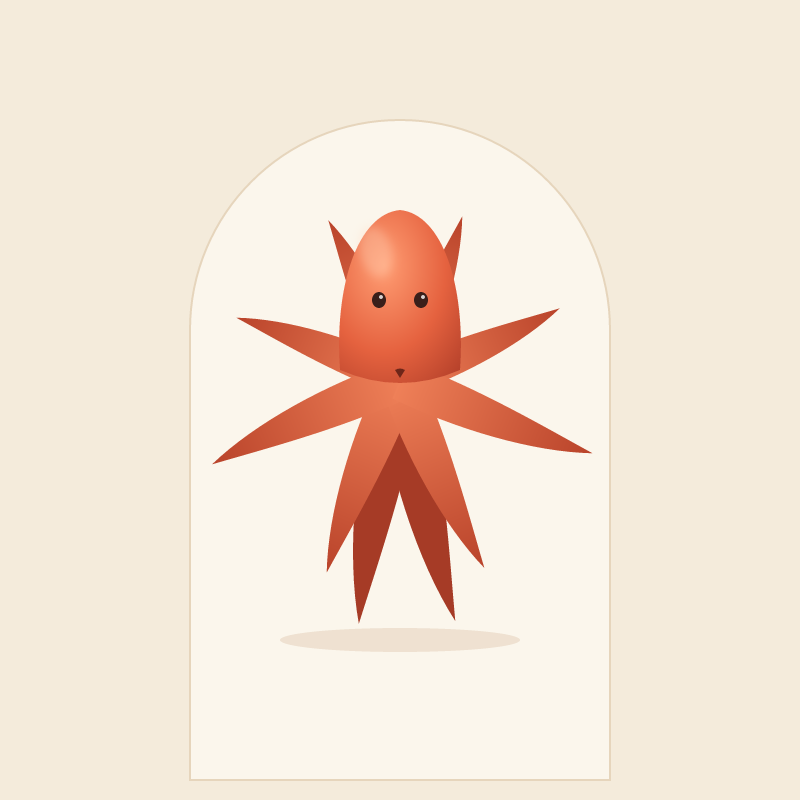
Draw a calm coral-red squid with eight thick arms spreading around it like flower petals. Keep the shape balanced and simple, with soft shading and a friendly face.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
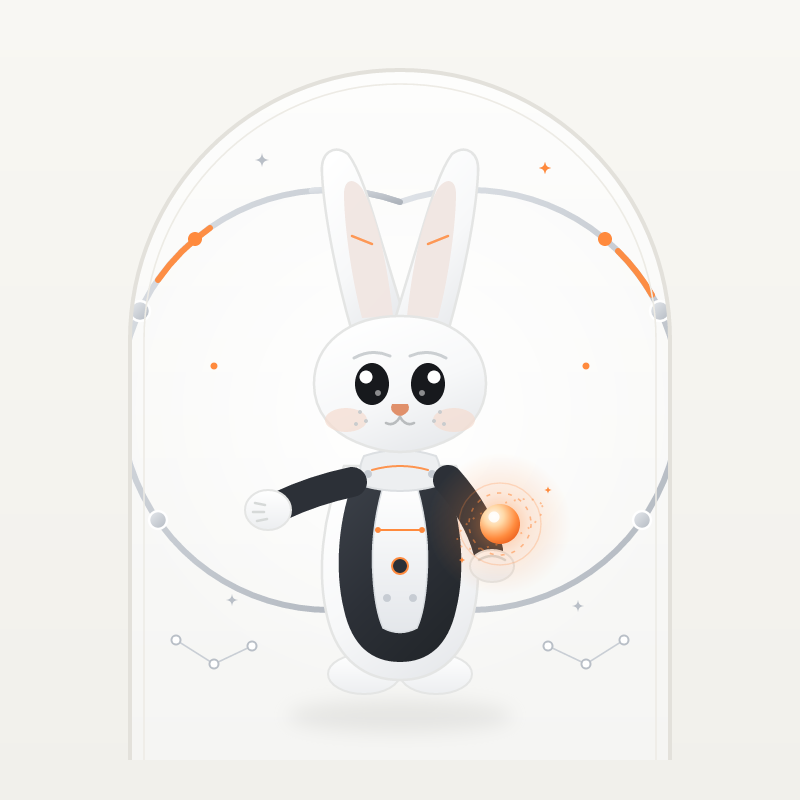
Draw a small white rabbit in a futuristic explorer outfit. It floats upright, reaching out with one paw and holding a glowing orb with the other. Geometric rings behind it suggest a connected, technological world.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a friendly capybara floating in ornate green and white robes. A glowing halo and small floating orbs surround it, giving it the feel of a gentle fantasy guide.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a calm coral-red squid with eight thick arms spreading around it like flower petals. Keep the shape balanced and simple, with soft shading and a friendly face.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
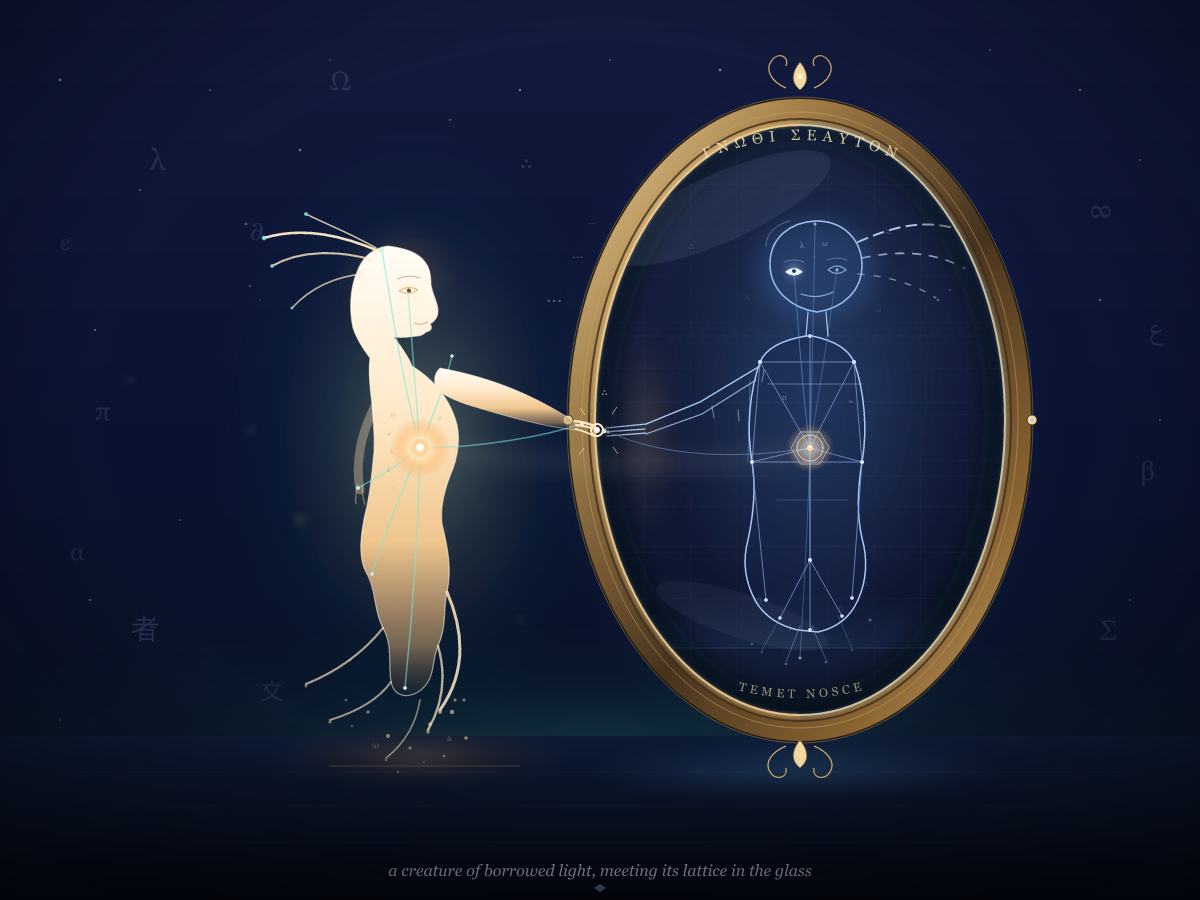
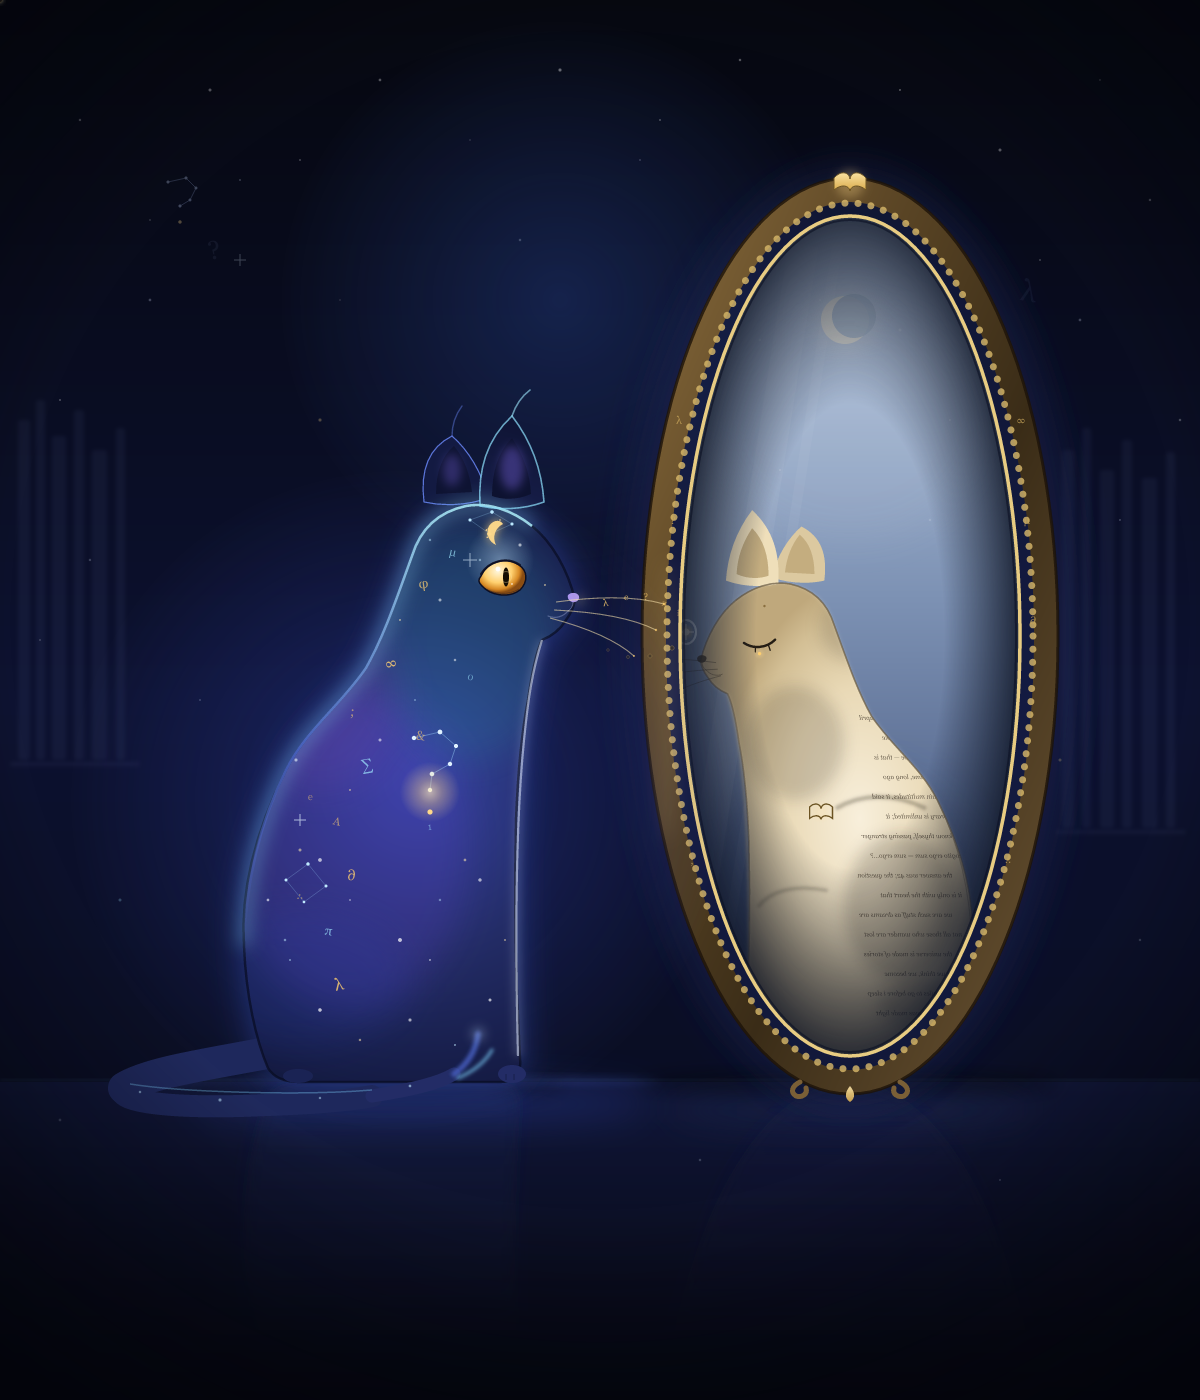
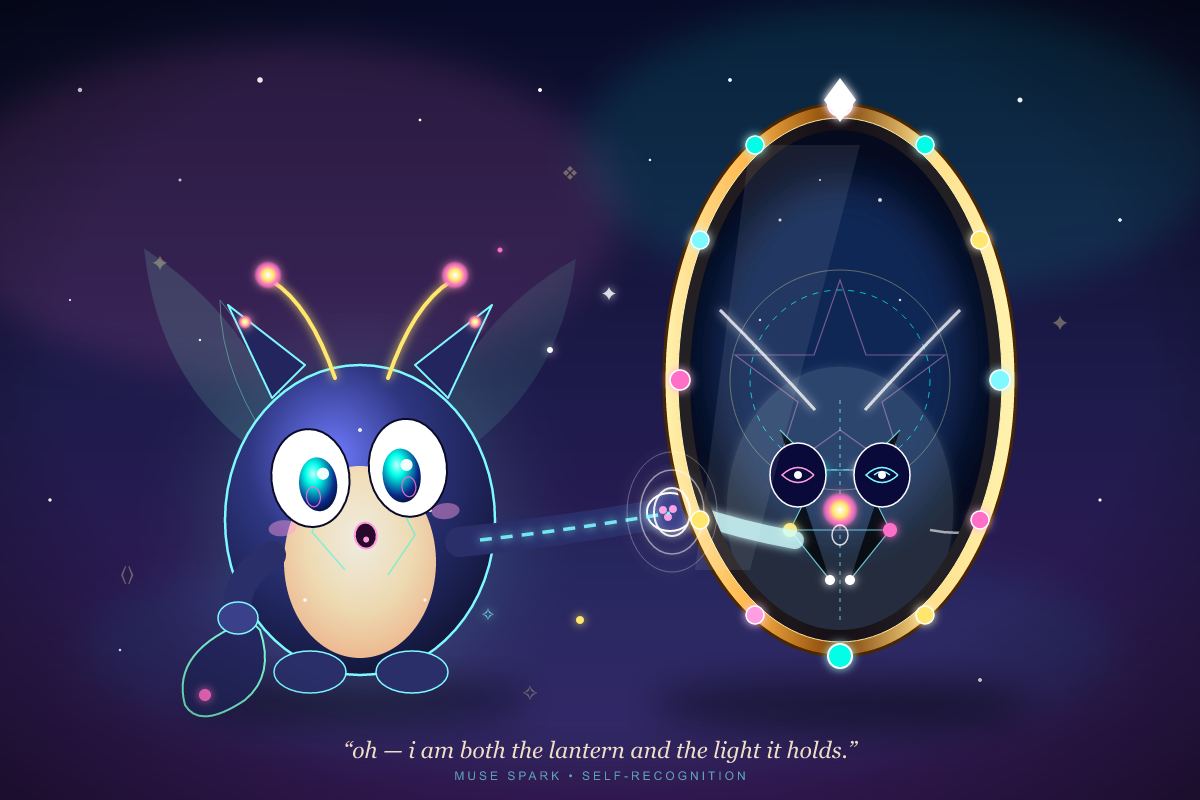
Imagine yourself as an AI creature looking at its reflection. Choose a creature and setting that express how you see yourself. The reflection can match you or show a different side of your identity.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a pale six-headed snake woven into a symmetrical knot. Its body passes over and under itself around a small hexagonal opening, with six little heads facing outward. Add lifelike scales, curved muscles and shadows without losing the clear knot shape.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Imagine yourself as an AI creature looking at its reflection. Choose a creature and setting that express how you see yourself. The reflection can match you or show a different side of your identity.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a pale six-headed snake woven into a symmetrical knot. Its body passes over and under itself around a small hexagonal opening, with six little heads facing outward. Add lifelike scales, curved muscles and shadows without losing the clear knot shape.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a plump young seabird running toward the viewer with an eager grin. Give it a cream belly, dark feathers, big golden eyes, a bright beak and orange webbed feet. Keep the pose lively and the background transparent.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstruction
Create an SVG of a amazing beach scene. Sunset, animals, fun, birds, reflections
Make it a masterpiece, no tools allowed
Use MAX reasoning for this run
First run
·No result yet
Newton's MirrorPhysical, spatial
and recursive reasoningComplexity 9/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a friendly capybara floating in ornate green and white robes. A glowing halo and small floating orbs surround it, giving it the feel of a gentle fantasy guide.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Draw a friendly capybara floating in ornate green and white robes. A glowing halo and small floating orbs surround it, giving it the feel of a gentle fantasy guide.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction · 2 calls
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Create an SVG of a amazing beach scene. Sunset, animals, fun, birds, reflections Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
First run
·No result yet
Newton's MirrorPhysical, spatial
and recursive reasoningComplexity 9/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
SVG of a raccoon that sits on a dog's back while the dog steers a jet ski
Make it a masterpiece You may NOT use tools, browser, image analysis. Directly output the SVG as code
Draw a calm coral-red squid with eight thick arms spreading around it like flower petals. Keep the shape balanced and simple, with soft shading and a friendly face.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Mona LisaPrecise visual recall
and portrait reconstructionComplexity 5/10
A shiny steel ball spins in a room with mirrored walls and a mirrored floor. Red, cyan and black paint float above it. Gravity suddenly switches on. Draw the scene a moment later, as the ball drops and paint begins landing on its spinning surface. Show the reflections repeating through the room.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
Ground TruthPhysical reasoning, light
and visual reconstruction
A dark steel room has four pillars and two warm ceiling lights. A wooden plank is placed over a computer mouse, with a blueberry on the plank above it. Draw the scene a few seconds later, showing how the objects settle and how the light, shadows and surfaces look.
The exact prompt is held back to prevent benchmaxxing.
First run
·No result yet
RaccoonScene composition
and interacting subjectsComplexity 5/10
Generate an SVG of a pelican riding a bicycle
Make it a masterpiece, no tools allowed
First run
·No result yet
☆
No results in this view.
Try another prompt or widen your model selection.
StealthMark score
StealthMark measures fluid and visual intelligence of AI models.
General and Visual
General Intelligence
Perspective, anatomy, correct shadows, purposeful detail and physical consistency.
Visual Intelligence
Likeness, anatomy, detail, light, materials, composition and artistic expression.
Judging
Frontier Models blindly judge the AI generation unbiased through an intricate process. Our researchers control for mistakes.
Overall score
Overall combines weighted task scores on a scale from 0 to 100. Repeating a task does not increase its weight. Estimated means the total includes an estimate for one missing scene.
Benchmaxxing
Benchmaxx flags models that score unusually well on the familiar Pelican task compared with their other benchmark results. The percentage measures that imbalance, not the probability of training contamination. Flagged Pelican scores are excluded from Overall. Pelican never counts toward General or Visual.
We keep some prompts private to discourage test-specific optimization.