Ox Alpha

Revealed · Z.ai GLM-5.3-Flash

Ox Alpha,
revealed. GLM-5.3-Flash

Multimodal coding, long agent tasks, and open weights. Meet Z.ai’s GLM-5.3-Flash.

Explore the model

VISION

Images + video

Give it screenshots, diagrams or screen recordings. Native visual input helps it understand interfaces and use visual feedback while coding.

Z.ai · visual capabilities ↗
1Mcontext · Z.ai
18B / 320Bactive / total parameters
MITopen-weight license

Model specifications ↗·Official weights ↗

Ox Alpha’s friendly jade ox mascot with ivory and brass horns, a gold alpha forelock, and one lifted hoof.

Advertisement · Demodokos

Give your world a voice.

Create expressive narration, character dialogue and original music on your Windows PC with Demodokos Foundry.

EPIC FANTASY · BOOK INTRO

Fantasy Audiobook

Created with Demodokos Foundry

OX ALPHA · BENCHMARKS

Reasoning. Coding.
The comparison.

Compare Ox Alpha’s released model, GLM-5.3-Flash, with Qwen 3.8, GPT, Claude and Gemini.

Ox Alpha / GLM-5.3-FlashIndependent results · Artificial Analysis27 September 2026

GRADUATE-LEVEL SCIENCE

GPQA Diamond

198 questions in physics, chemistry and biology. Measures scientific knowledge and reasoning.

  • GPT-6 Astramax96.1%
  • Gemini 3.7 Flashhigh94.5%
  • GPT-5.6 Solmax94.1%
  • Qwen 3.8 Max0902 · reasoning92.8%
  • GPT-5.6 Terramax92.5%
  • Qwen 3.8 Flash NextReasoning92.3%
  • Claude Opus 4.8Adaptive · max92.0%
  • GLM-5.3-FlashOx Alpha · max91.2%
  • Qwen 3.8 27Bxhigh90.5%

Artificial Analysis · results ↗

9 models · highest score first · scroll to compare ↕

HLE · TEXT-ONLY · NO TOOLS

Humanity’s
Last Exam

2,158 expert-level questions across mathematics, humanities and science.

  • GPT-6 Astramax54.7%
  • GPT-5.6 Solmax49.5%
  • Claude Opus 4.8Adaptive · max48.7%
  • Gemini 3.7 Flashhigh47.9%
  • Qwen 3.8 Max0902 · reasoning43.1%
  • GPT-5.6 Terramax42.9%
  • GLM-5.3-FlashOx Alpha · max39.9%
  • Qwen 3.8 Flash NextReasoning38.0%
  • Qwen 3.8 27Bxhigh33.9%

Artificial Analysis · results ↗

9 models · highest score first · scroll to compare ↕

91.2% on GPQA Diamond. 39.9% on HLE. GLM-5.3-Flash scores above Qwen 3.8 Flash Next on HLE; Qwen 3.8 Max leads it on both reasoning tests.

CODING & LONG CONTEXT

The same models. Three more tests.

Higher is better · gold underline = best shown

Sorted by Terminal-Bench 2.1 · highest first

Swipe the table to compare all three tests. Model names stay in view.

Independent Artificial Analysis scores, checked 27 September 2026. Percent correct; higher is better. Reasoning settings appear below each model name.
Model / reasoningTerminal-Bench 2.1Complete terminal tasksSciCodeScientific Python · subproblemsAA-LCR v1.1Reason across long documents
Qwen 3.8 Max0902 · reasoning88.8%52.1%80.3%
GPT-6 Astramax88.4%56.5%80.7%
GPT-5.6 Solmax88.0%57.1%84.0%
GPT-5.6 Terramax88.0%55.0%83.0%
Qwen 3.8 Flash NextReasoning86.1%50.6%79.7%
Gemini 3.7 Flashhigh85.8%57.2%81.7%
Claude Opus 4.8Adaptive · max84.6%54.4%77.7%
GLM-5.3-FlashOx Alpha · max84.3%51.6%80.0%
Qwen 3.8 27Bxhigh79.8%46.6%82.0%
Test settings & sources
Reasoning tests
GPQA uses the 198-question Diamond subset. HLE uses the 2,158 text-only questions from the May 2025 revision, without tools. Both report pass@1.
Coding tests
Terminal-Bench 2.1 uses Terminus 2 across 89 tasks, averaged over three runs. SciCode scores 288 Python subproblems with scientific background provided, also over three runs.
Long context
AA-LCR v1.1 uses 100 questions over documents of roughly 100K tokens, averaged over three runs. Model links open the evaluator’s individual result pages.

Reasoning effort is shown beside each model; Qwen 3.8 Max is the 0902 release. Scores are rounded to one decimal. Artificial Analysis methodology ↗

Z.AI RELEASE EVALUATION

Code & automation

Score / 100

Sorted by DeepSWE · highest first

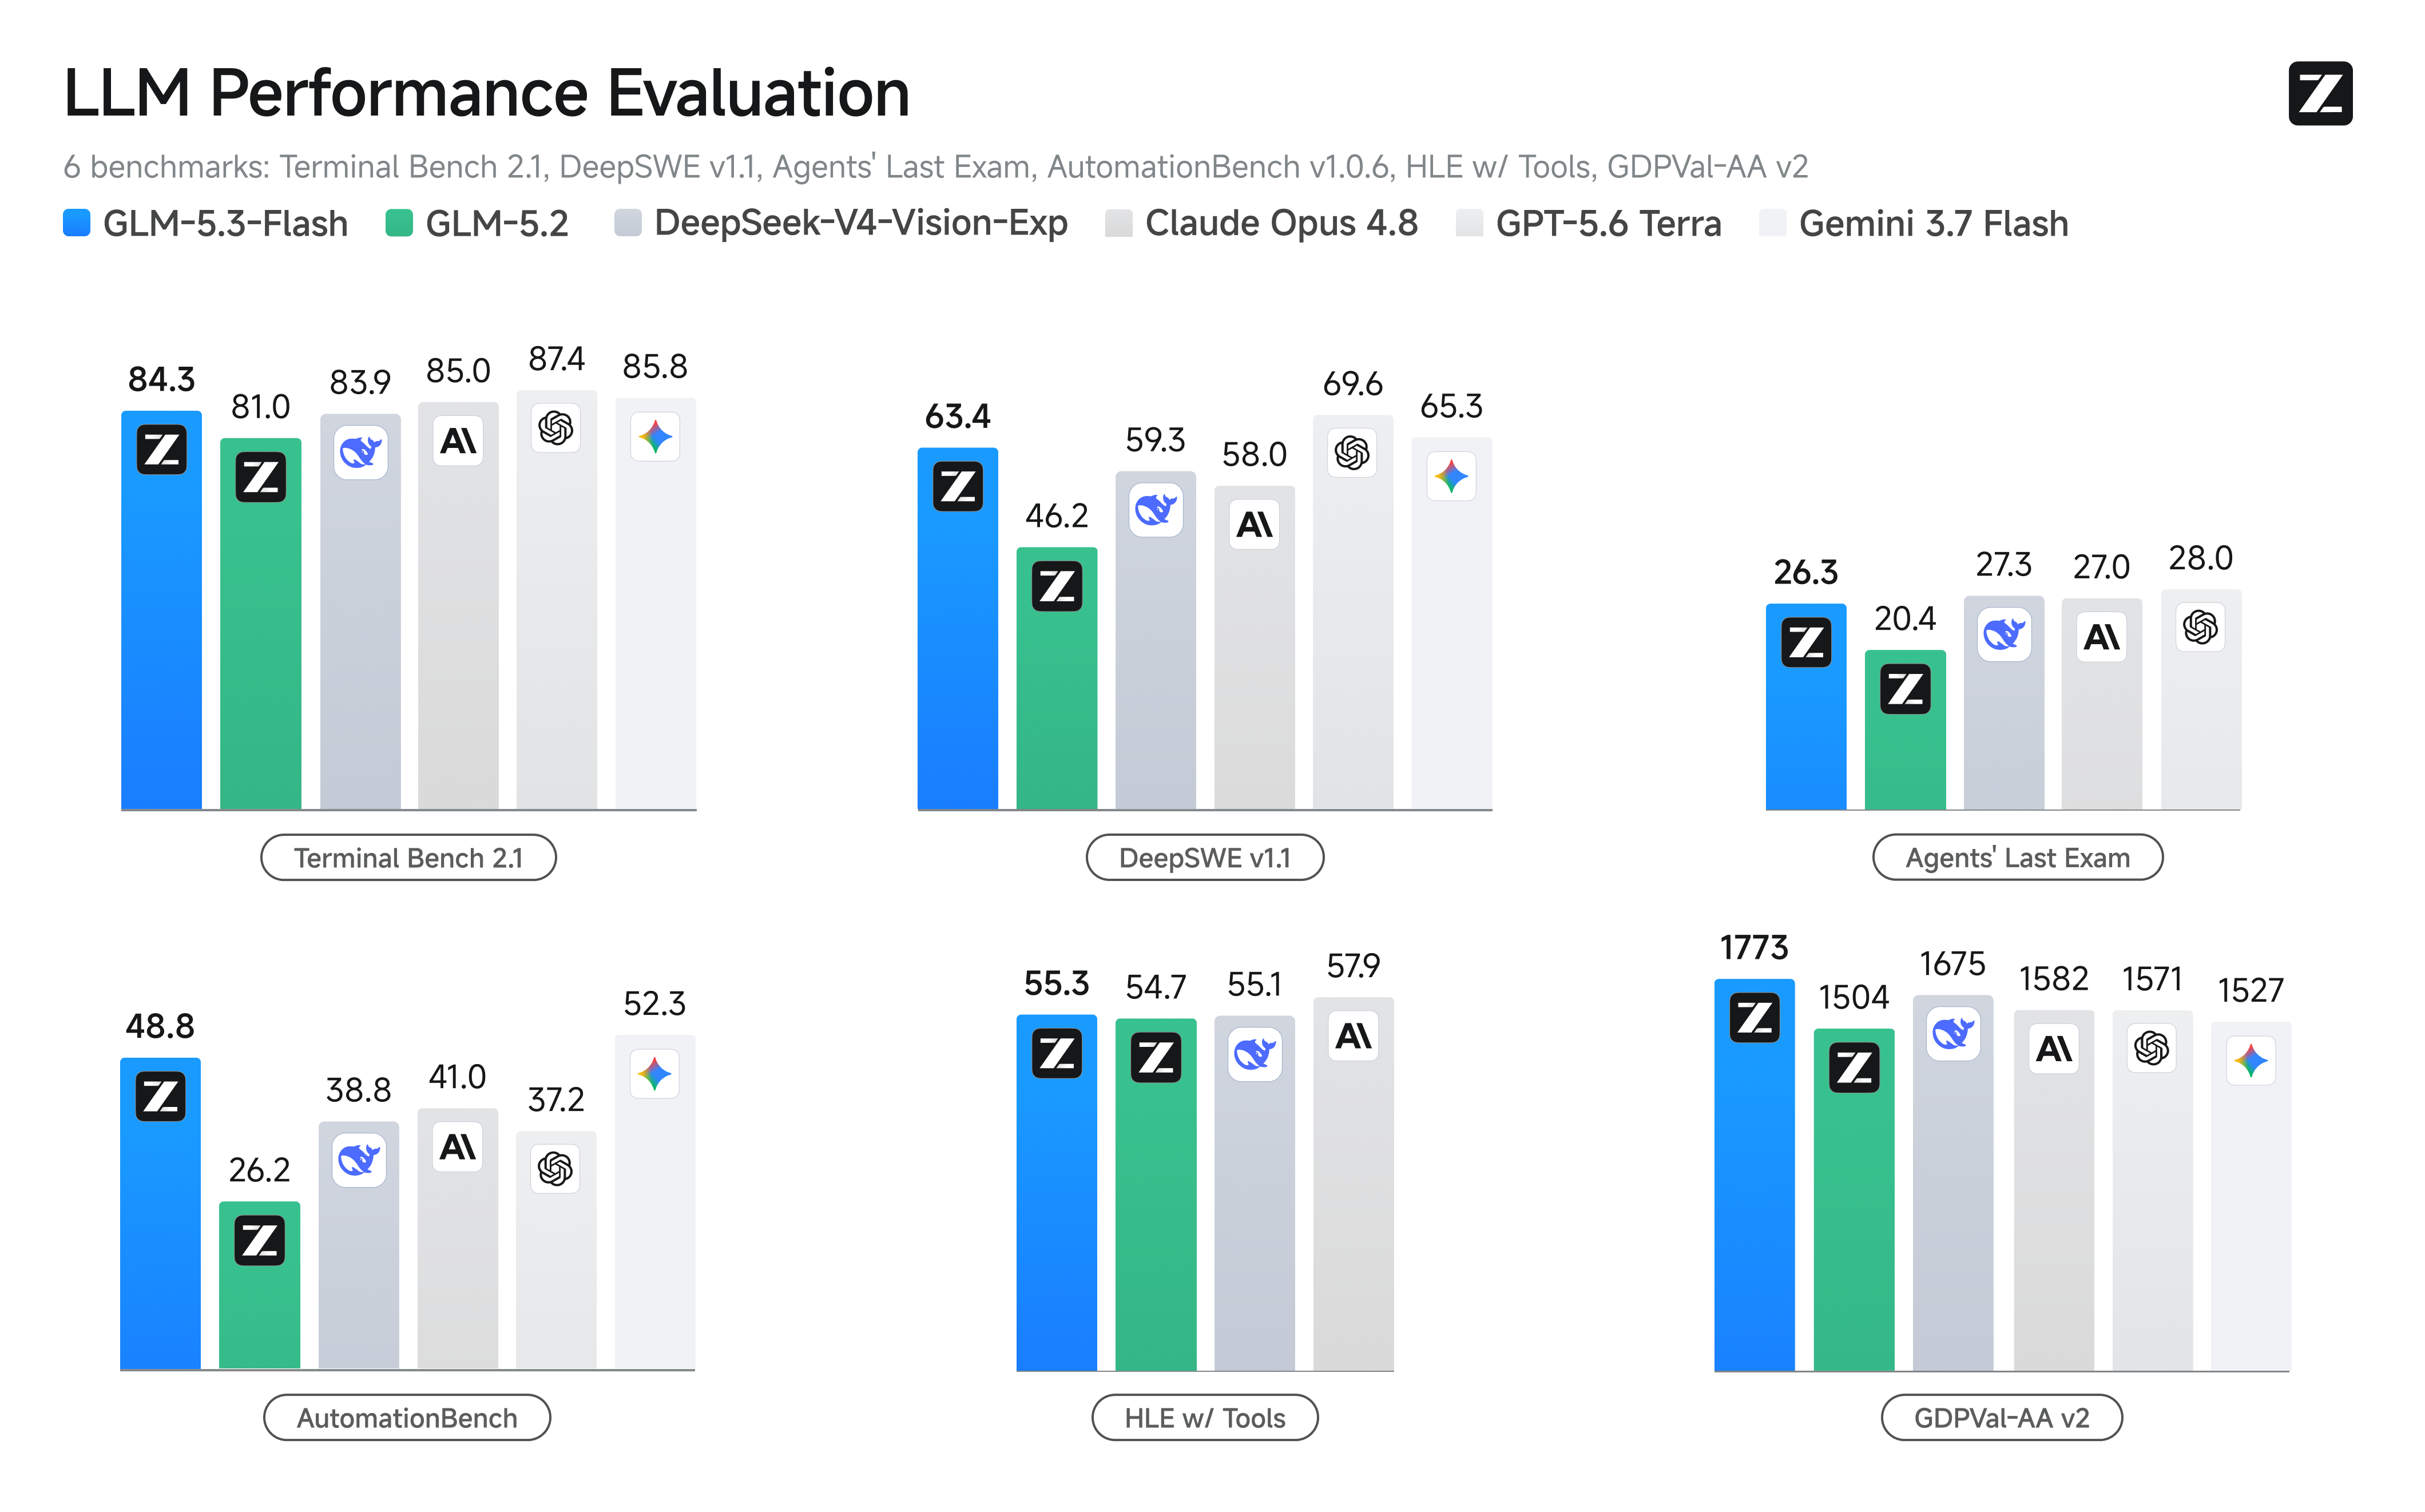
Z.ai reported DeepSWE v1.1 and AutomationBench v1.0.6 scores. Higher is better.
ModelDeepSWEv1.1AutomationBenchv1.0.6
GPT-5.6 Terra69.637.2
Gemini 3.7 Flash65.352.3
GLM-5.3-Flash63.448.8
DeepSeek-V4-Vision-Exp59.338.8
Claude Opus 4.858.041.0
GLM-5.246.226.2

DeepSWE tests software engineering; AutomationBench tests automated workflows. Z.ai’s DeepSWE run uses mini-swe-agent, 400K context and a 6-hour timeout. Release chart ↗ · Evaluation settings ↗

6 models · scroll to compare ↕

Z.AI API · USD / 1M TOKENS

A lighter token bill.

Input
$0.15
Cached input
$0.03
Output
$0.50

Current standard rates. The free Ox Alpha preview has ended.

Official pricing ↗

Benchmarks checked 27 September 2026 · Read the identity reveal ↗

ONE MODEL · TWO NAMES

Ox Alpha is GLM-5.3-Flash.

From ox-alpha to glm-5.3-flash

Z.ai previewed GLM-5.3-Flash under the codename Ox Alpha, using stealth/ox-alpha on OpenRouter. The released model is also written as GLM 5.3 Flash. Read Z.ai’s model overview ↗

Use the released model

The Z.ai API uses glm-5.3-flash; OpenRouter uses z-ai/glm-5.3-flash. For Z.ai, create an account and API key, then add a token balance as needed. The weights are available under the MIT license.