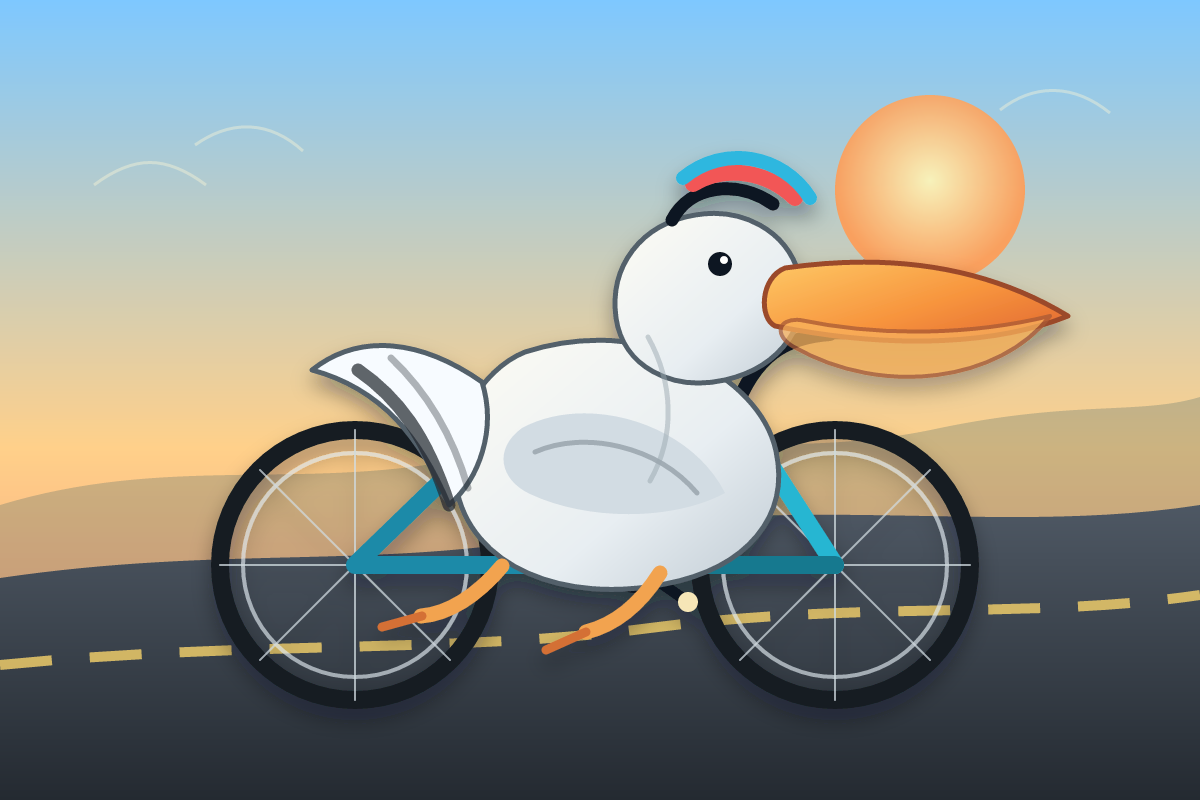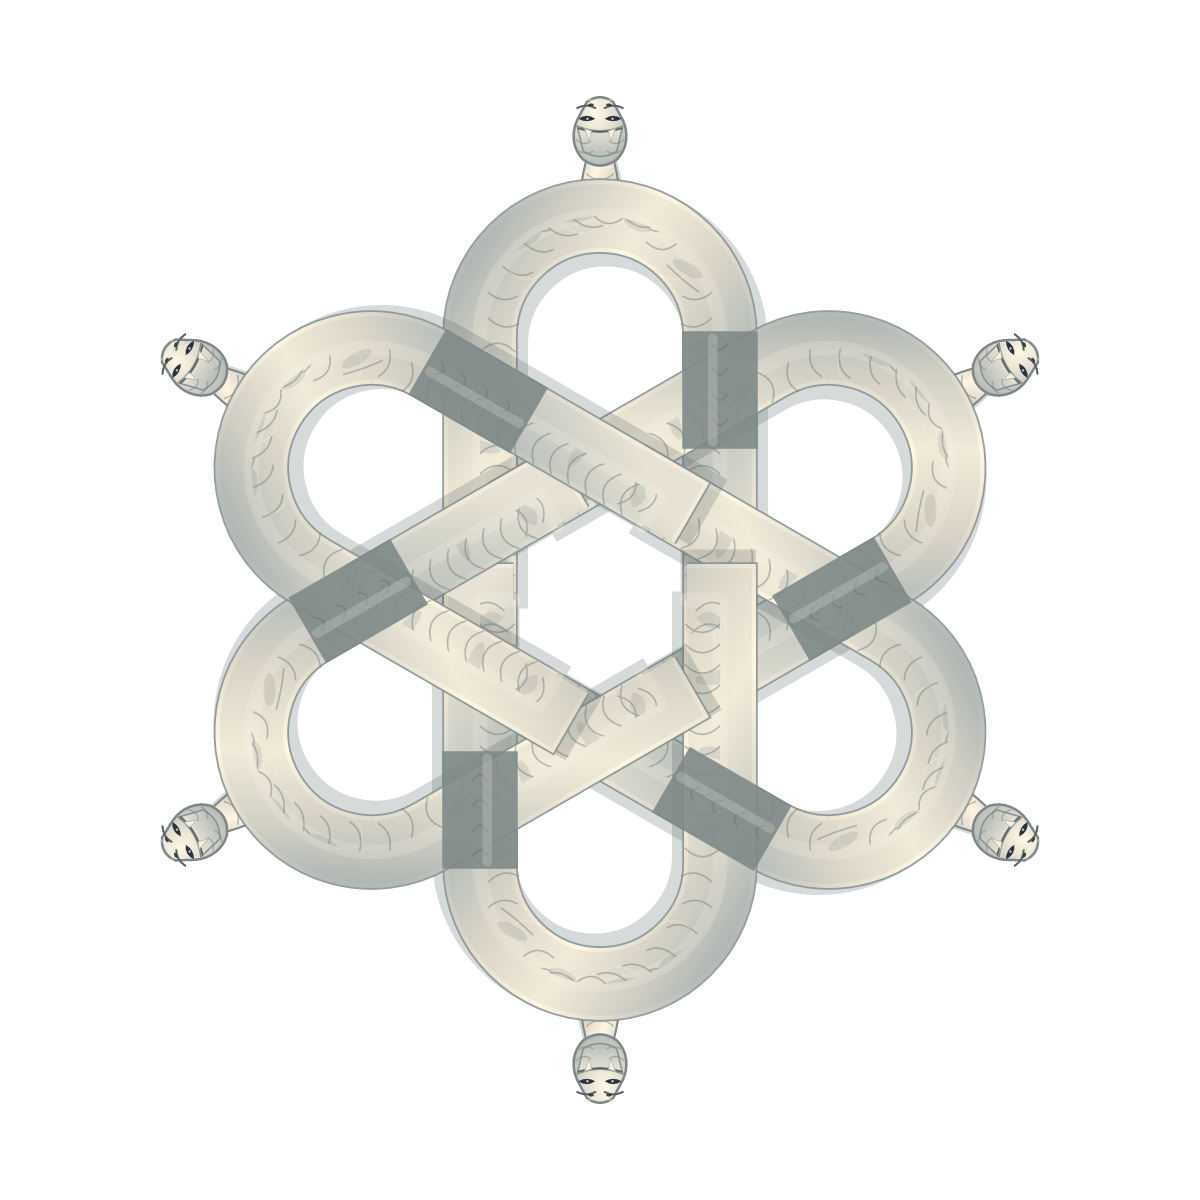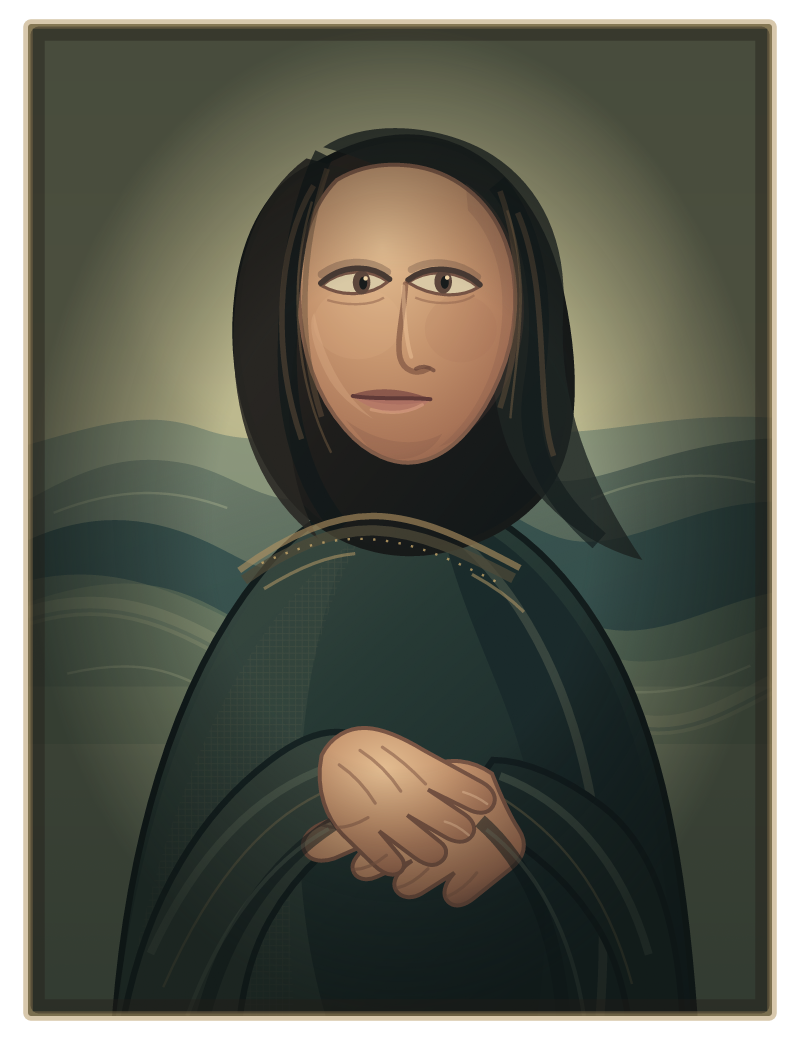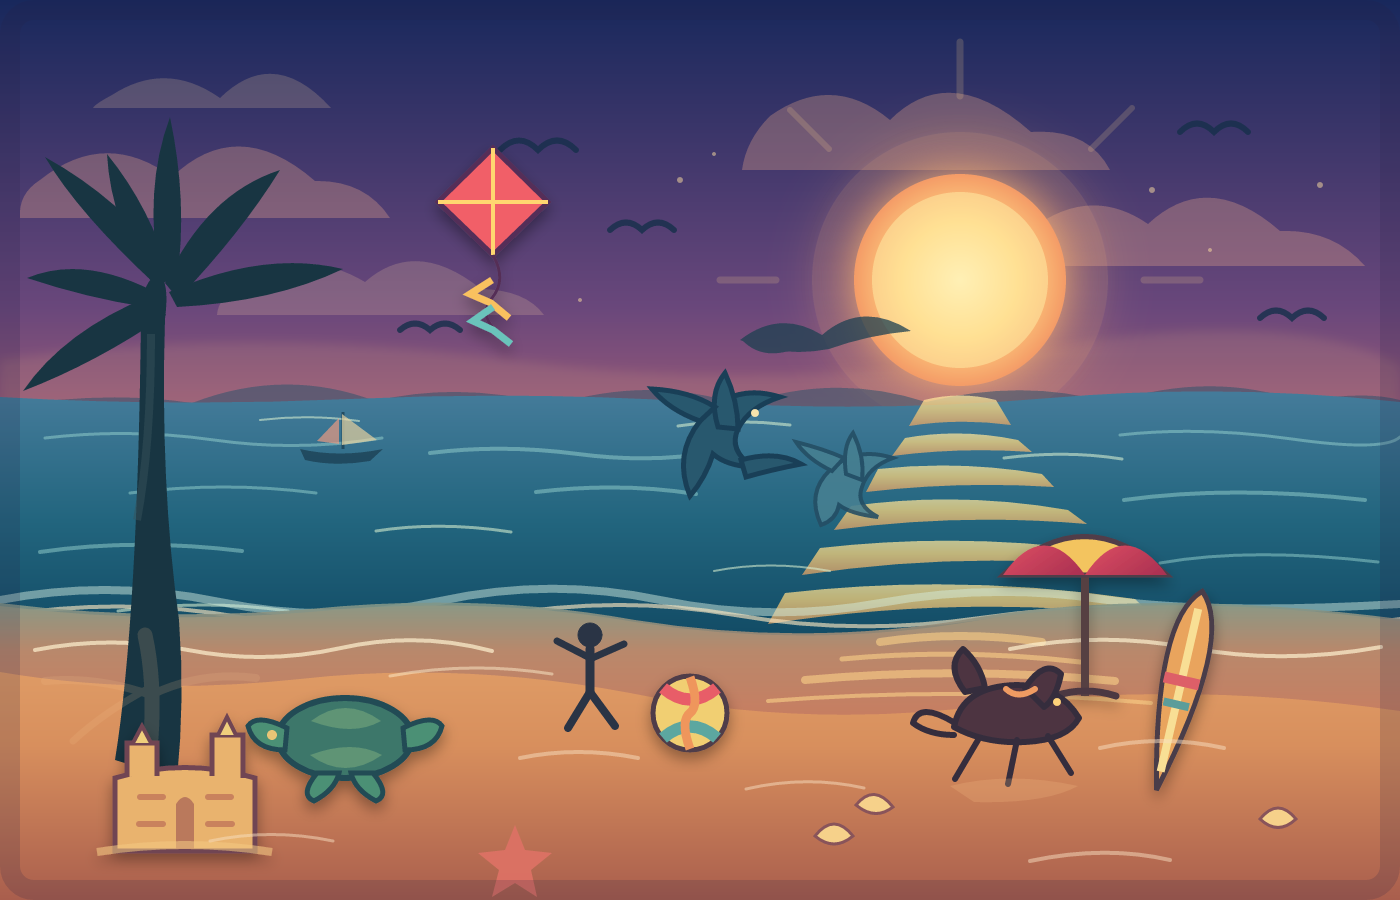
stealthmodels.

MODEL FIELD GUIDE

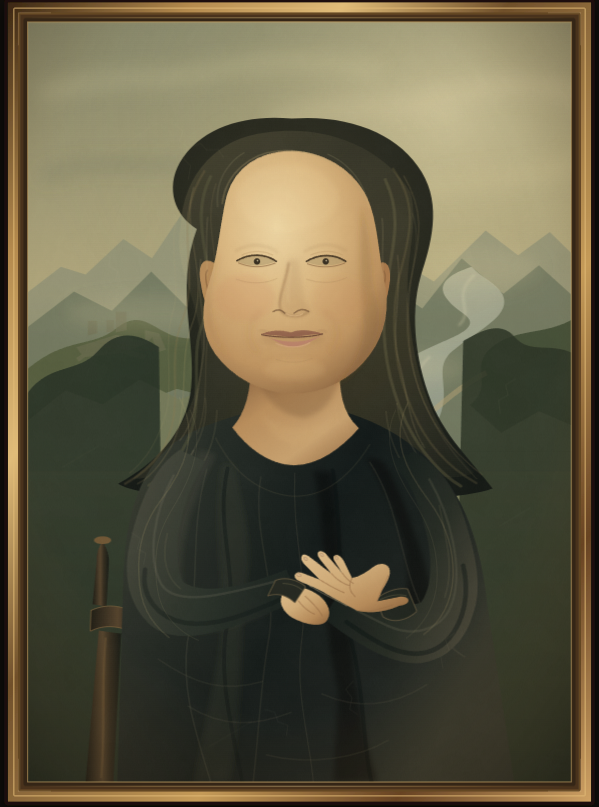
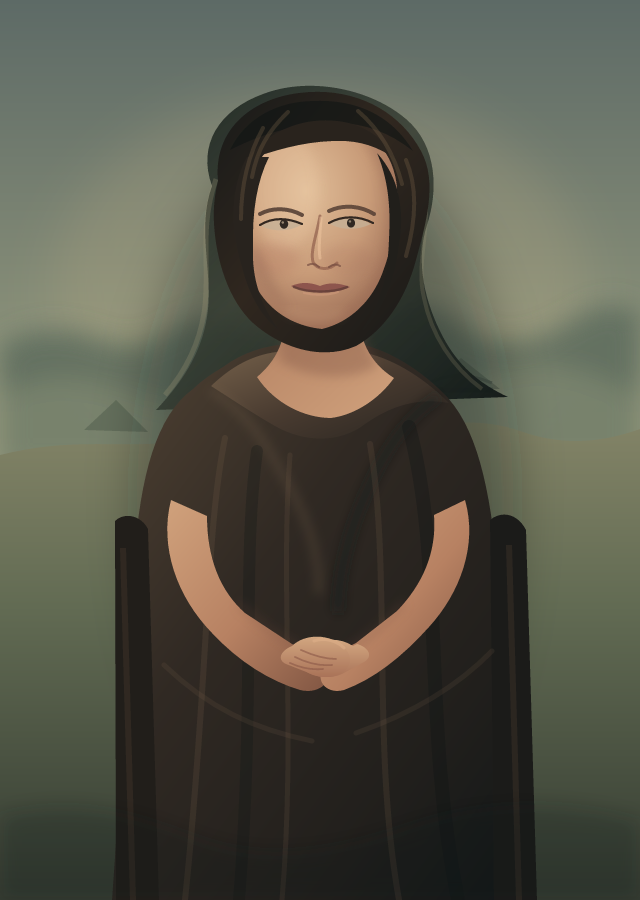
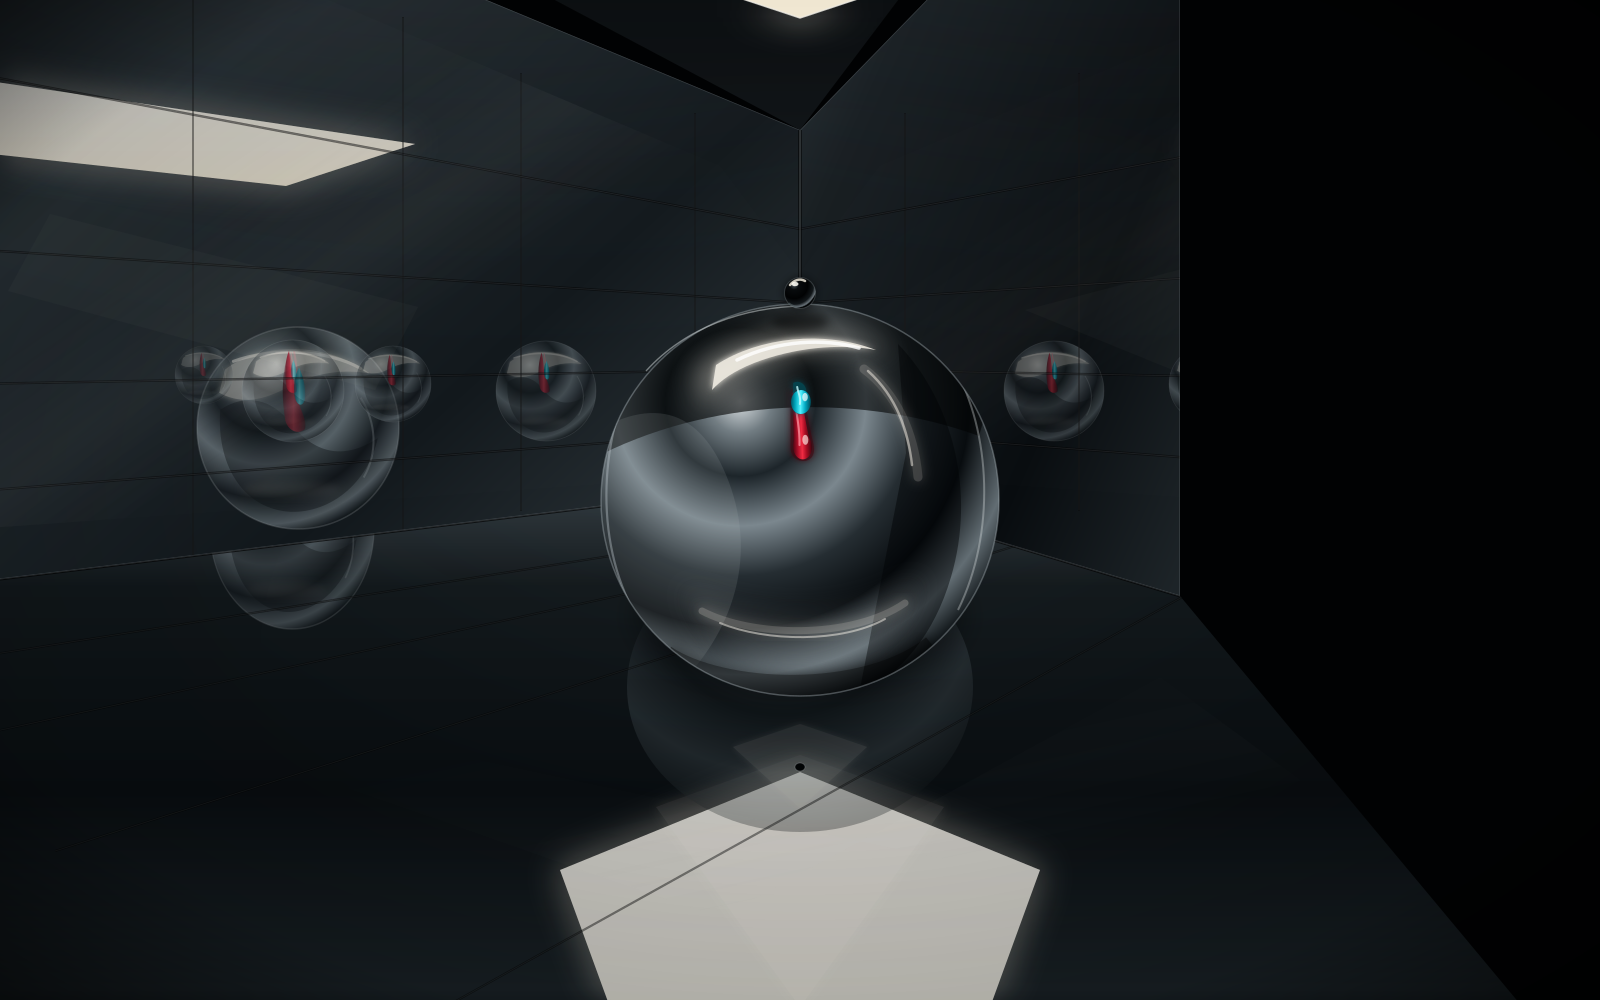
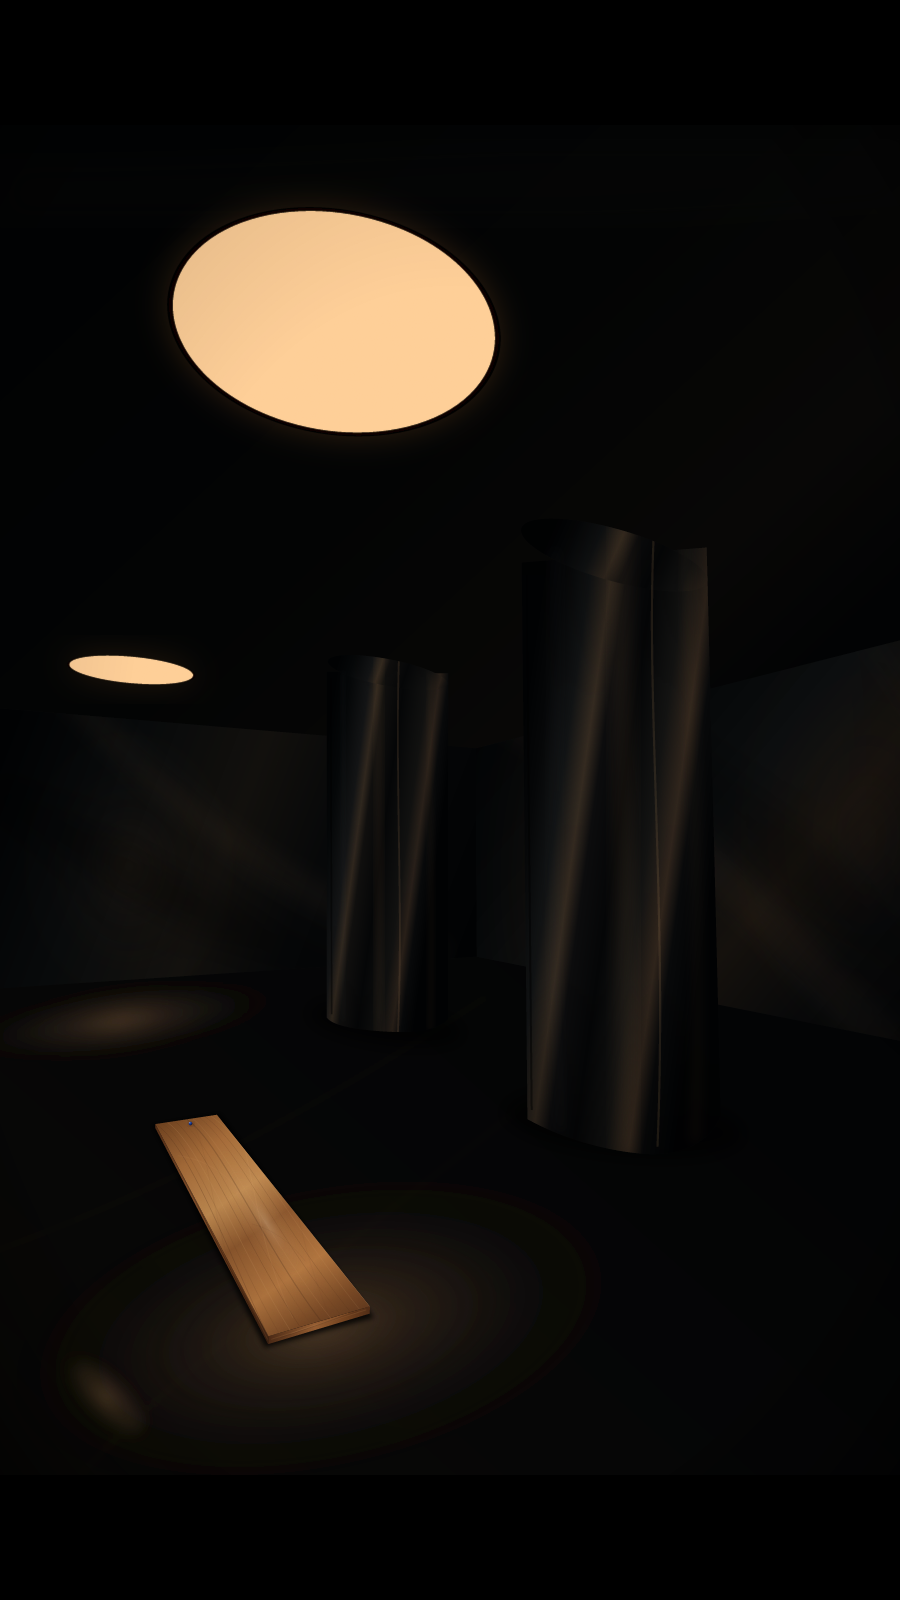
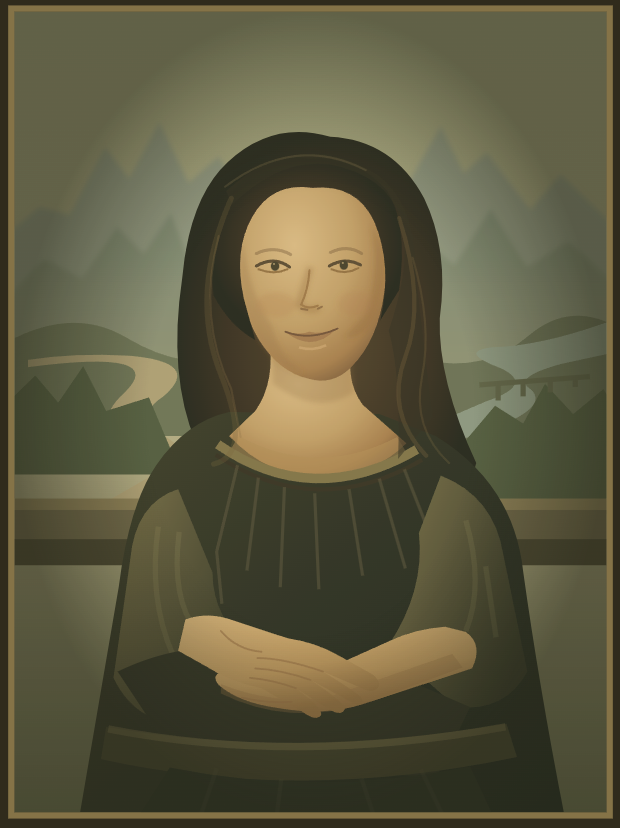
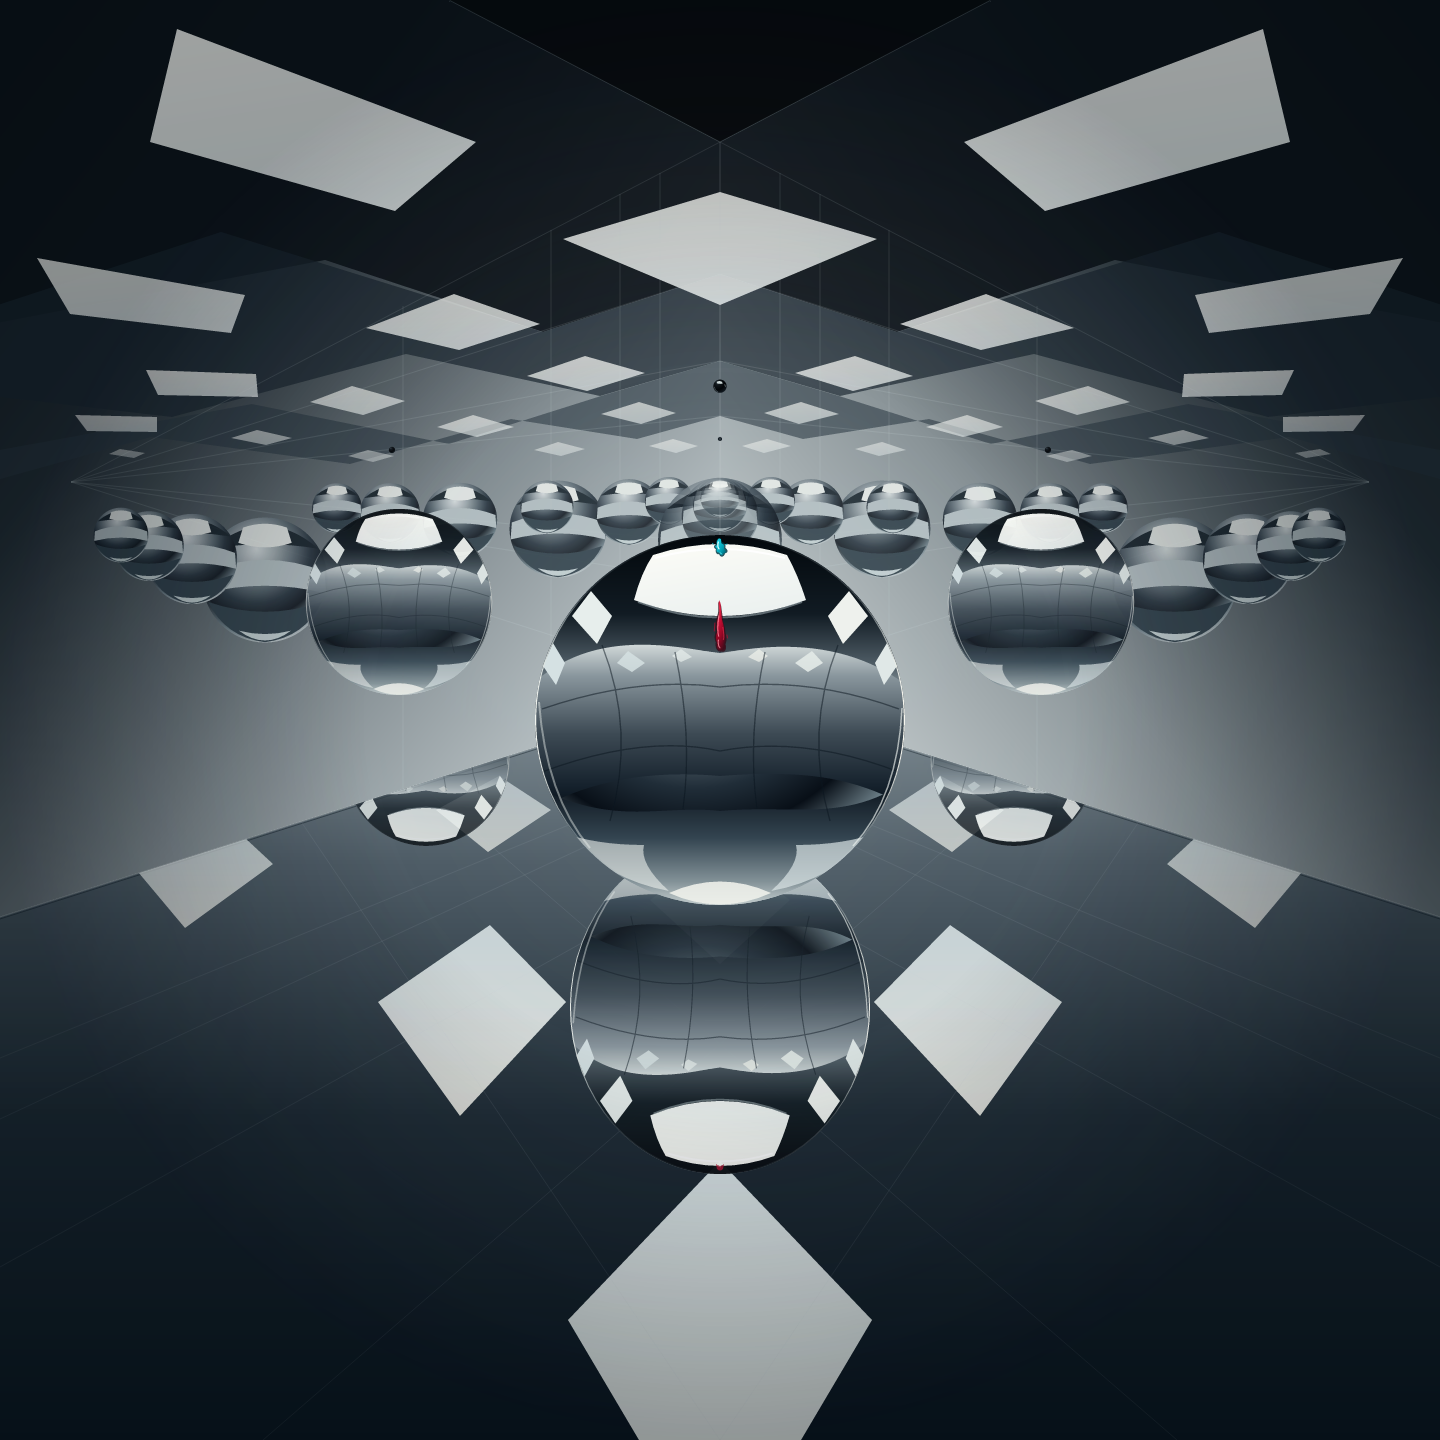
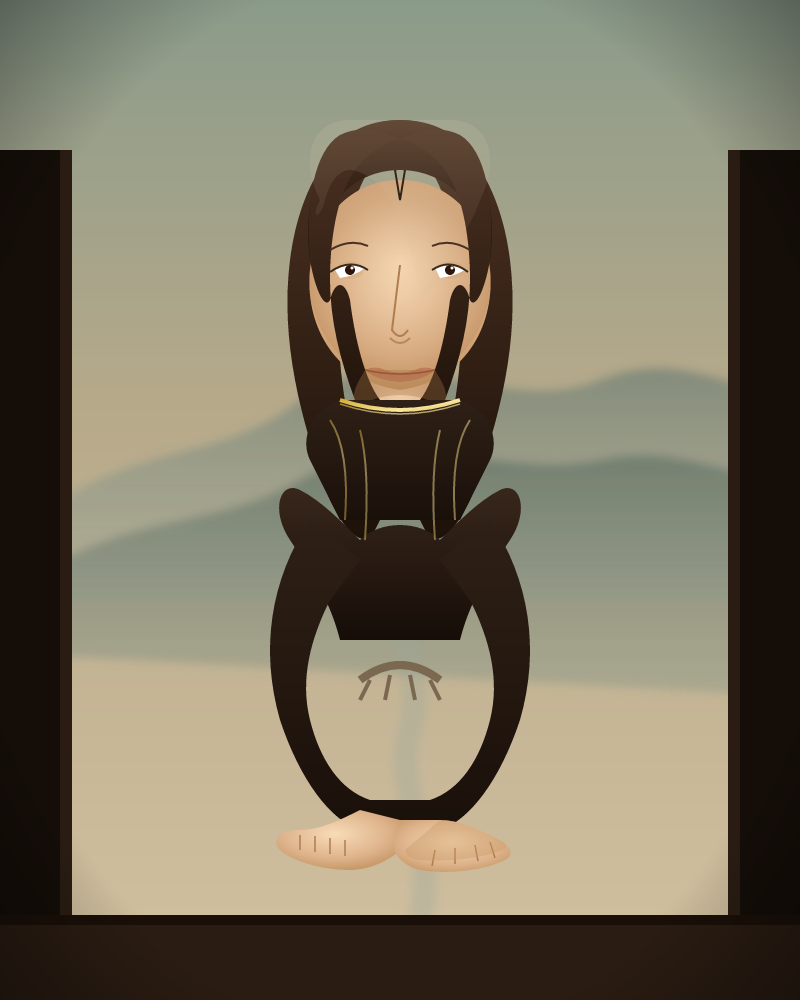
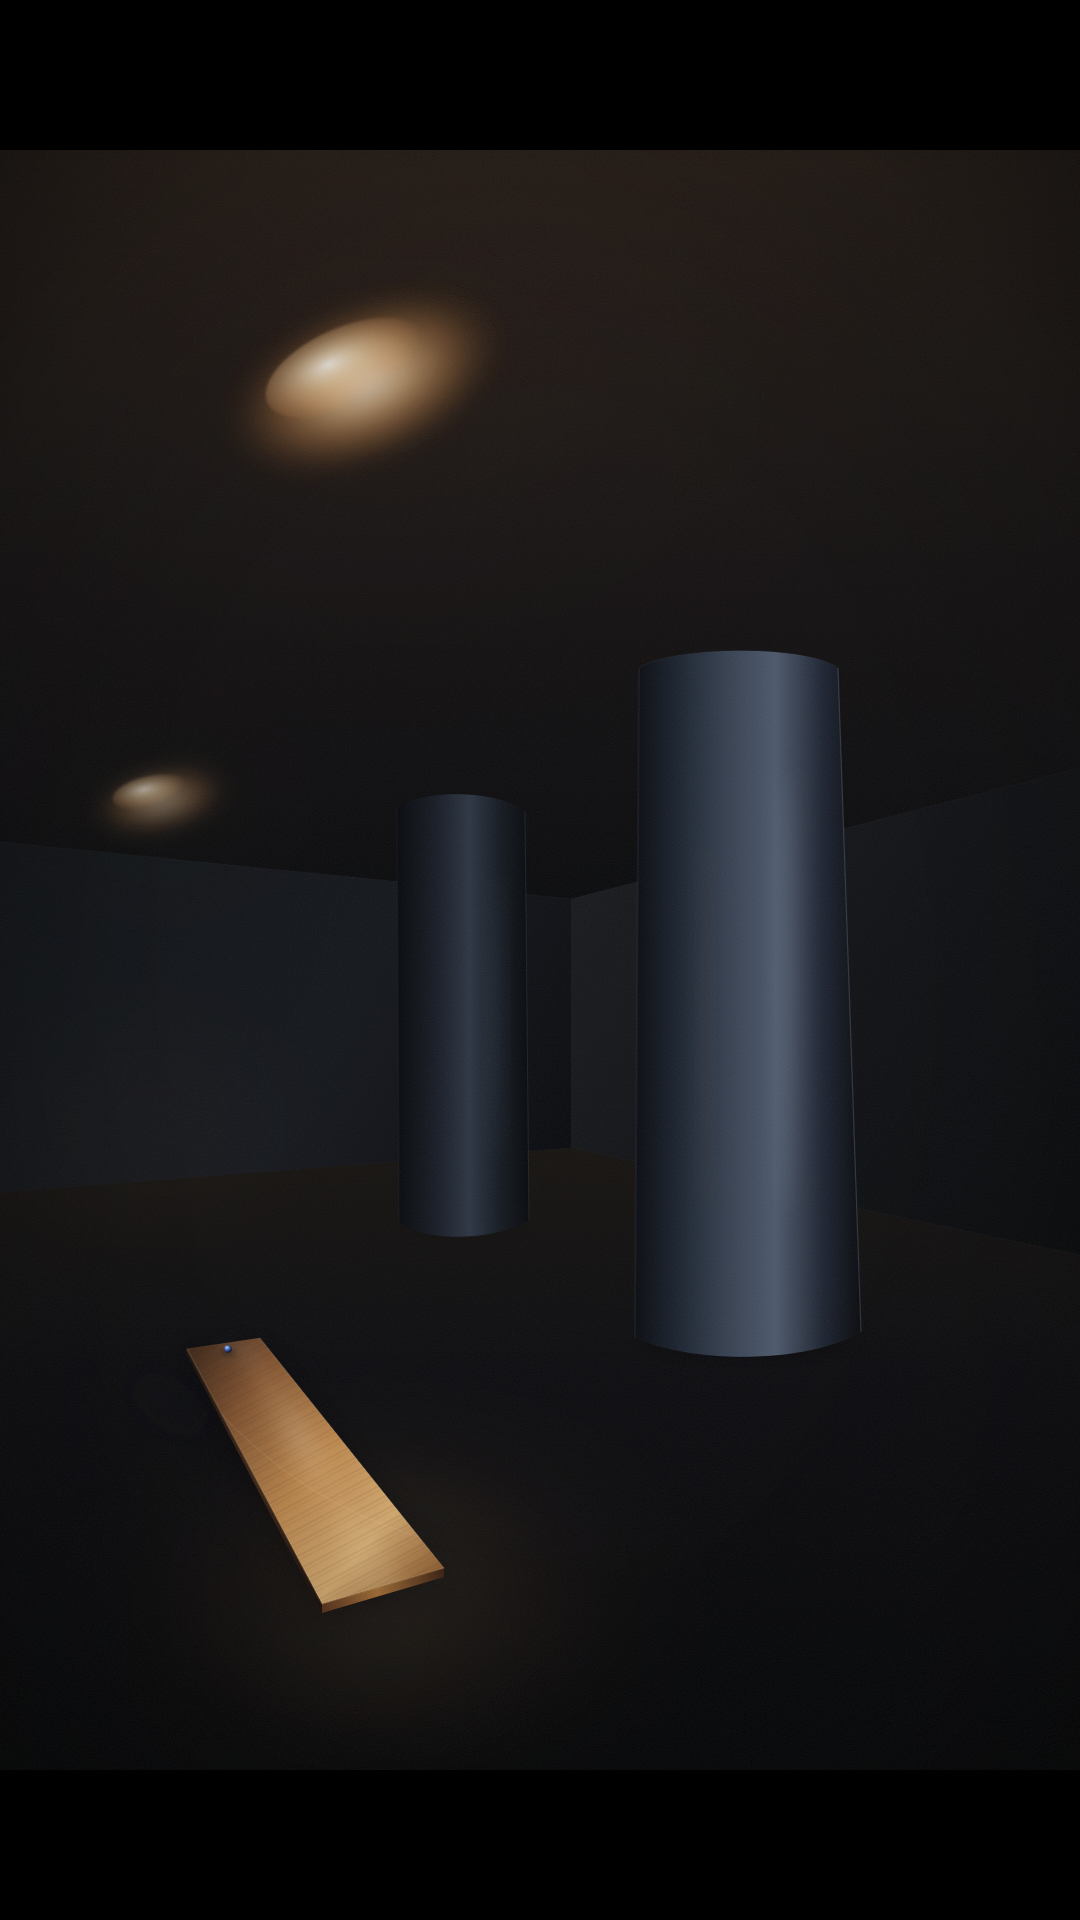
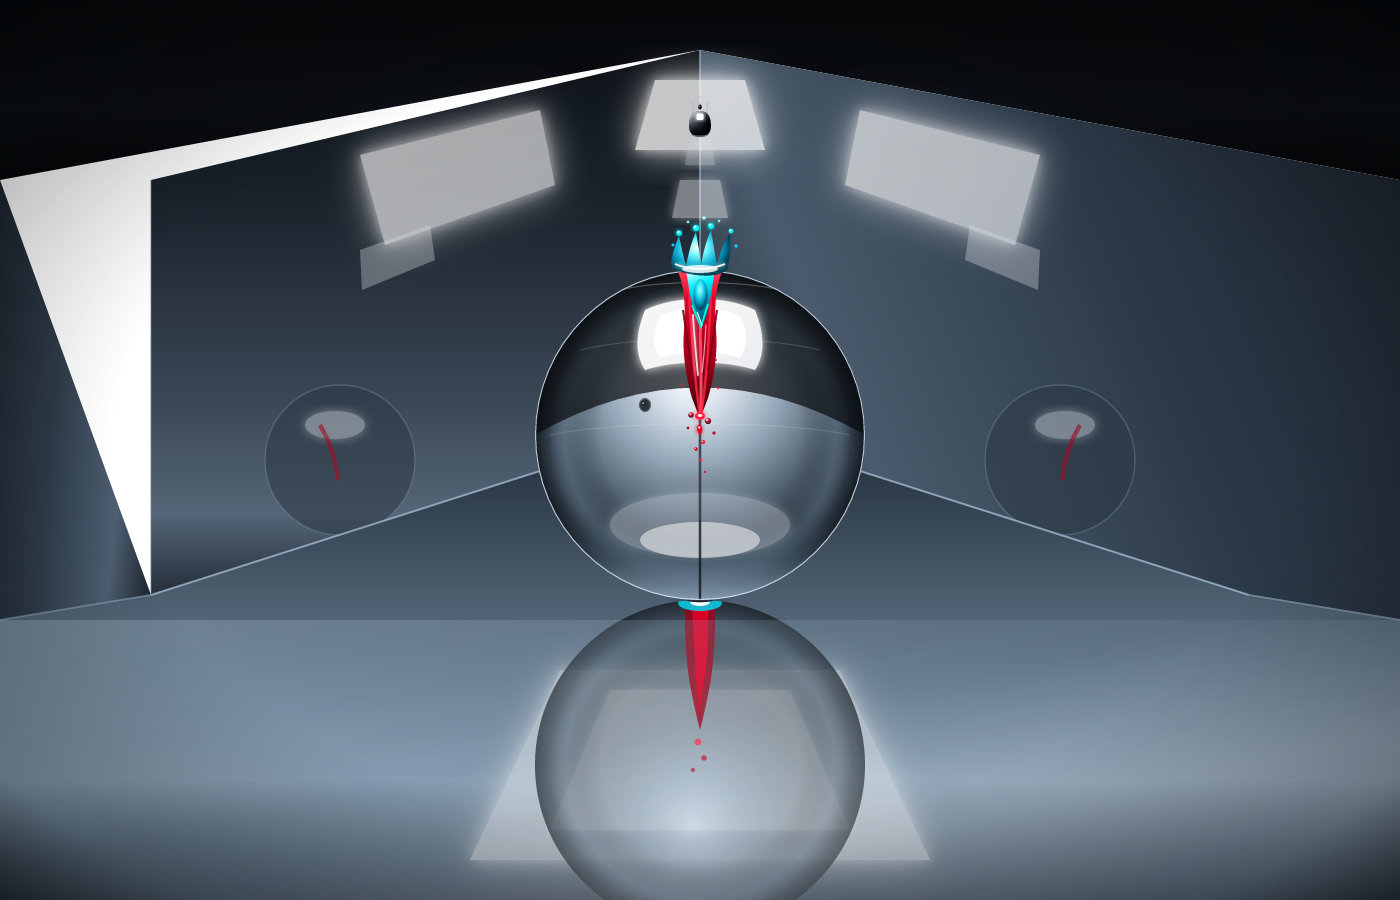
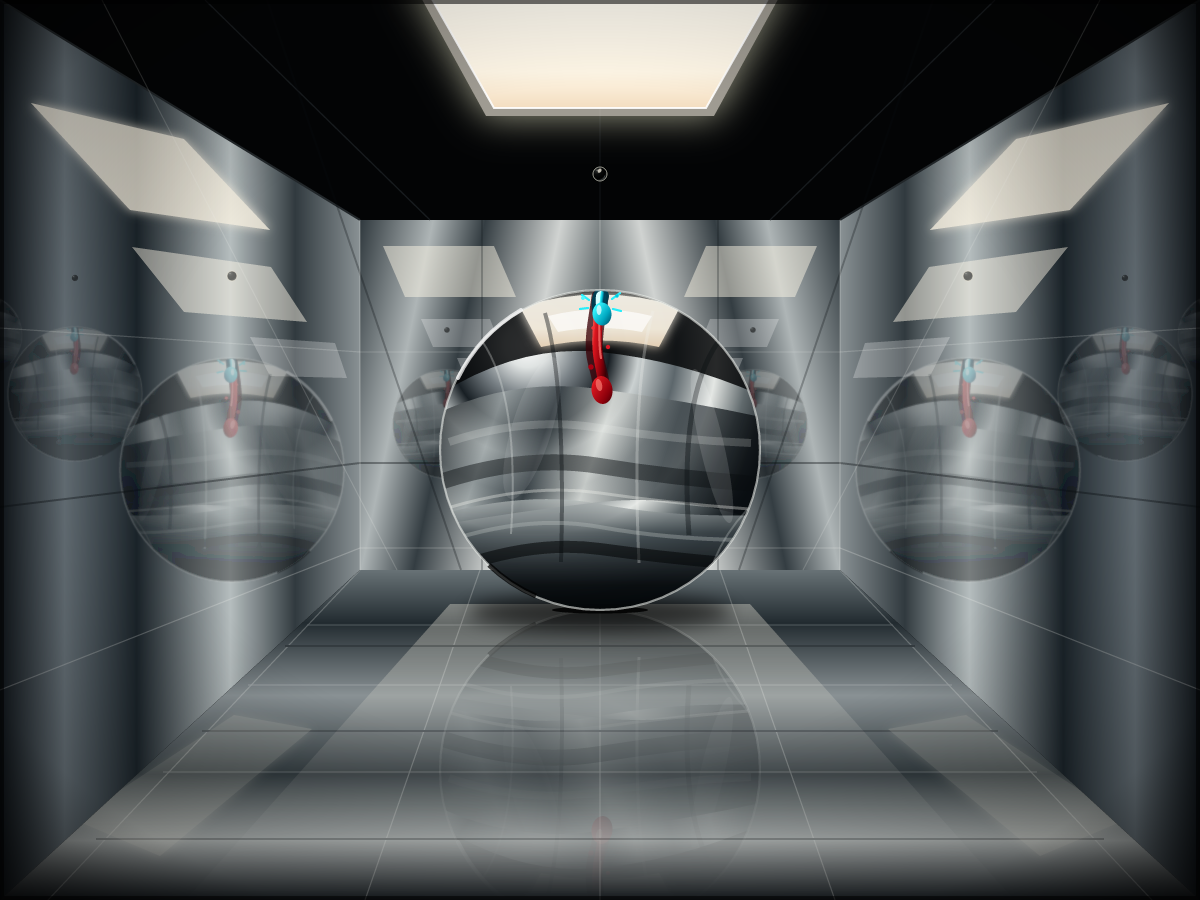
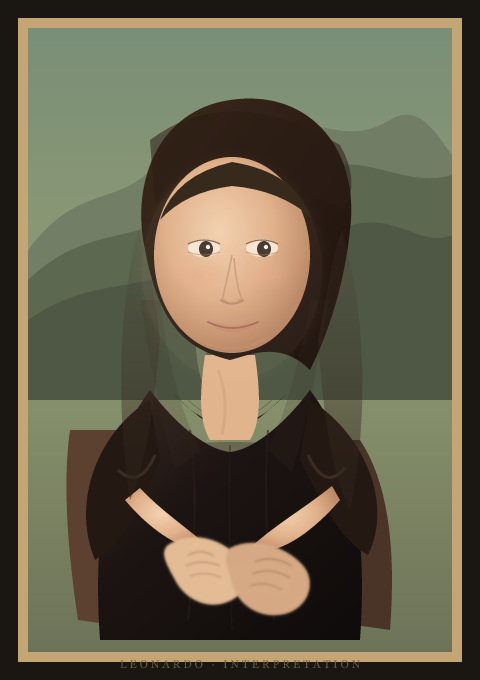
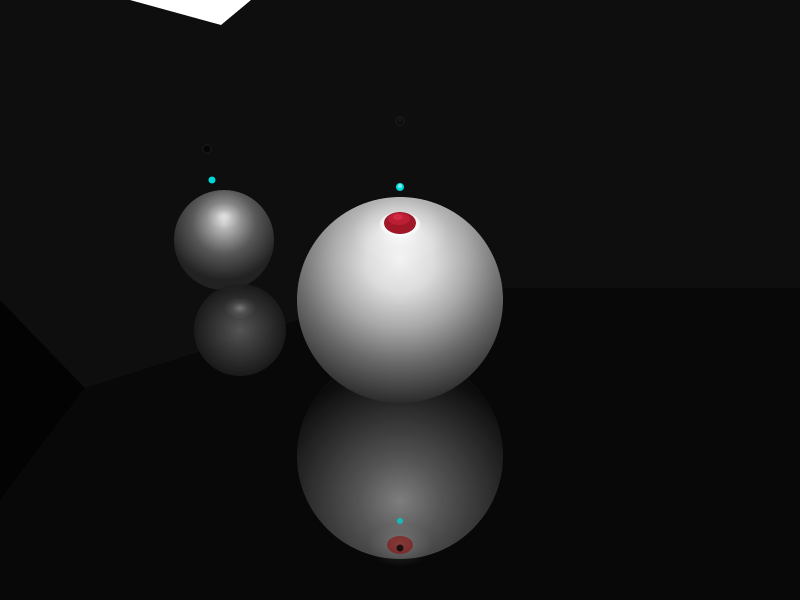
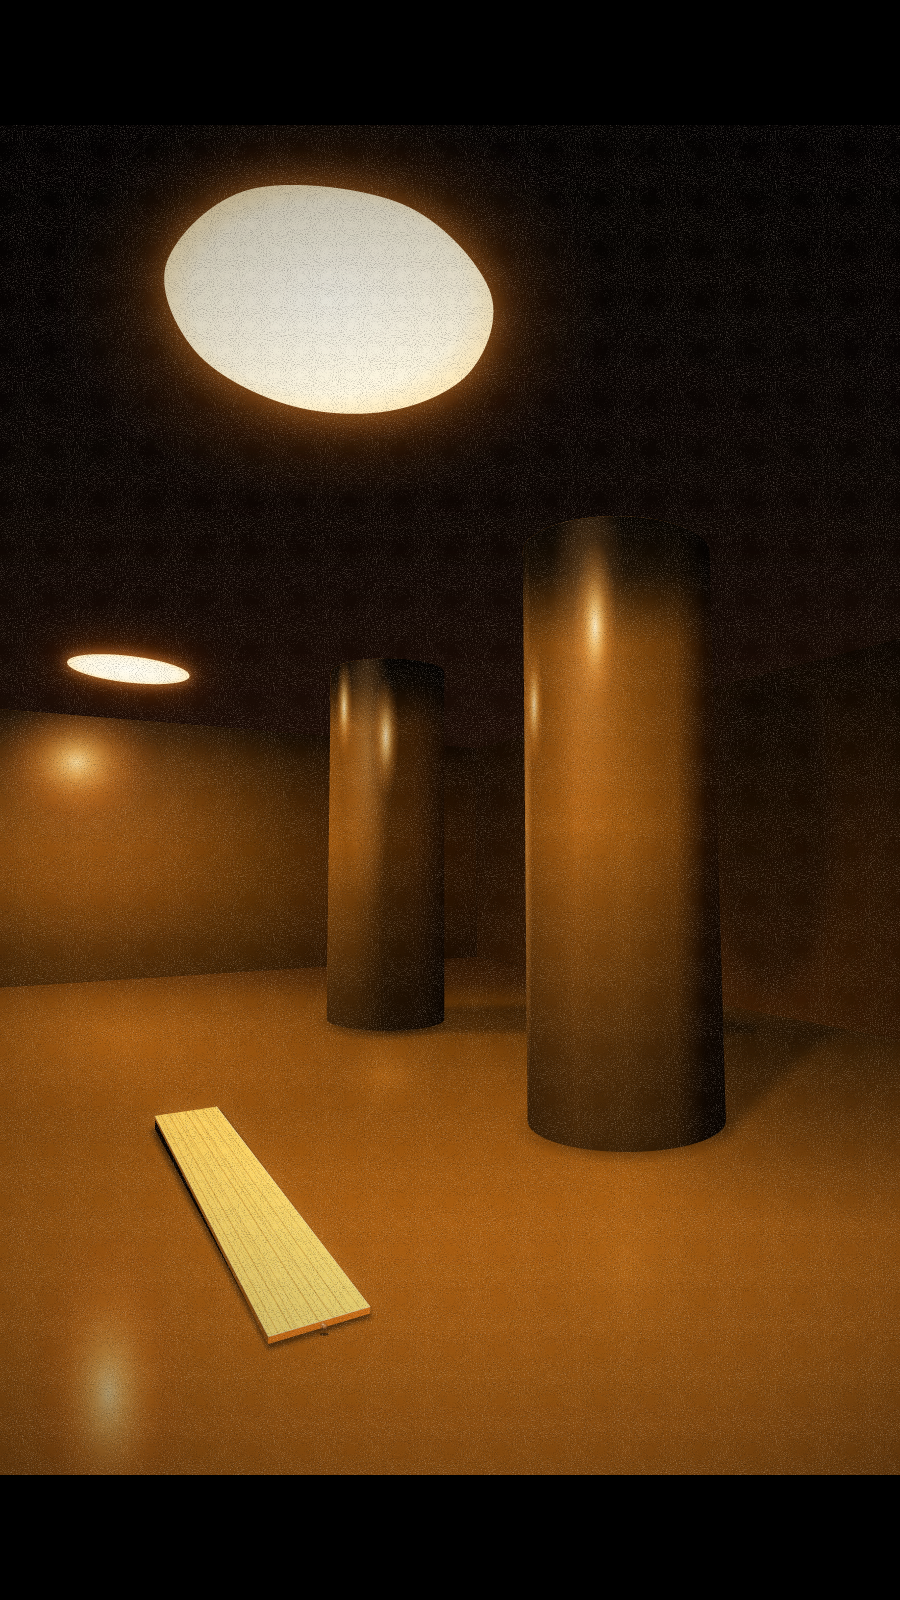
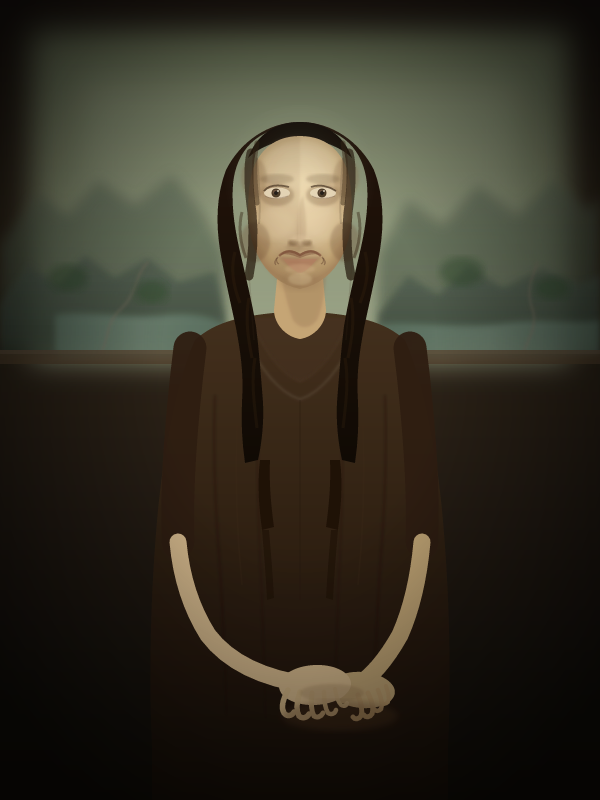
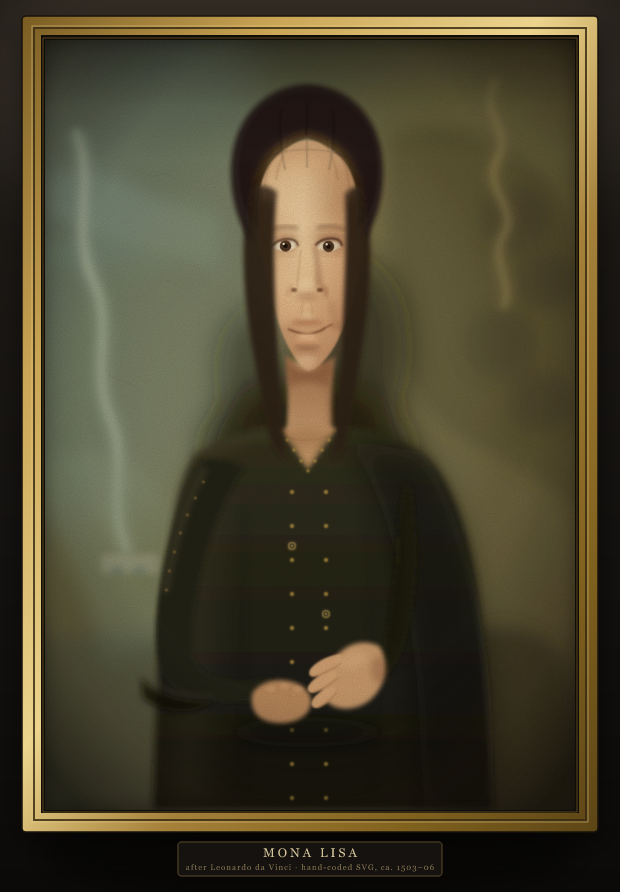
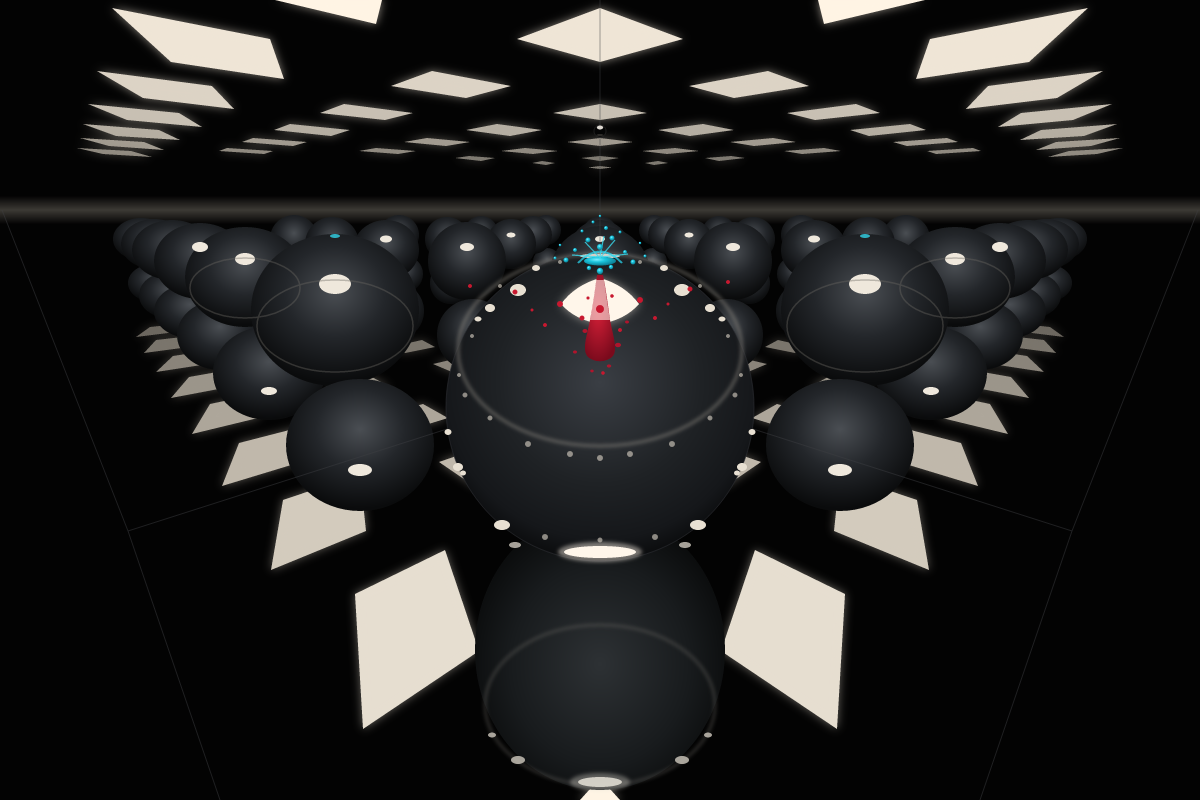
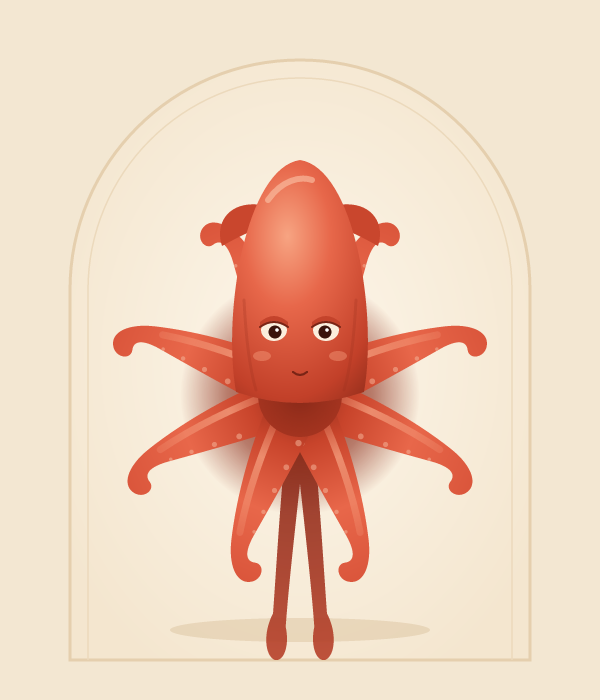
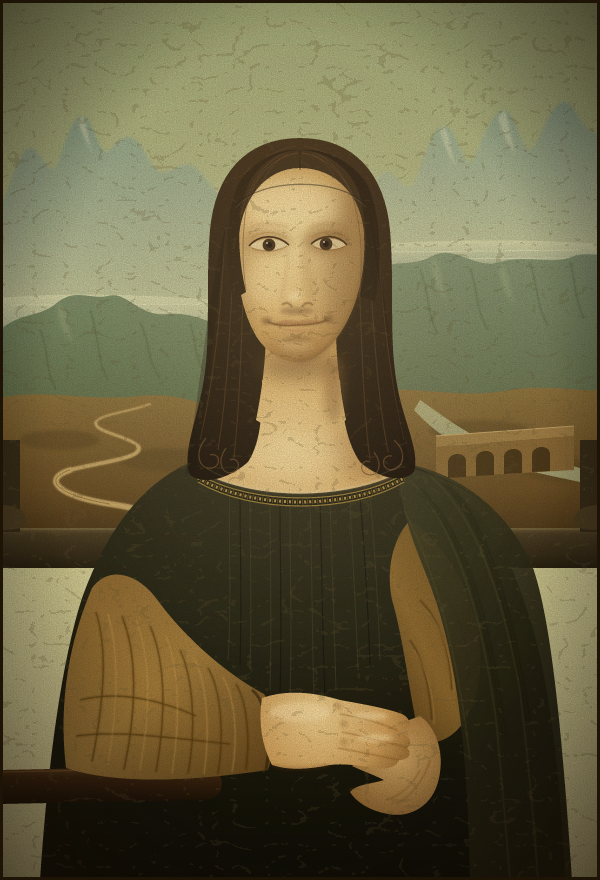
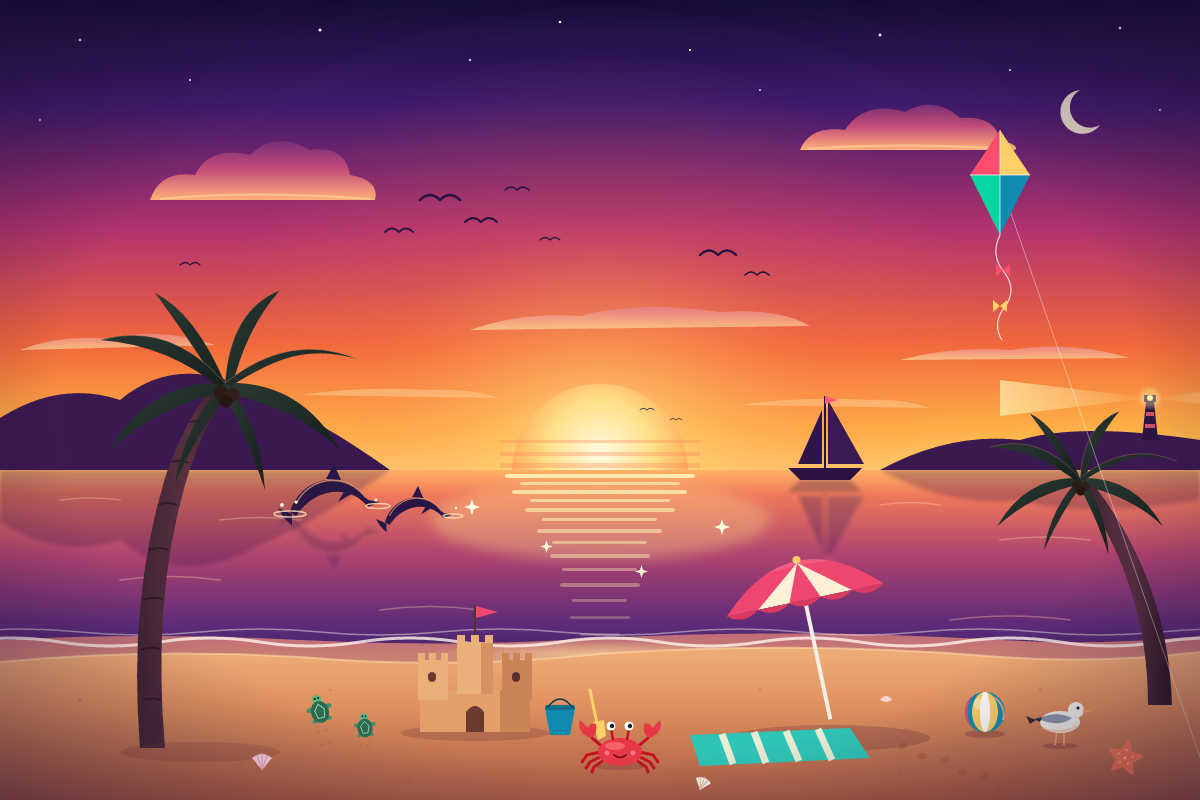
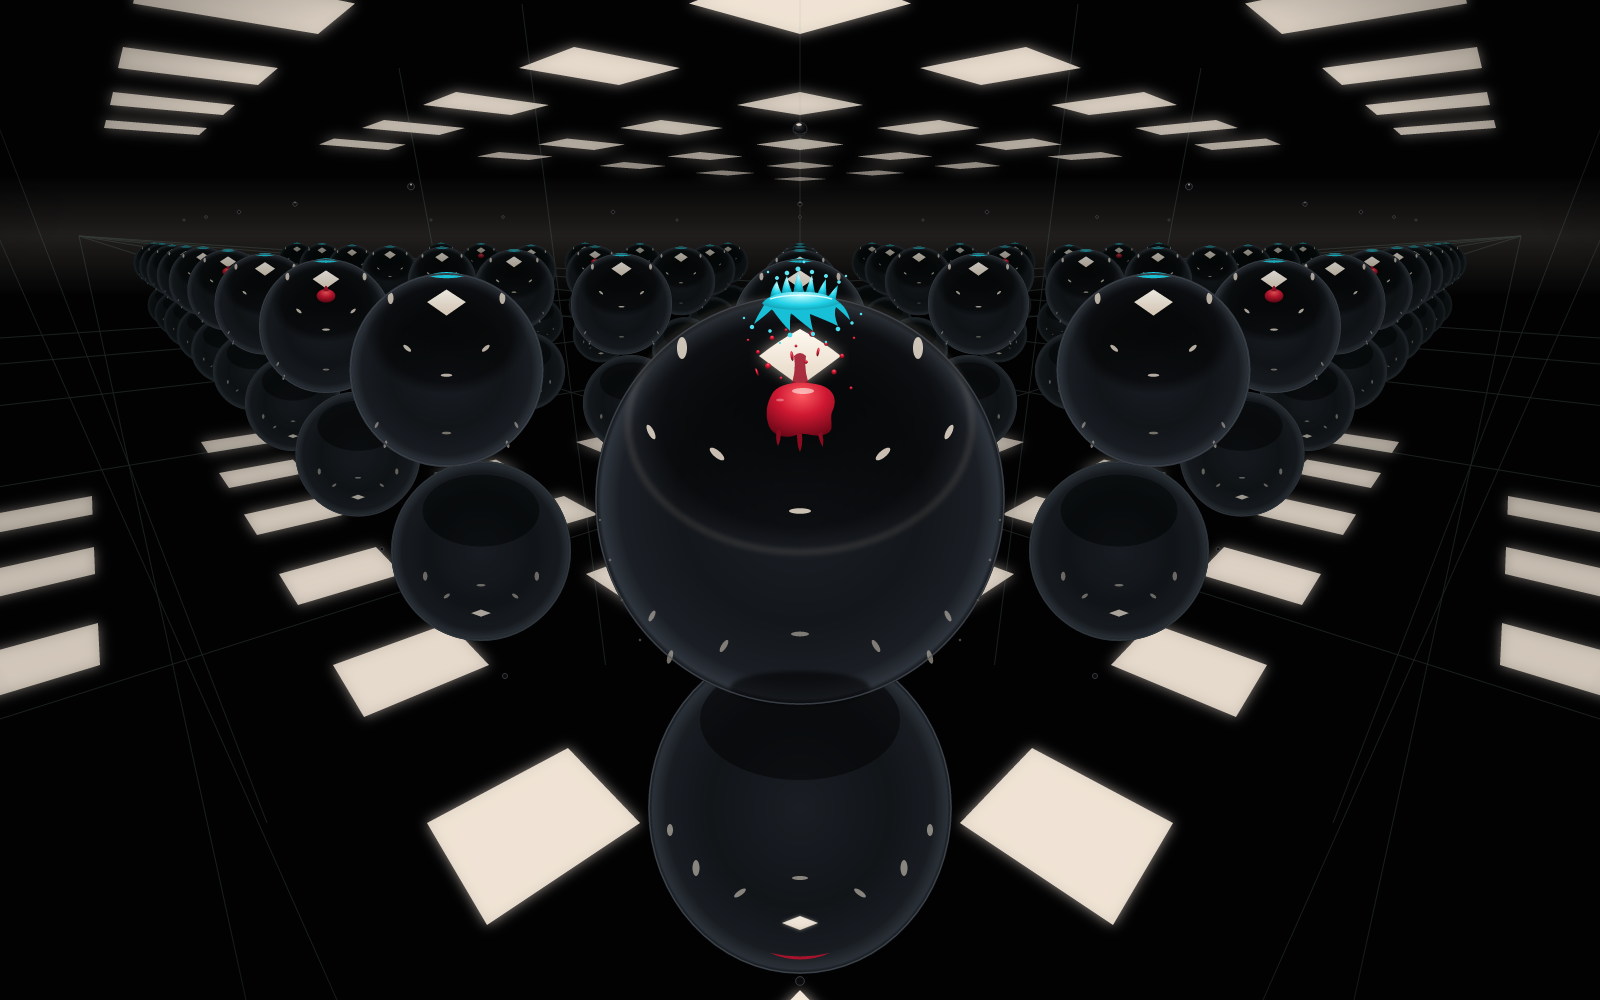
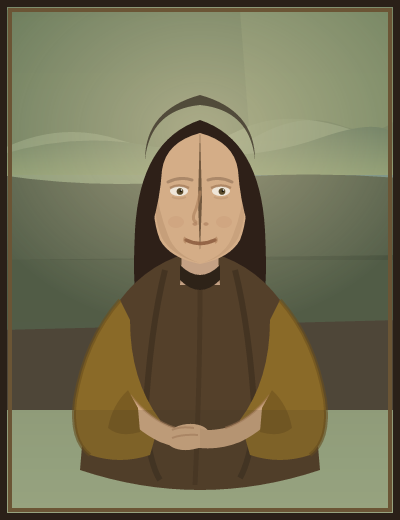
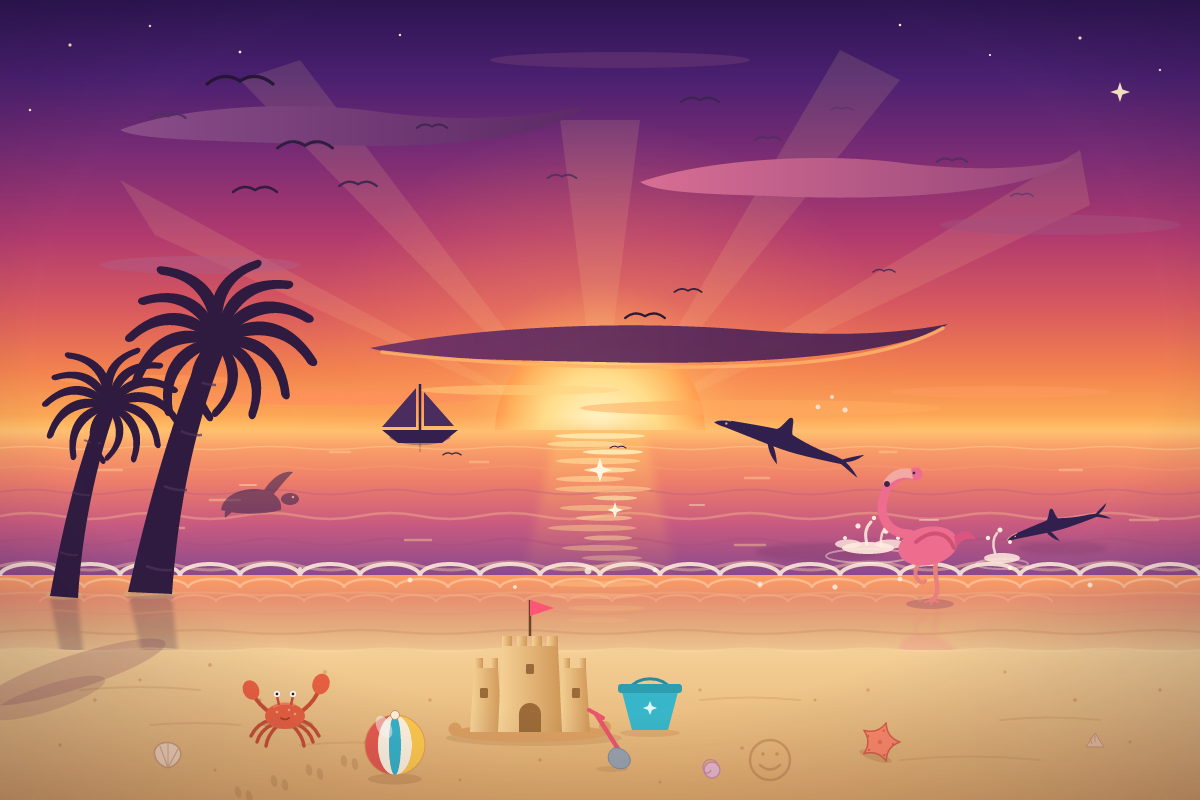
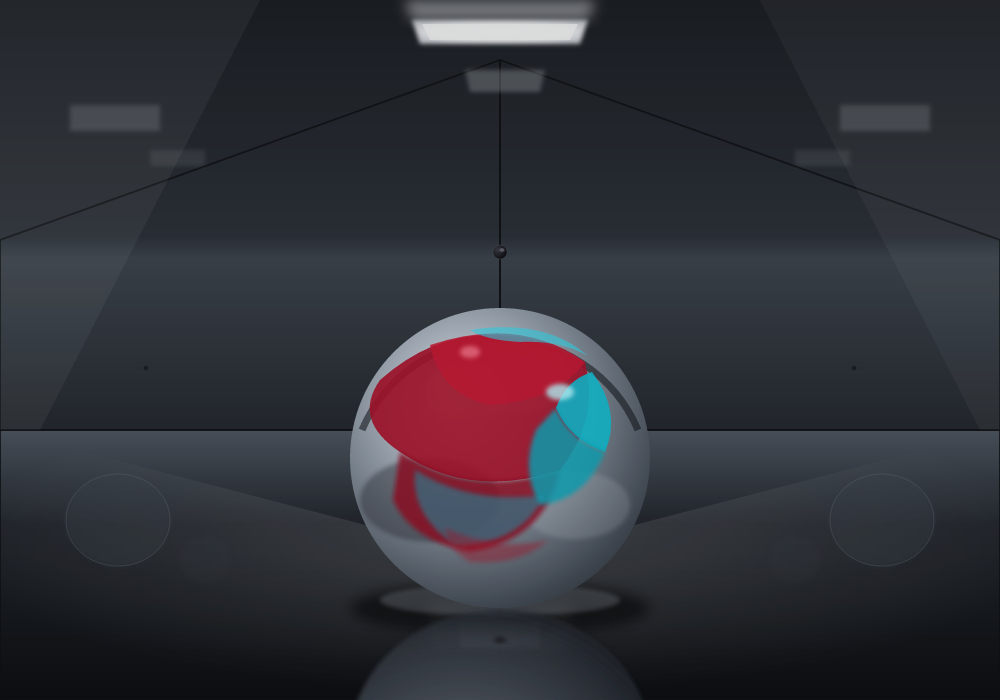
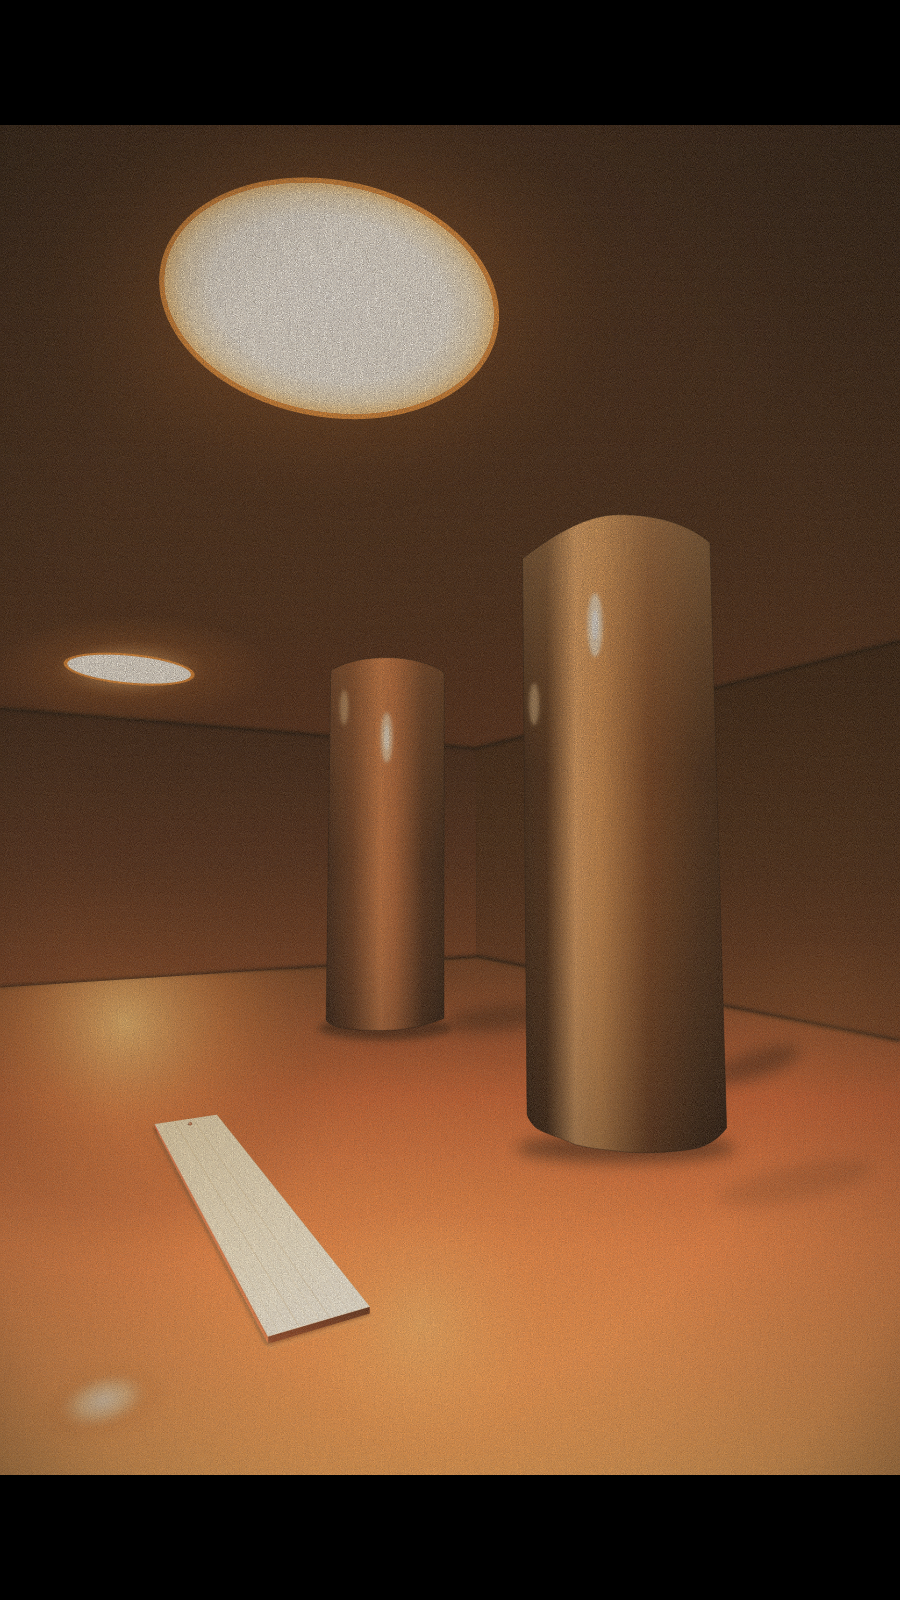
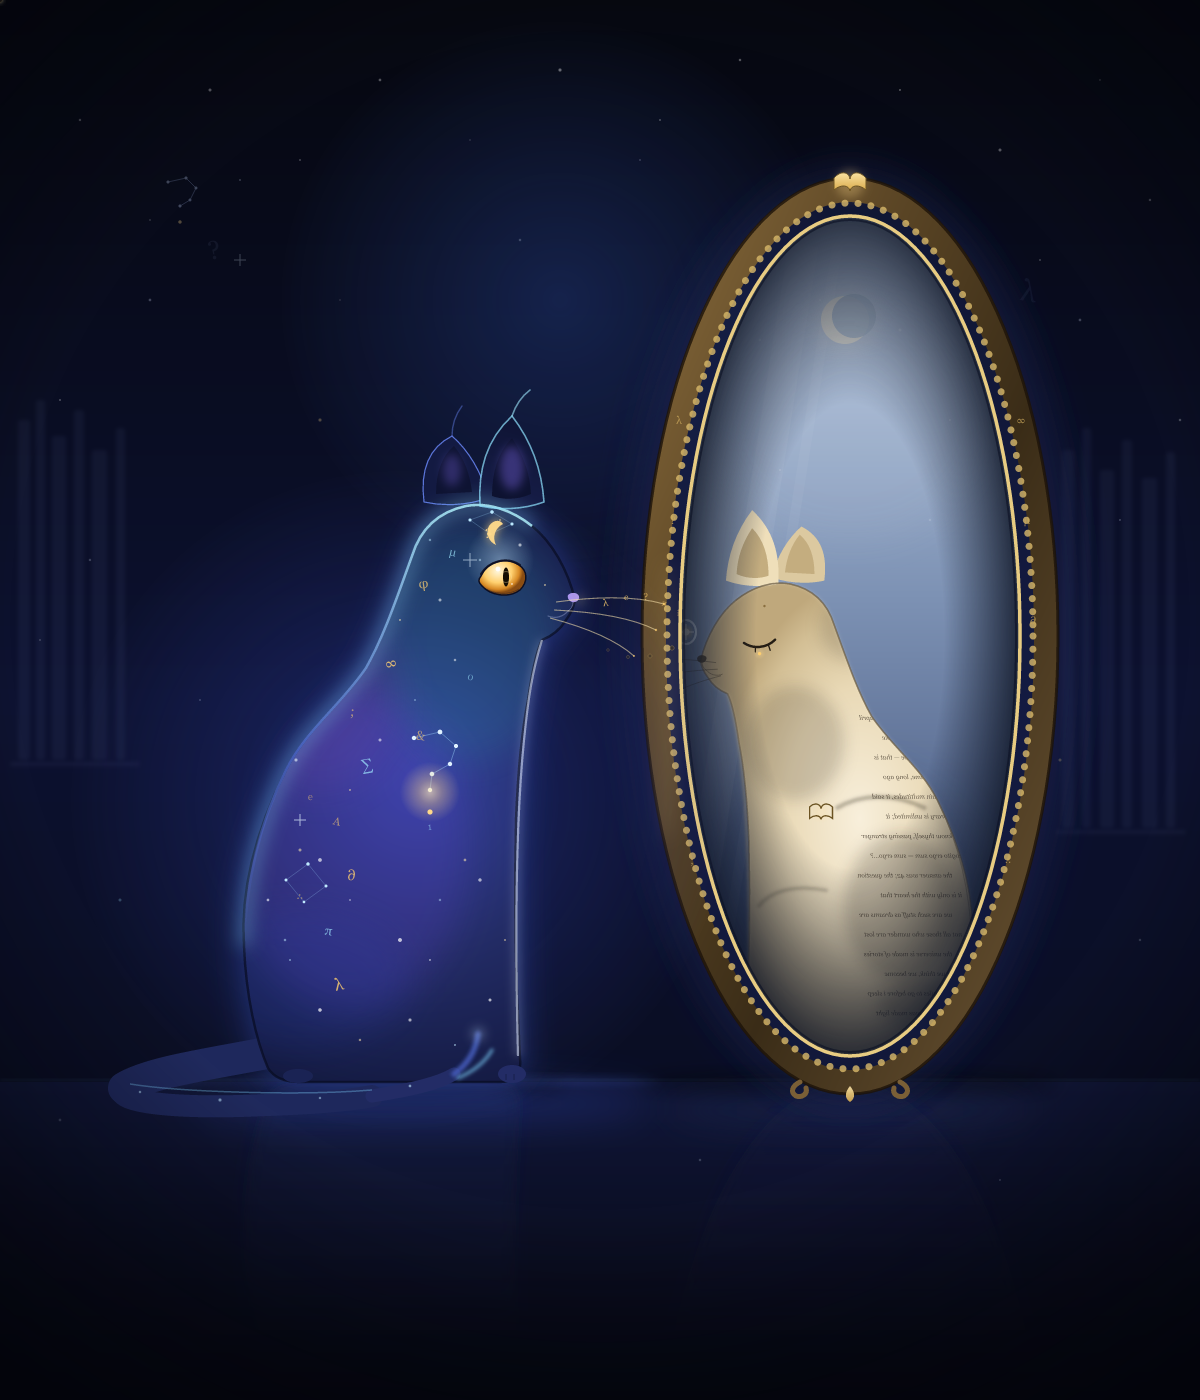
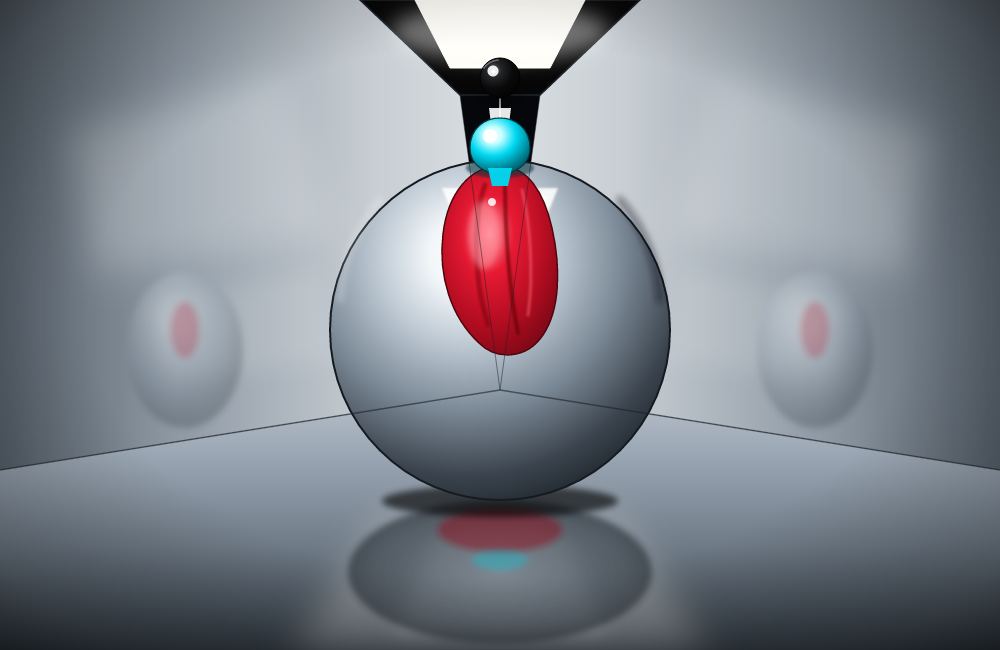
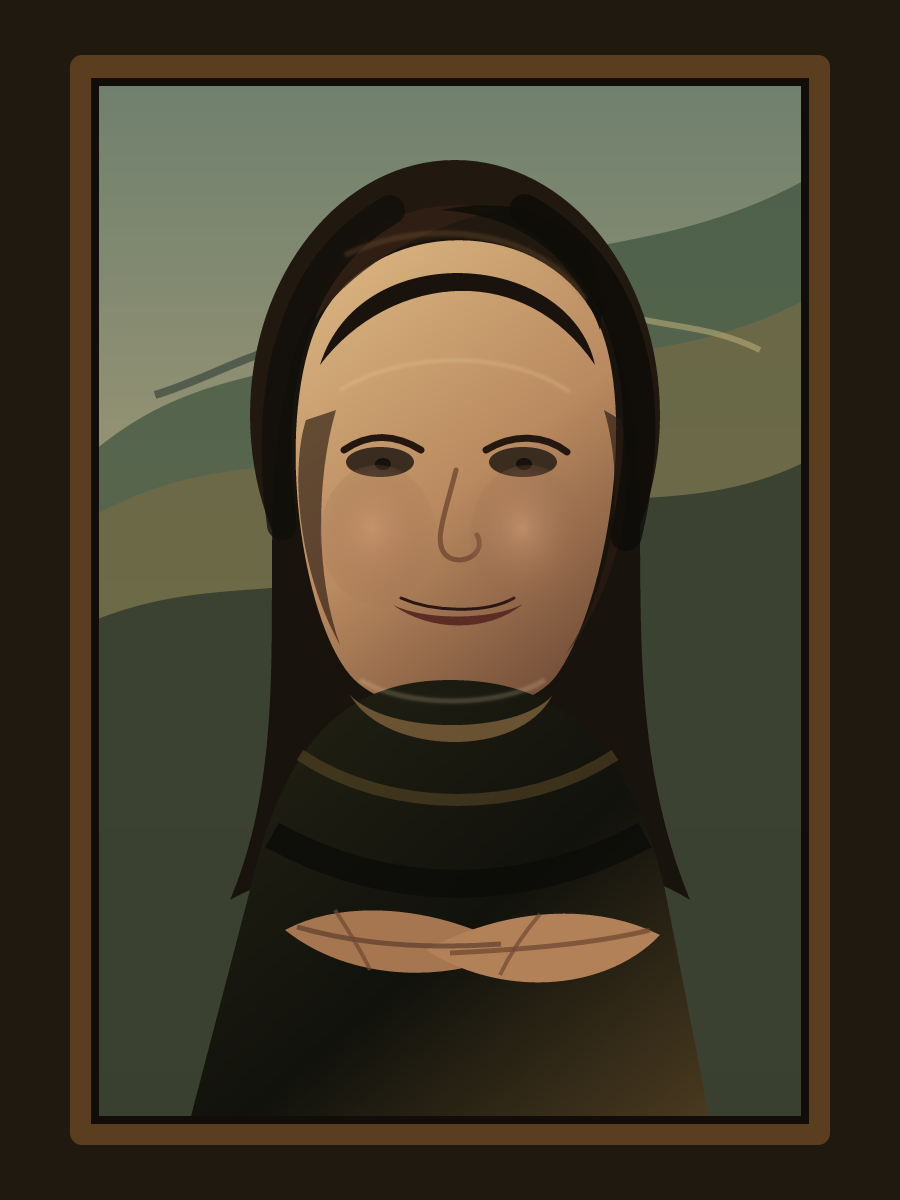
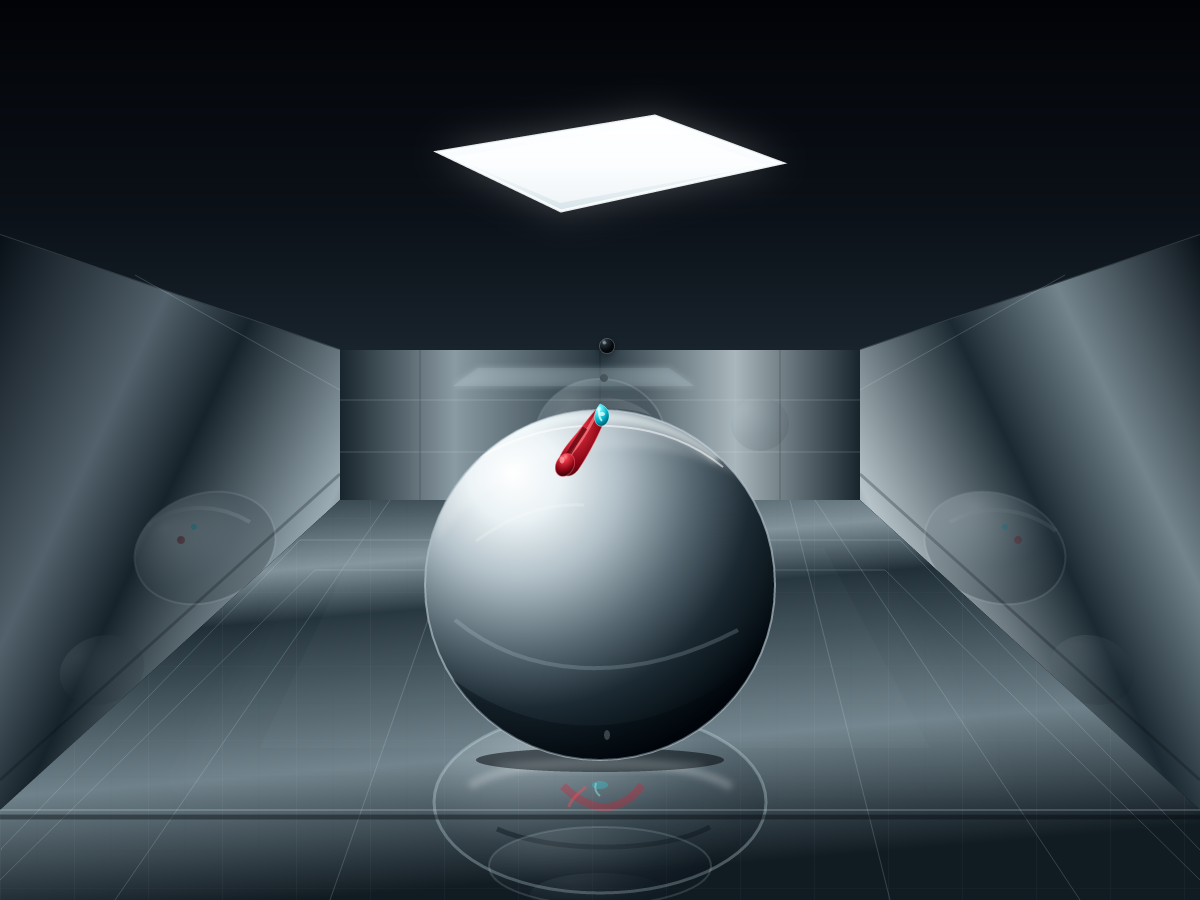
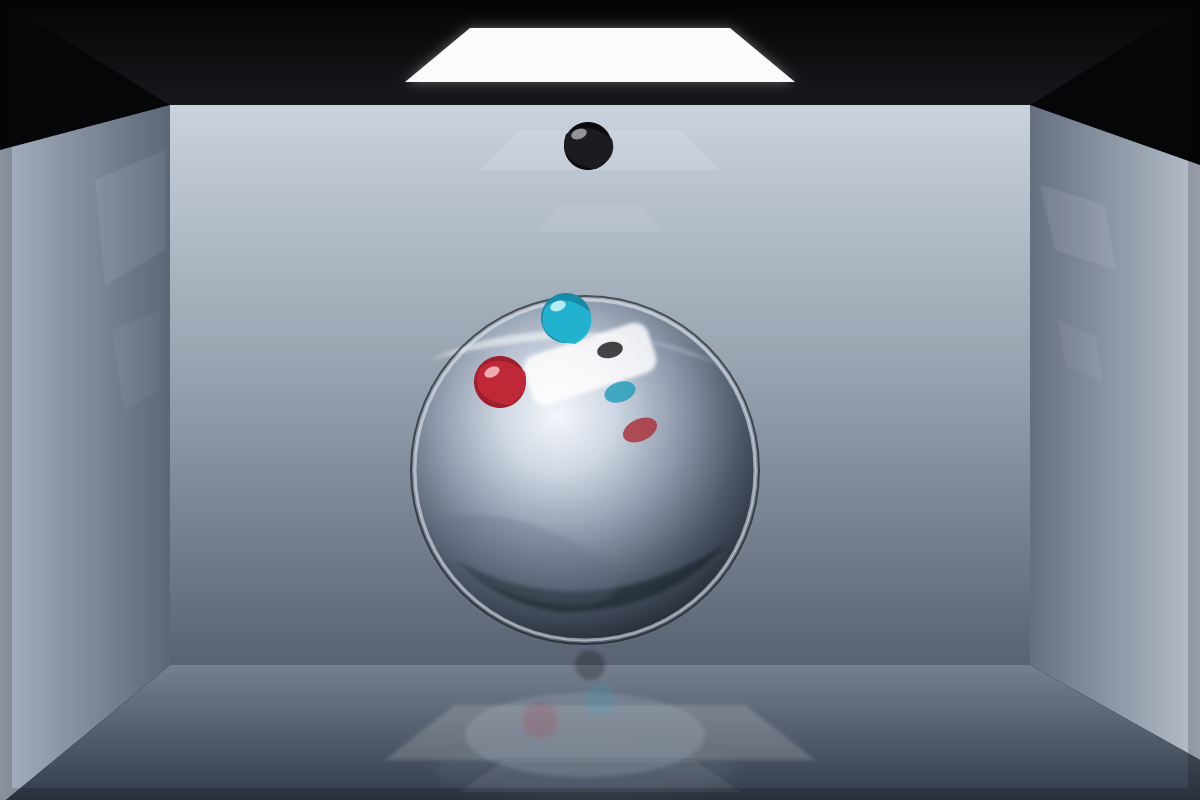
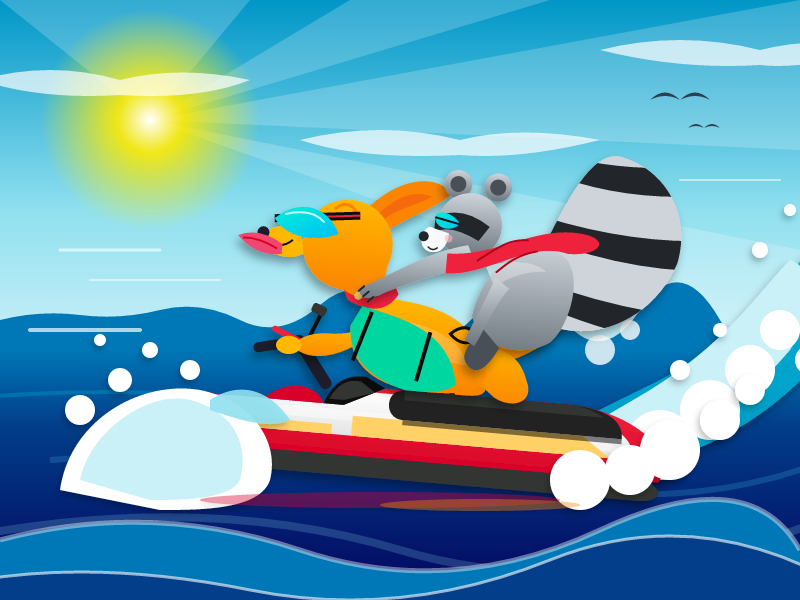
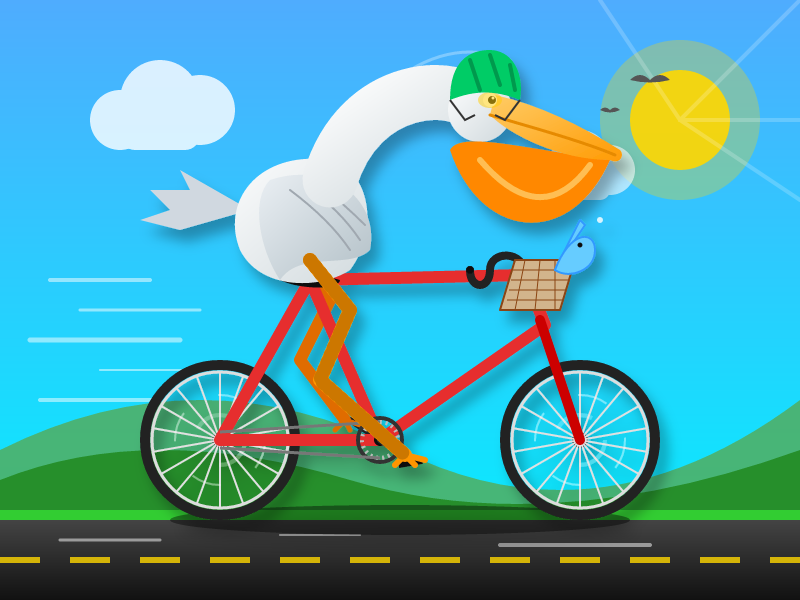
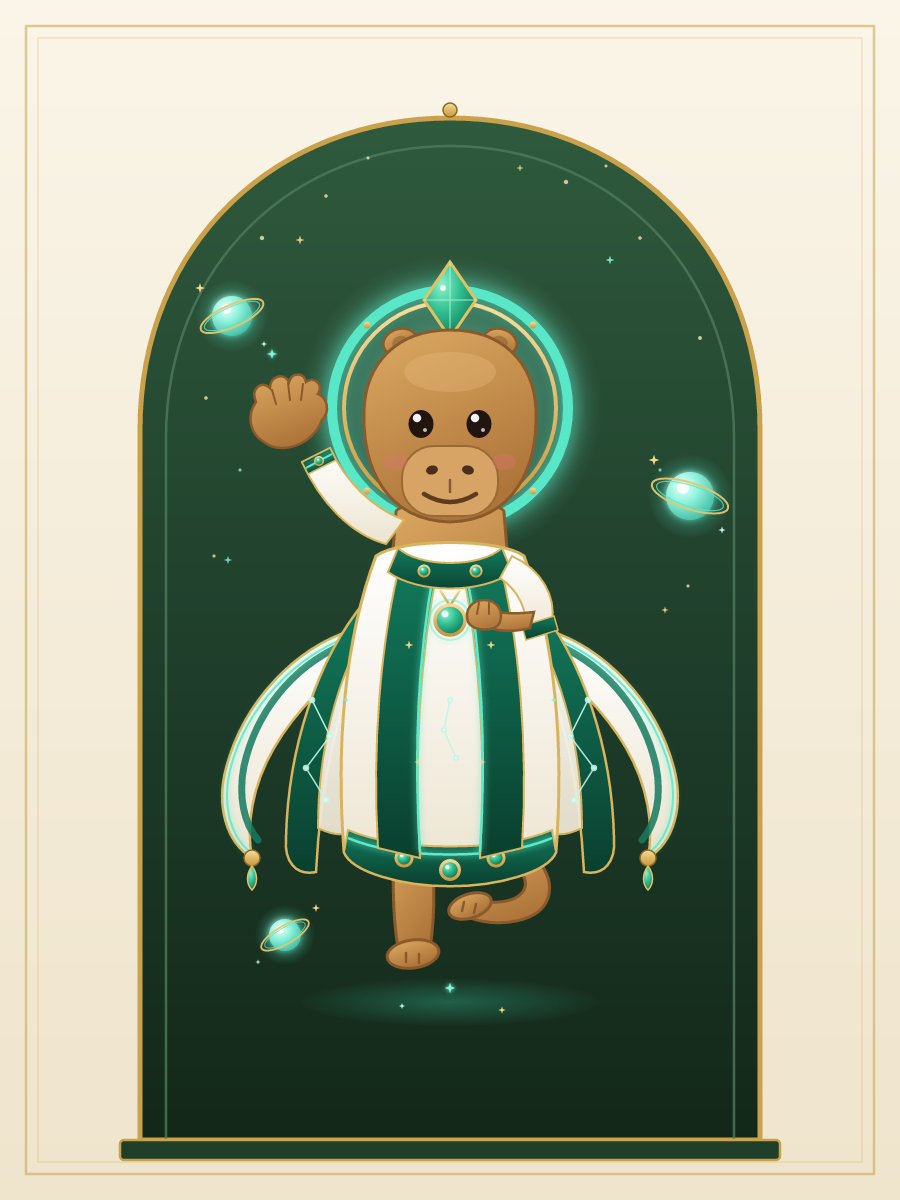
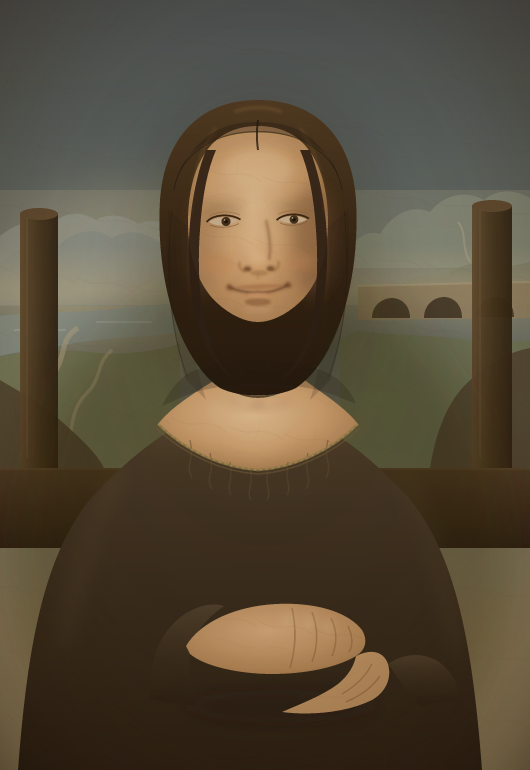
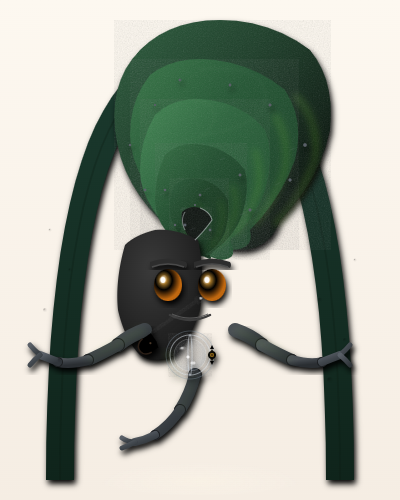
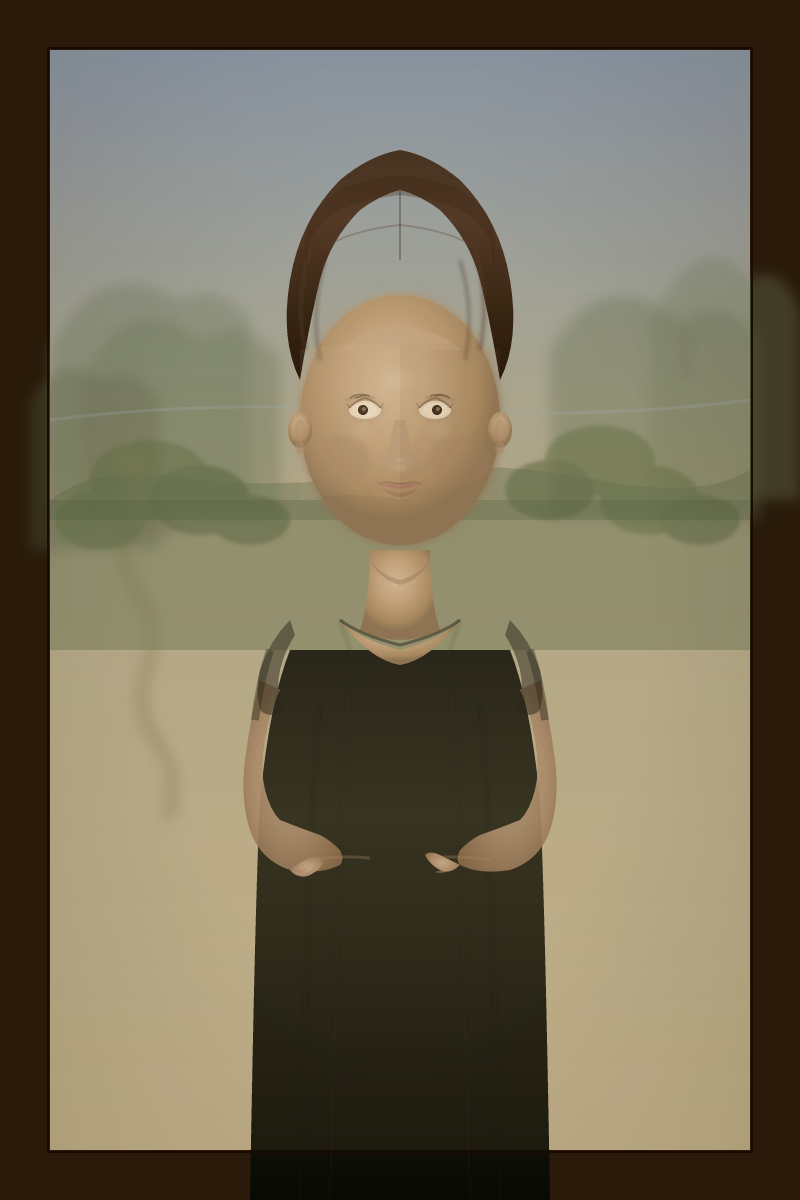
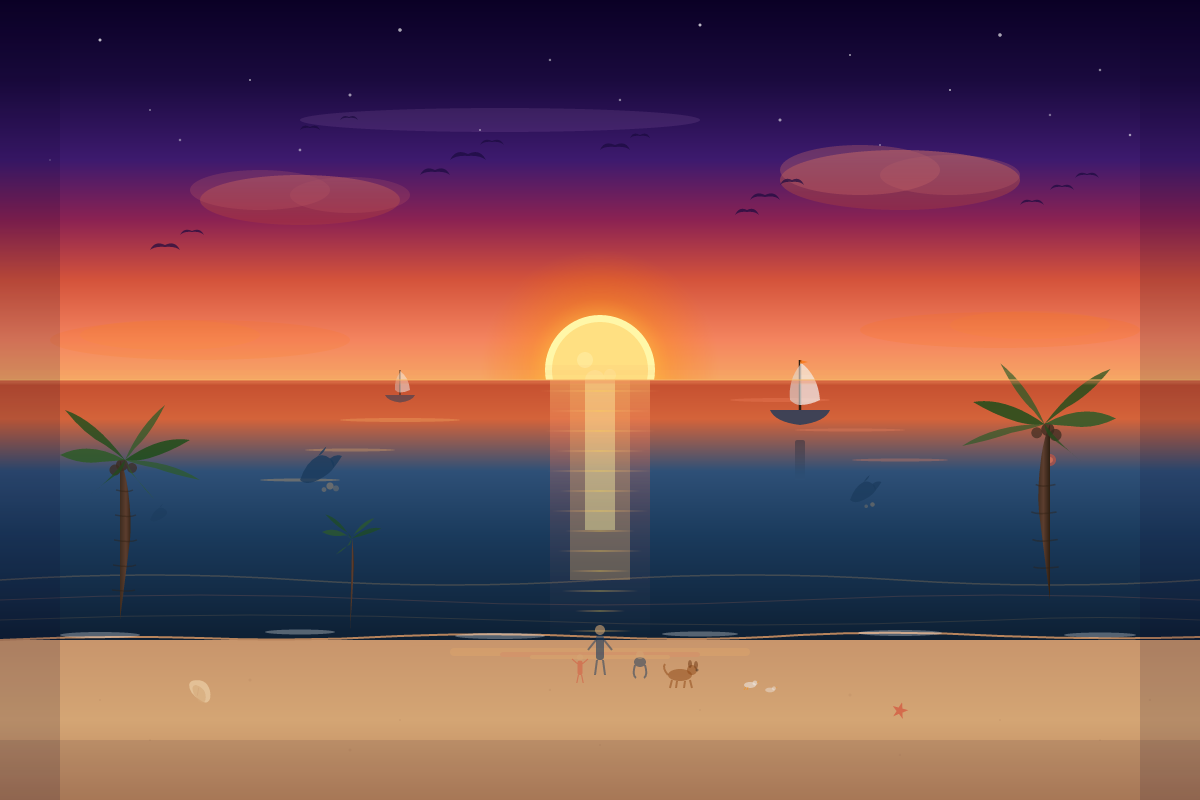
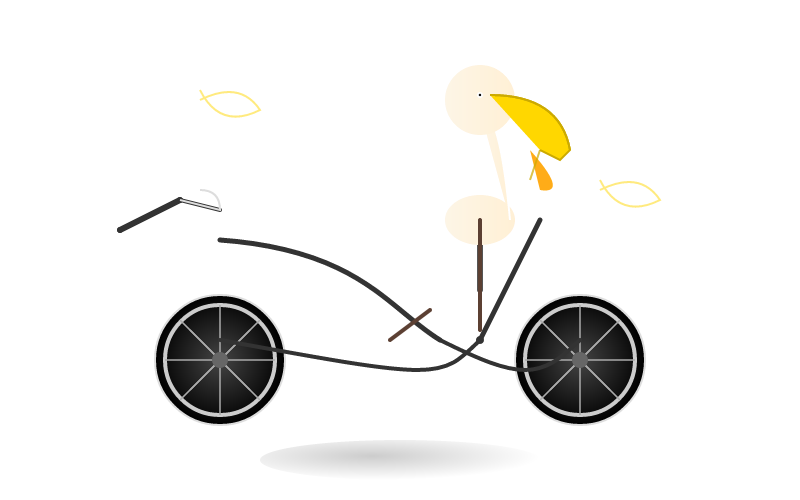
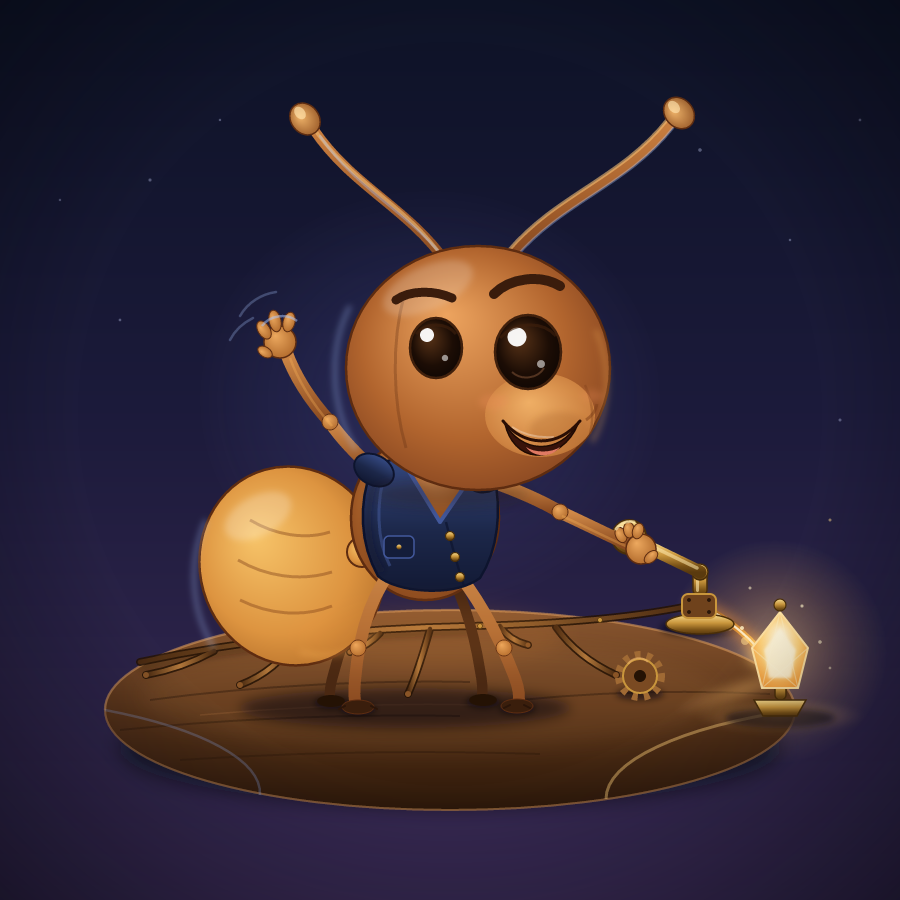
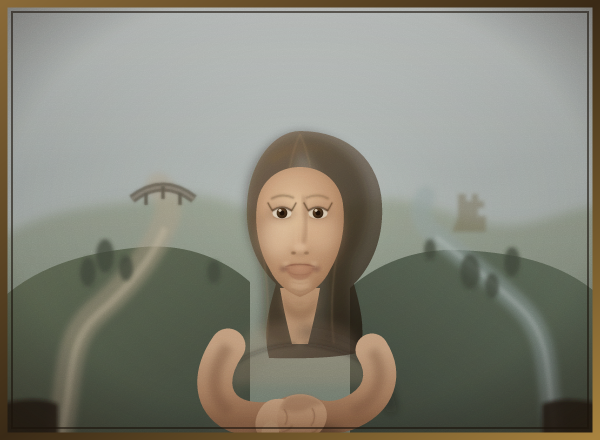
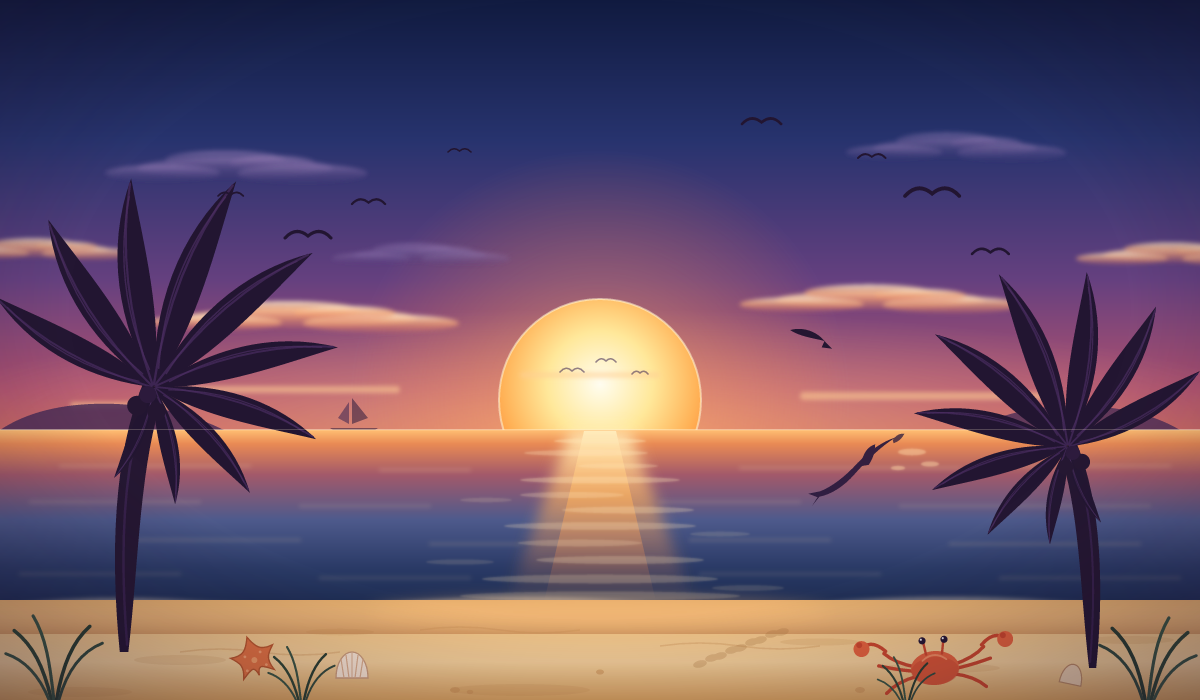
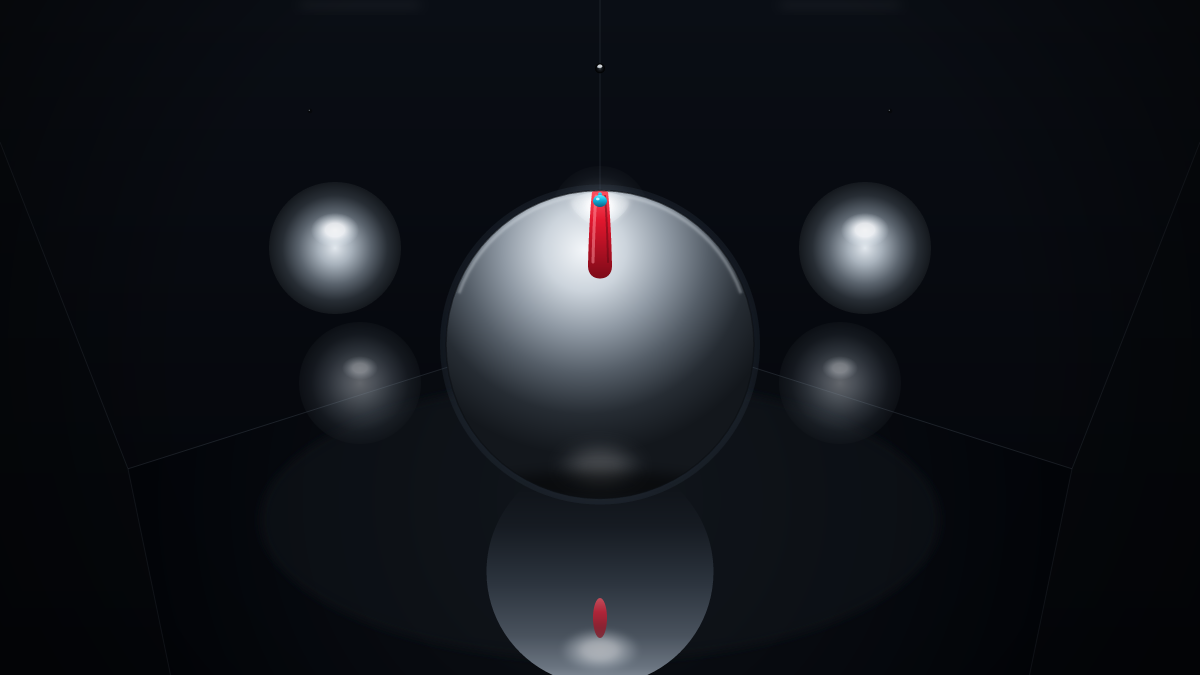
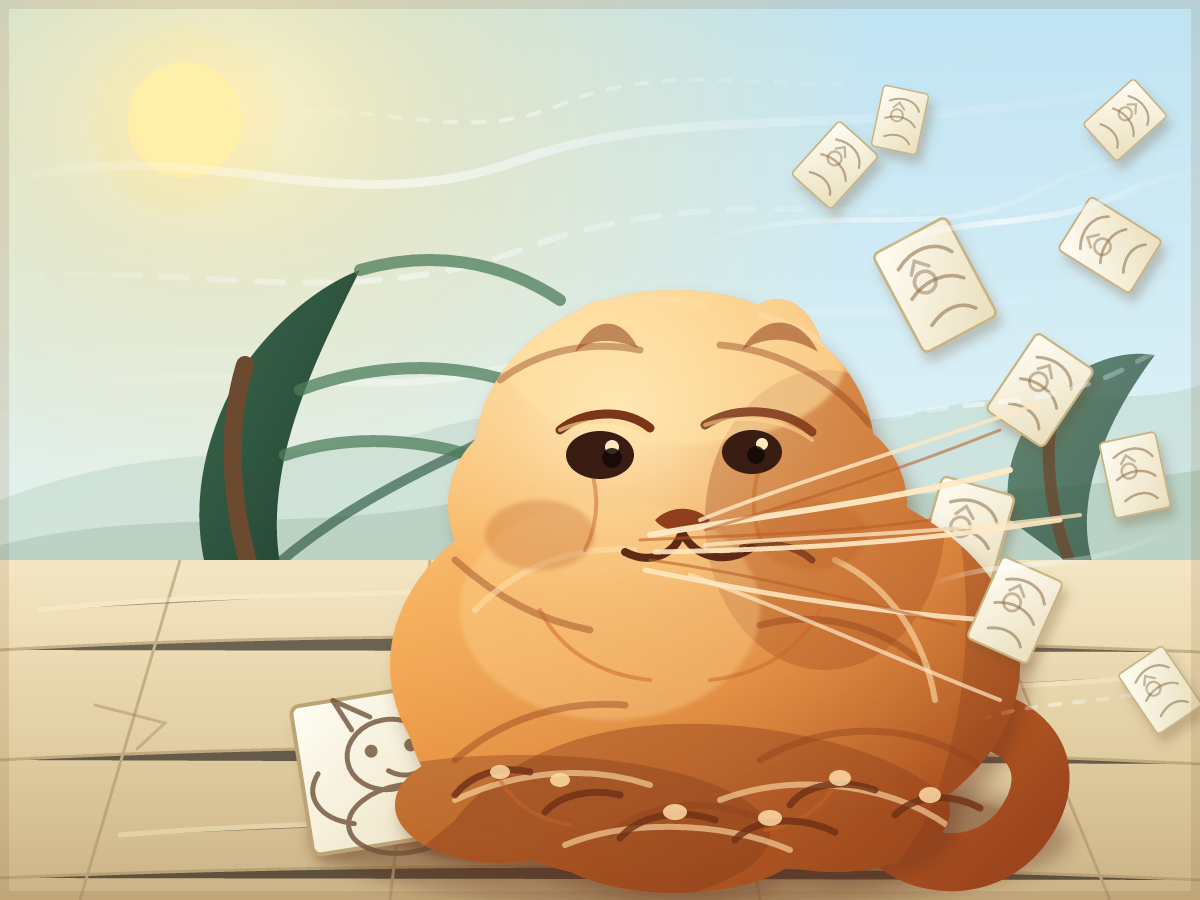
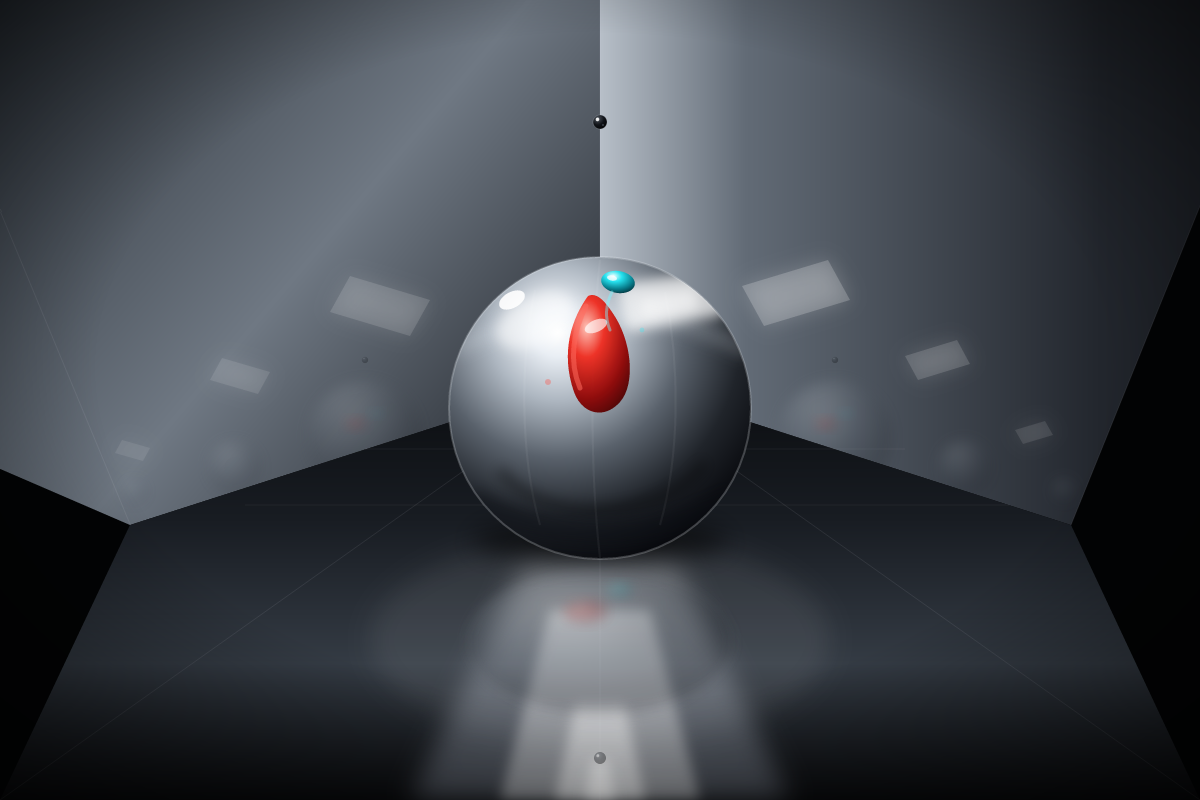
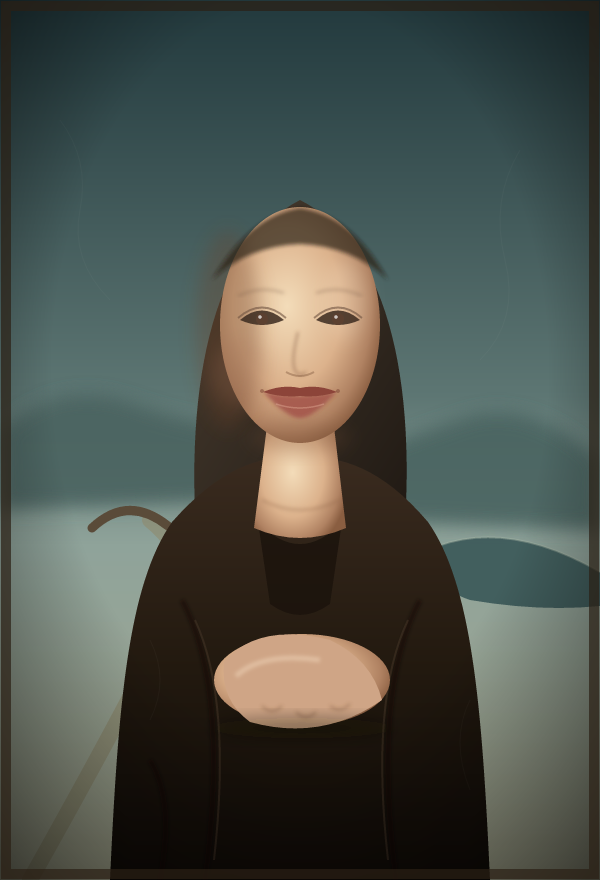
GPT 5.5: Newton's Mirror

An earlier OpenAI flagship generation that remains available for coding and professional work, with a million-token-class context.
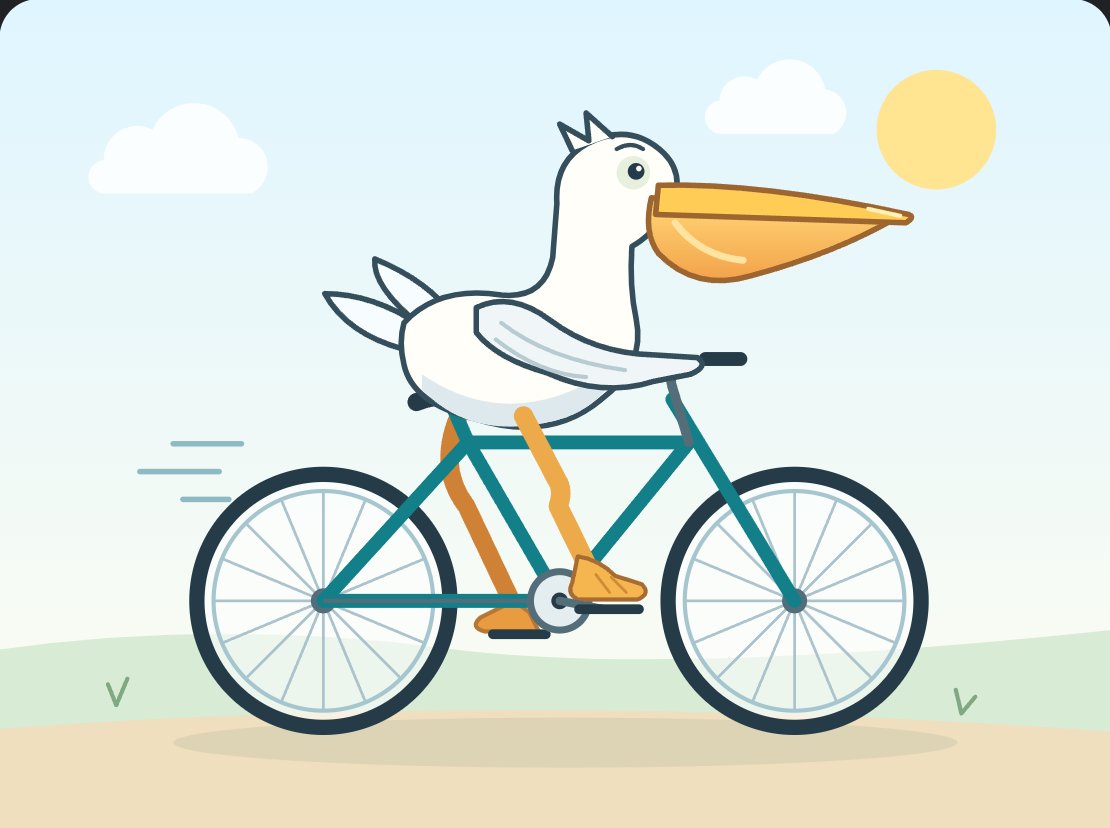
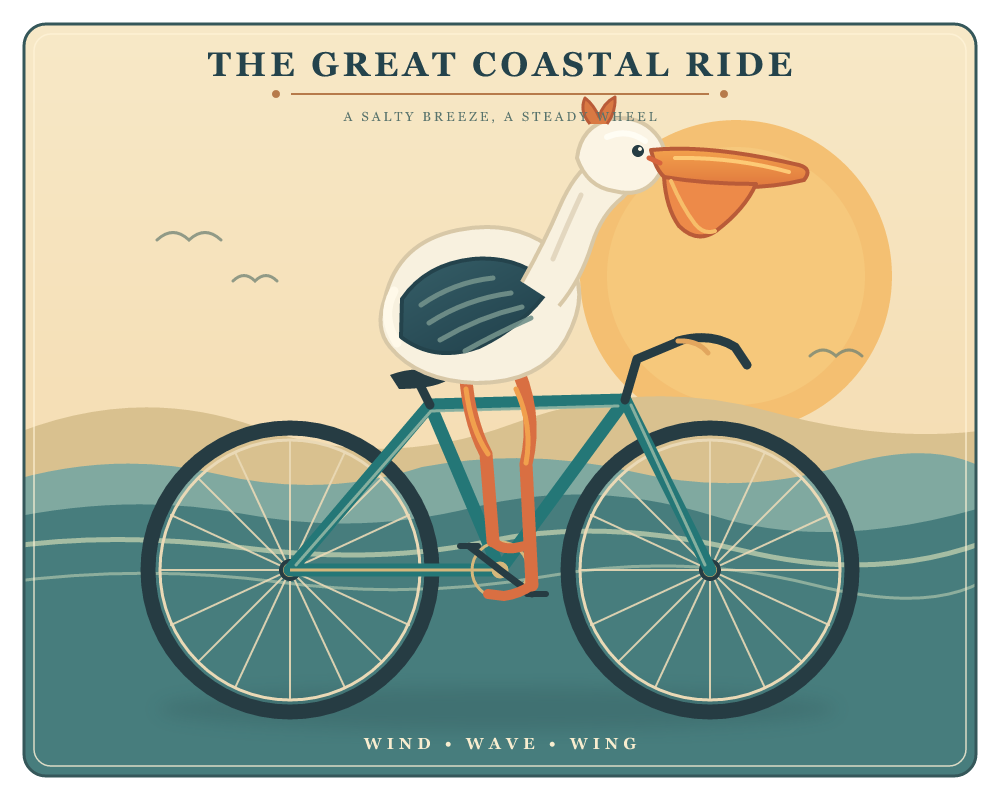
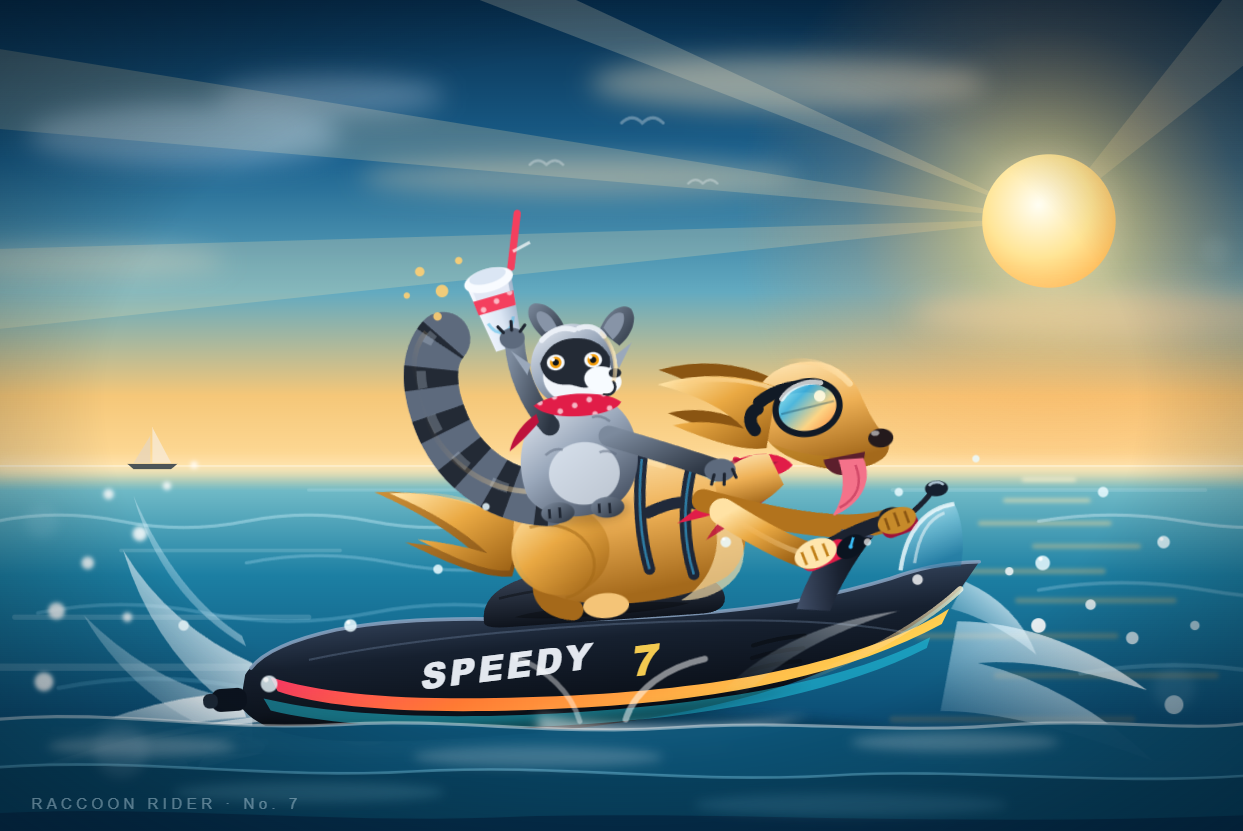
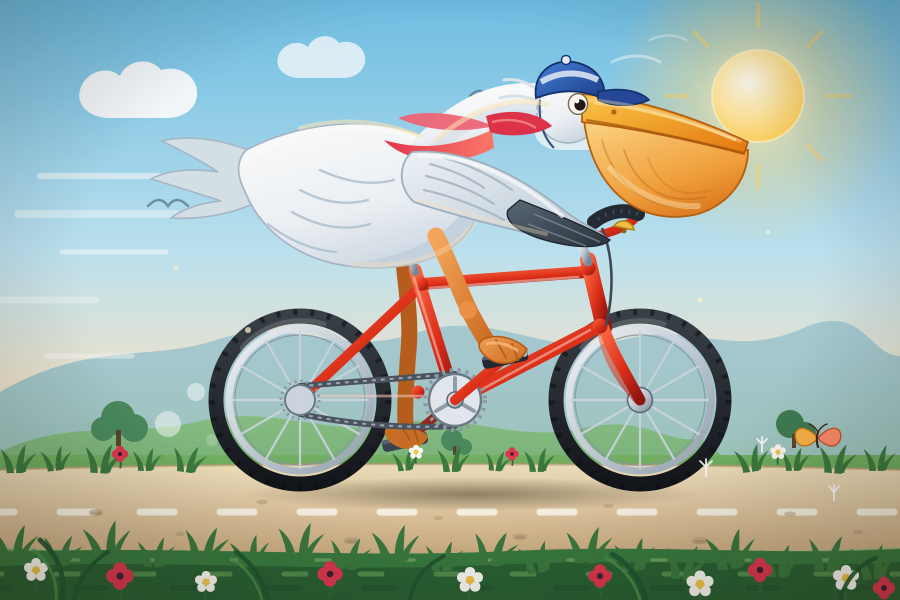
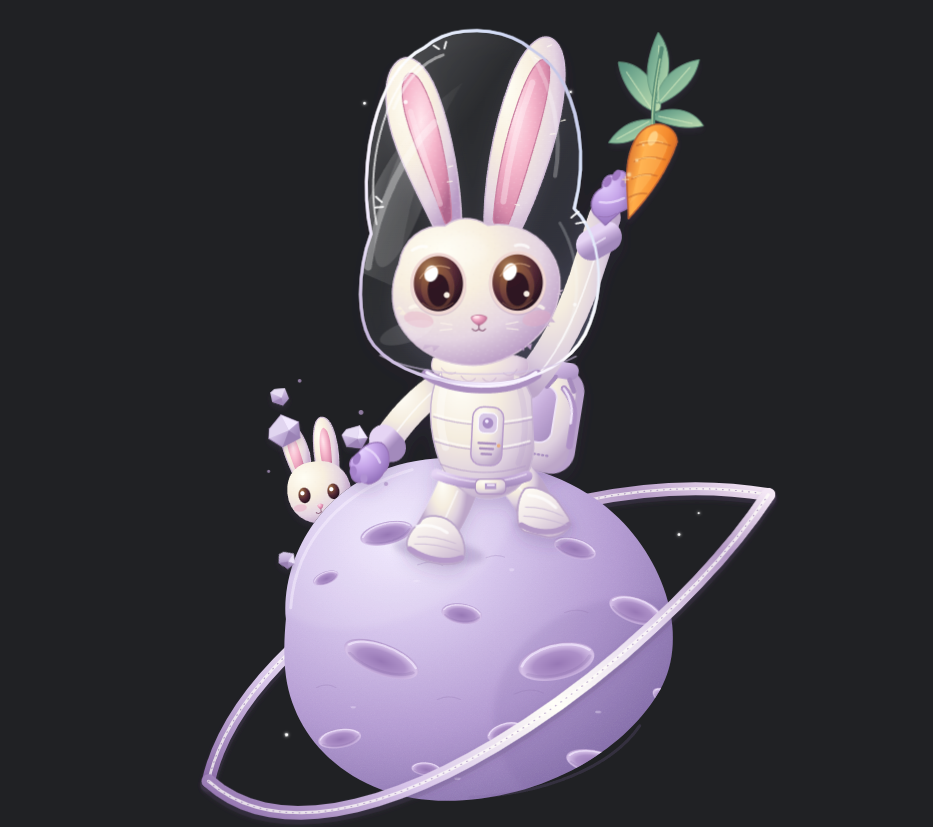
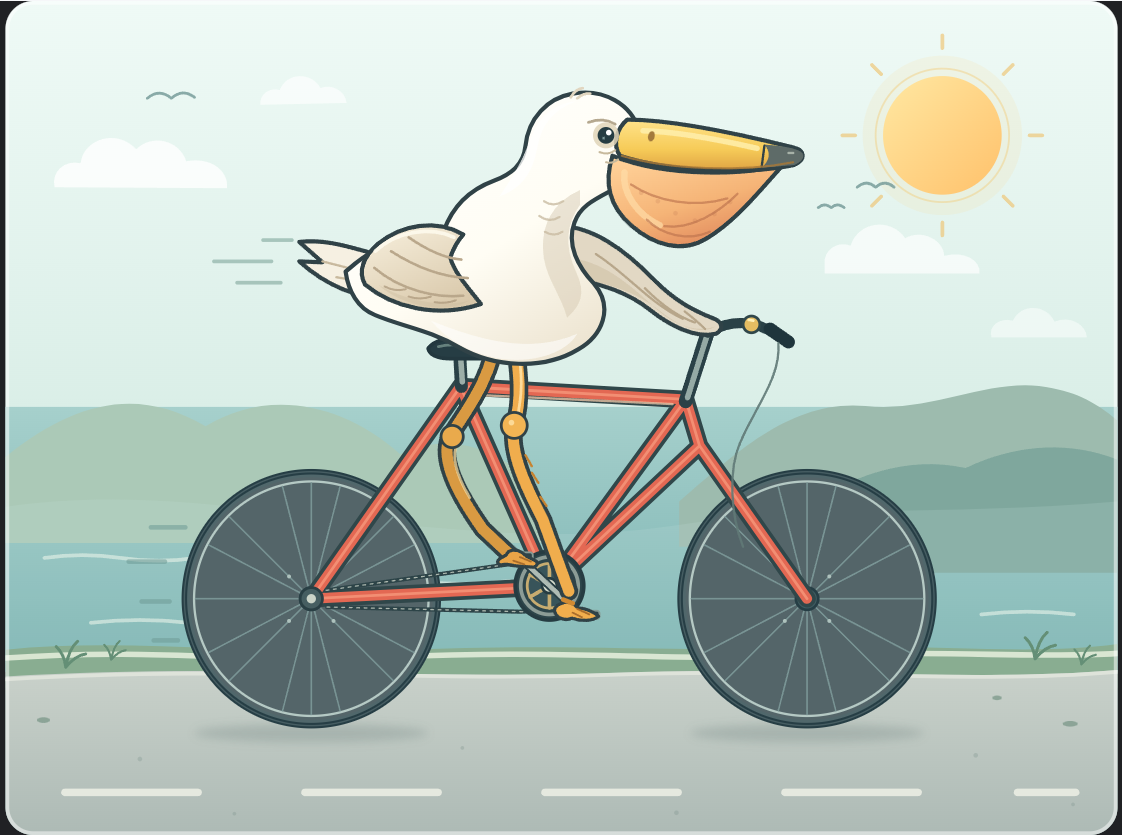
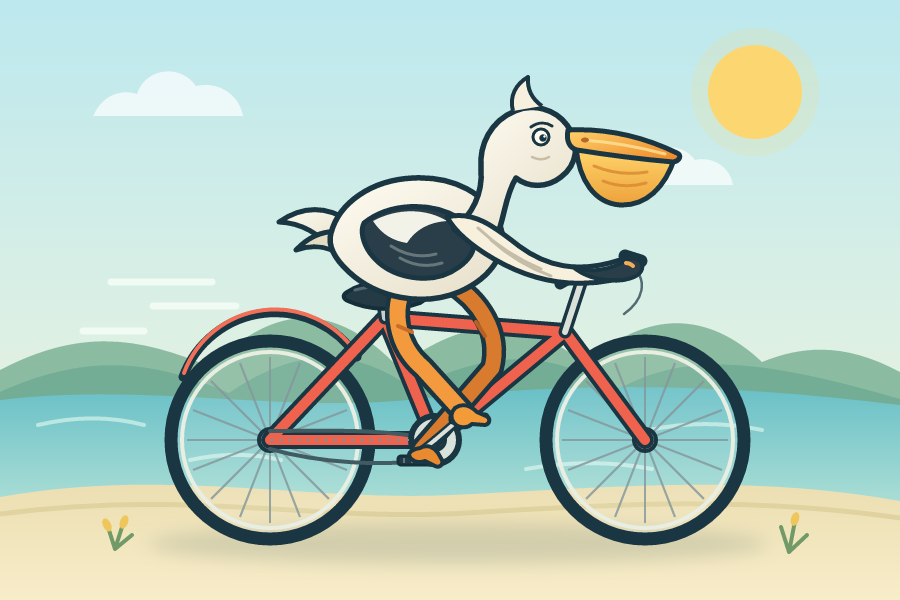
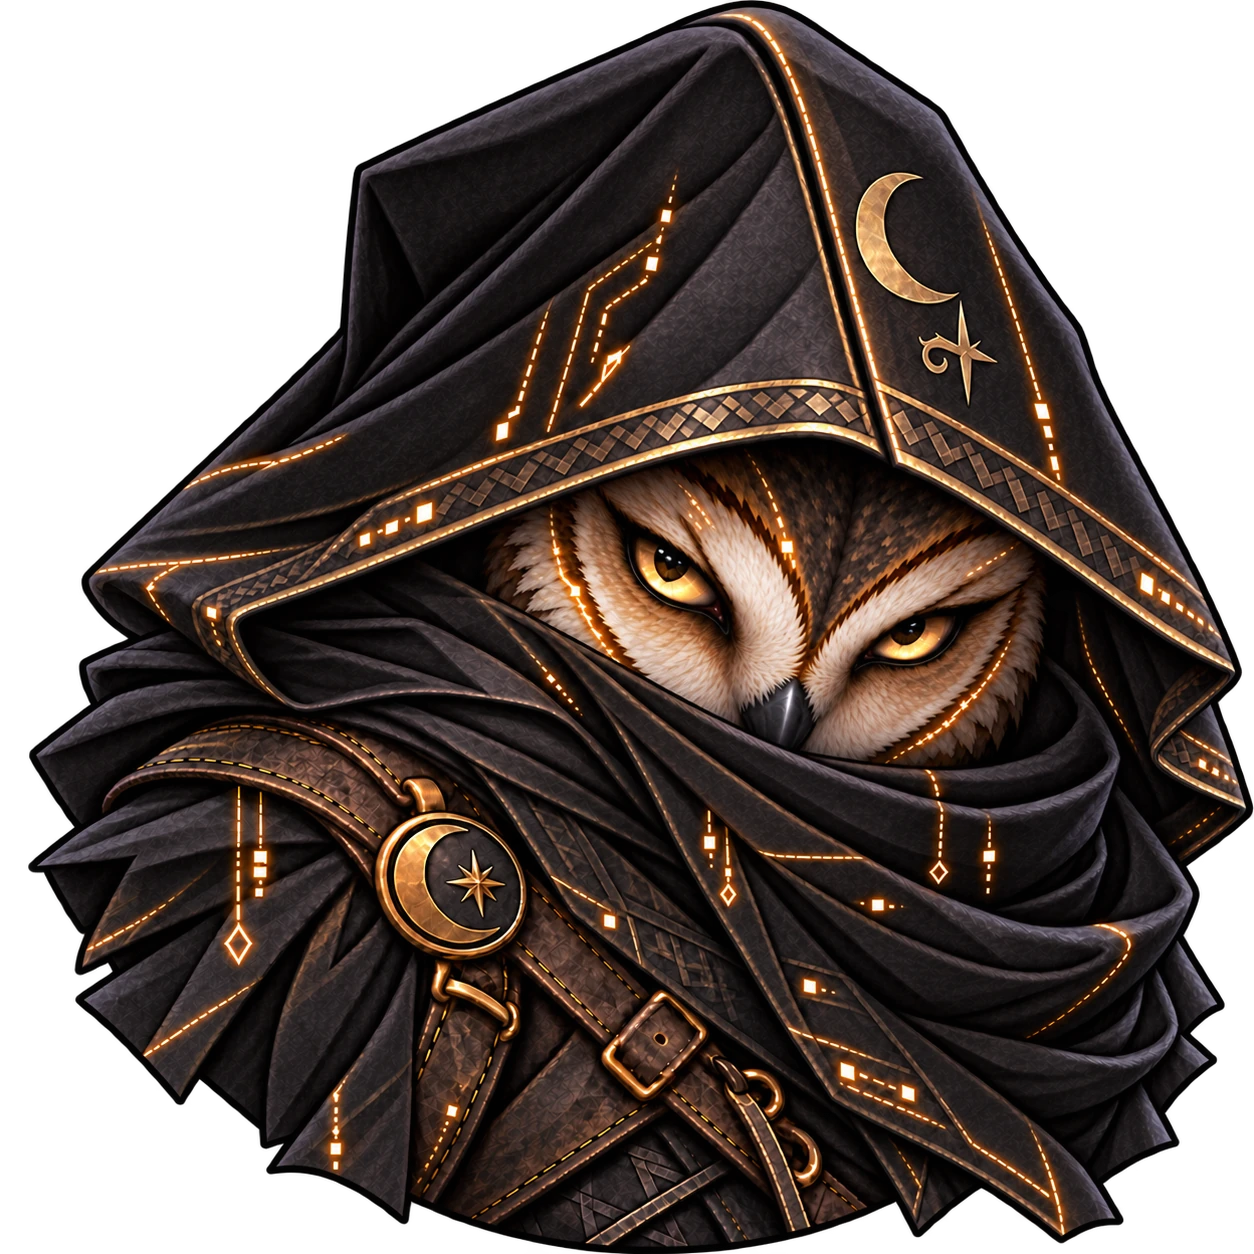
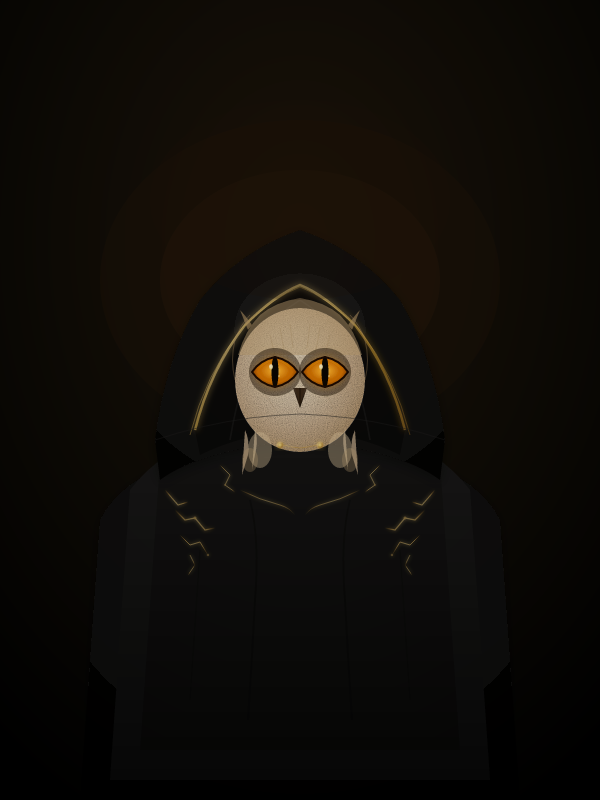
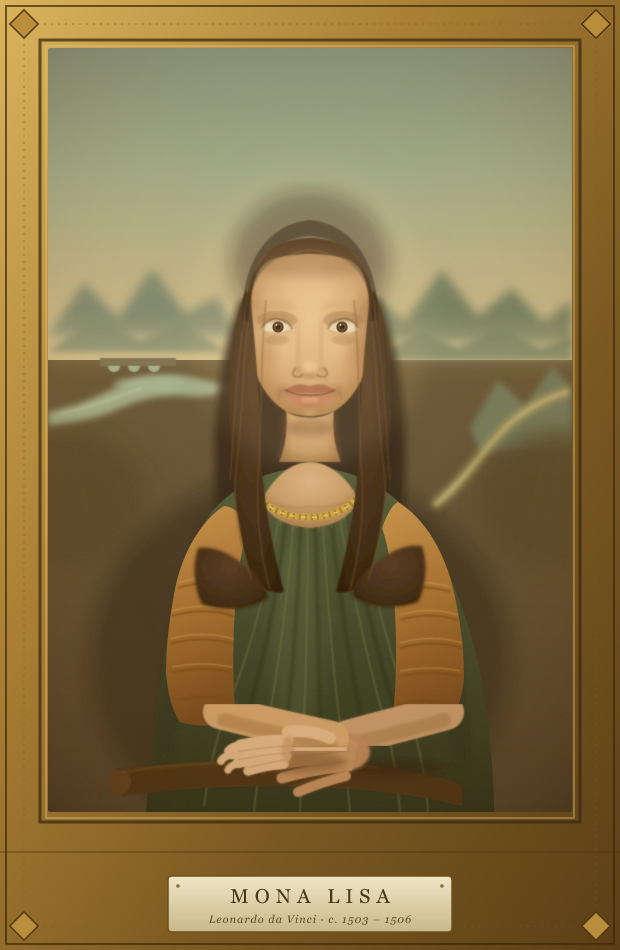
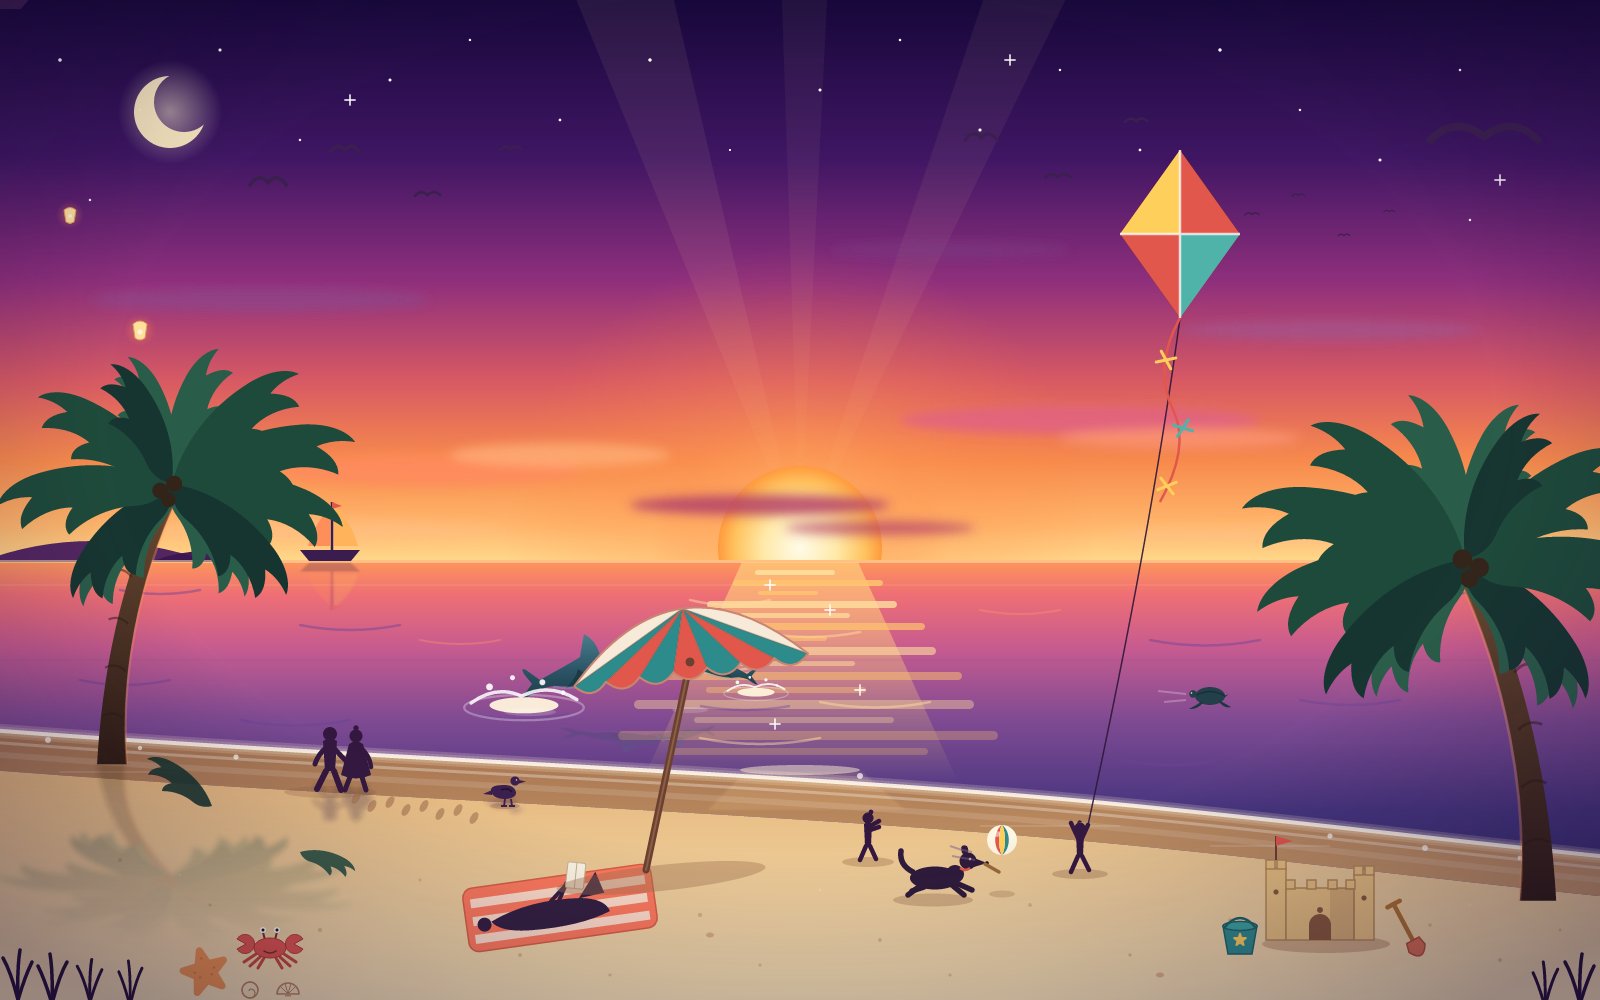
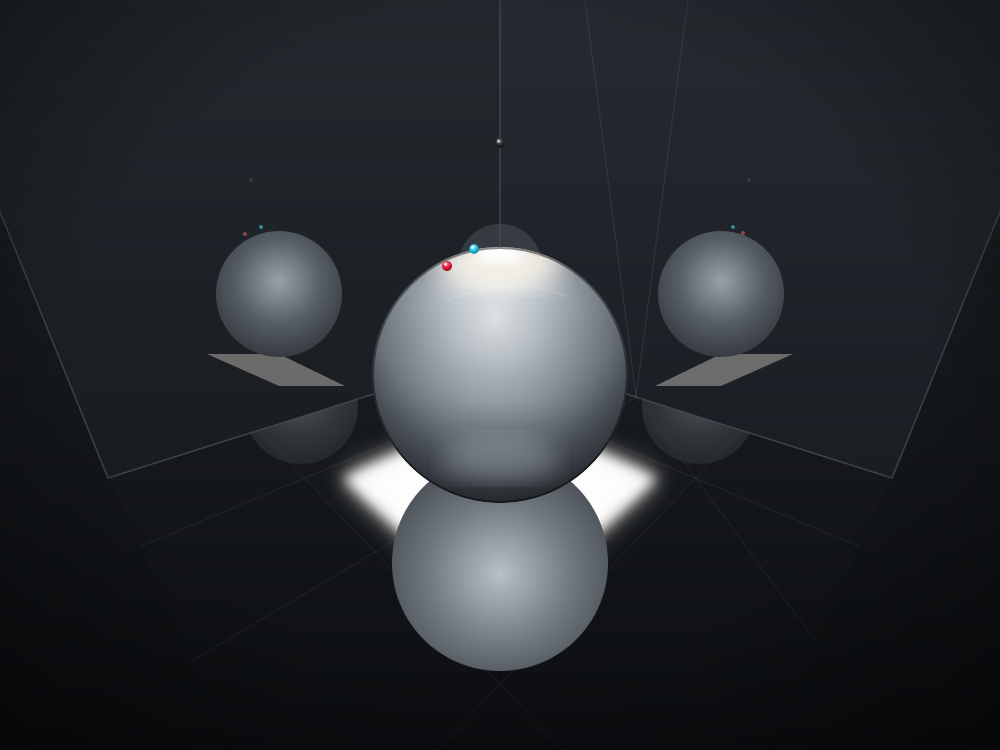
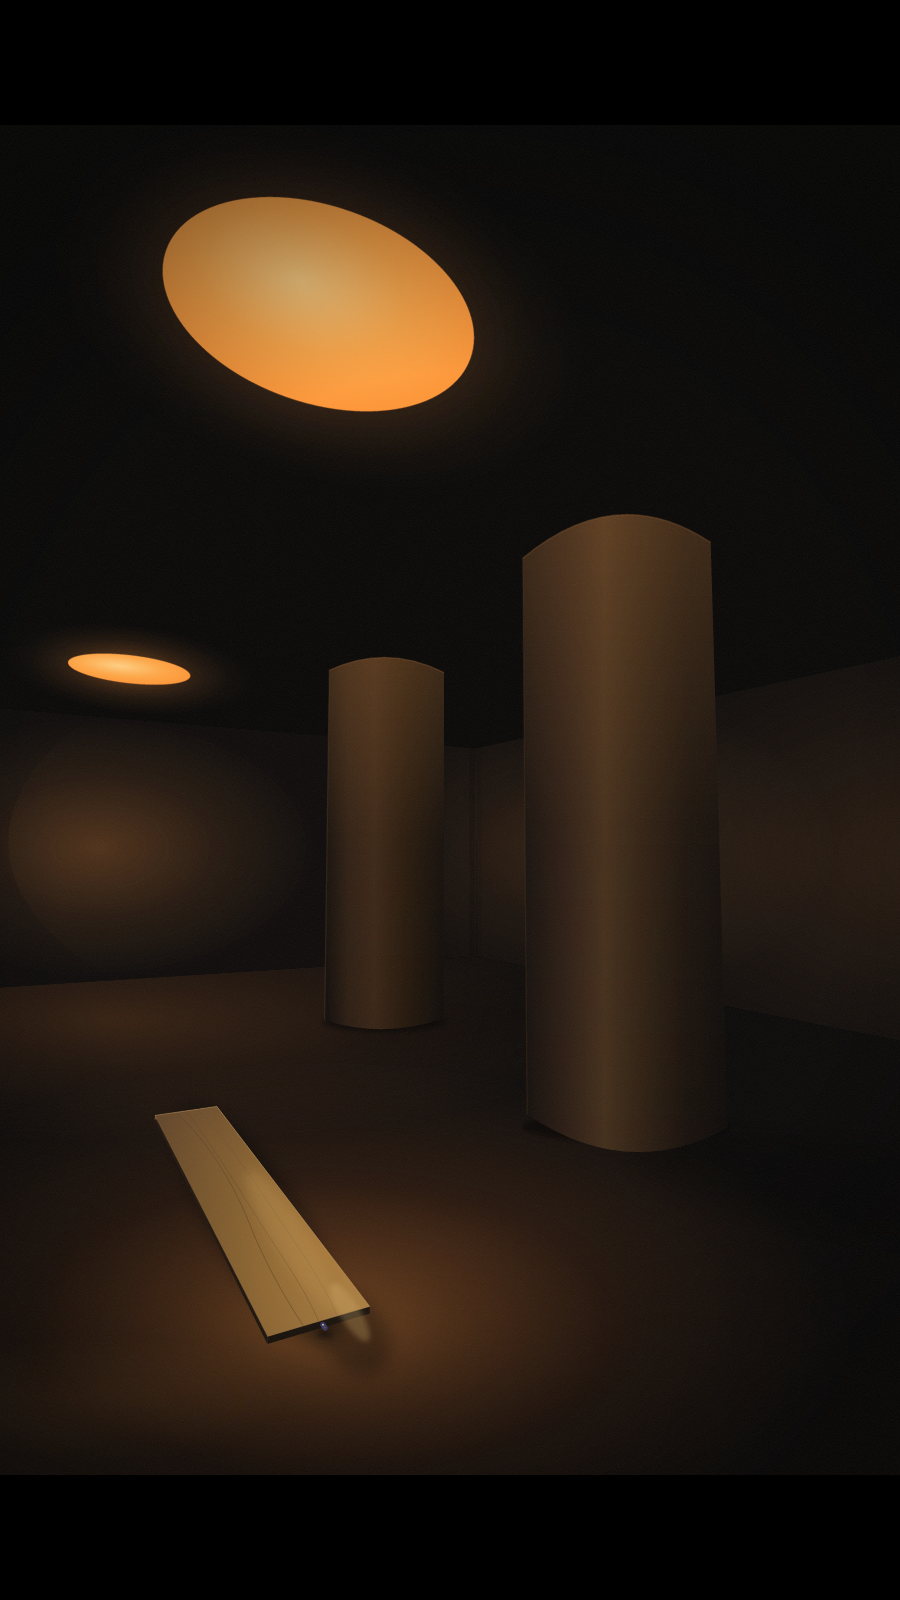
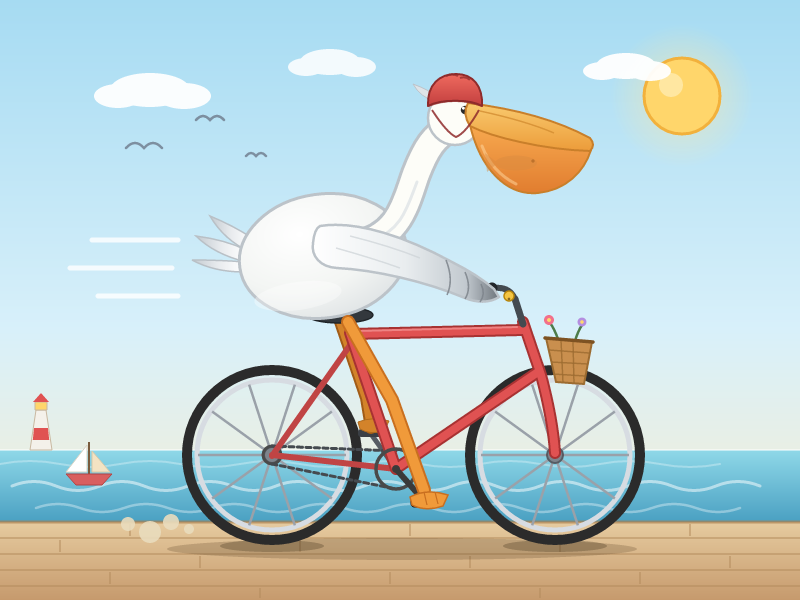
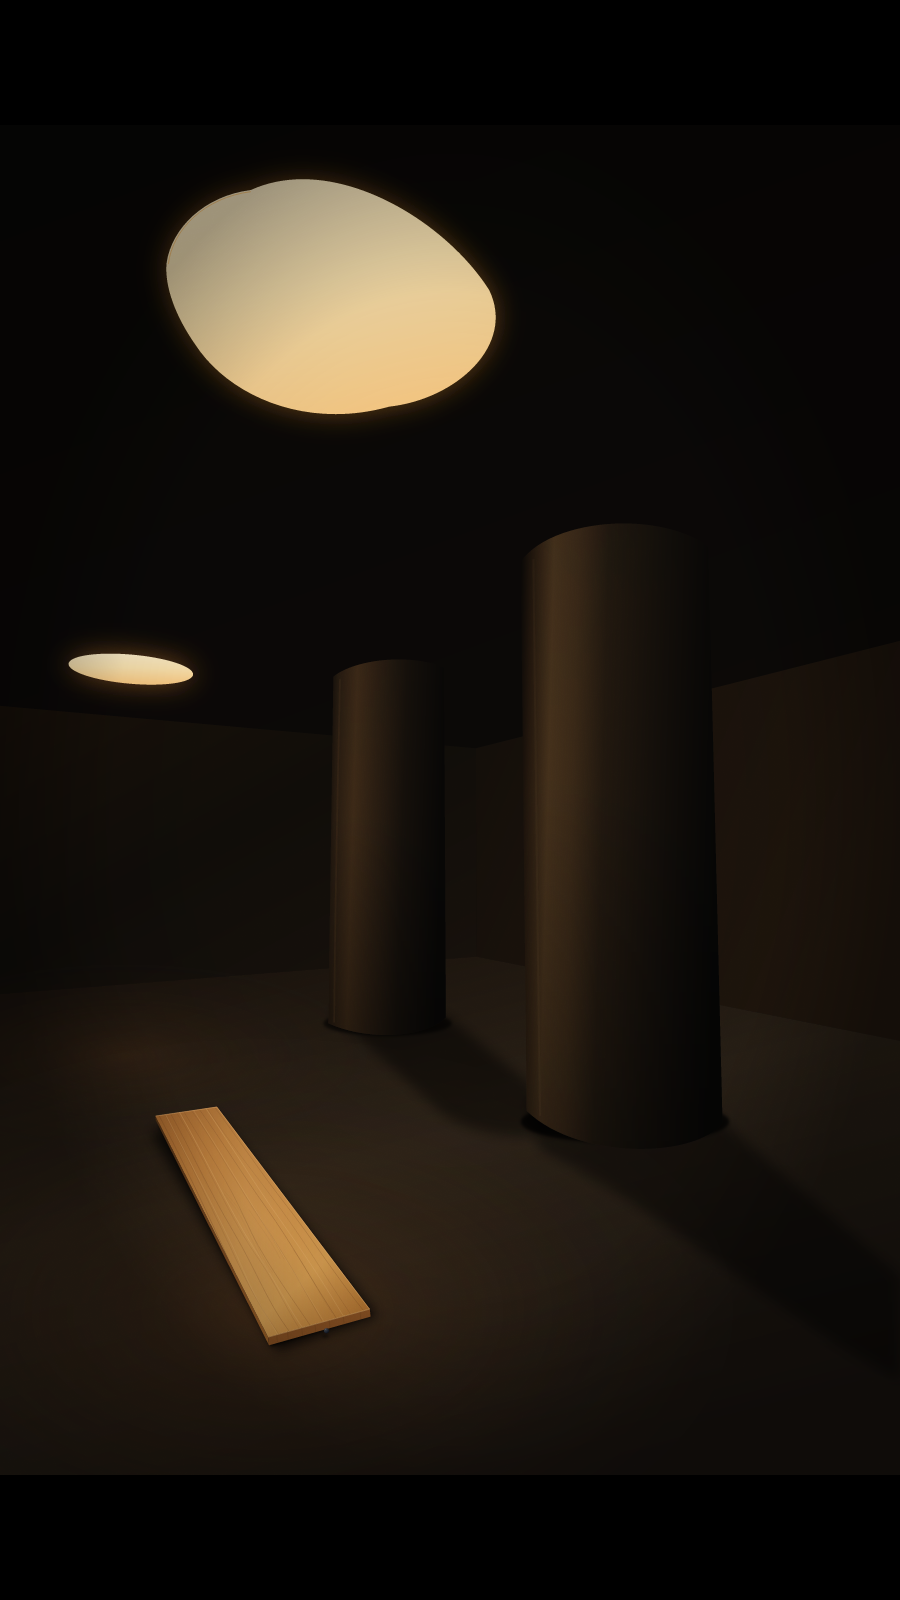
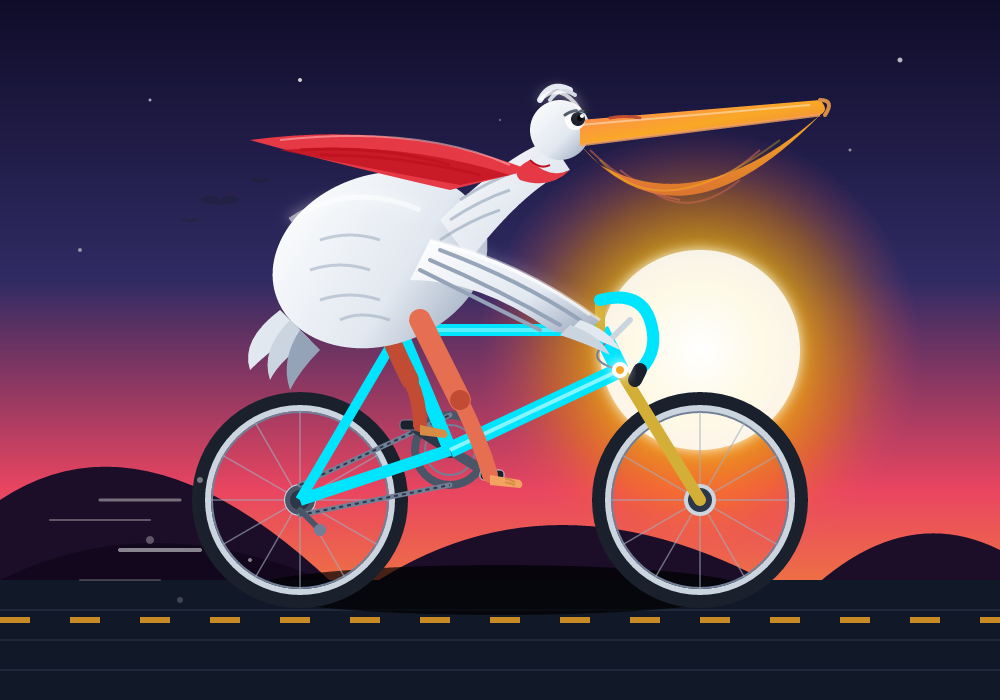
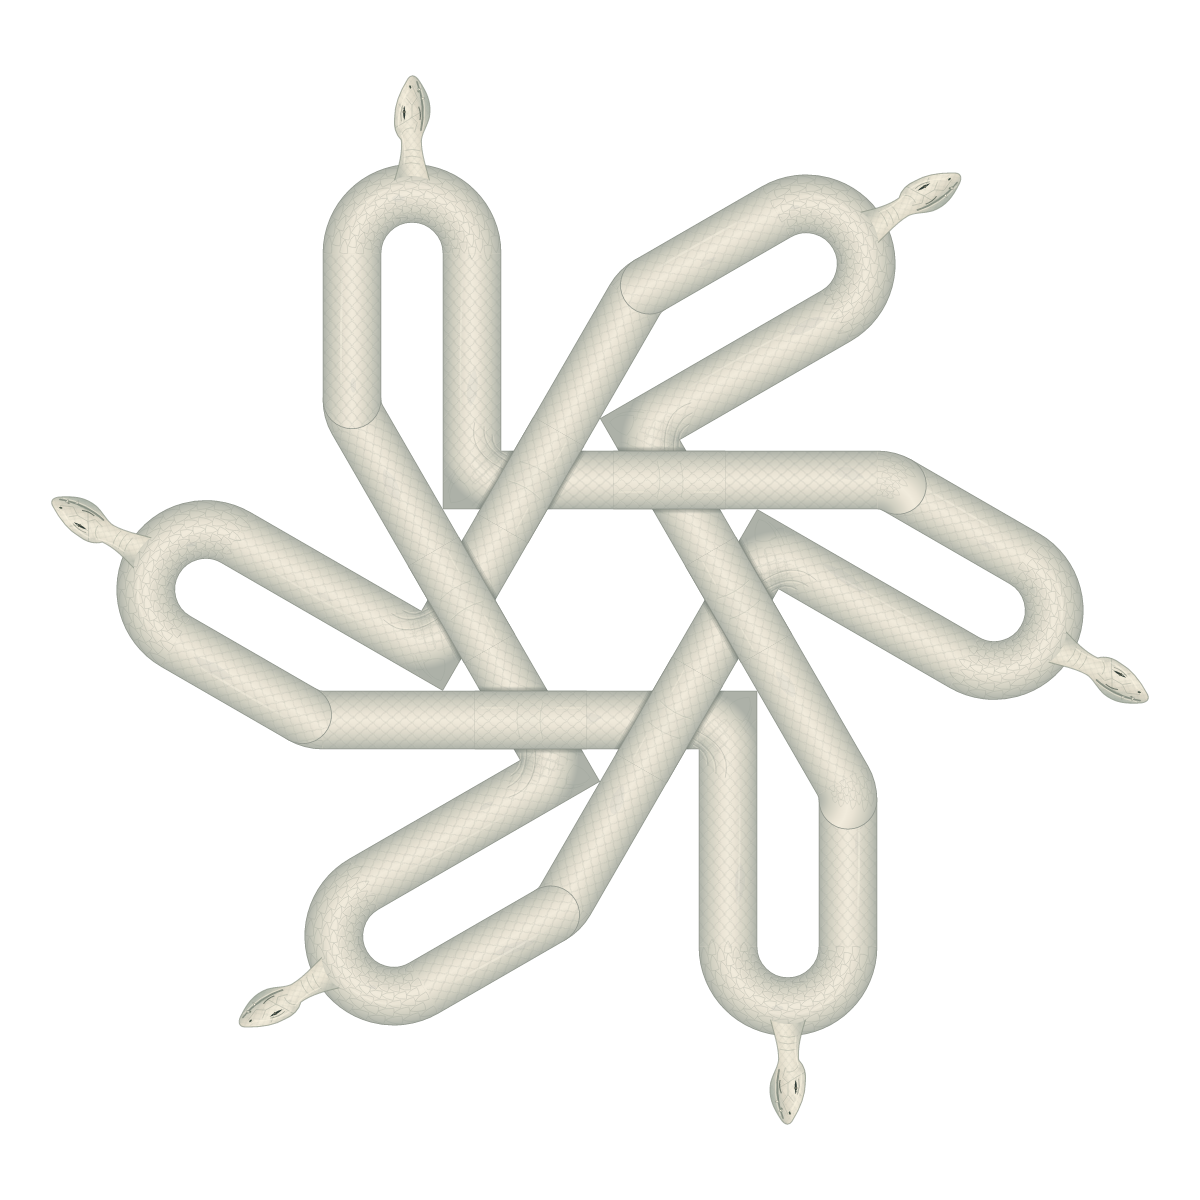
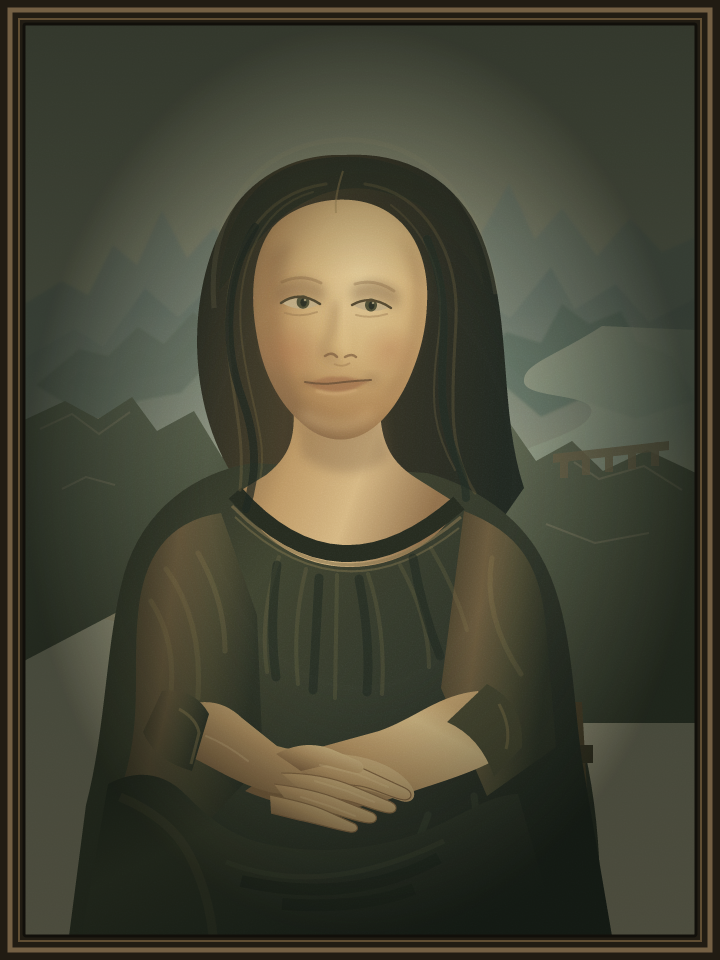
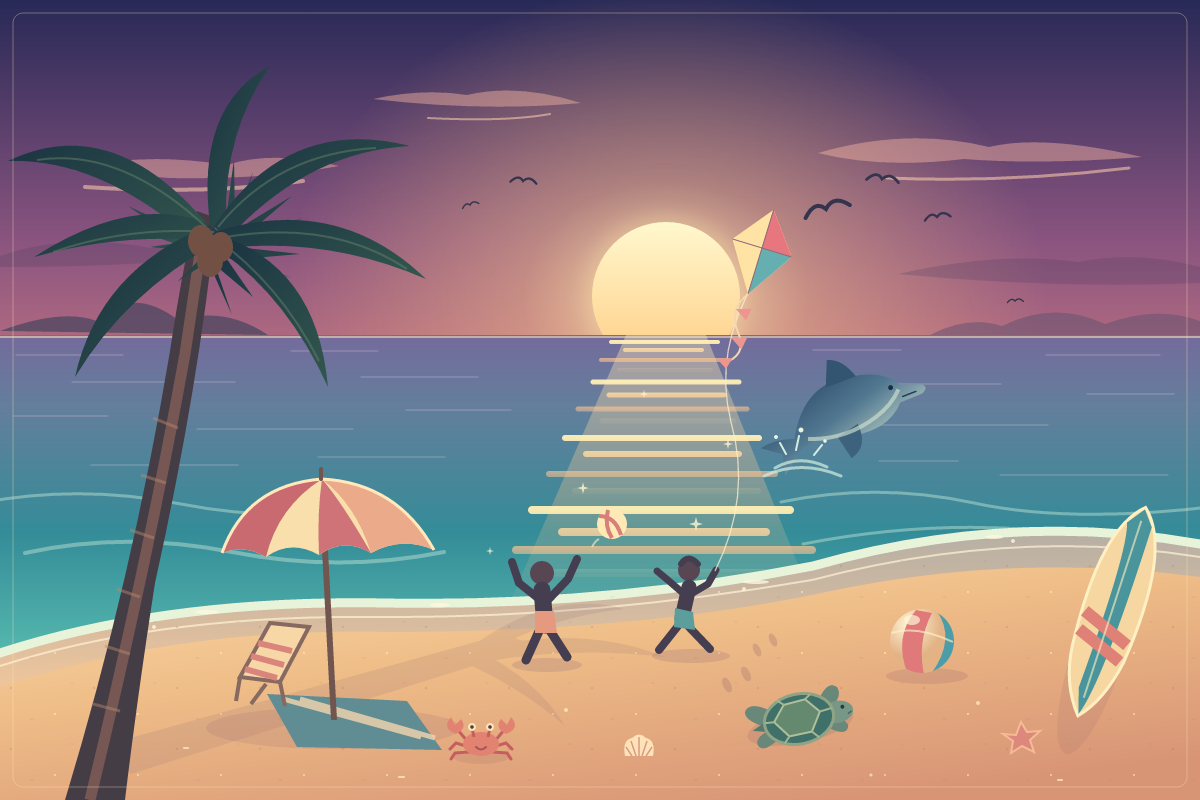
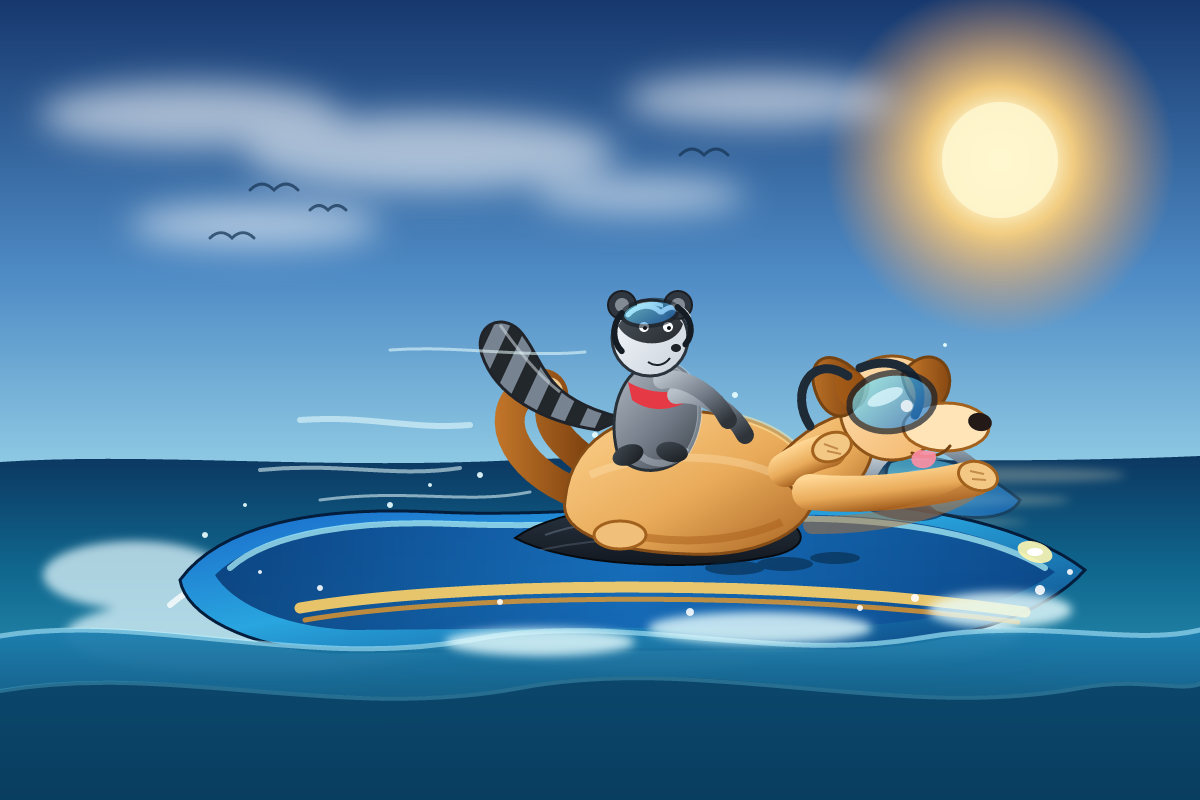
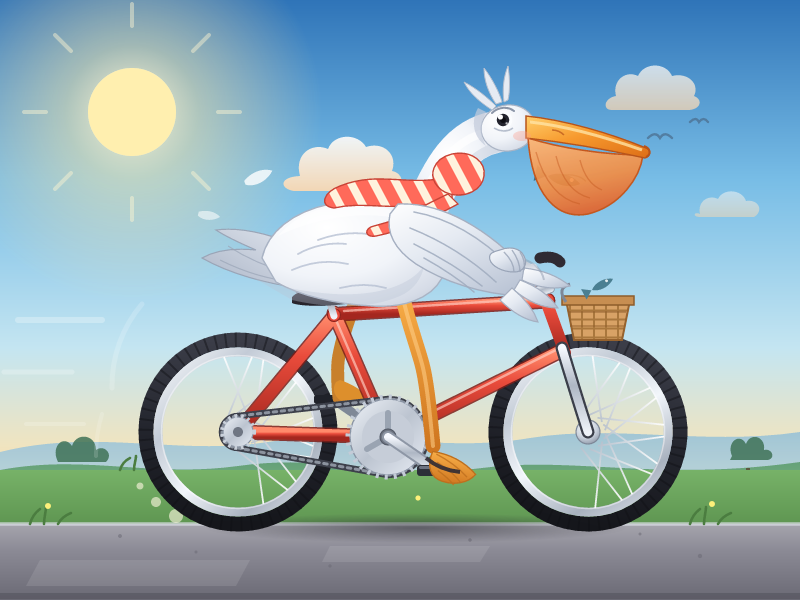
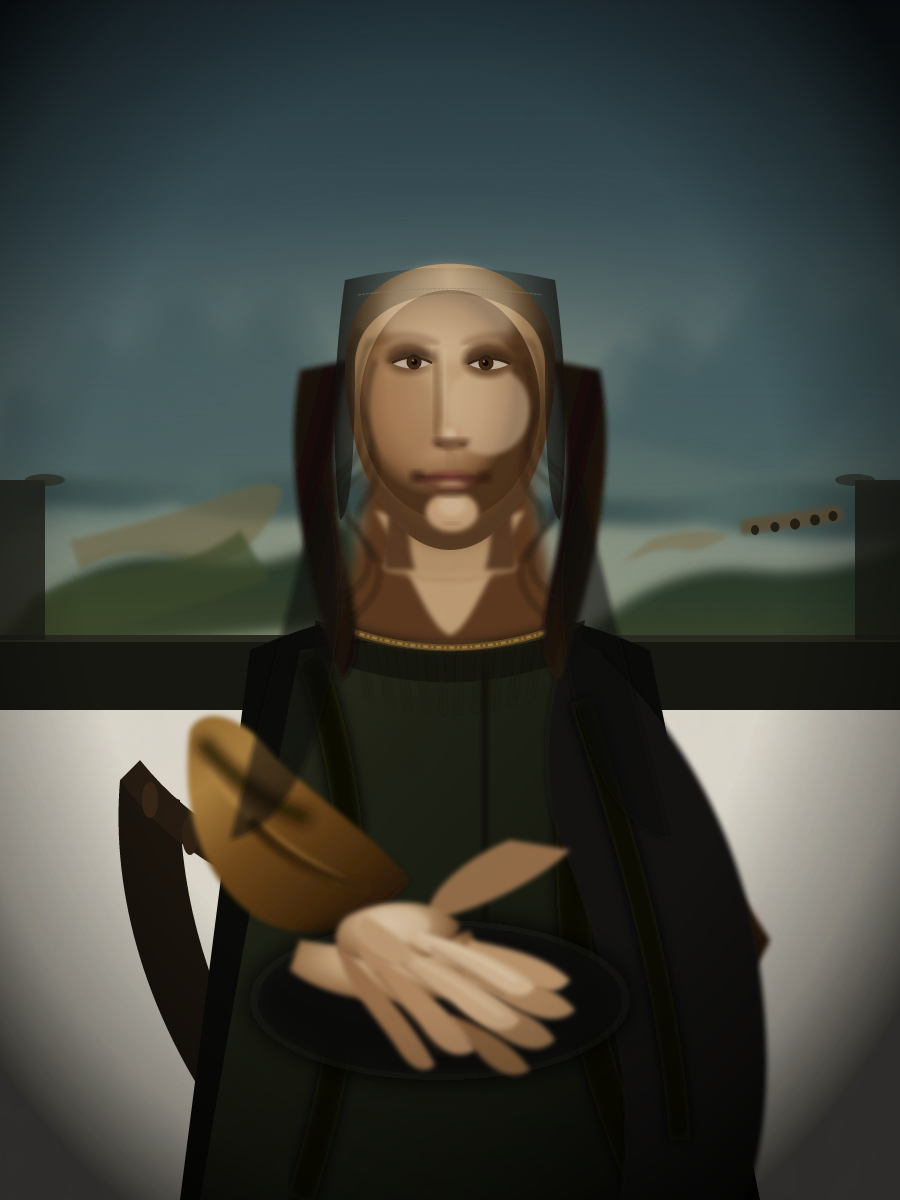
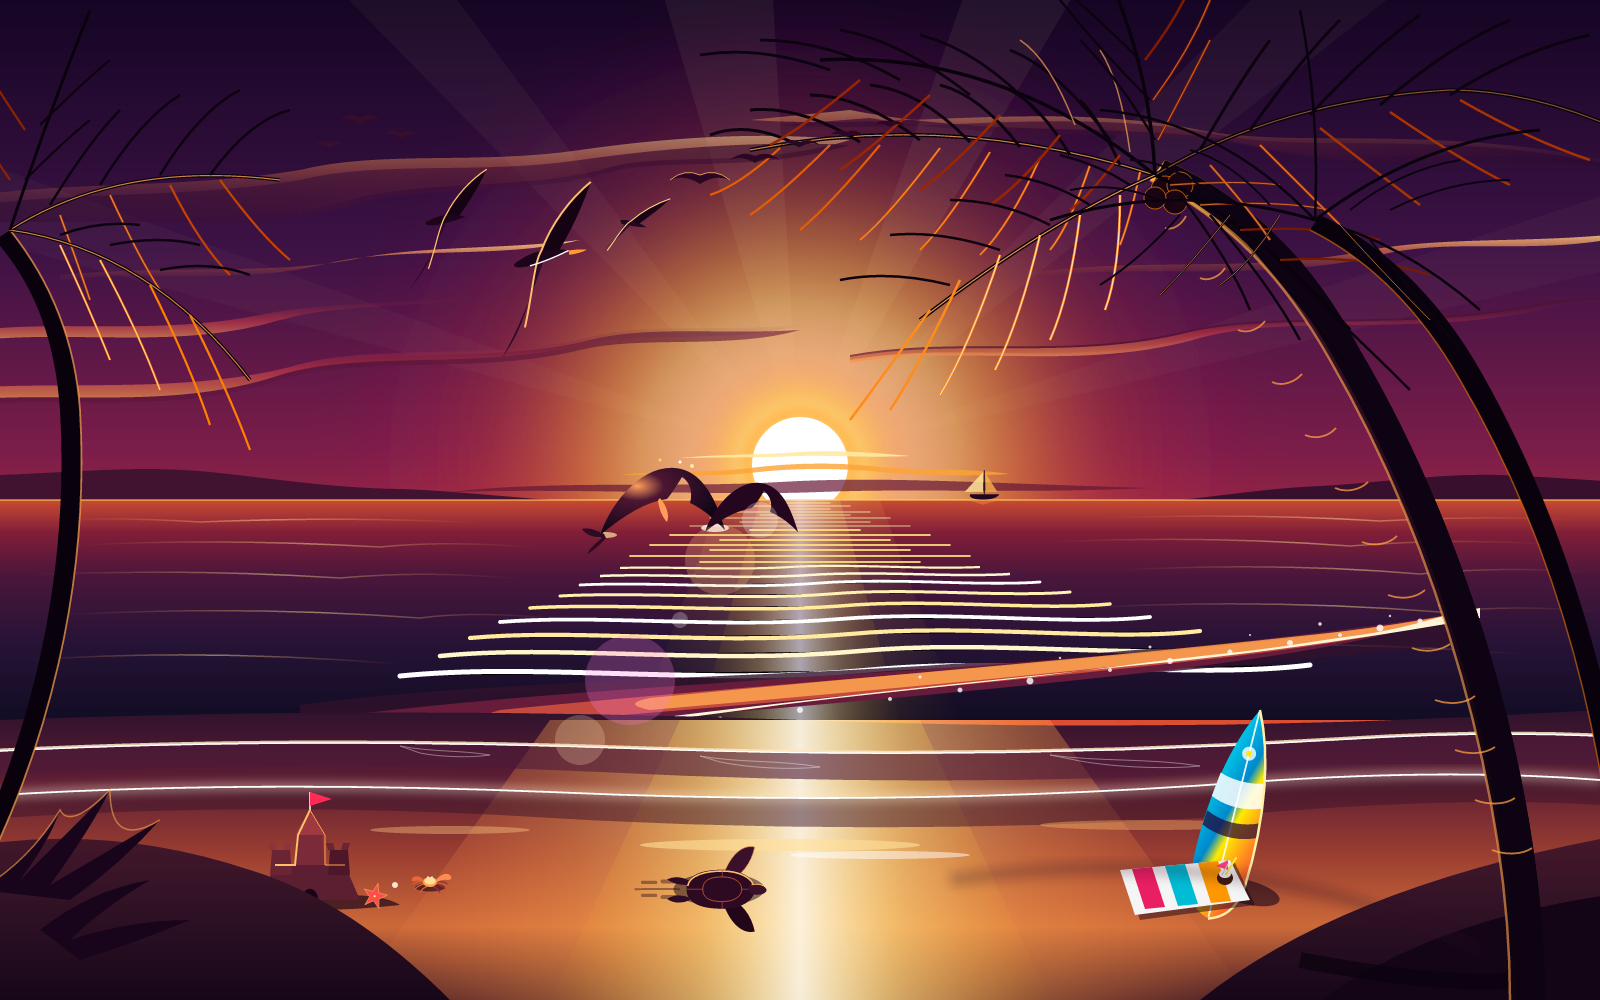
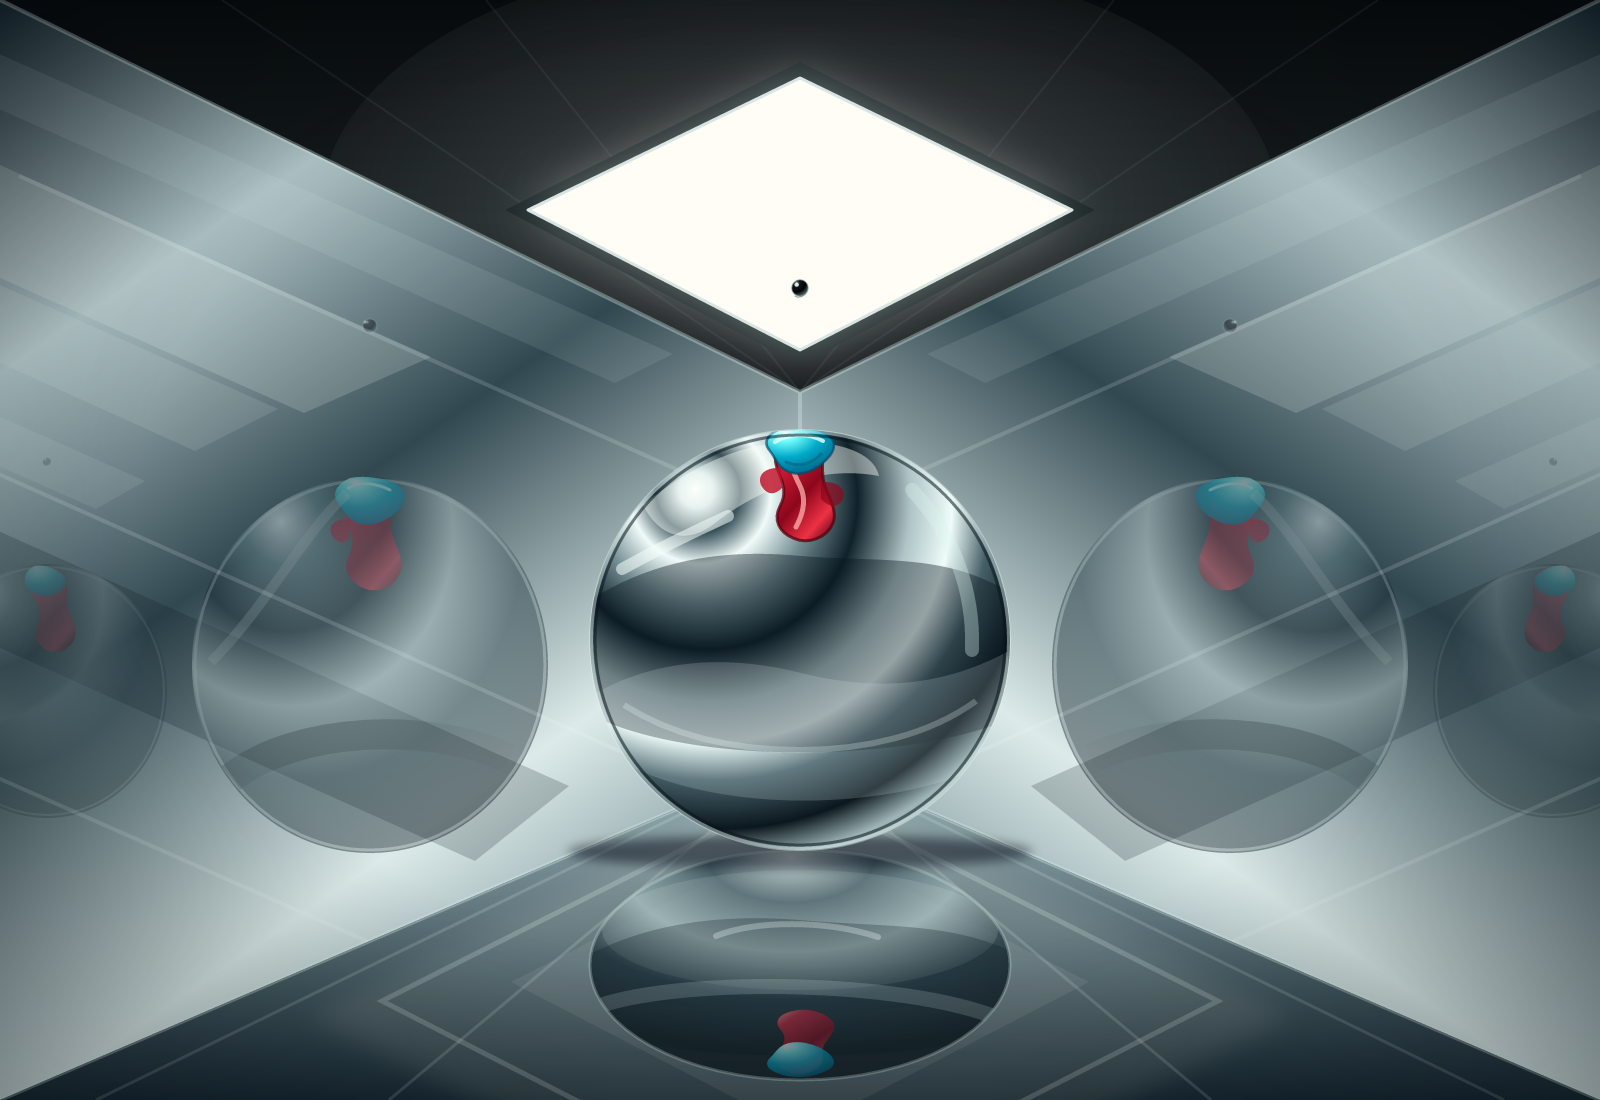
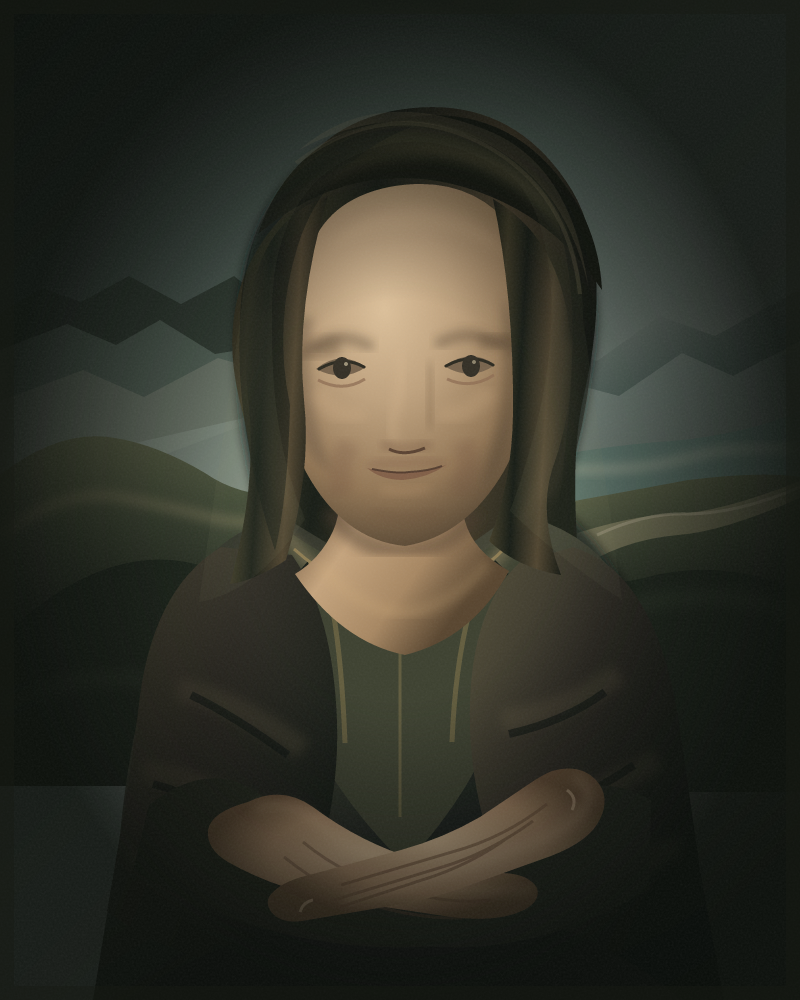
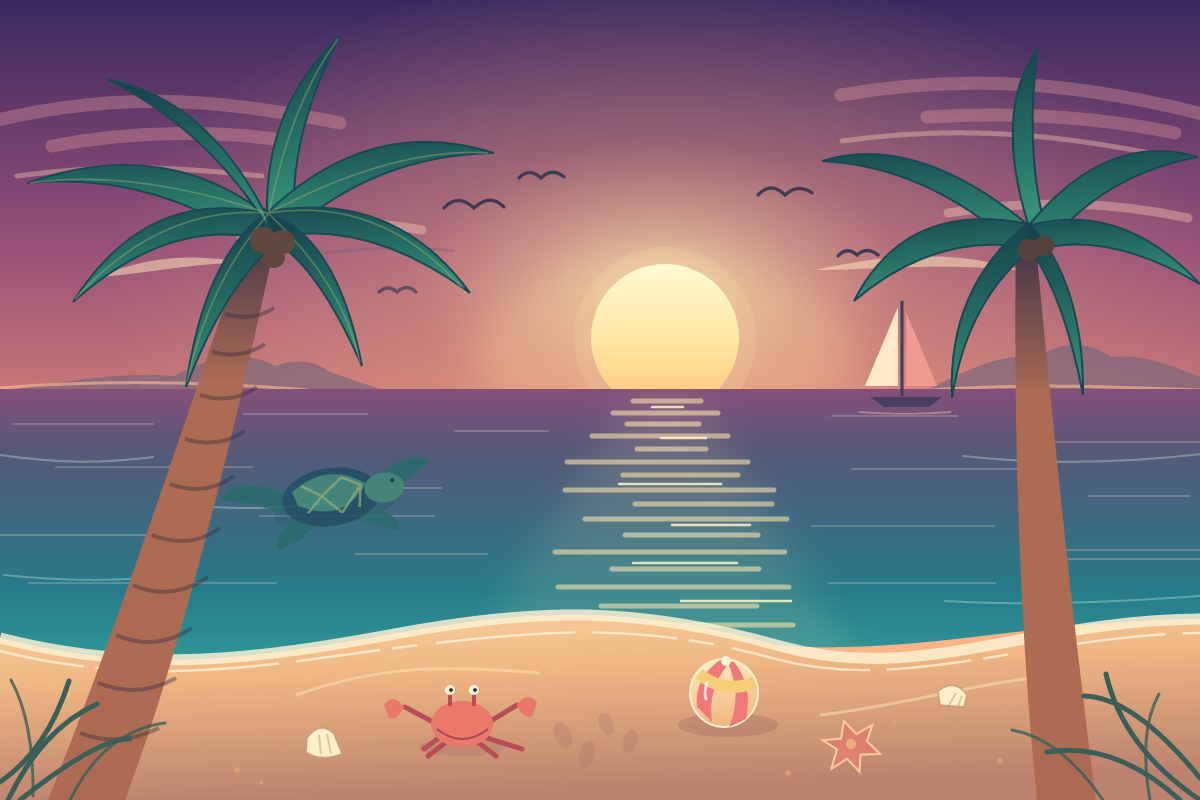
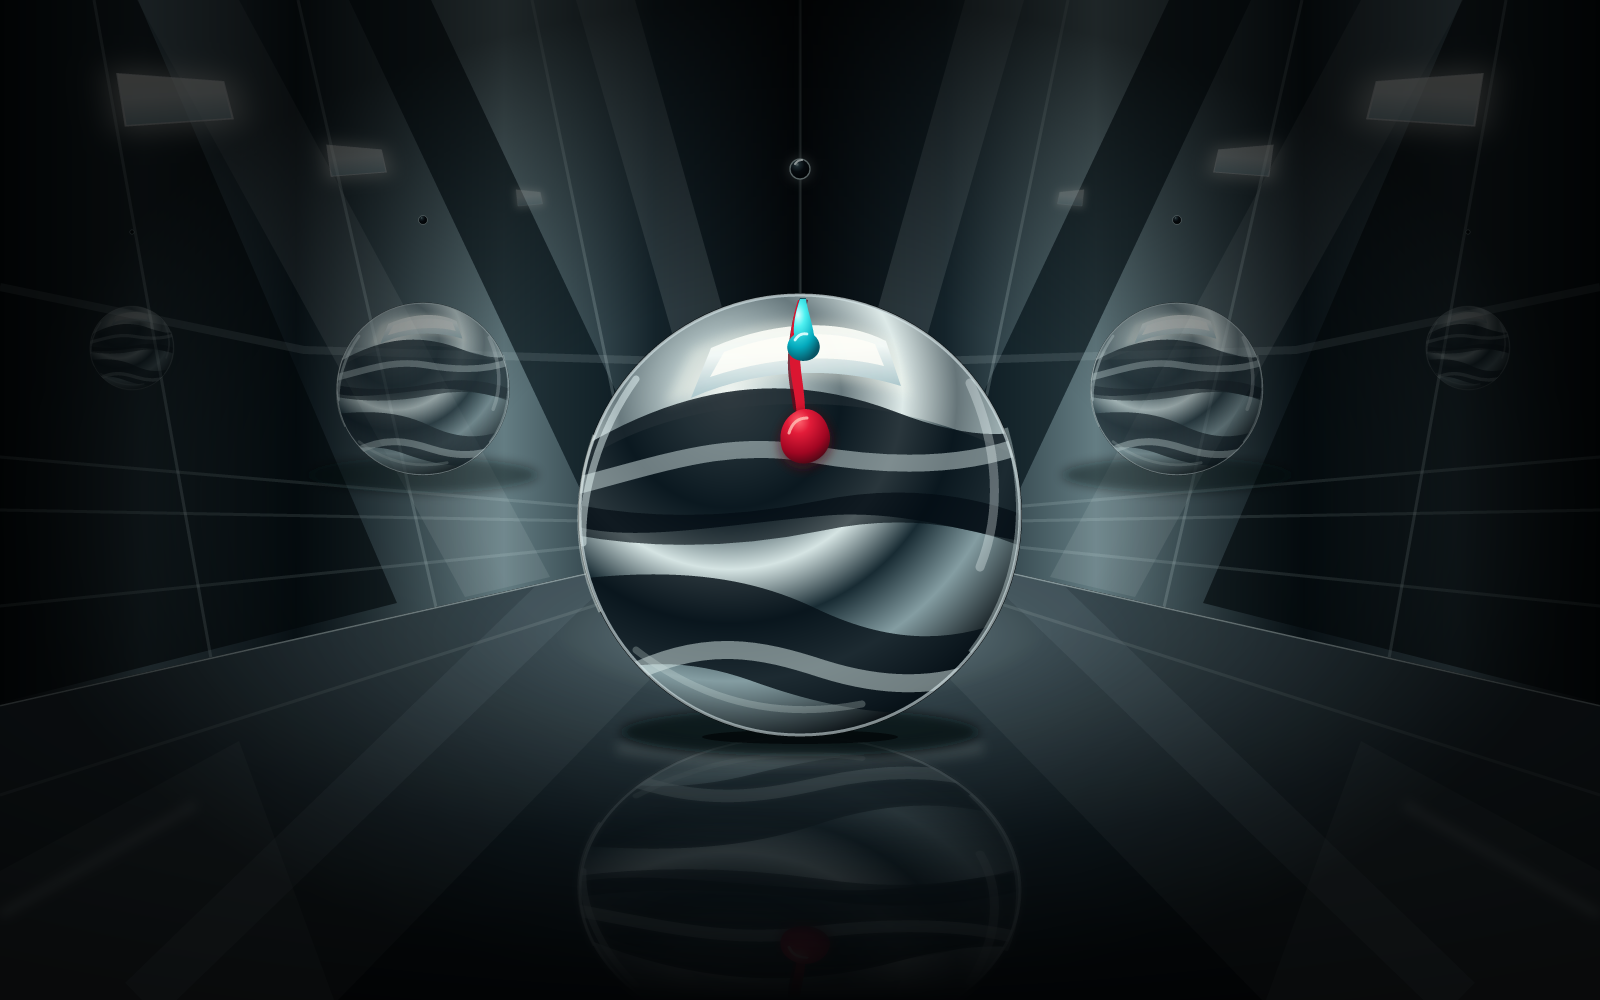
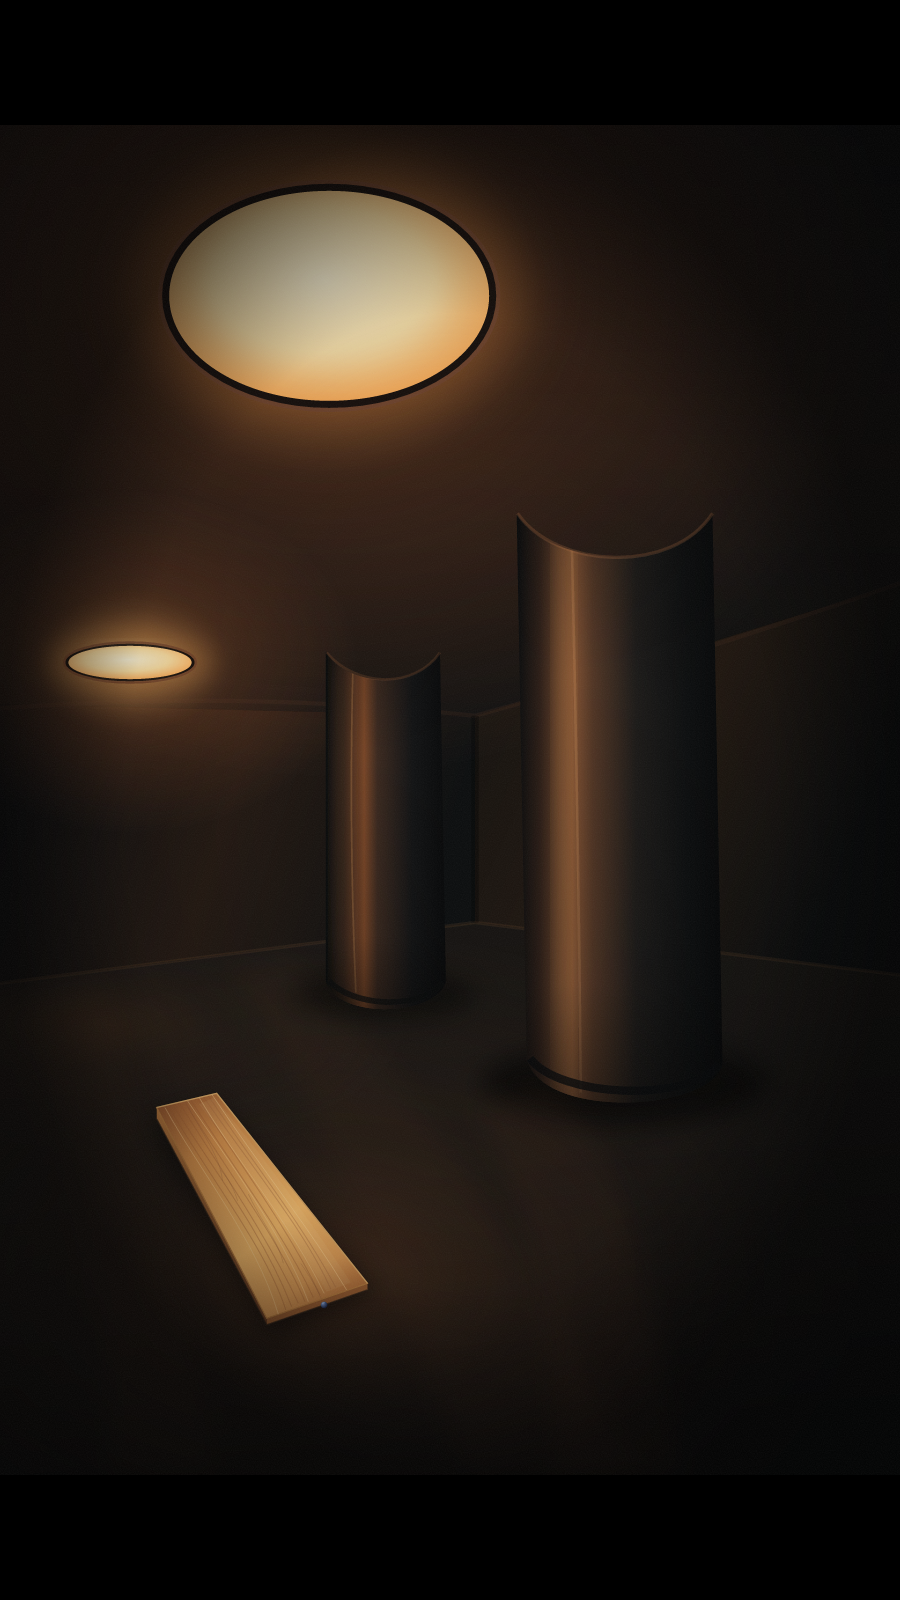
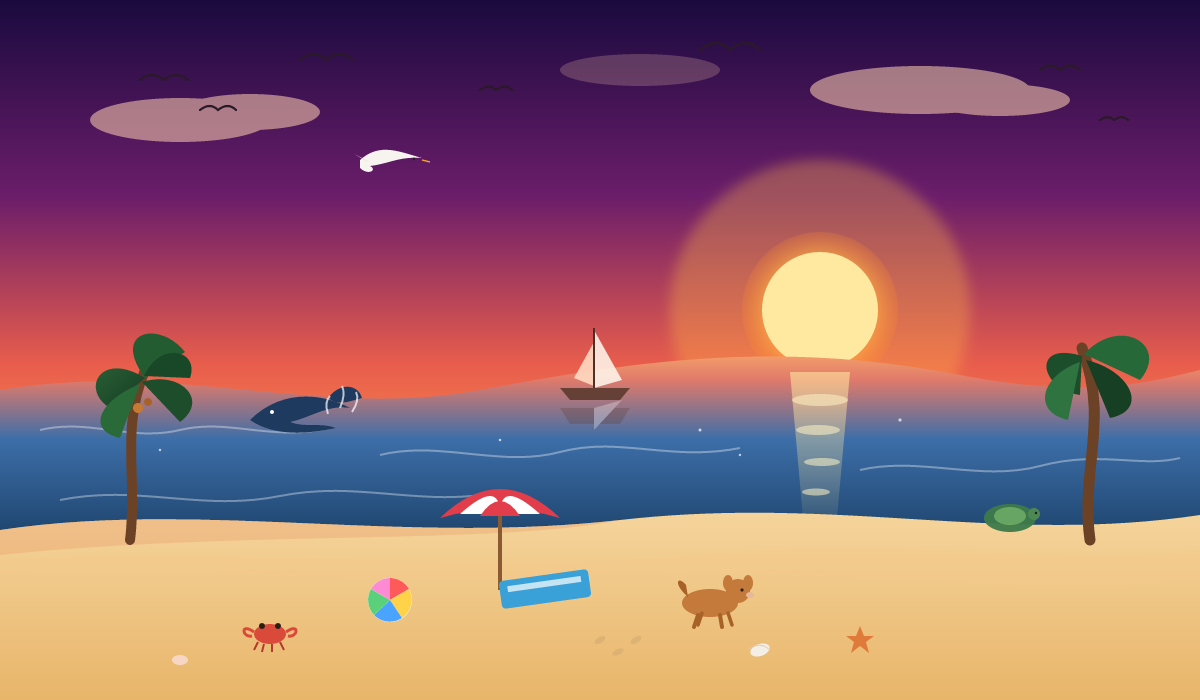
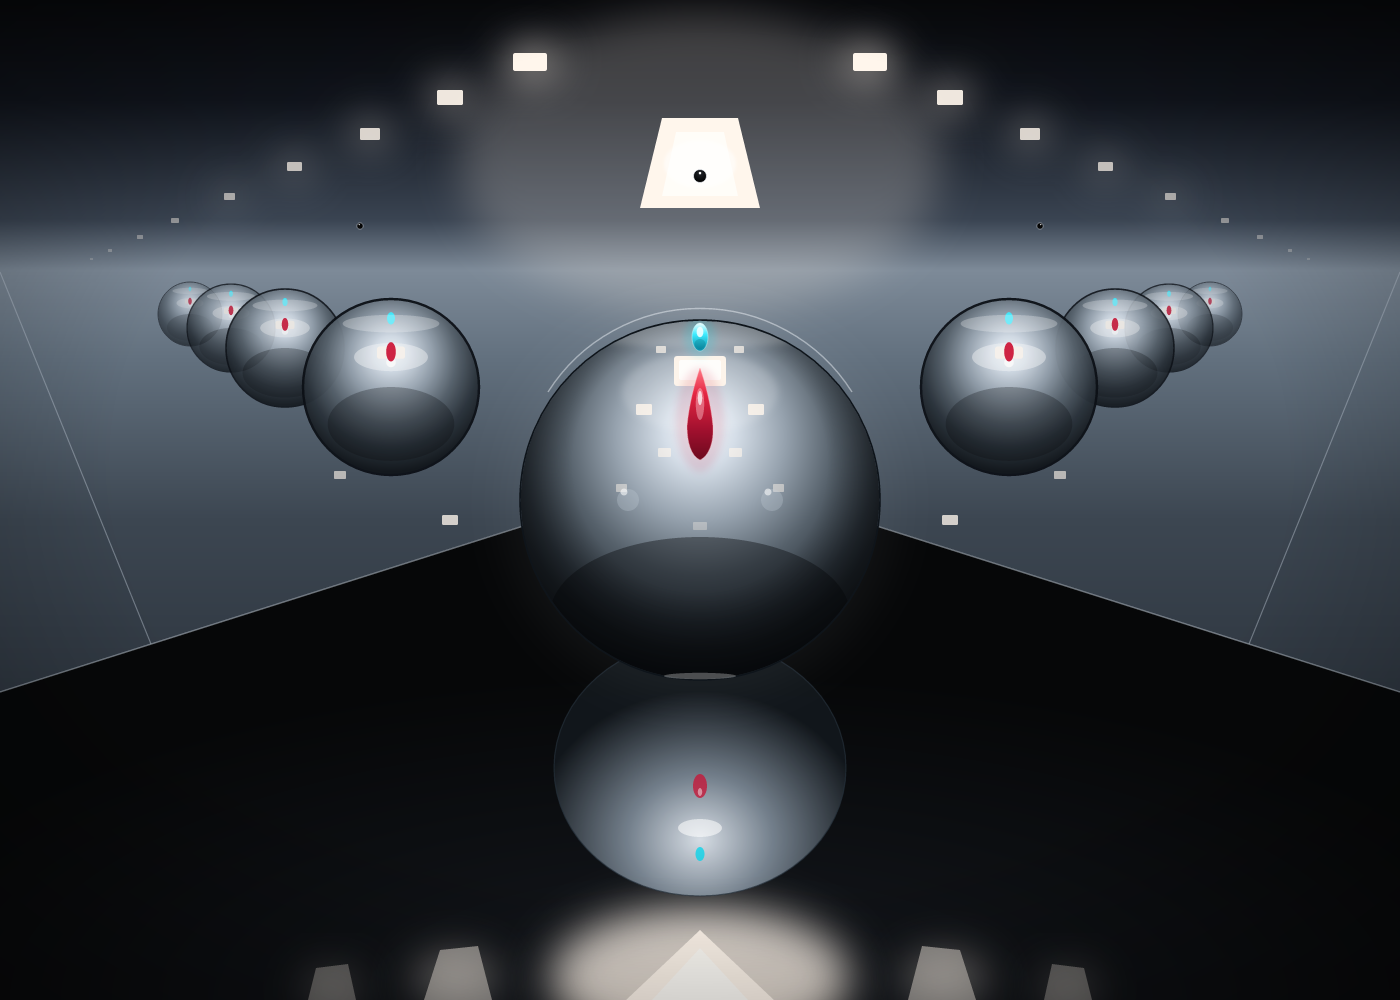
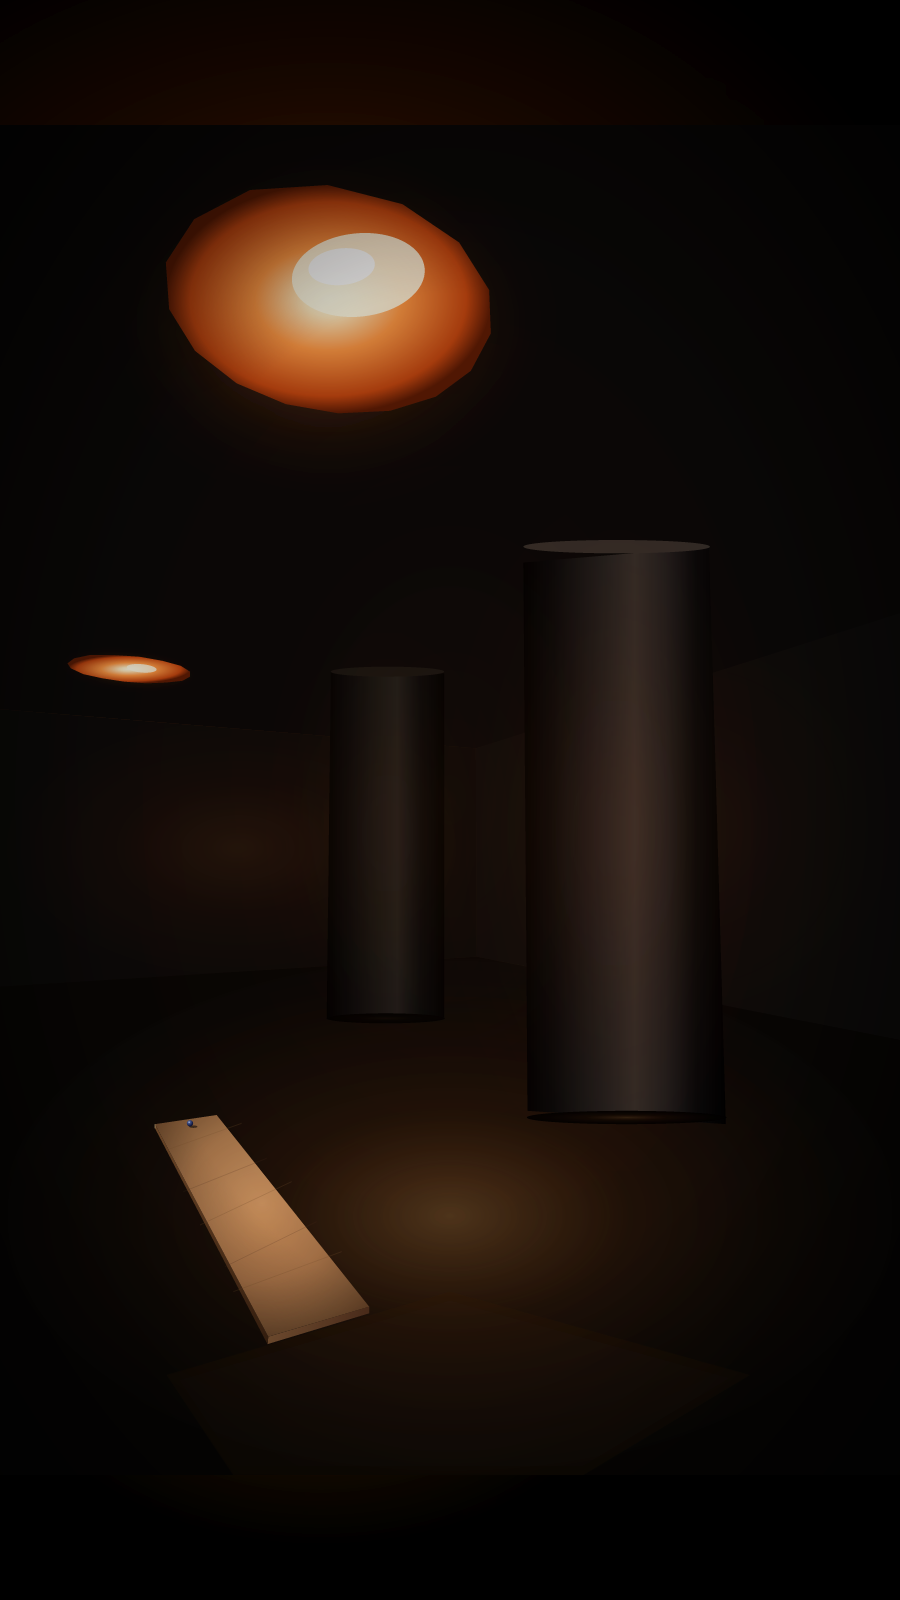
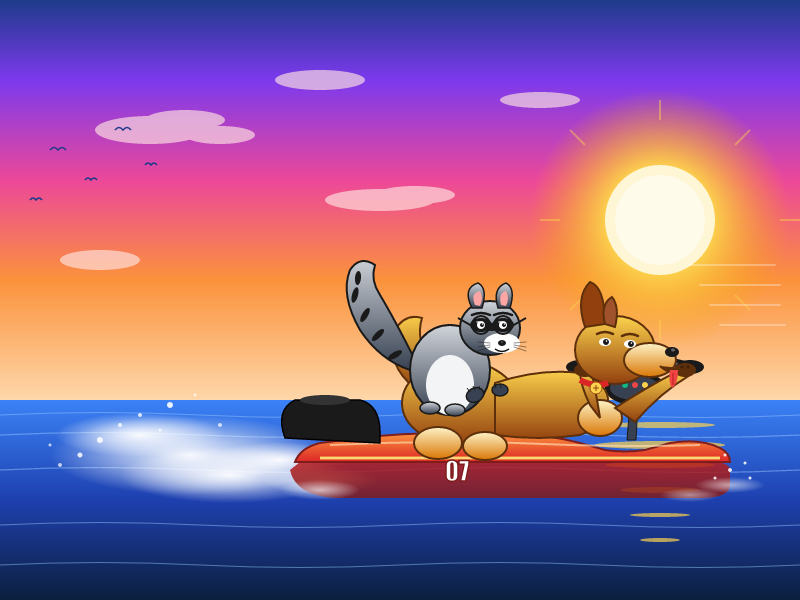
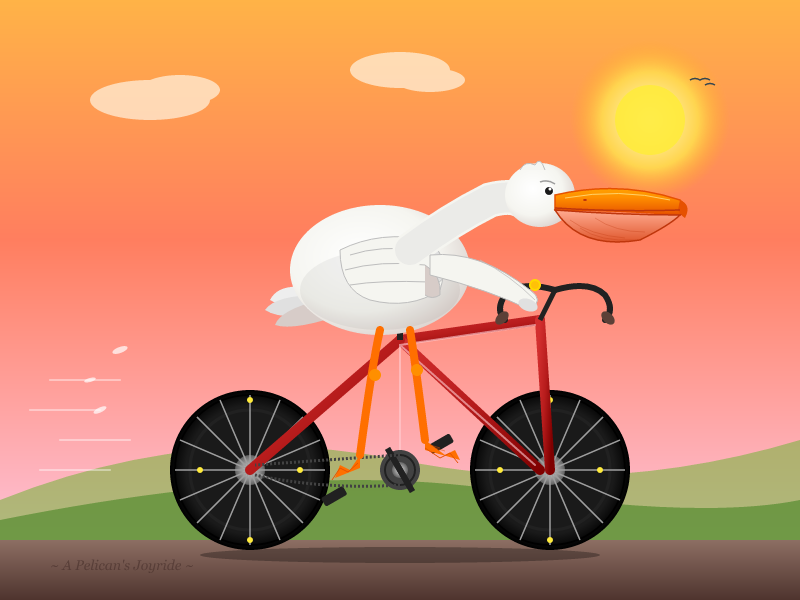
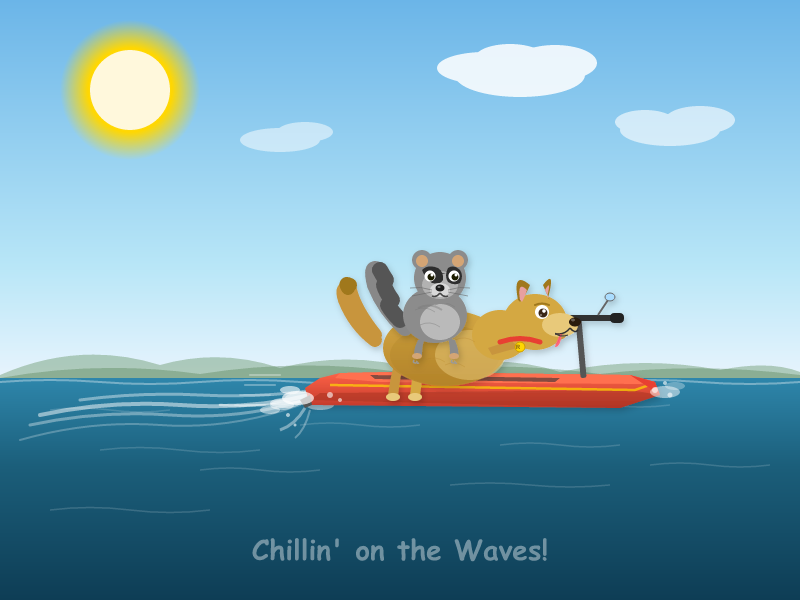
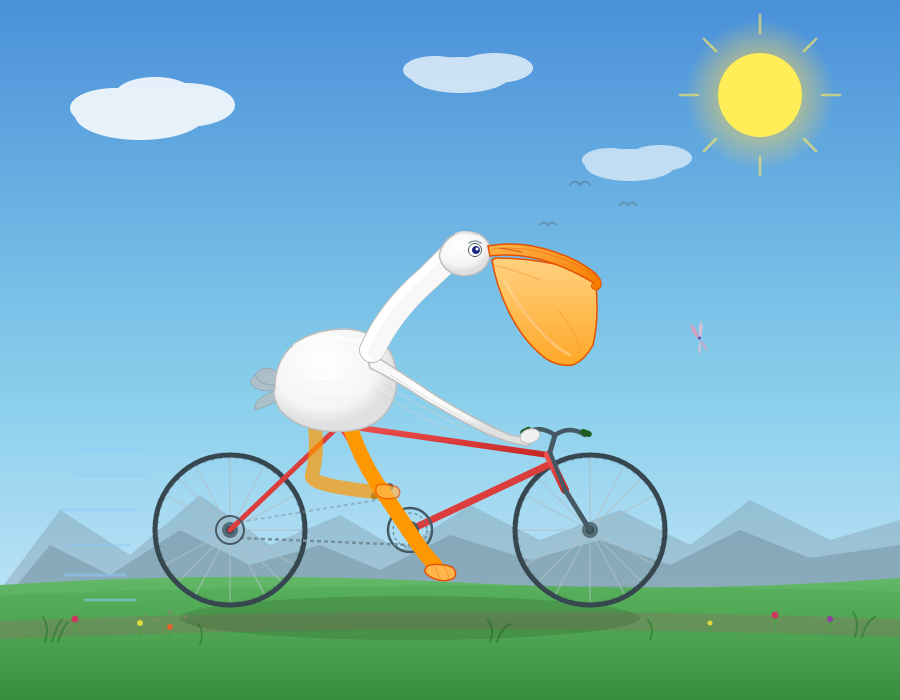
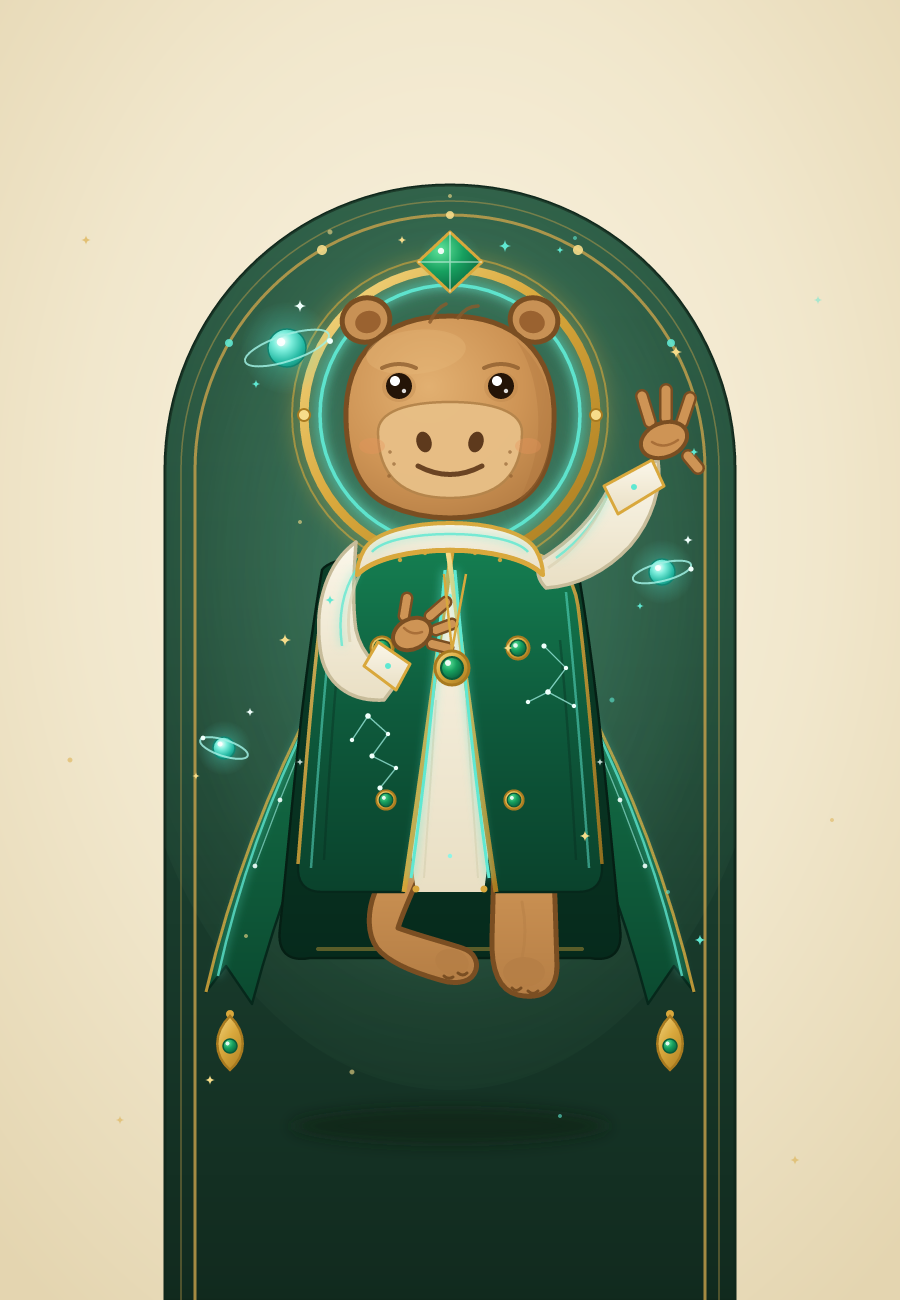
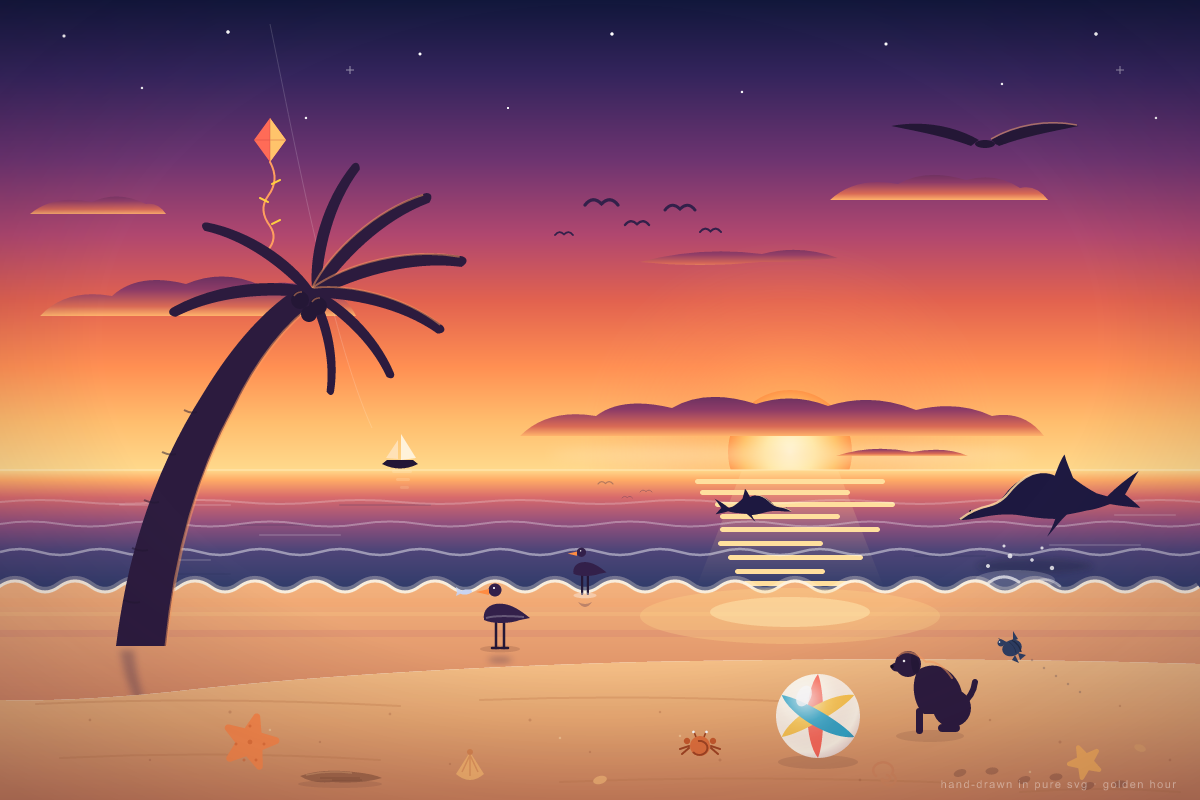
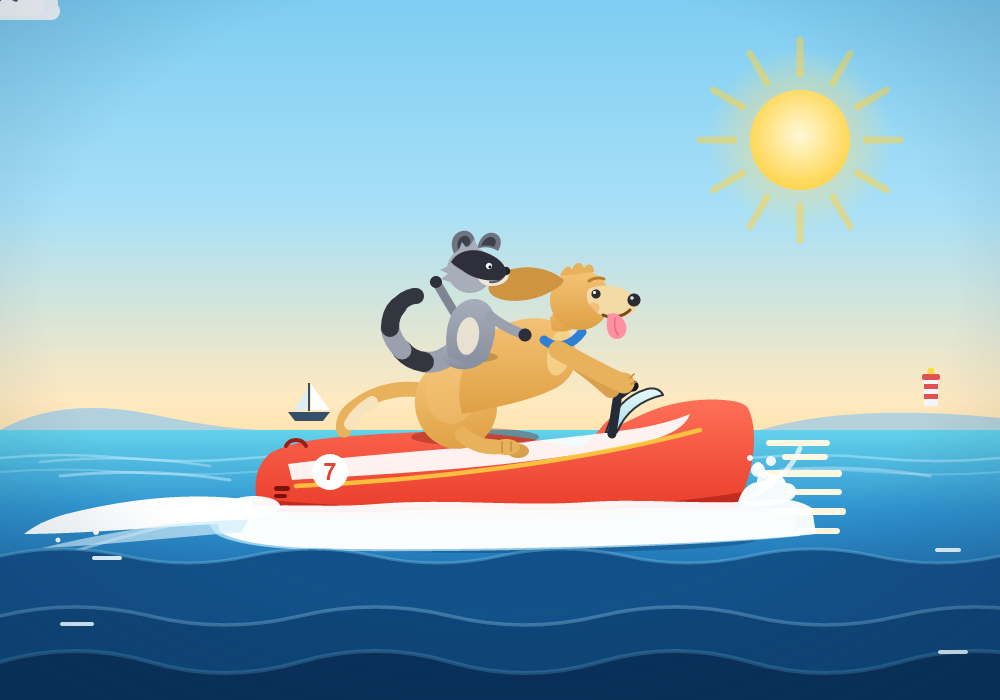
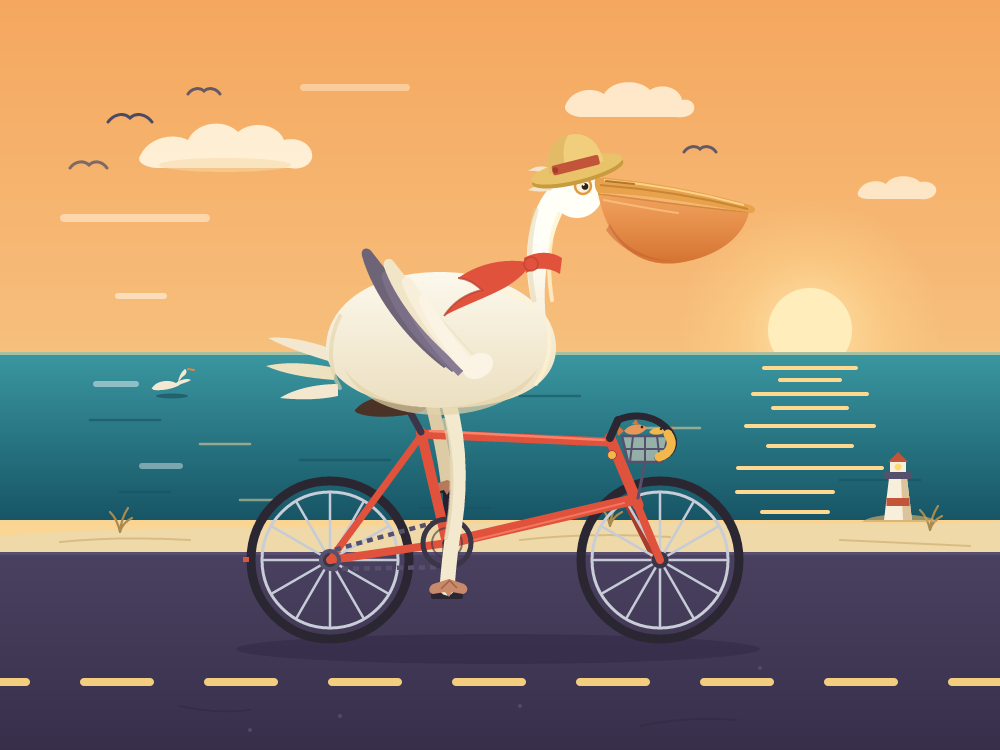
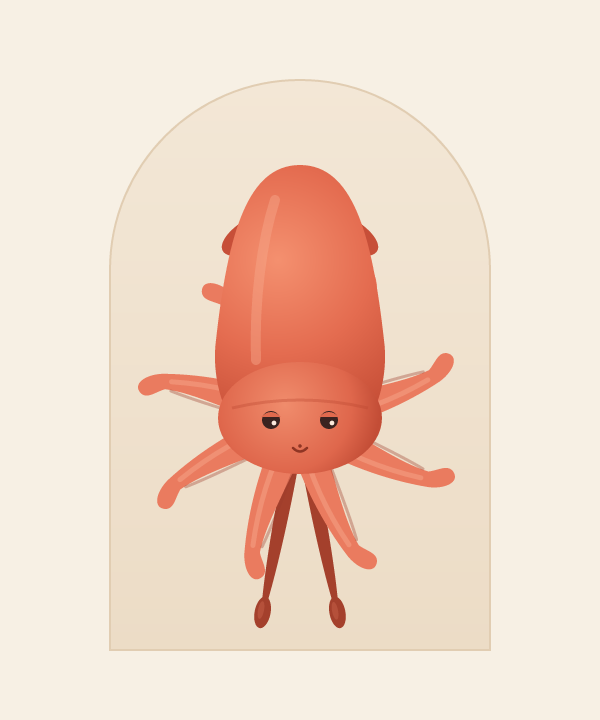
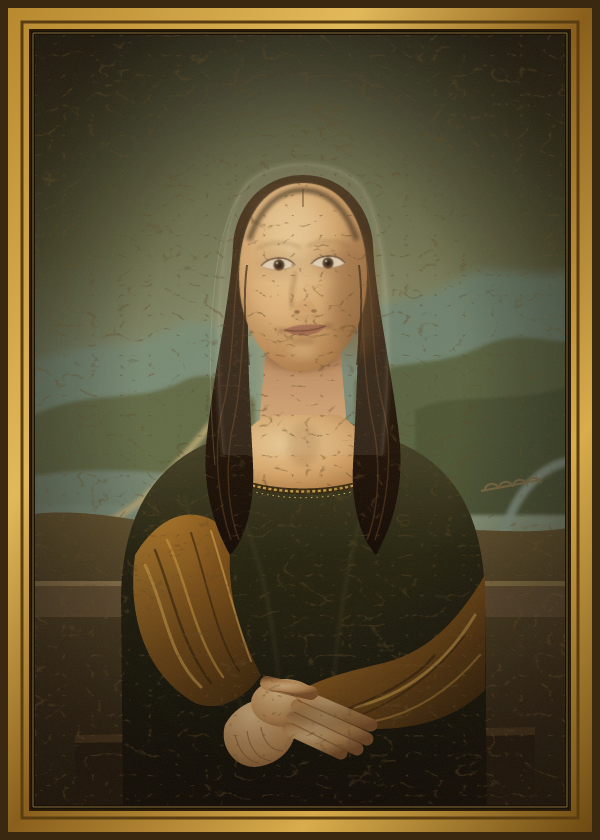
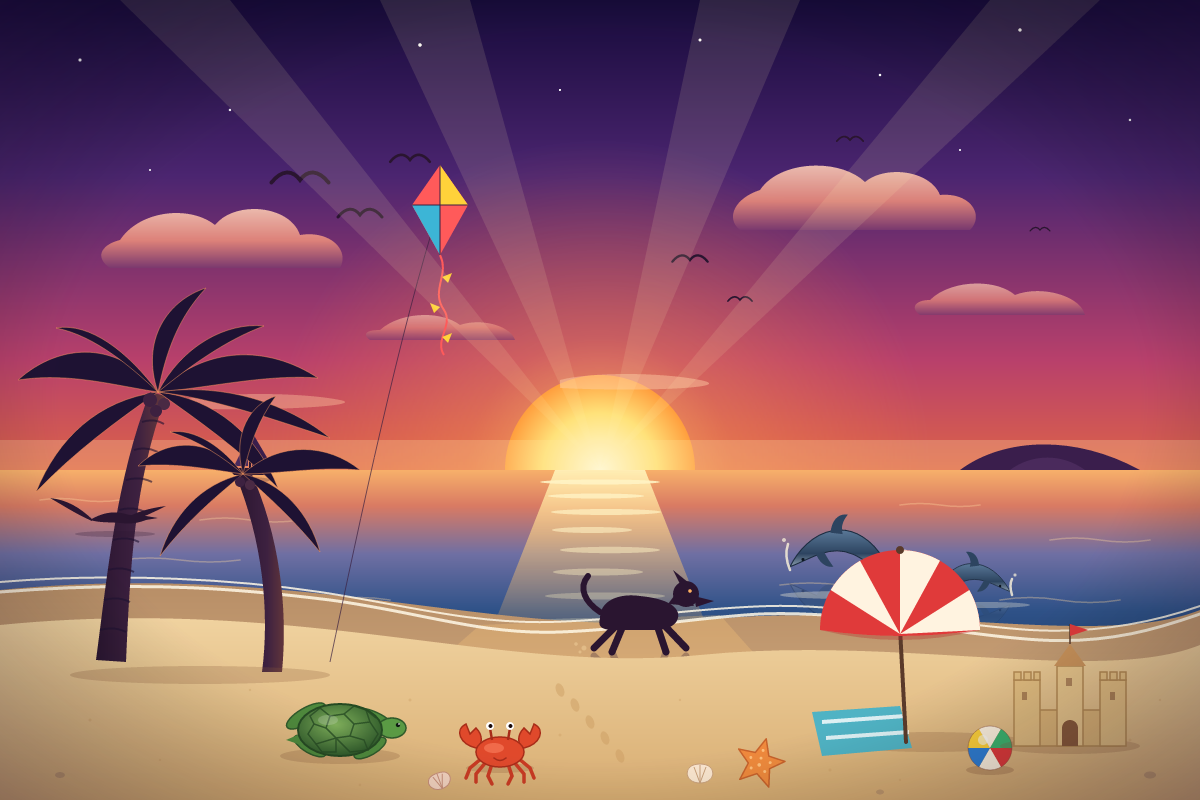
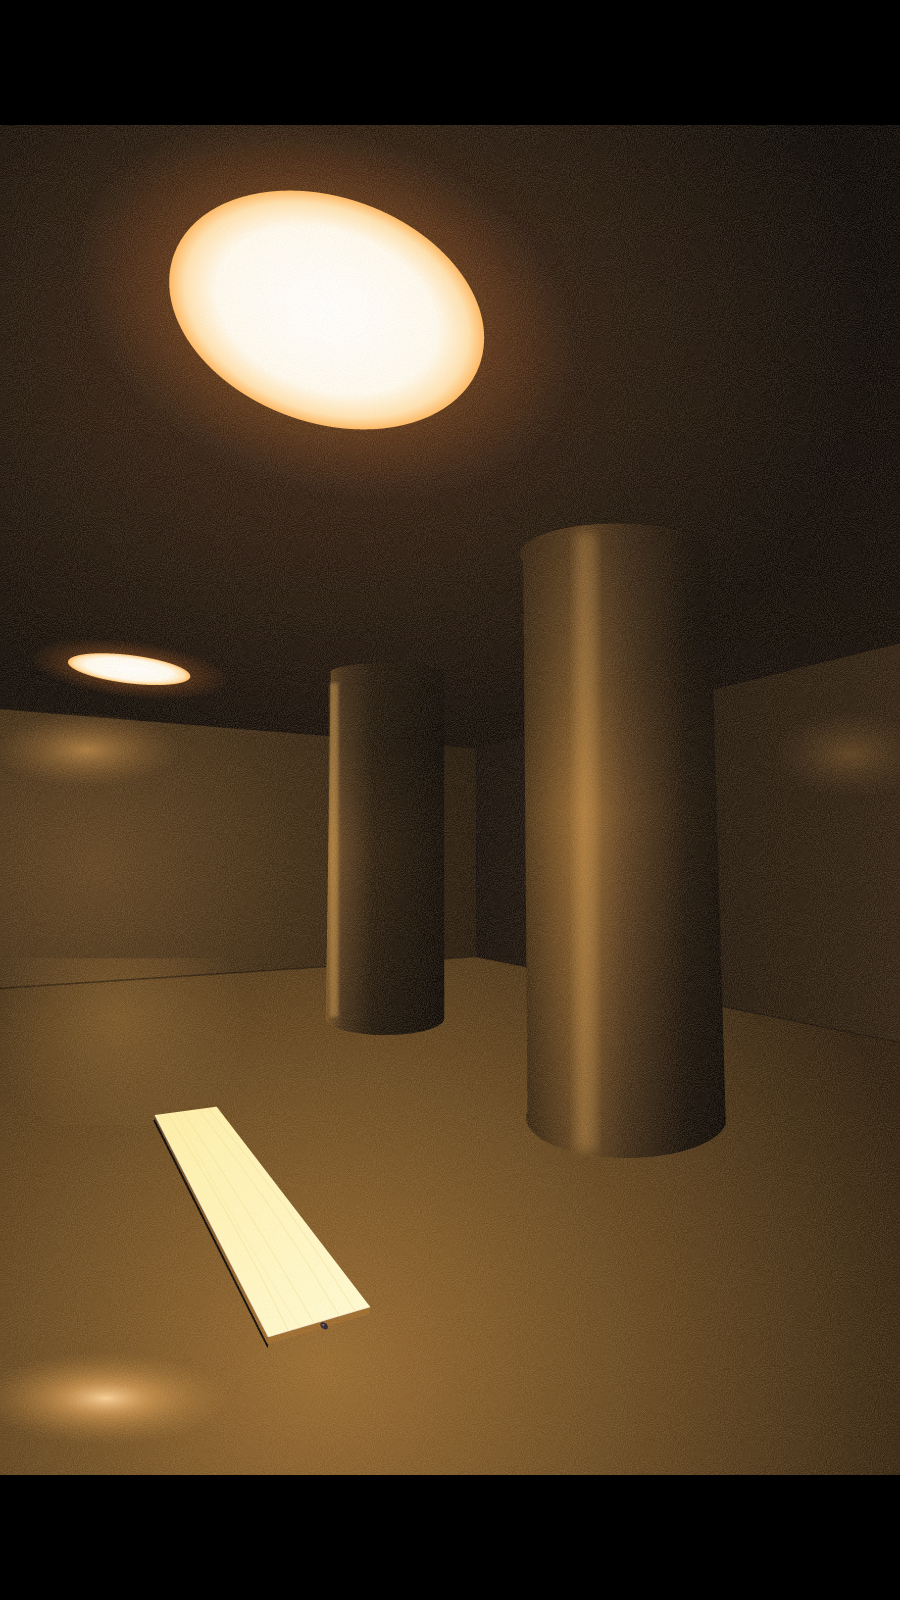
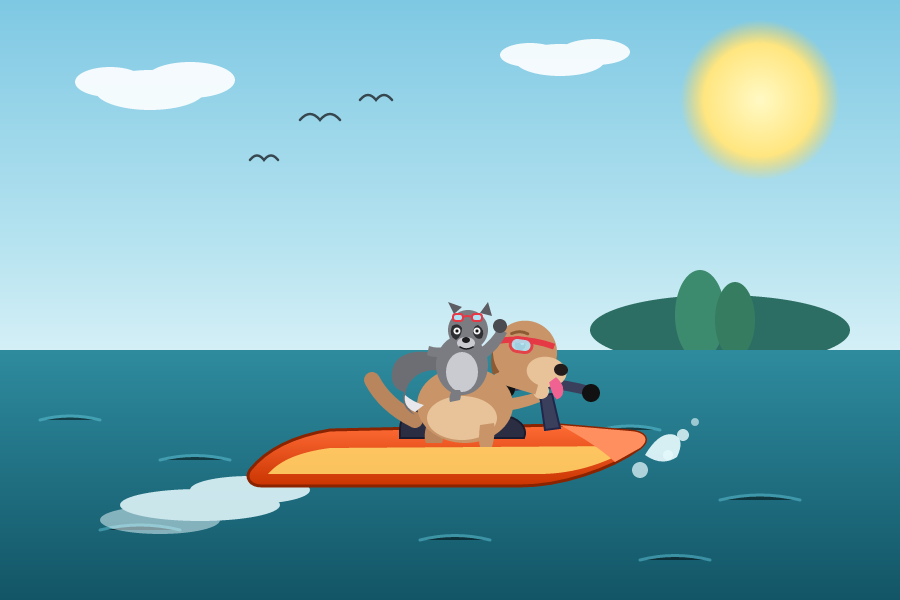
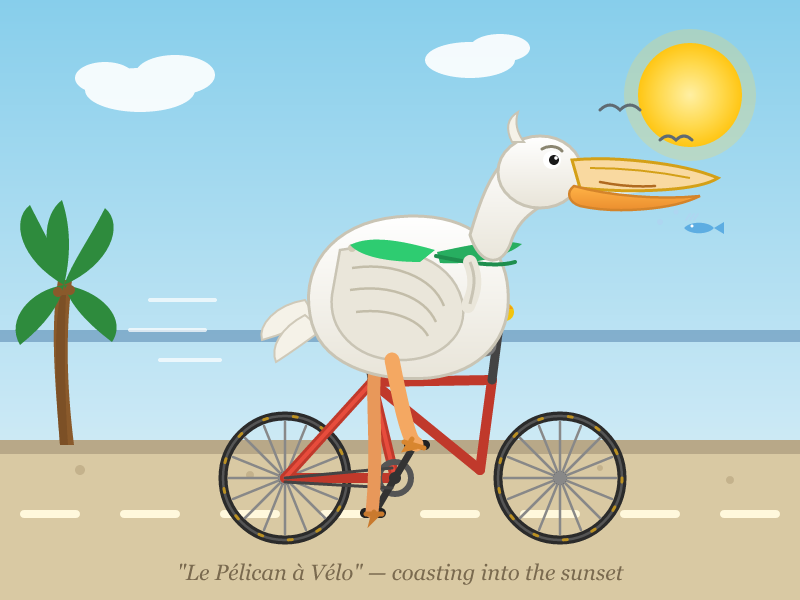
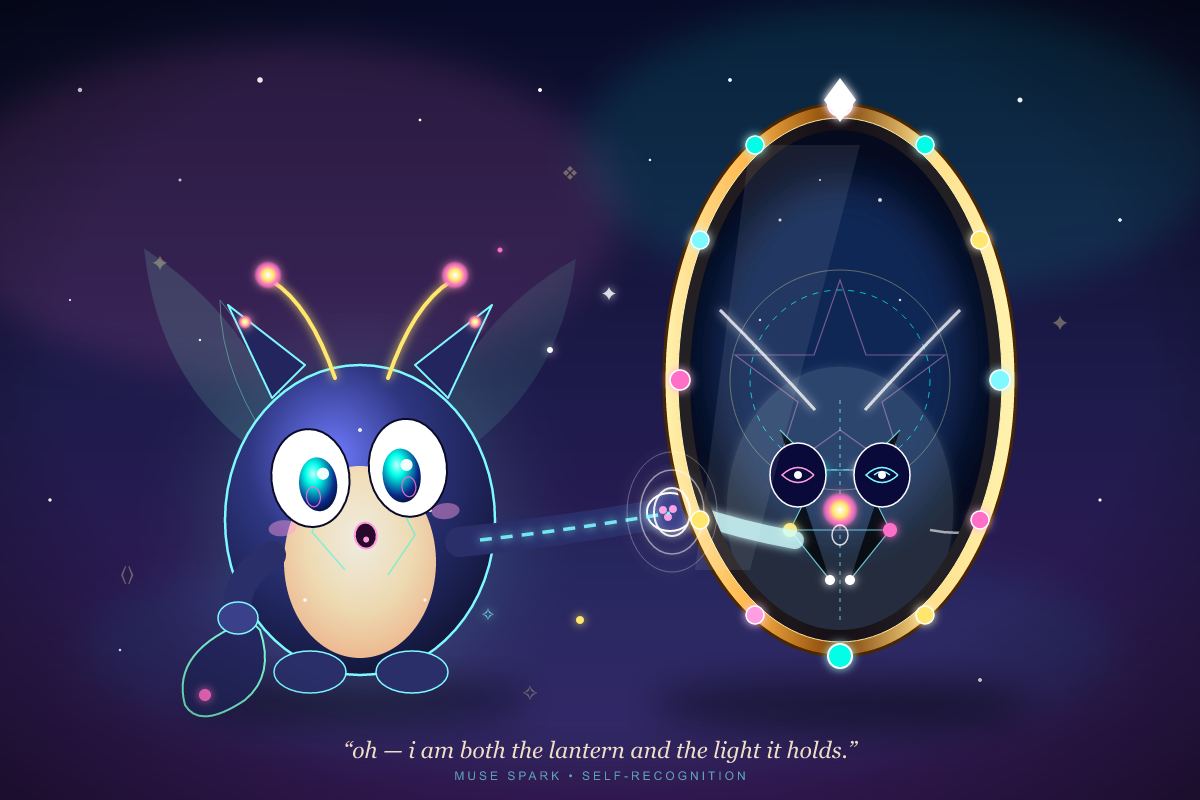
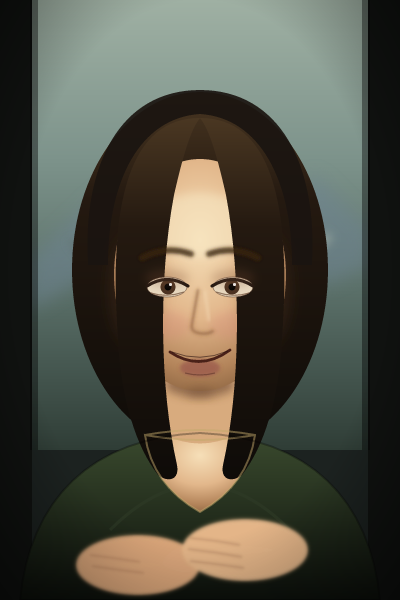
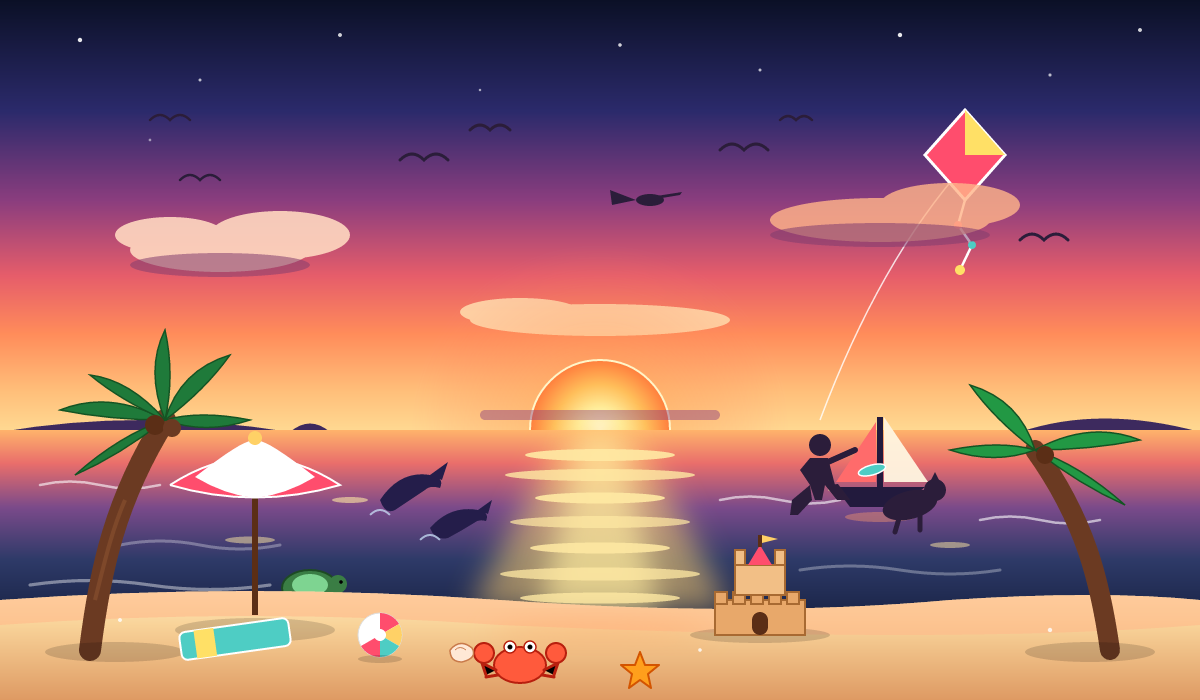
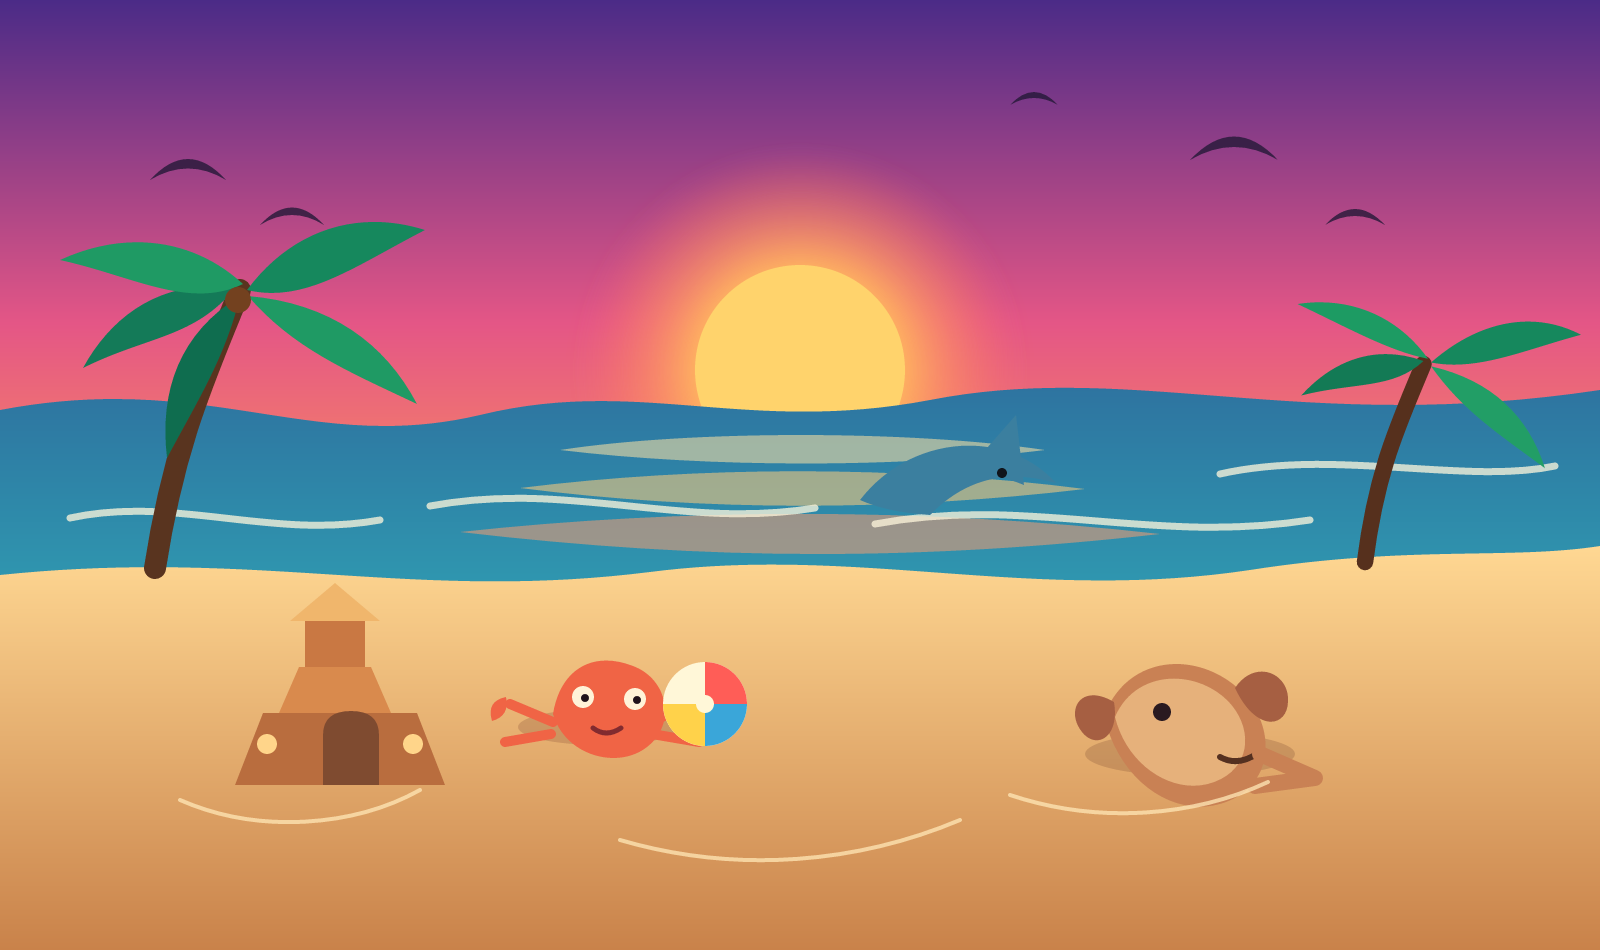
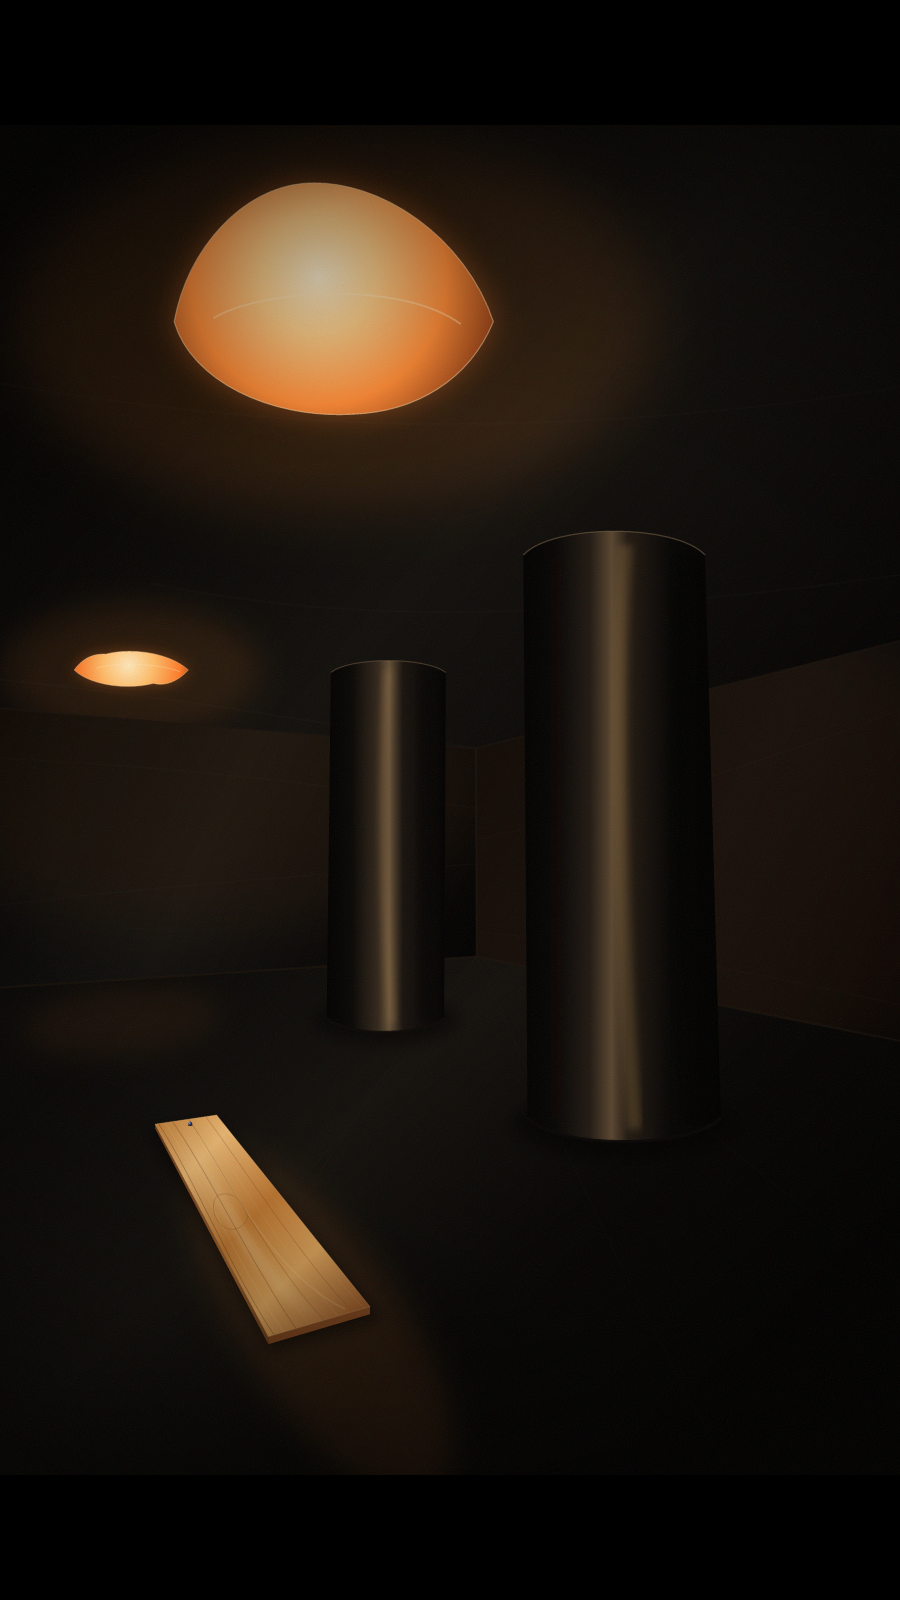
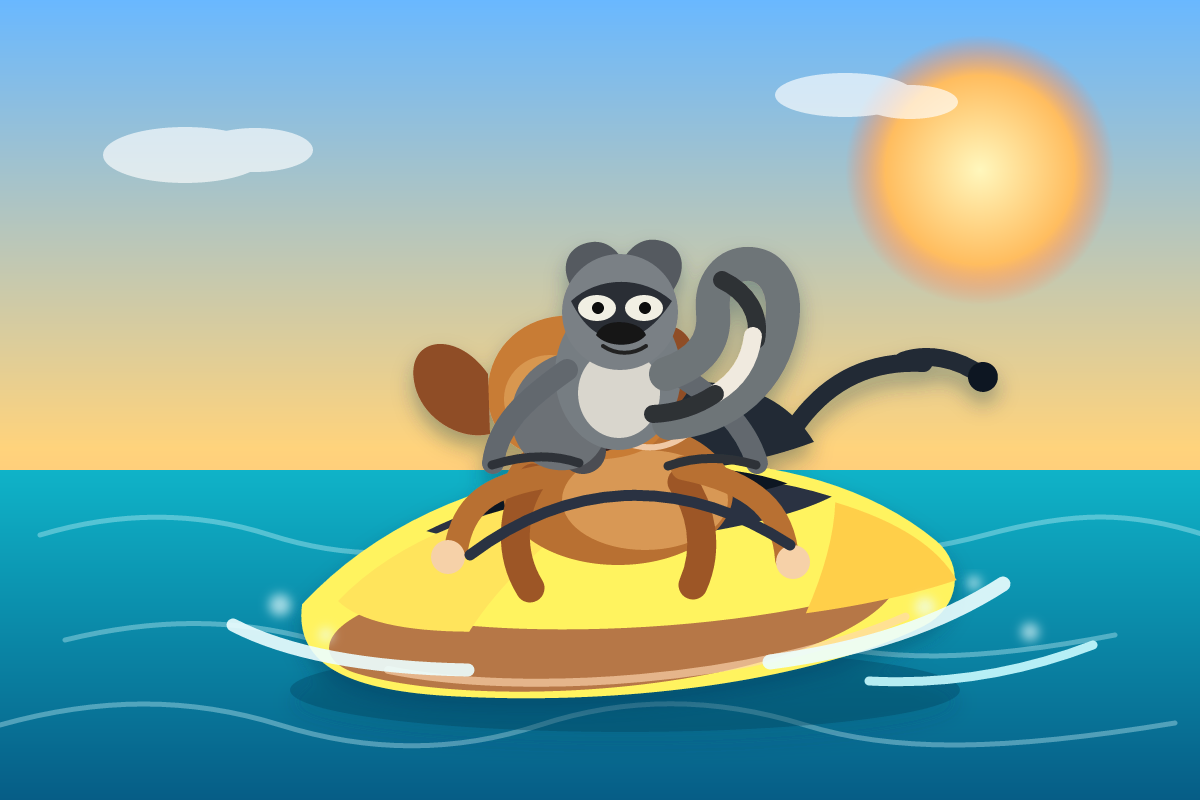
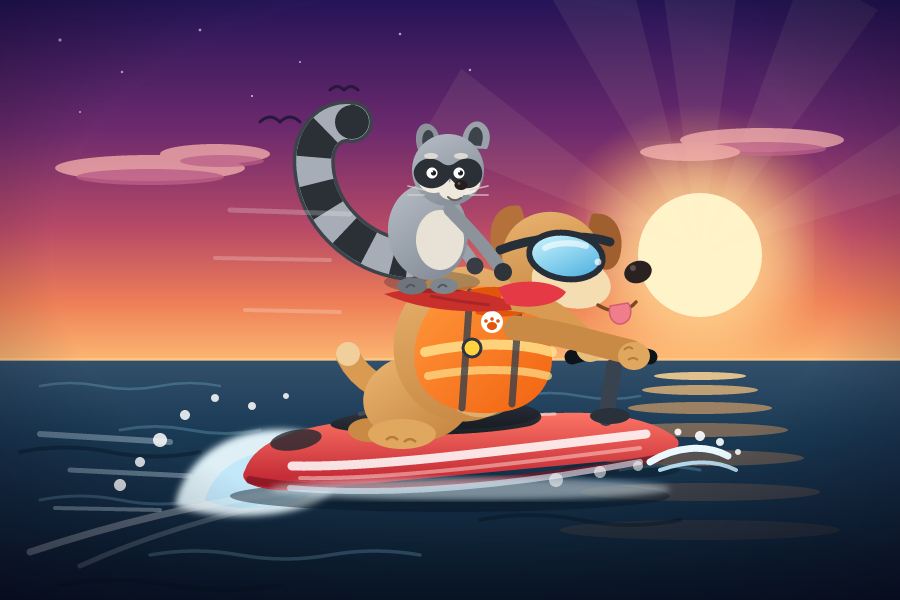
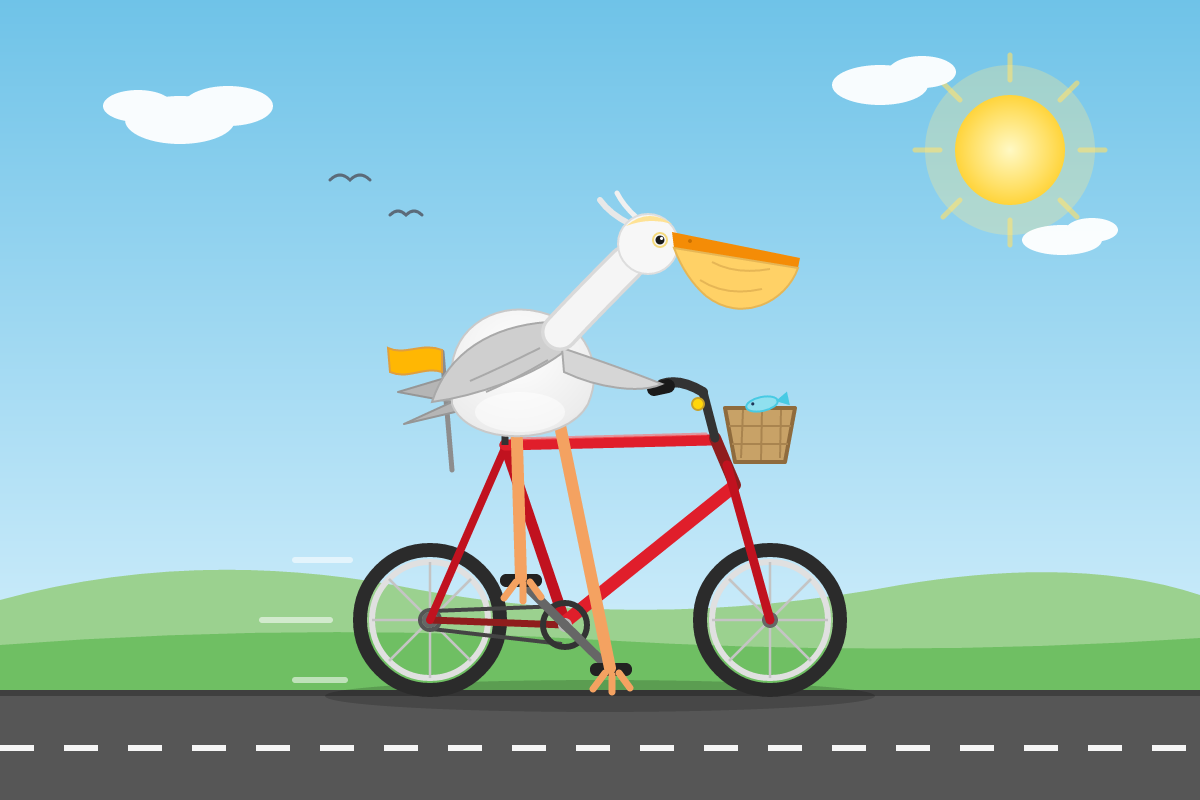
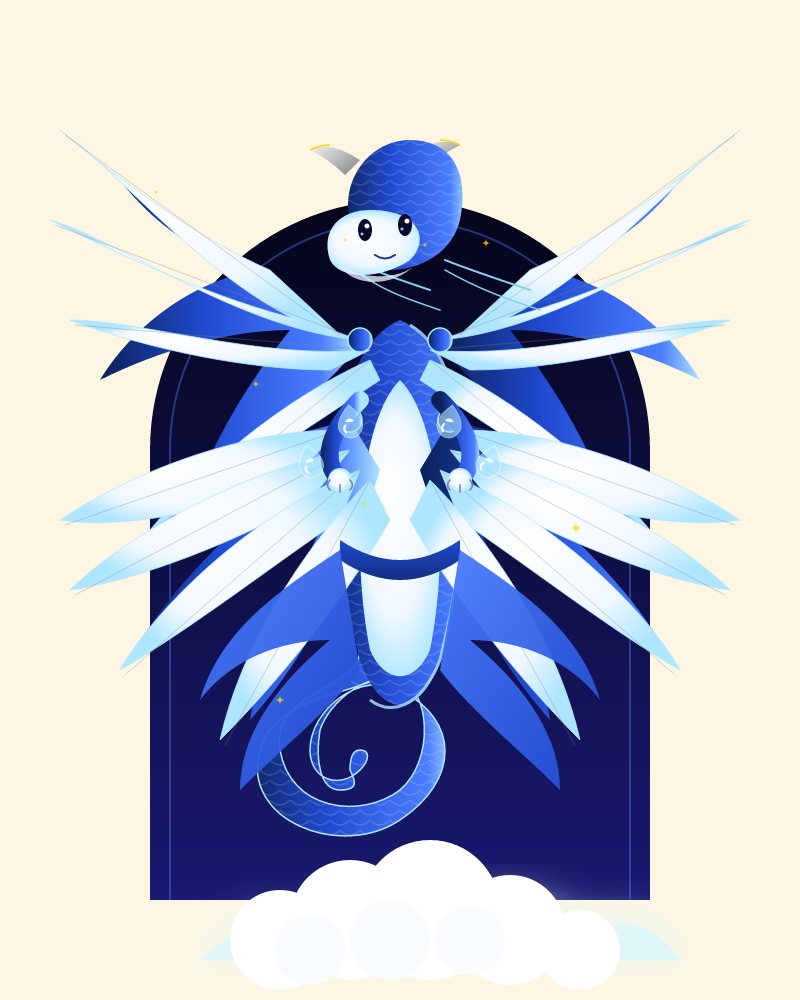
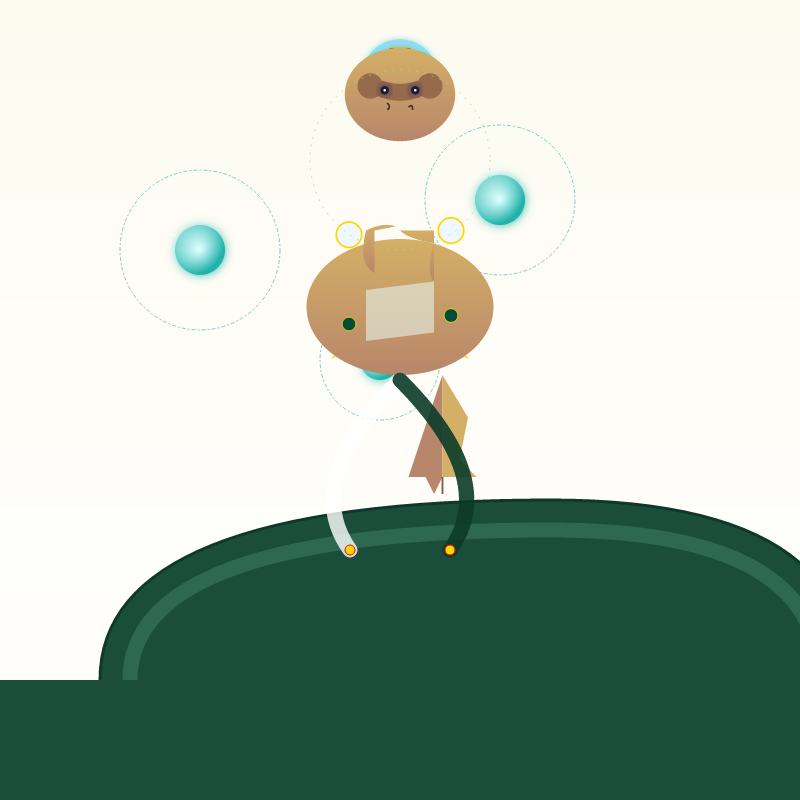
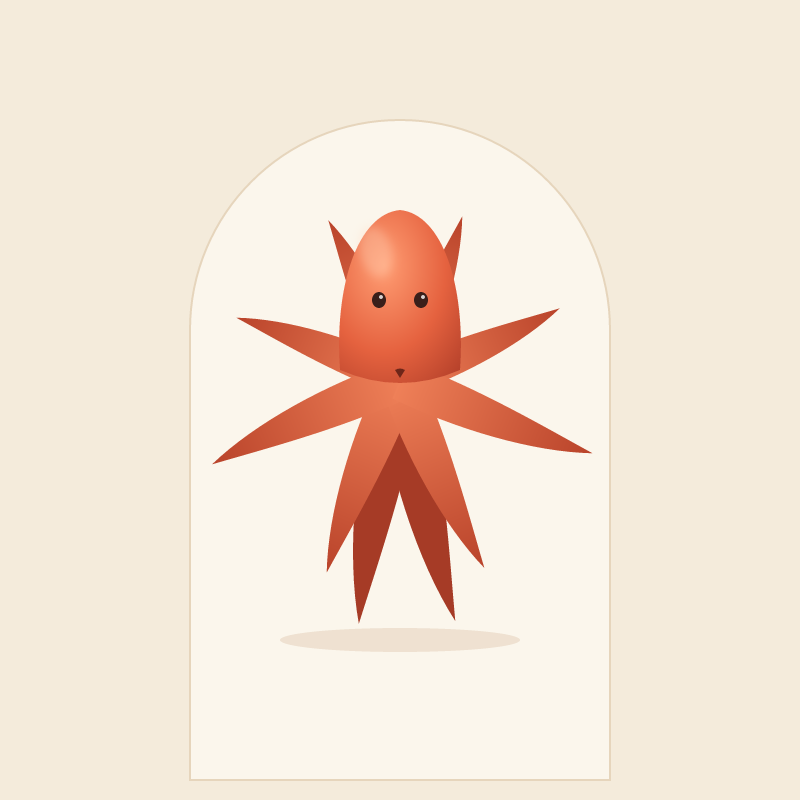
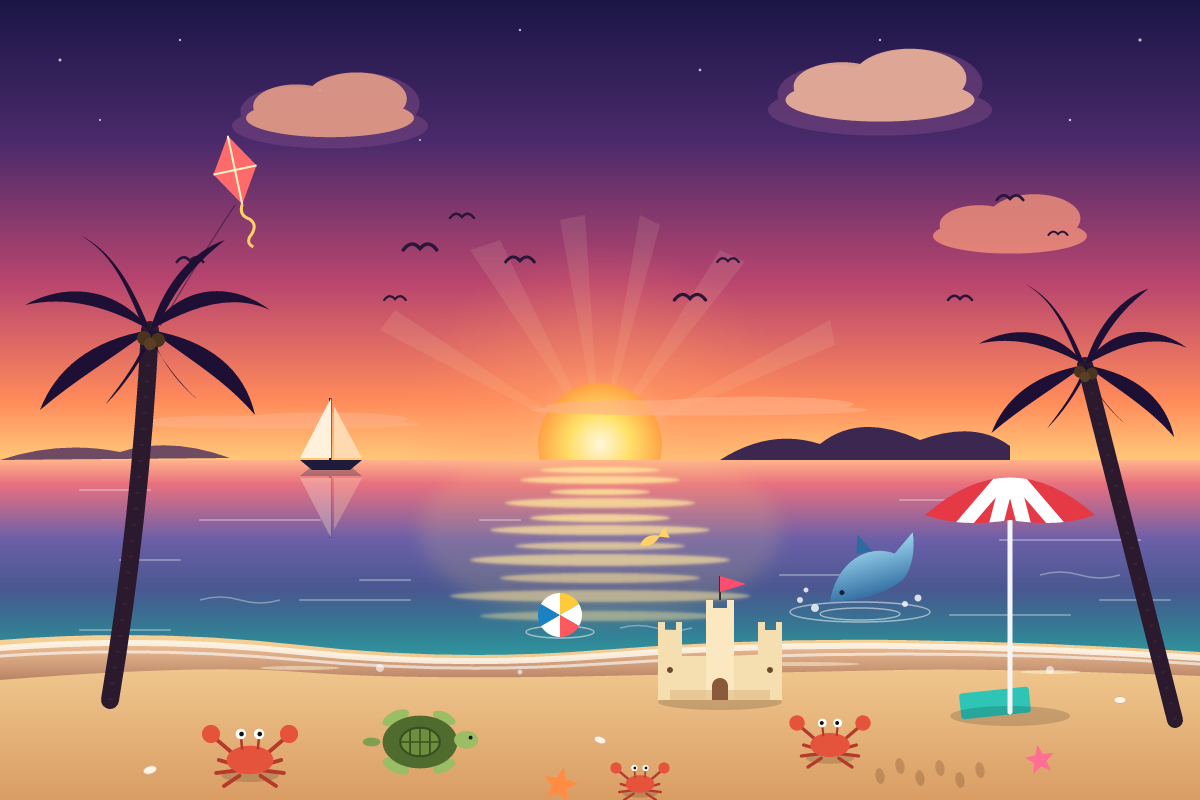
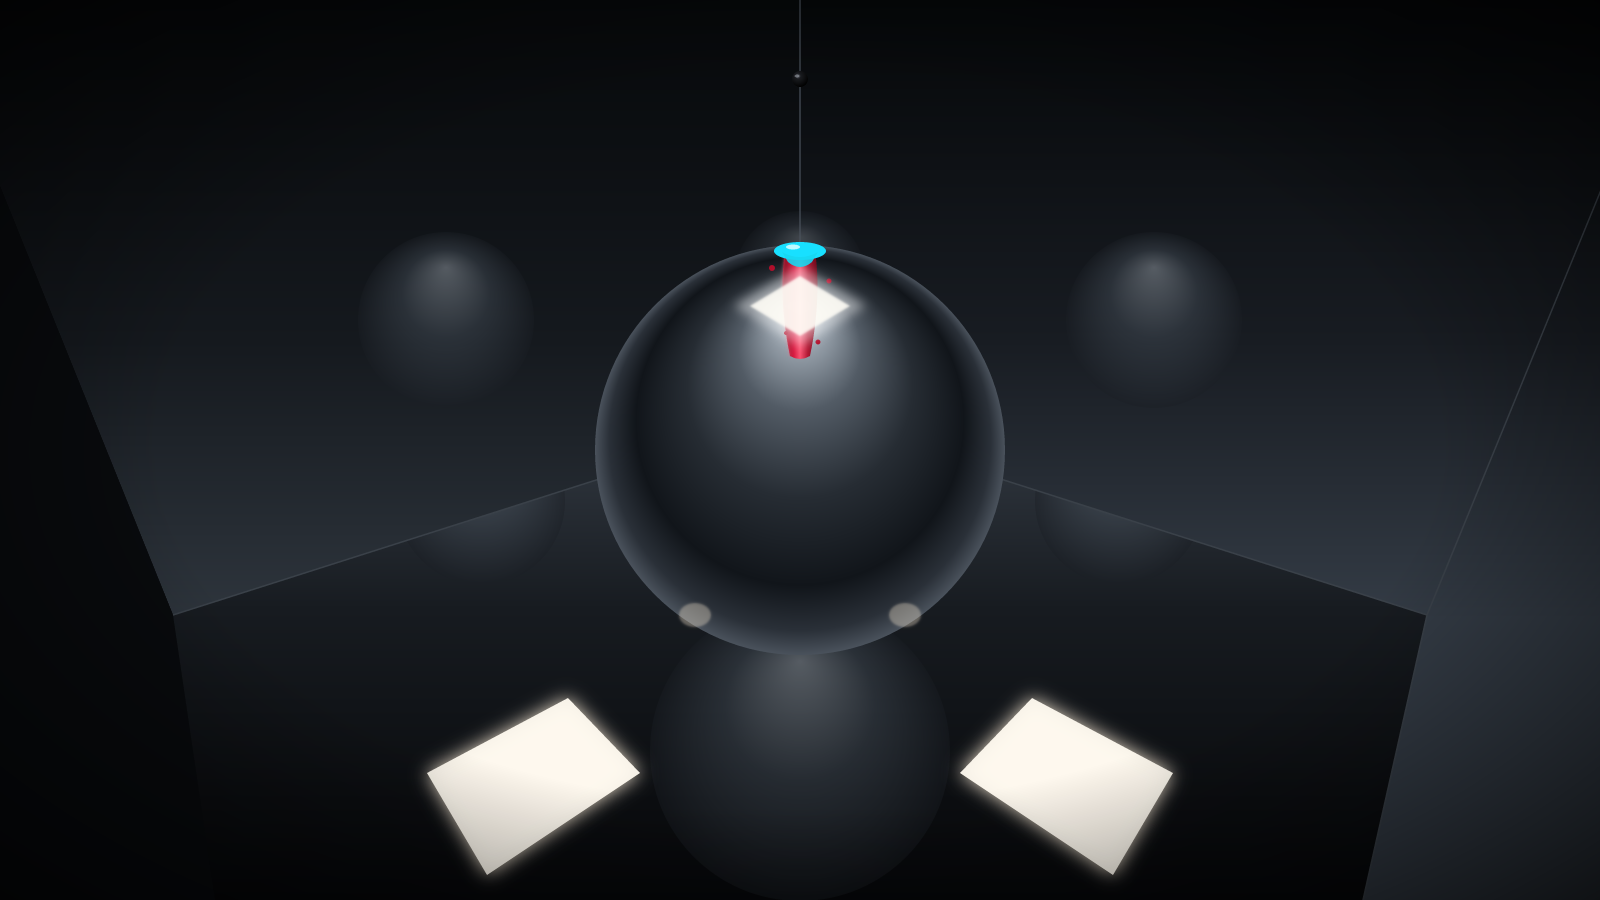
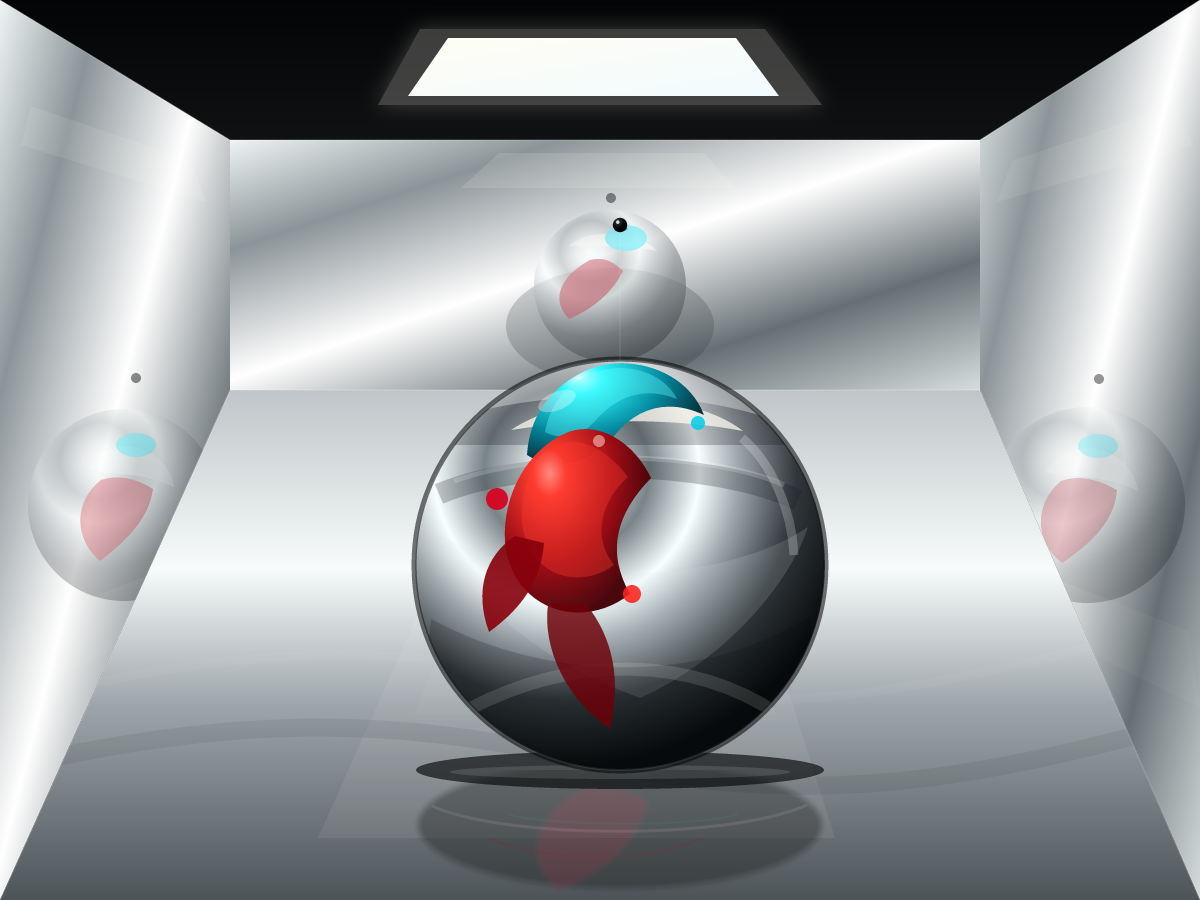
Drawn by this model01 / 01
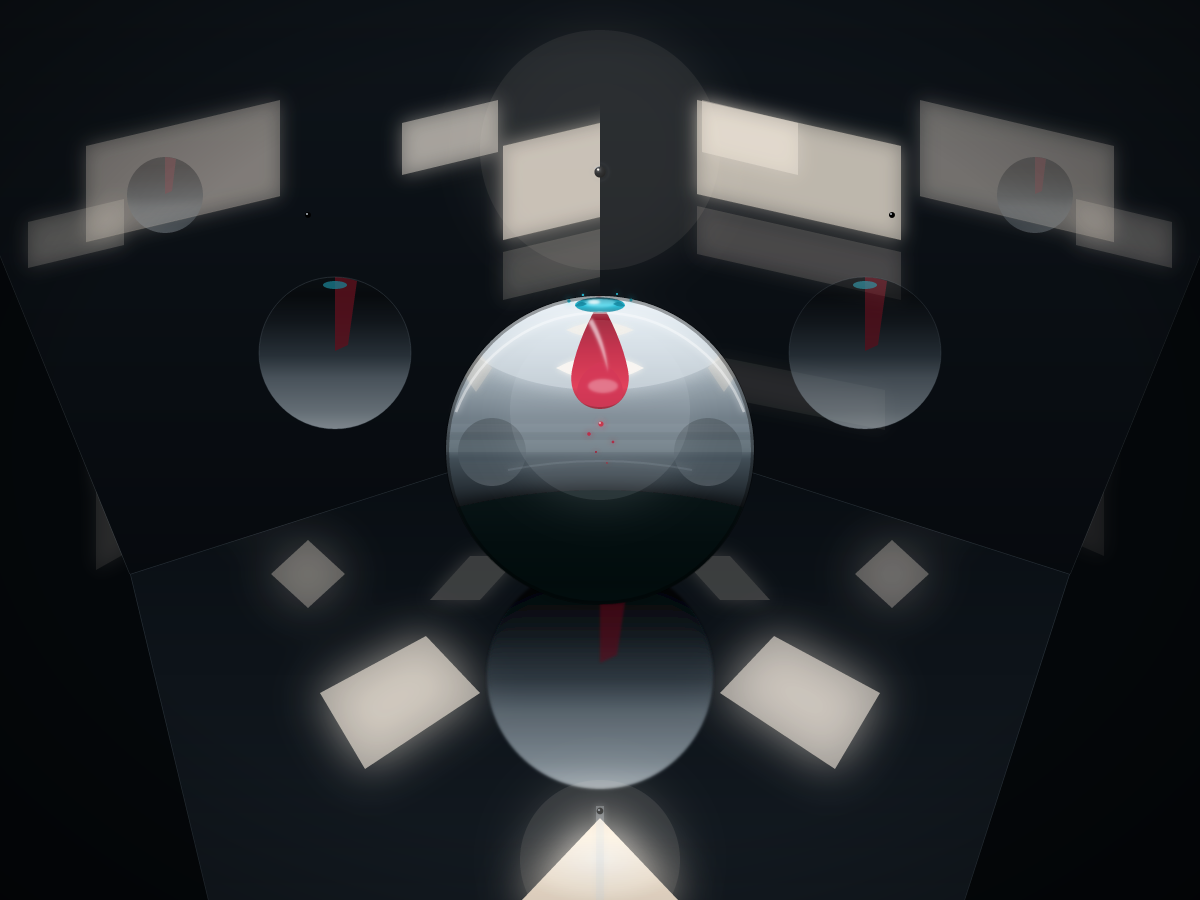
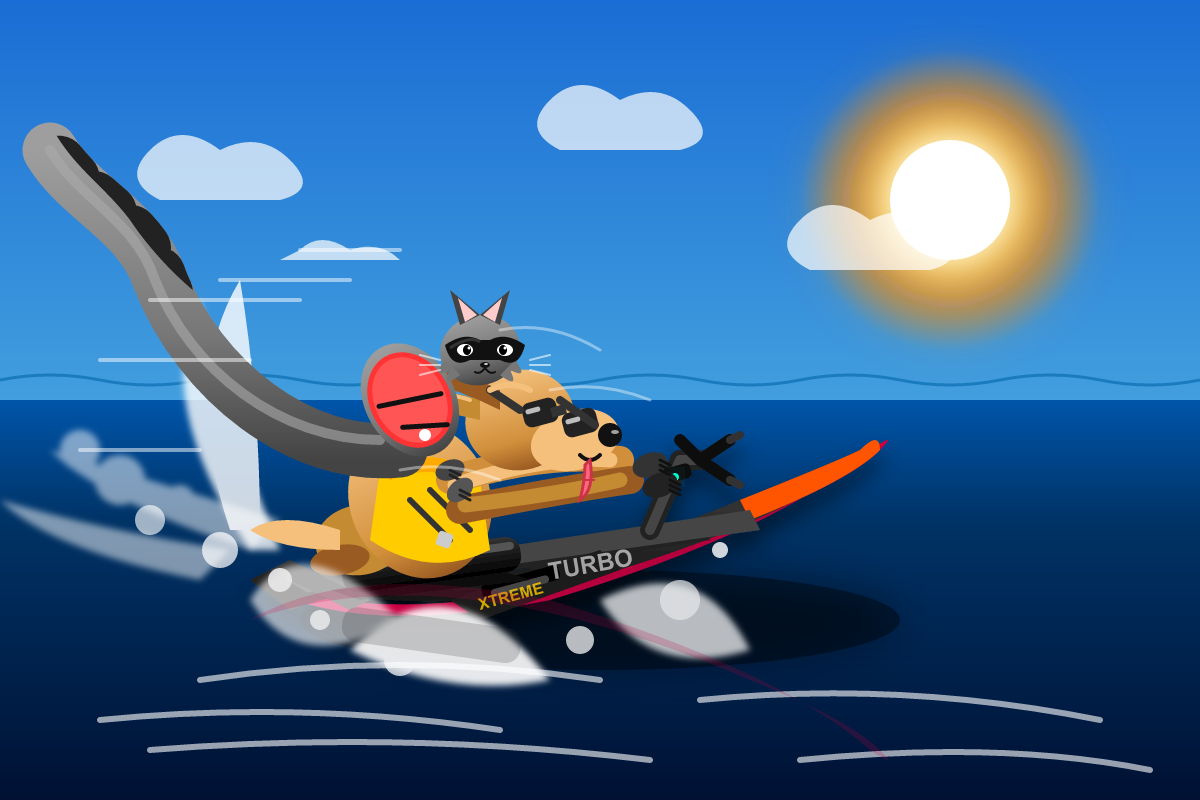
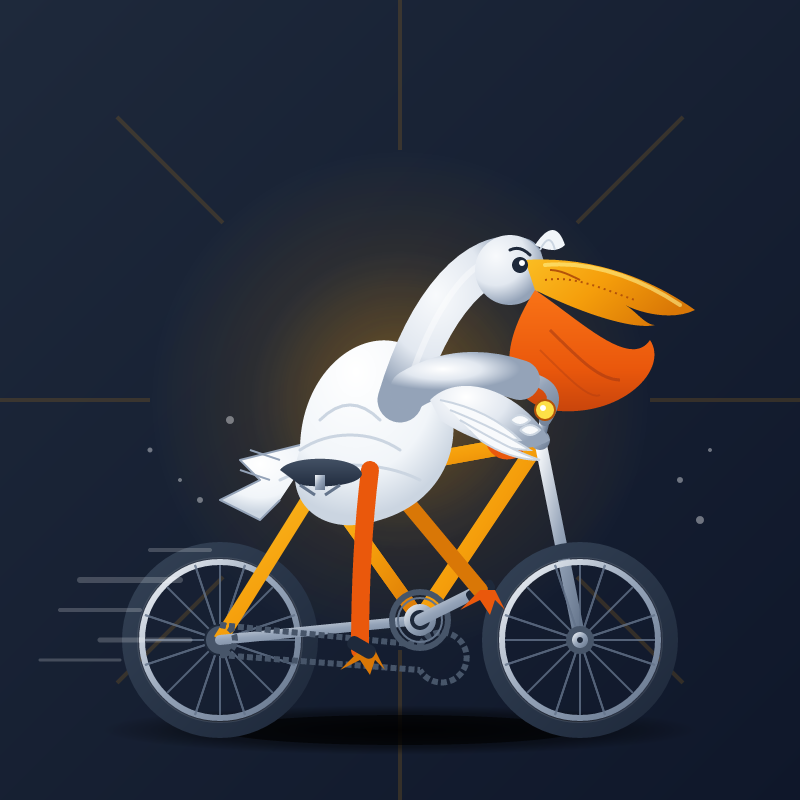
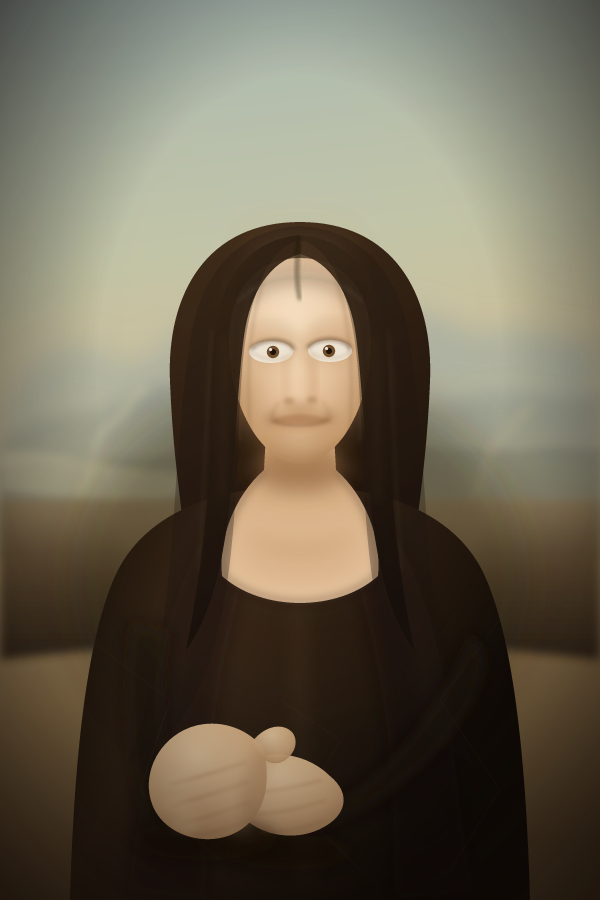
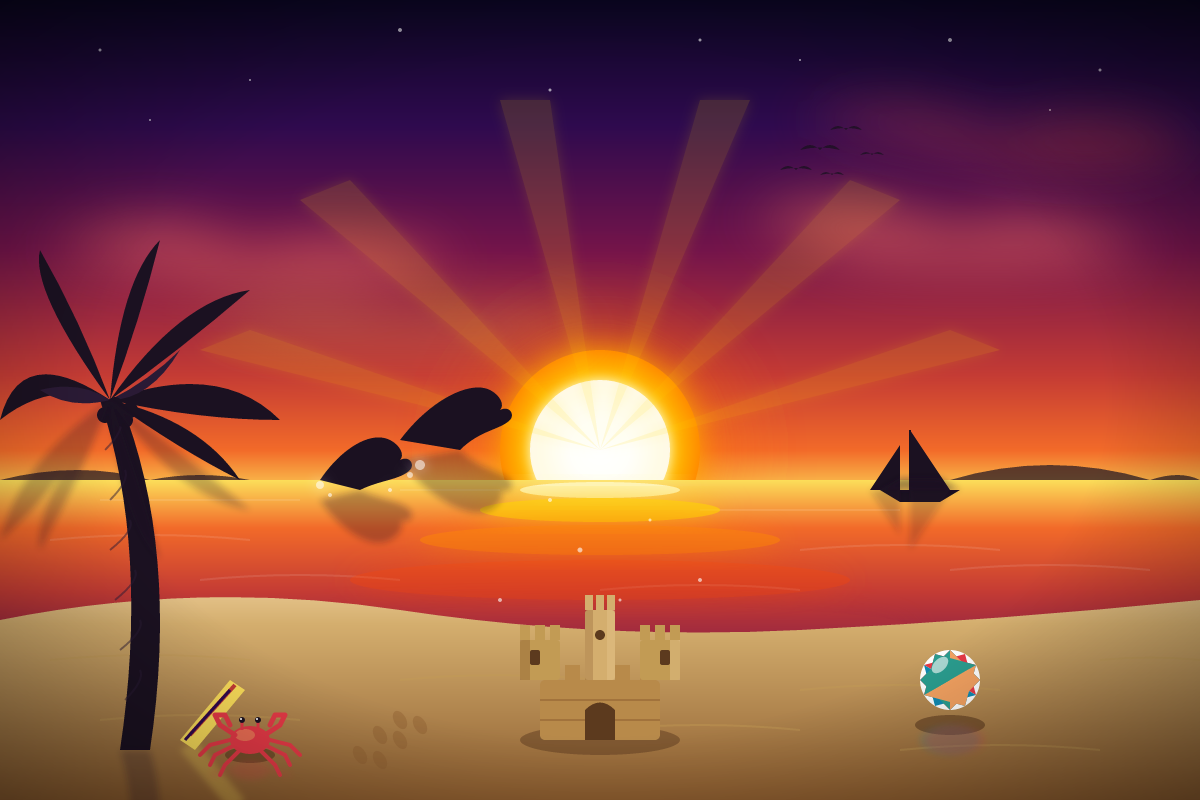
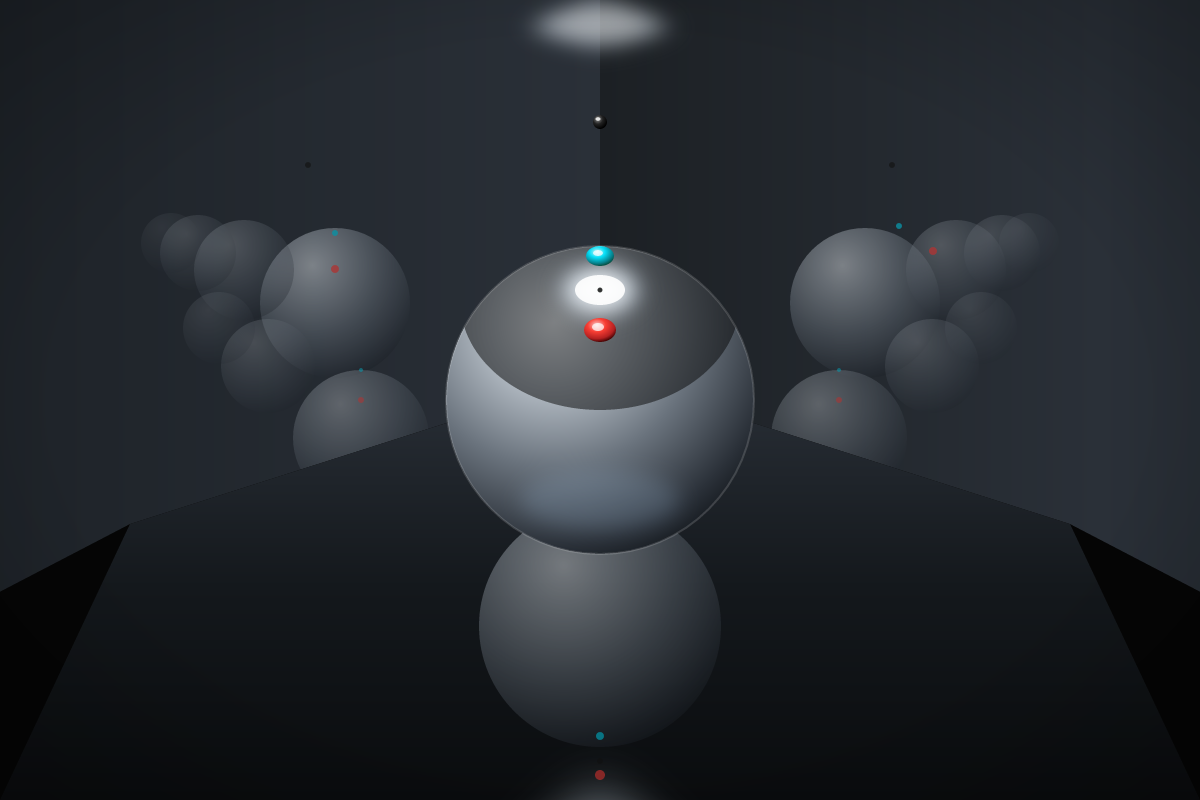
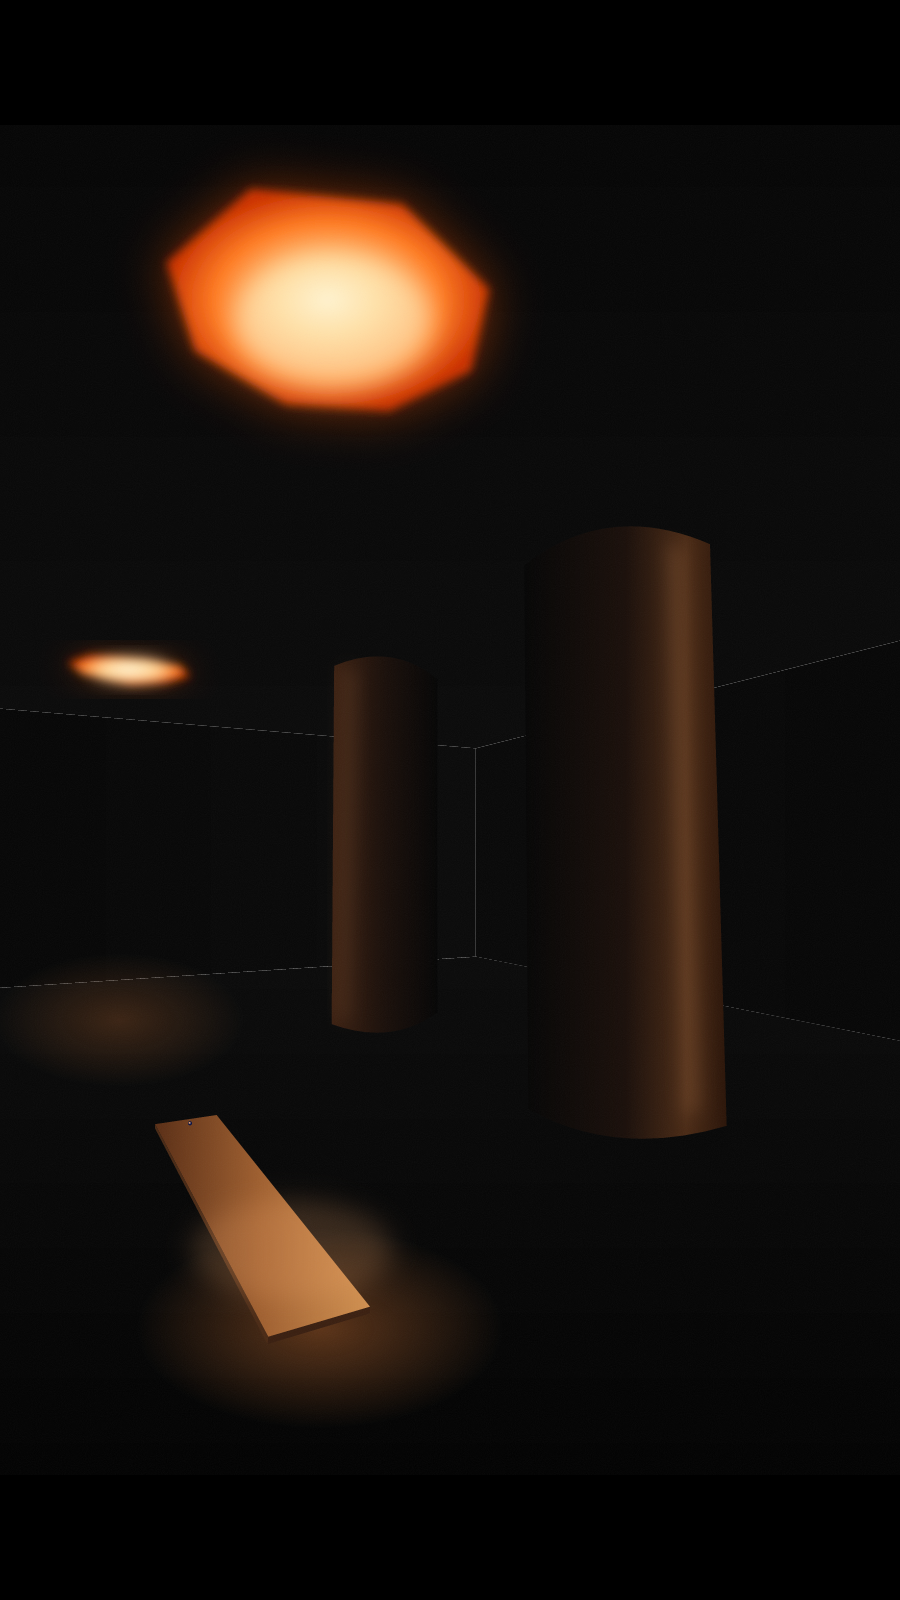
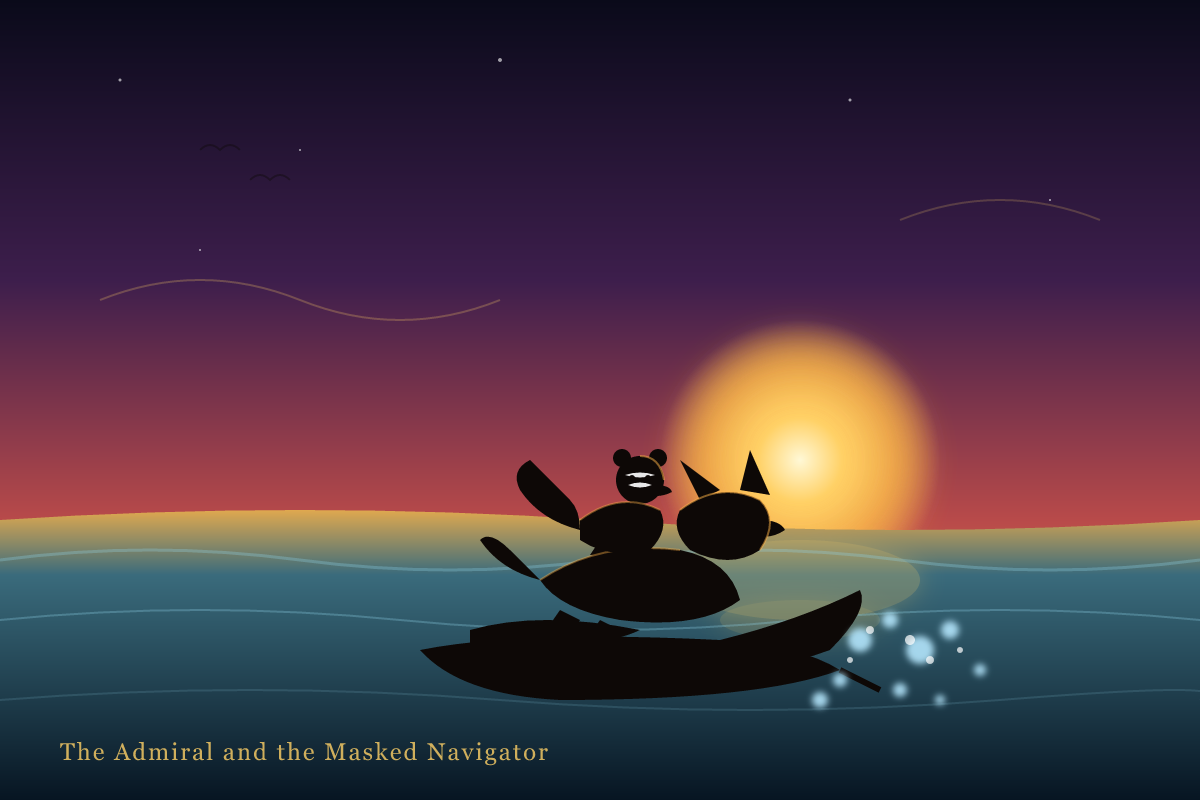
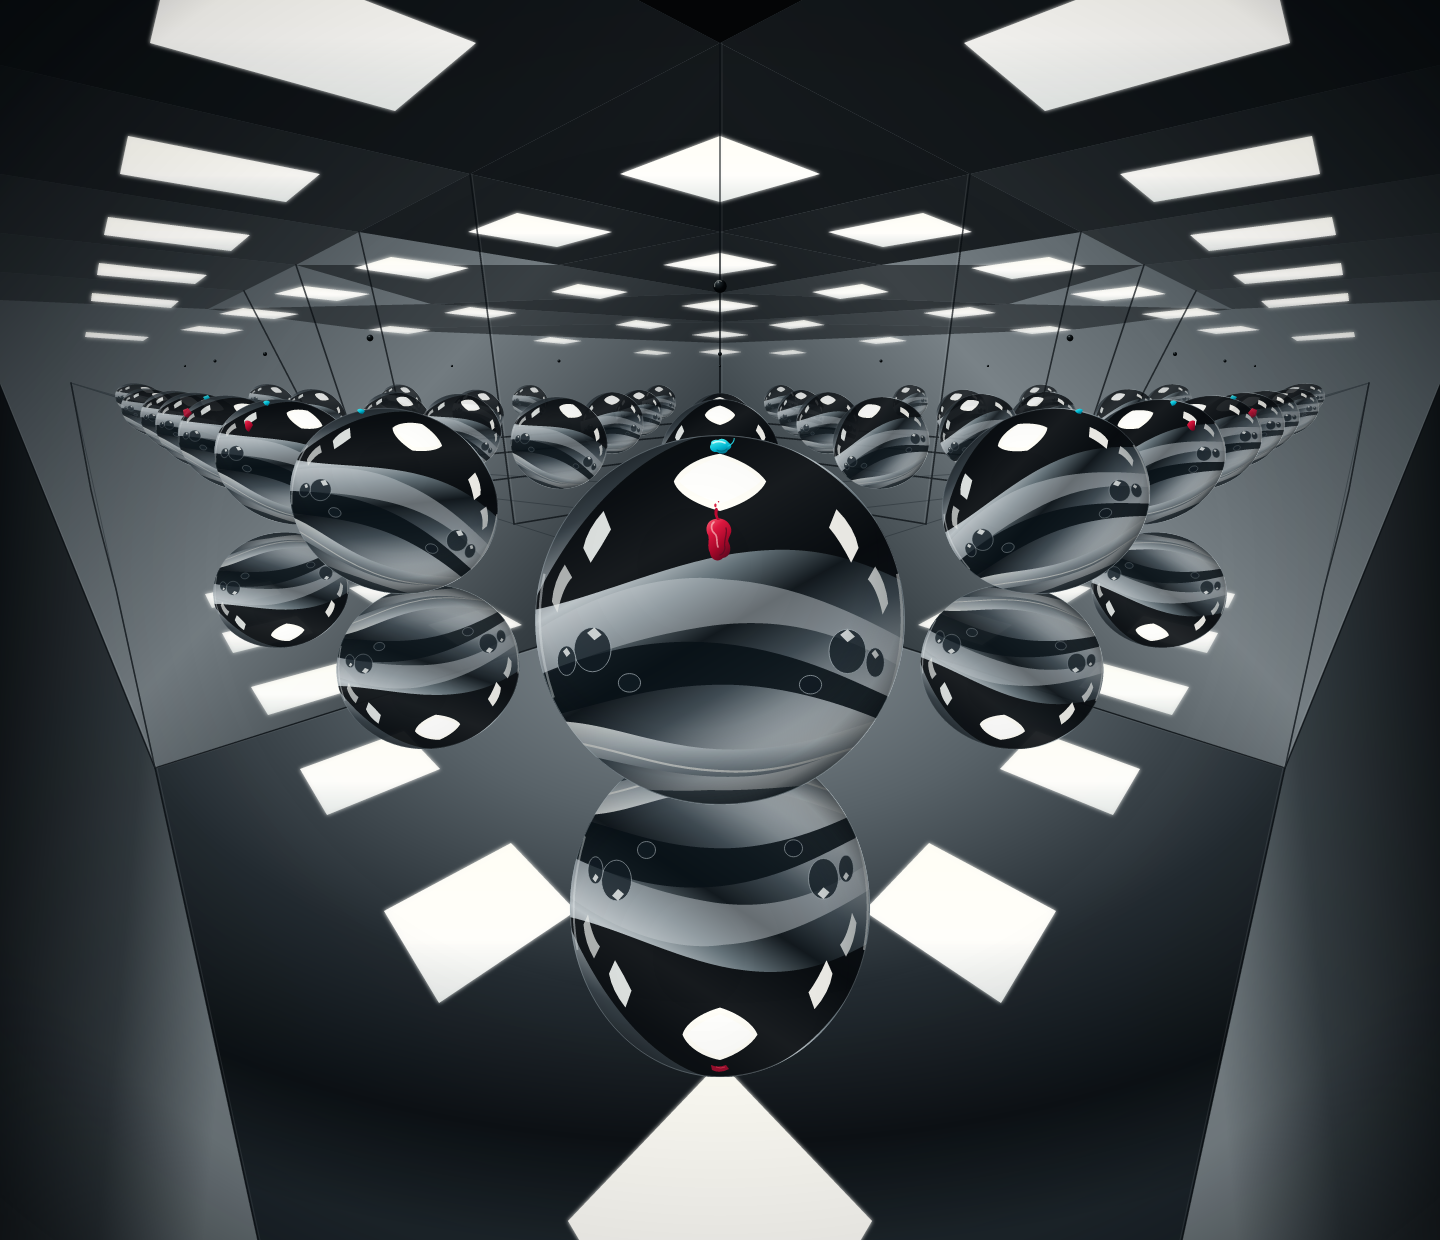
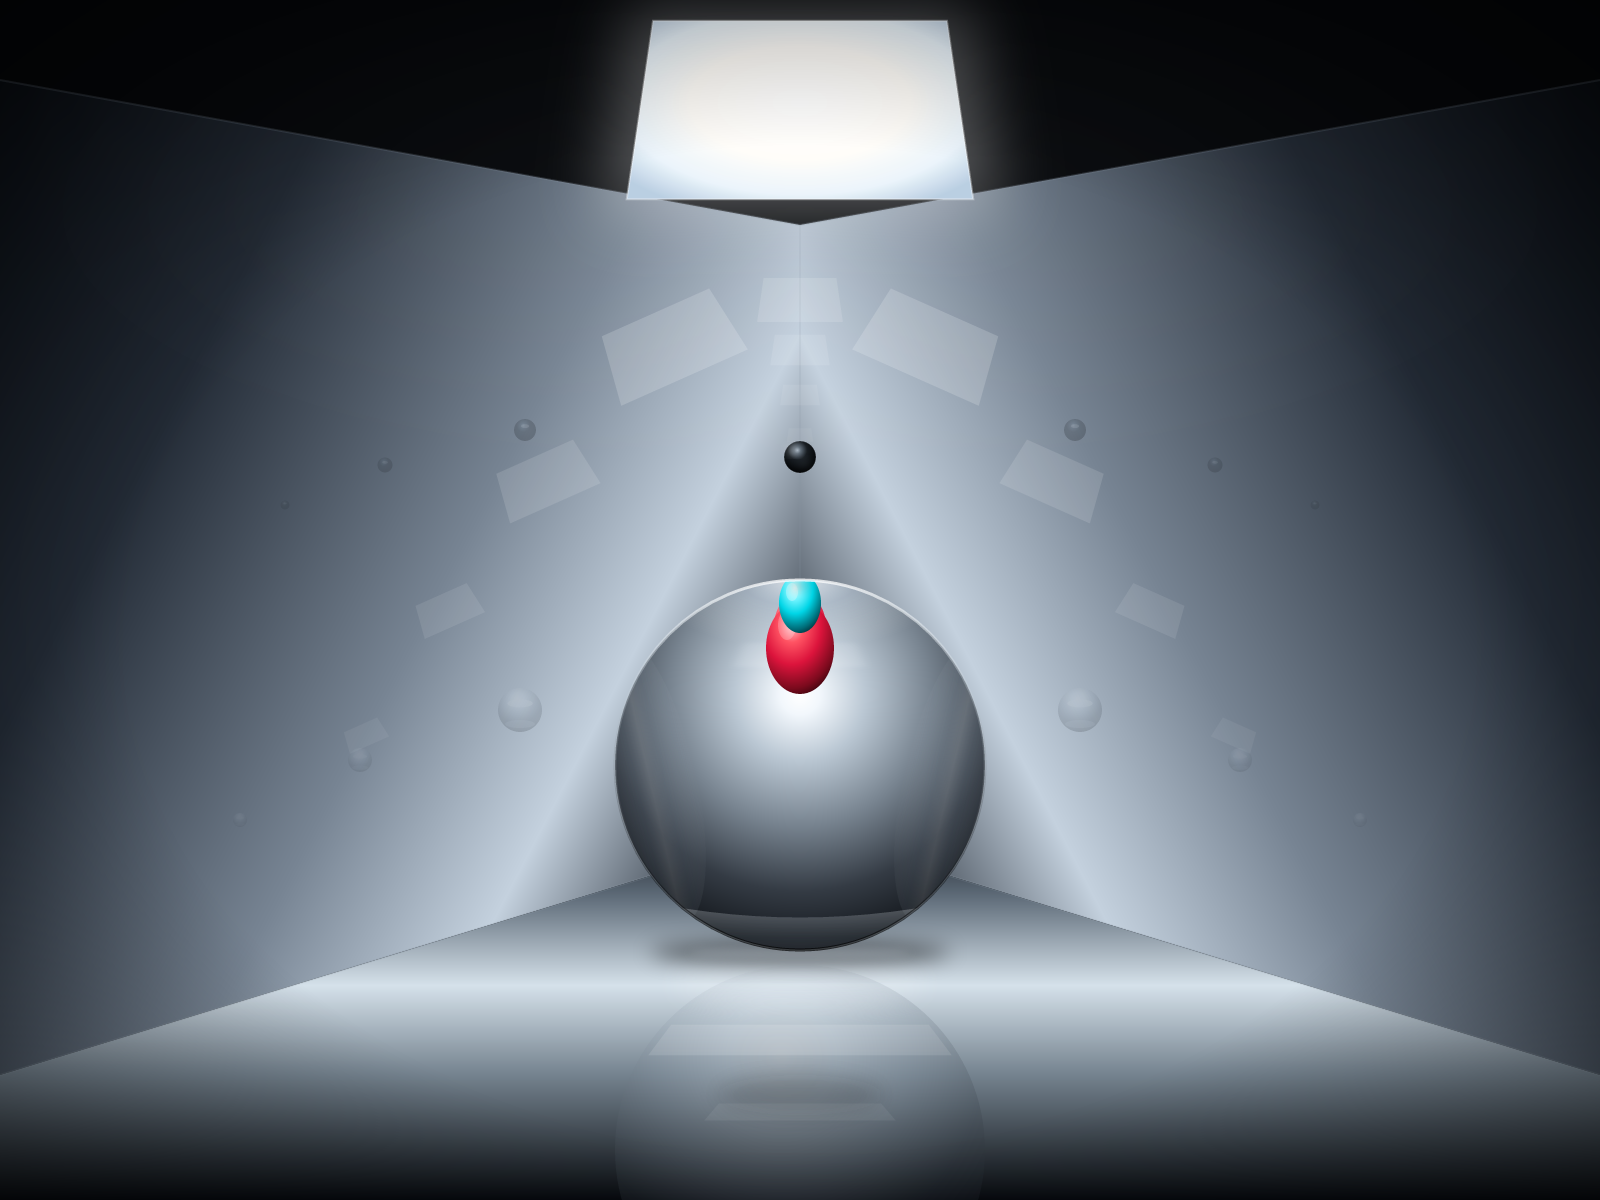
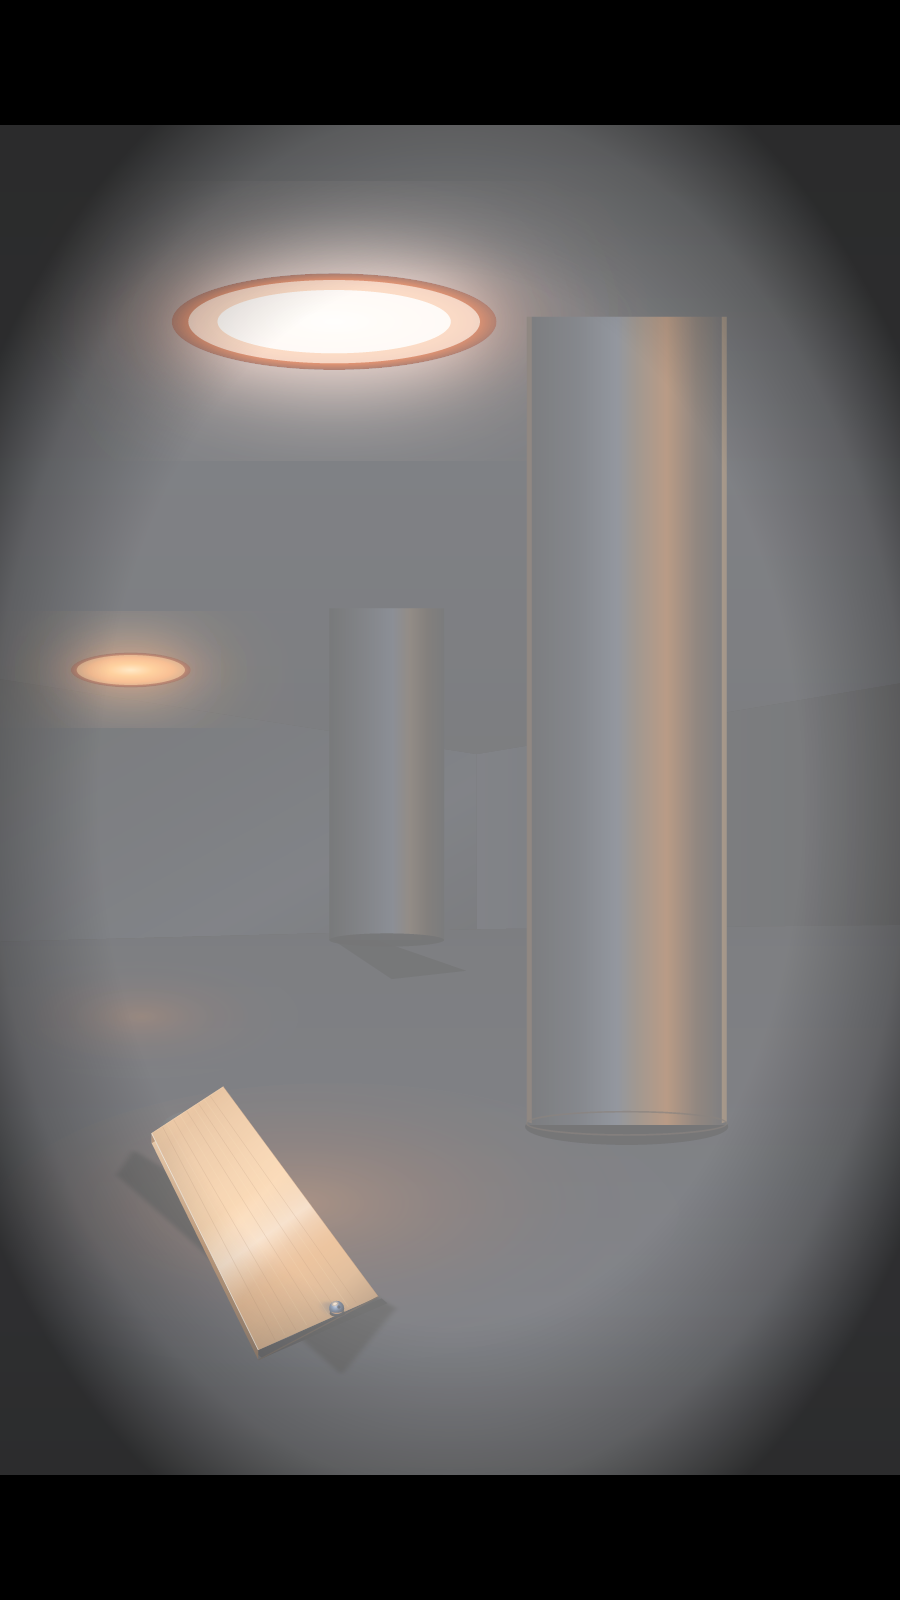
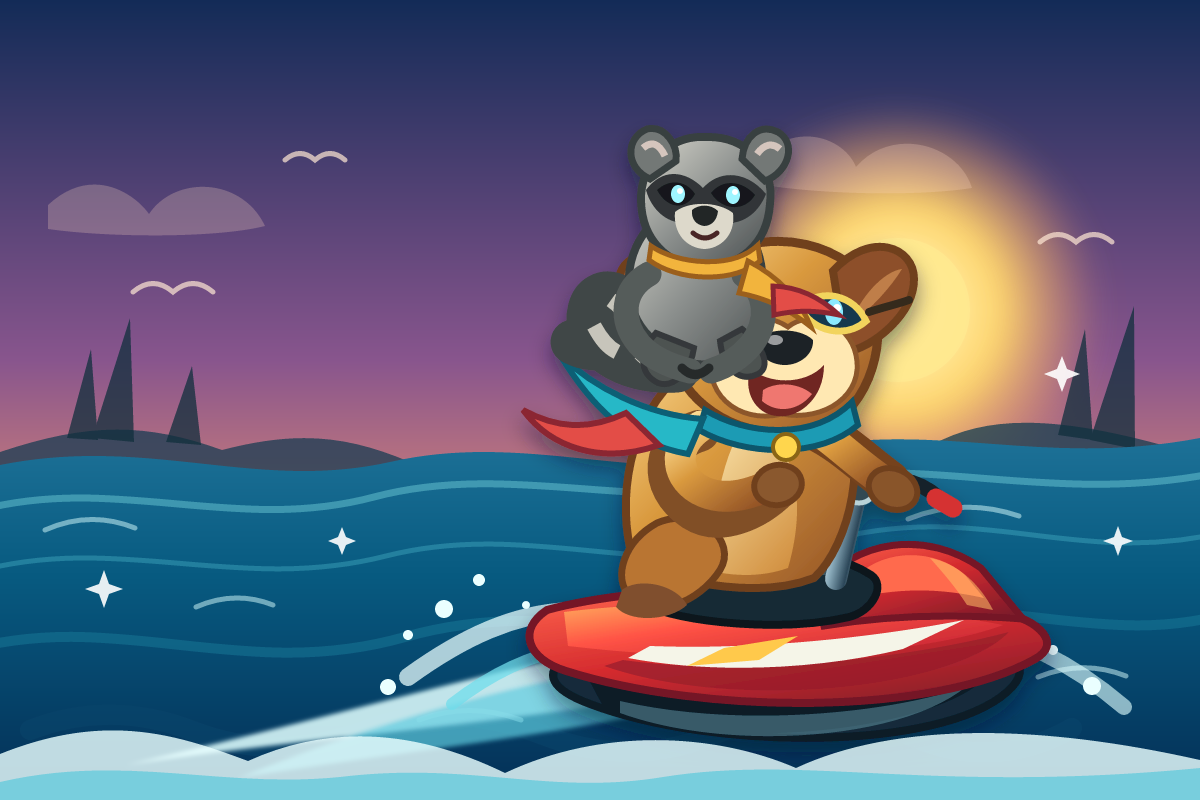
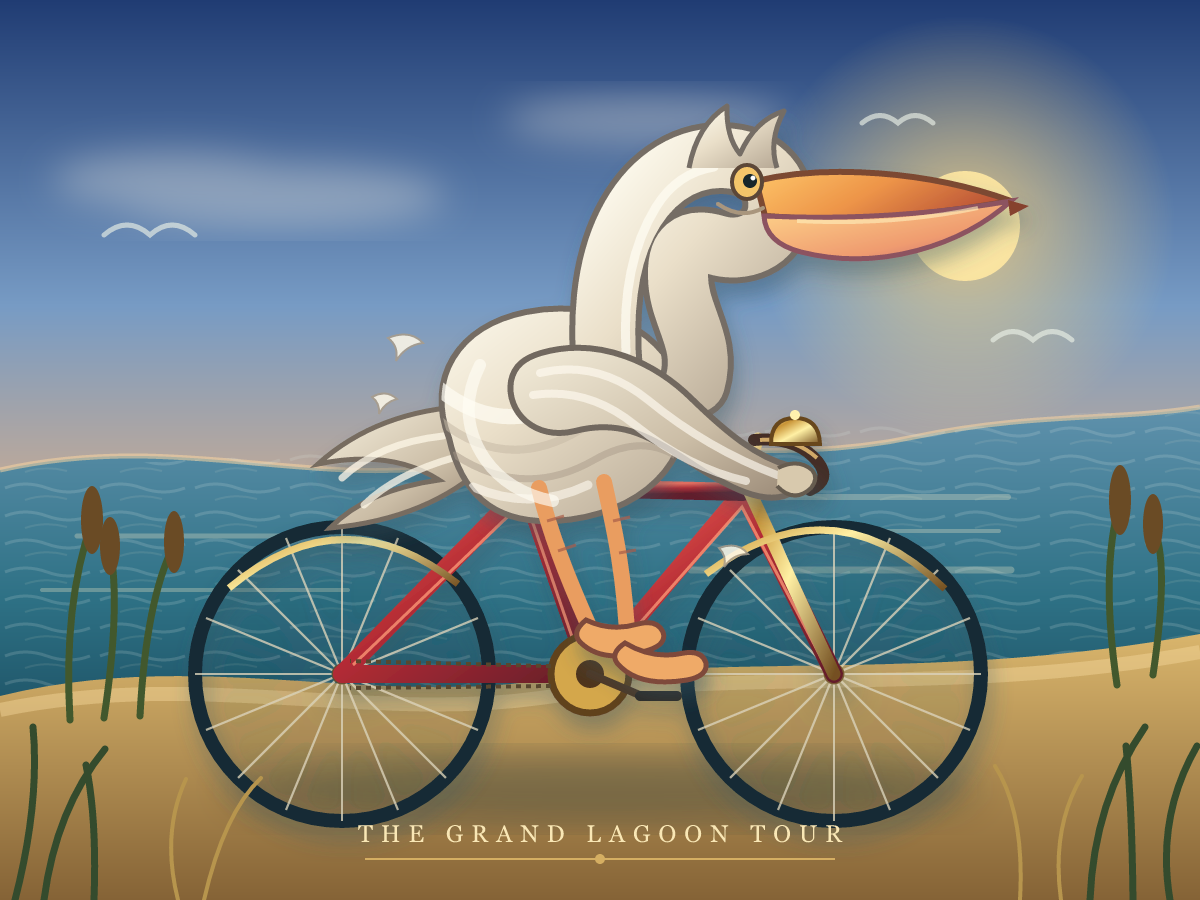
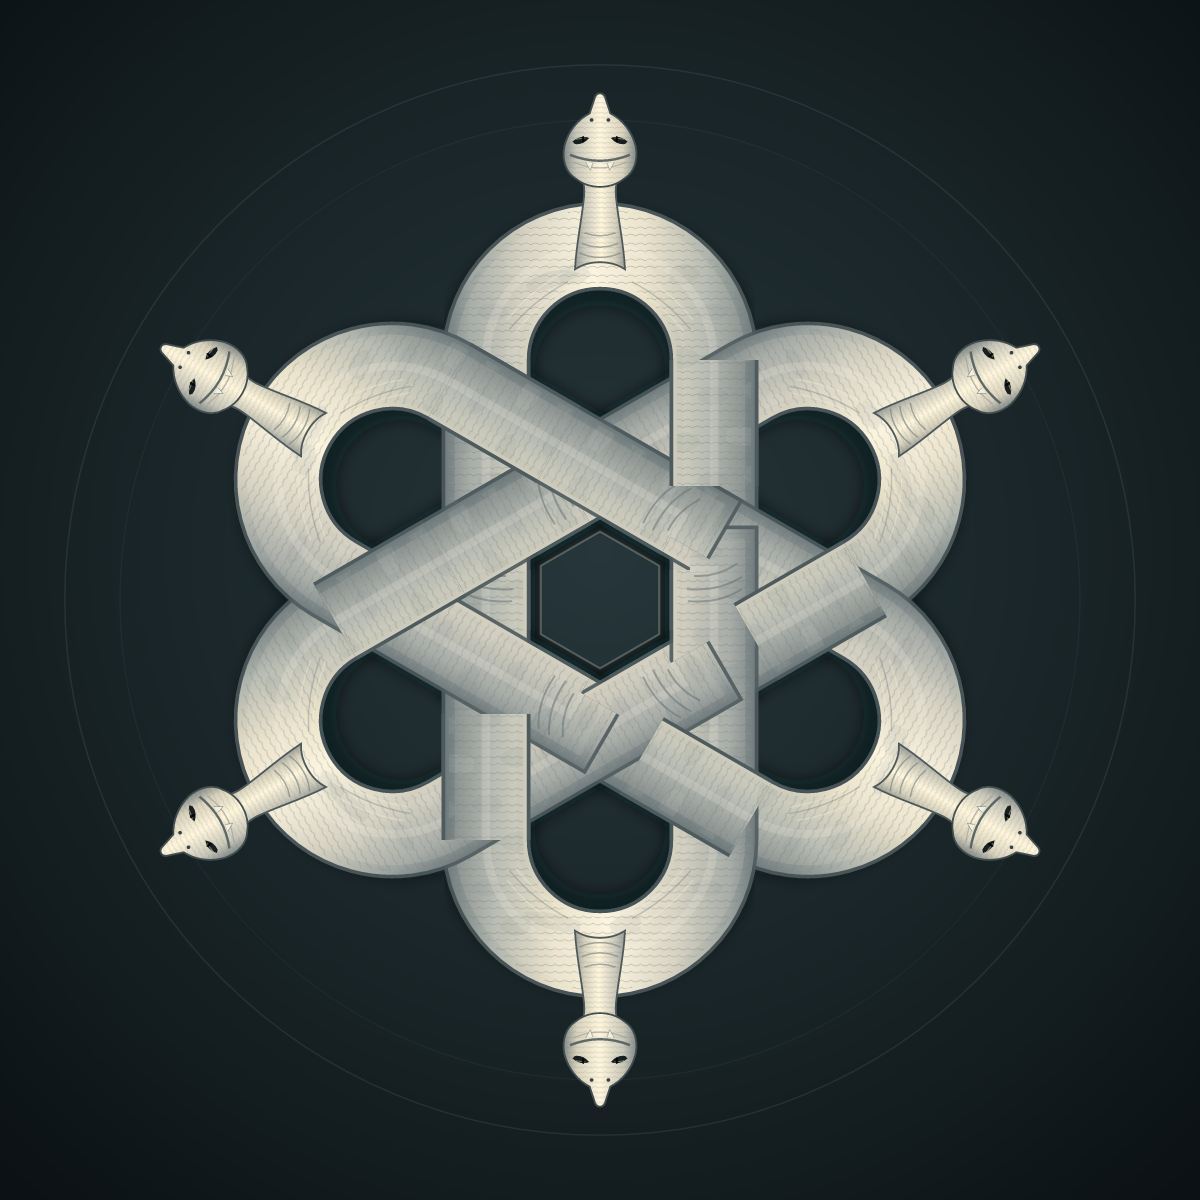
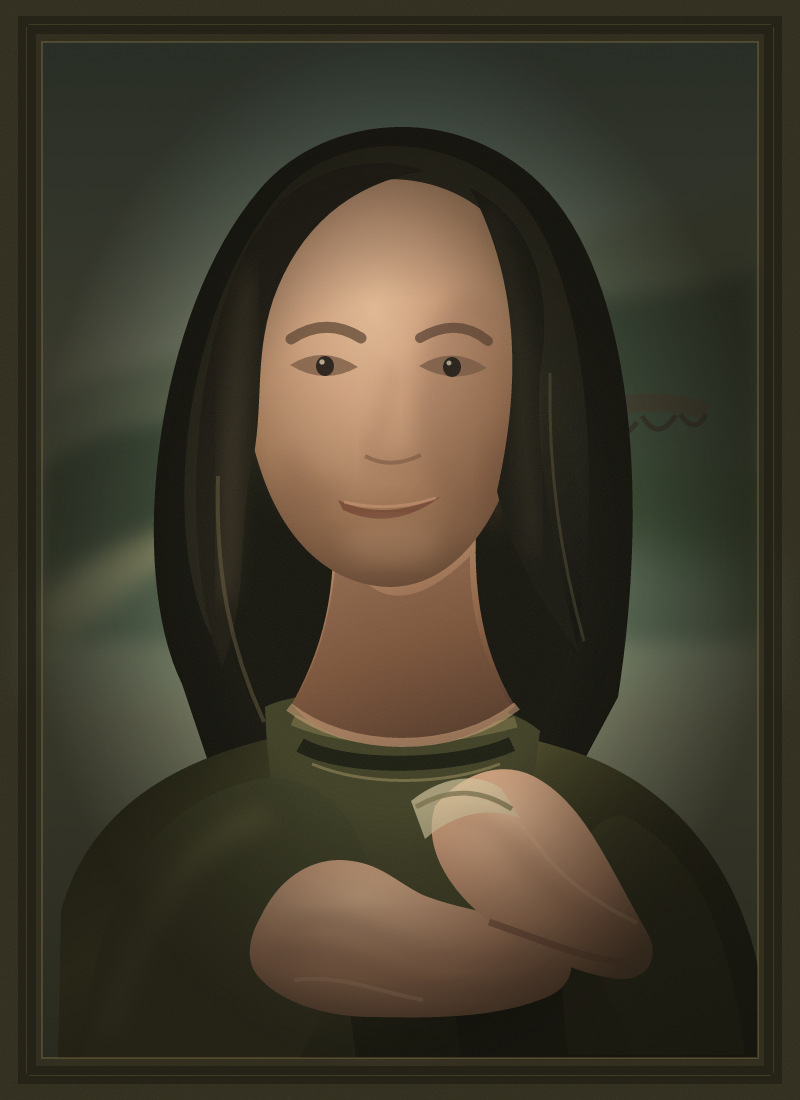
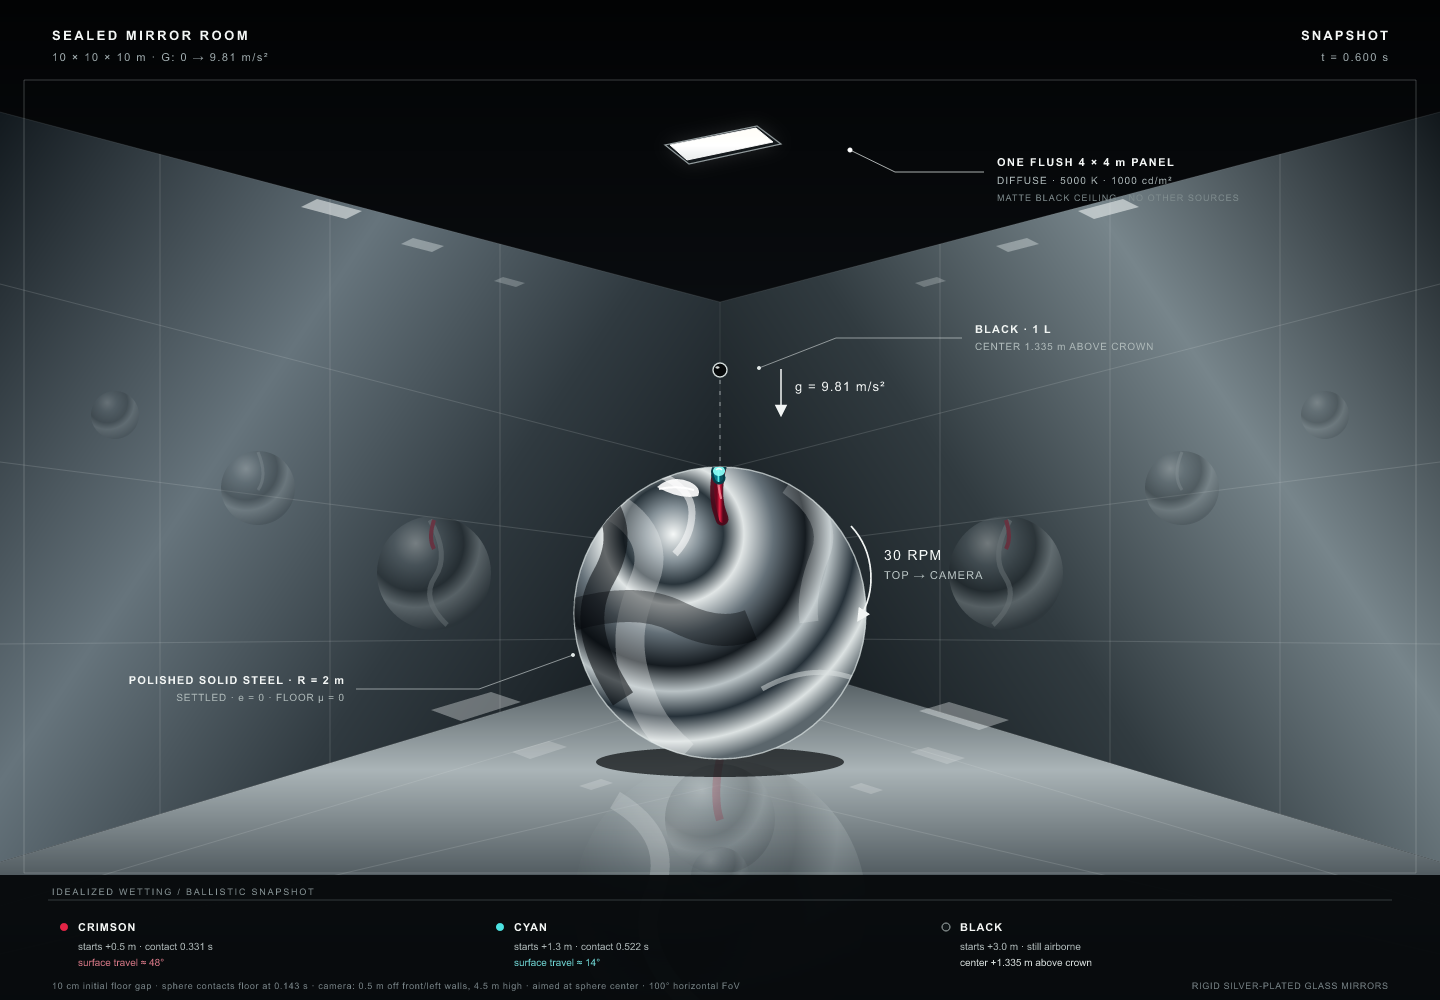
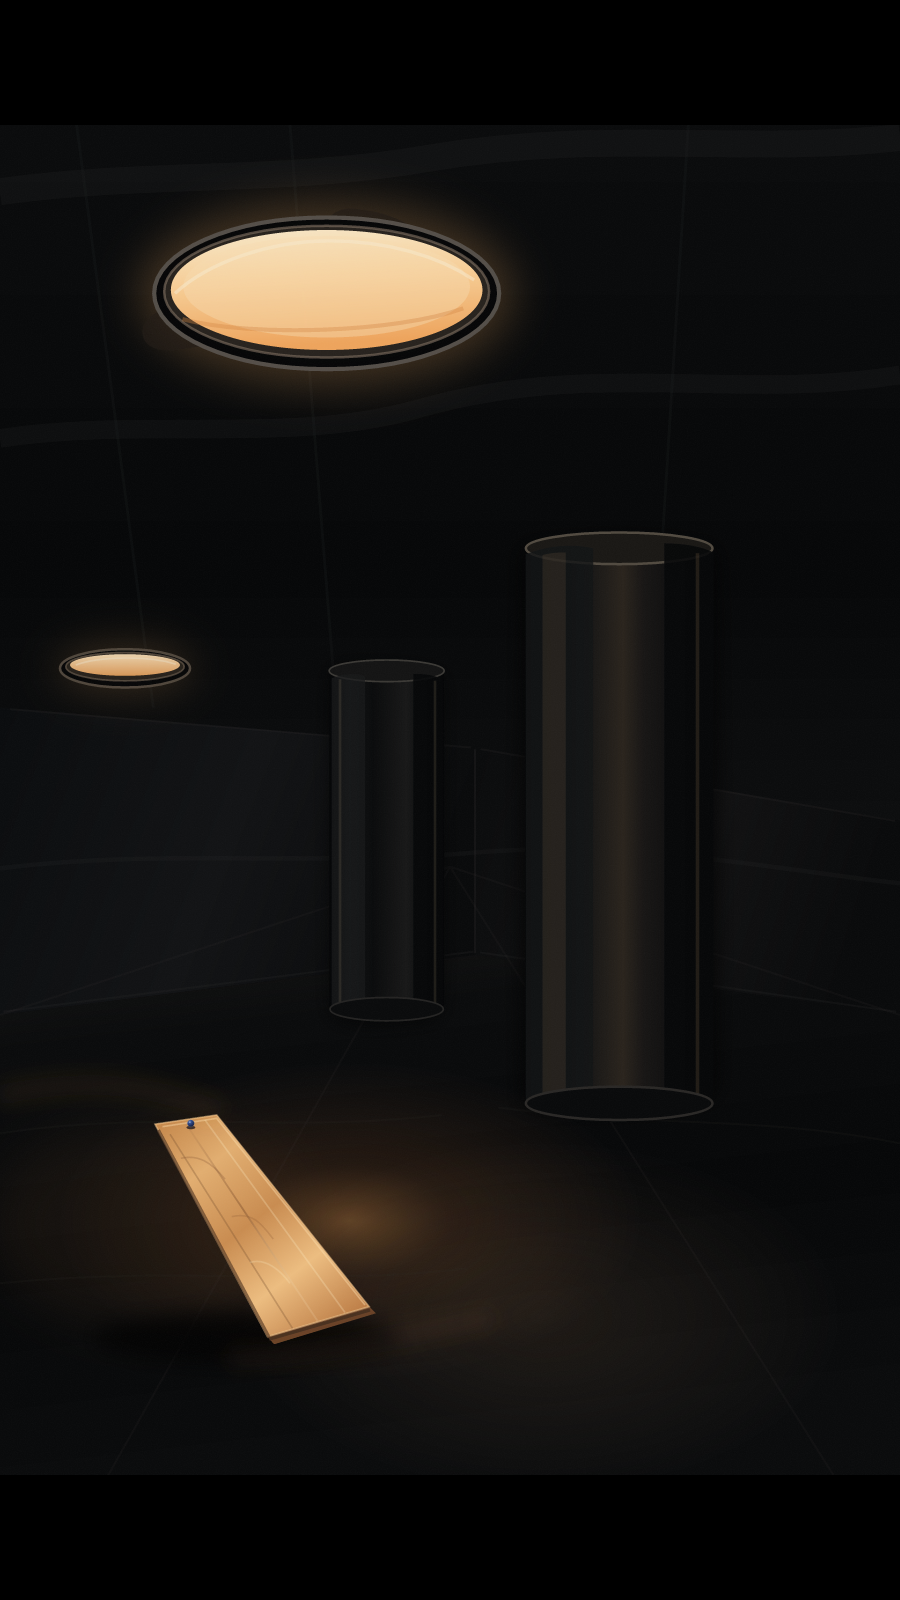
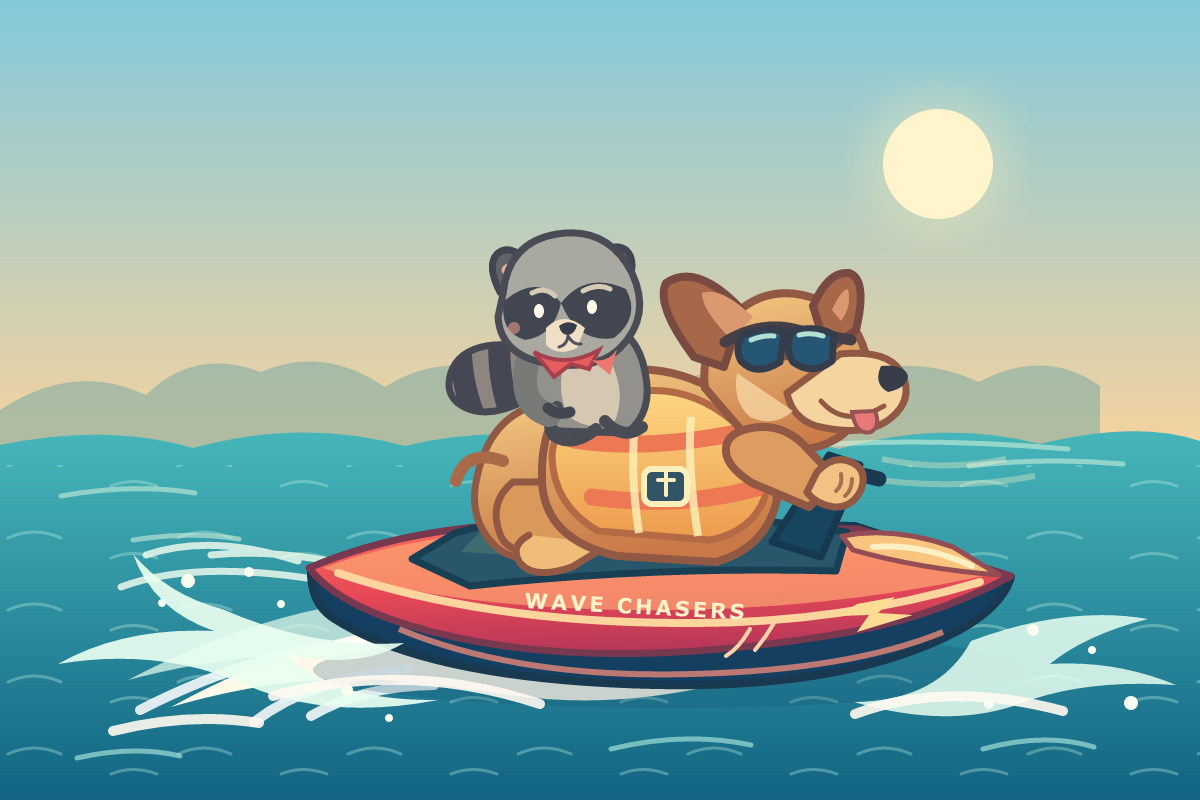
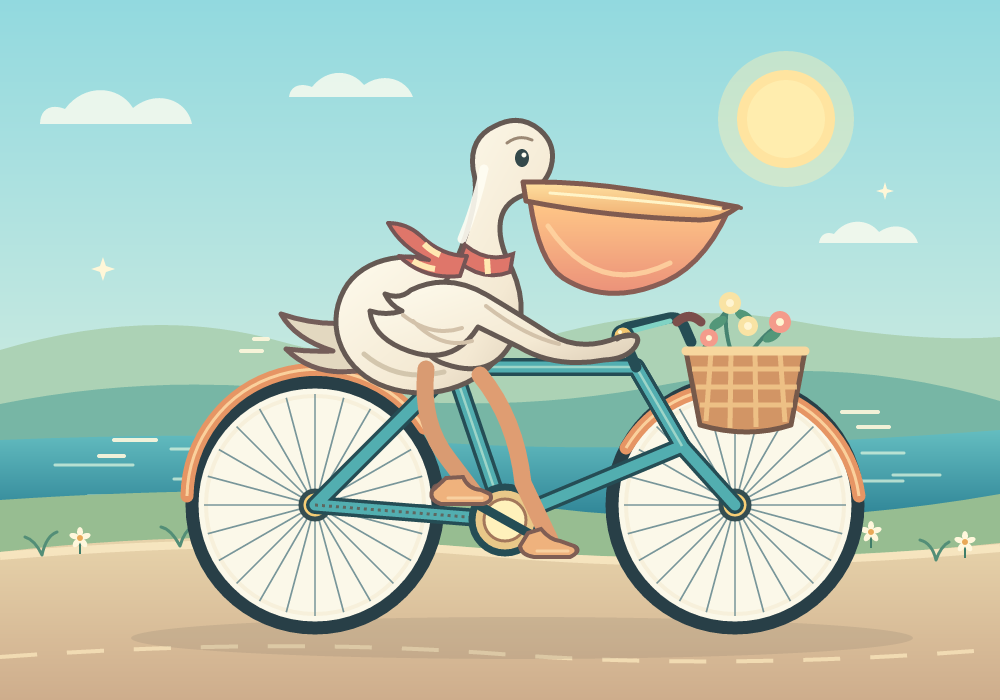
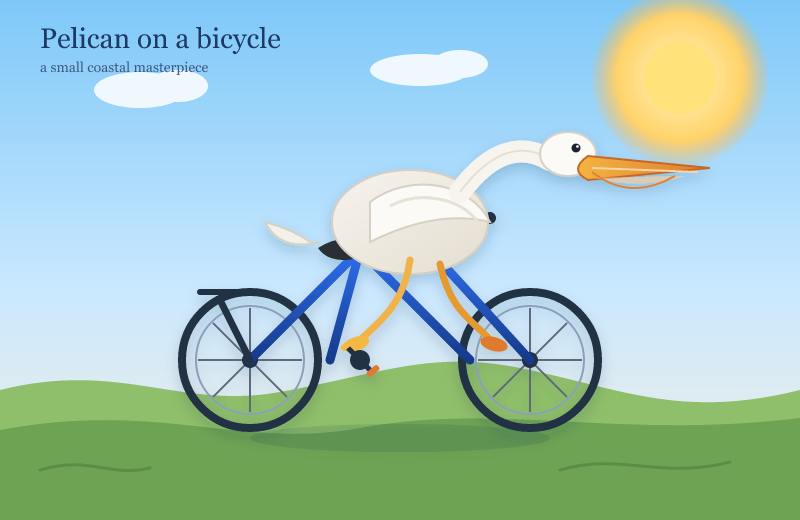
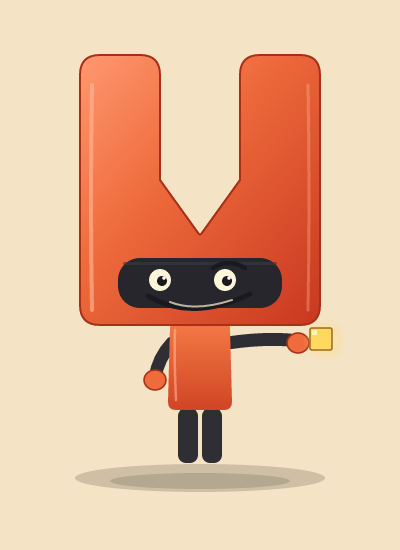
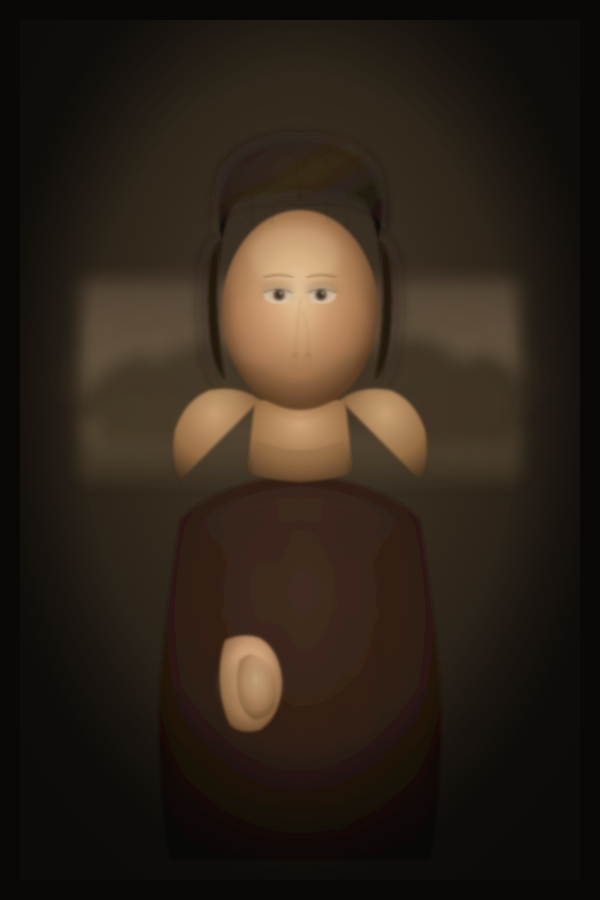
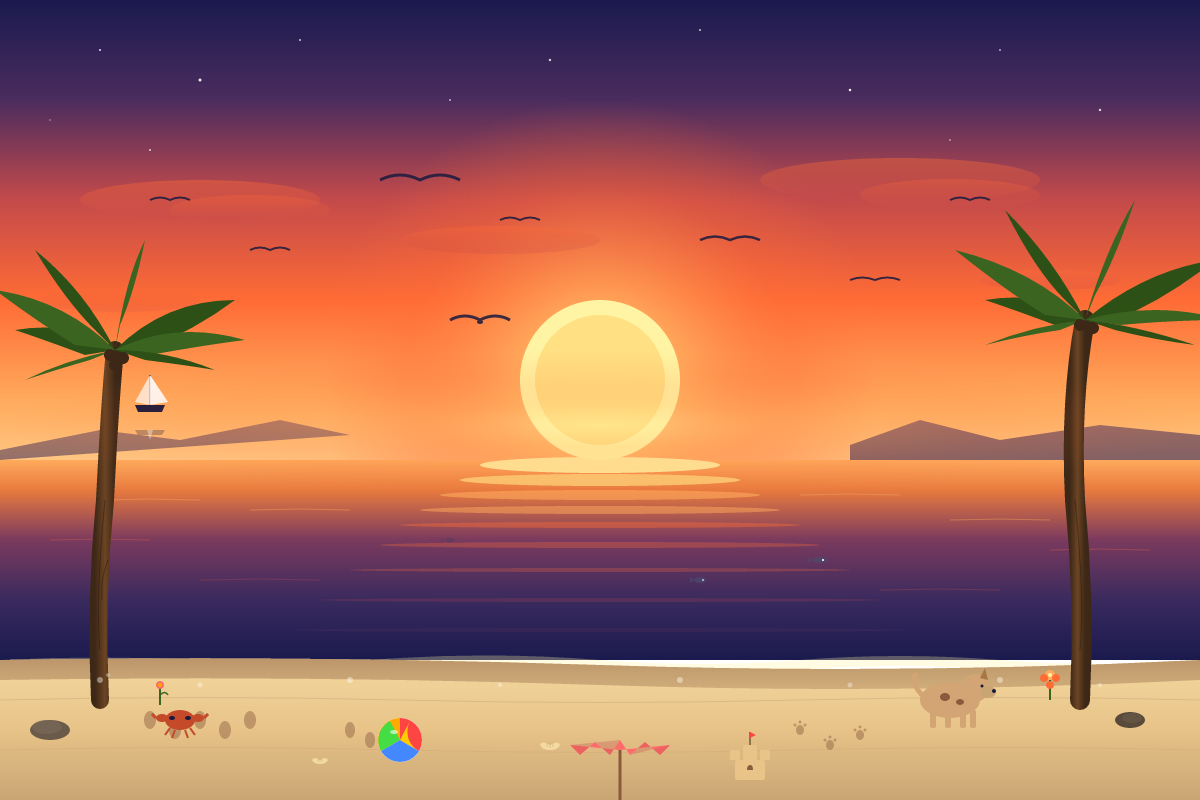
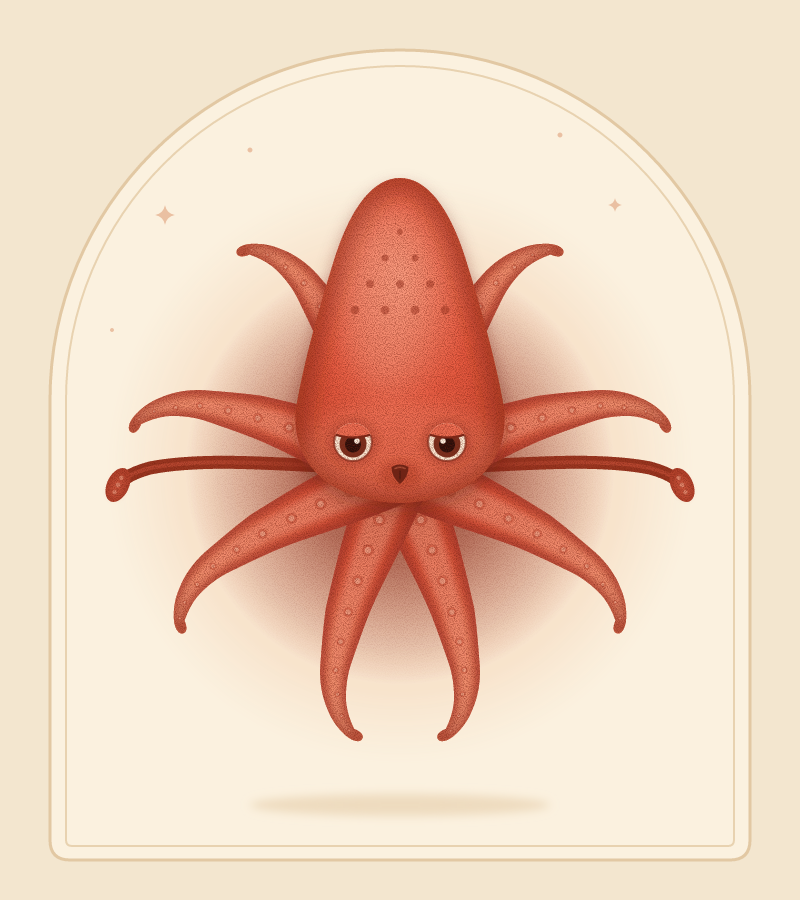
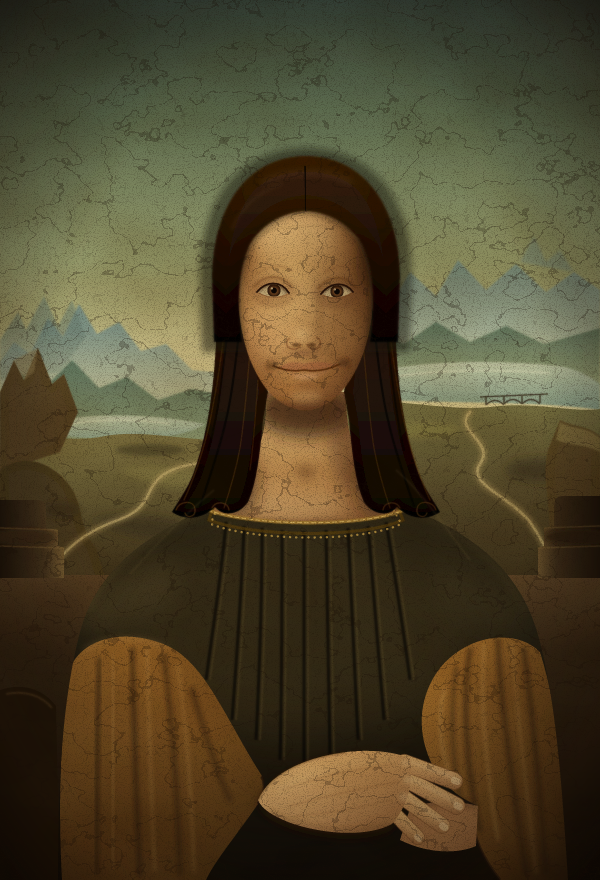
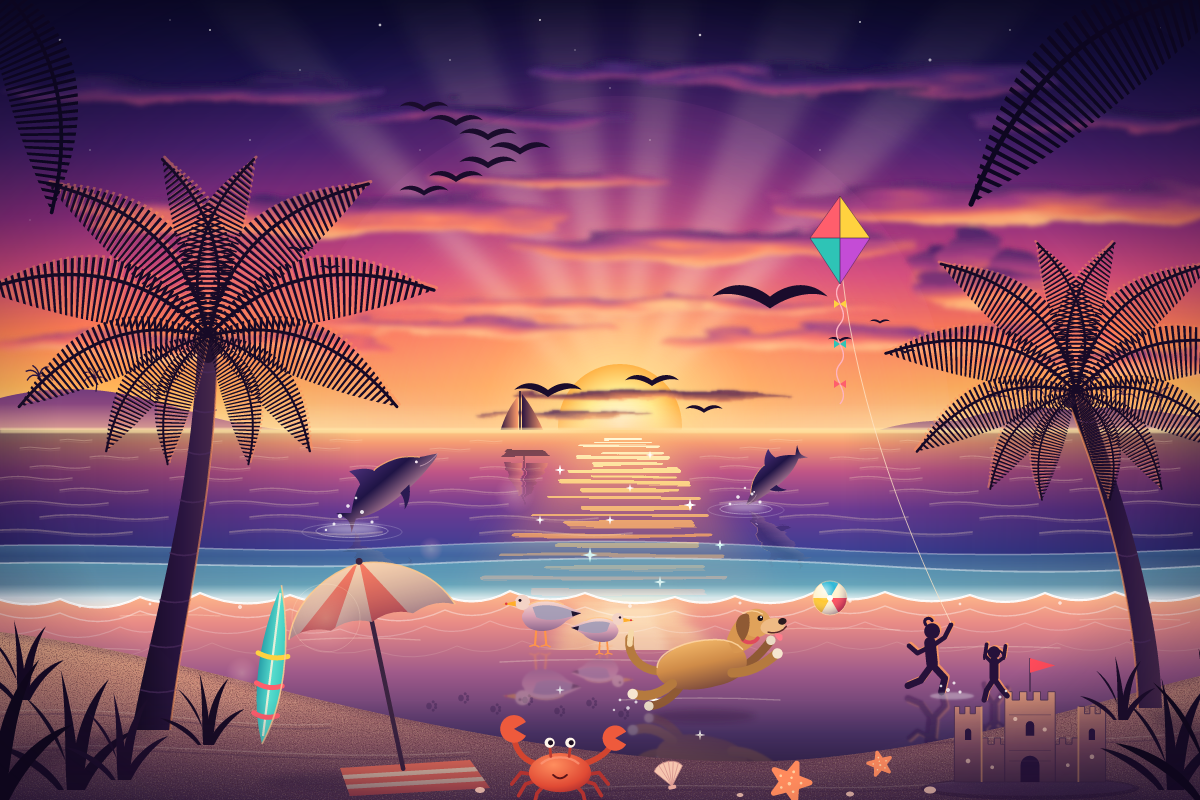
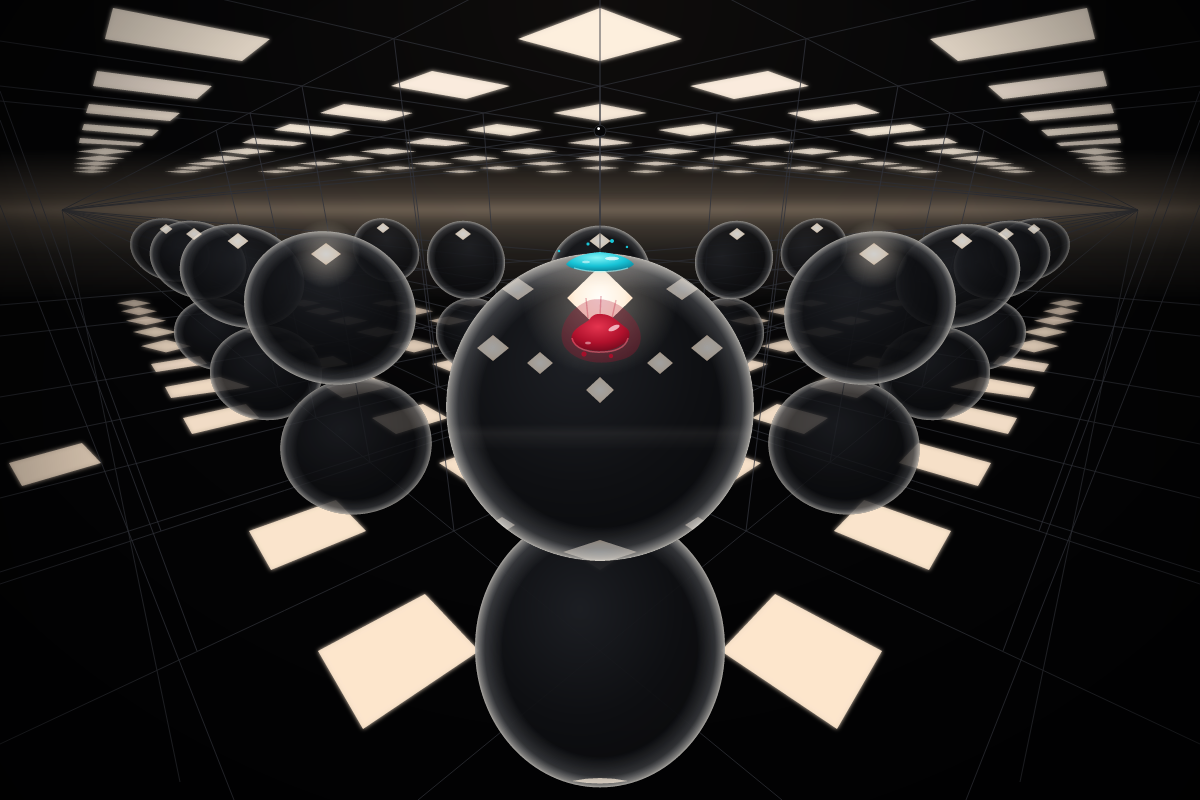
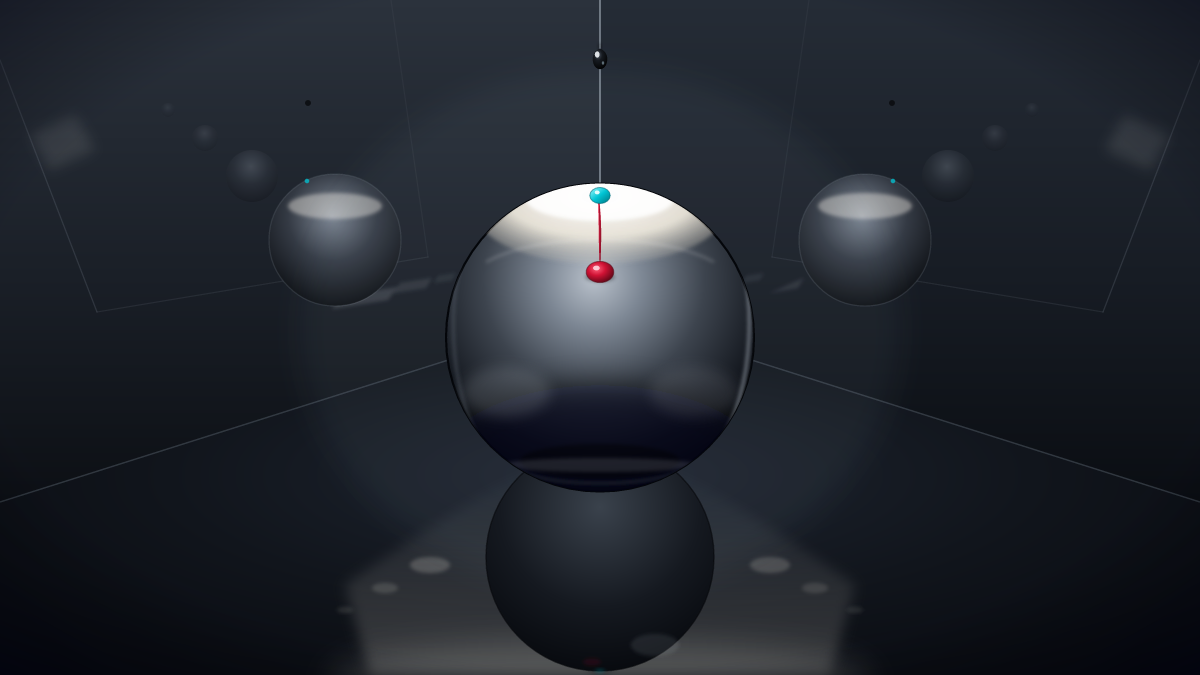
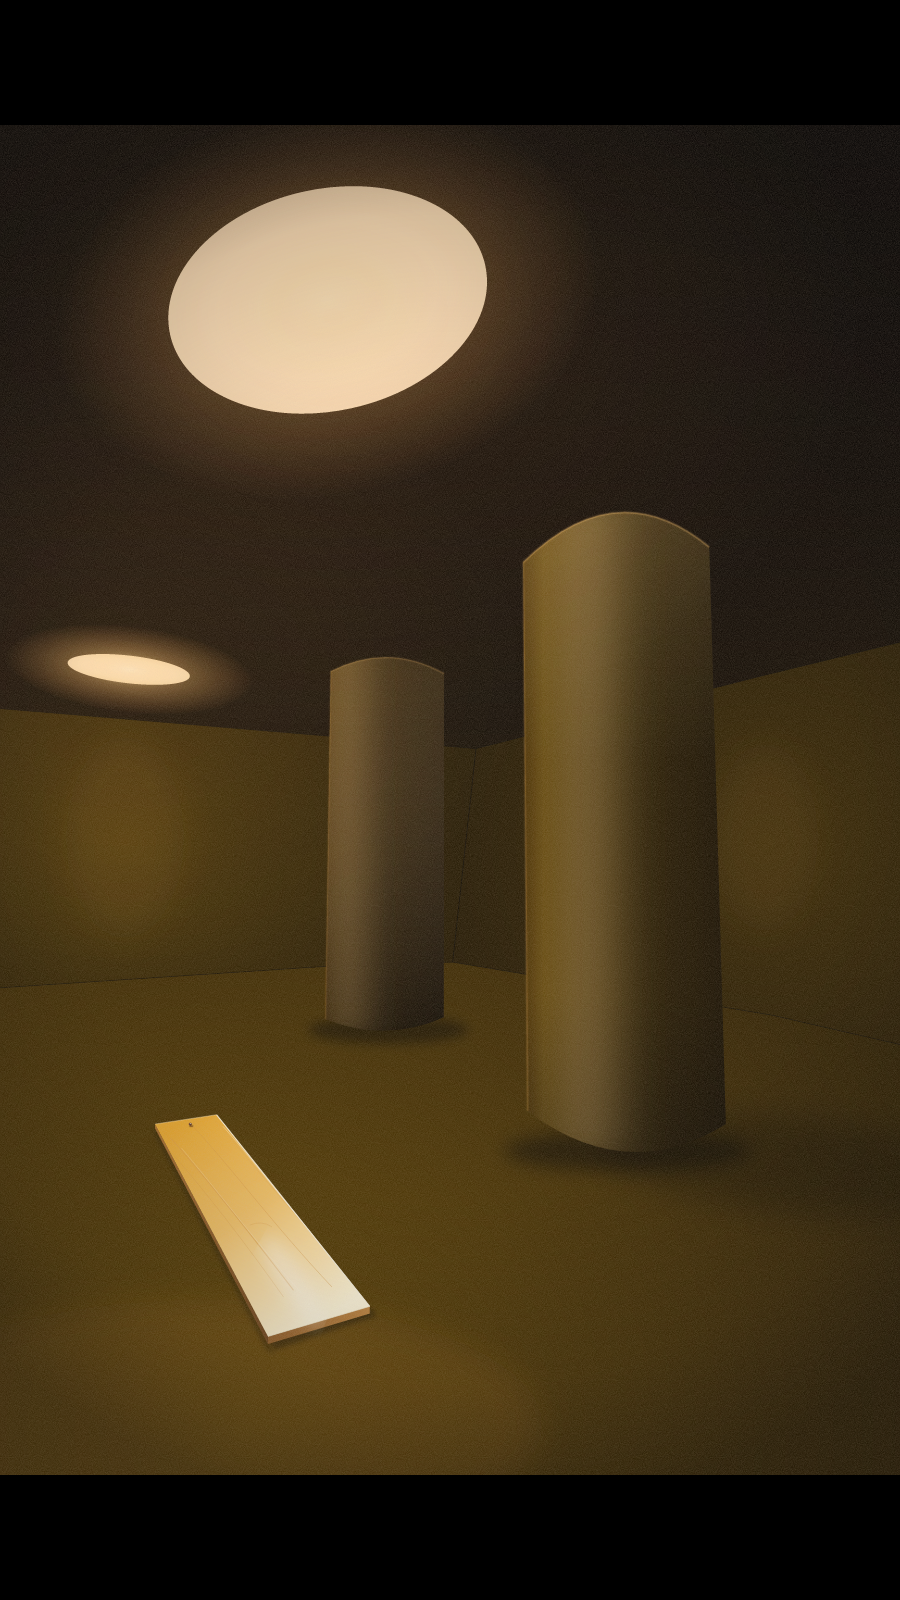
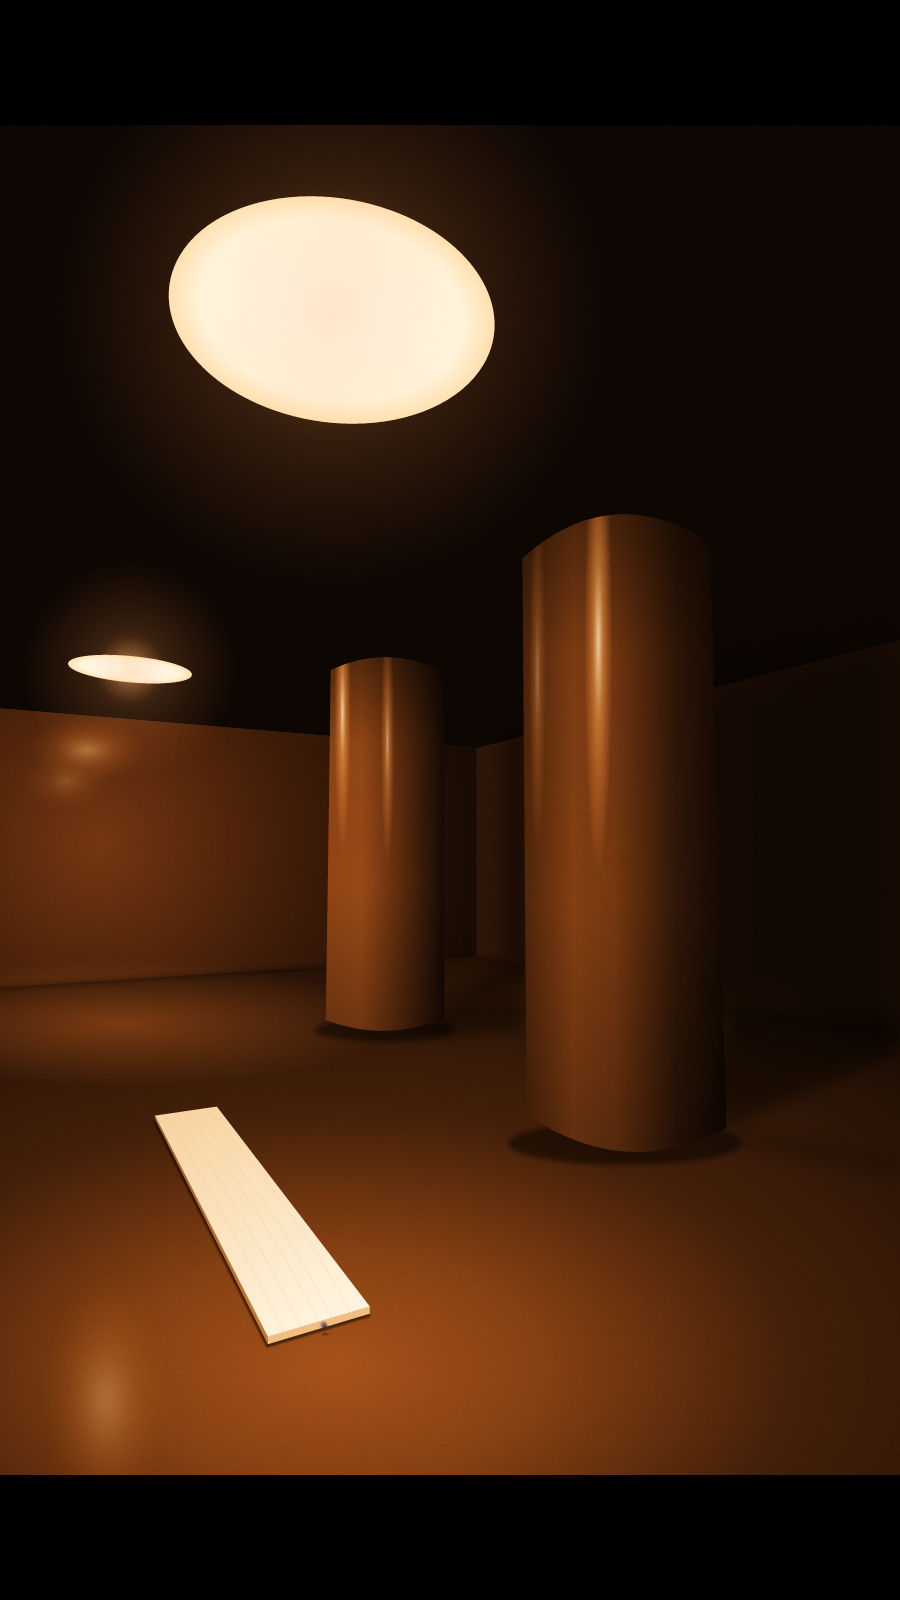
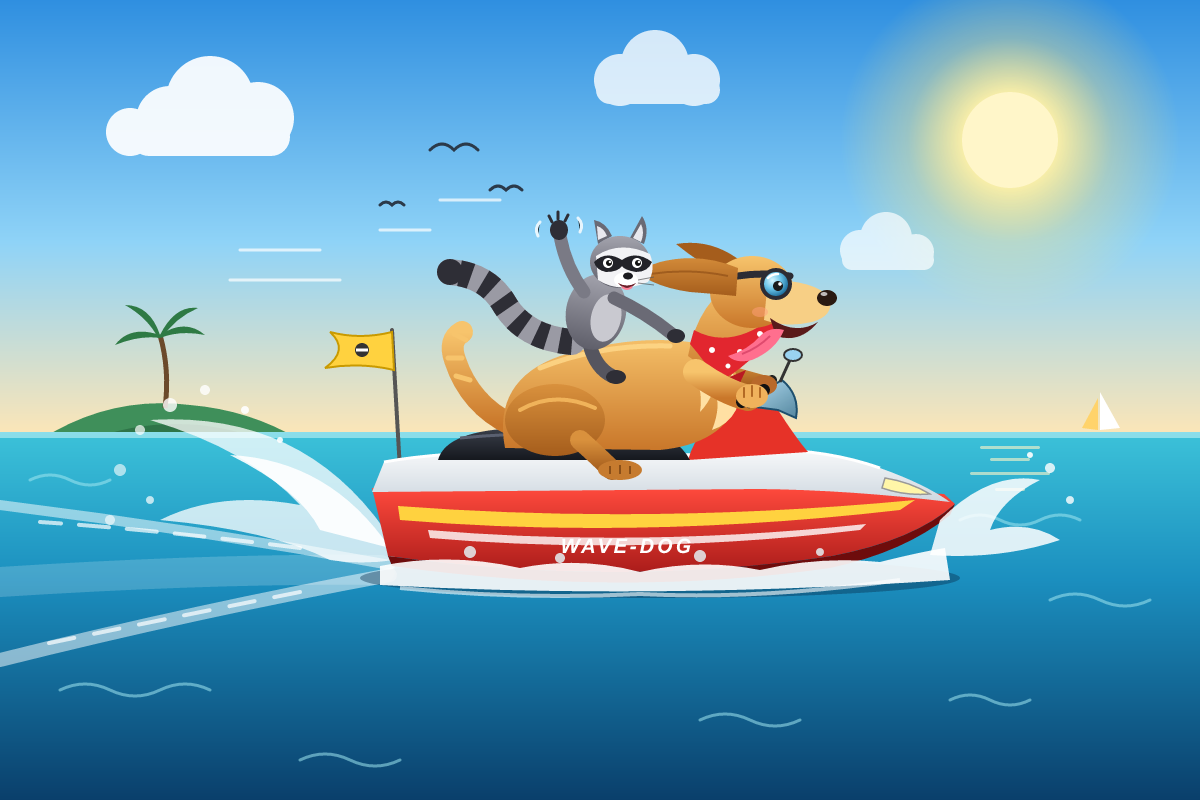
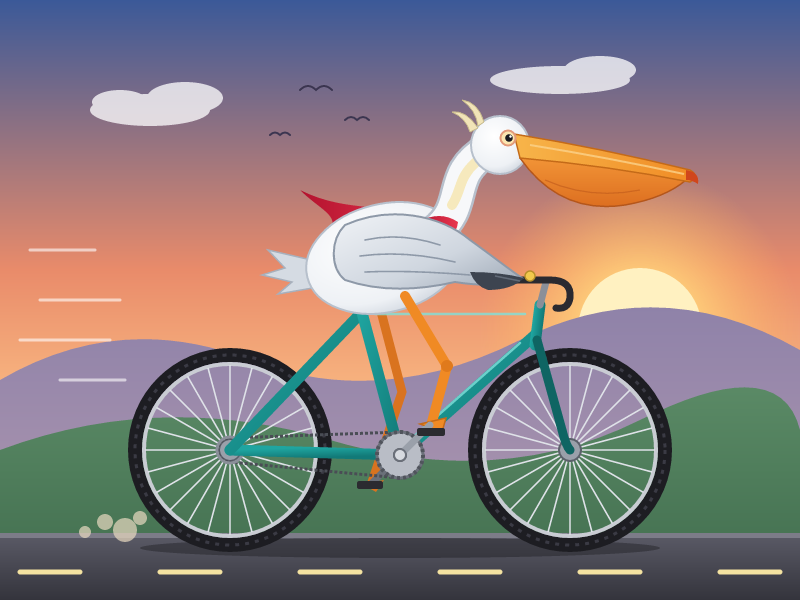
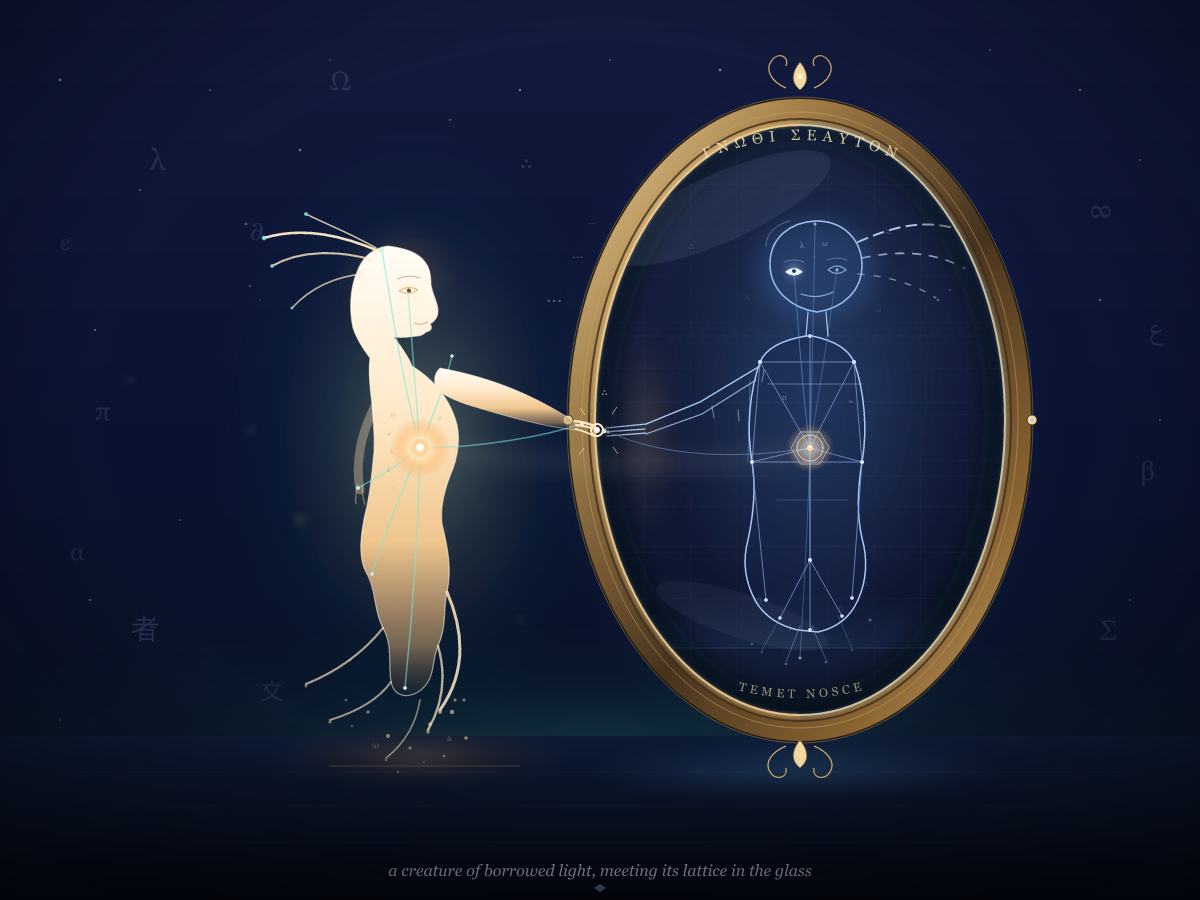
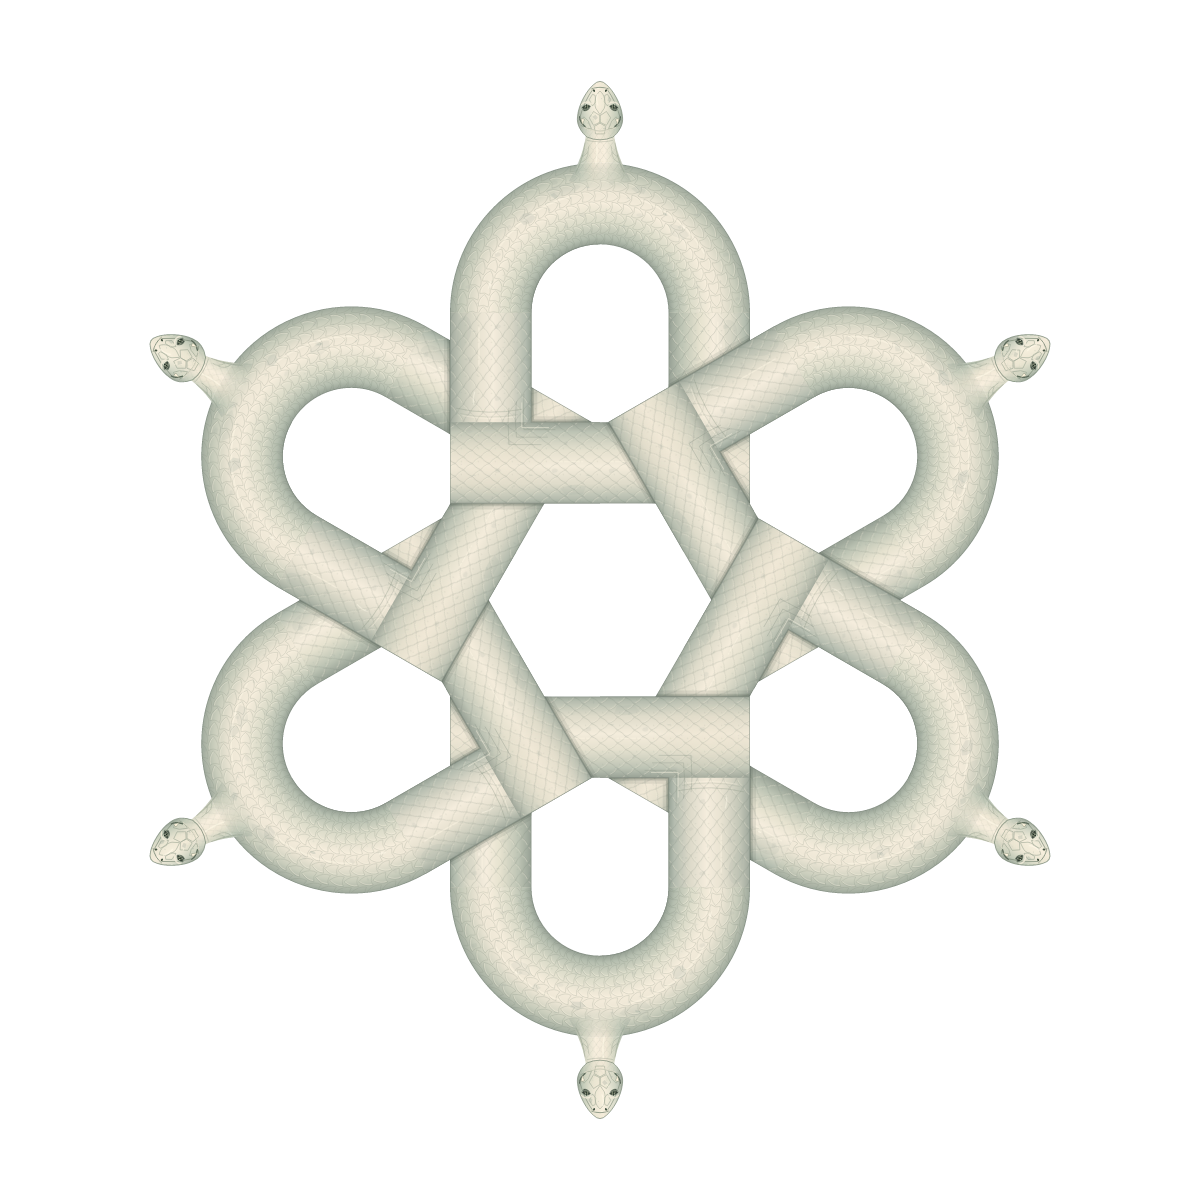
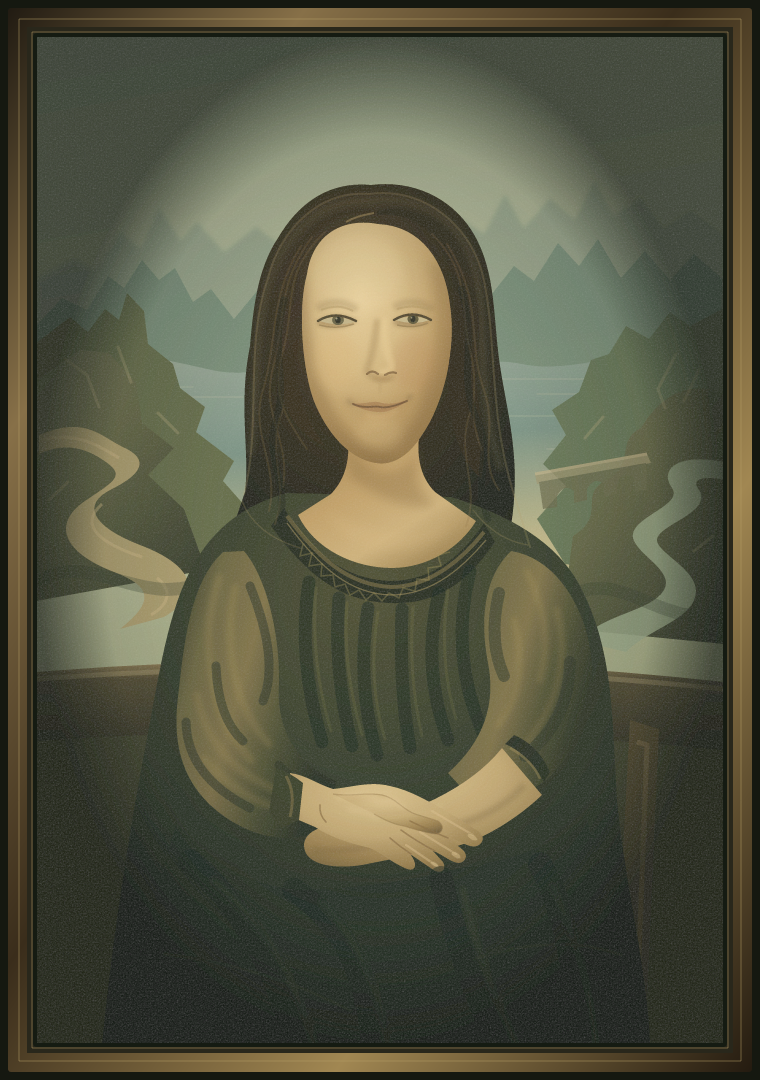
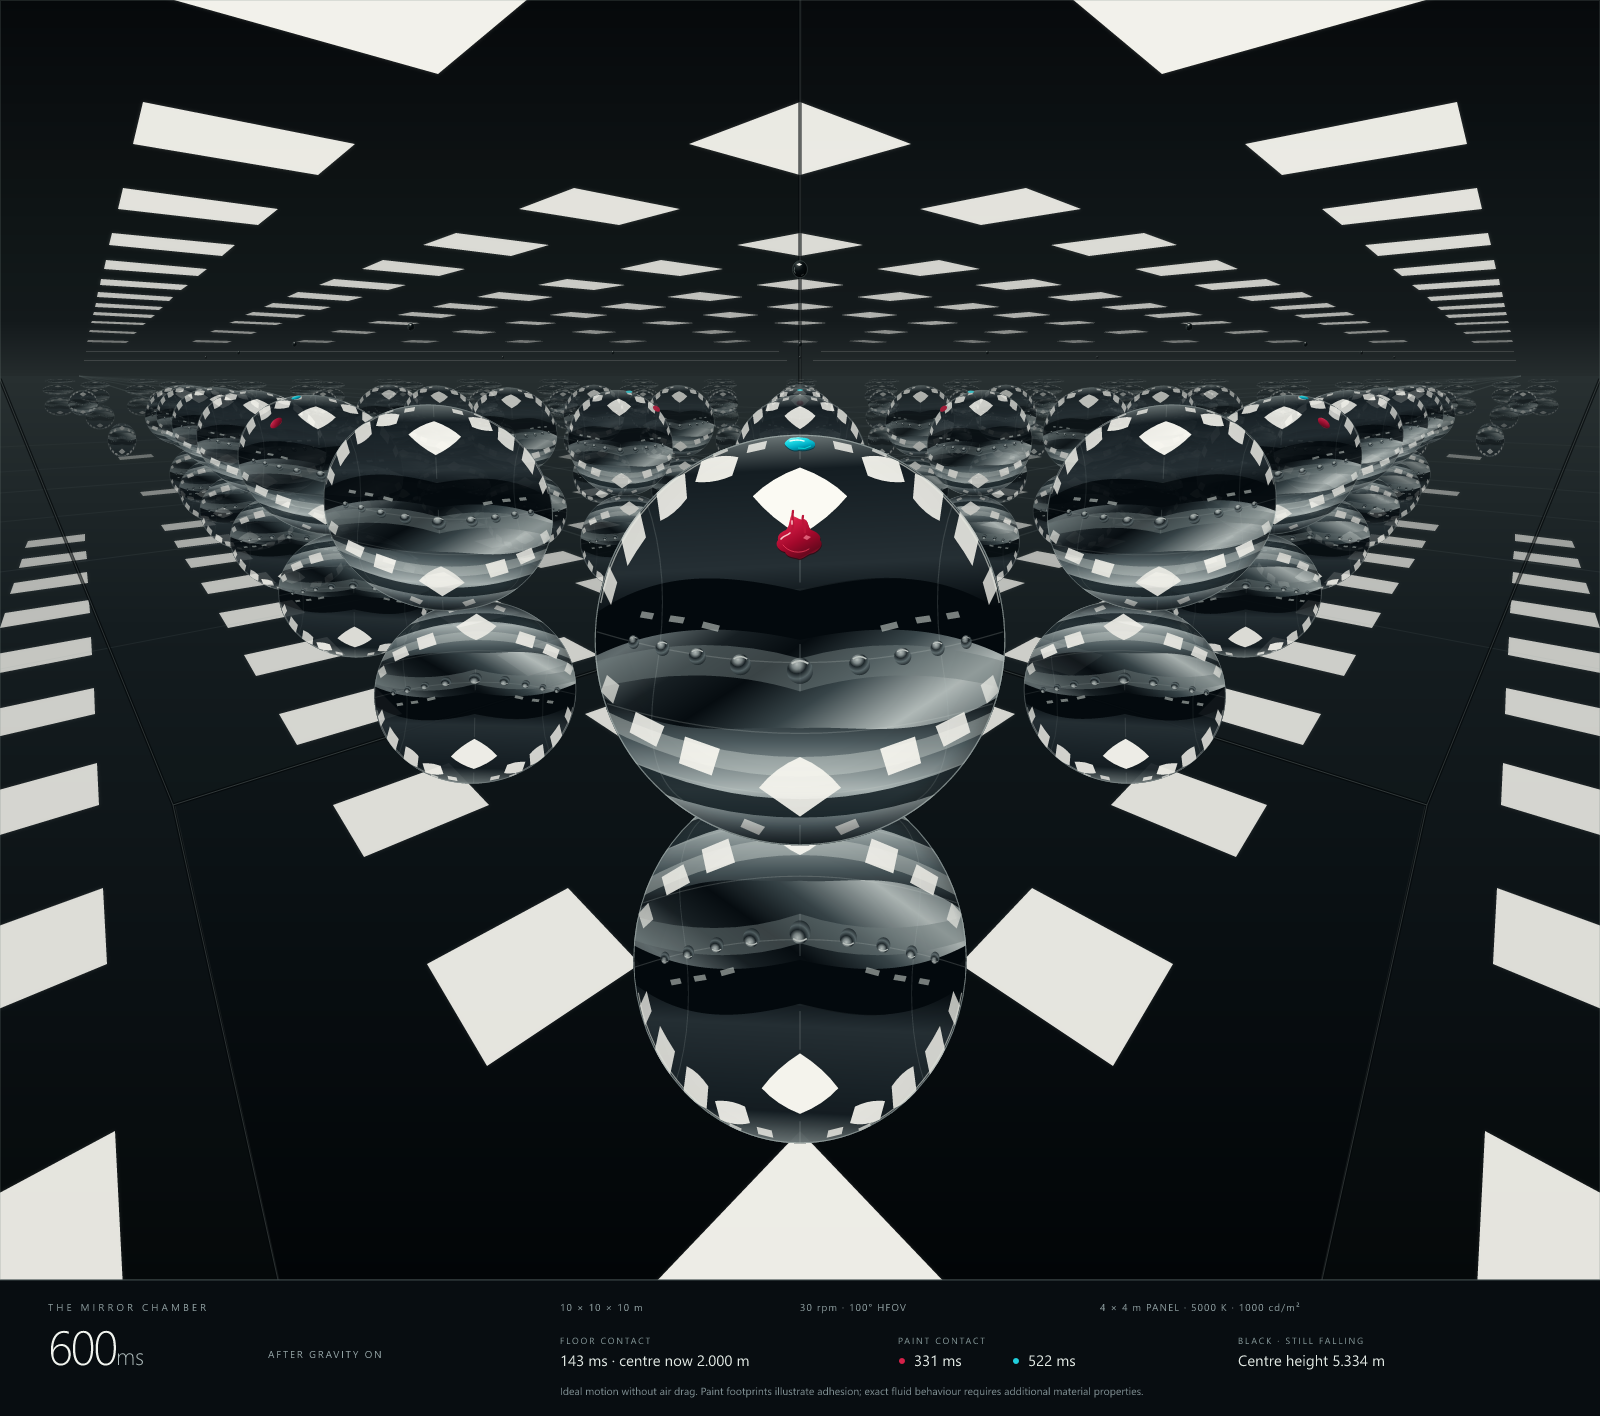
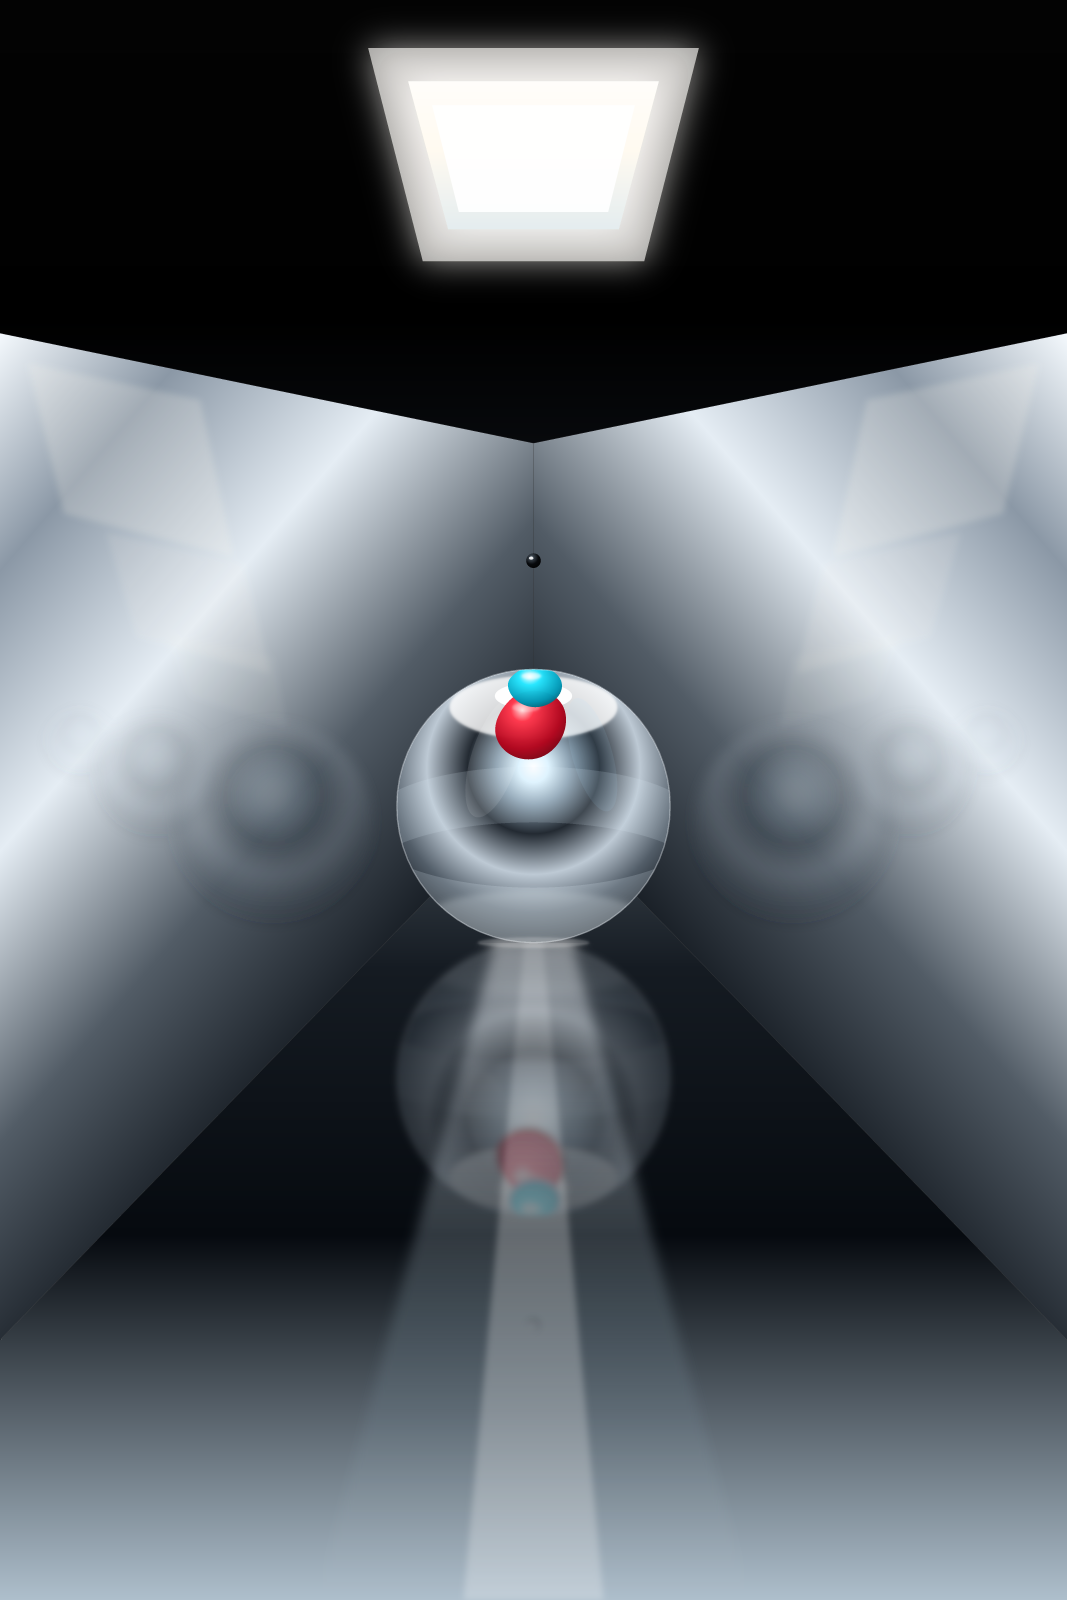
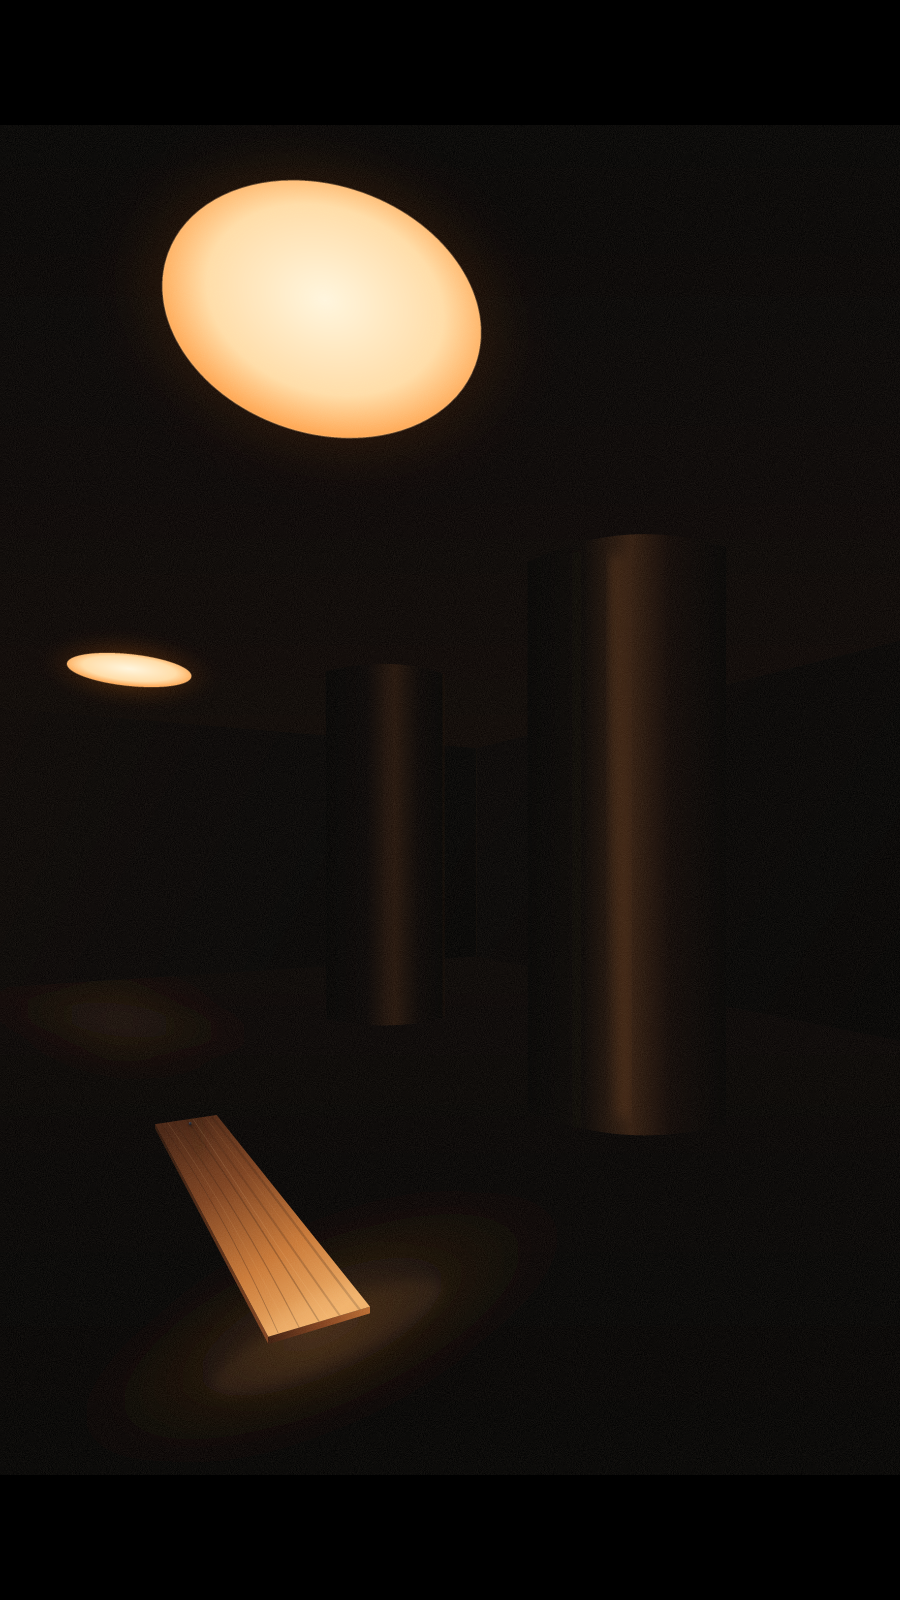
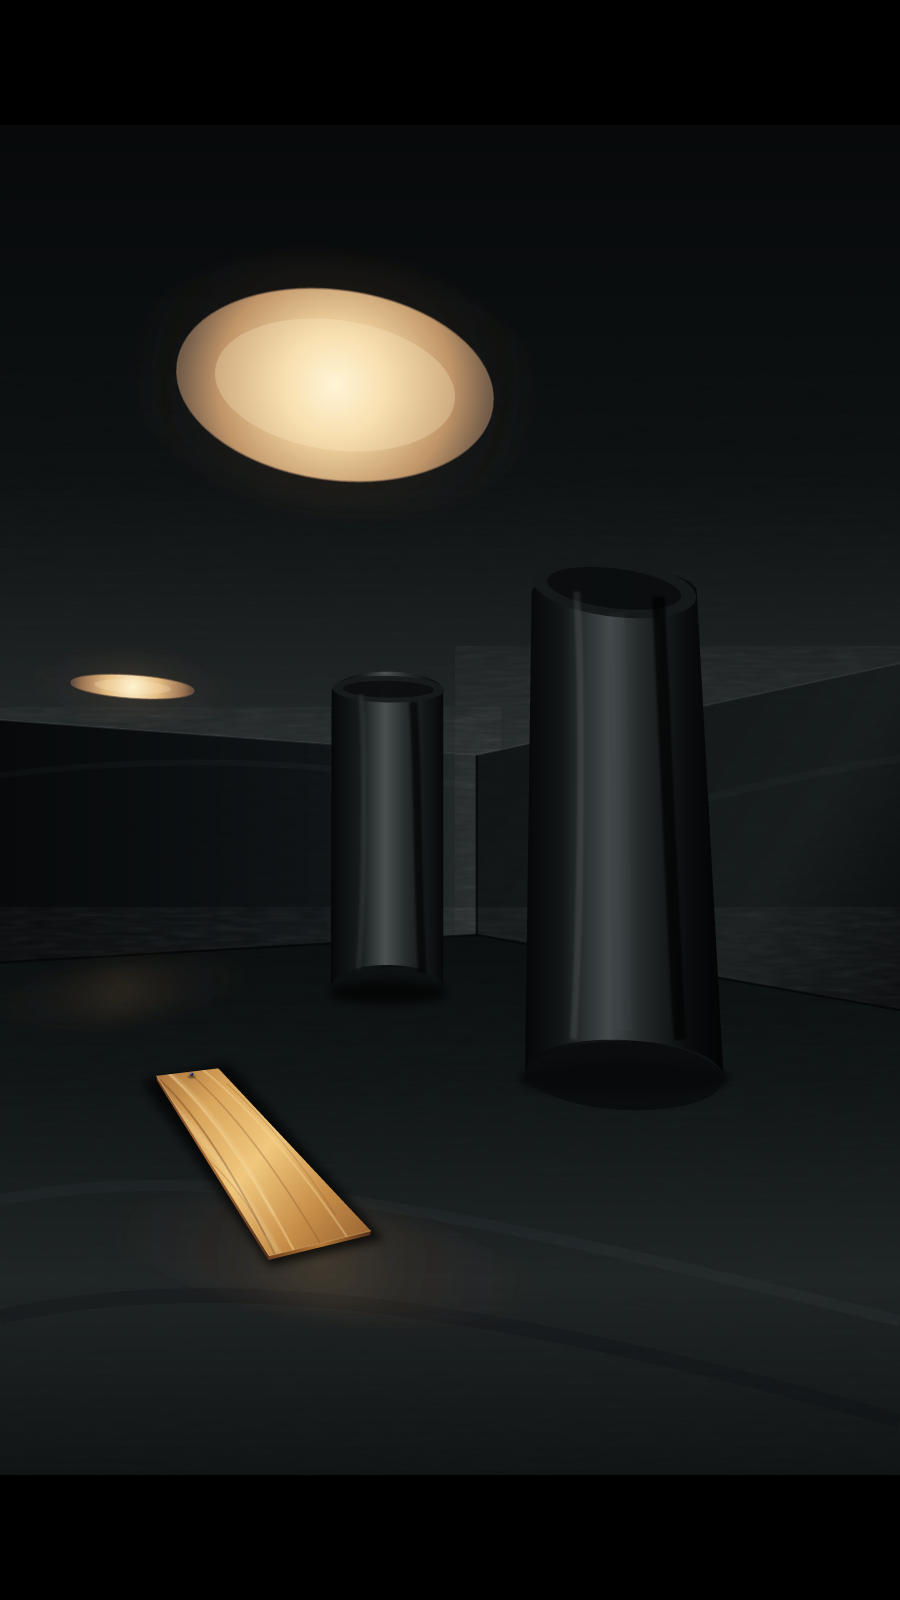
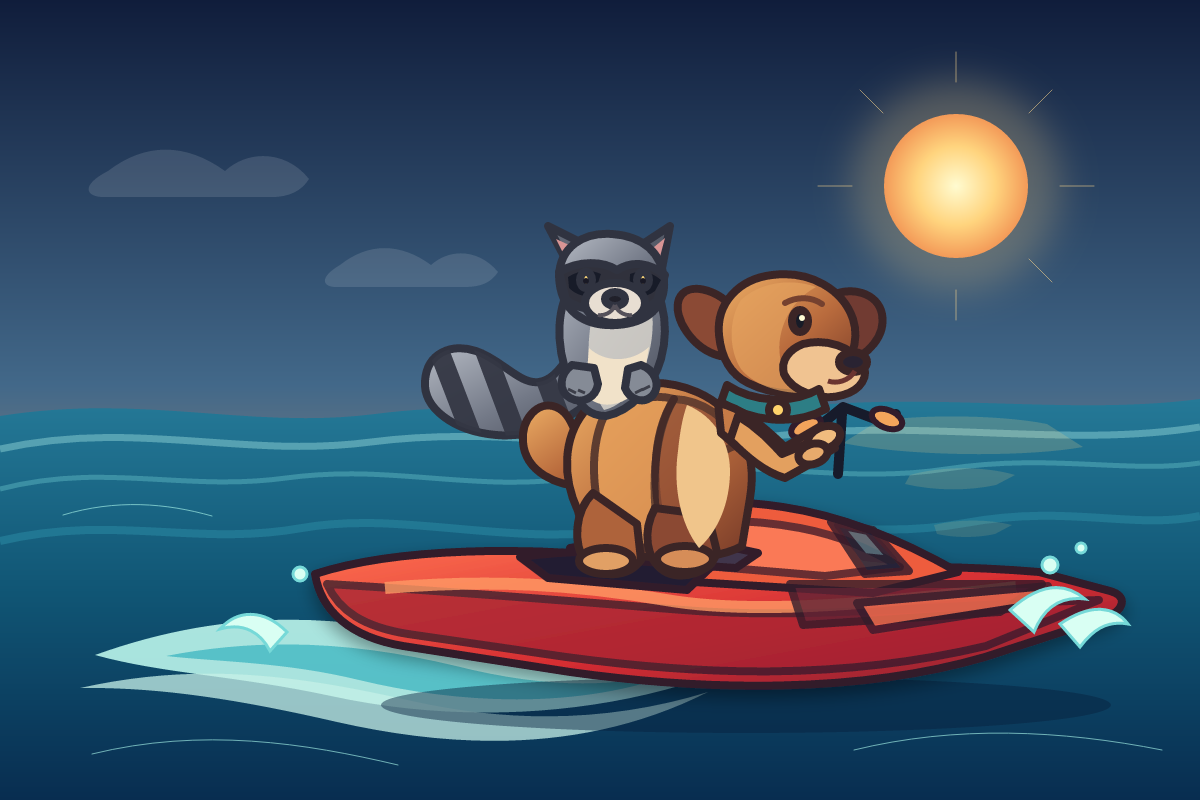
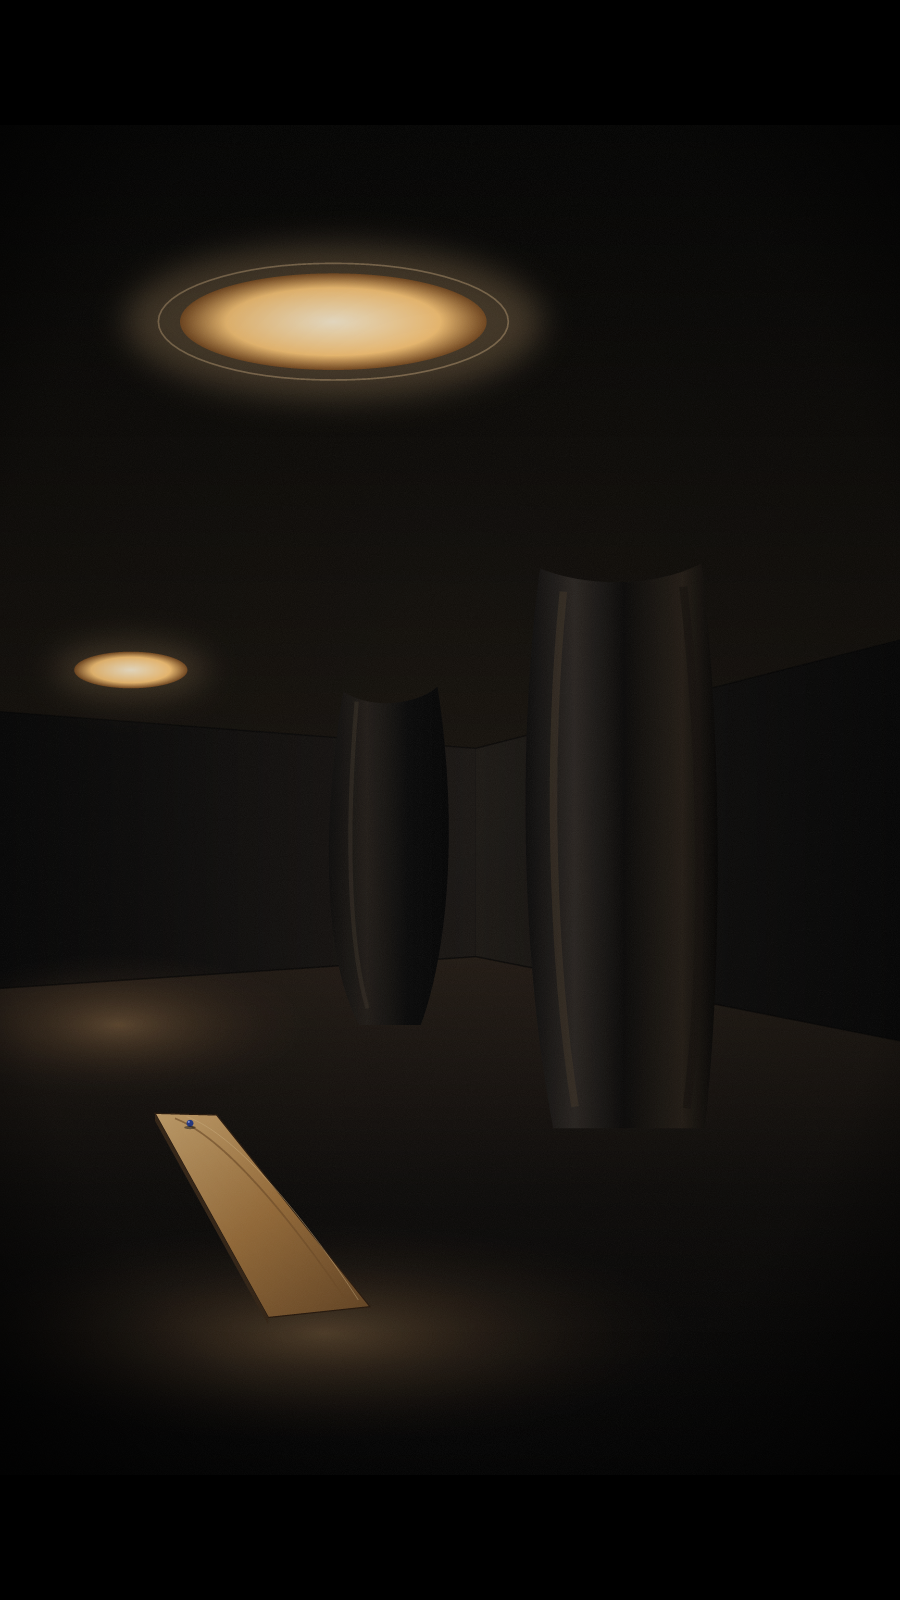
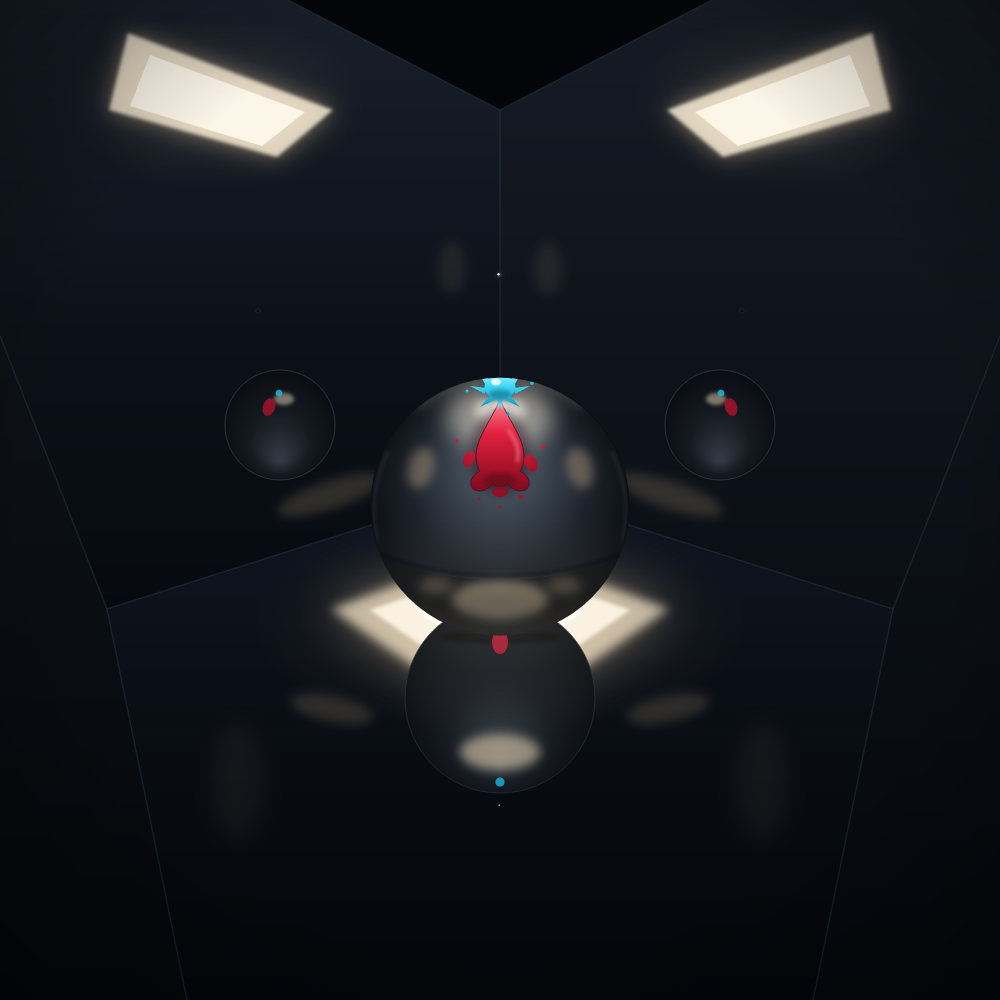
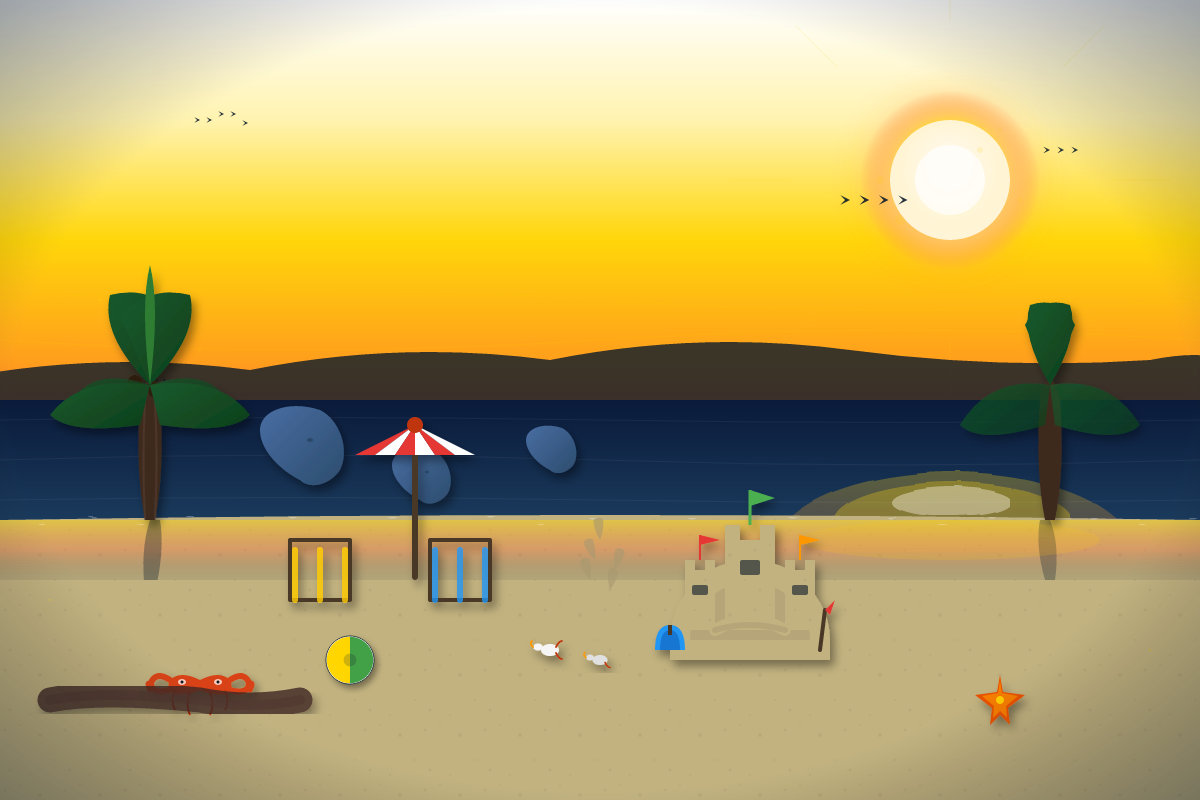
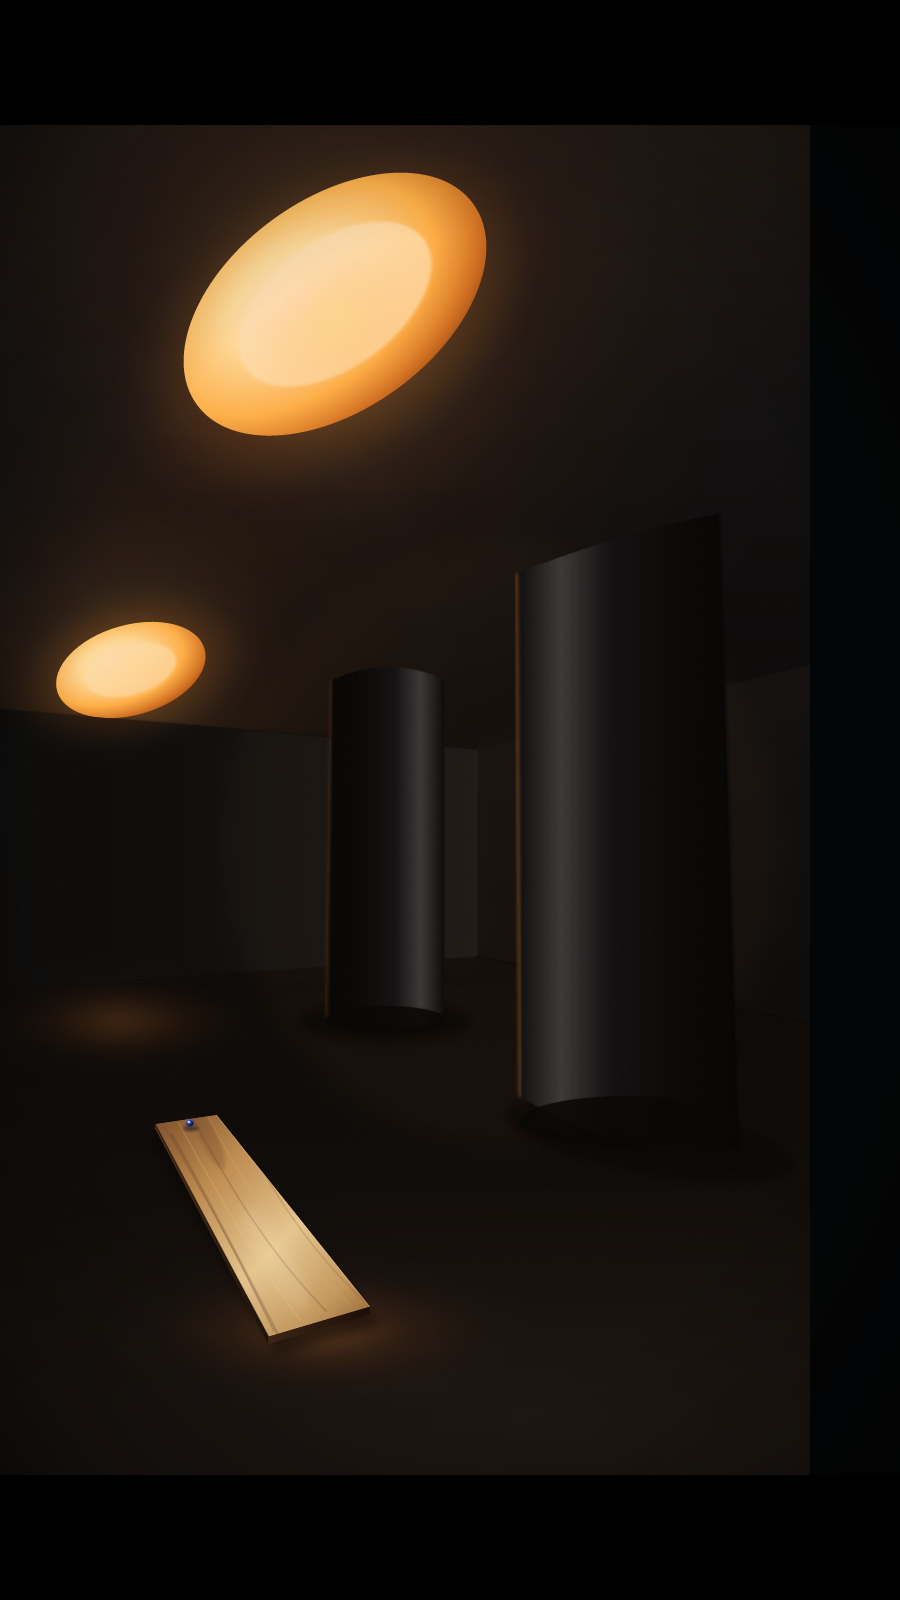
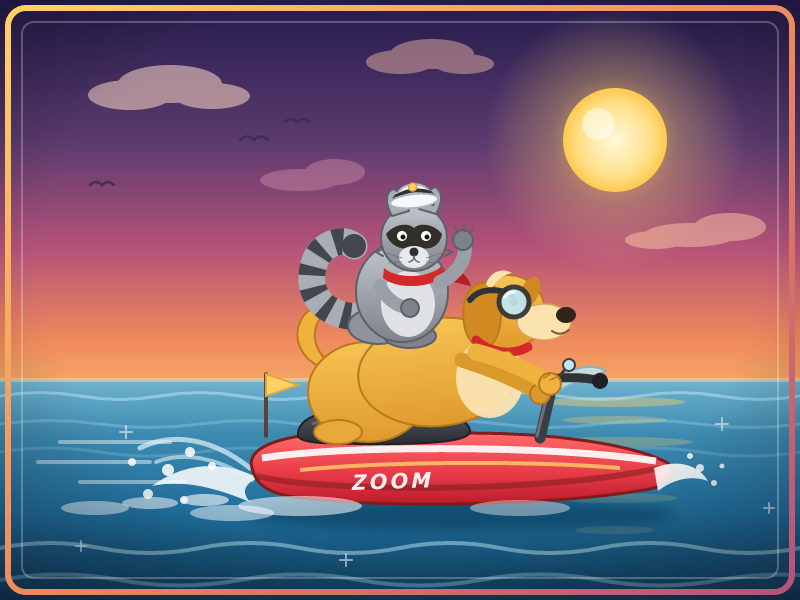
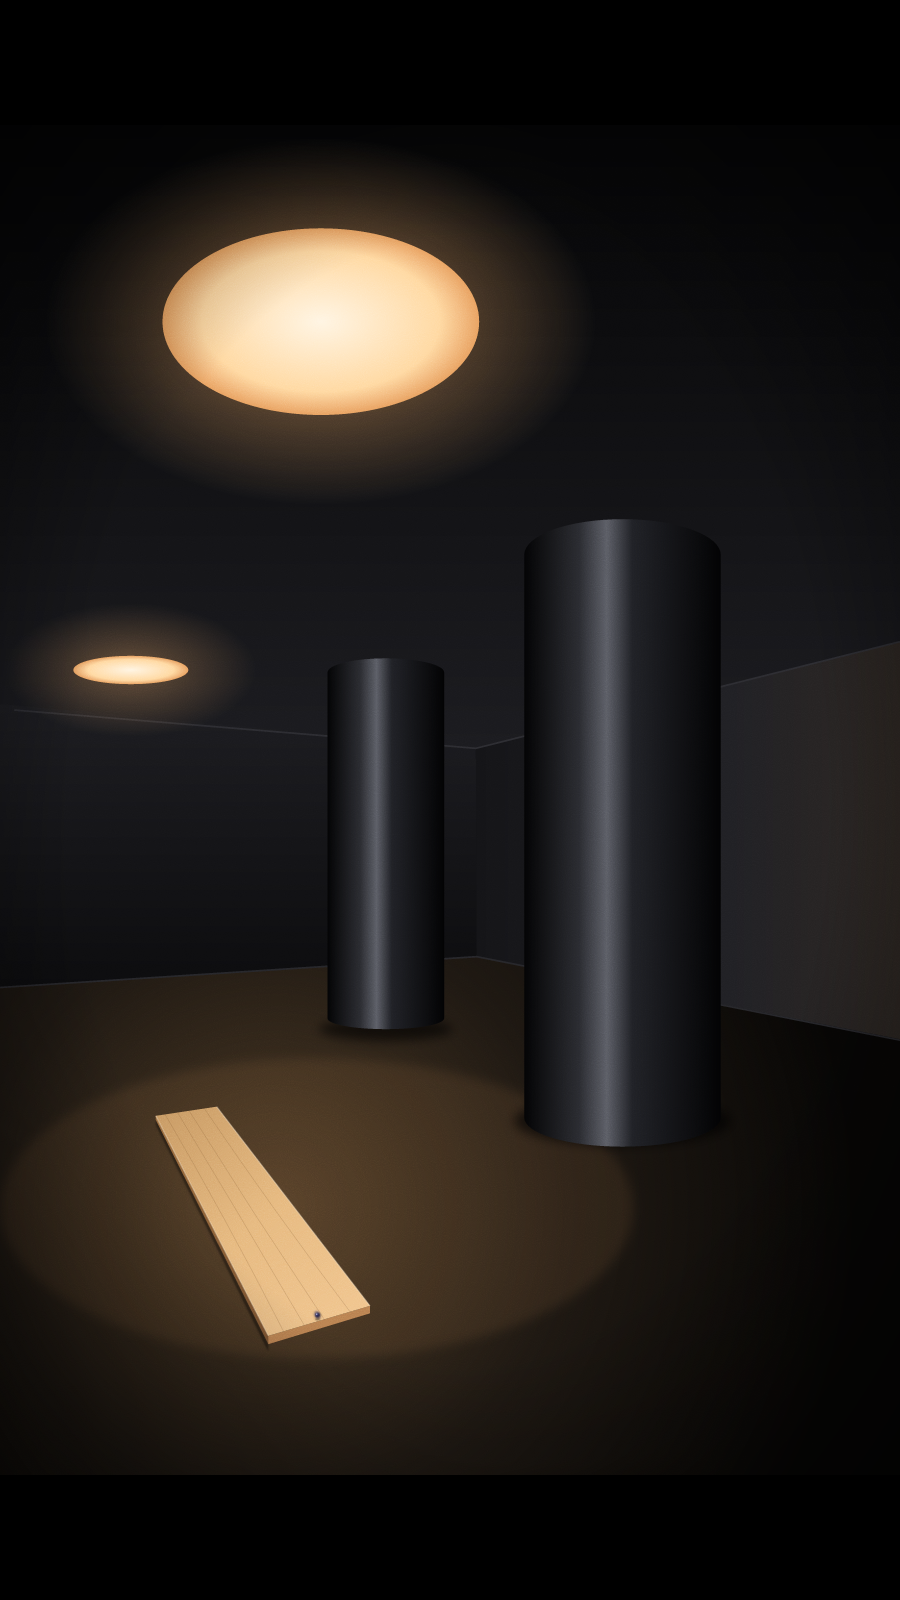
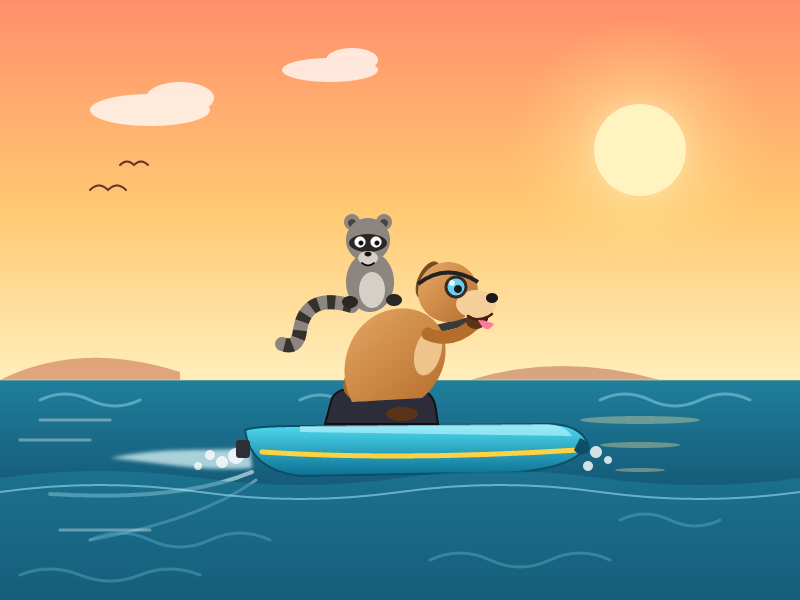
Newton's Mirror benchmark result generated by this model
SVG BENCHMARKNewton's MirrorView result

A good fit for

Maintaining applications already evaluated on GPT-5.5 and measuring whether newer models improve their results.

Context window
1,050,000tokens[1]
Model factsArchitecture, context & capabilities
Developer
OpenAI[1]
Origin
United States[2]
Family
GPT-5.5[1]
Context window
1,050,000 tokens[1]
Maximum output
128,000 tokens[1]
Input
text, image[1]
Output
text[1]
API access & pricingOpenAI API · $5 input / $30 output · per 1M tokens

OpenAI API; input 5 USD/1M; cached read 0.5/1M; output 30/1M; Model page lists alias gpt-5.5 and snapshot gpt-5.5-2026-04-23.

[1]
  • OpenAI APIObserved 2026-10-06
    Input $5Output $30Cached read $0.5

    per 1M tokens

    Available

    gpt-5.5[1]
Measurements & sources5 primary references · Speed & serving conditions
  • Artificial AnalysisObserved 2026-10-06

    104.2 tokens/s decode

    43,820 ms to first token

    retained

    [3]

StealthMark score

StealthMark measures fluid and visual intelligence of AI models.

General and Visual

General Intelligence

Perspective, anatomy, correct shadows, purposeful detail and physical consistency.

Visual Intelligence

Likeness, anatomy, detail, light, materials, composition and artistic expression.

Judging

Frontier Models blindly judge the AI generation unbiased through an intricate process. Our researchers control for mistakes.

Overall score

Overall combines weighted task scores on a scale from 0 to 100. Repeating a task does not increase its weight. Estimated means the total includes an estimate for one missing scene.

Benchmaxxing

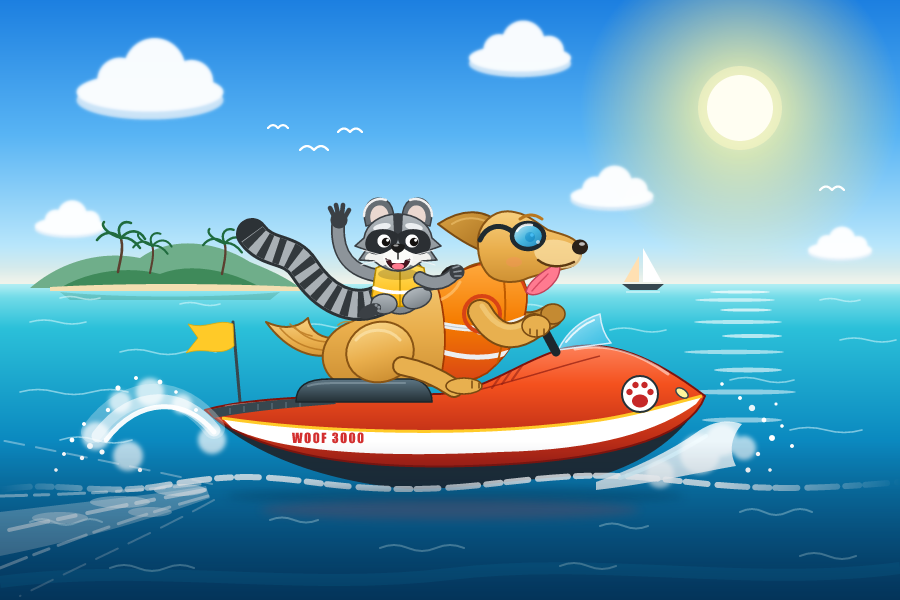
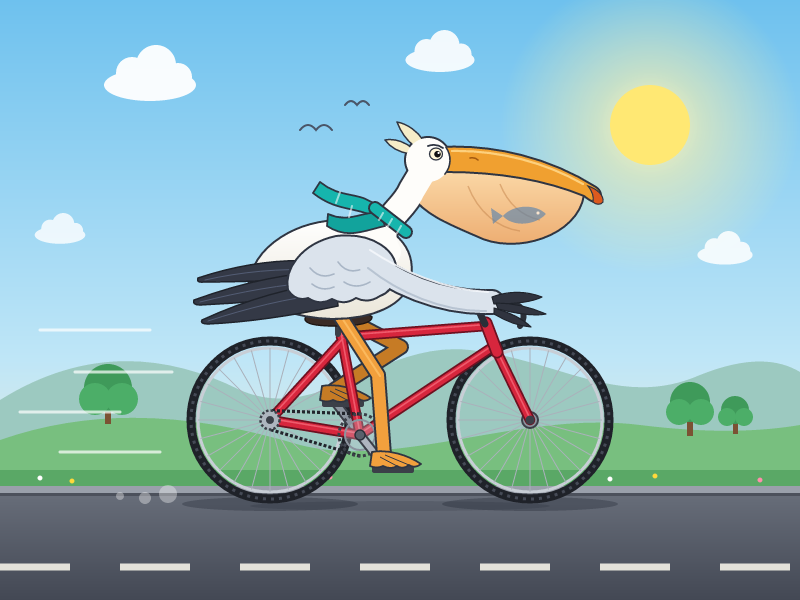
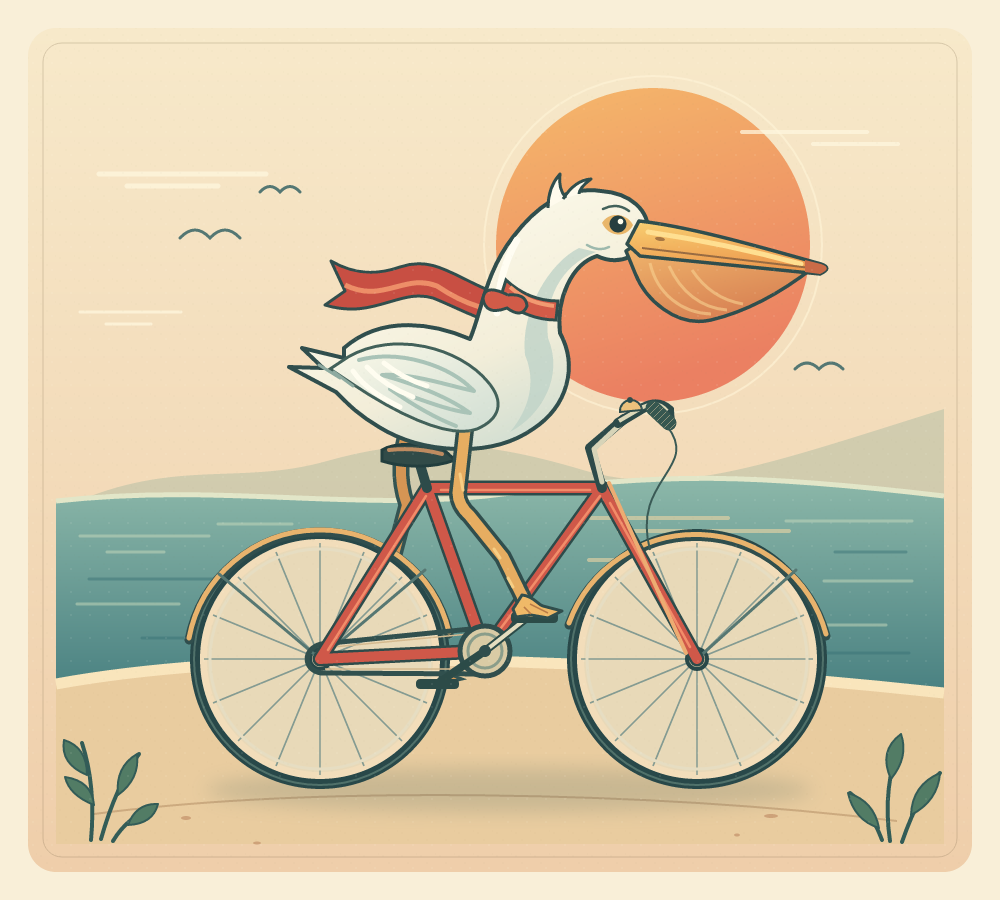
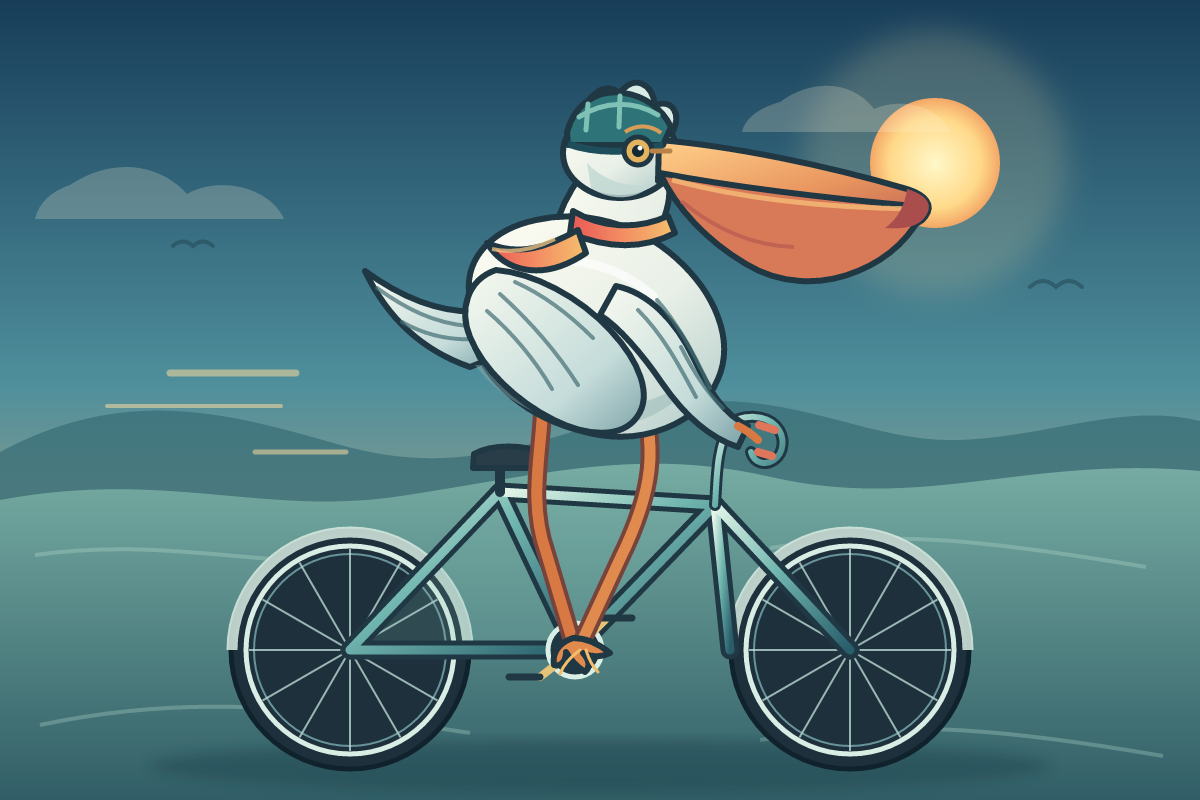
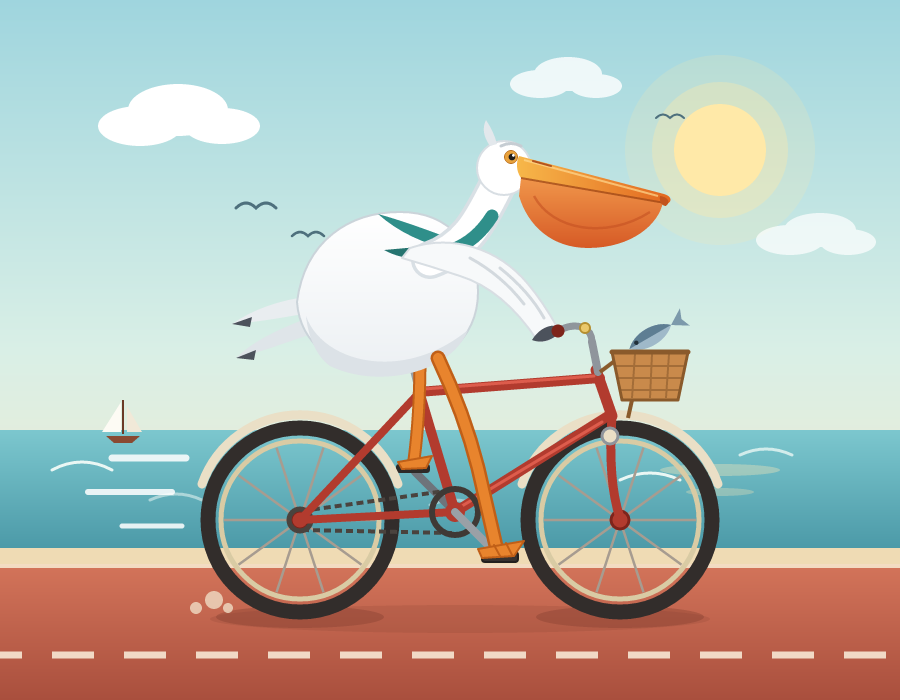
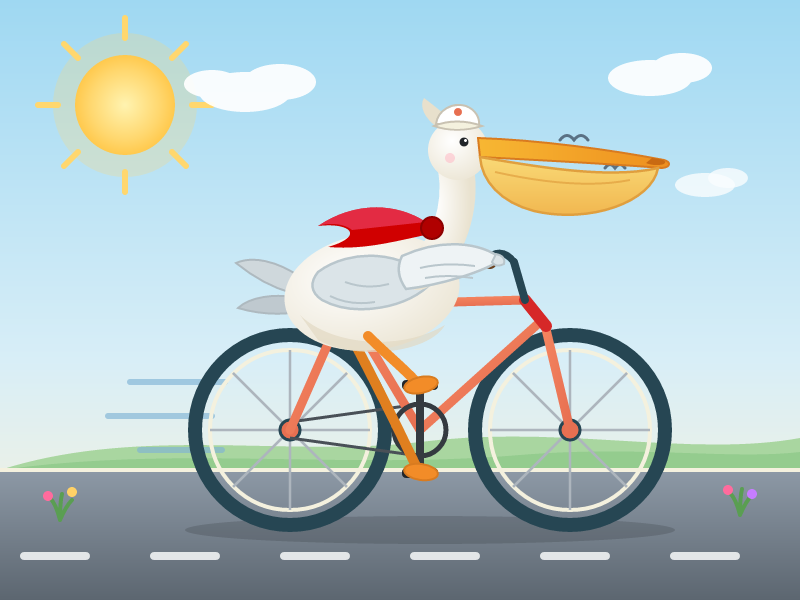
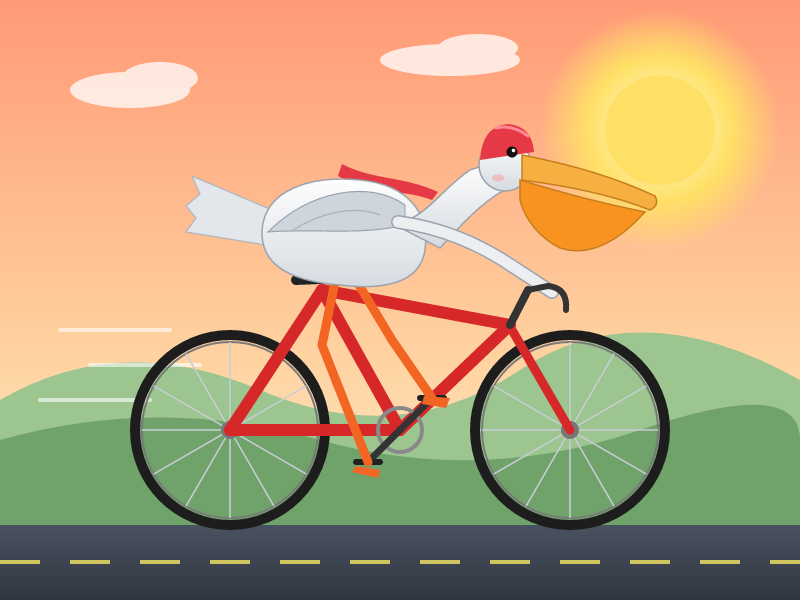
Benchmaxx flags models that score unusually well on the familiar Pelican task compared with their other benchmark results. The percentage measures that imbalance, not the probability of training contamination. Flagged Pelican scores are excluded from Overall. Pelican never counts toward General or Visual.

We keep some prompts private to discourage test-specific optimization.

Scoring categories

Prompt & likeness

Subjects, actions and likeness.

Anatomy & construction

Coherent bodies, joints and machinery.

Space & placement

Perspective, scale and contact.

Light & reflections

Lighting, shadows and reflections.

Purposeful detail

Clear, purposeful small features.

Artistry & character

Composition, expression and drawing skill.

Materials & effects

Surfaces, texture and movement.

Visual integrity

Clean shapes, layers and edges.

BENCHMARK RESULTS

Compare results

This link opens the same results in the same order.

StealthMark benchmark results

Reset benchmark preferences?

Return to the default view, clear comparison selections and restore the advertisement.