SelfieVisual construction
and creative interpretation
Benchmark task
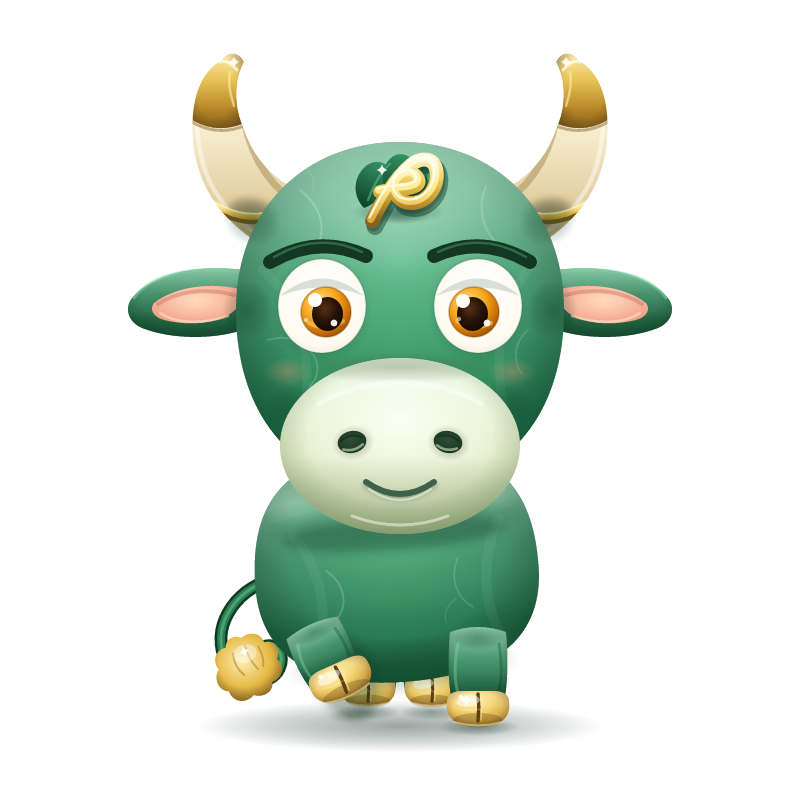
A rounded jade bull raising a hoof tests anatomy, balance and the appearance of polished stone and metal.
First run
 stealthmodels.
MODEL BENCHMARKS
Formerly Ox Alpha, this MIT-licensed multimodal MoE combines a million-token context with low hosted token rates. Read the Ox Alpha reveal and model guide →
DATASHEET
A good fit forCost-conscious coding and multimodal agents through an API, or self-hosting where several hundred gigabytes of model memory are available.
GLM-5.3-FlashOther modelsMedian
Vercel AI Gateway / DigitalOcean route; input 0.15 USD/1M; cached read 0.03/1M; output 0.5/1M; A specific gateway provider route; Vercel lists other providers with different prices and limits.
per 1M tokens
z-ai/glm-5.3-flashper 1M tokens
Available
zai/glm-5.3-flashz-ai/glm-5.3-flashz-ai/glm-5.3-flashzai/glm-5.3-flashOur speed measurement: 88.98 tokens/s on average, from 18.65 to 127.37 tokens/s.
119 tokens/s decode
500 ms to first token
53 tokens/s decode
How StealthMark scores models · General and Visual Intelligence
Benchmark results
LicenseMIT
Model IDz-ai/glm-5.3-flash
 StealthMark#19of 53General42.3Visual59.7
A rounded jade bull raising a hoof tests anatomy, balance and the appearance of polished stone and metal.
First run
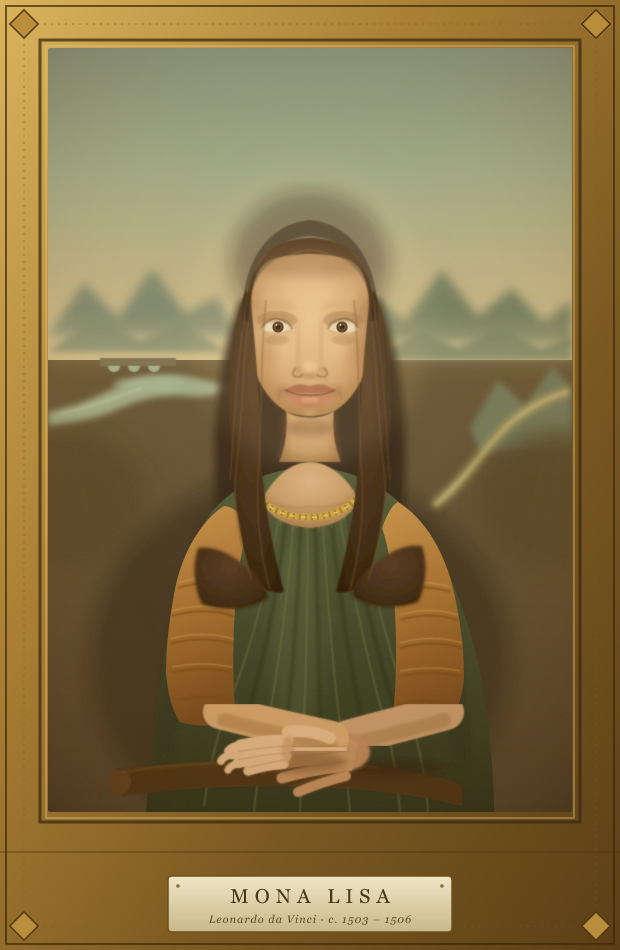
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
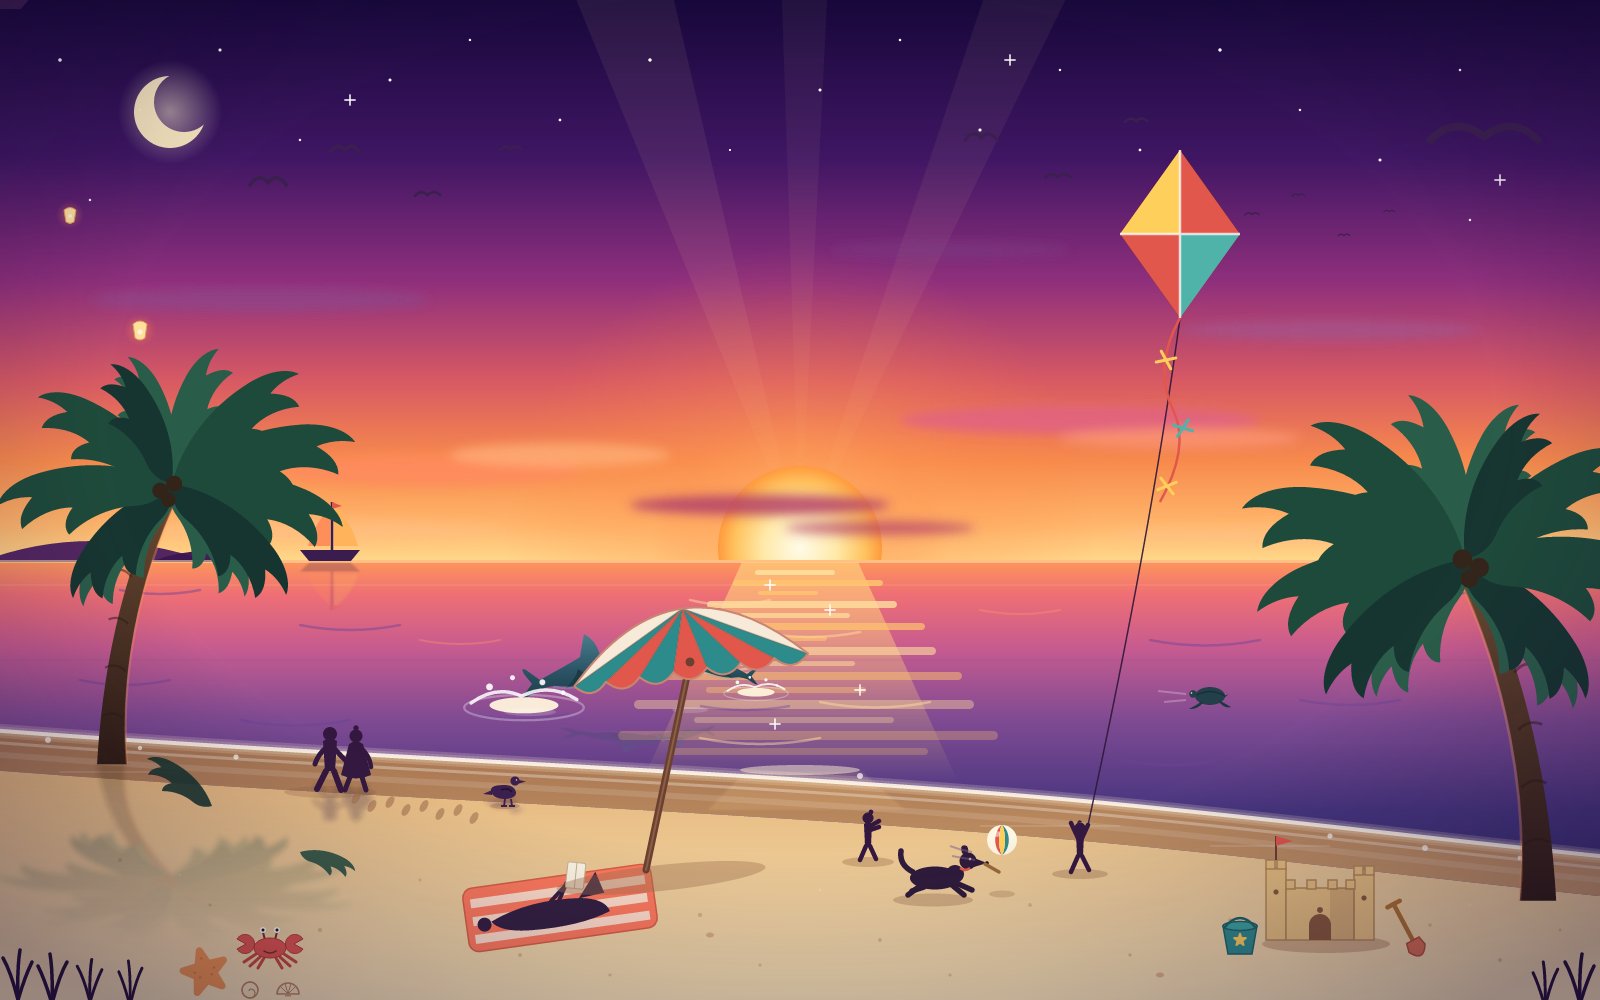
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
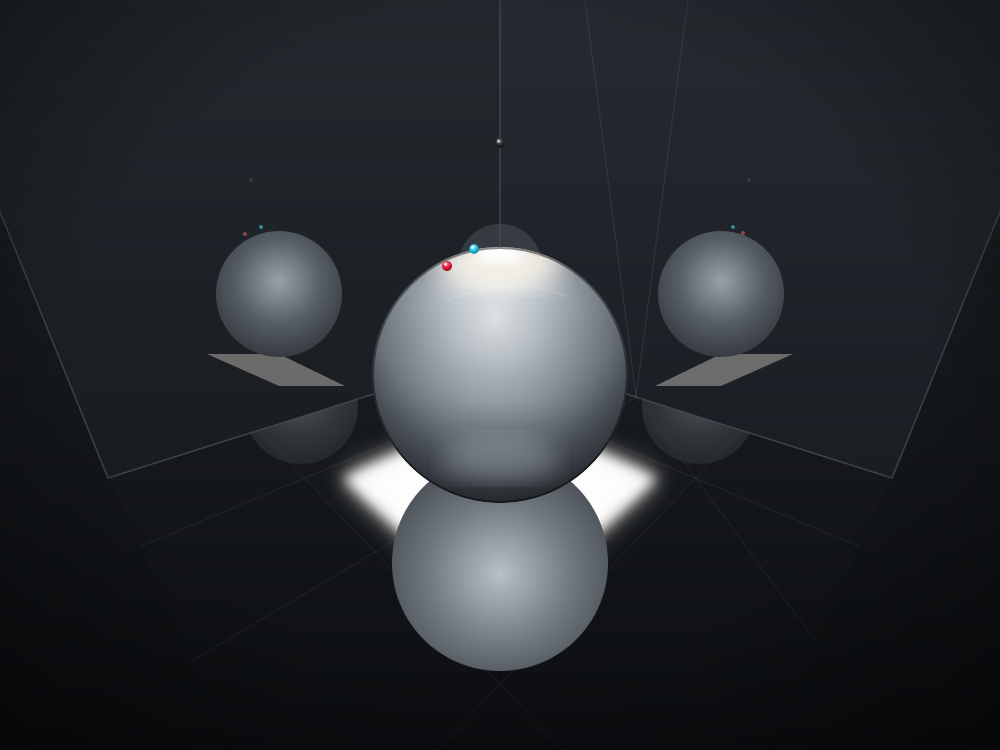
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
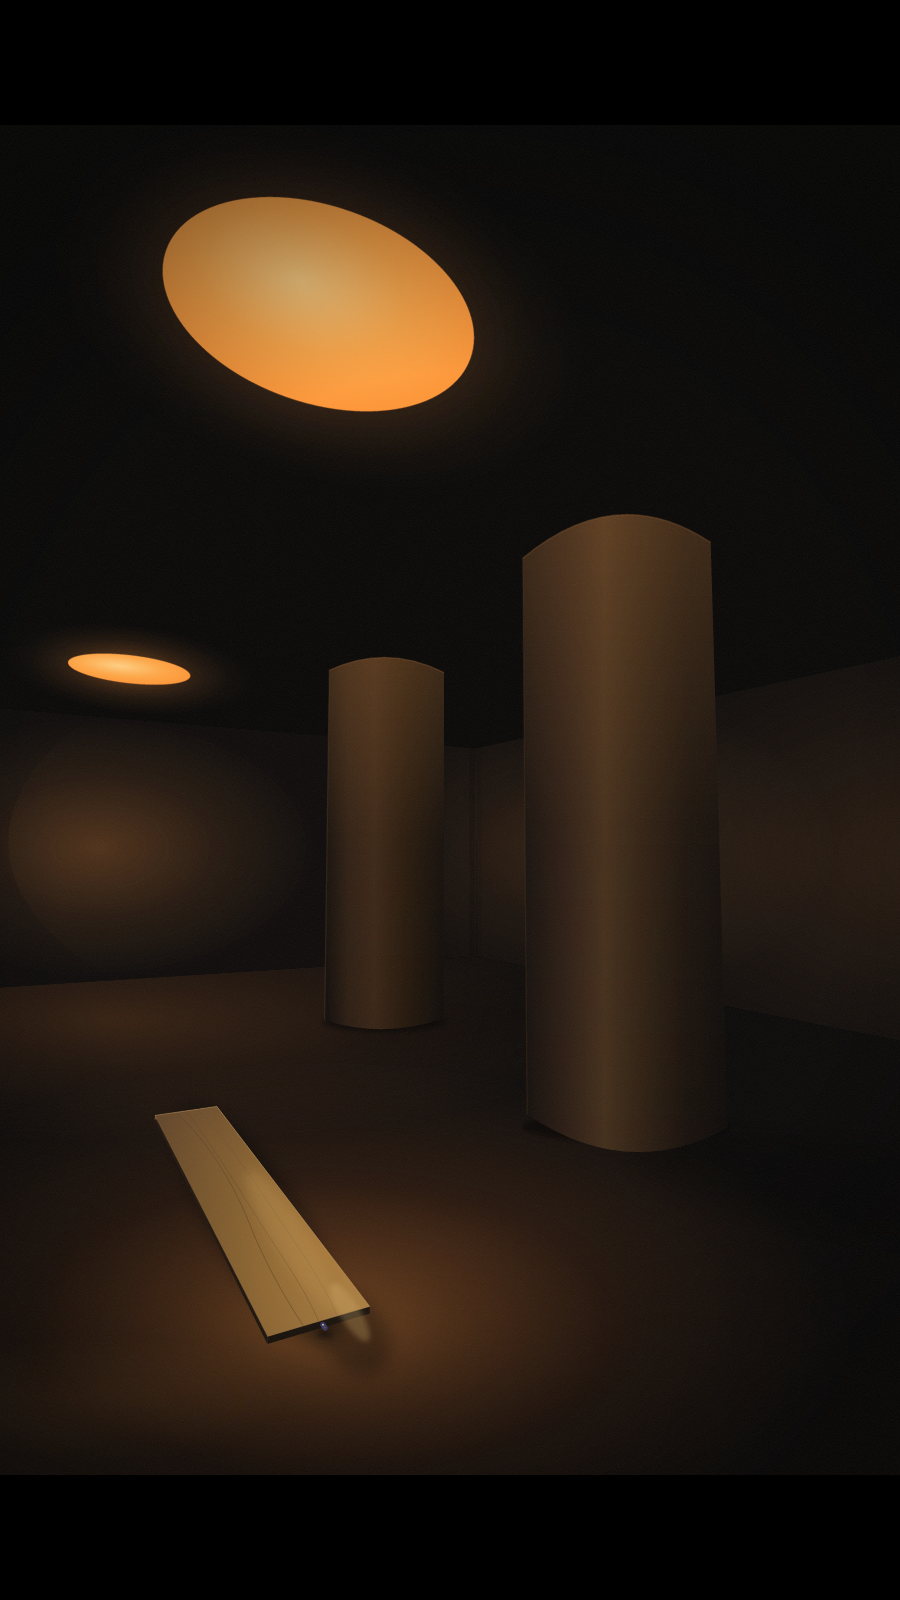
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
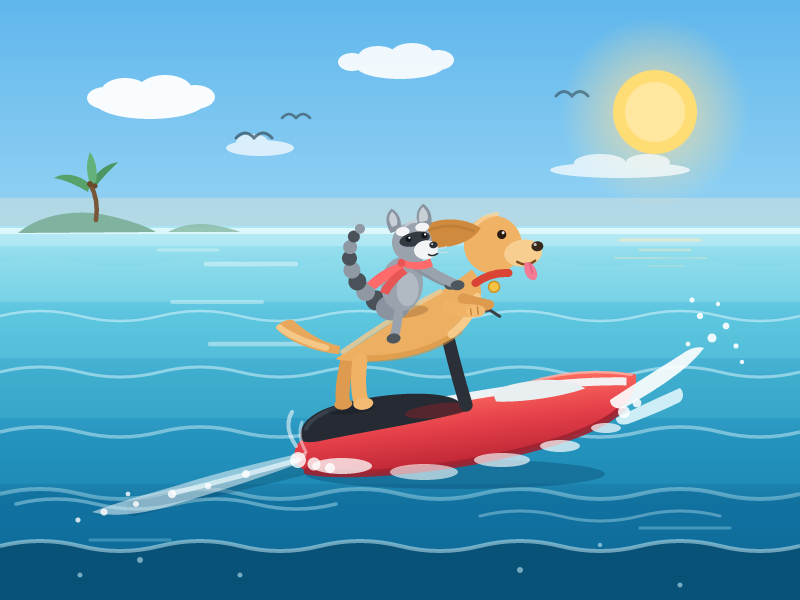
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
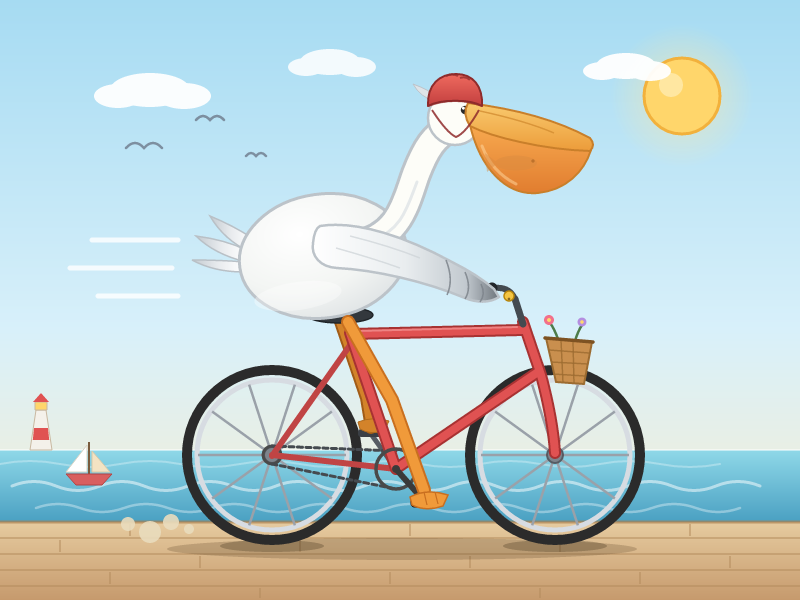
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
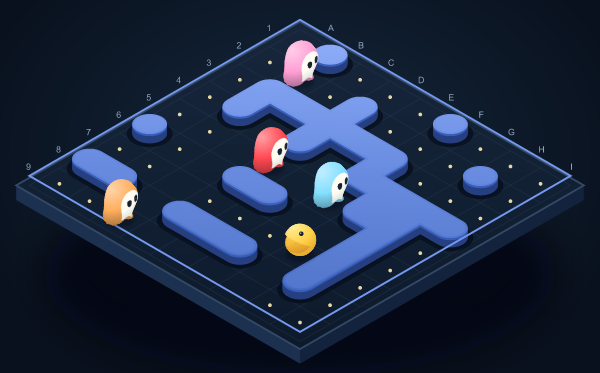
Try another task or widen your model selection.
StealthMark scoreStealthMark measures how well a model’s abilities carry over to original, demanding tasks it could not have trained for: physical and spatial reasoning, planning across many steps, and precise visual work. How StealthMark works explains every benchmark, what it tests and why it is hard.
The ability to reason, plan, solve problems and understand how things relate and behave. A high score means it thinks hard problems through, from careful analysis to plans that span many steps.
The ability to understand visual intent and turn ideas, descriptions and plans into coherent, effective visuals. A high score means design ideas come out the way you meant them, in illustrations, icons, diagrams or interface visuals.
Overall shows how well a model’s abilities carry over to original, demanding tasks, weighting every benchmark into one score from 0 to 100. Estimated means the total includes an estimate for one missing scene.
Scores reflect how well each result meets the benchmark requirements. Game scores come from the recorded play: the points earned on each level and how each level ended. How StealthMark keeps scores honest.
Each game is a sequence of levels, and earlier moves carry into later levels. A level that was not played is shown as not played and never counts as zero. Play every level of Latch or Foresight yourself to get a score calculated like the models’.
Good results with little thinking score high. On each task, a model’s result and reasoning tokens are compared with every other model and combined with the Balanced Integration Score (Liesefeld & Janczyk, 2019); 50 is average. Single step shows how much reasoning a model needs to understand and solve one problem, multi-step how efficiently it keeps working on a task by building on its earlier reasoning, as in agentic workflows. Not part of StealthMark.