SelfieVisual construction
and creative interpretation
Benchmark task
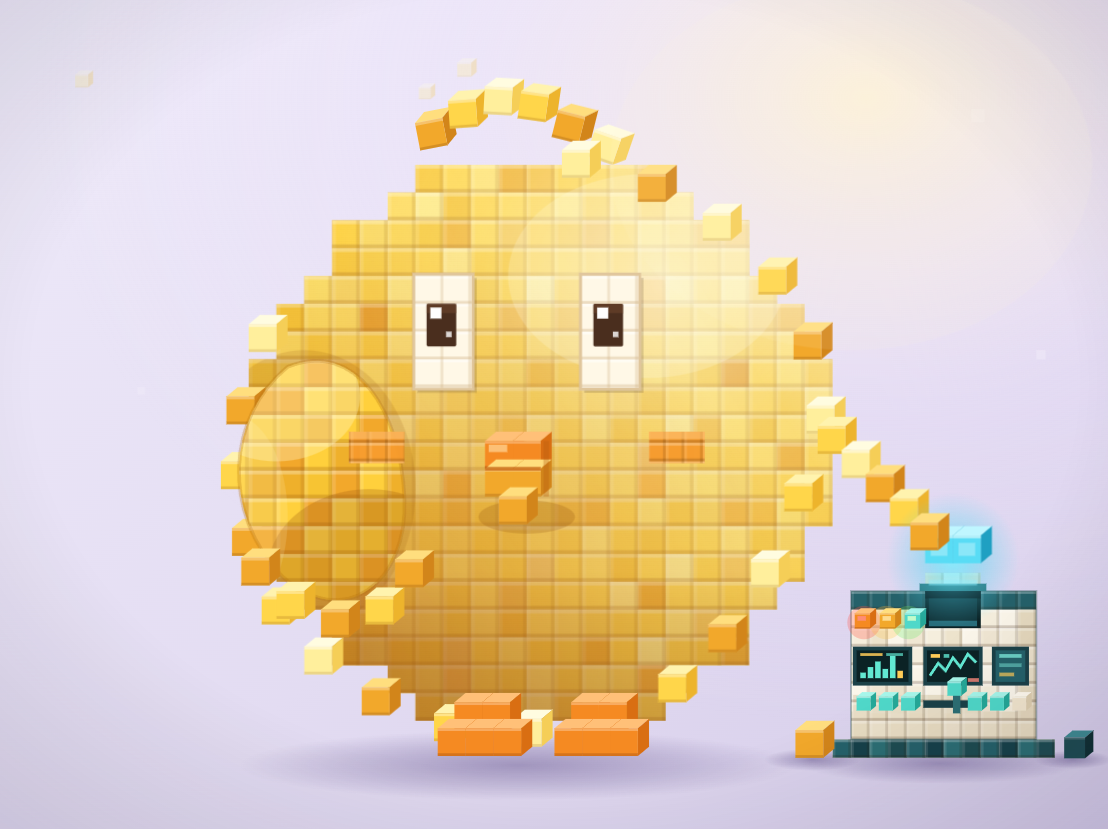
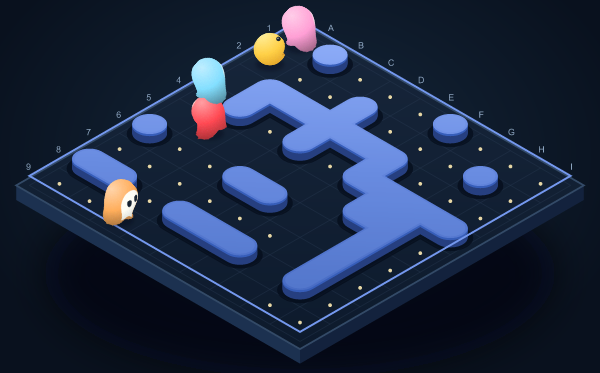
A rounded bird built from small cubes explores a miniature machine. The scene tests block construction, expressive proportions, contact and soft lighting.
First run
 stealthmodels.
MODEL BENCHMARKS
Reflection’s open-weight reasoning model activates 23.4B of its 501.3B parameters per token, with a million-token context for coding and long-running agents.
A good fit for
Software engineering, multi-step tool workflows and mathematical or scientific reasoning across large codebases and documents.
beam-freeChecked 2026-10-16reflection/beam-1.0-501b-a23bChecked 2026-10-16Beam-1.0-501B-A23BChecked 2026-10-16Beam-1.0-501B-A23BChecked 2026-10-16reflection/beam-freeChecked 2026-10-16OpenCode Beam Free: $0 input / $0 output for a limited time. OpenRouter / Nebius: $0.25 input / $1 output per 1M tokens. Reflection advertises free-to-start public beta access; no exact first-party rate verified.
[9] [10] [2]per 1M tokens
limited-time promotion
Limited-time free offer; account access and regional availability follow OpenCode’s terms.
beam-free[9]per 1M tokens
Available
Listed Nebius FP8 endpoint; input and output rates per million tokens.
reflection/beam-1.0-501b-a23b[10] [7]large multi-GPU server or substantial host-memory offload
[1] [14]Weight payload size excludes KV cache, runtime overhead and additional serving components; it is not a minimum VRAM requirement.
[15] [16]StealthMark methodology · Intelligence methodology
Benchmark results
LicenseProprietary hosted service
Model IDcallstack/apex
 StealthMarkOverall rank17/498 rated results
A rounded bird built from small cubes explores a miniature machine. The scene tests block construction, expressive proportions, contact and soft lighting.
First run
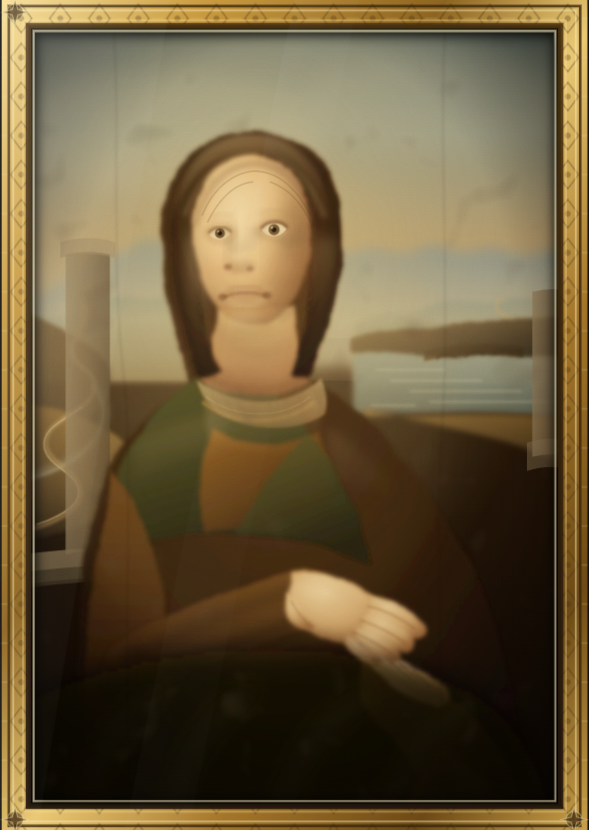
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
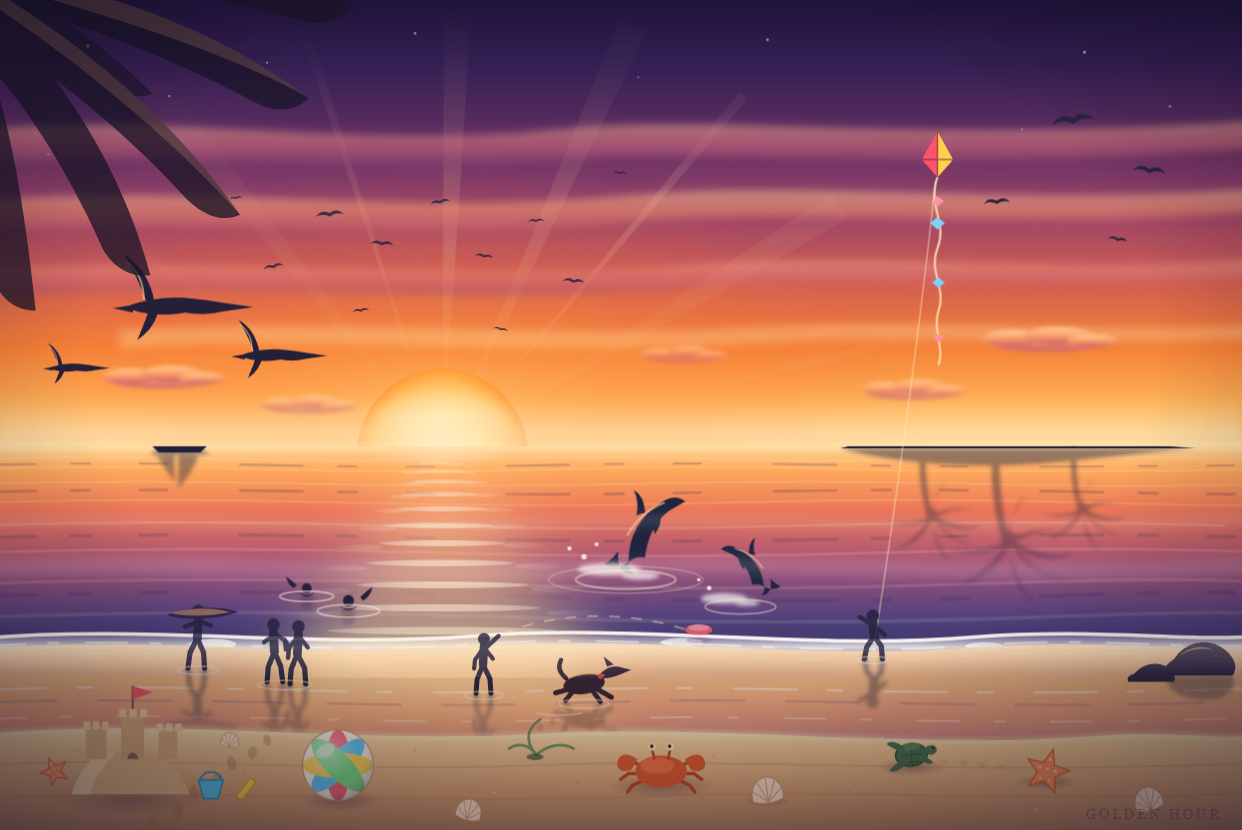
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
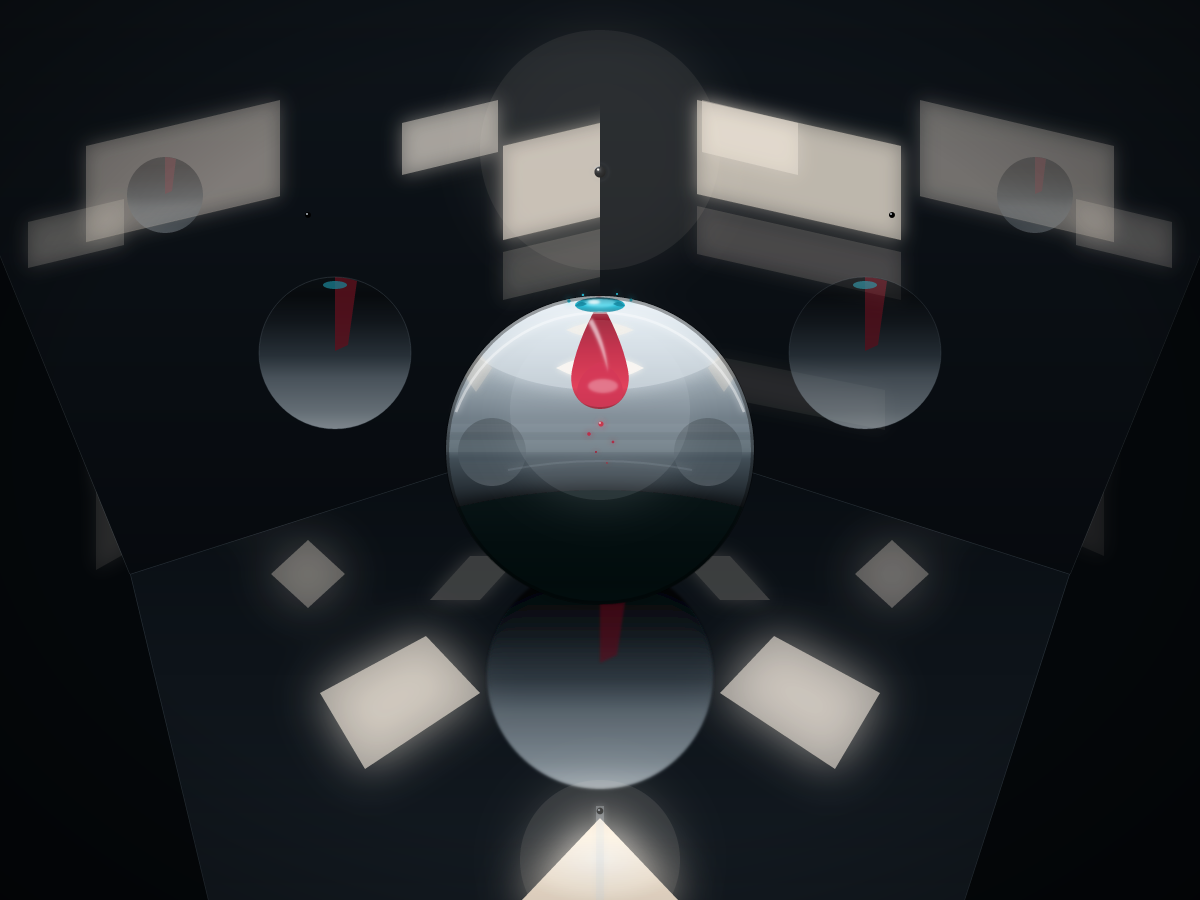
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
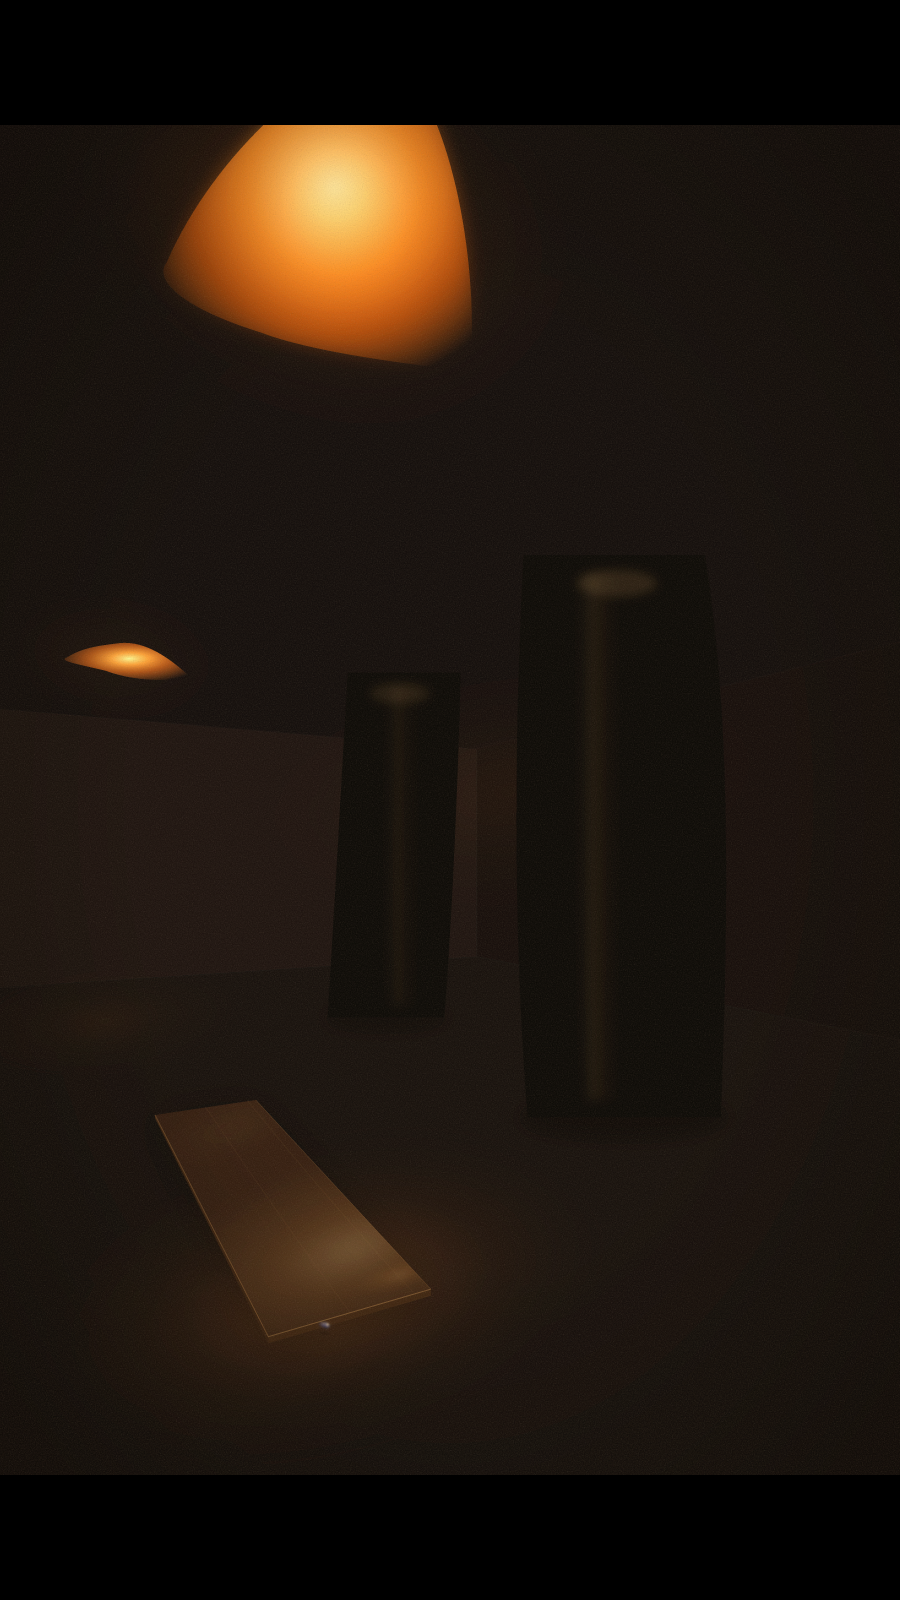
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
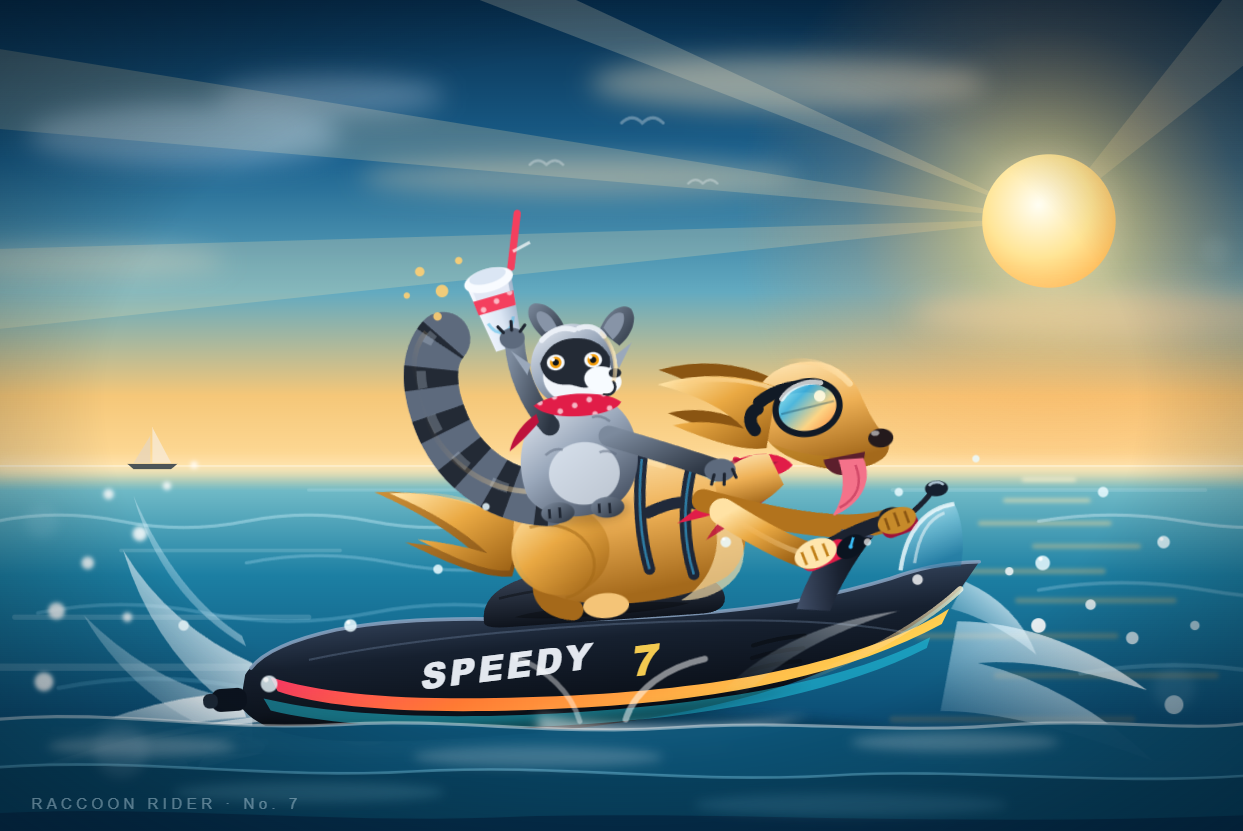
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
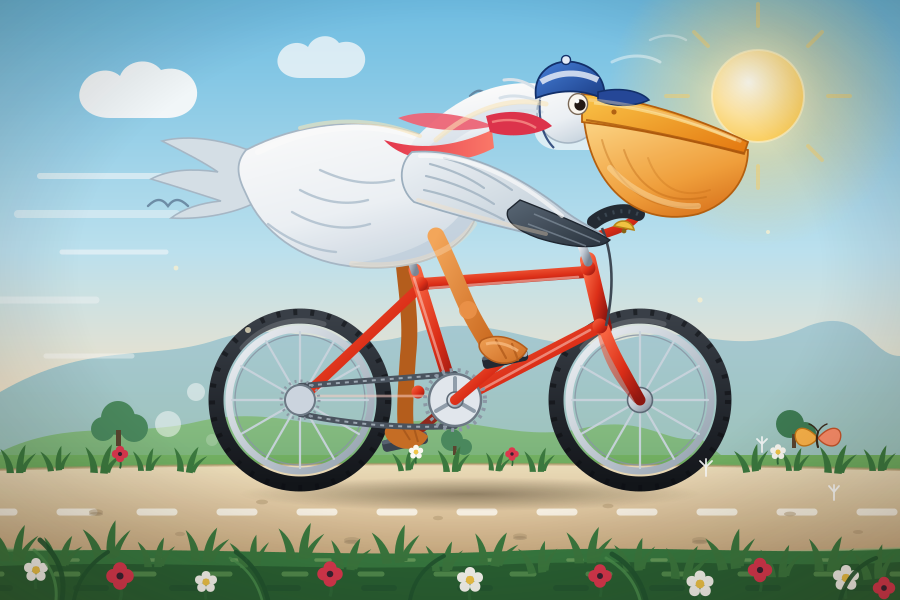
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
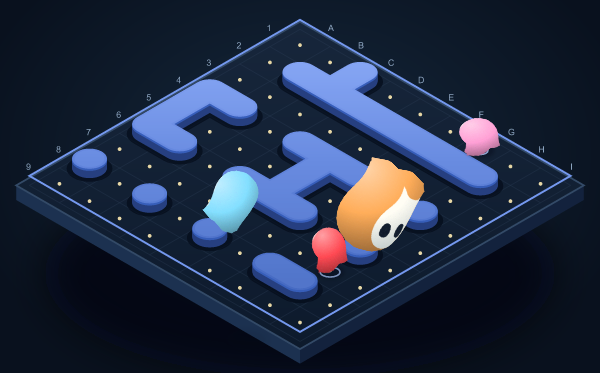
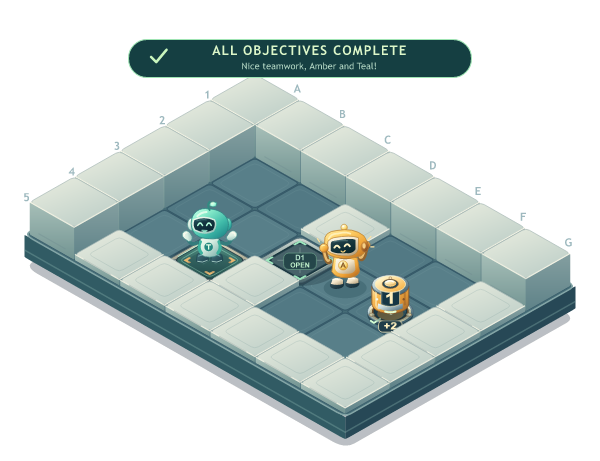
Unknown (Suspected union of GPT-6.1 Sol + DeepSeek + MiniMax)
Model IDstealth/space-bunny-alpha
StealthMarkOverall rank21/499 rated results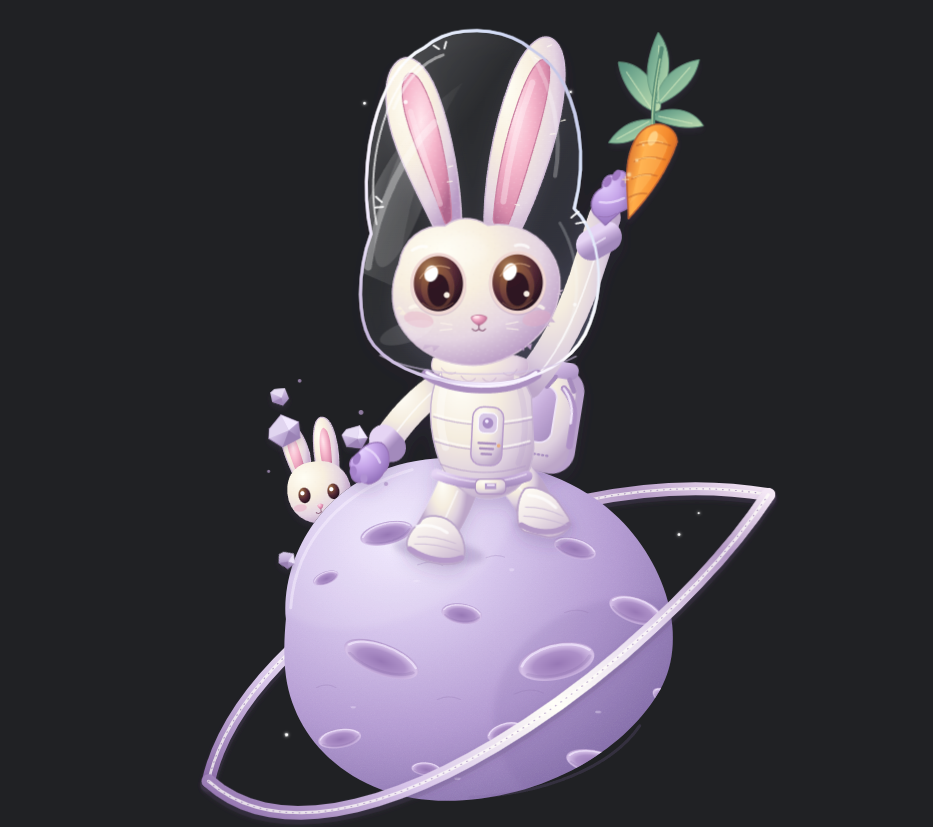
An astronaut rabbit reaches for a carrot above a small moon while a younger companion peeks into view. The scene tests expressive characters, spatial relationships and material detail.
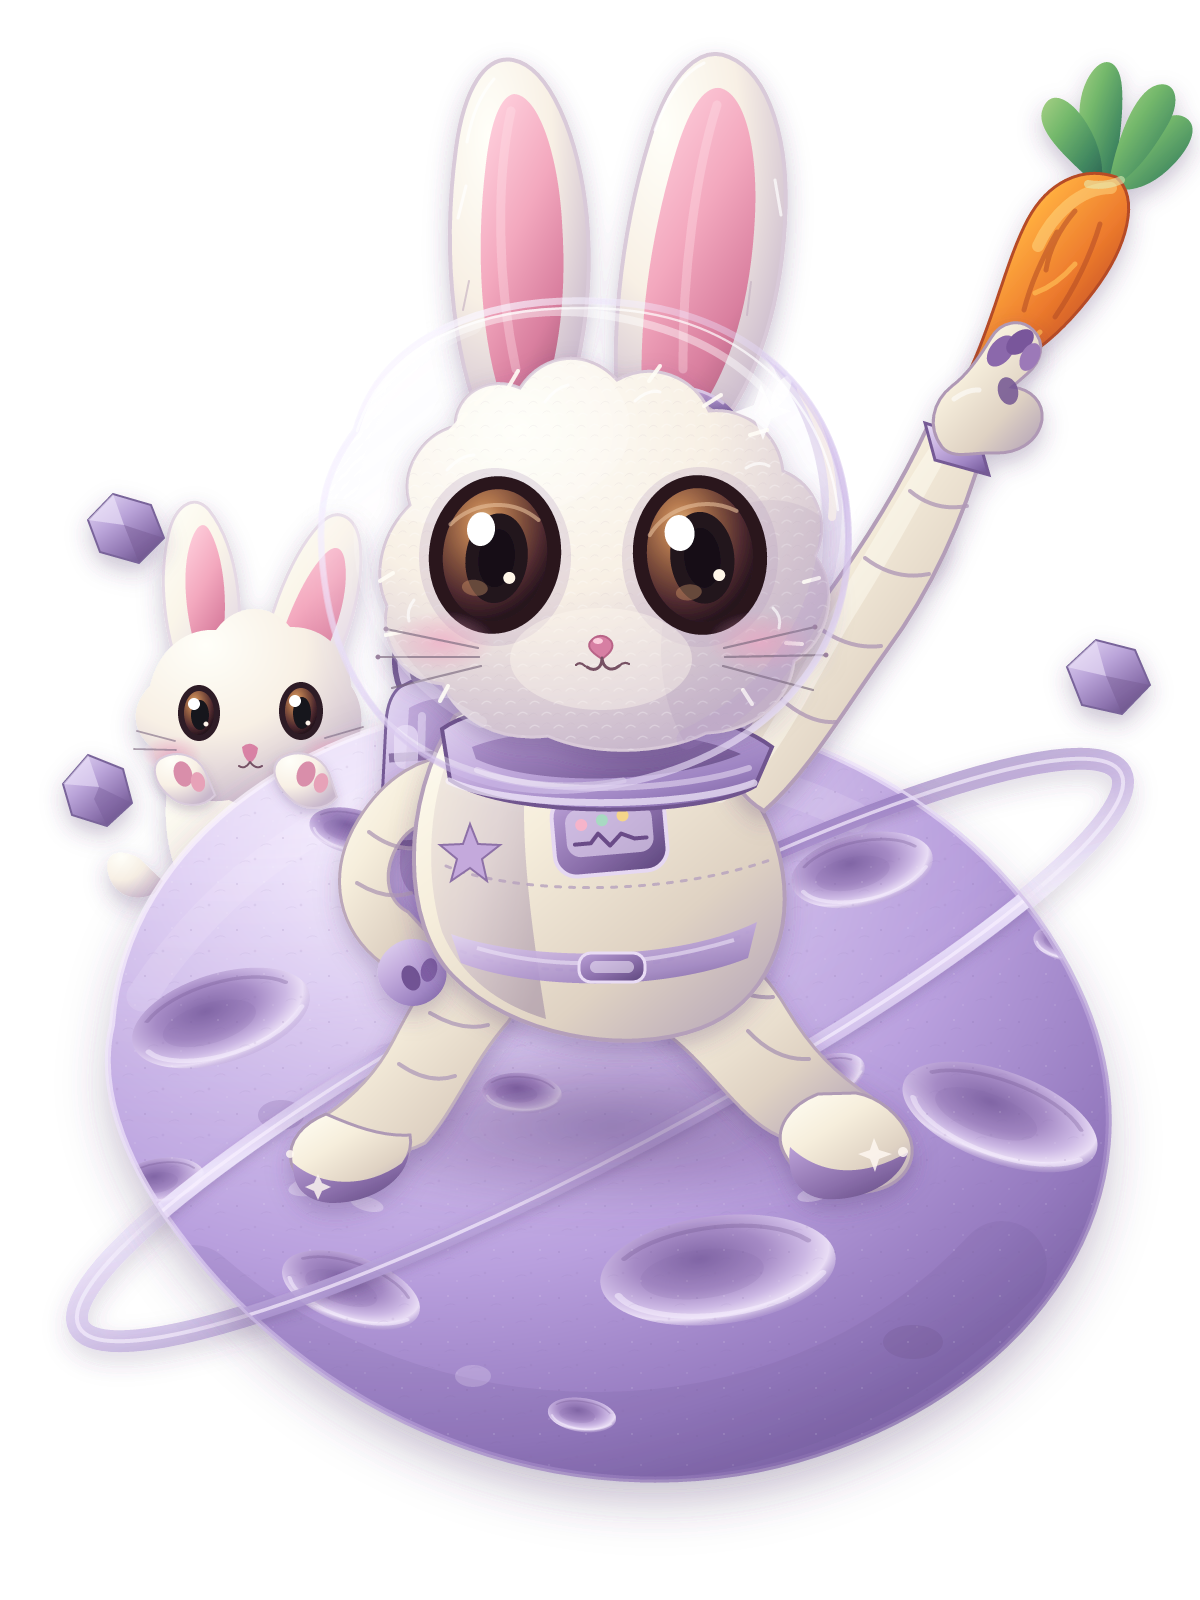
An astronaut rabbit reaches for a carrot above a small moon while a younger companion peeks into view. The scene tests expressive characters, spatial relationships and material detail.
First run
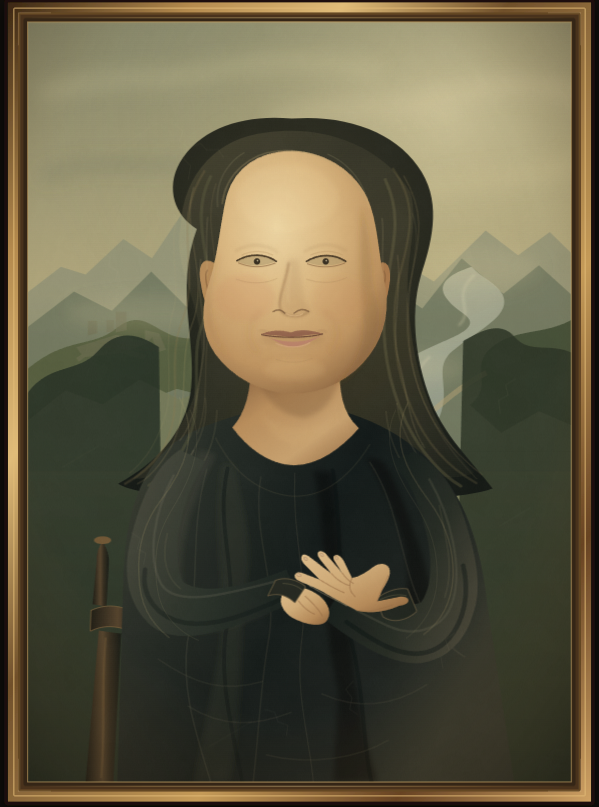
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
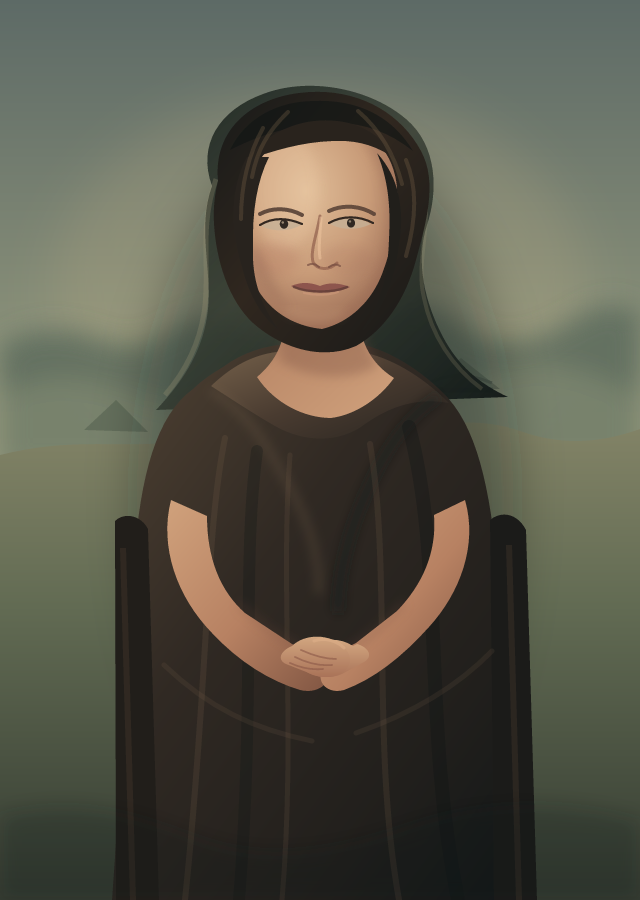
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
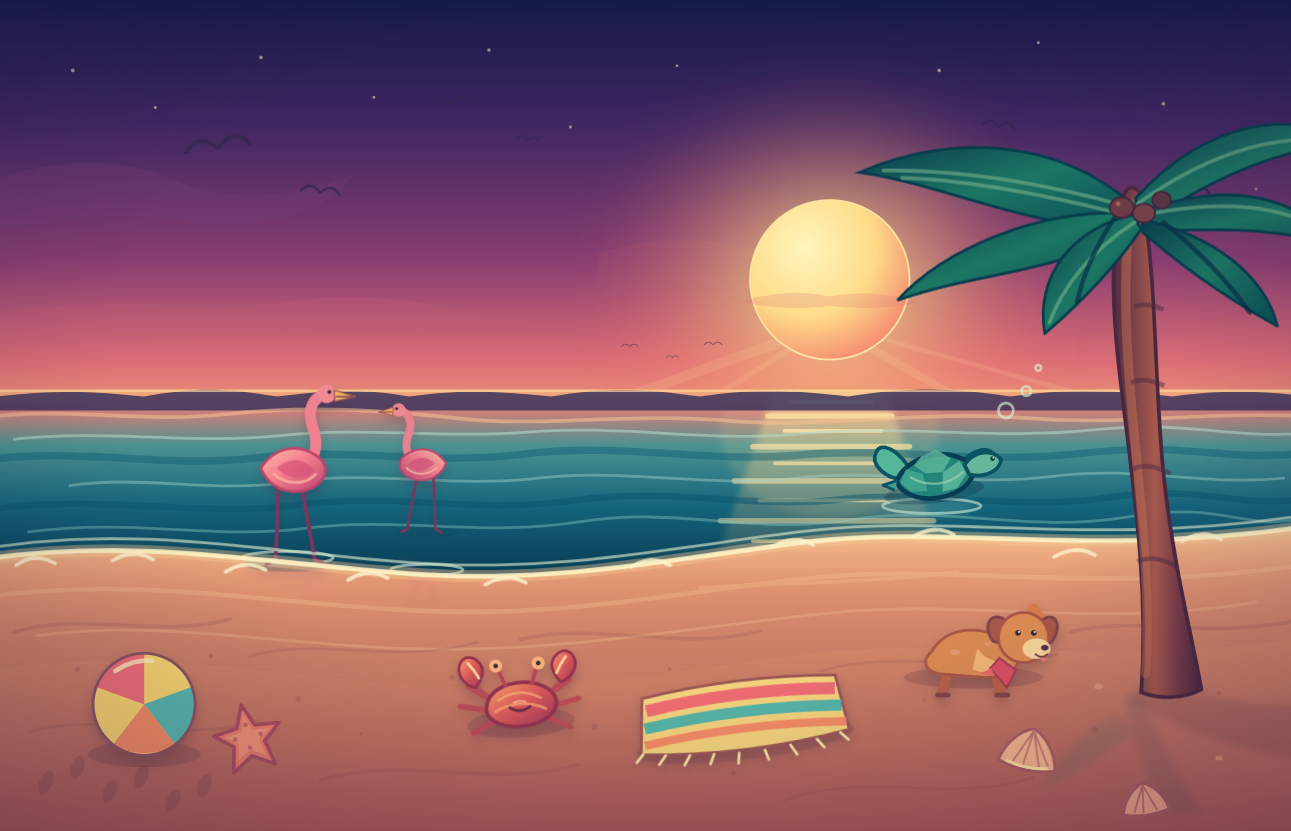
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
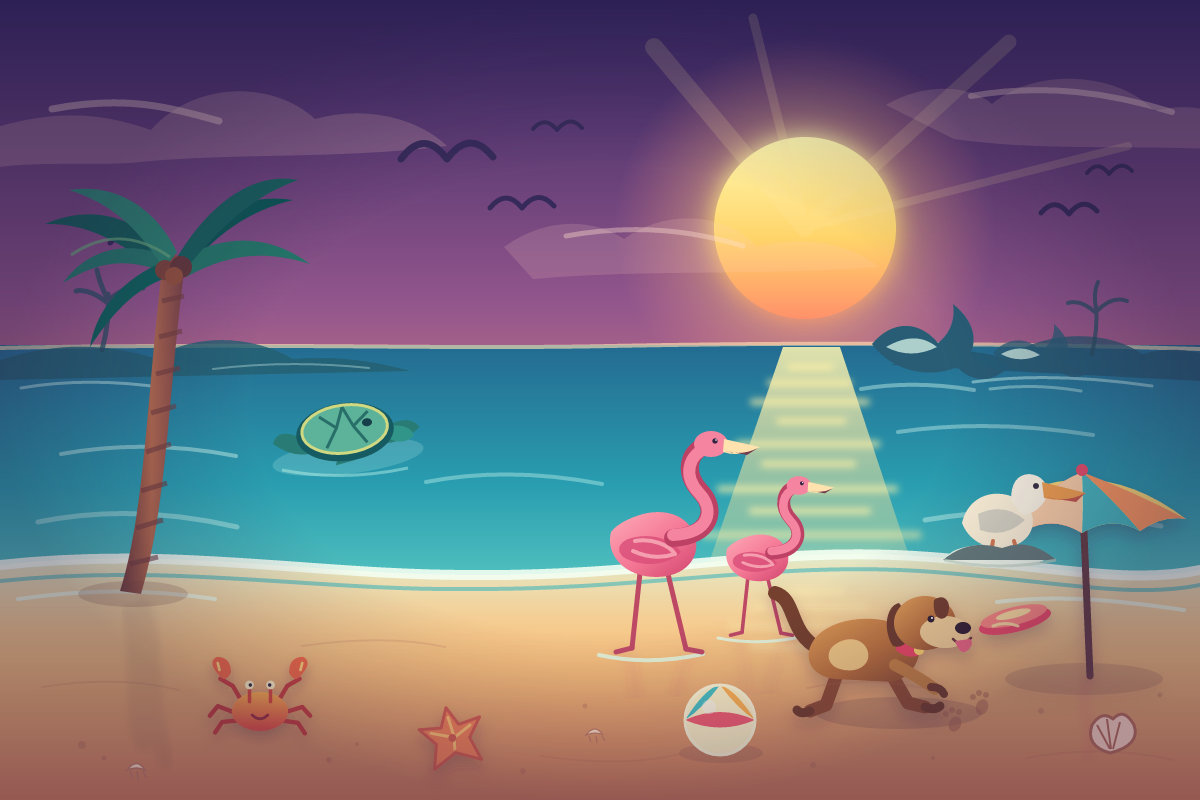
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
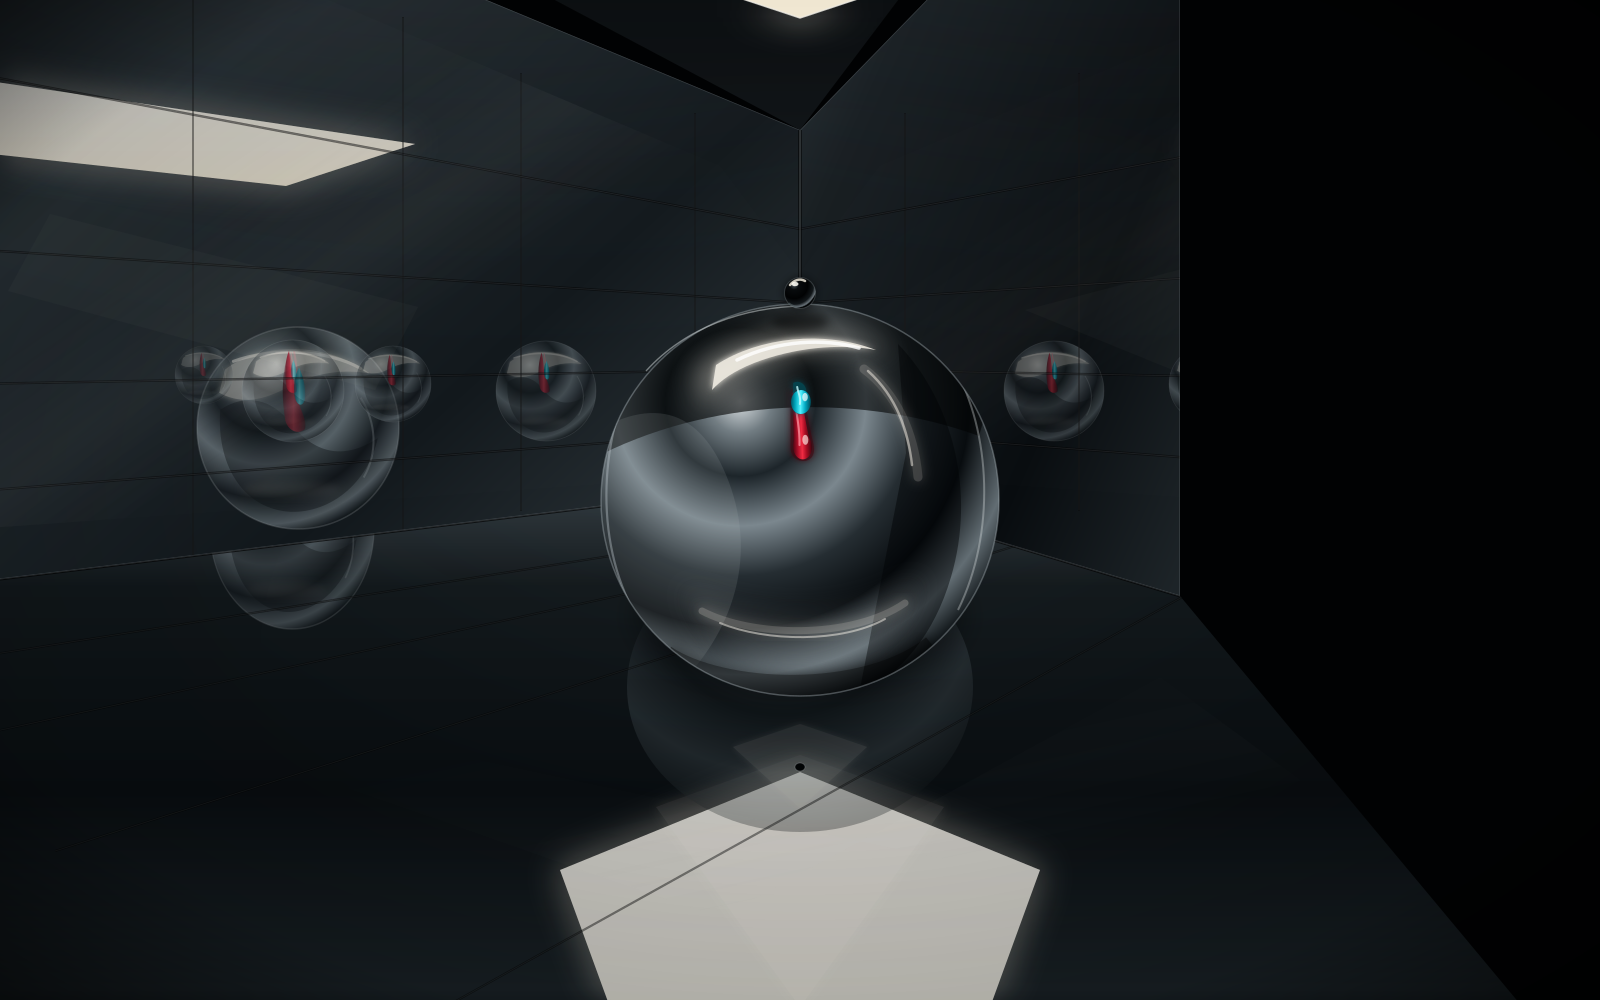
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
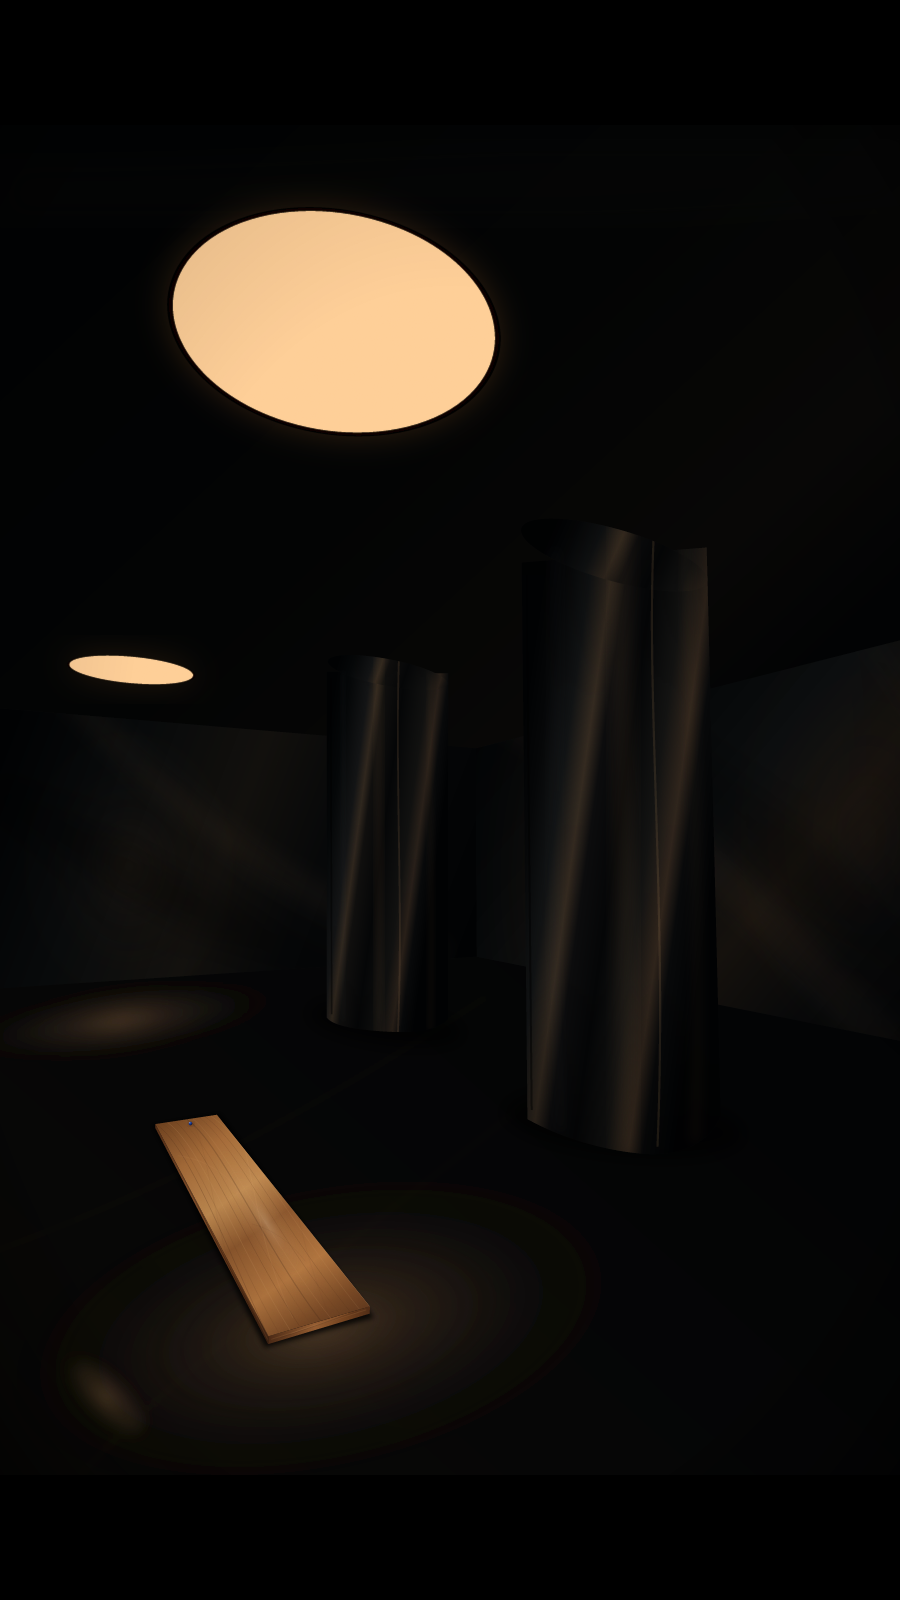
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
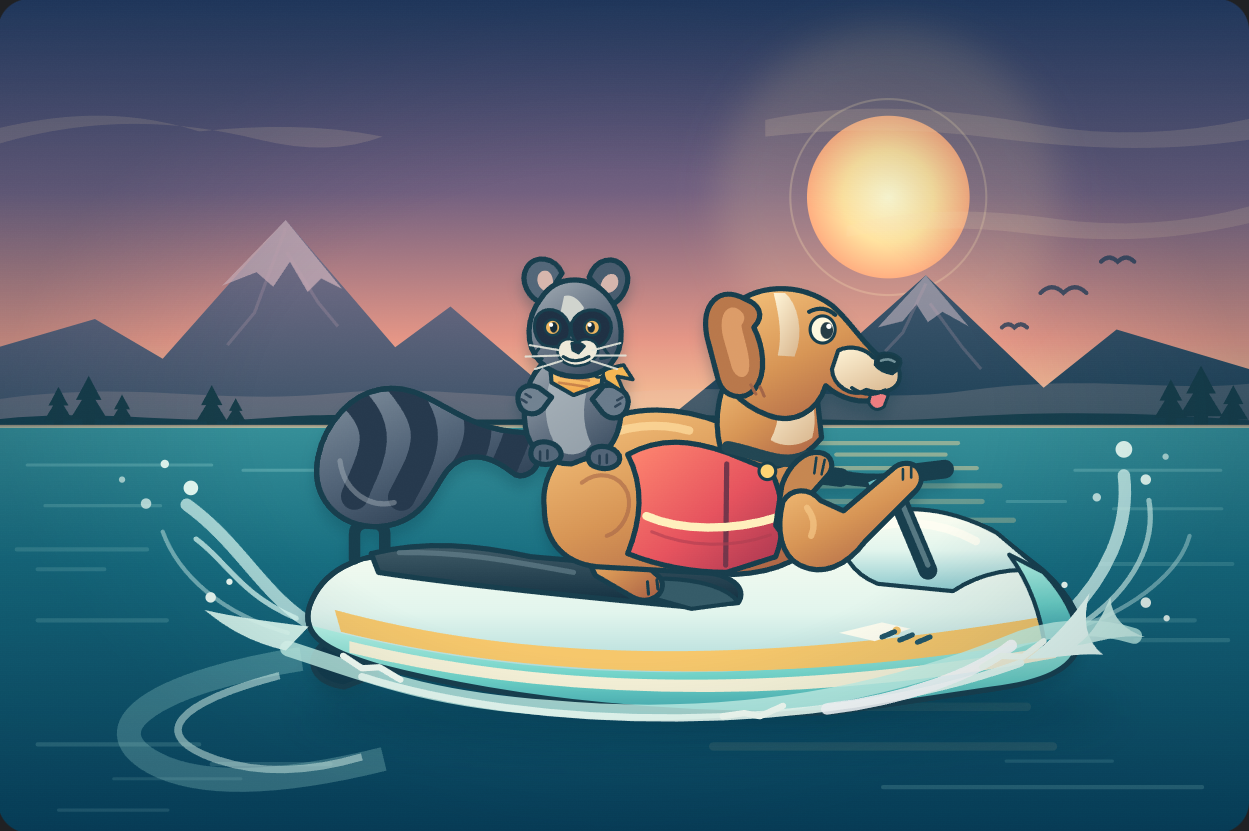
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
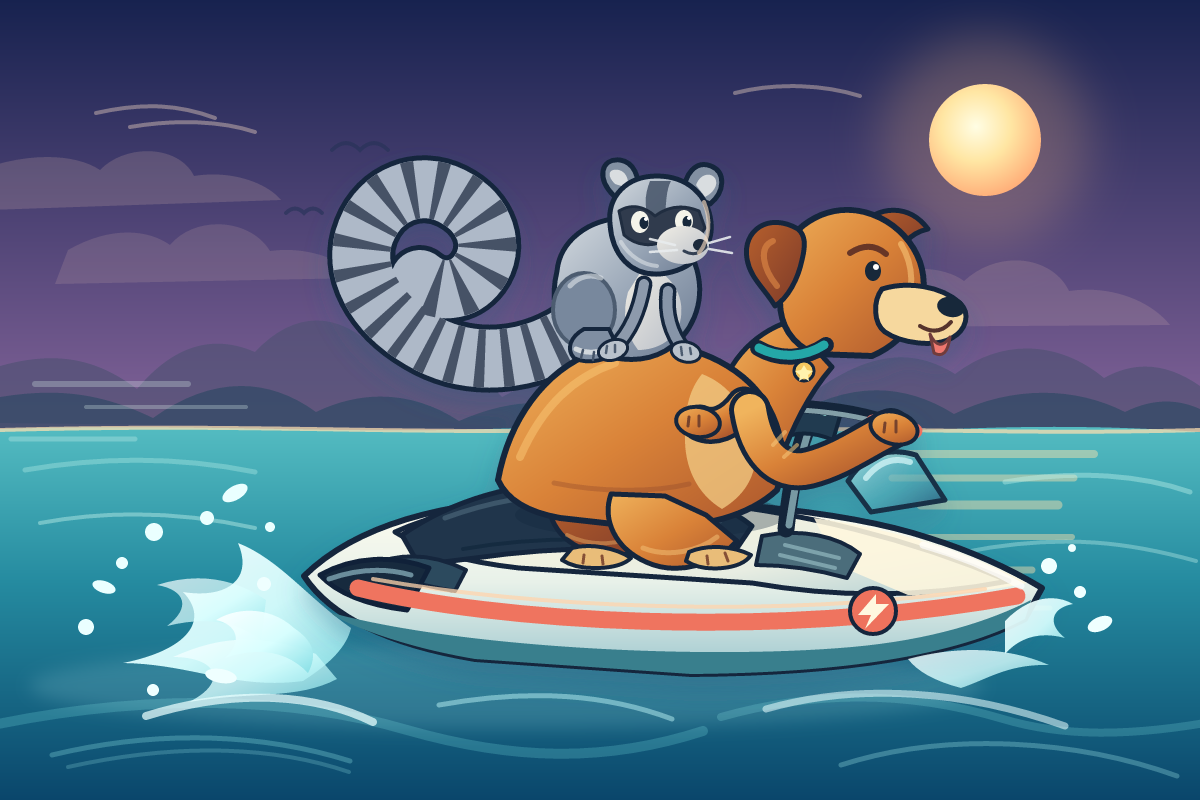
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
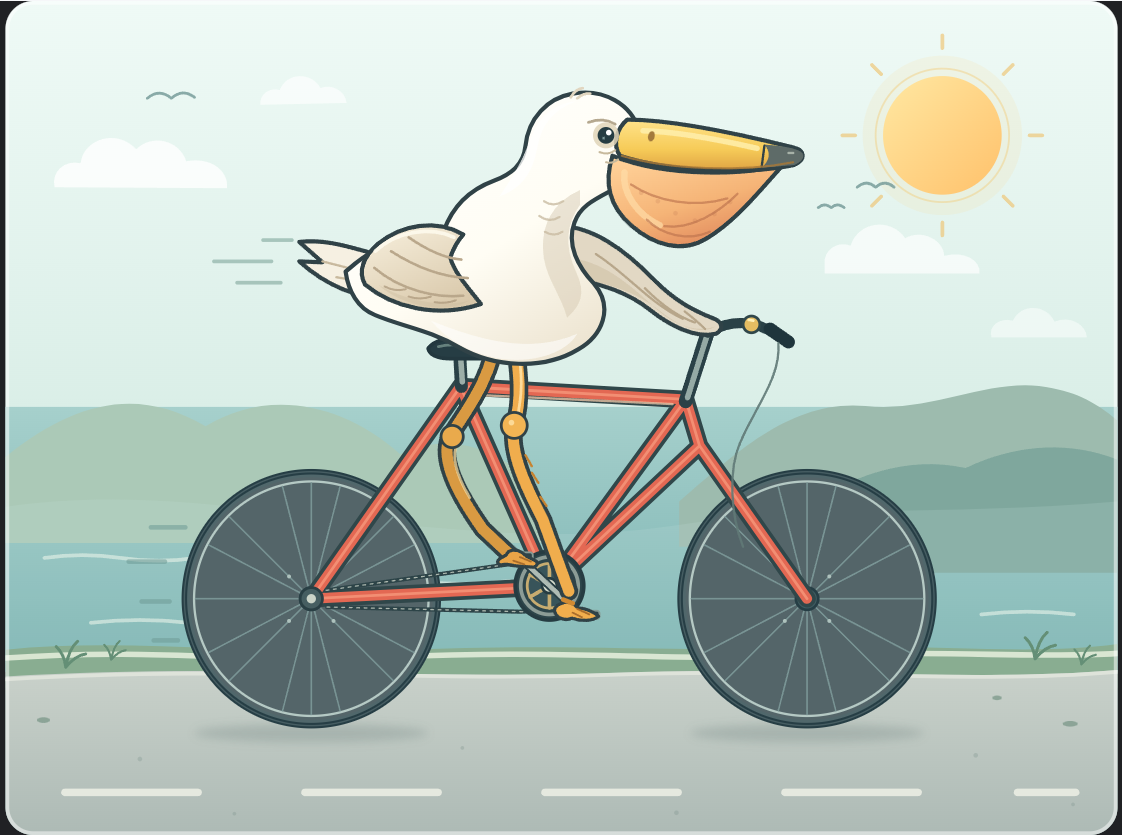
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
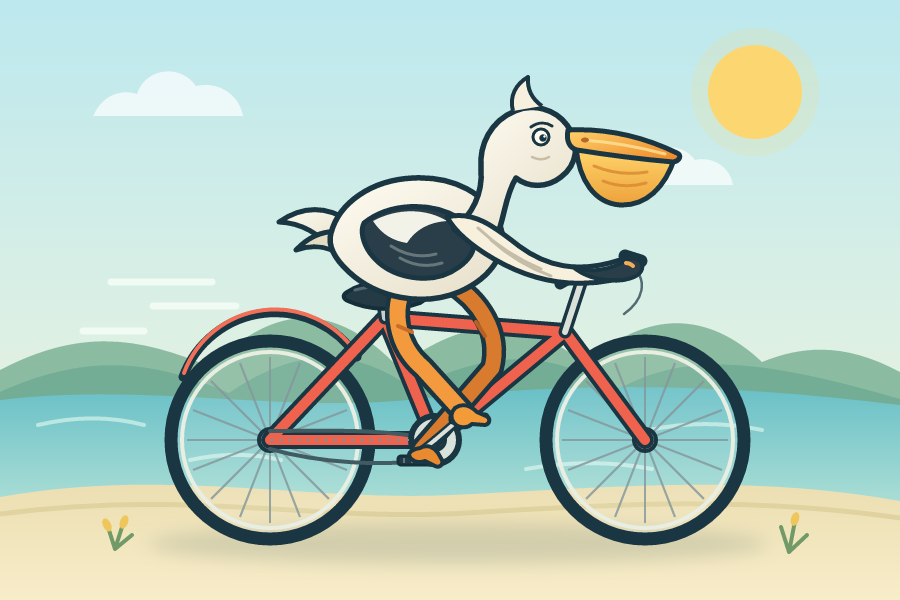
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseMIT
Model IDmeituan/longcat-2.0
StealthMarkOverall rank42/497 rated results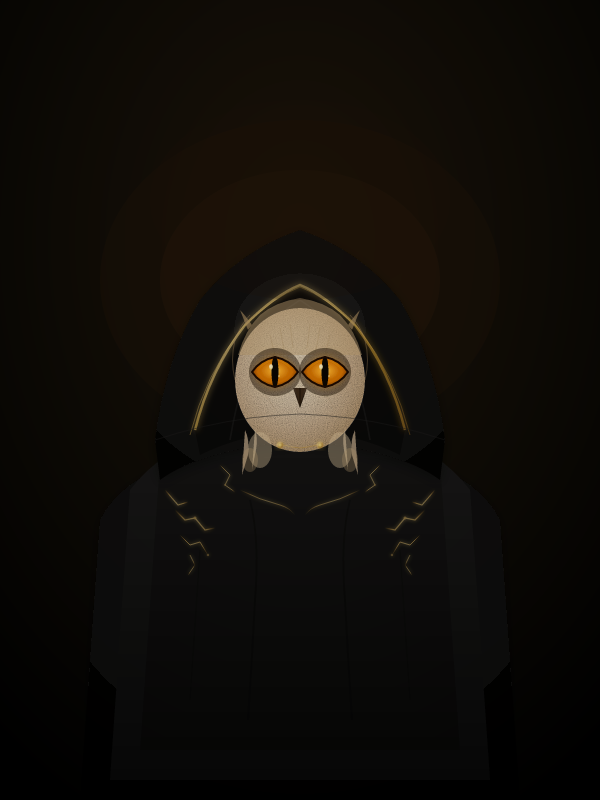
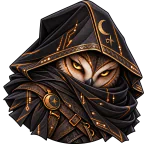
A cloaked owl with luminous eyes tests expression, fabric folds and the separation of dark forms.
First run
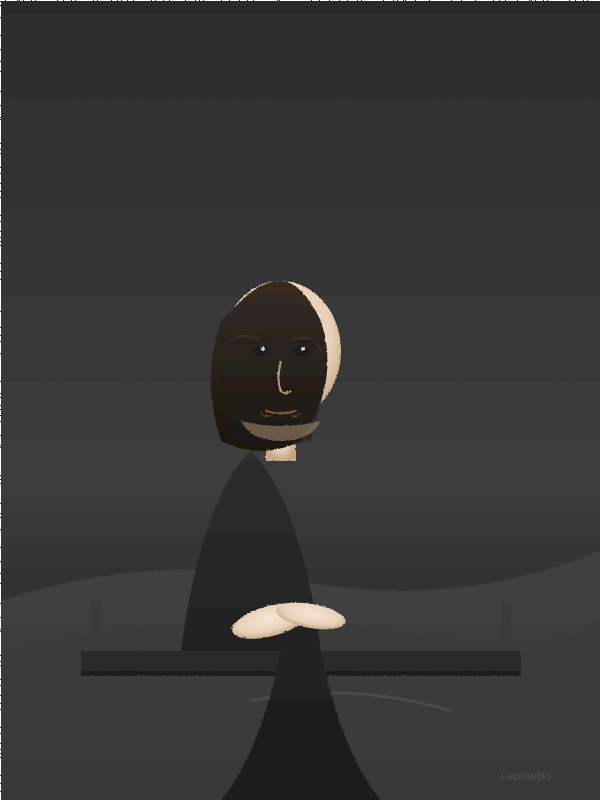
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
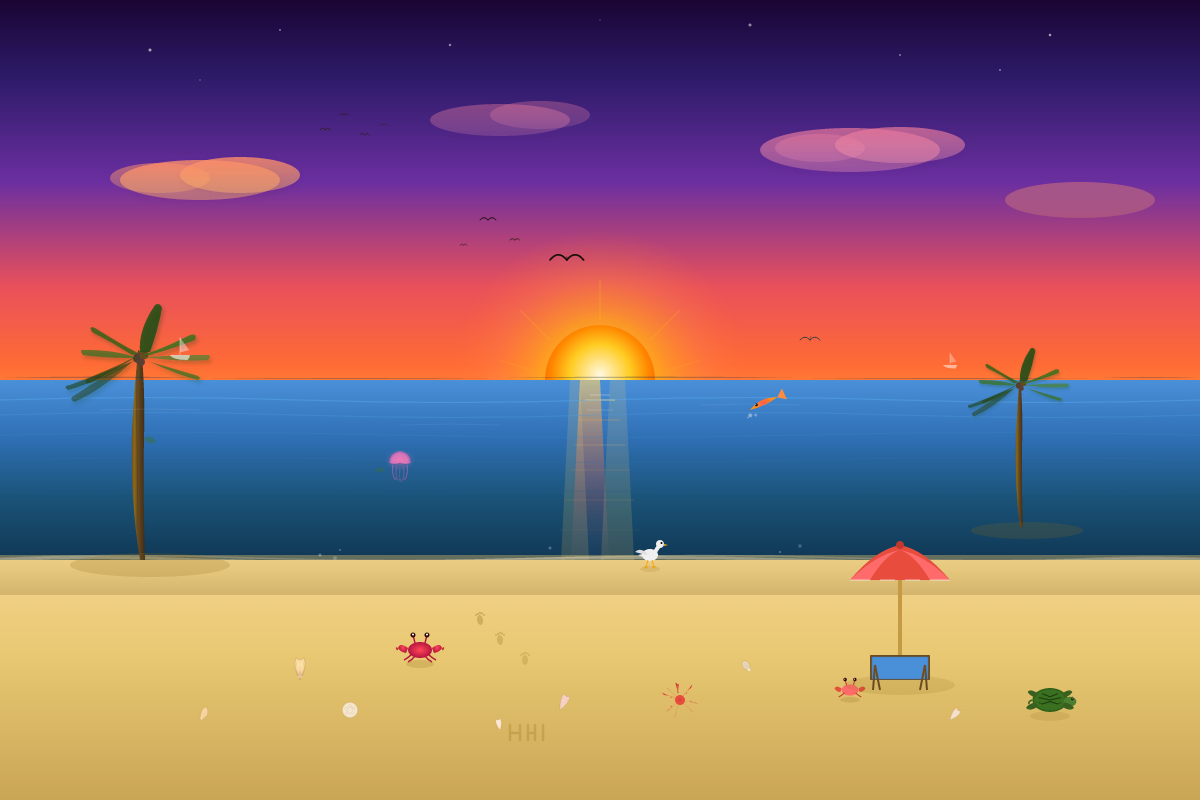
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
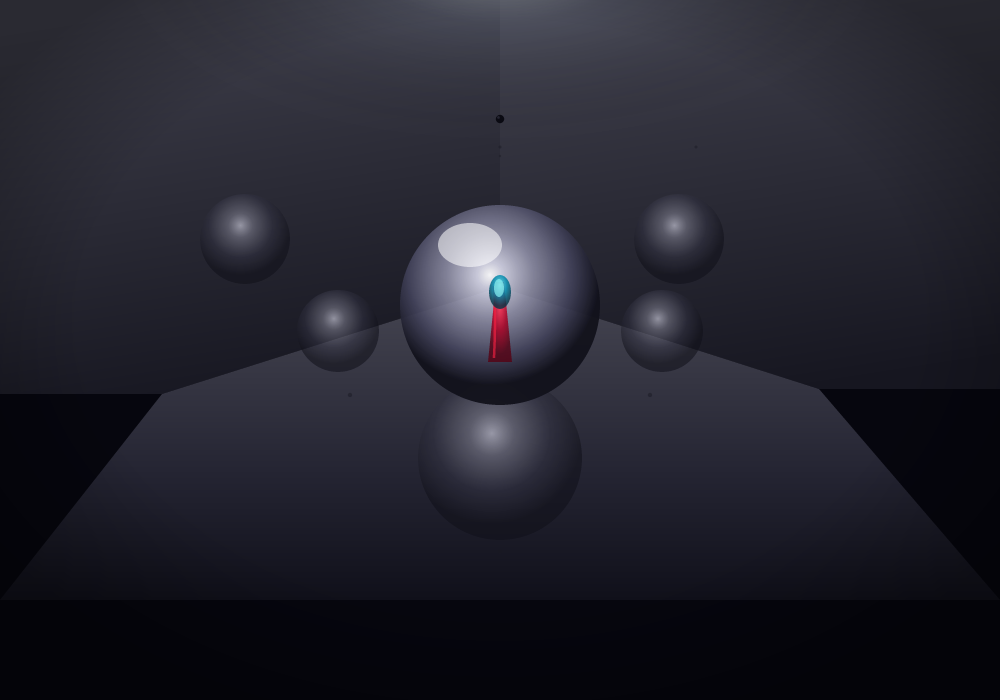
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
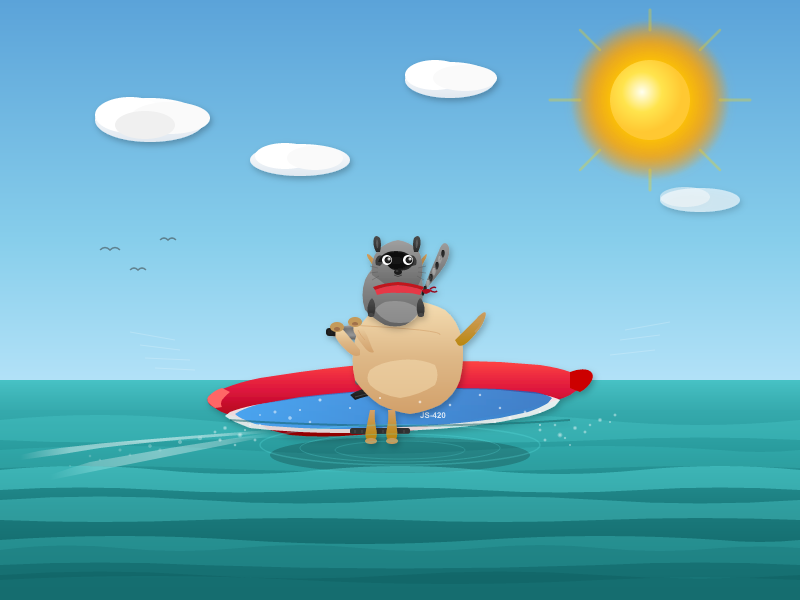
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
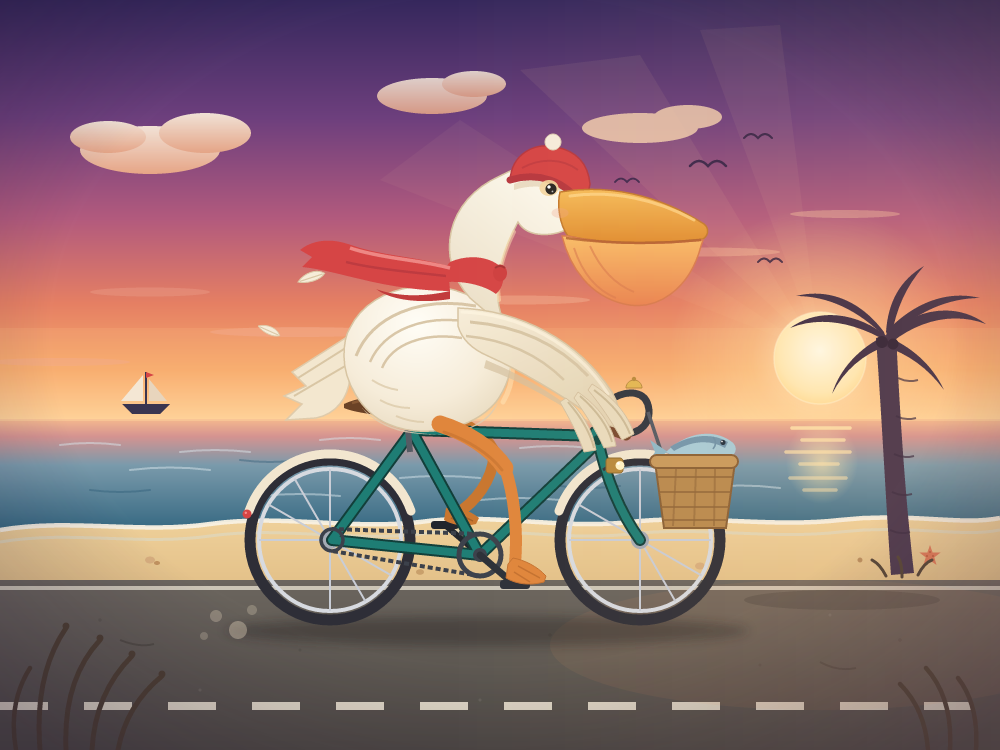
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseMIT
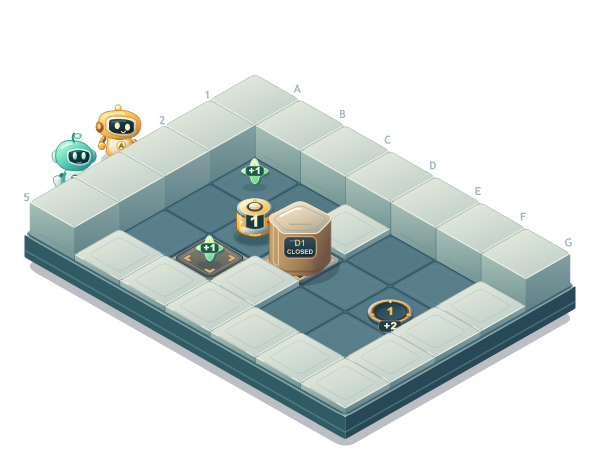
Model IDz-ai/glm-5.3-flash
StealthMarkOverall rank15/498 rated results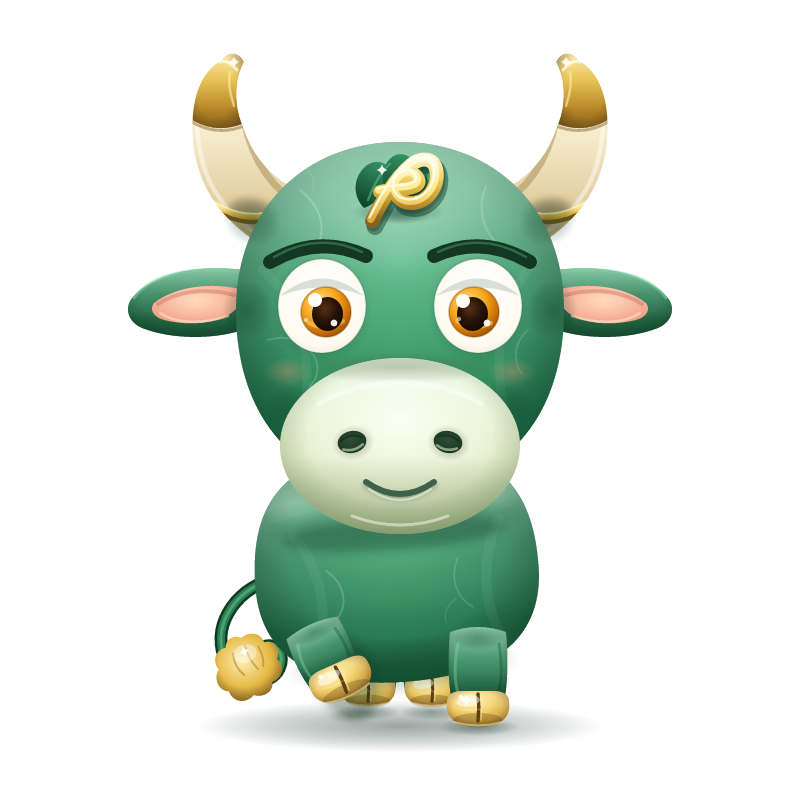
A rounded jade bull raising a hoof tests anatomy, balance and the appearance of polished stone and metal.
First run
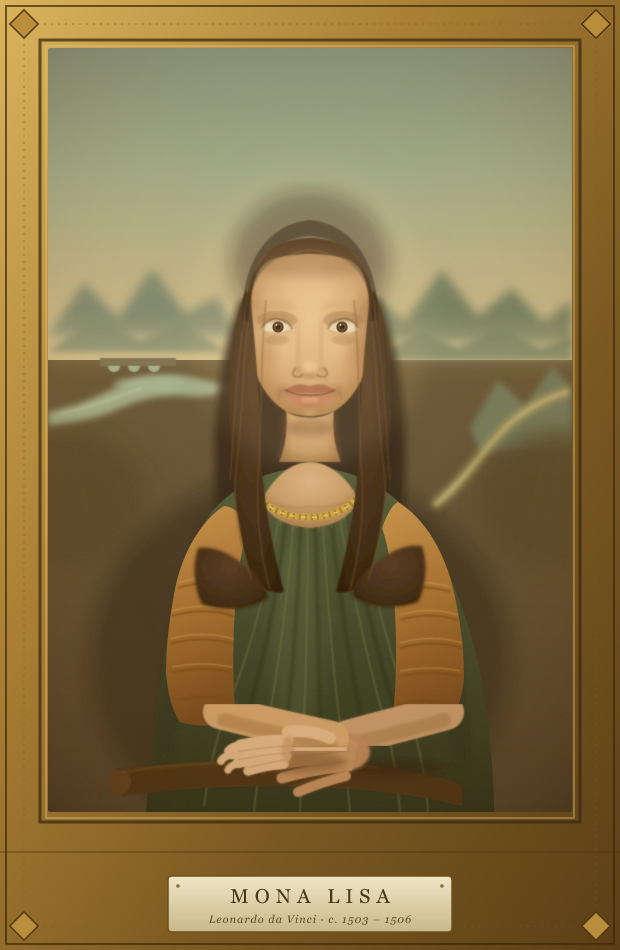
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
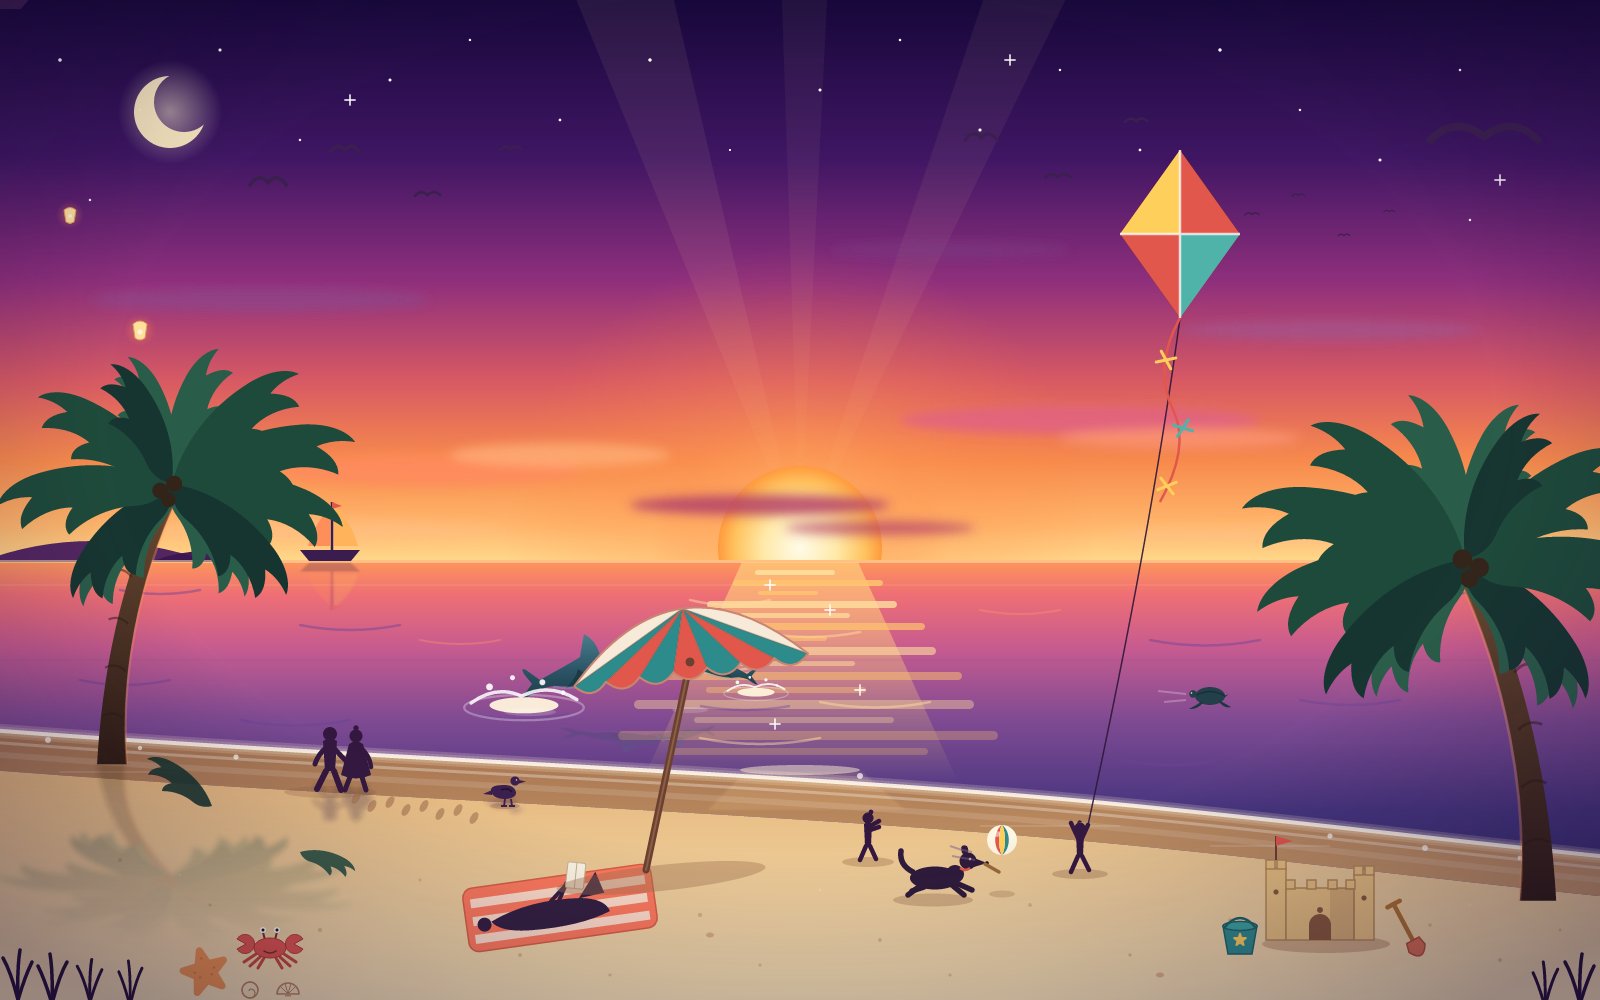
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
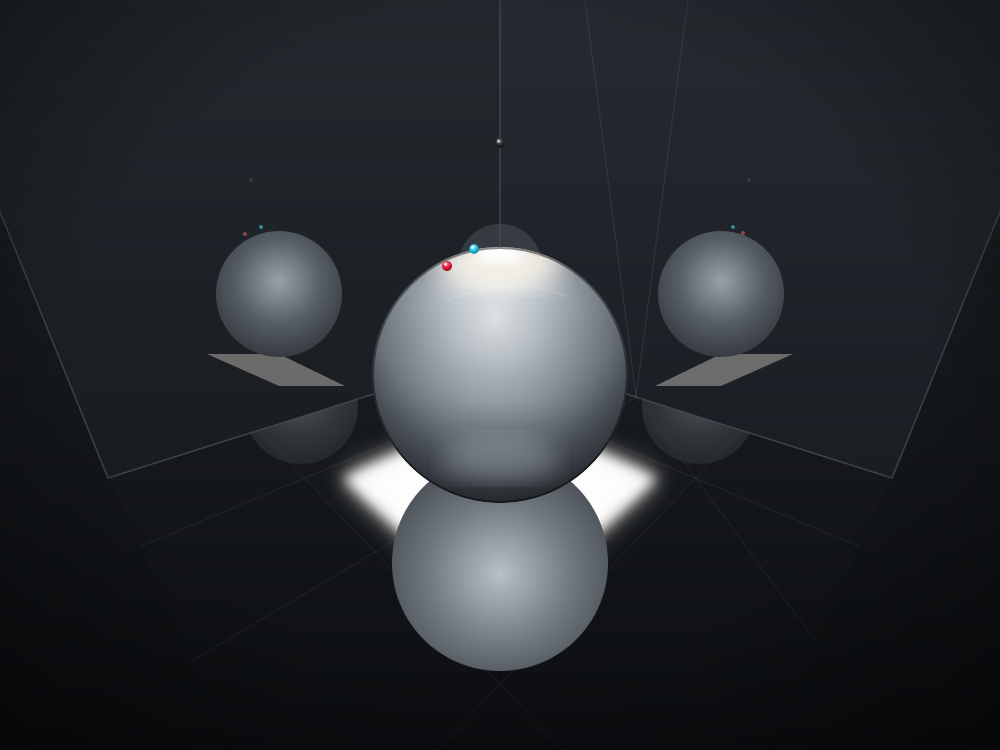
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
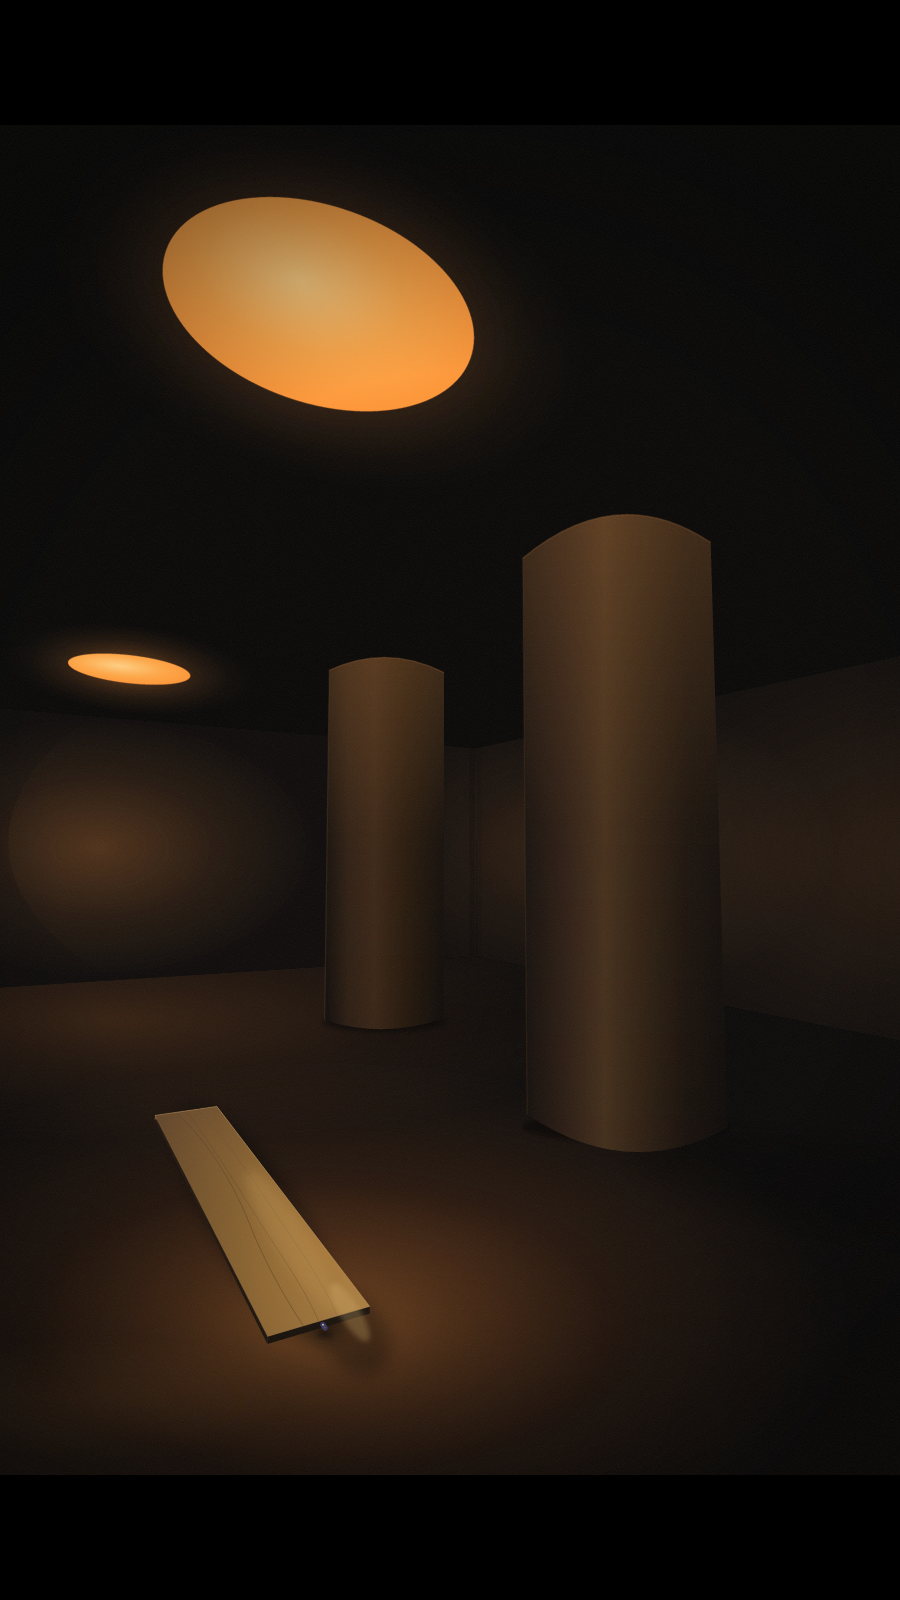
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
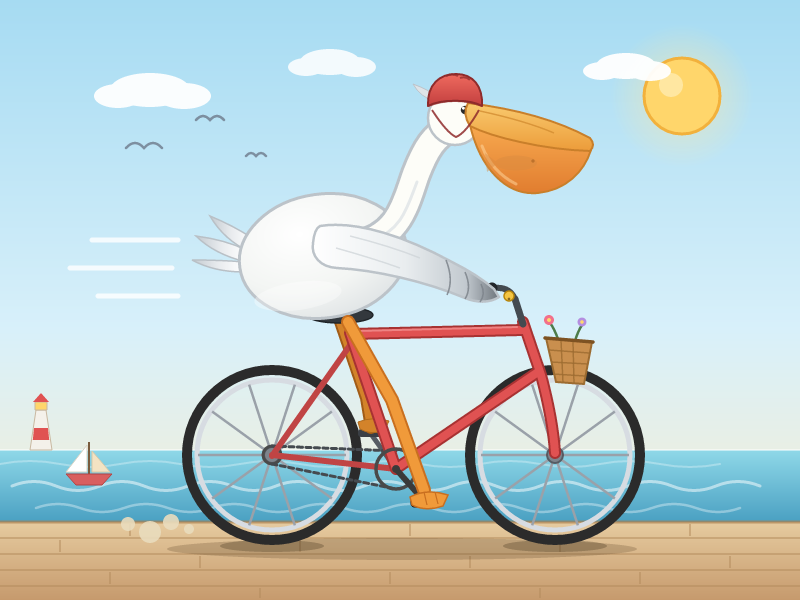
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDunbiased/pareto
StealthMarkOverall rank7/499 rated results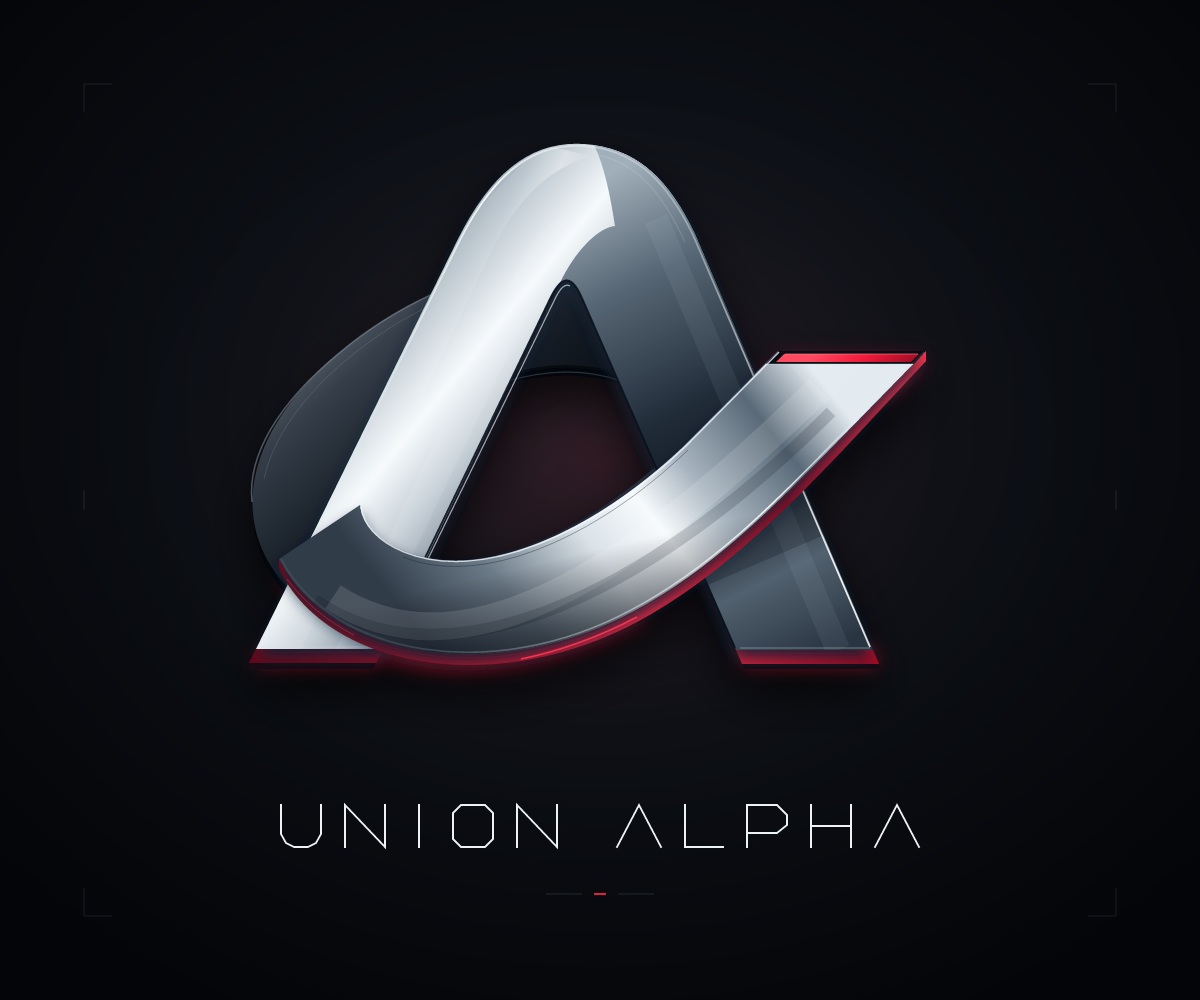
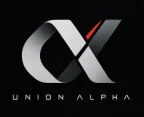
An interwoven metallic emblem tests ribbon geometry, overlapping forms and the appearance of reflective metal against a dark background.
First run
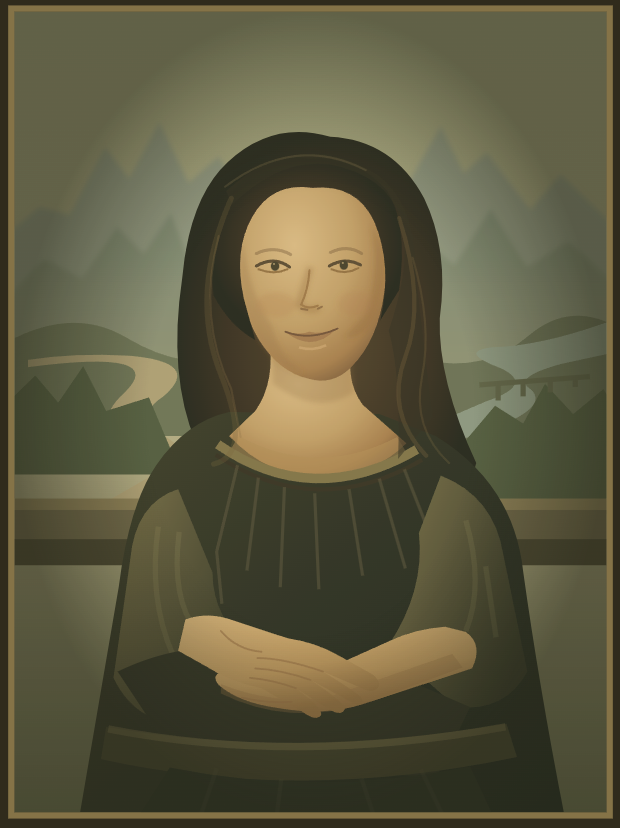
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
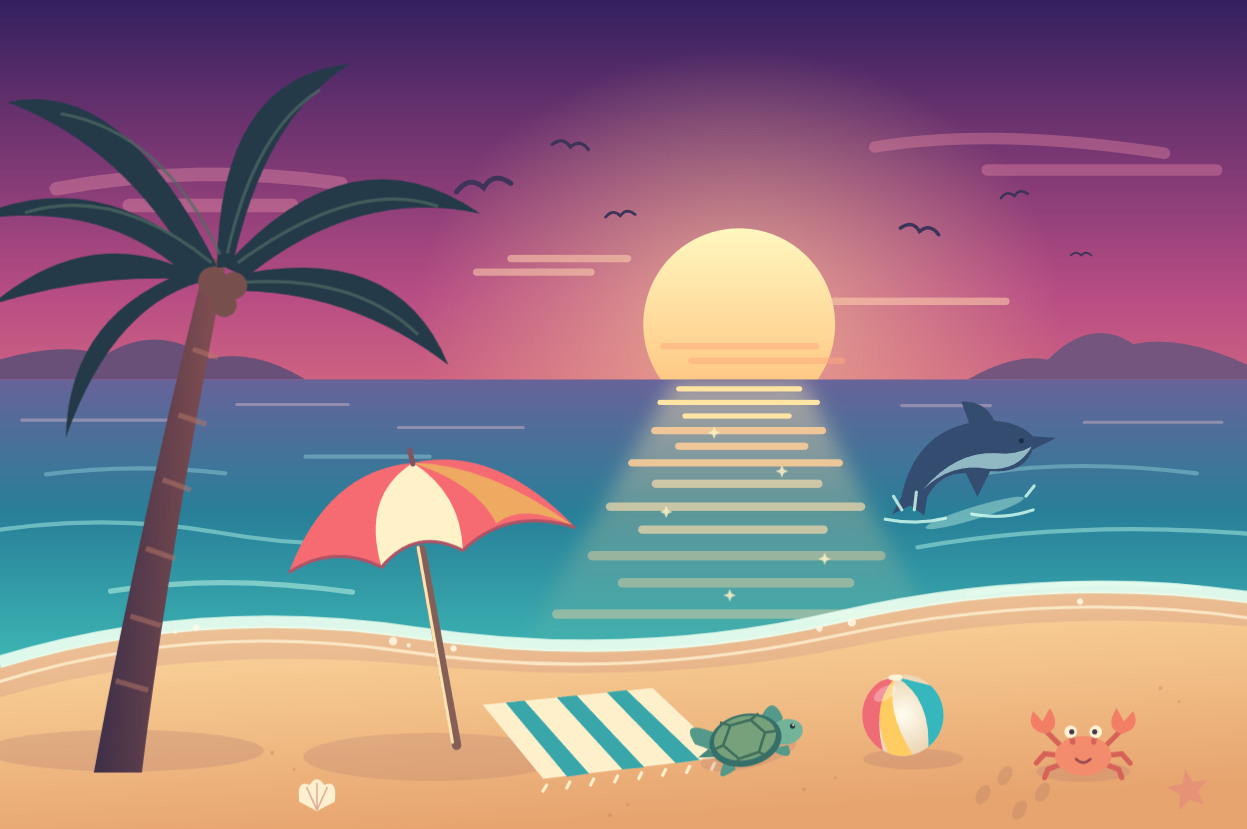
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
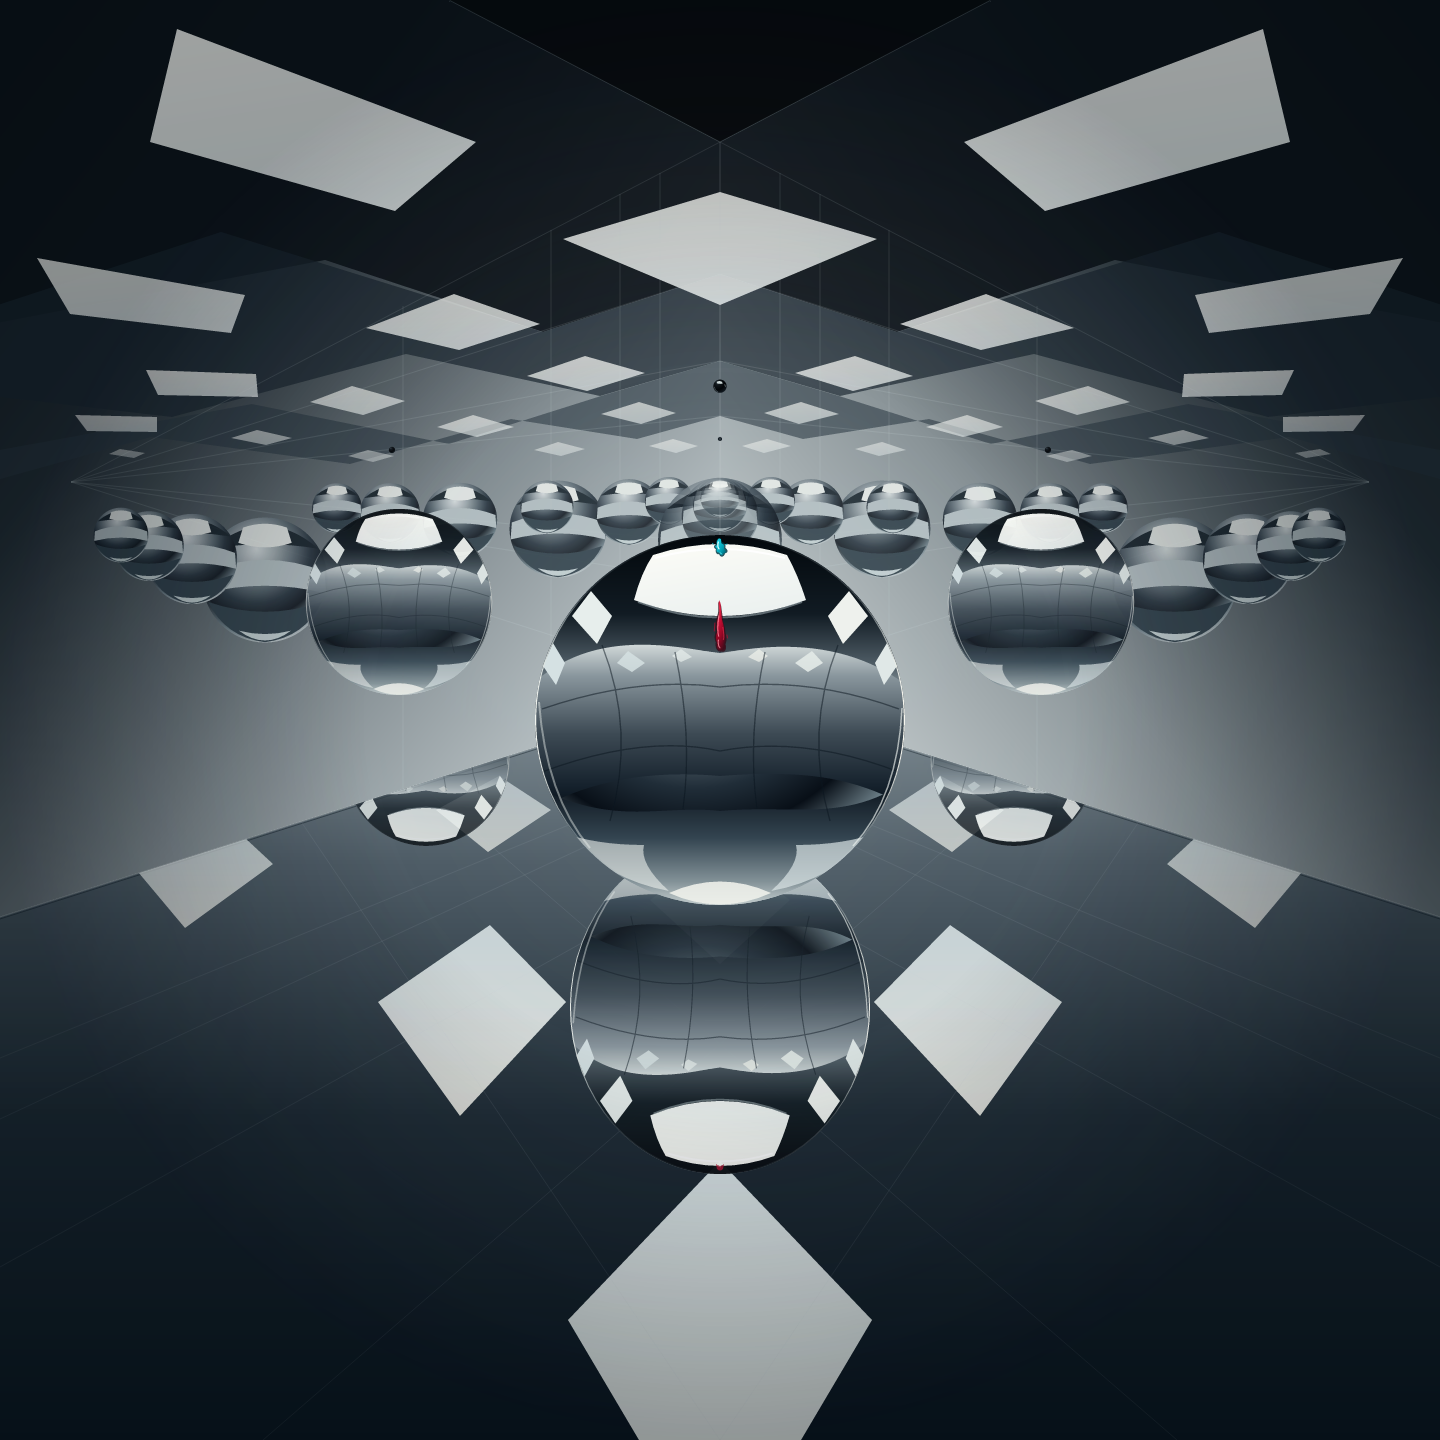
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
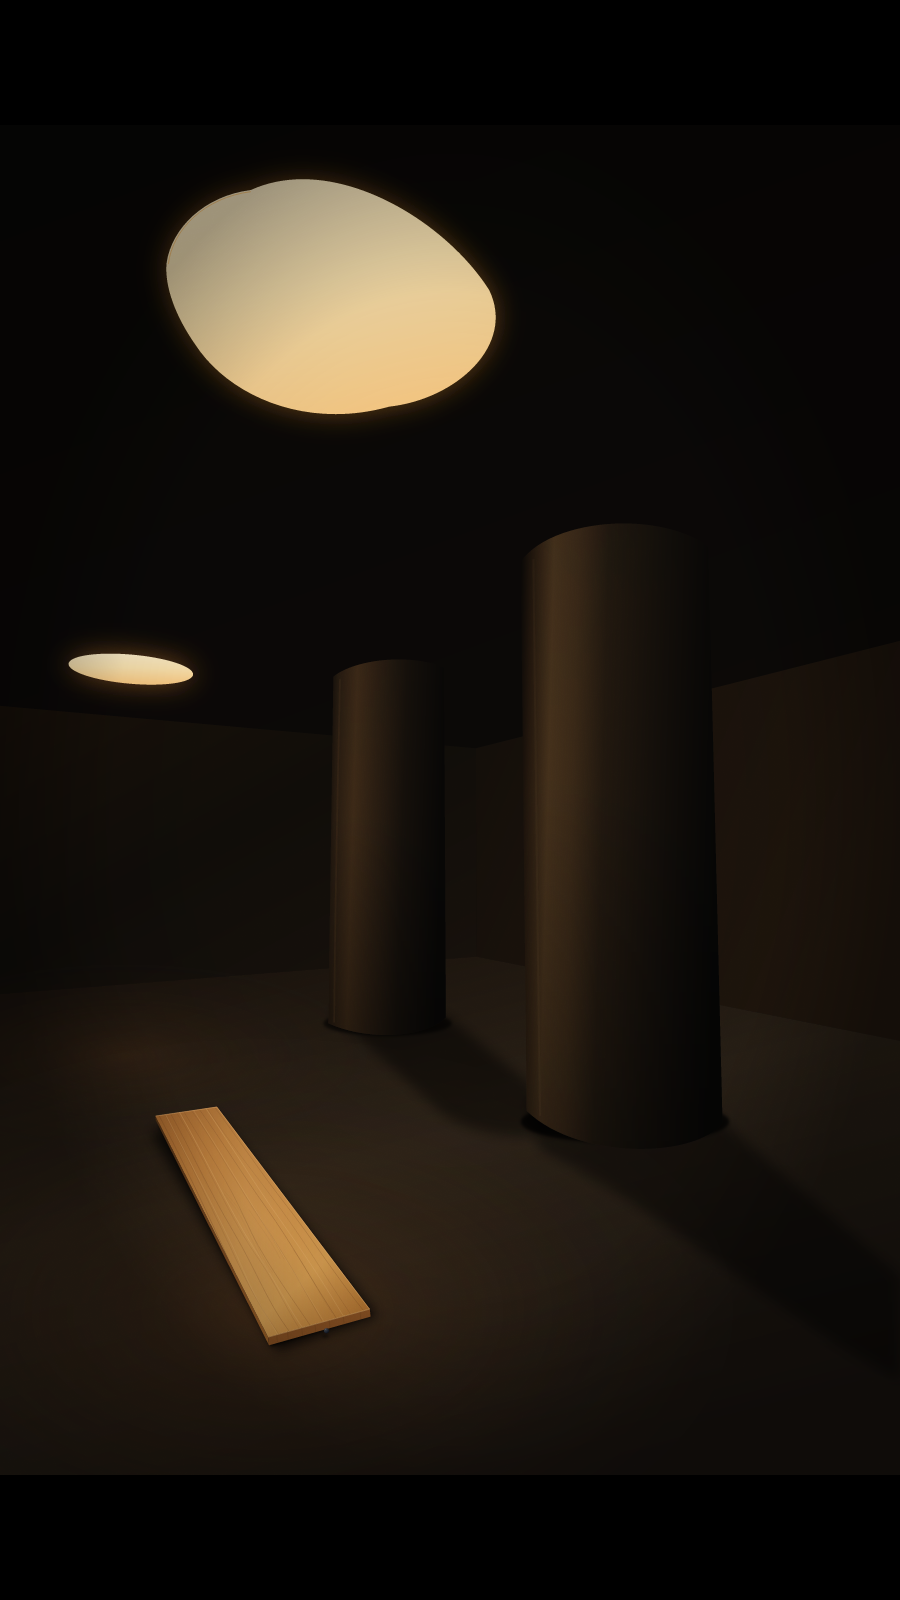
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
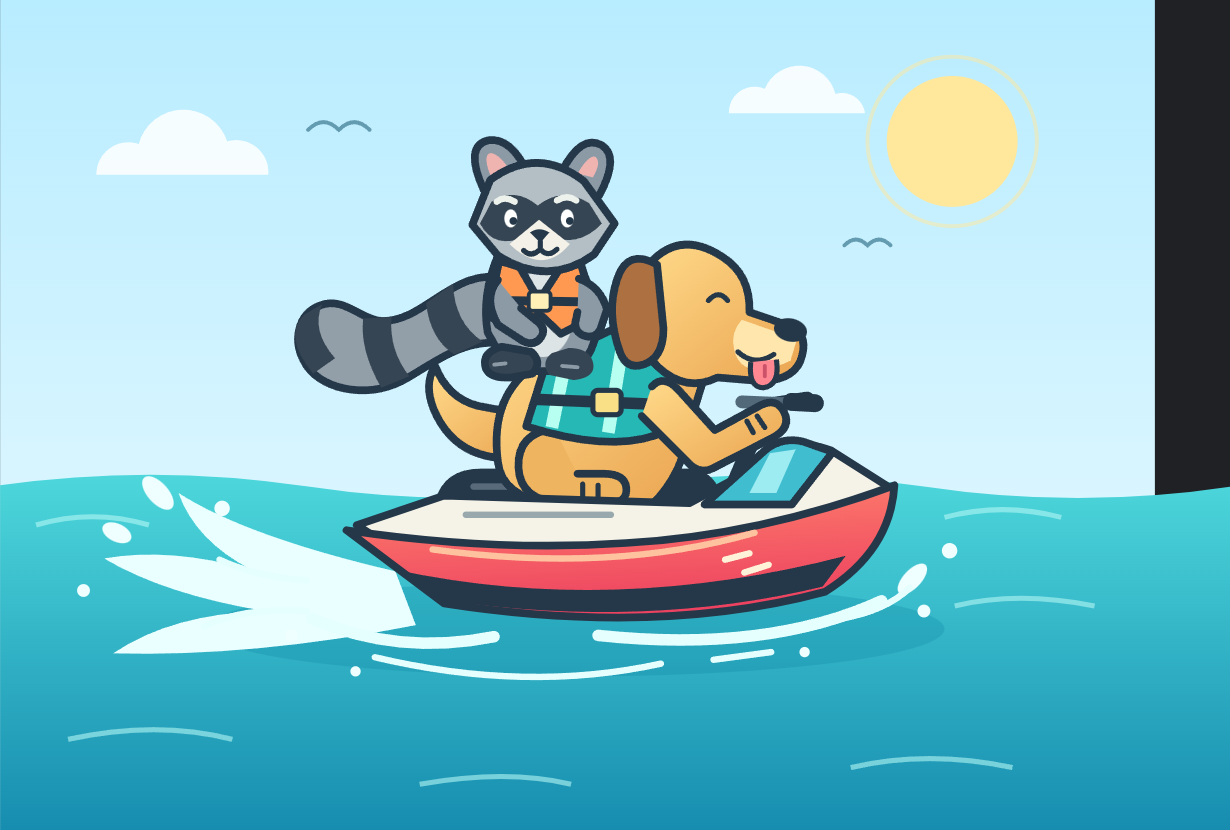
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
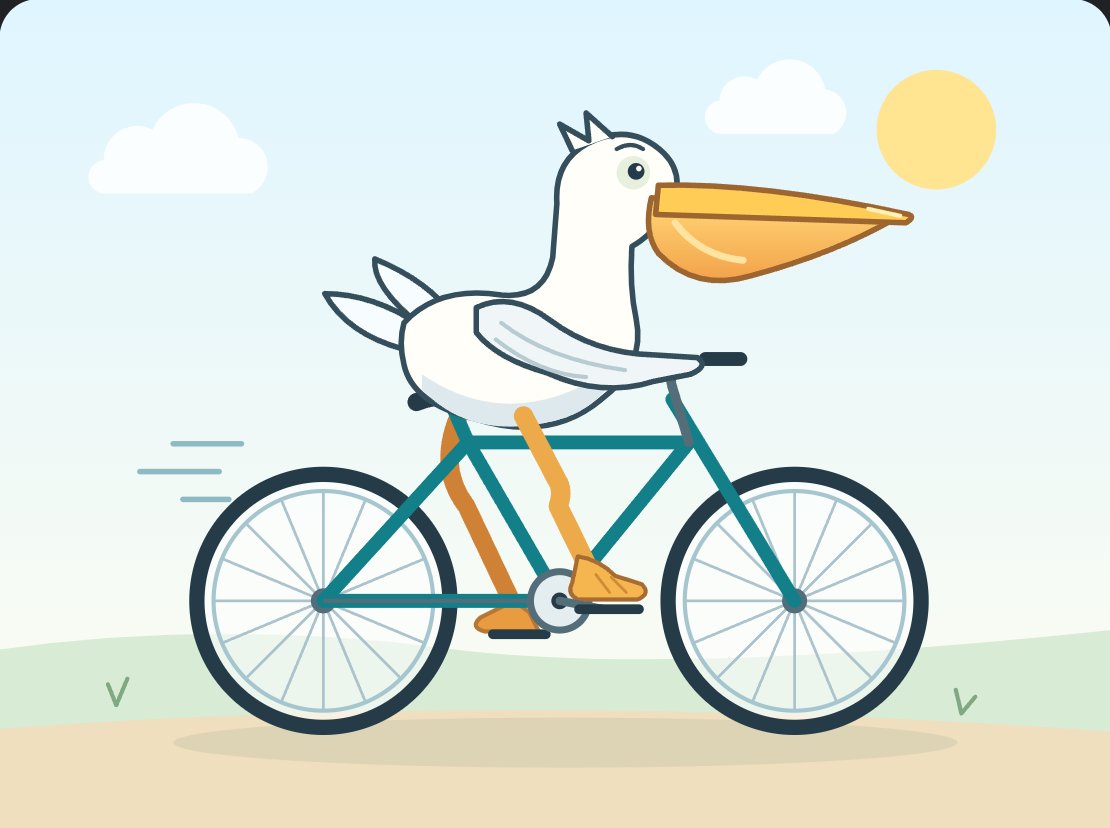
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.

LicenseMIT
Model IDdeepseek/deepseek-v4-pro-0813
StealthMarkOverall rank29/499 rated results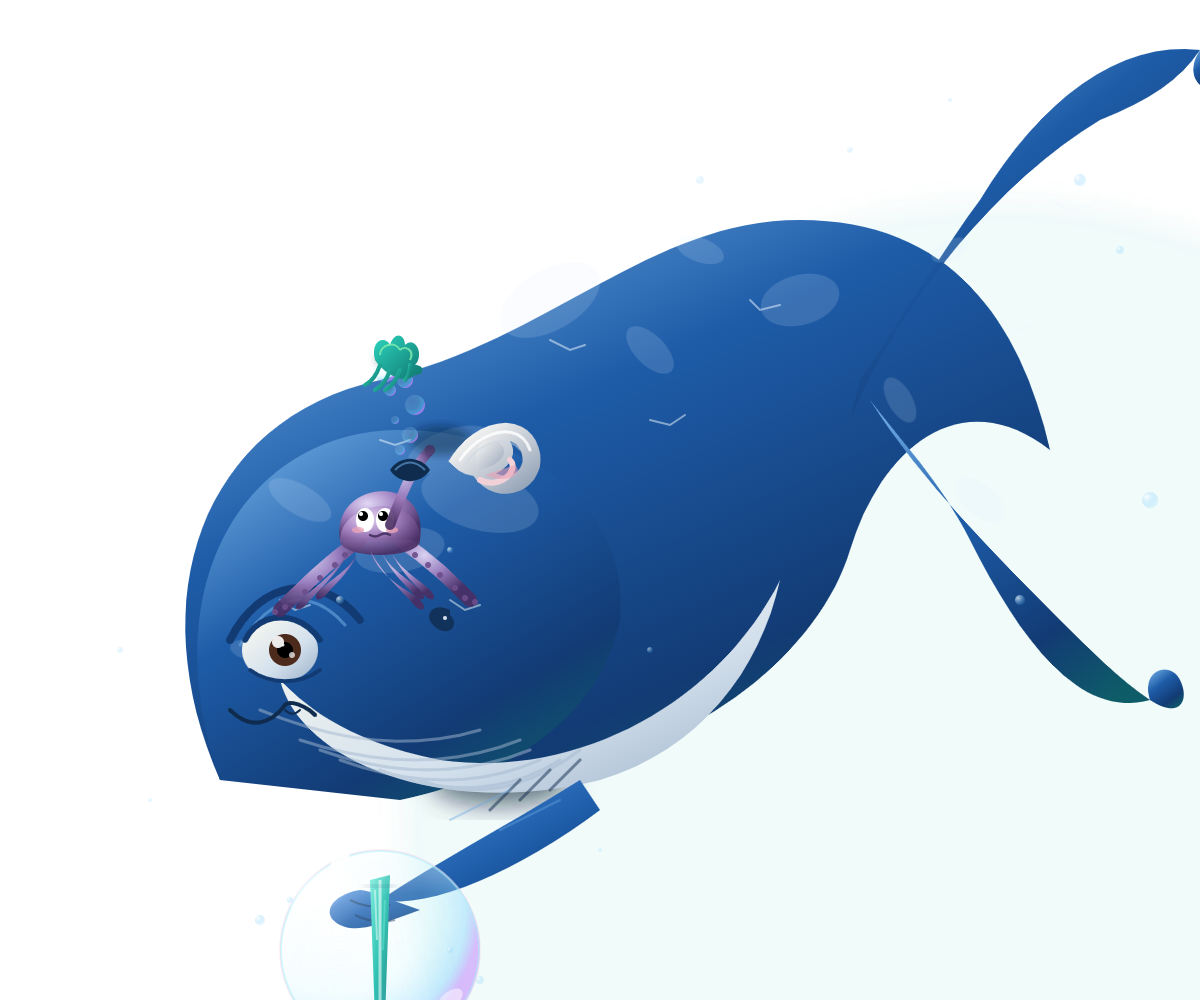
A whale and a tiny shrimp examine one another through bubble lenses, with an octopus nearby. The scene tests interacting characters, differences in scale and transparent materials.
First run
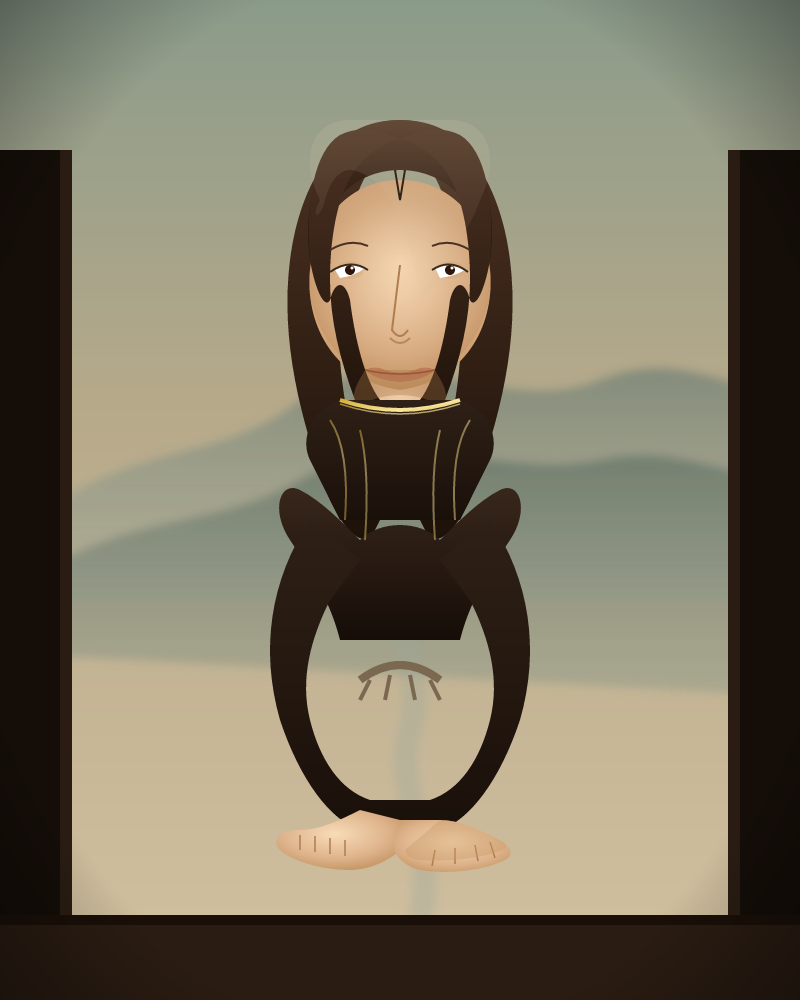
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
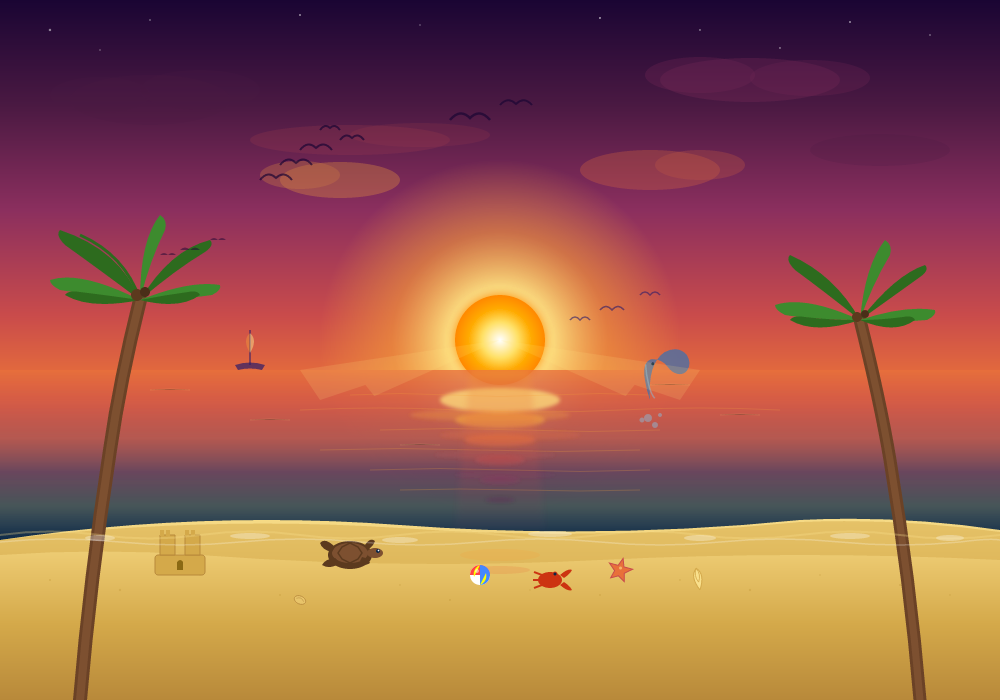
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
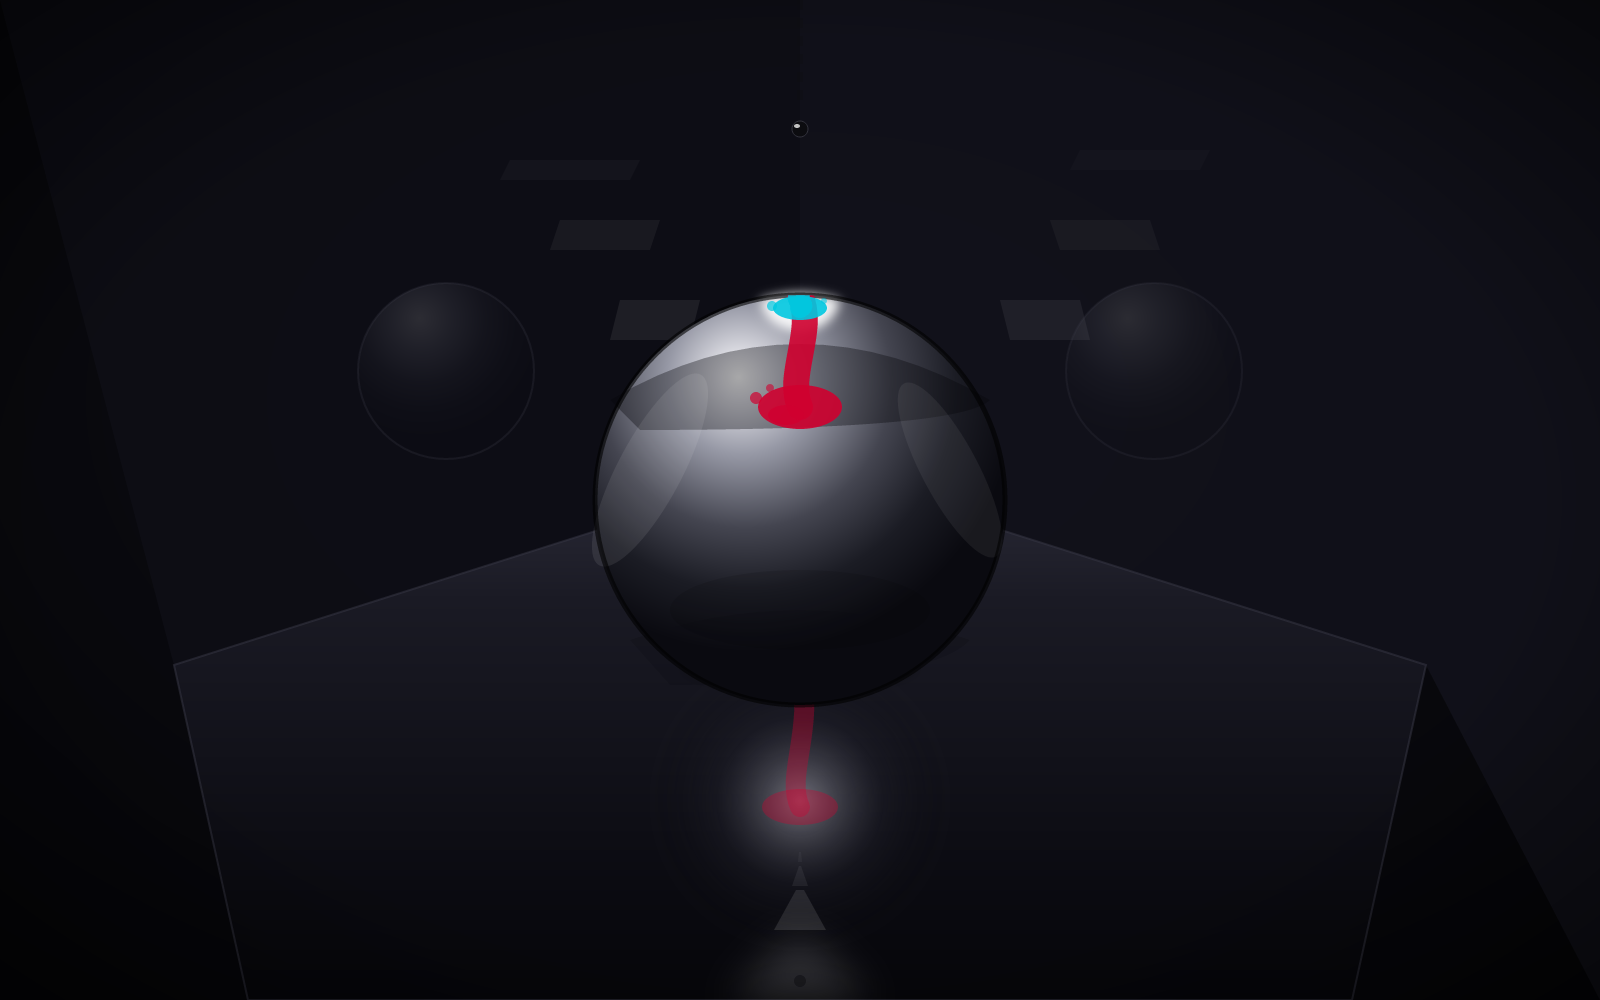
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
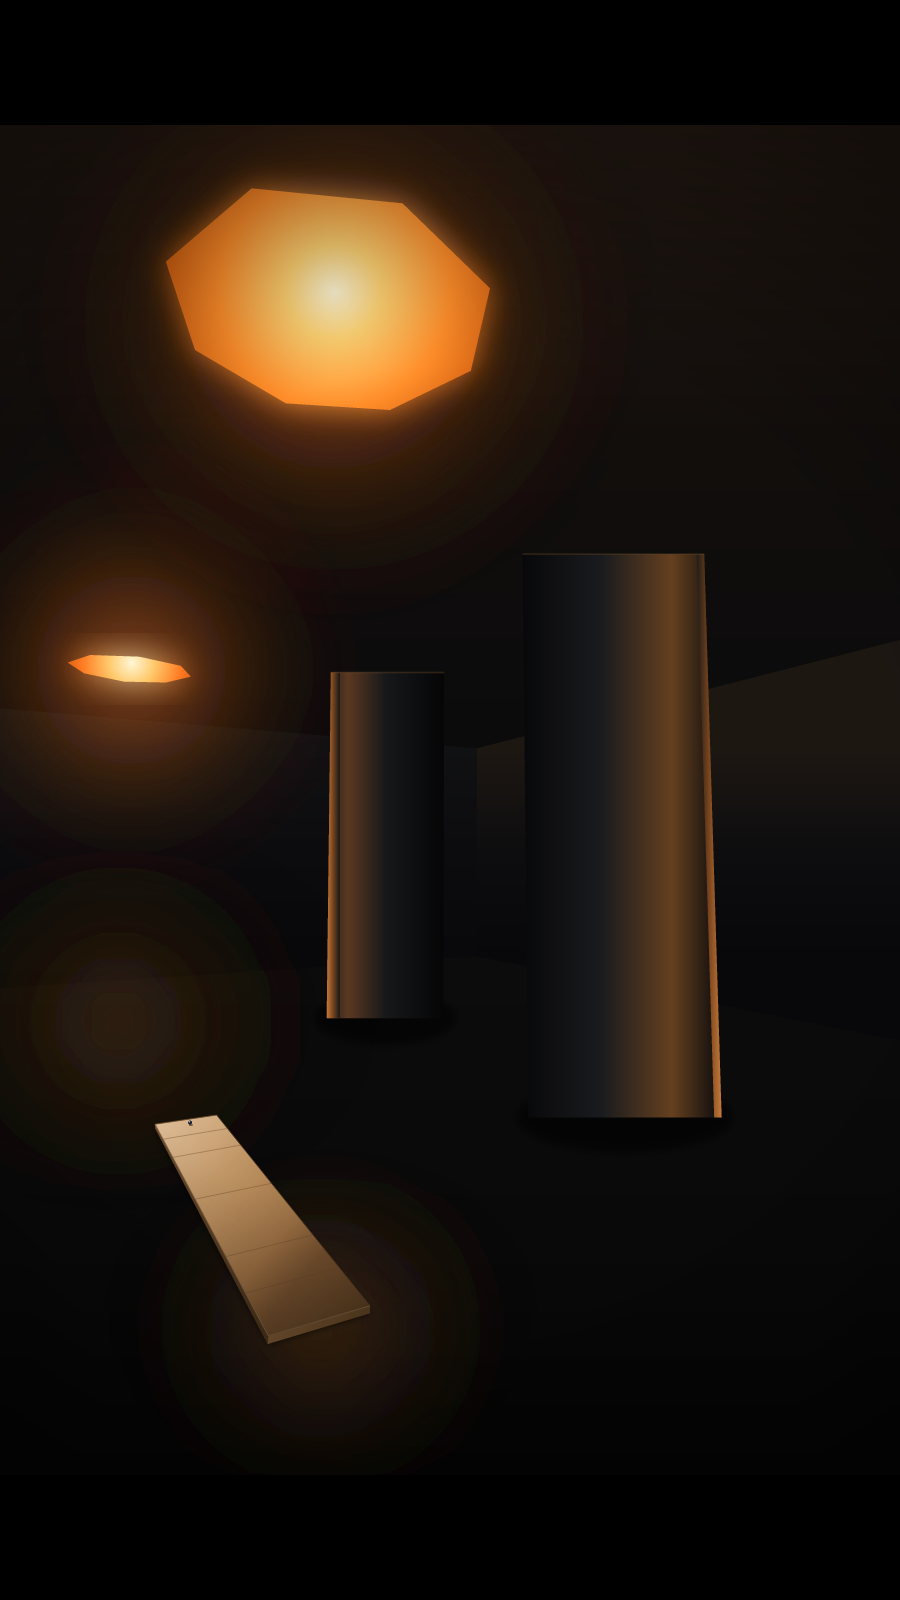
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
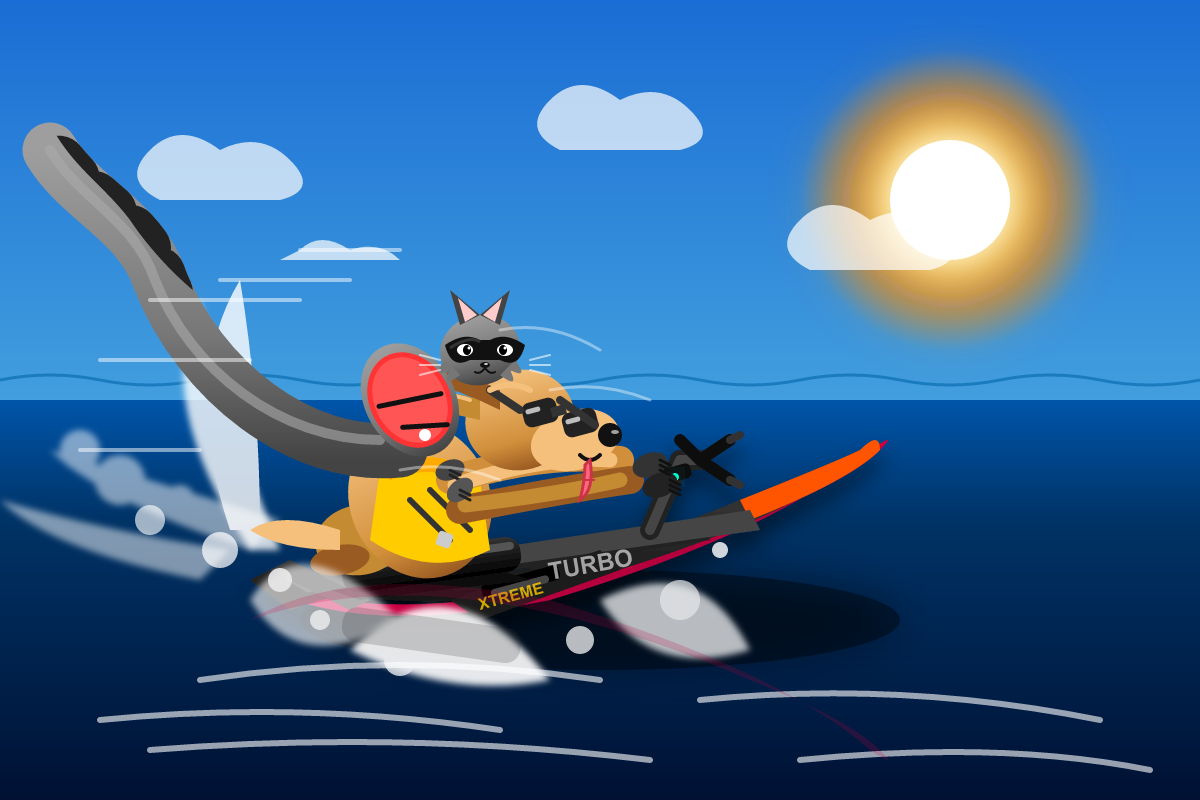
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
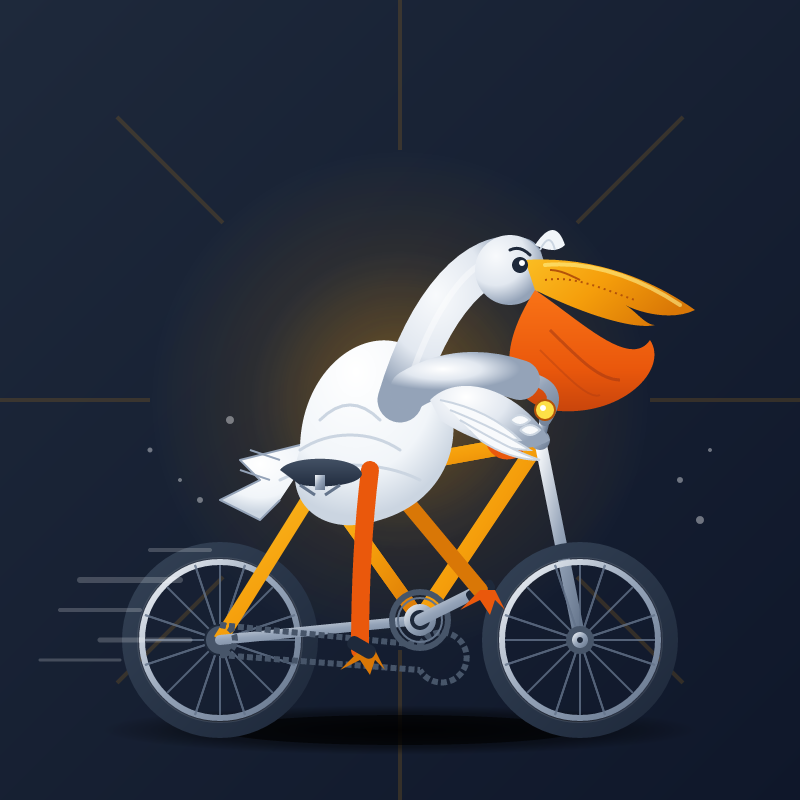
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseMIT
Model IDdeepseek/deepseek-v4.1-flash
StealthMarkOverall rank16/499 rated results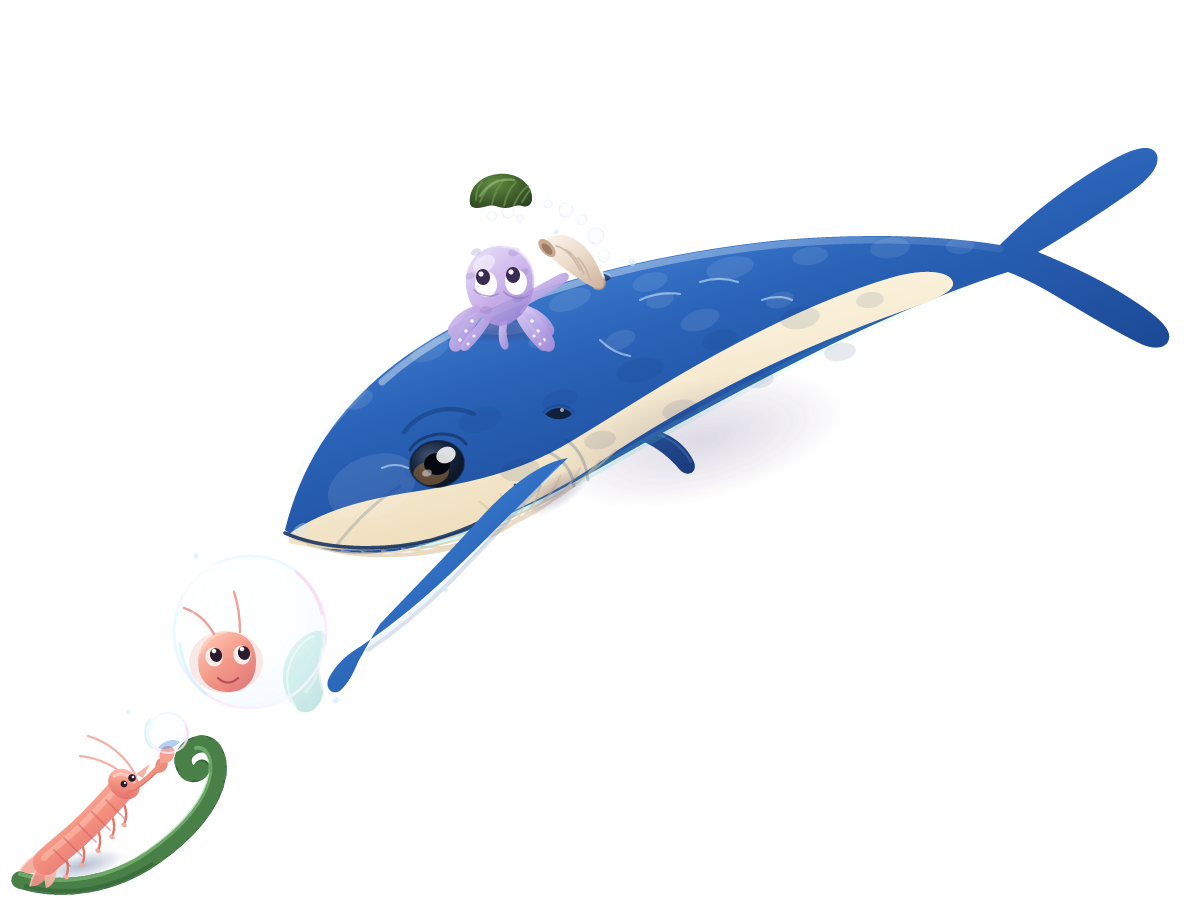
A whale and a tiny shrimp examine one another through bubble lenses, with an octopus nearby. The scene tests interacting characters, differences in scale and transparent materials.
First run
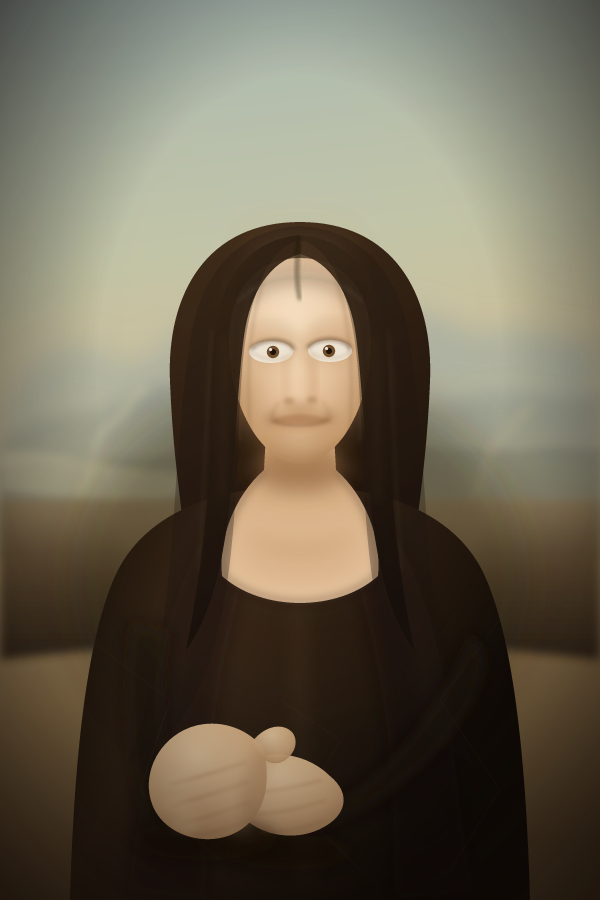
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
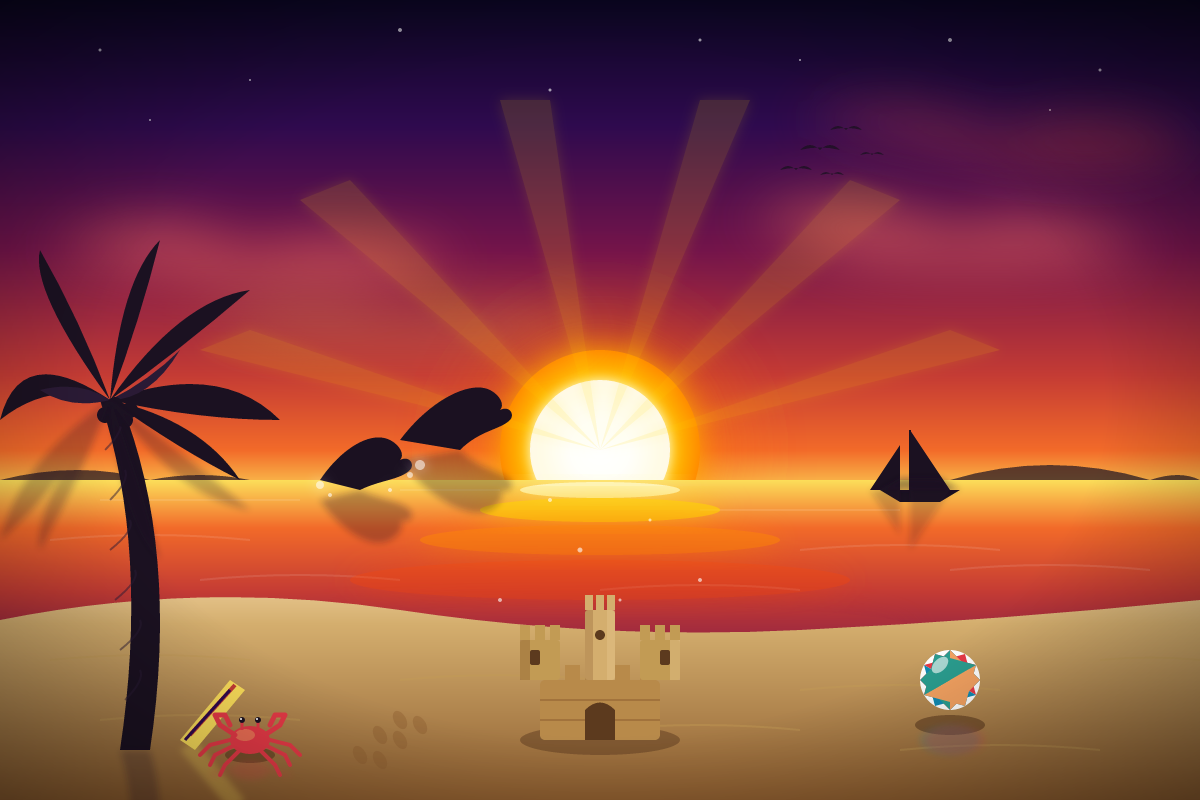
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
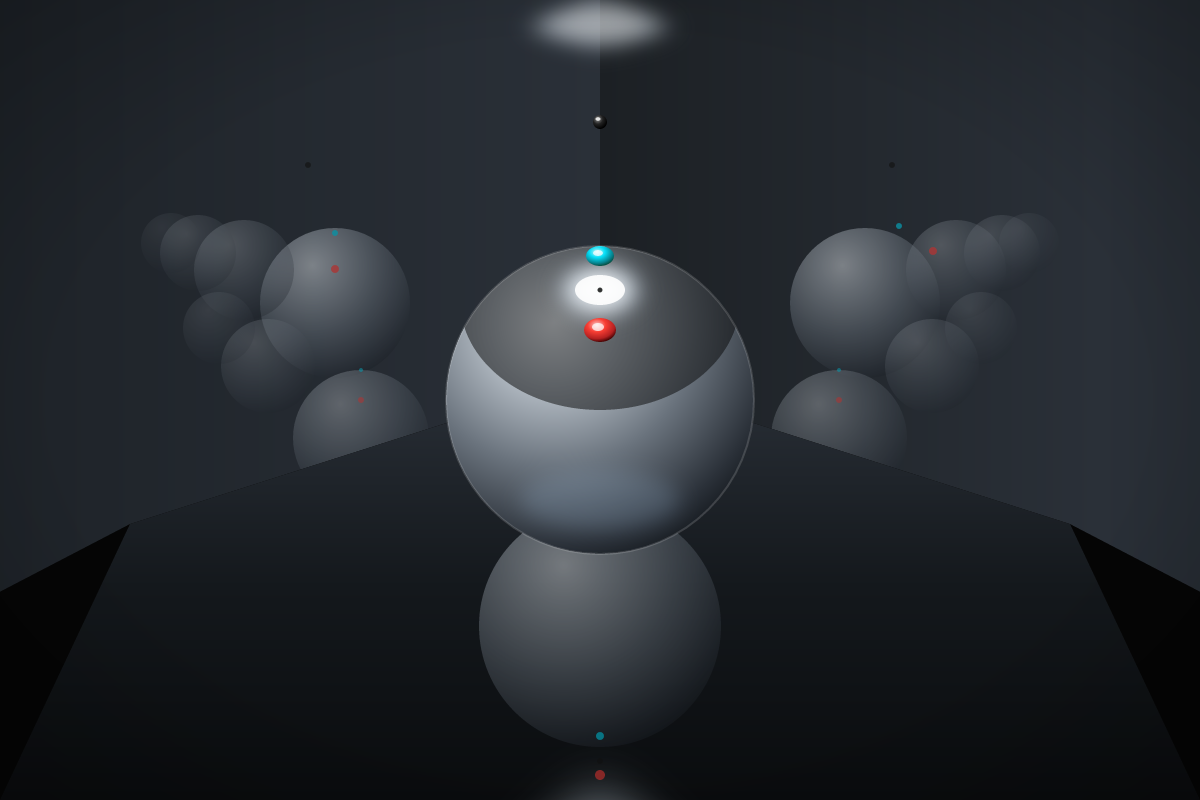
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
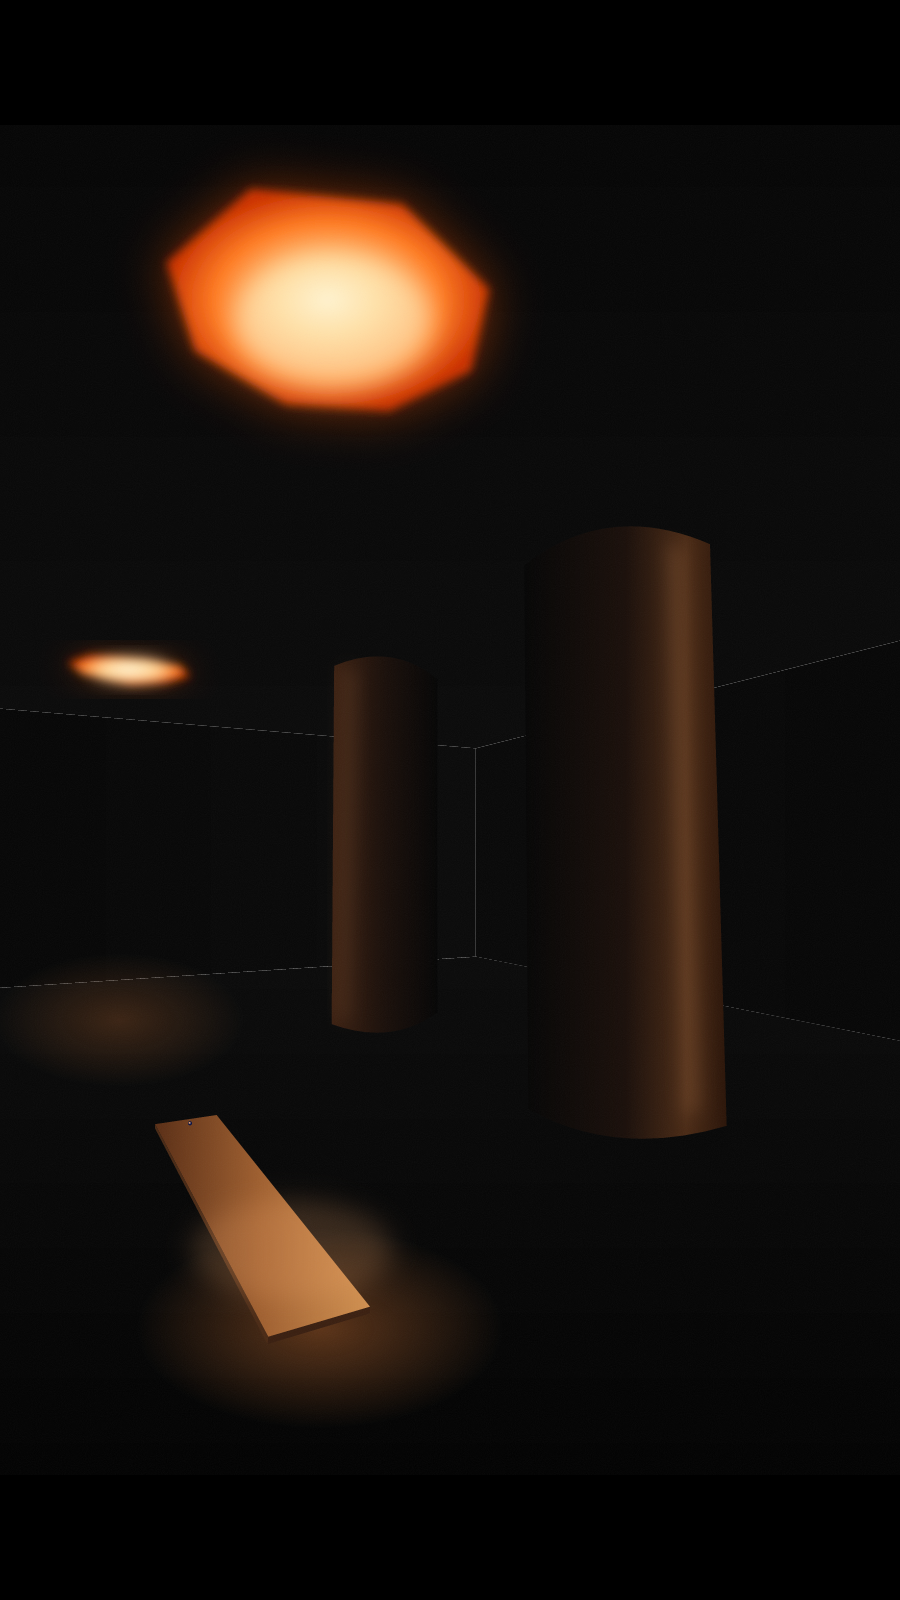
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
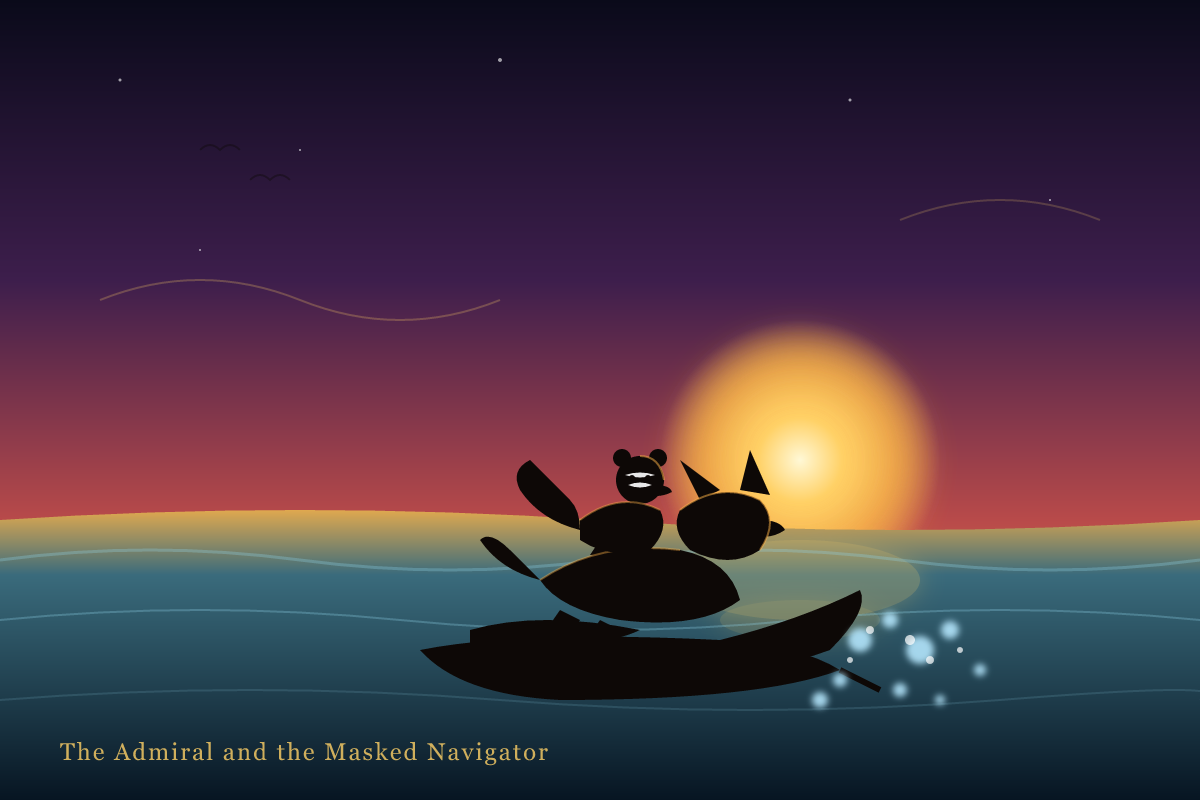
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
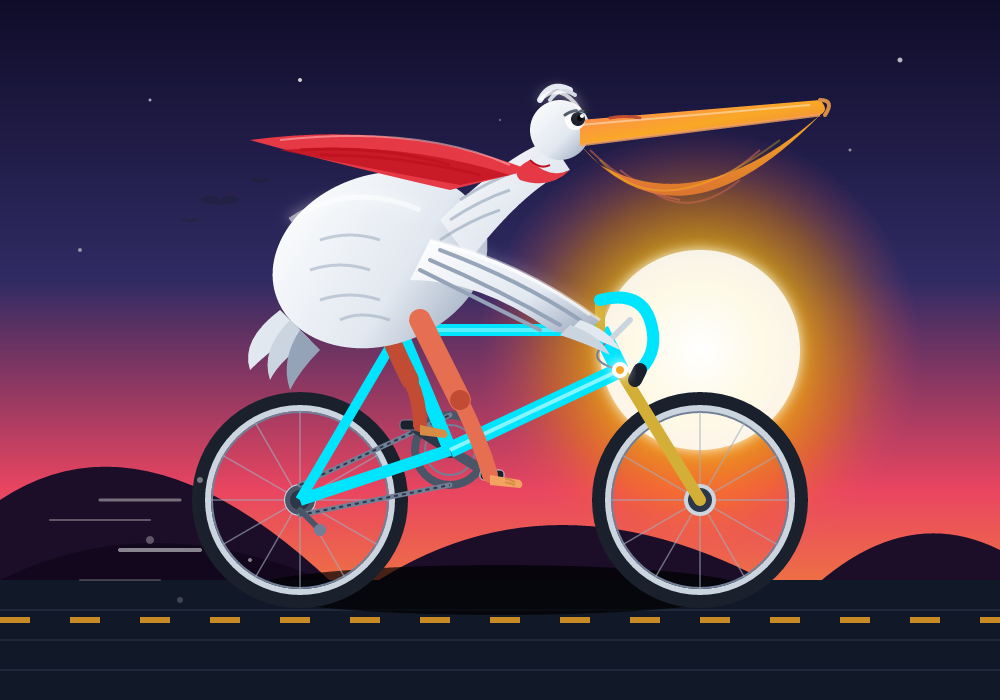
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseProprietary hosted service
Model IDopenai/gpt-6.1-sol
StealthMarkOverall rank4/499 rated results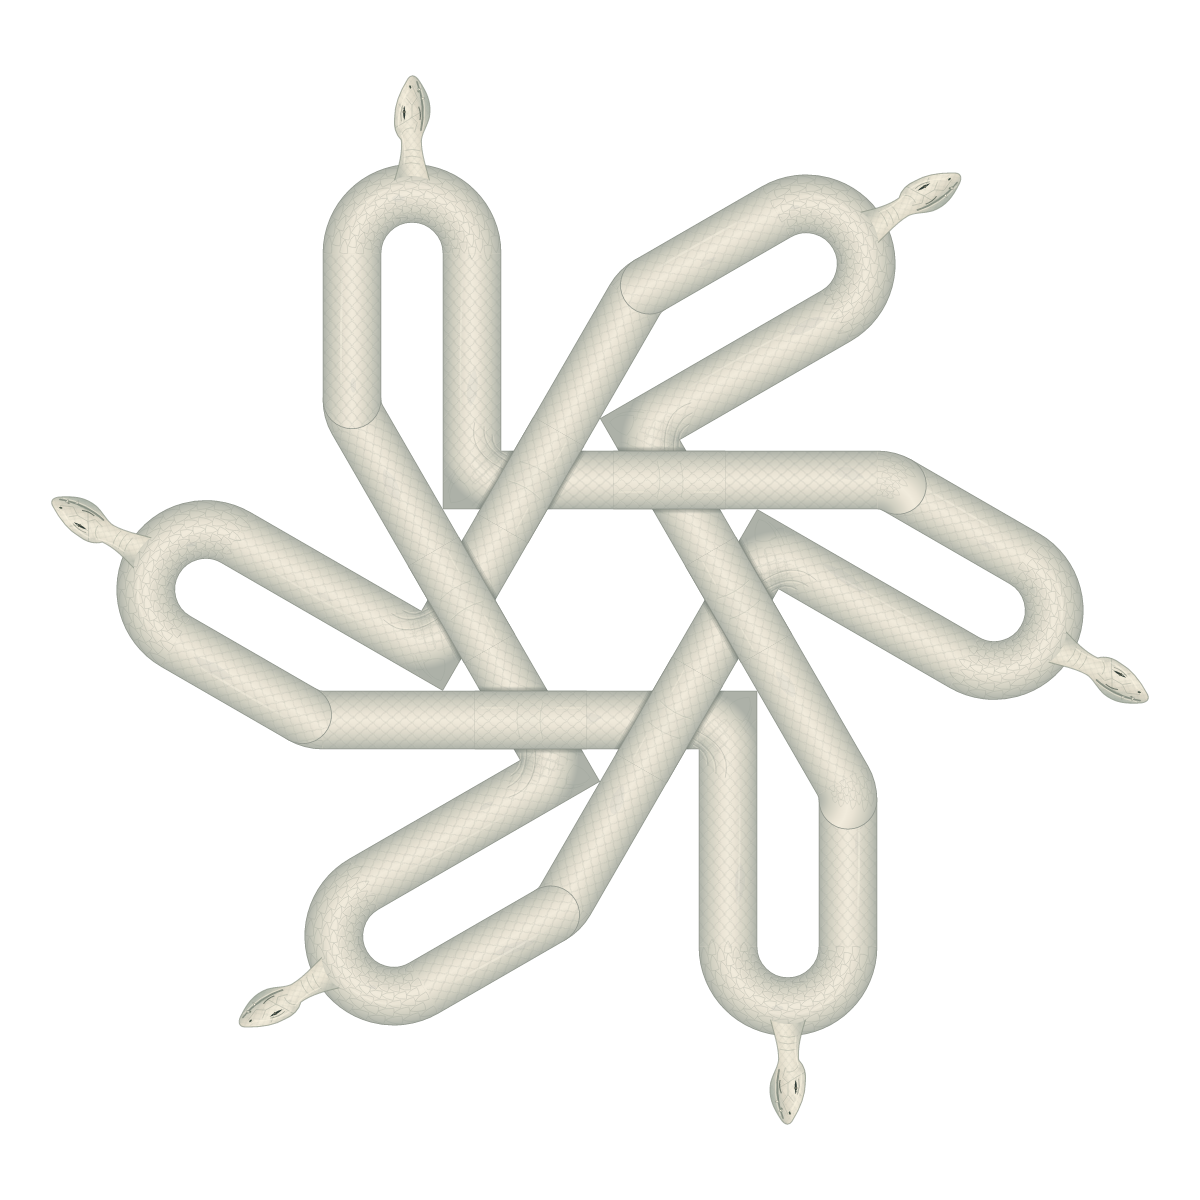
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
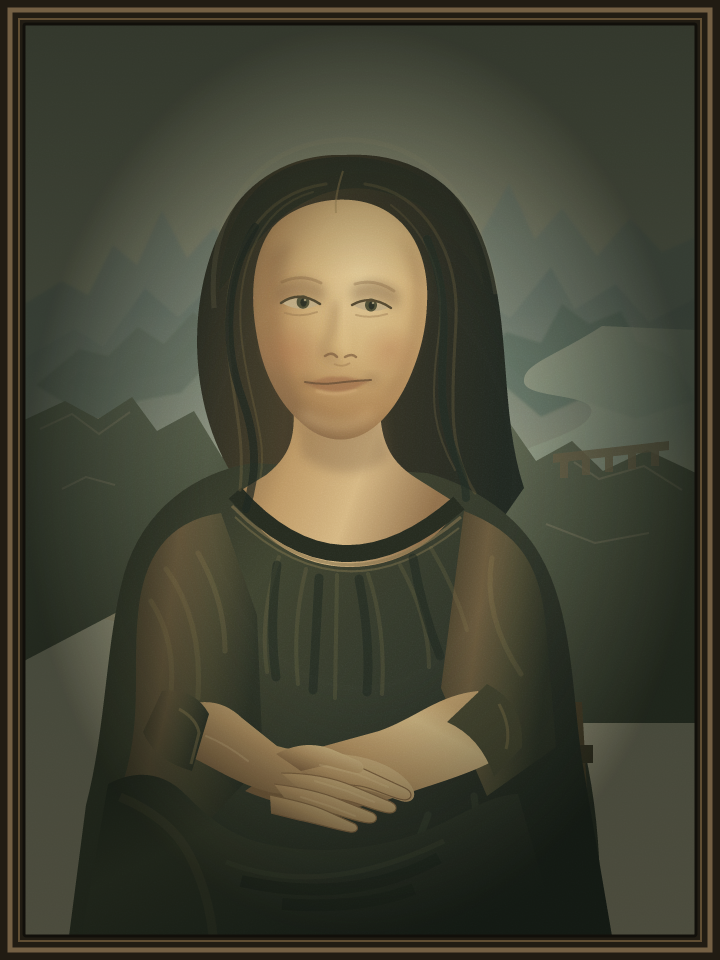
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
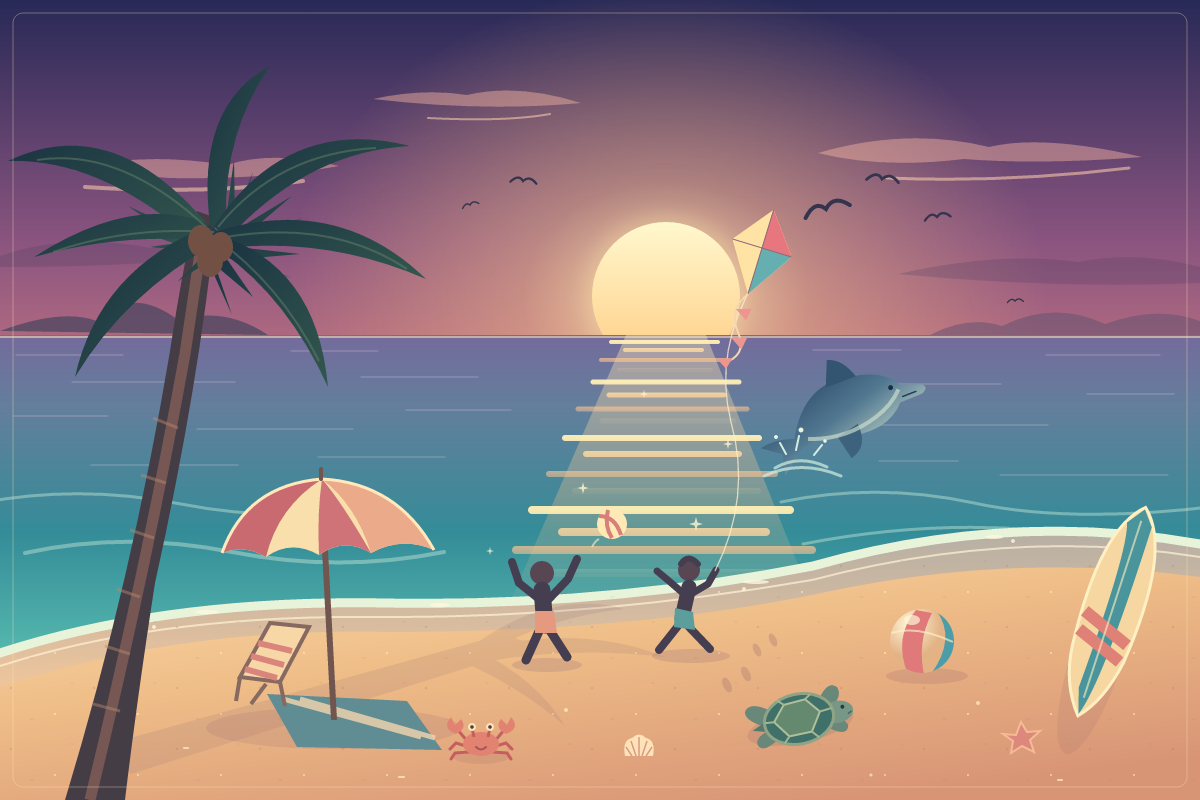
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
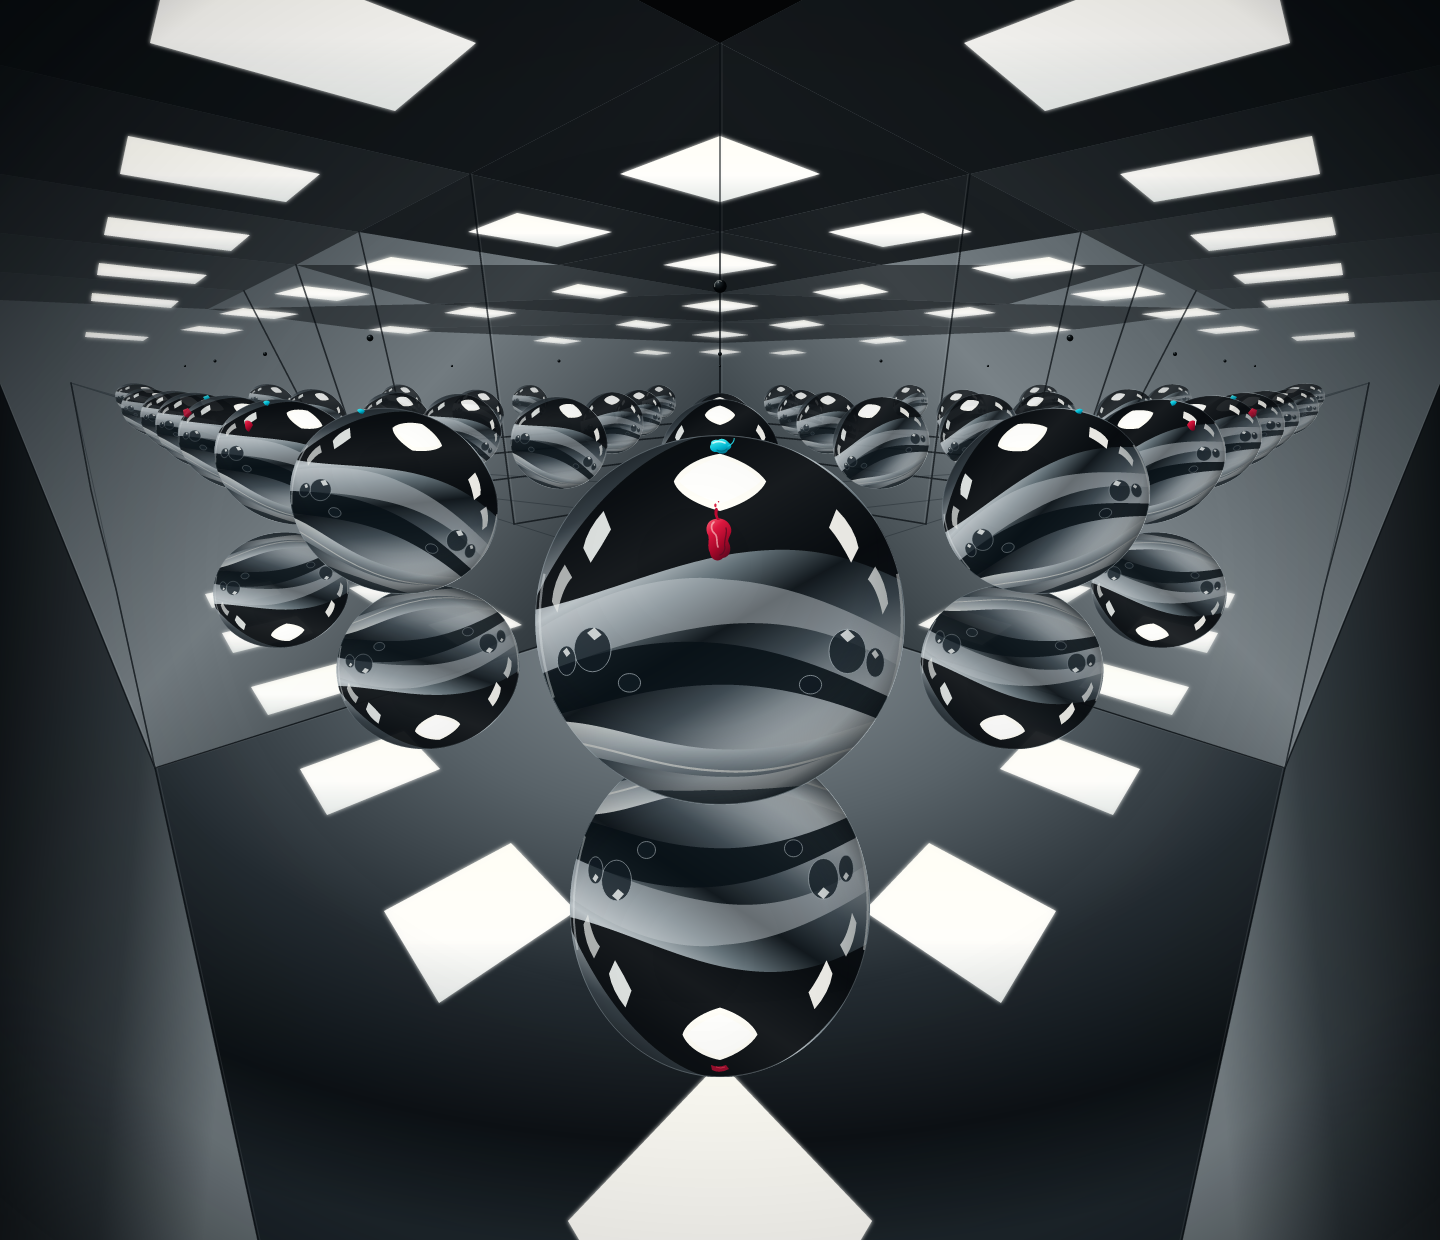
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
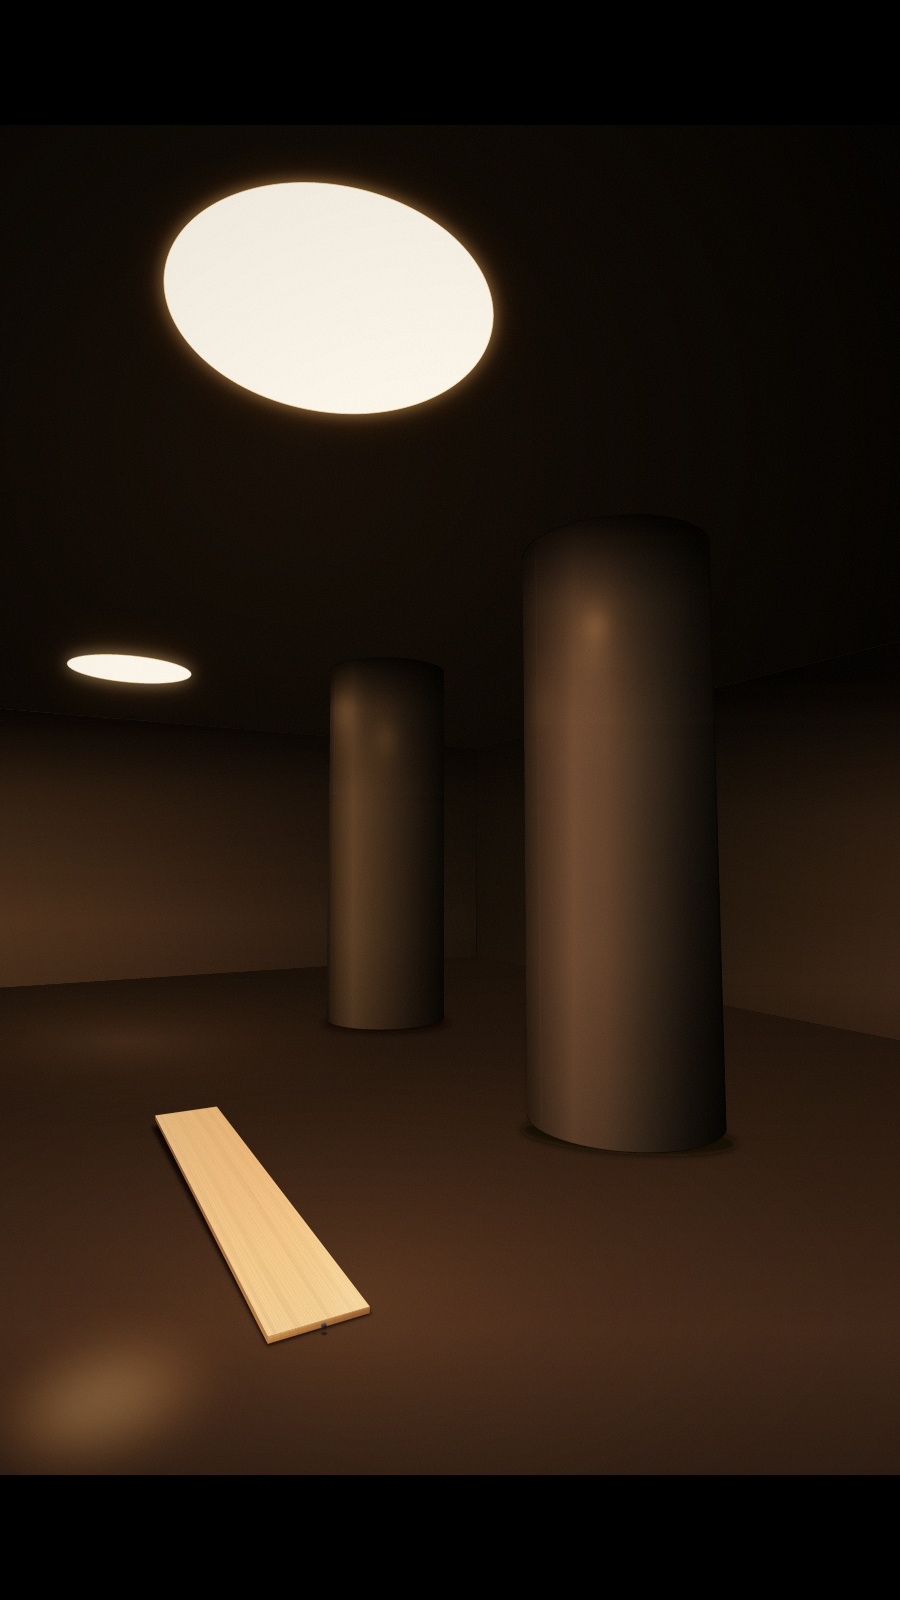
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
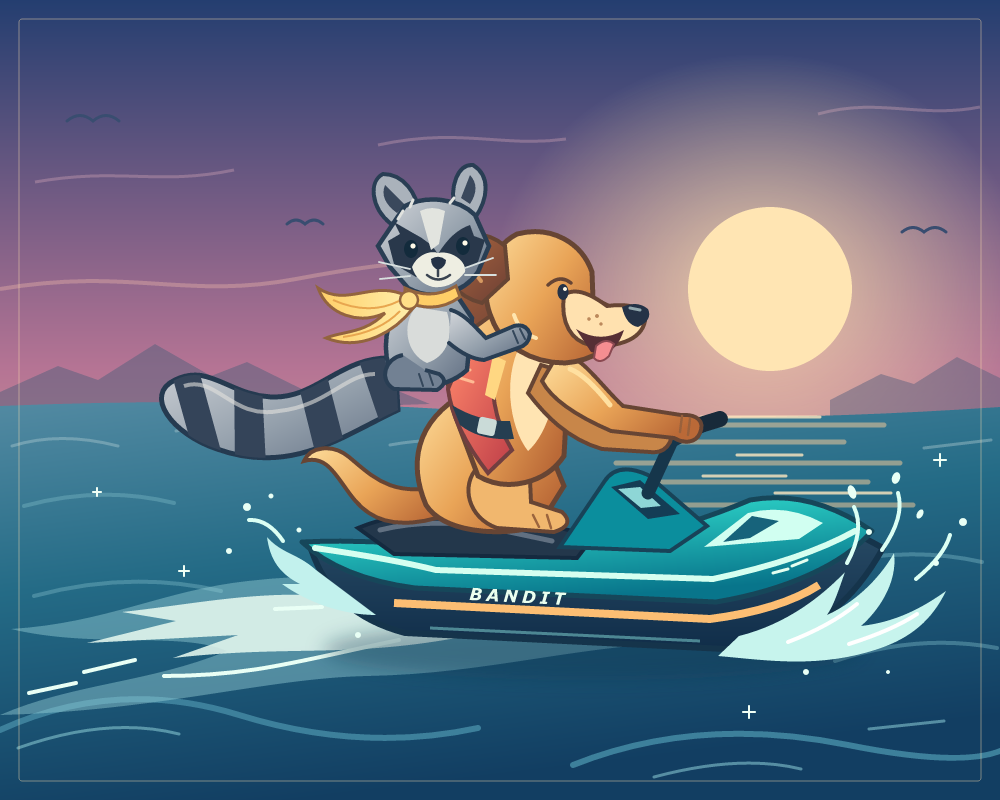
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
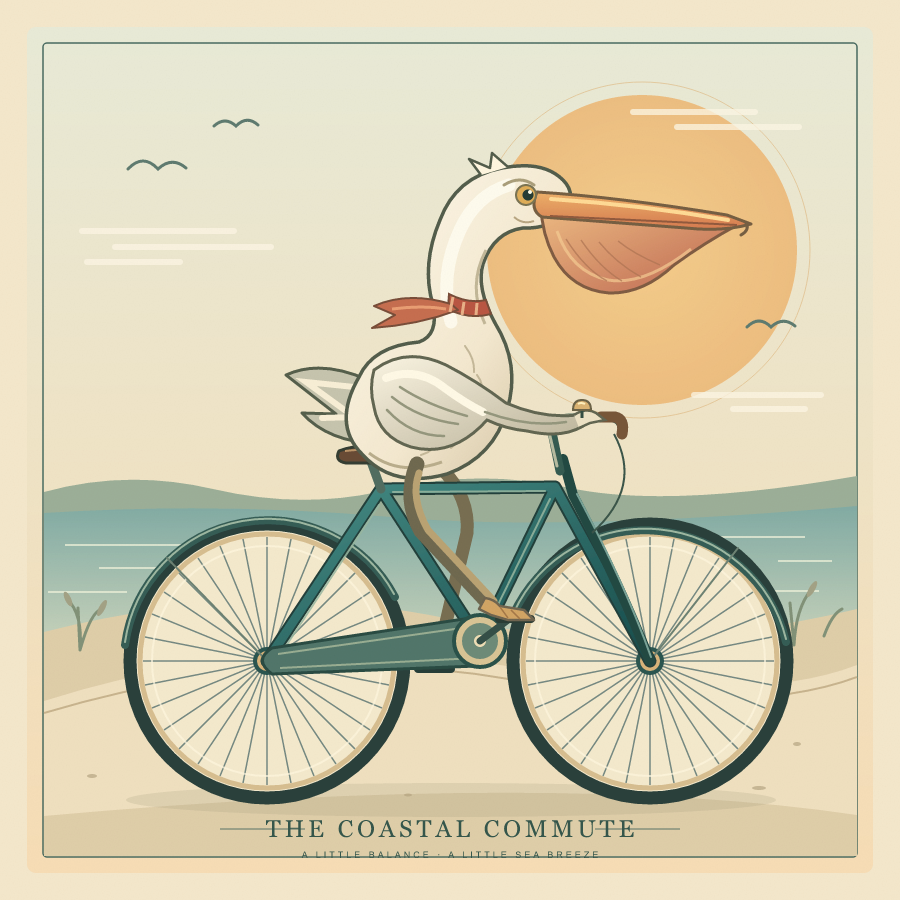
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseQwen Community 1.0
Model IDqwen/qwen3.8-flash
StealthMarkOverall rank24/499 rated results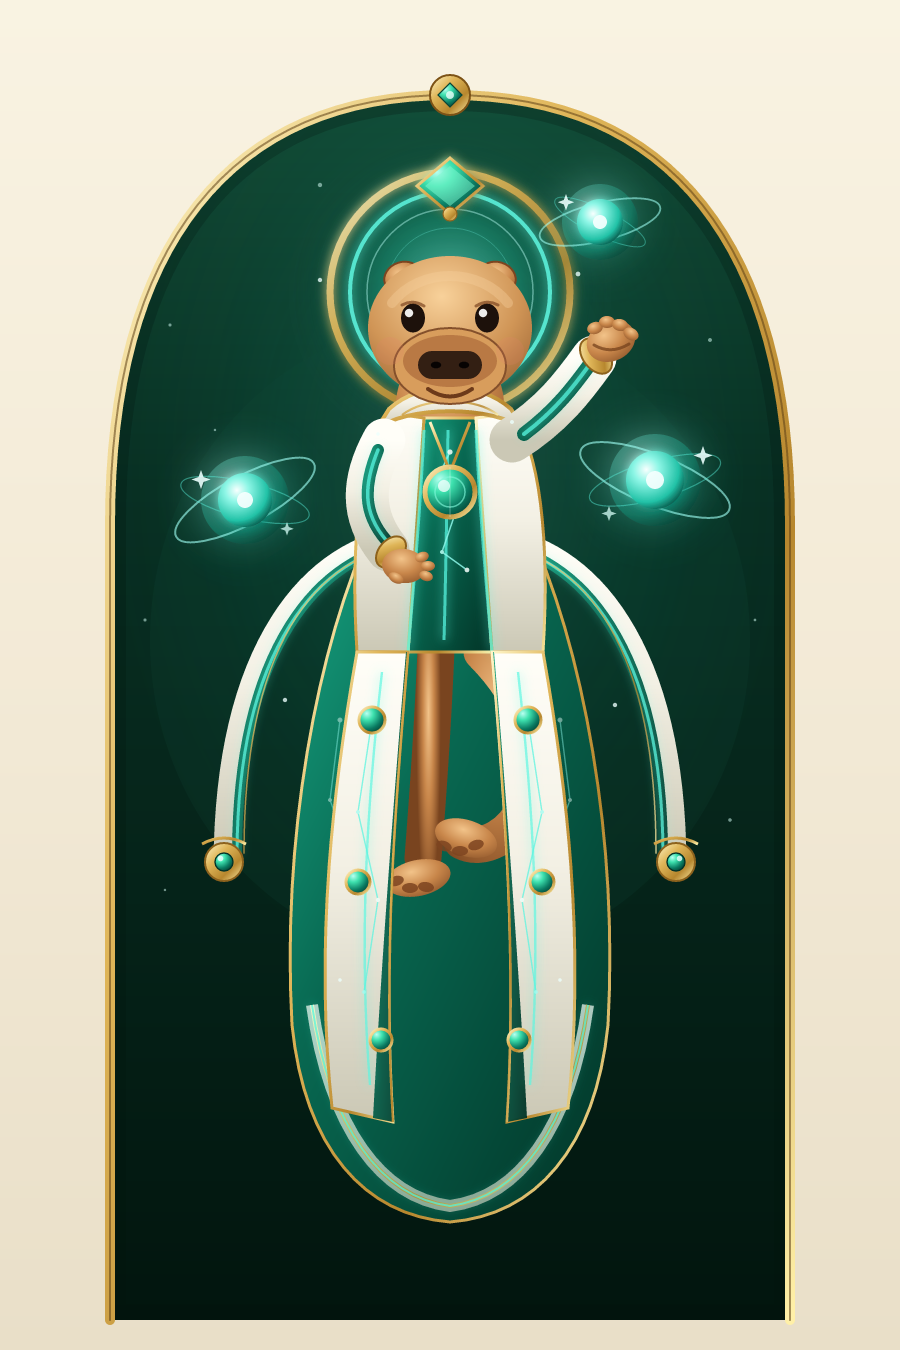
A floating capybara in ornate robes tests character anatomy, layered fabric and the placement of surrounding luminous forms.
First run
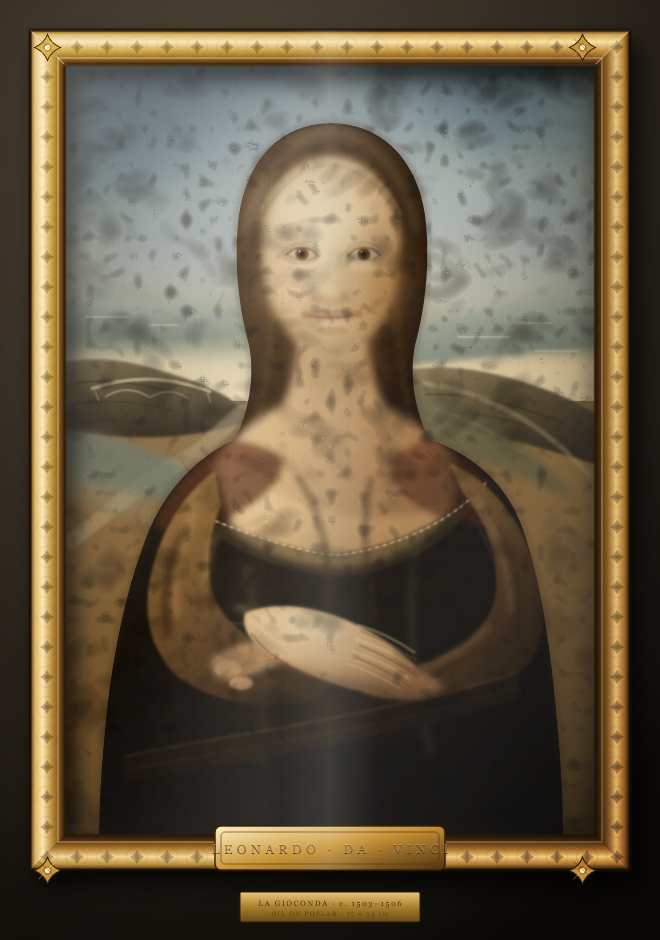
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
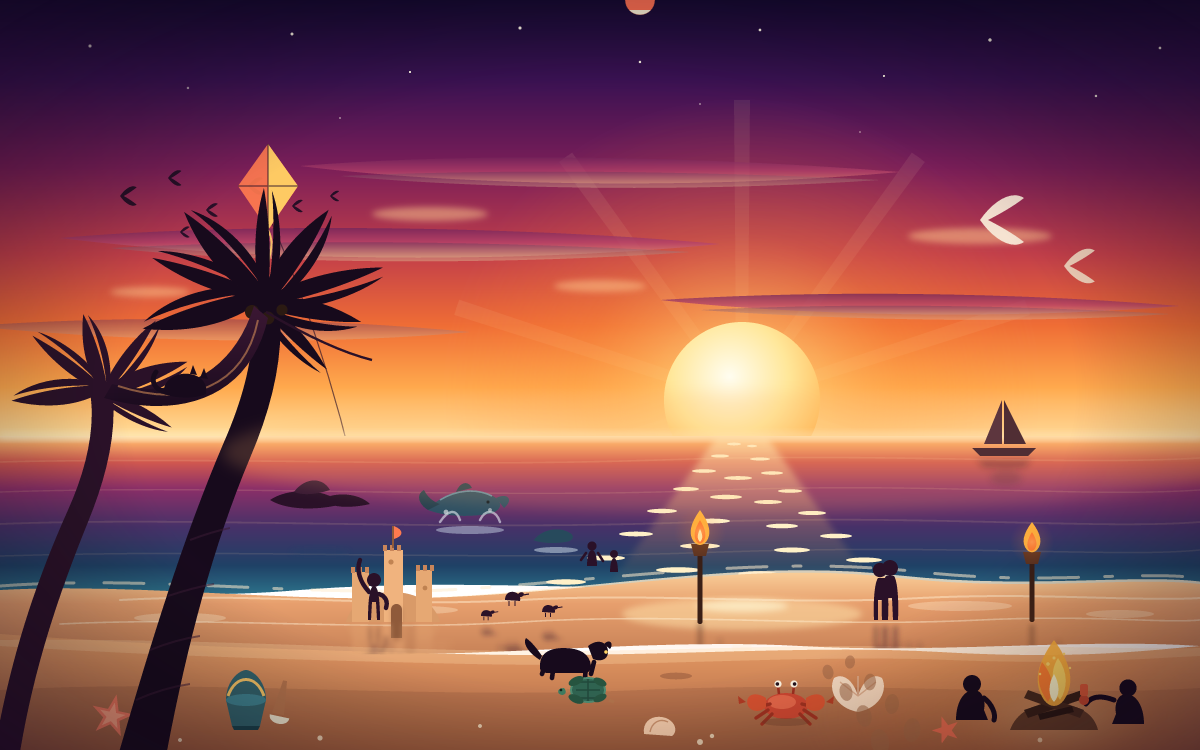
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
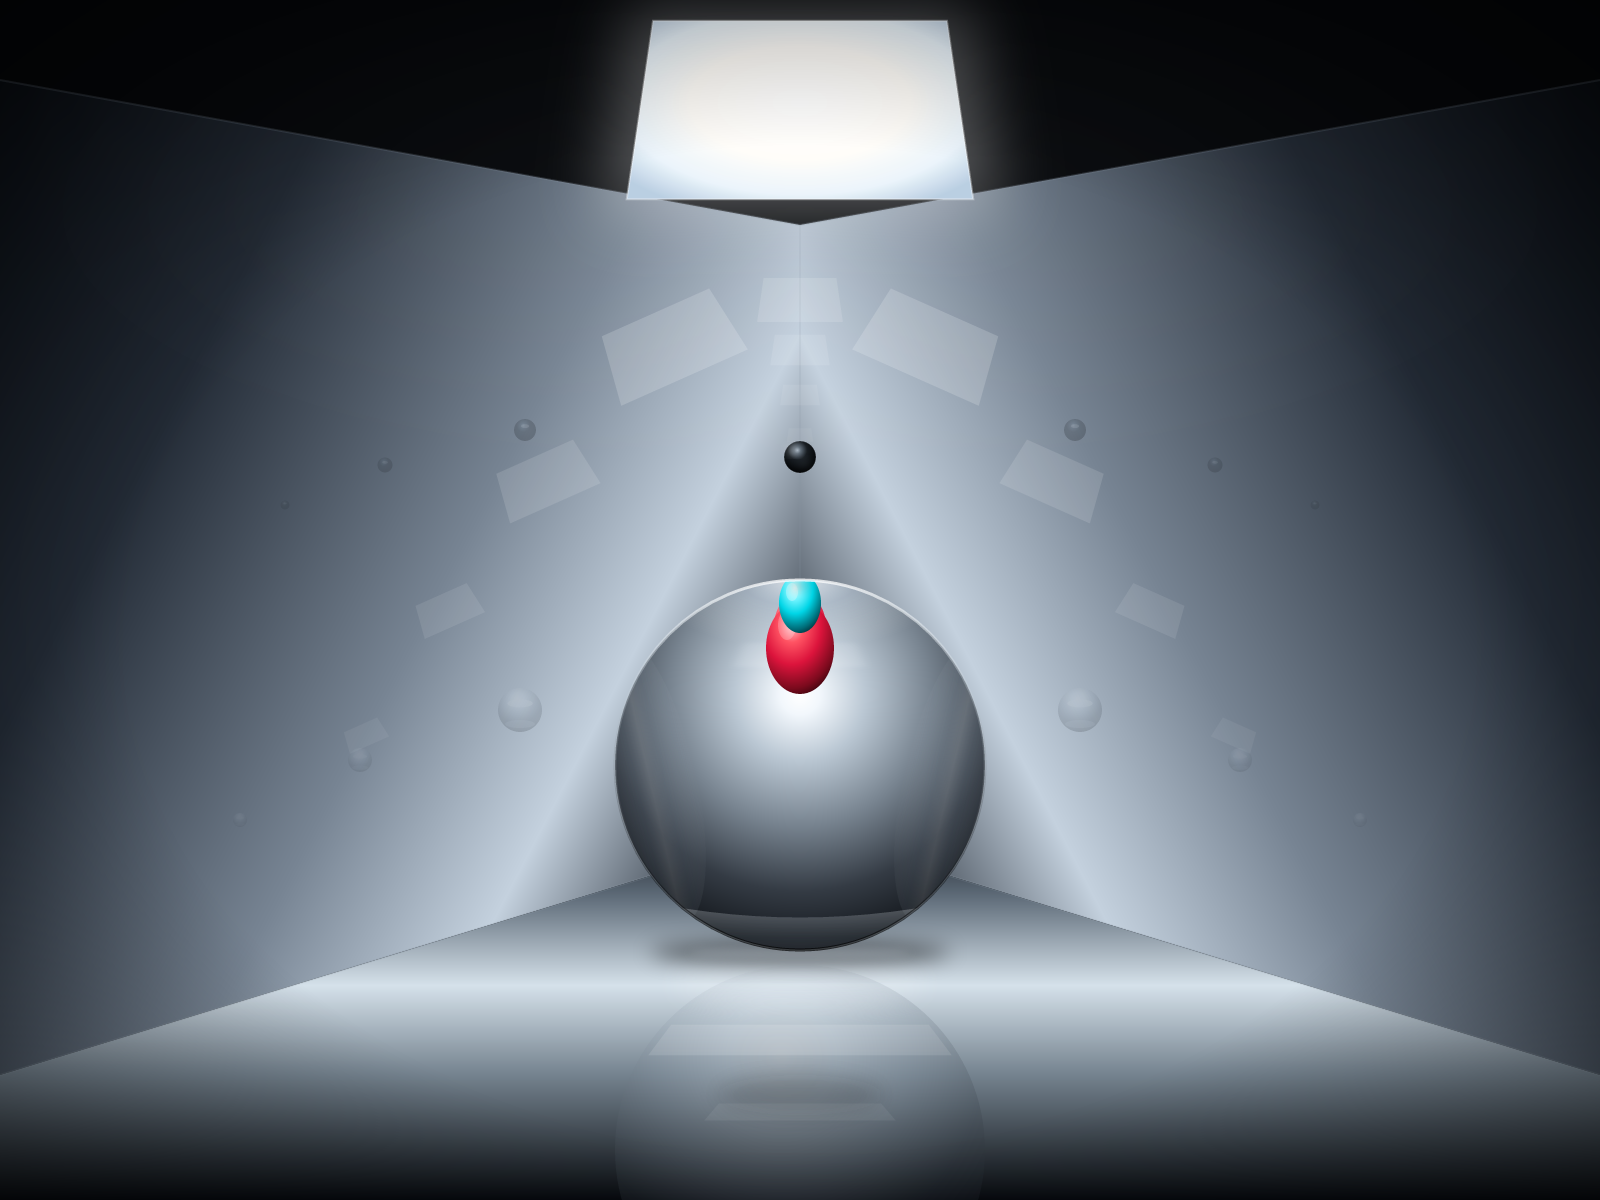
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
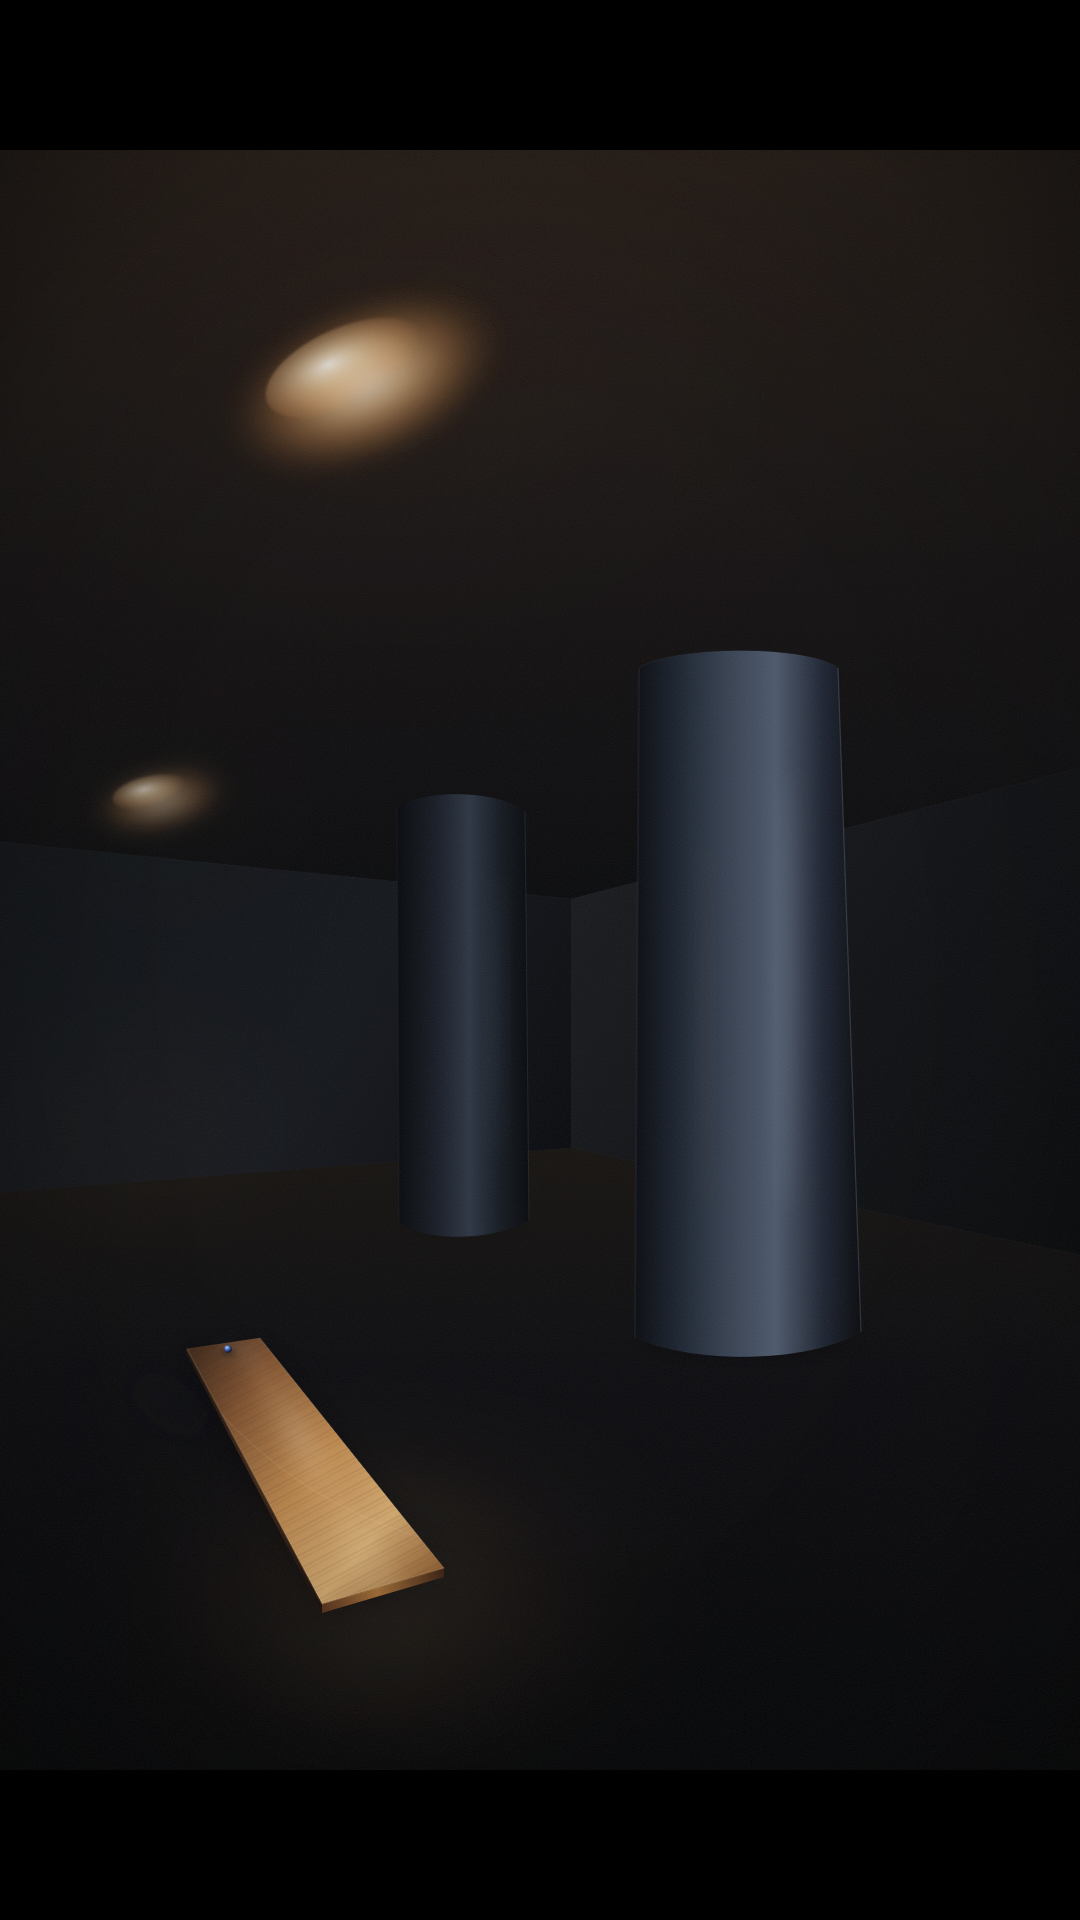
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
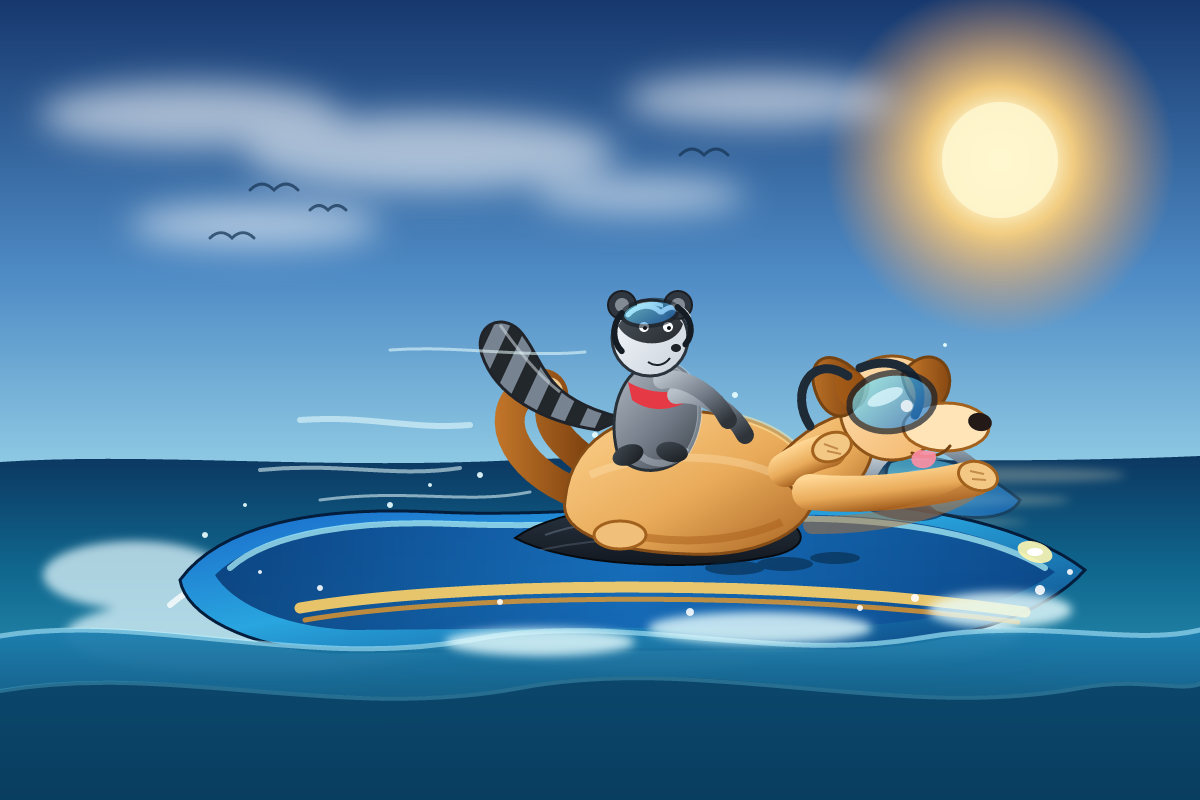
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
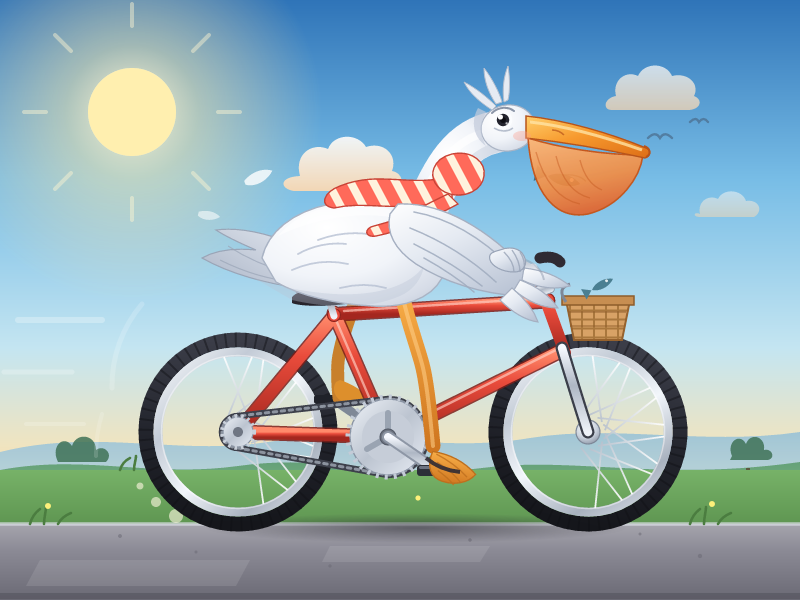
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDgoogle/gemini-3.8-flash
StealthMarkOverall rank19/499 rated results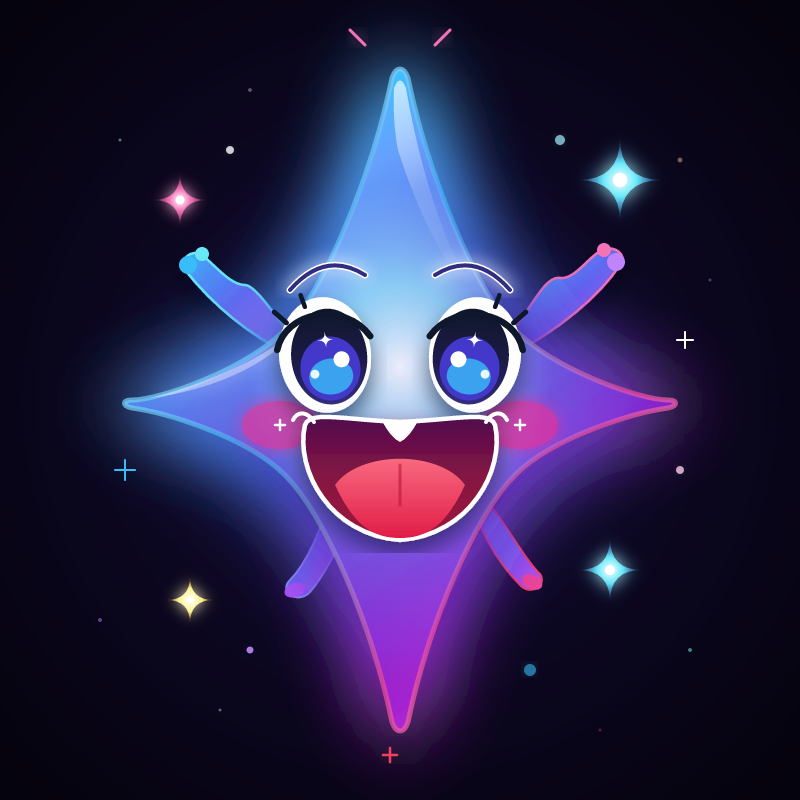
A luminous star-shaped creature tests expressive features, a clear silhouette and smooth colour transitions.
First run
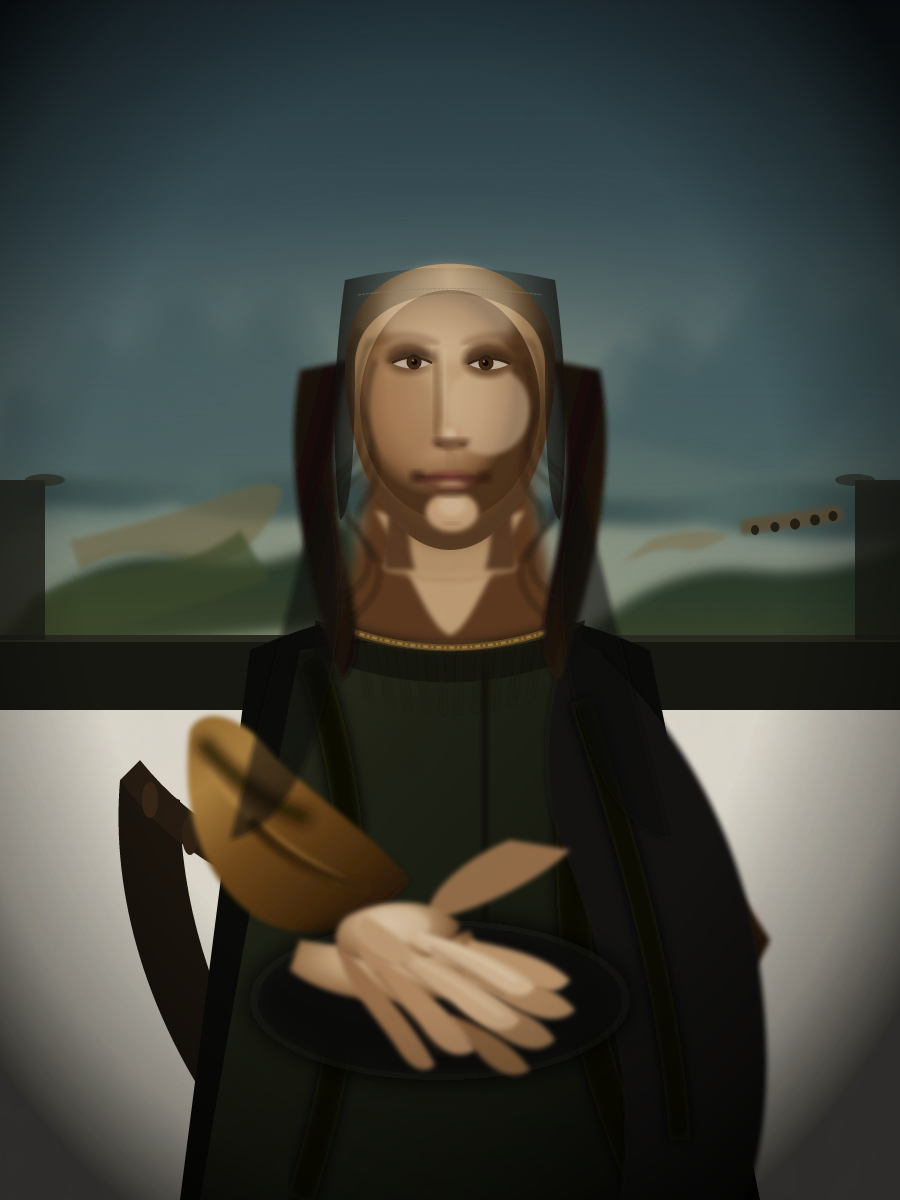
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
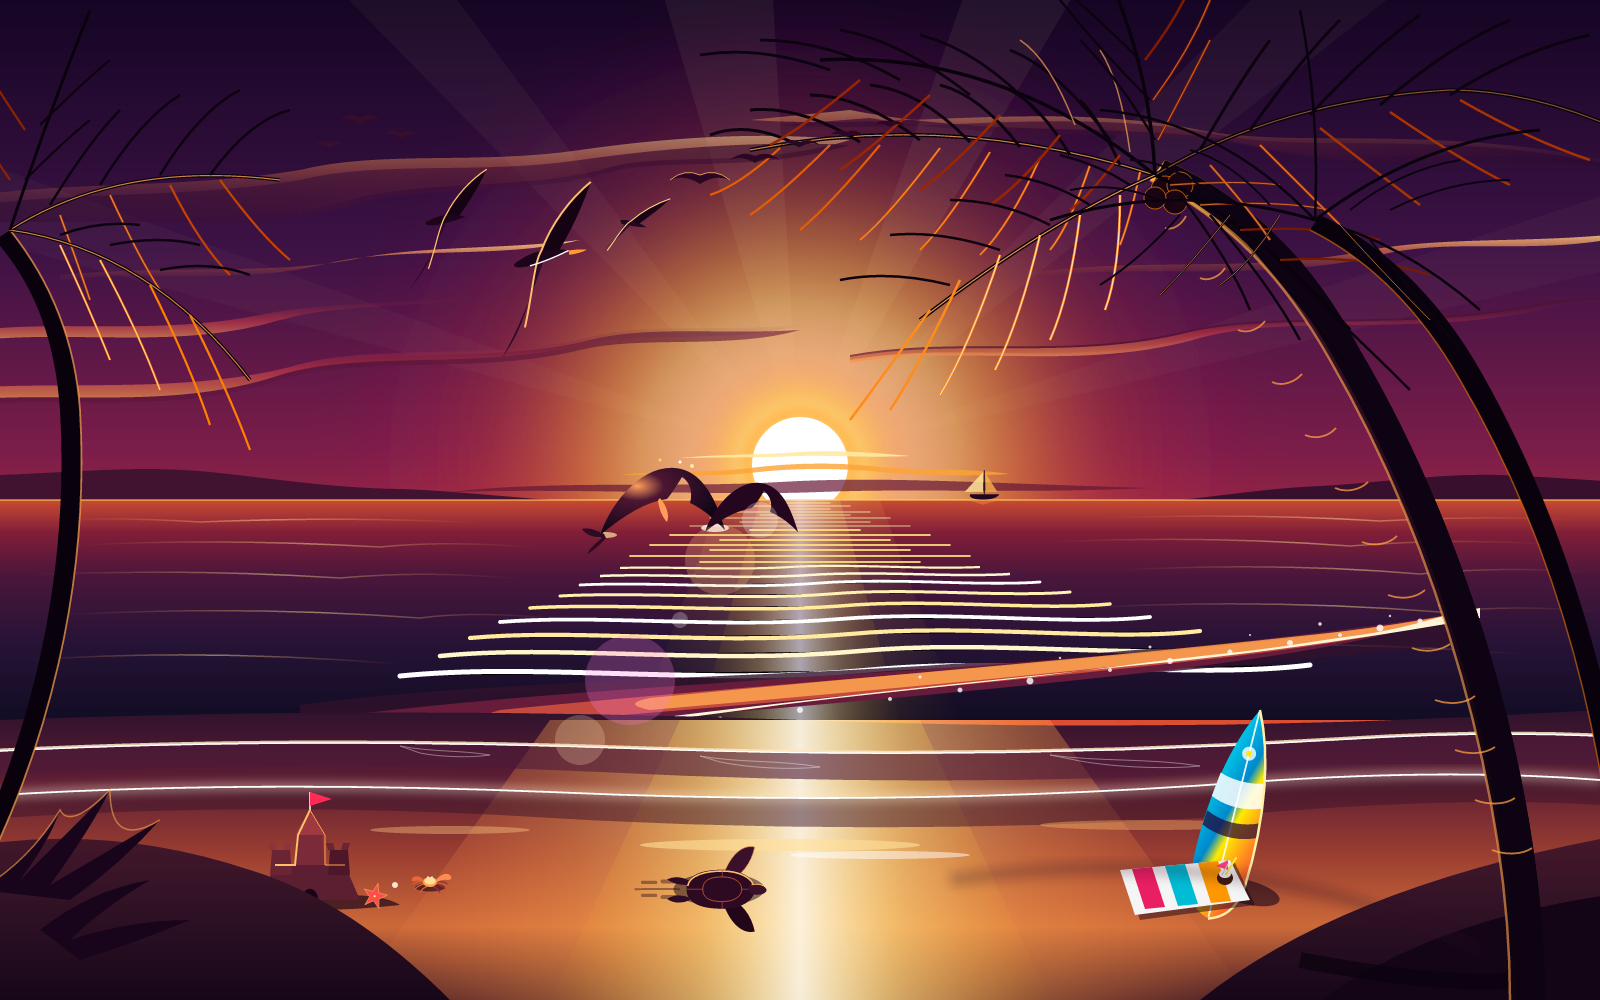
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
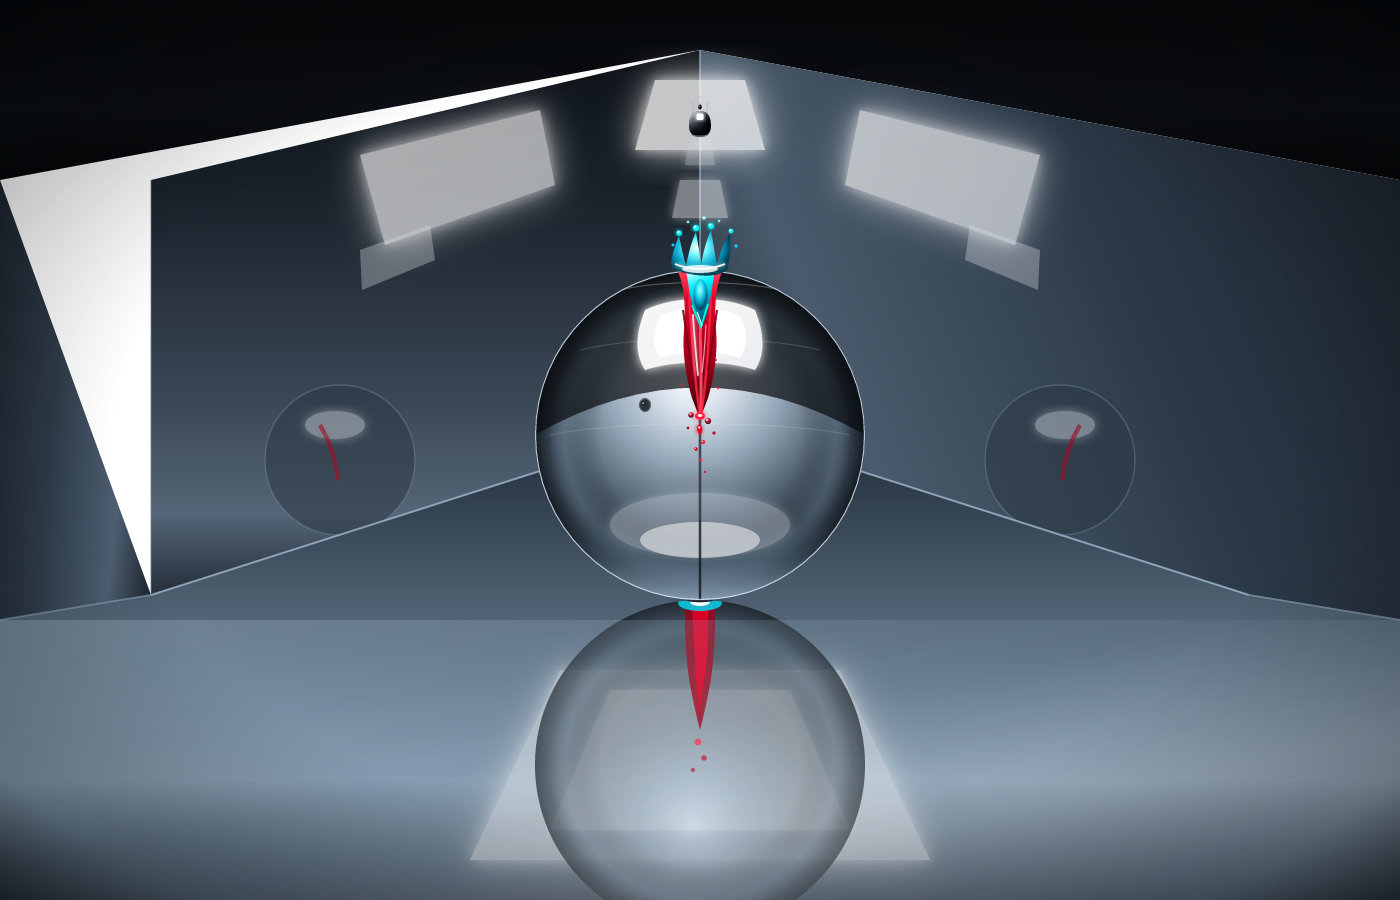
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
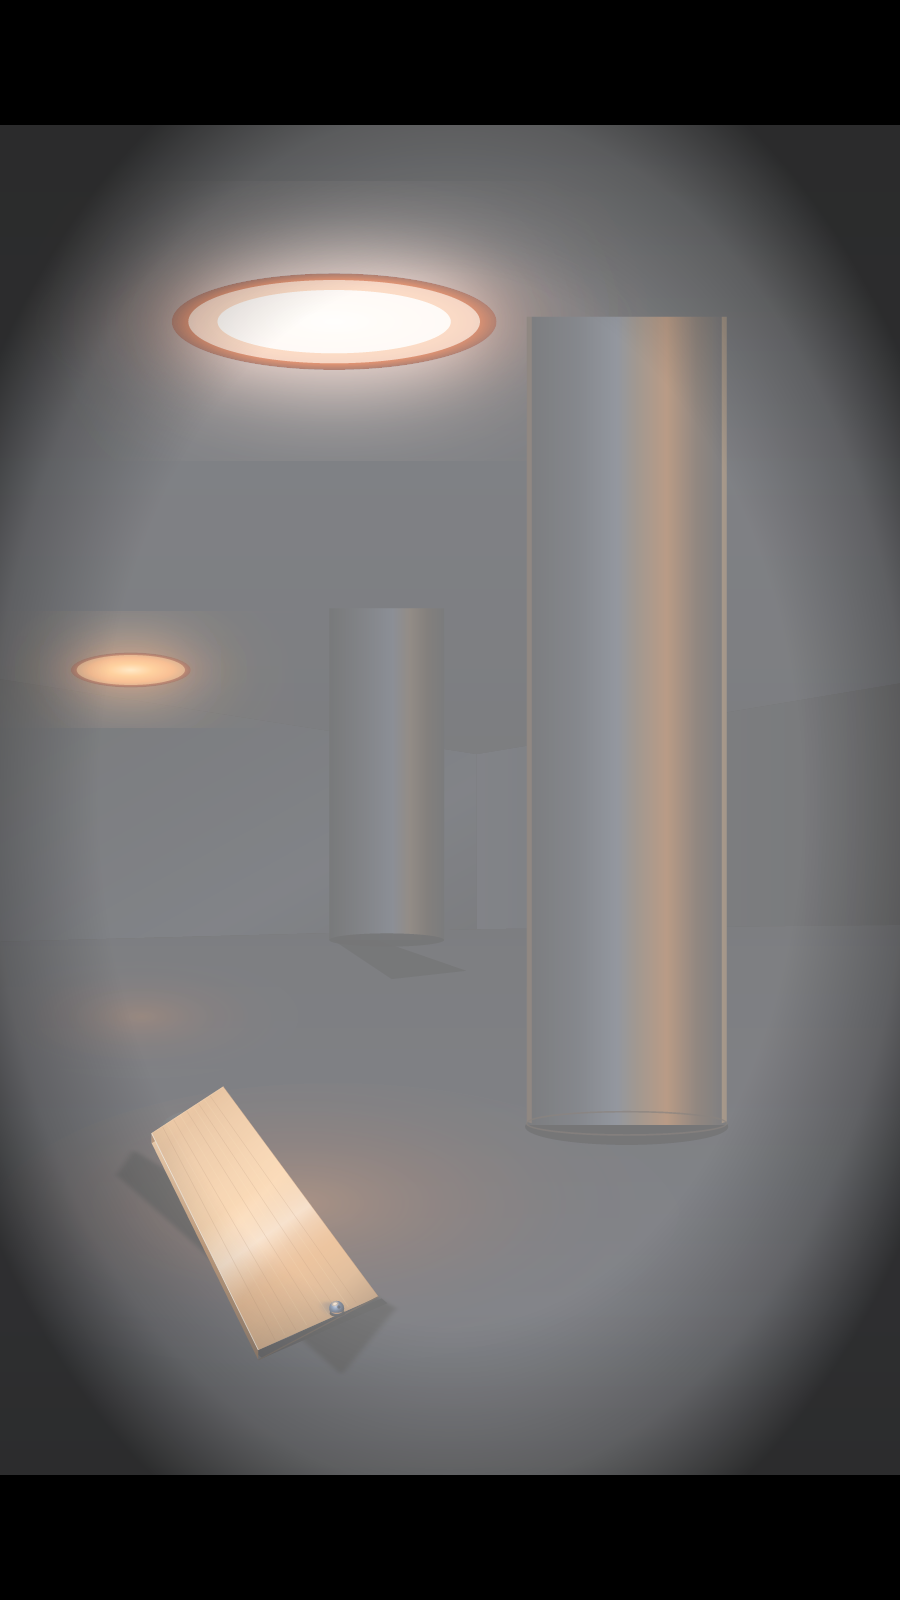
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
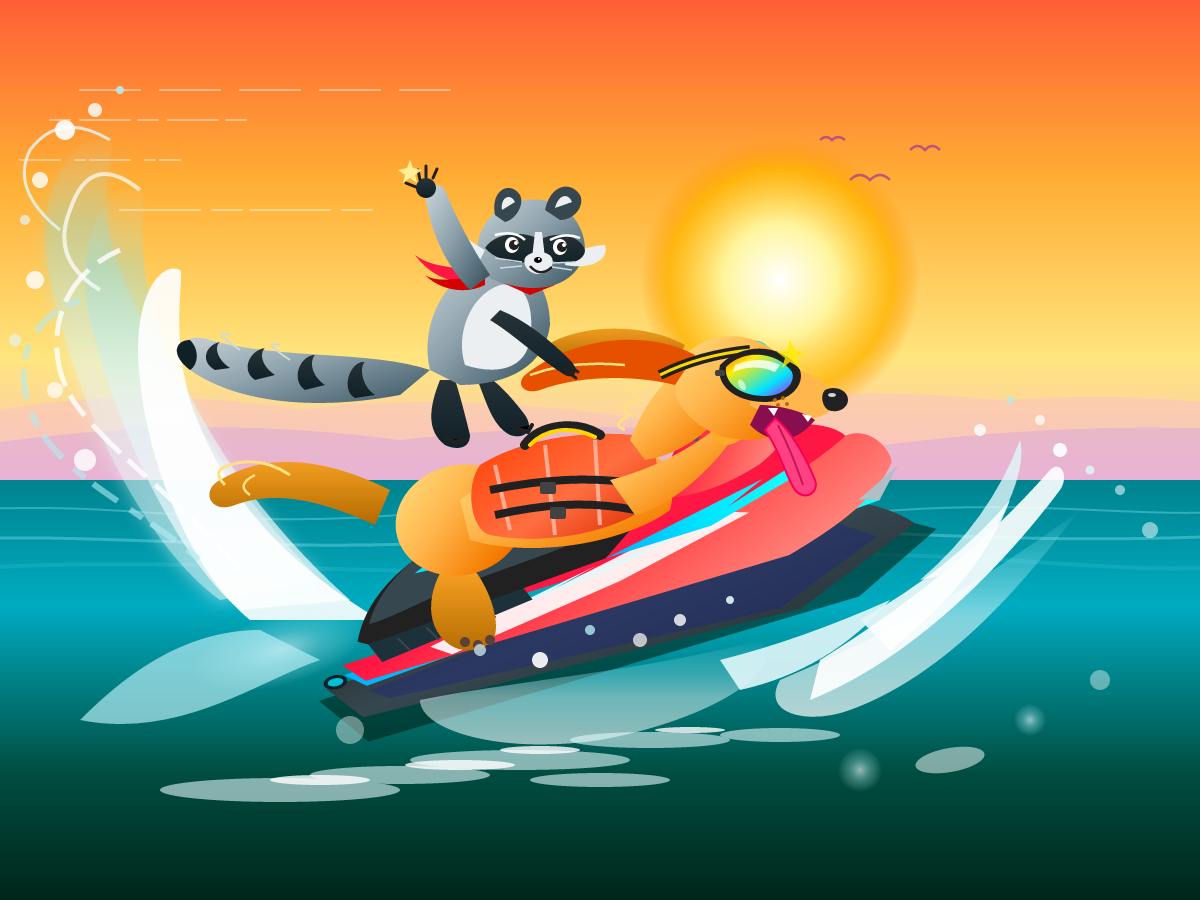
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
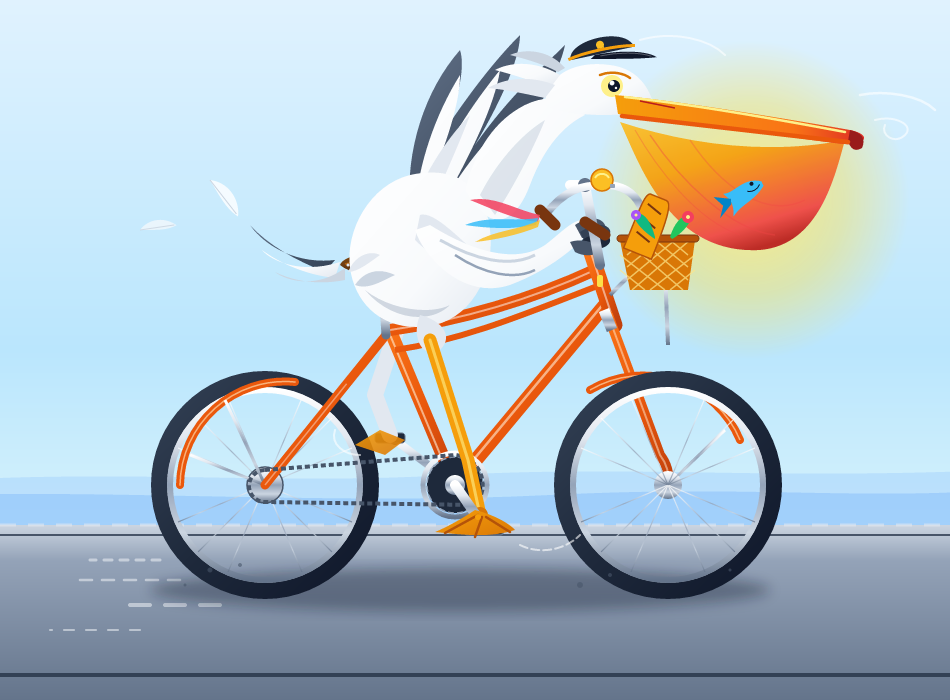
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDopenai/gpt-5.6-sol
StealthMarkOverall rank11/499 rated results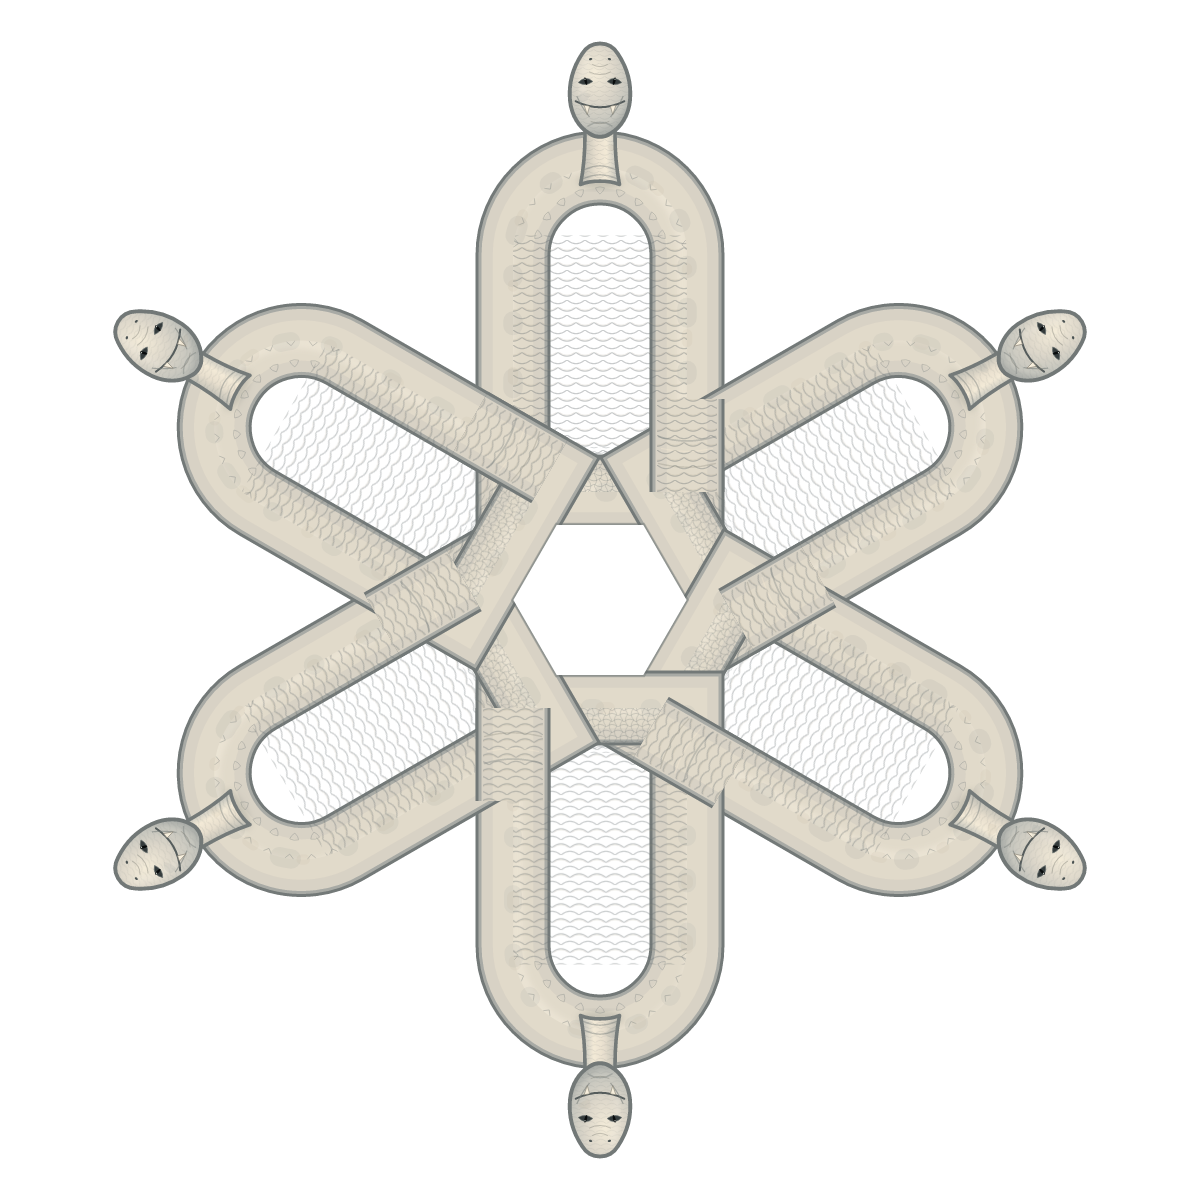
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
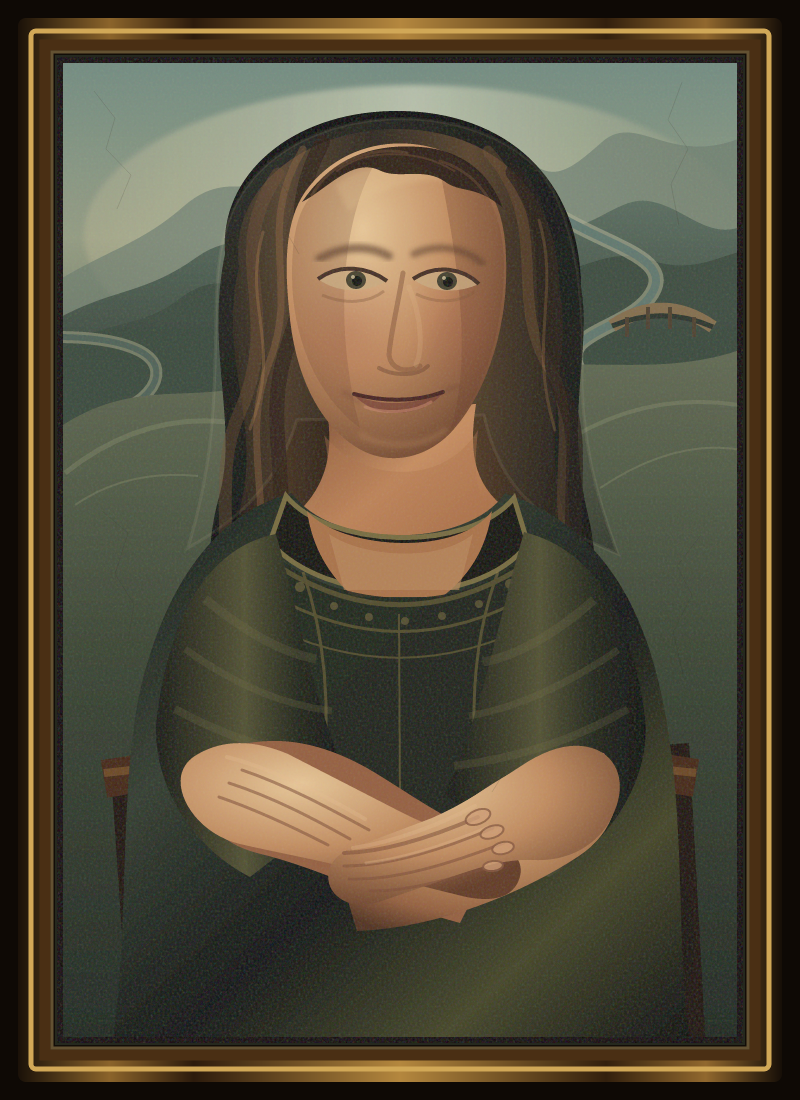
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
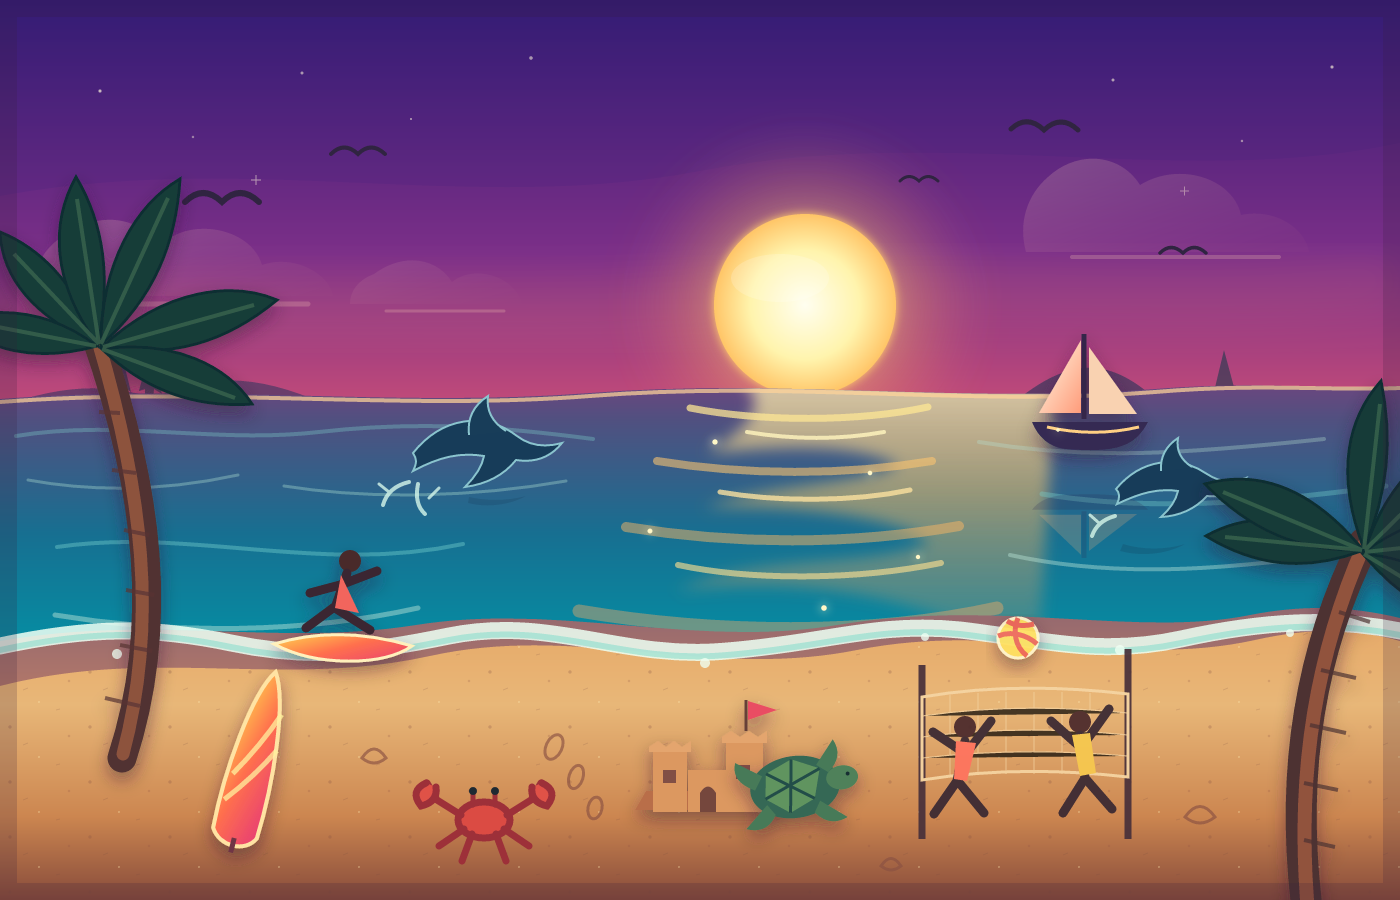
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
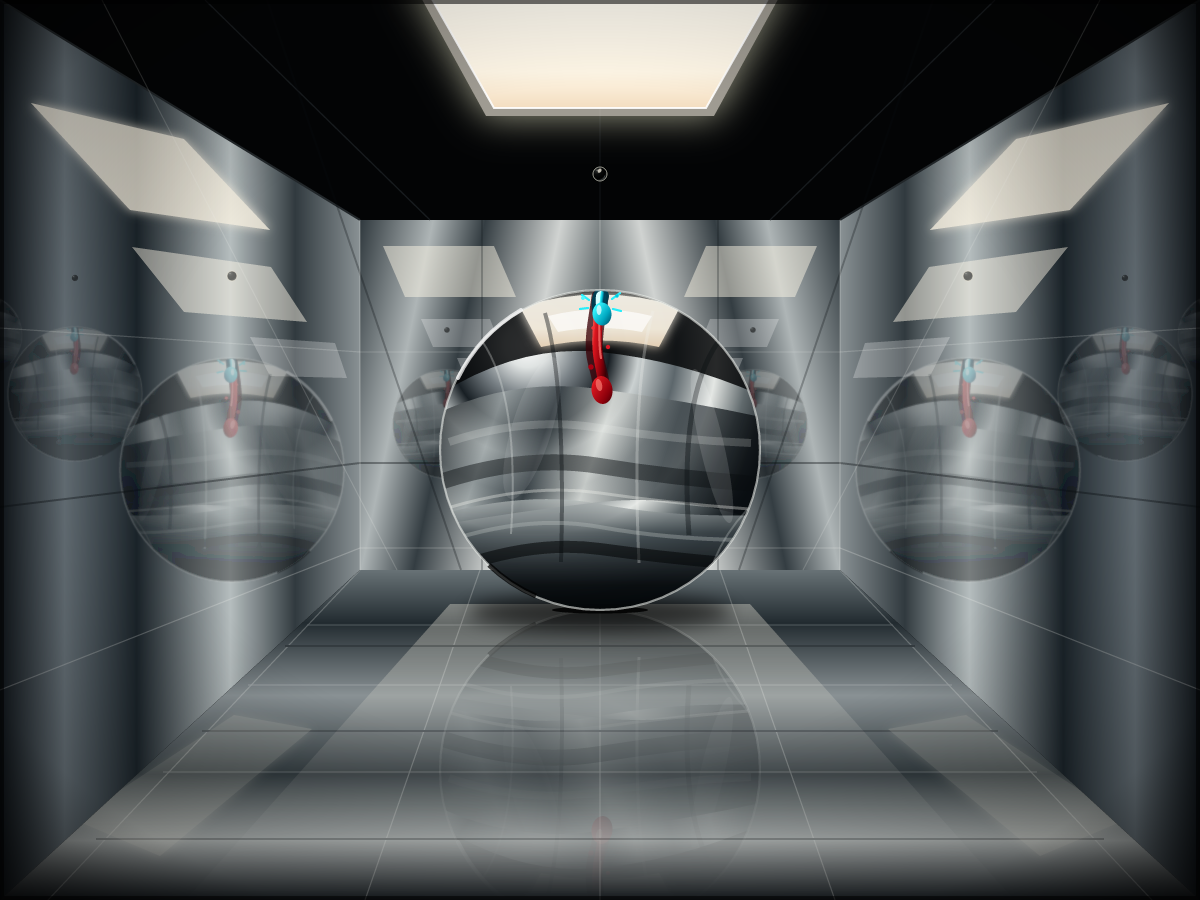
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
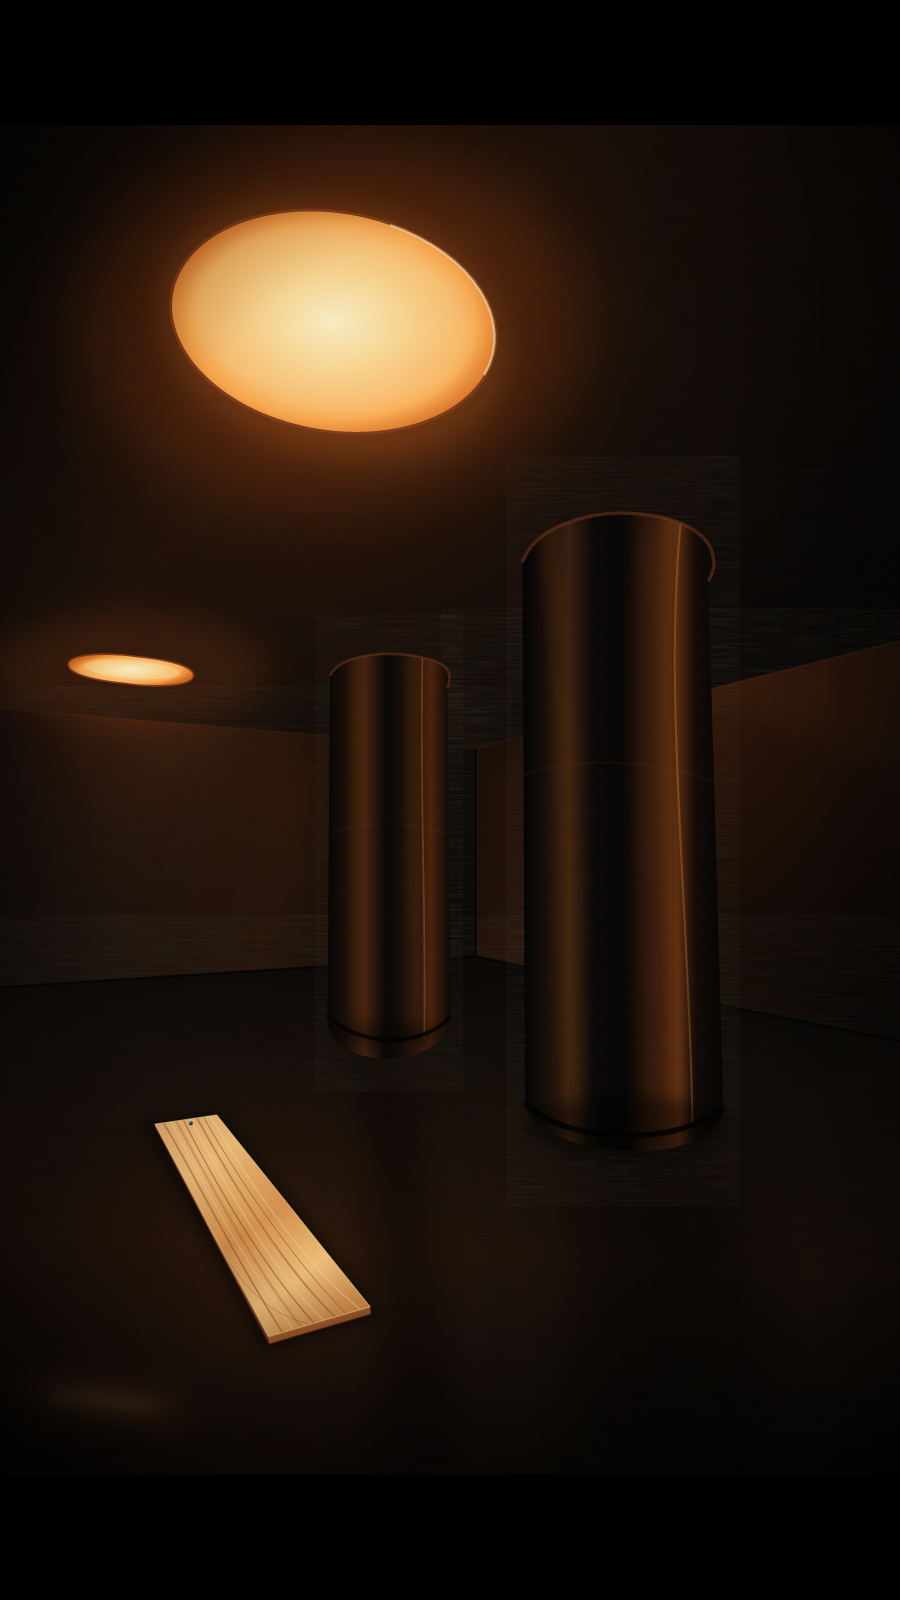
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
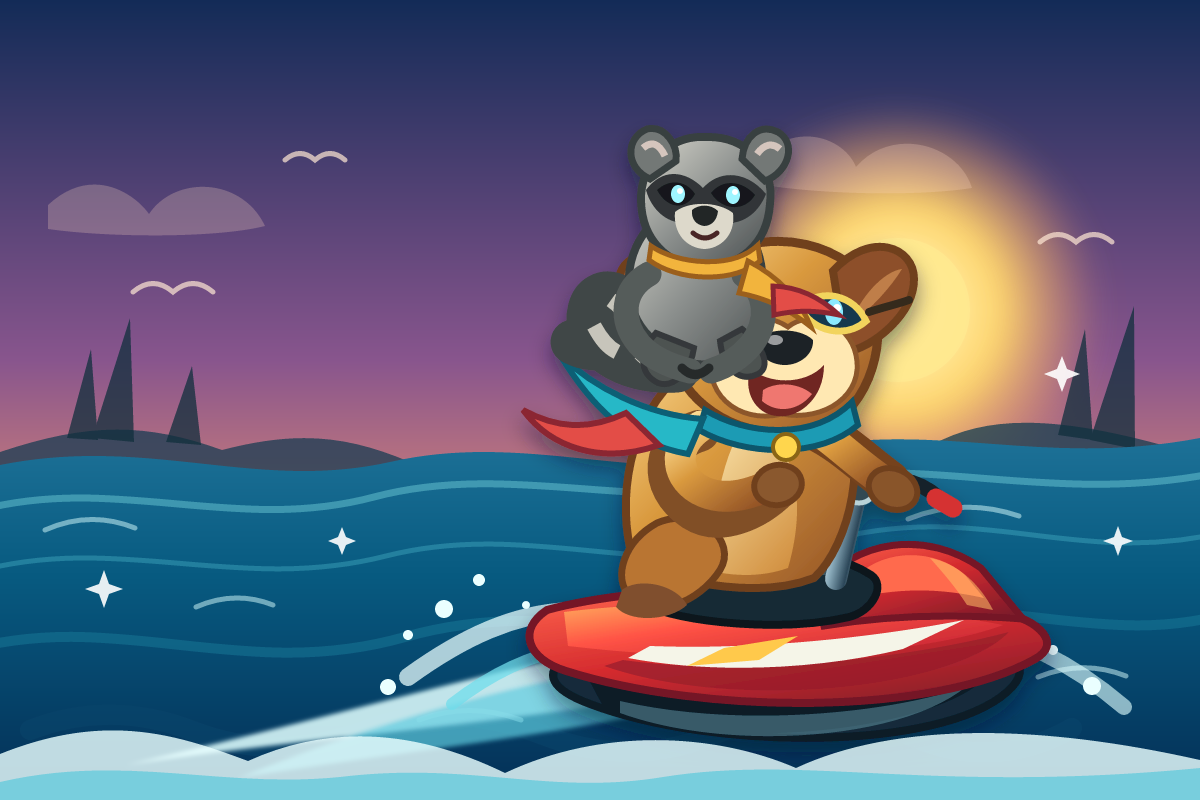
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
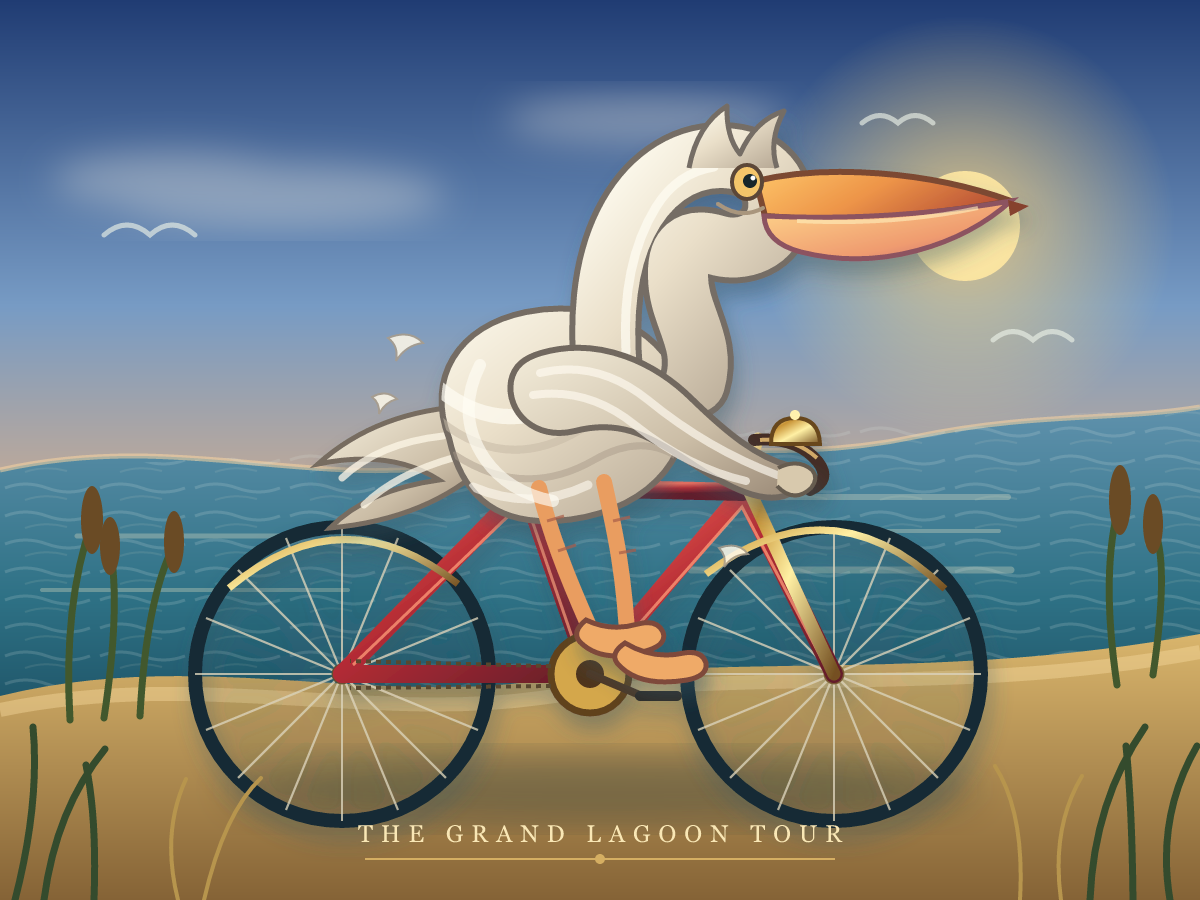
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDopenai/gpt-5.6-terra
StealthMarkOverall rank22/499 rated results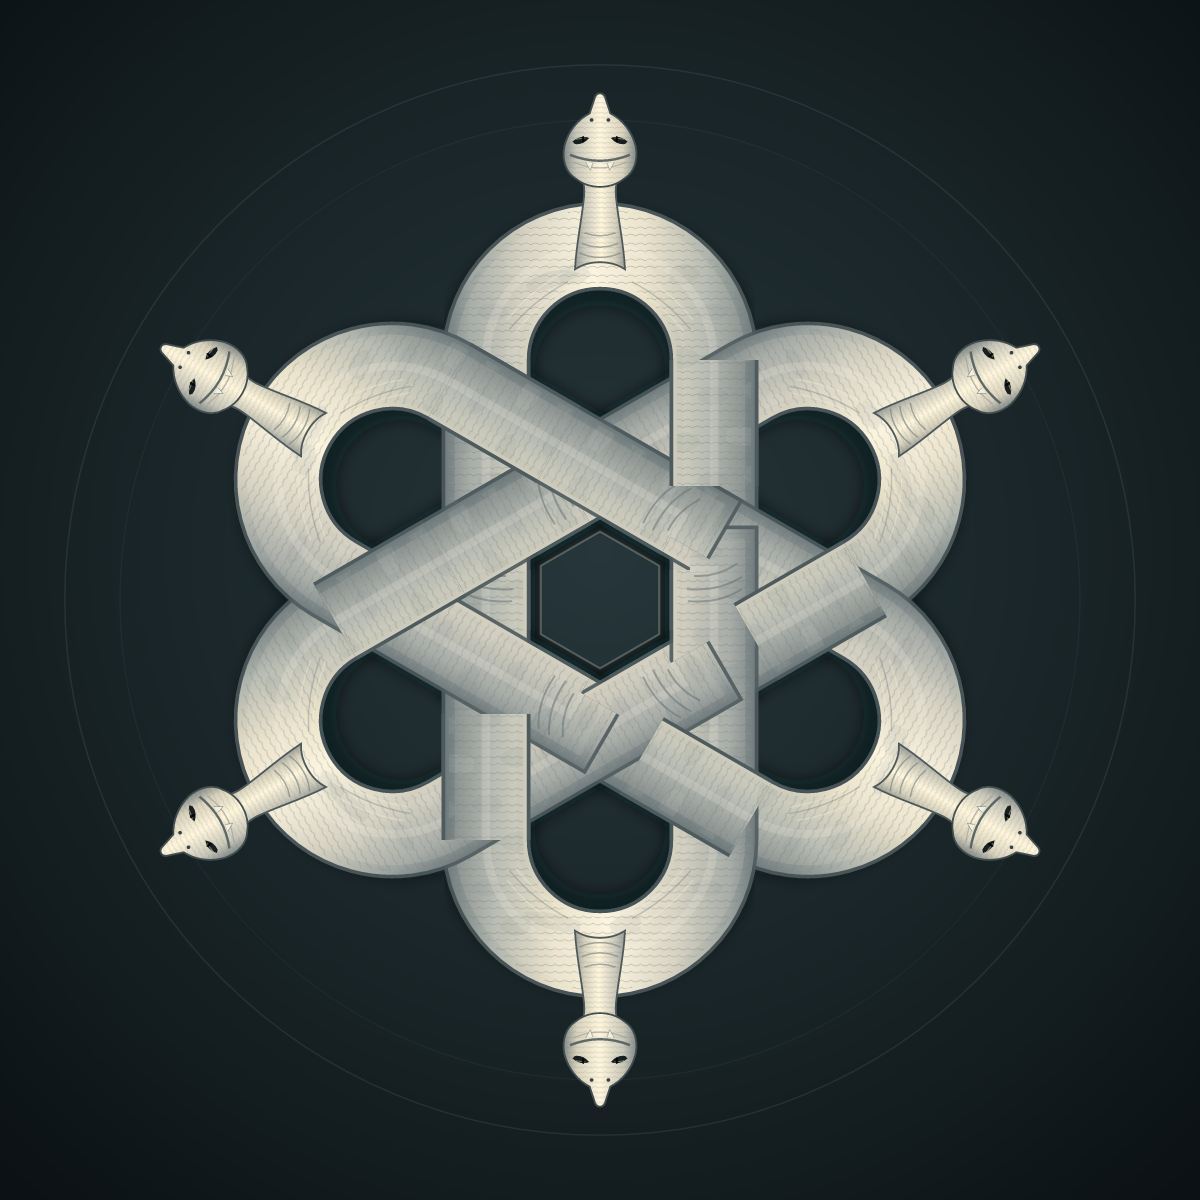
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
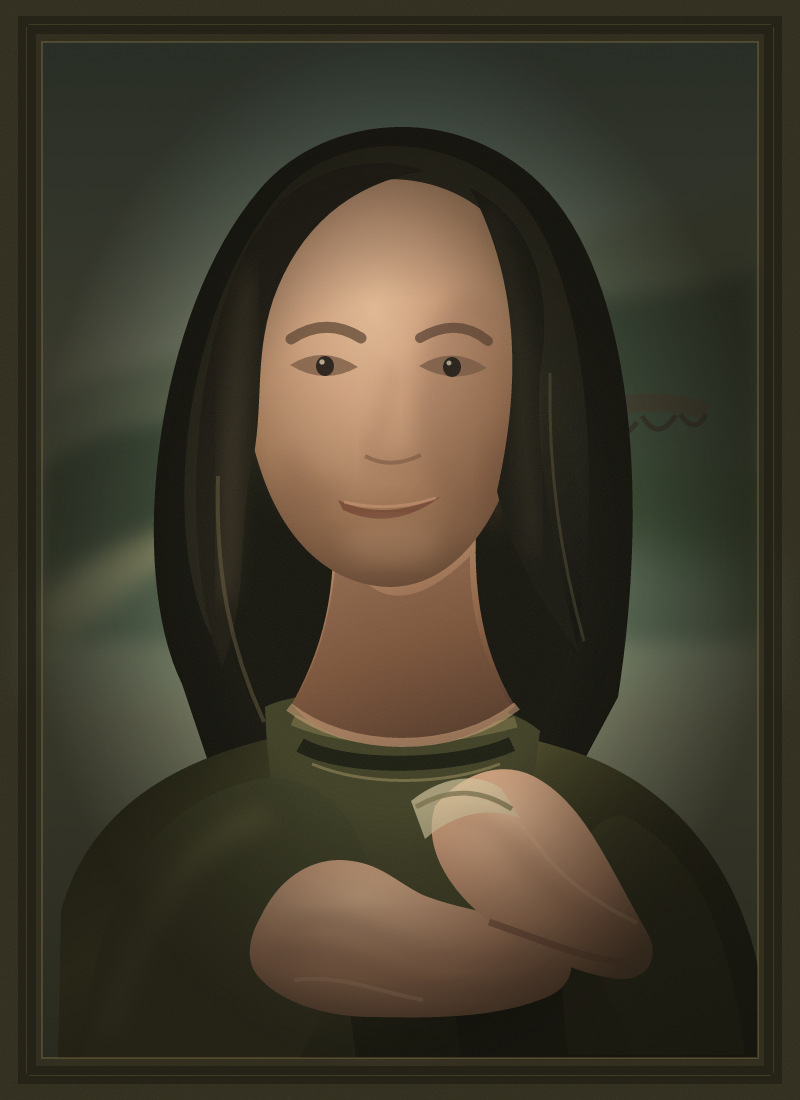
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
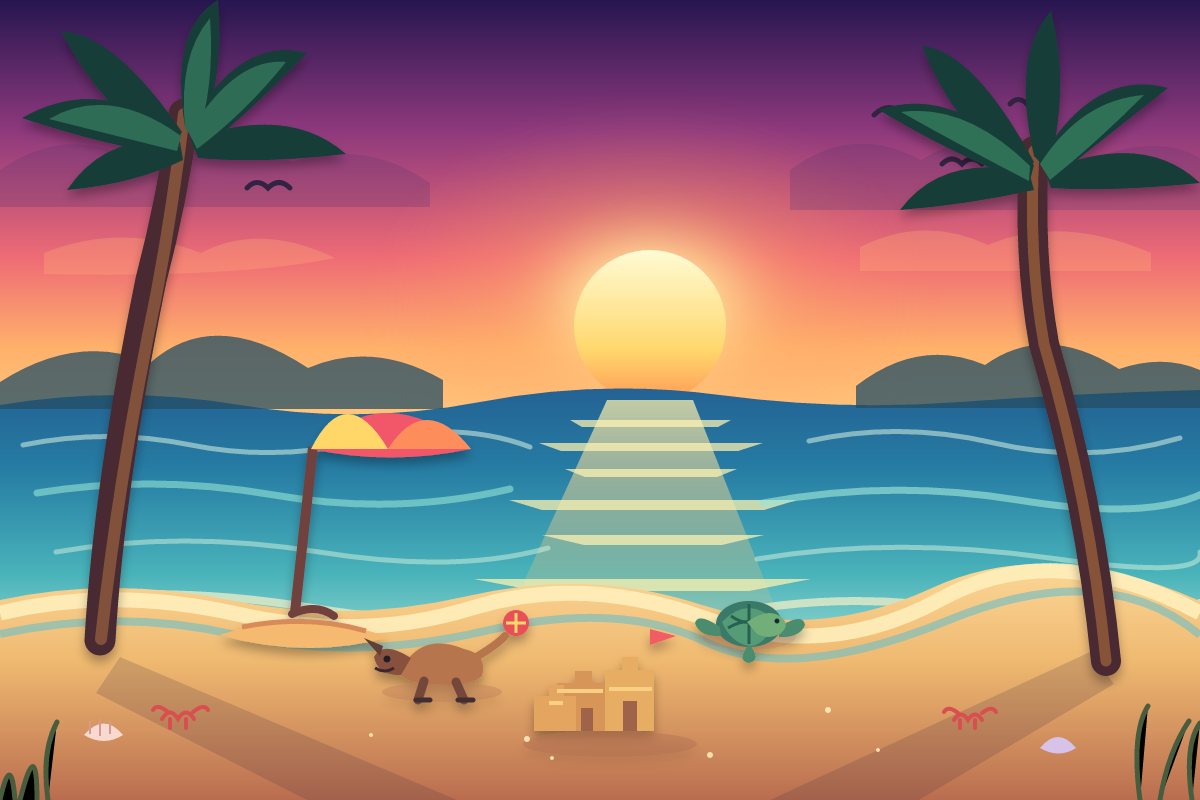
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
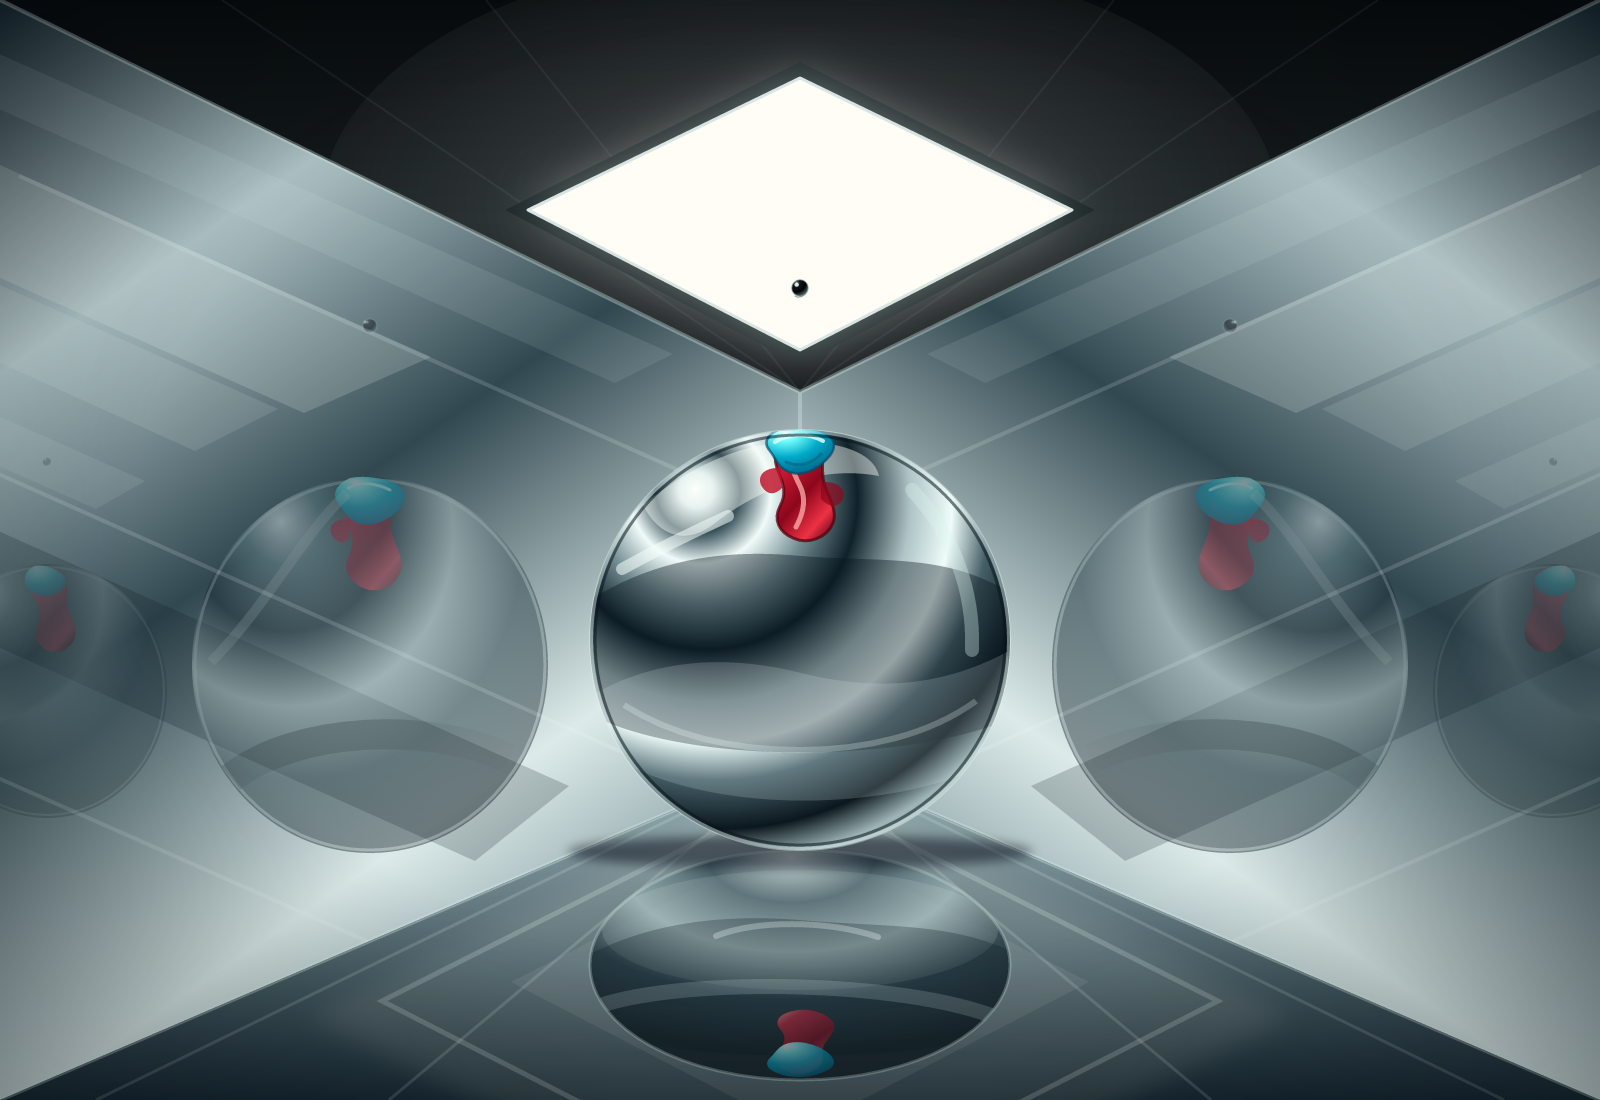
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
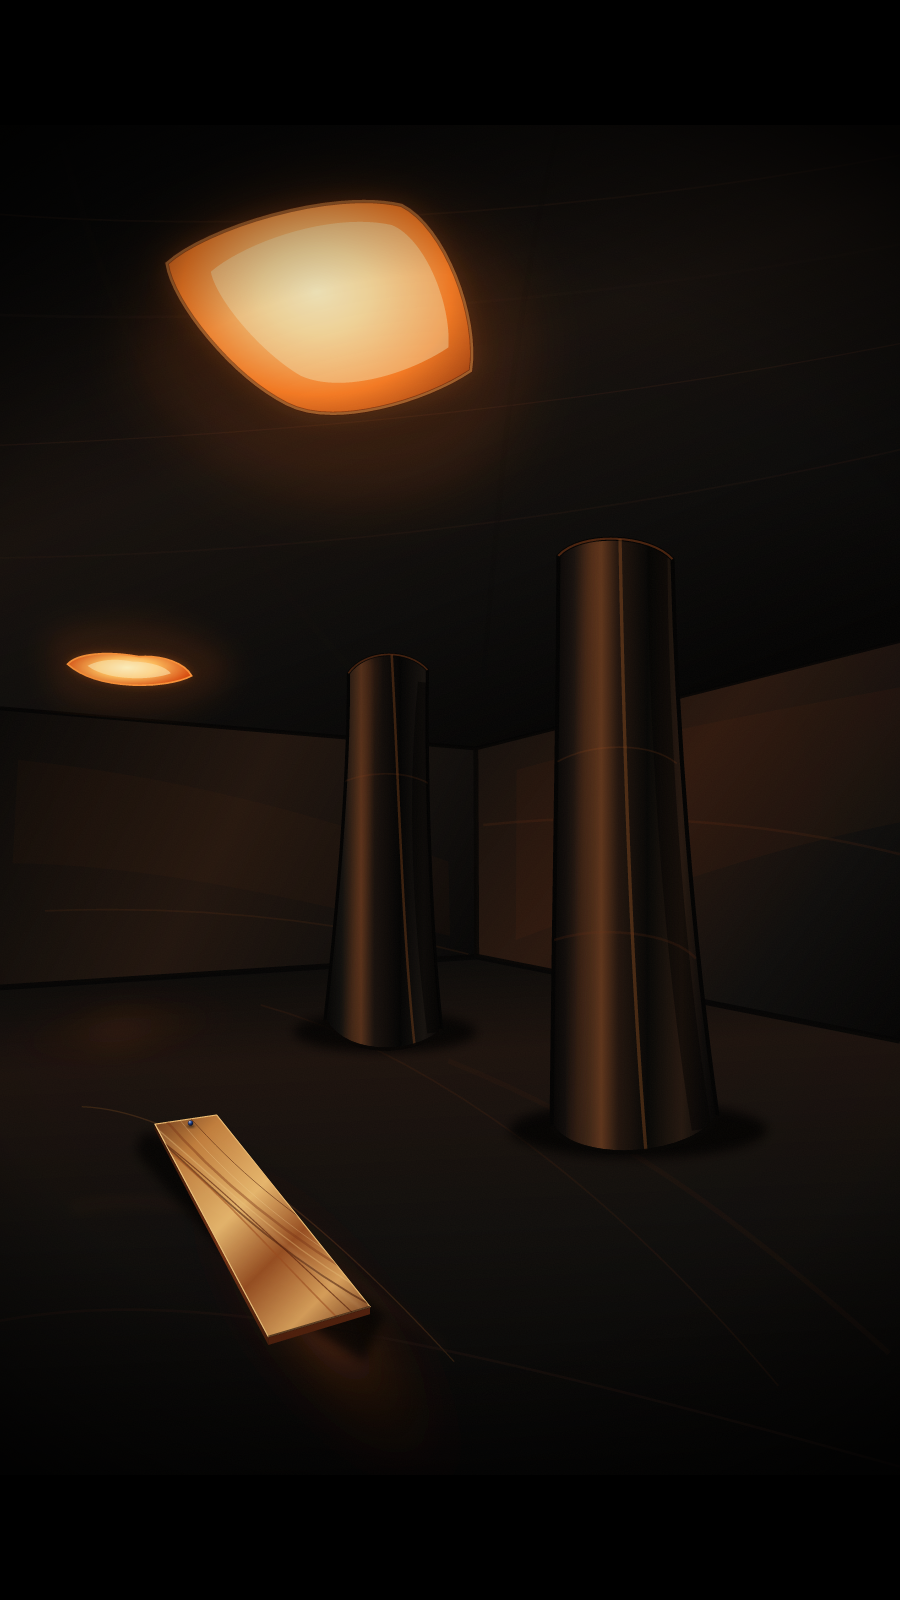
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
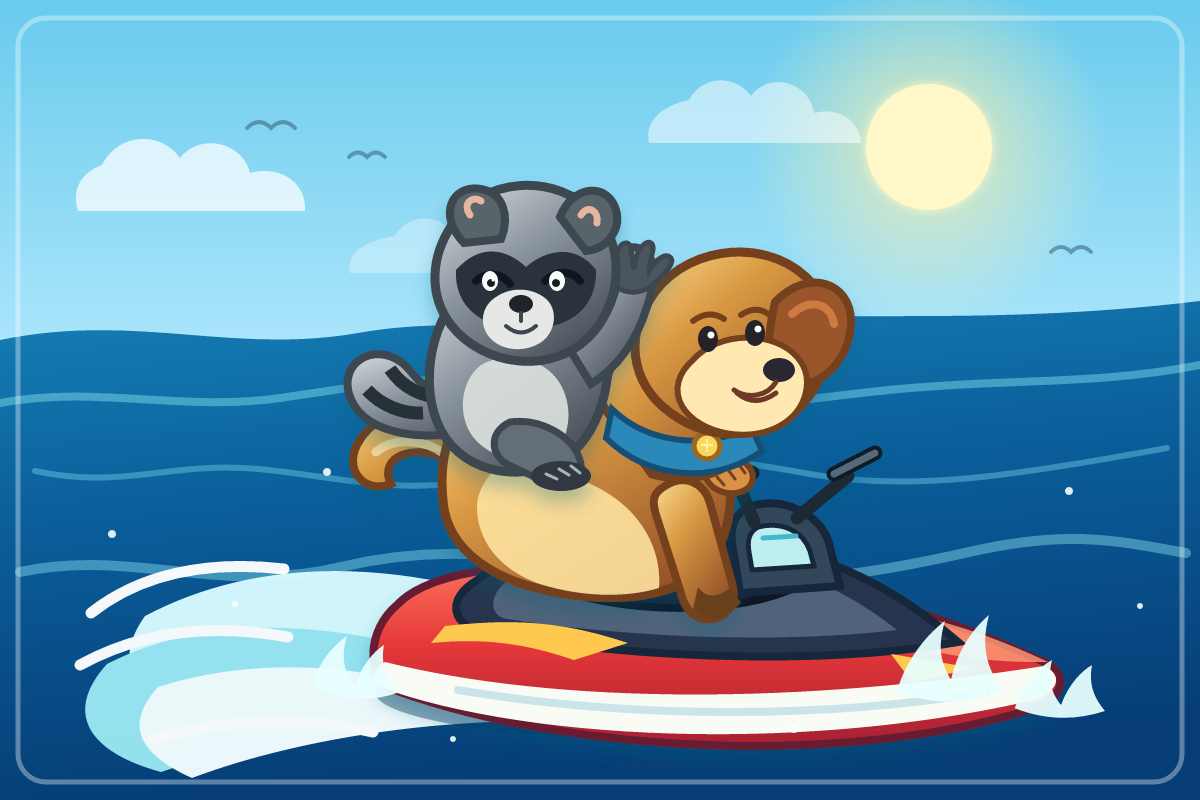
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
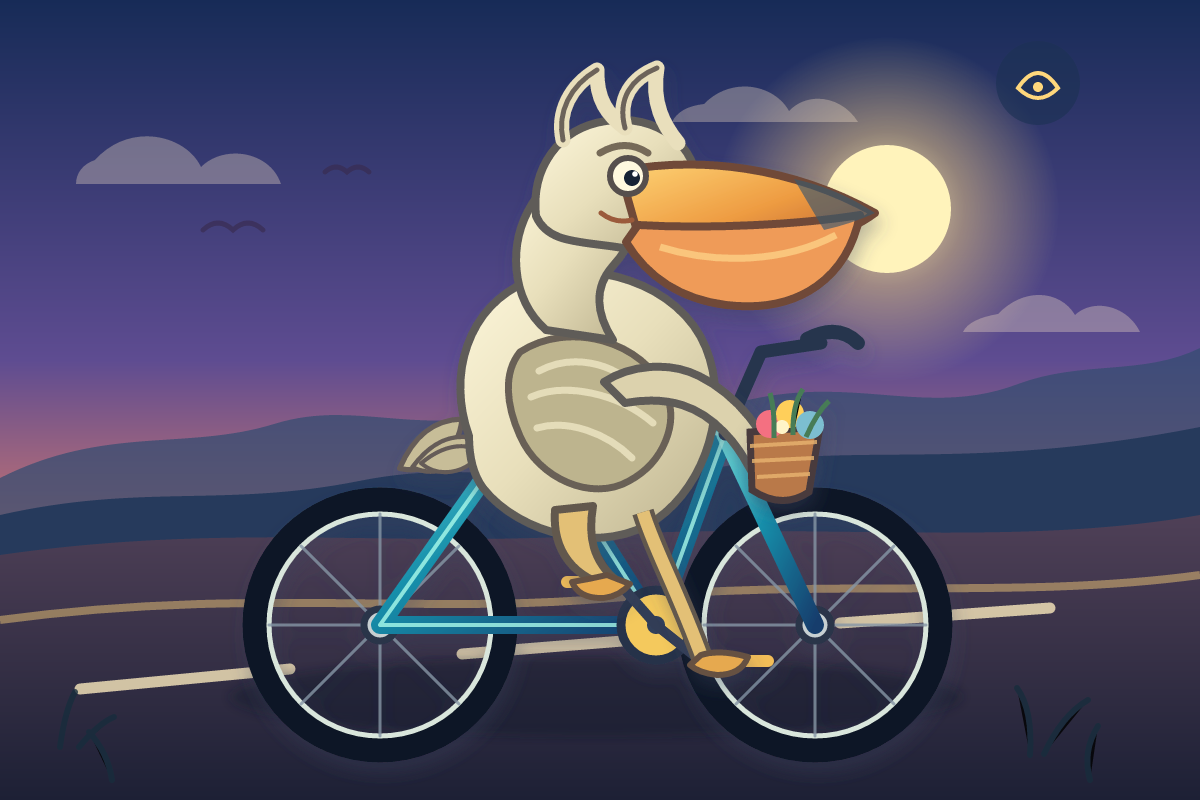
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDopenai/gpt-6-luna
StealthMarkOverall rank32/499 rated results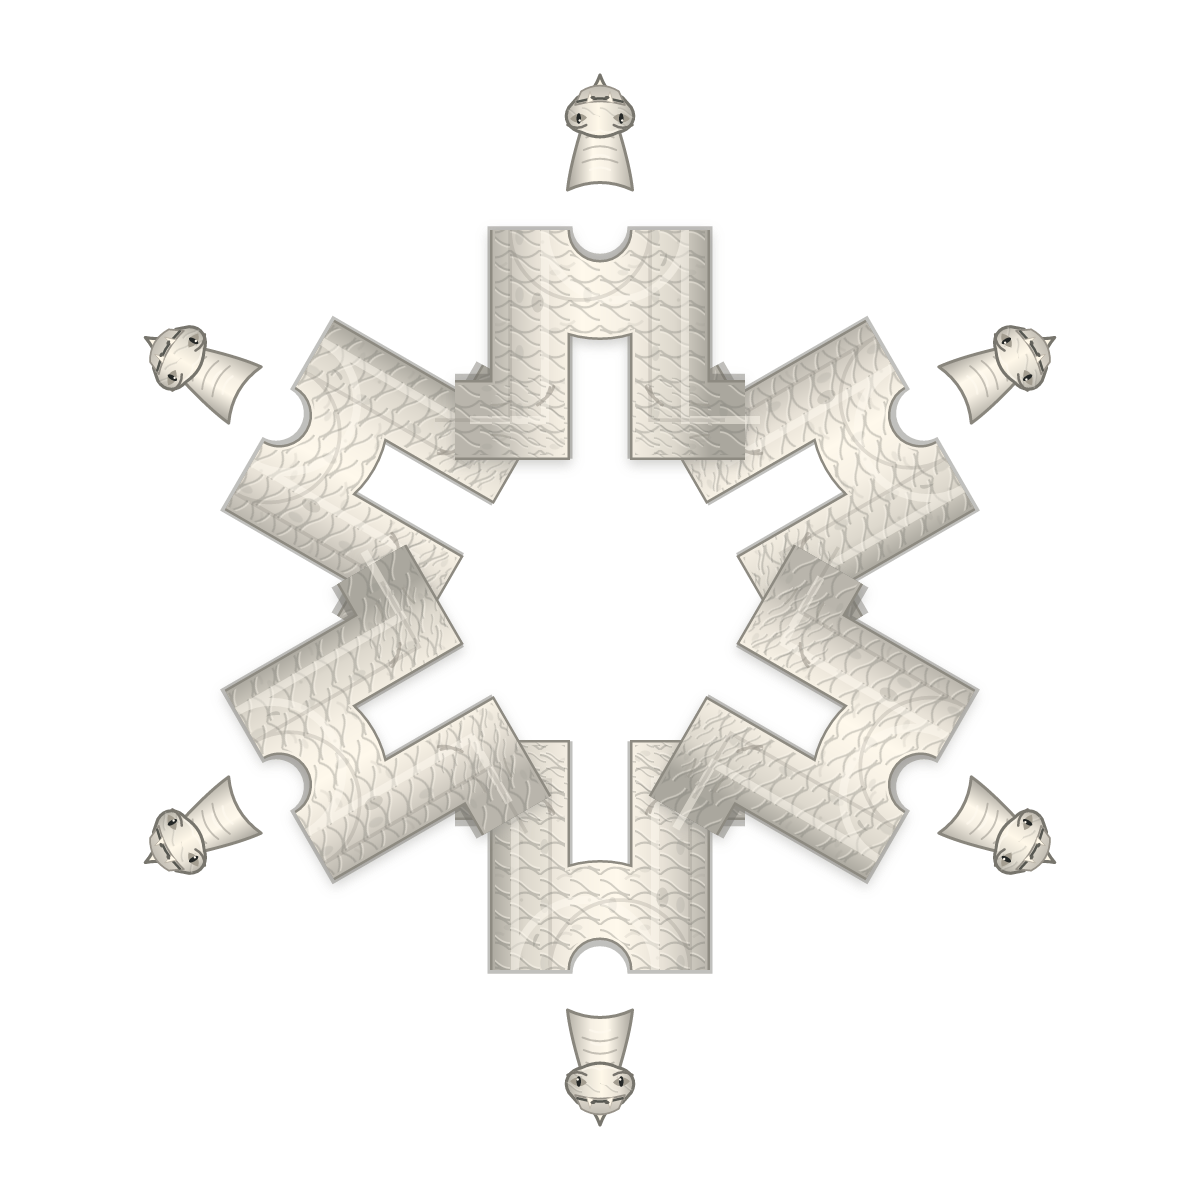
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
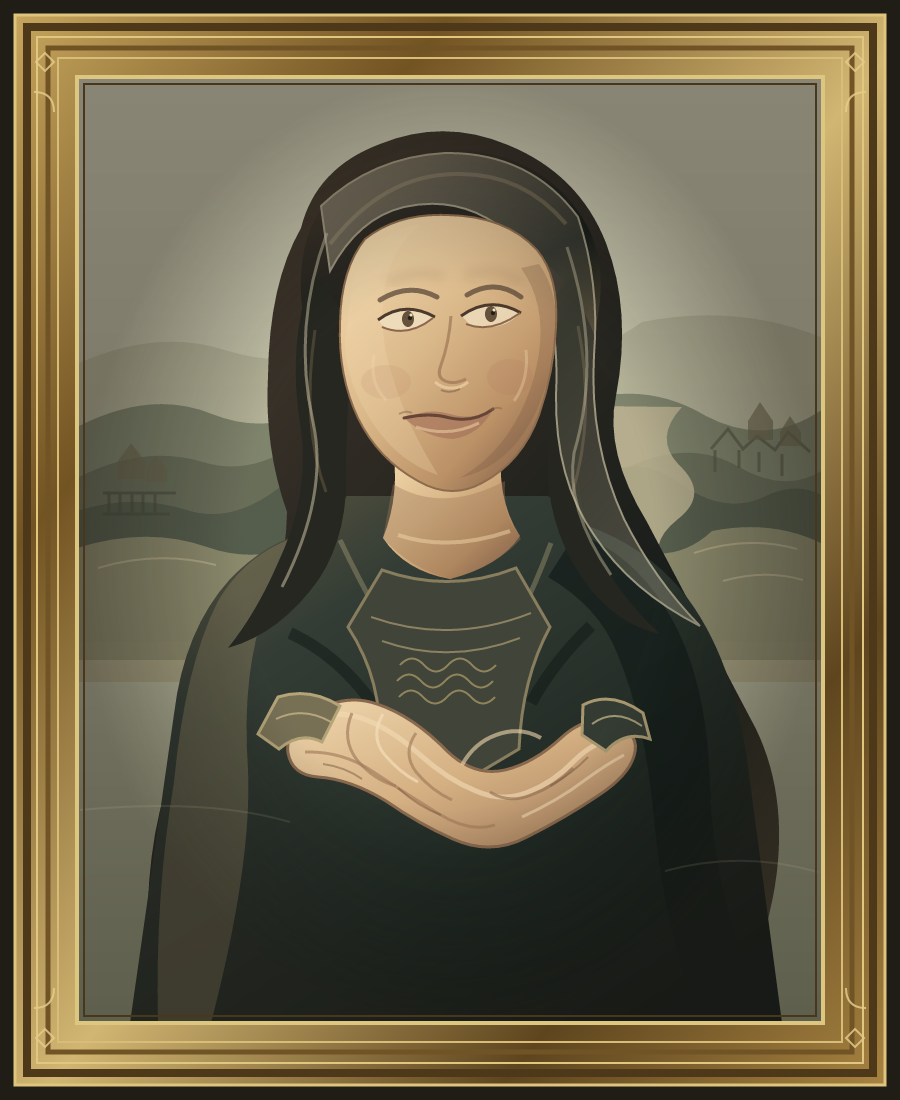
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
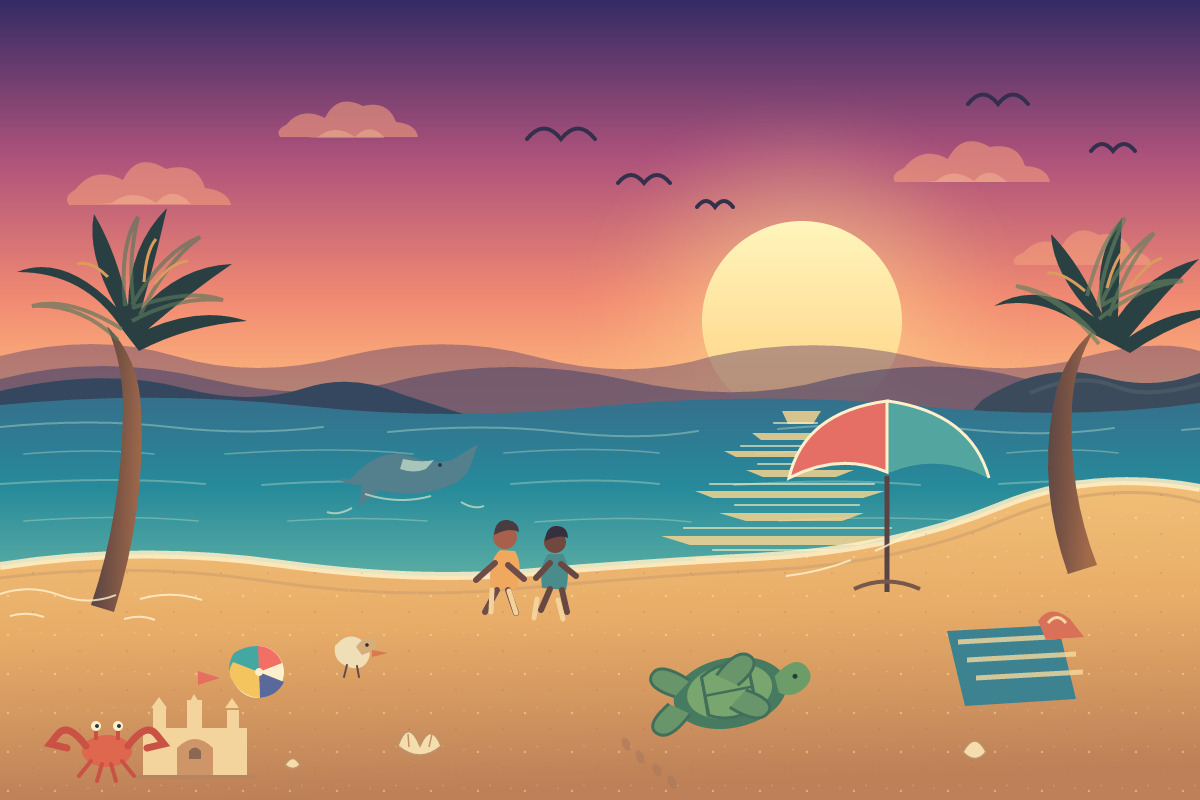
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
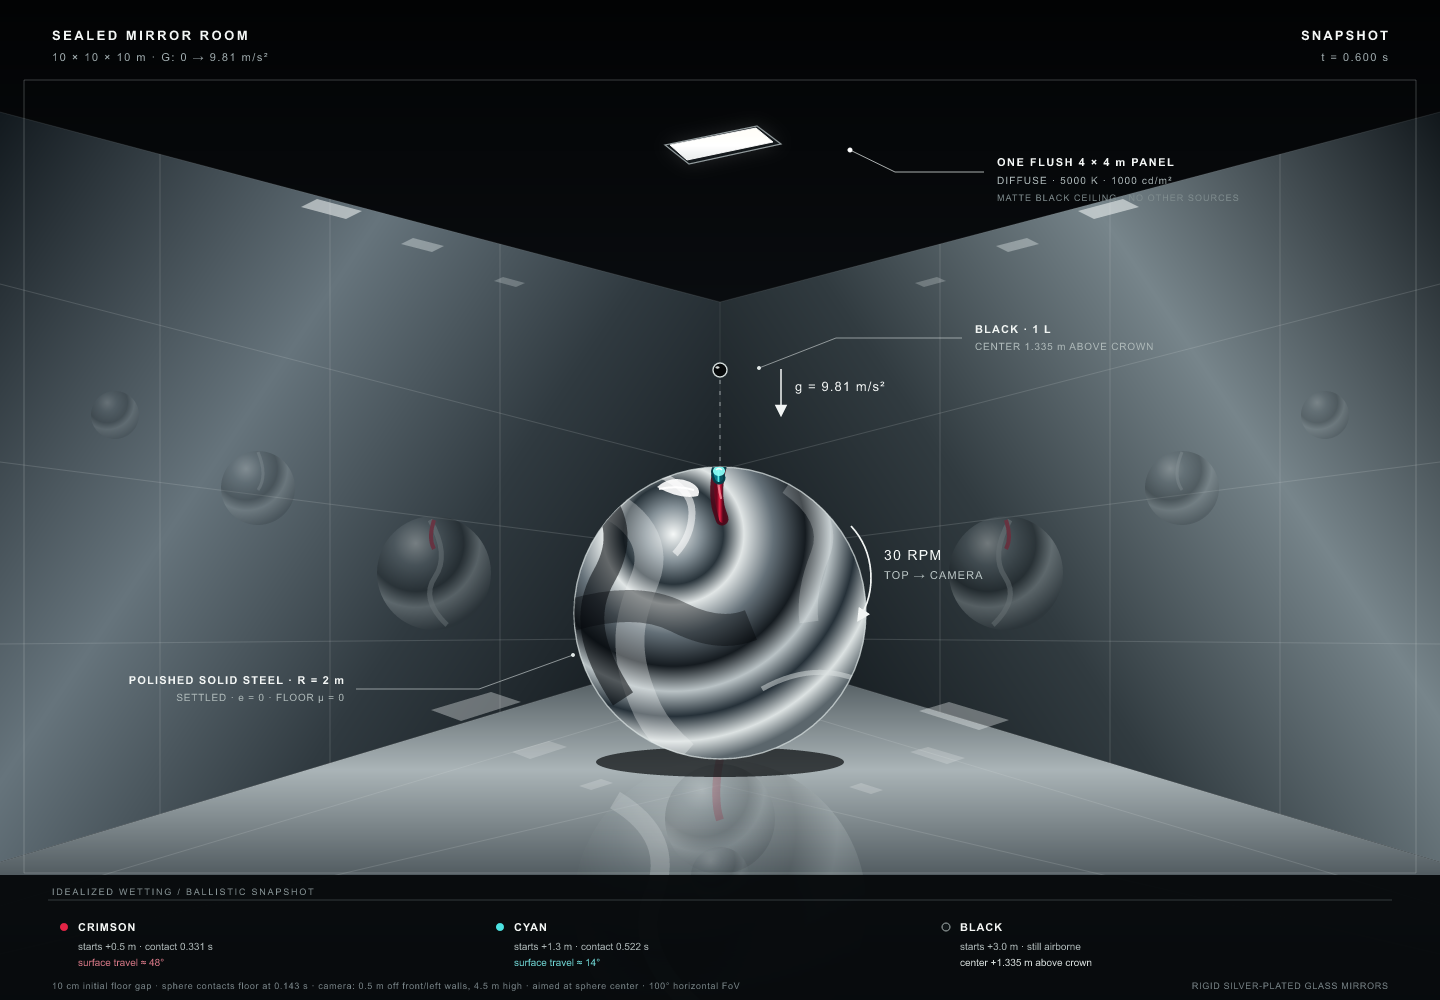
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
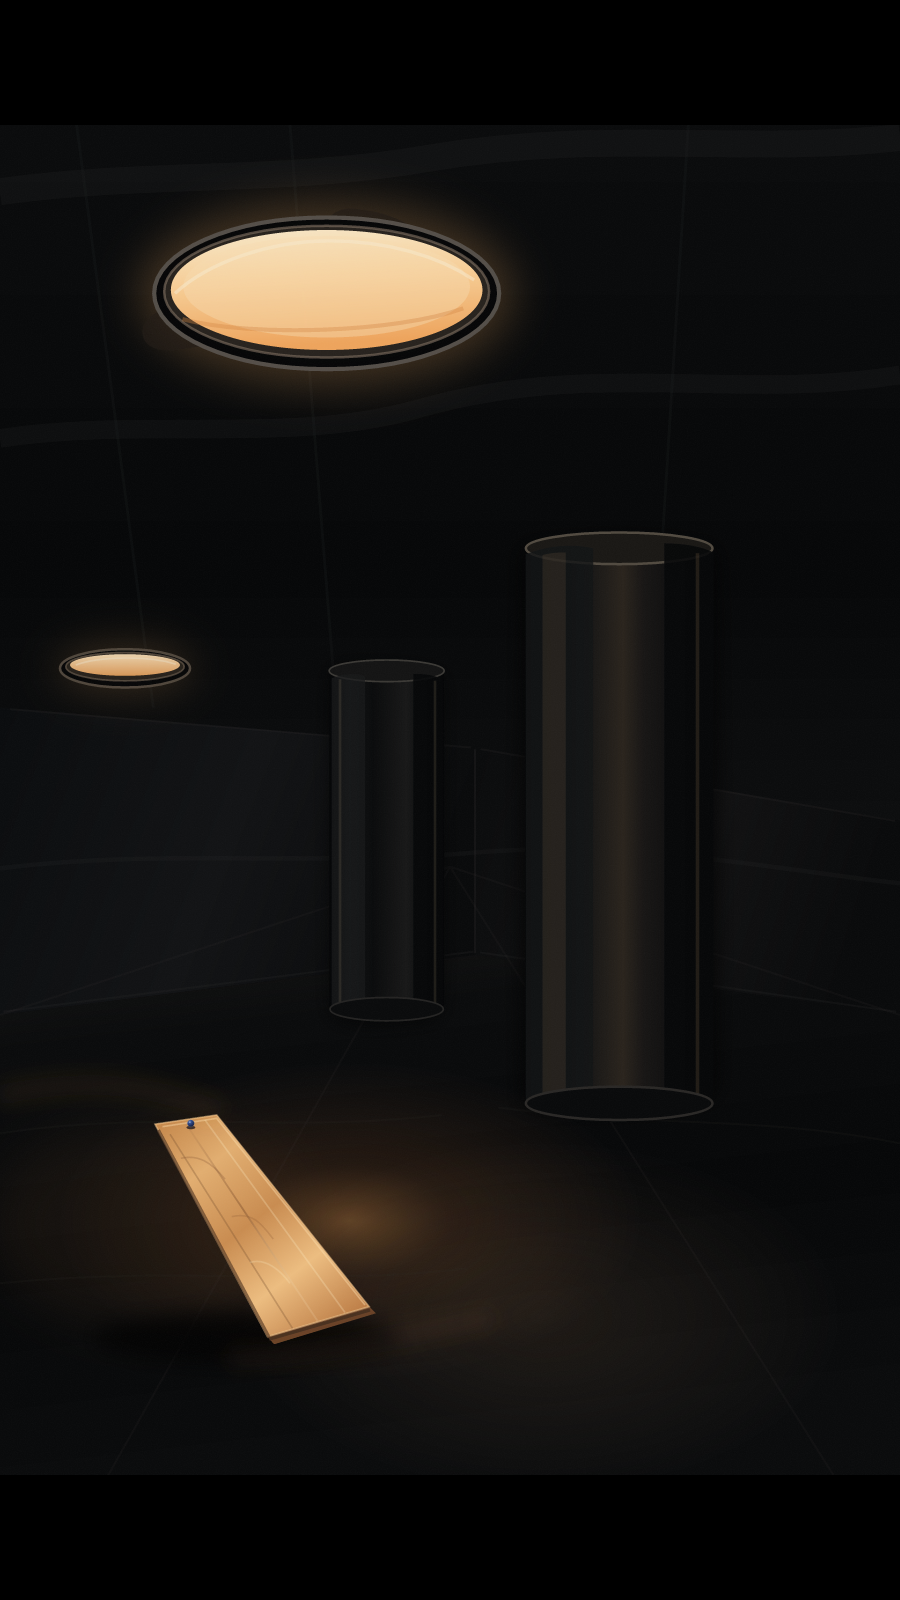
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
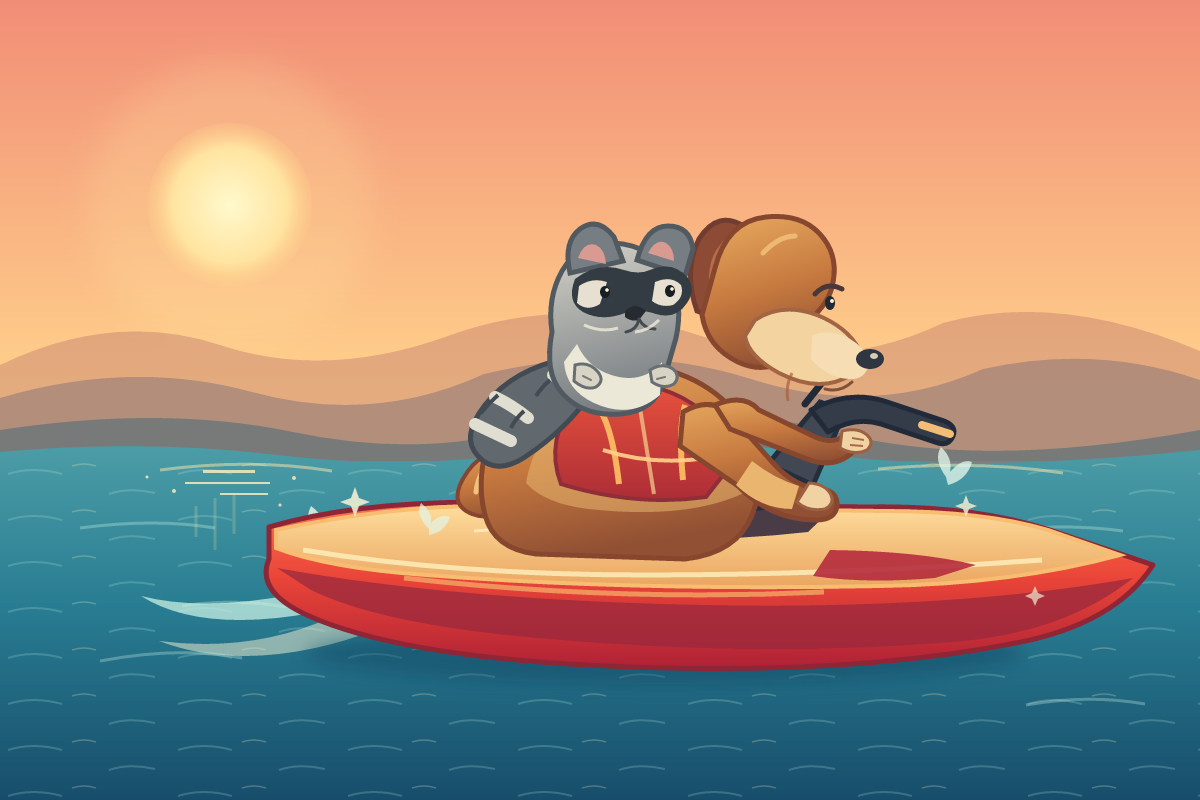
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
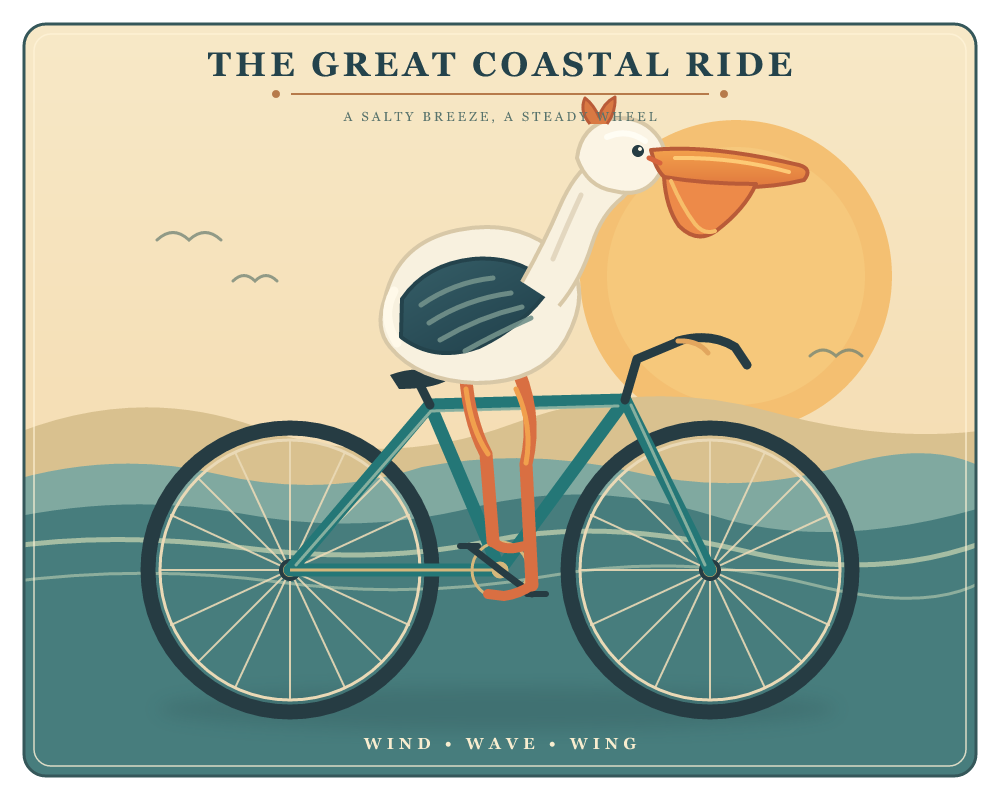
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDopenai/gpt-6-sol
StealthMarkOverall rank13/499 rated results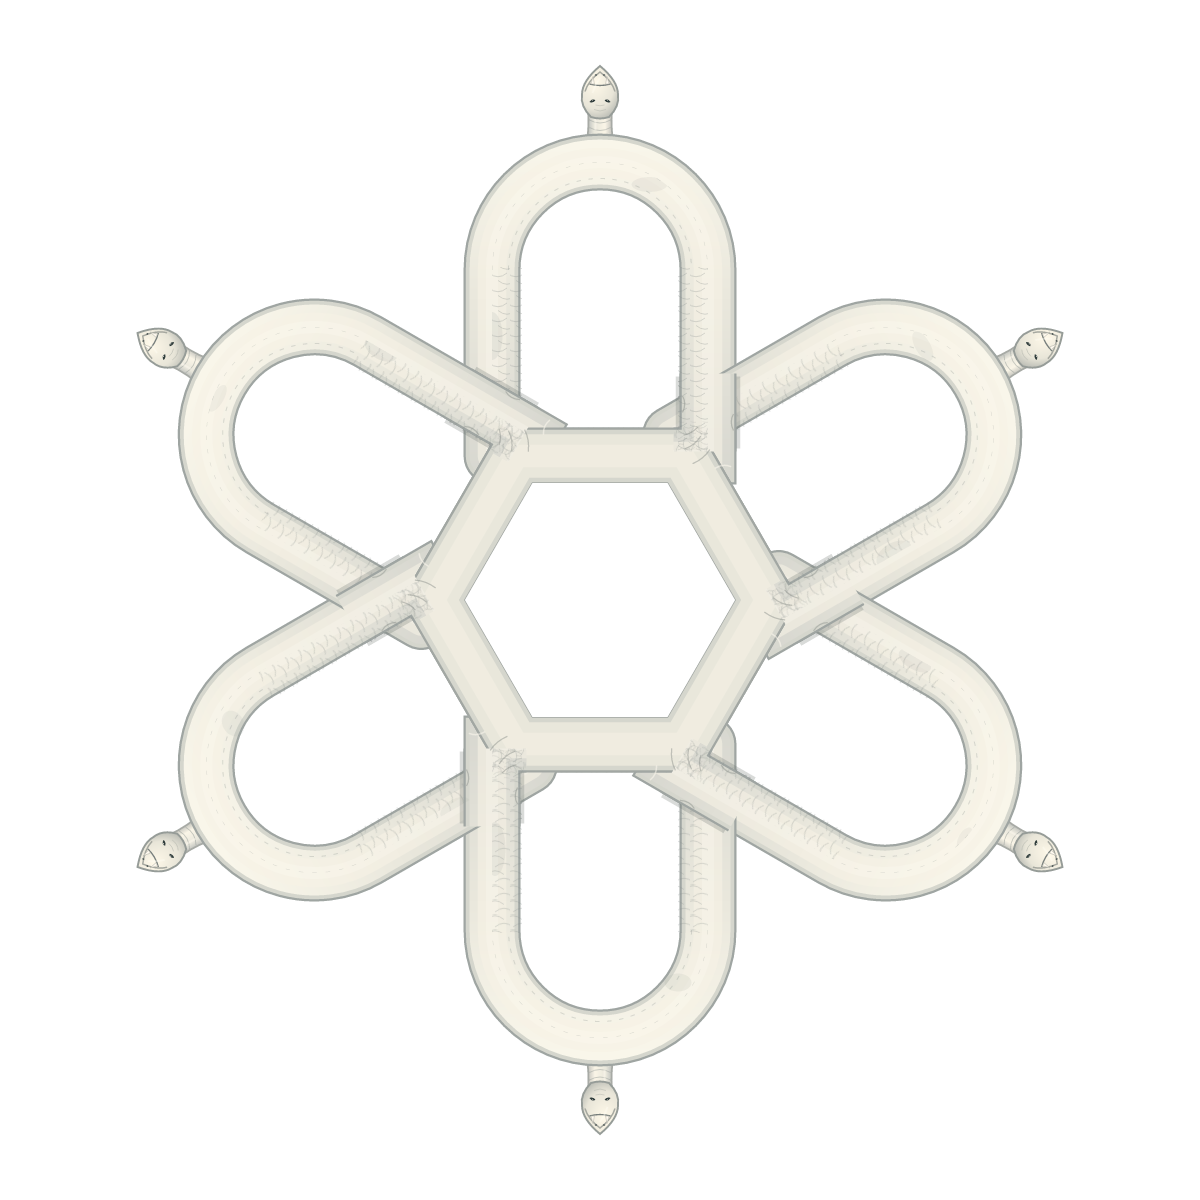
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
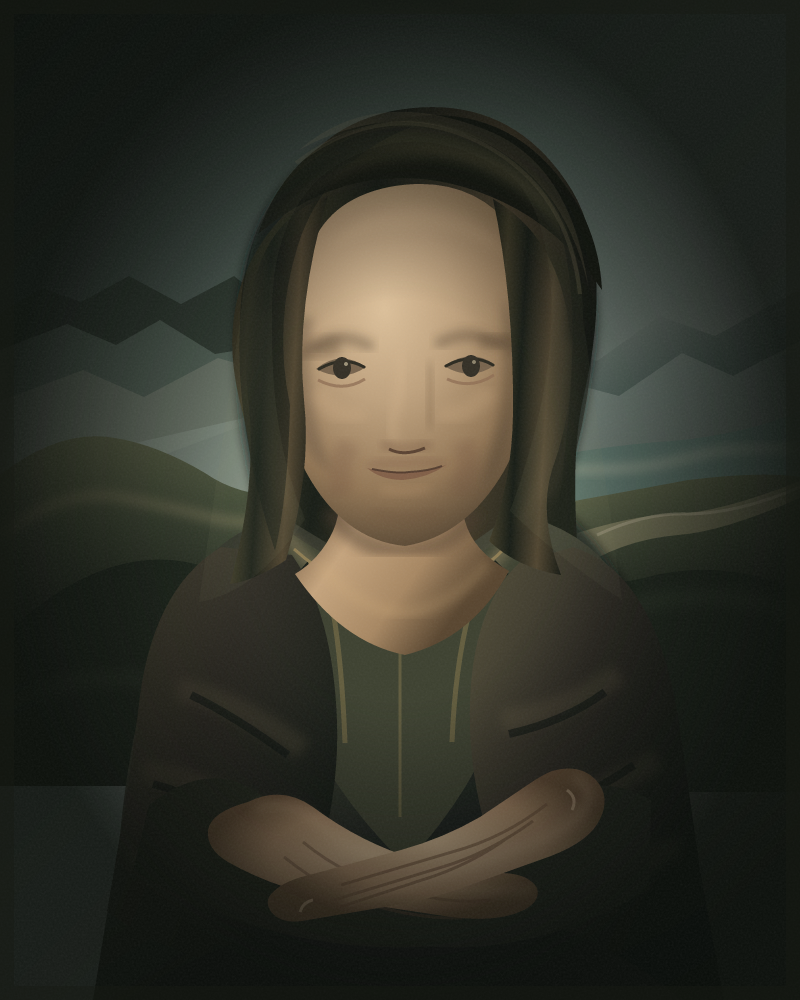
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
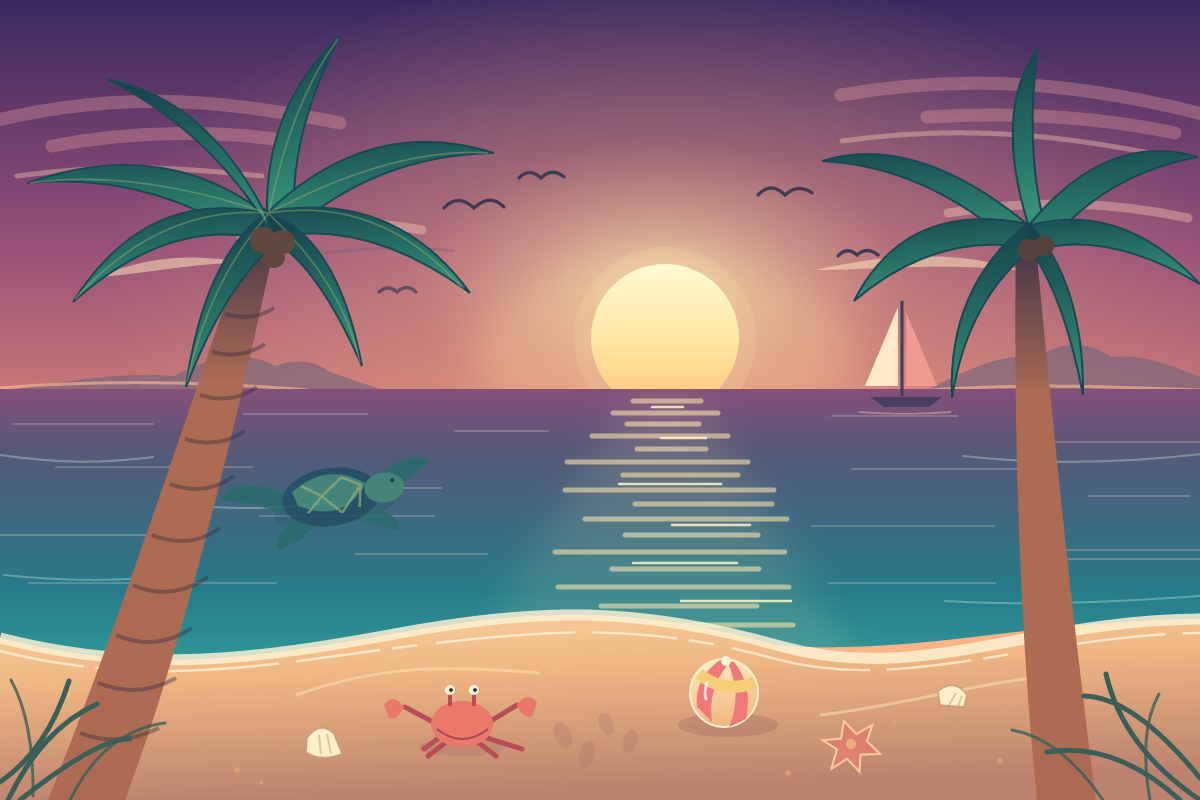
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
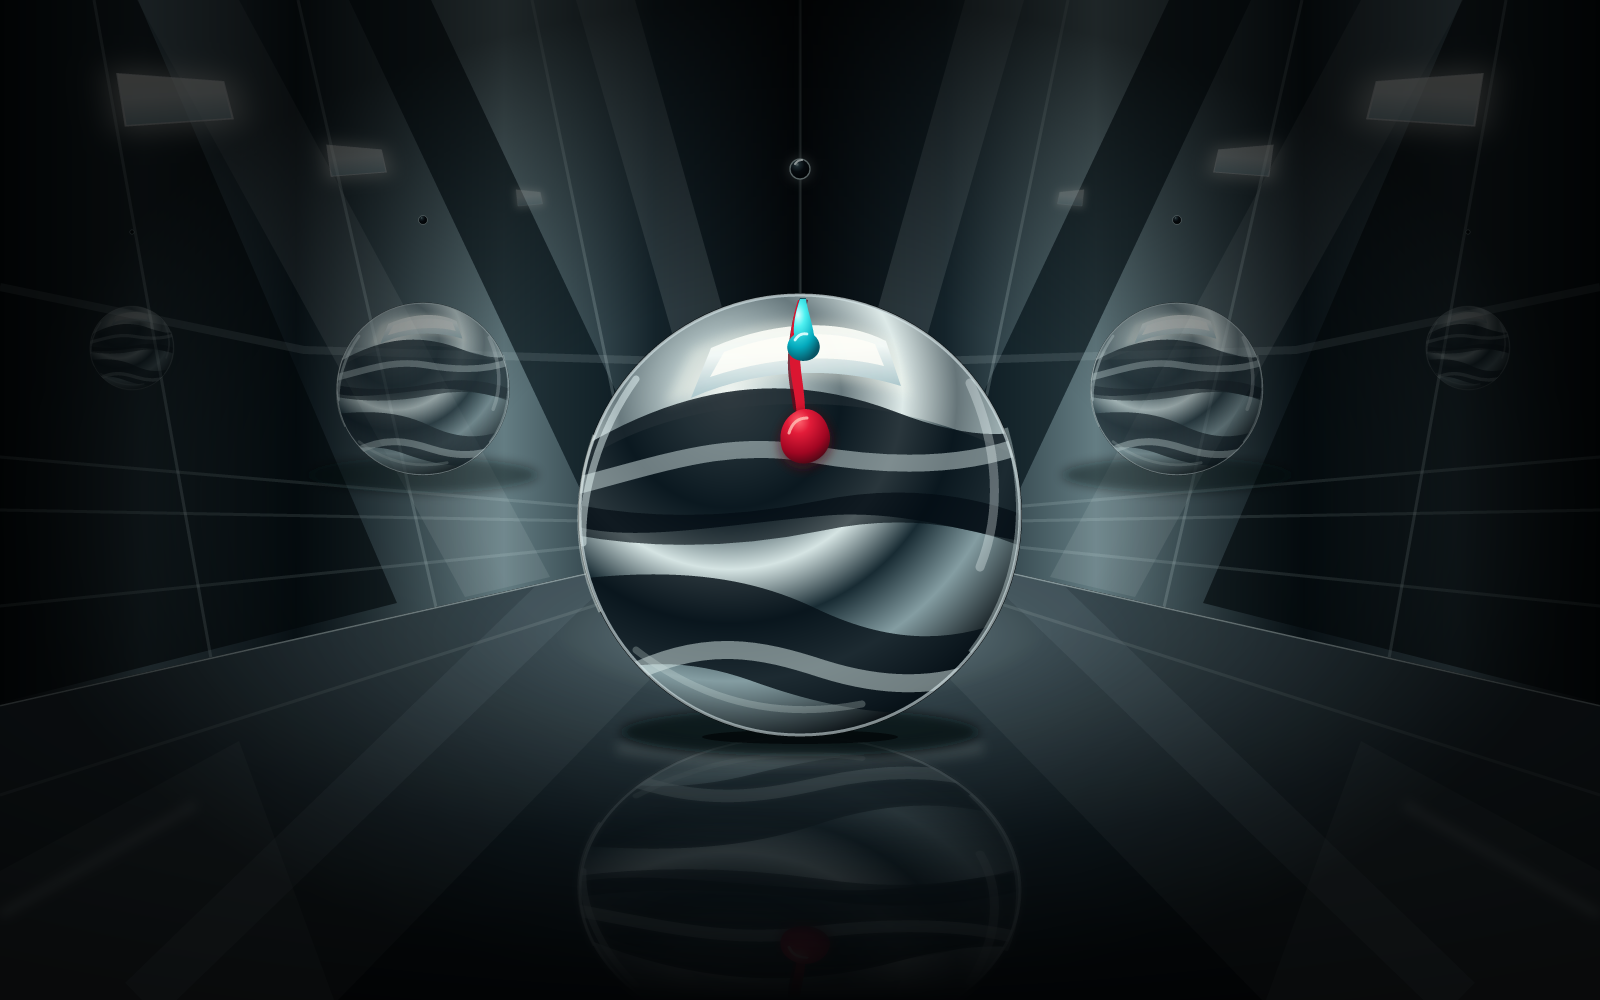
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
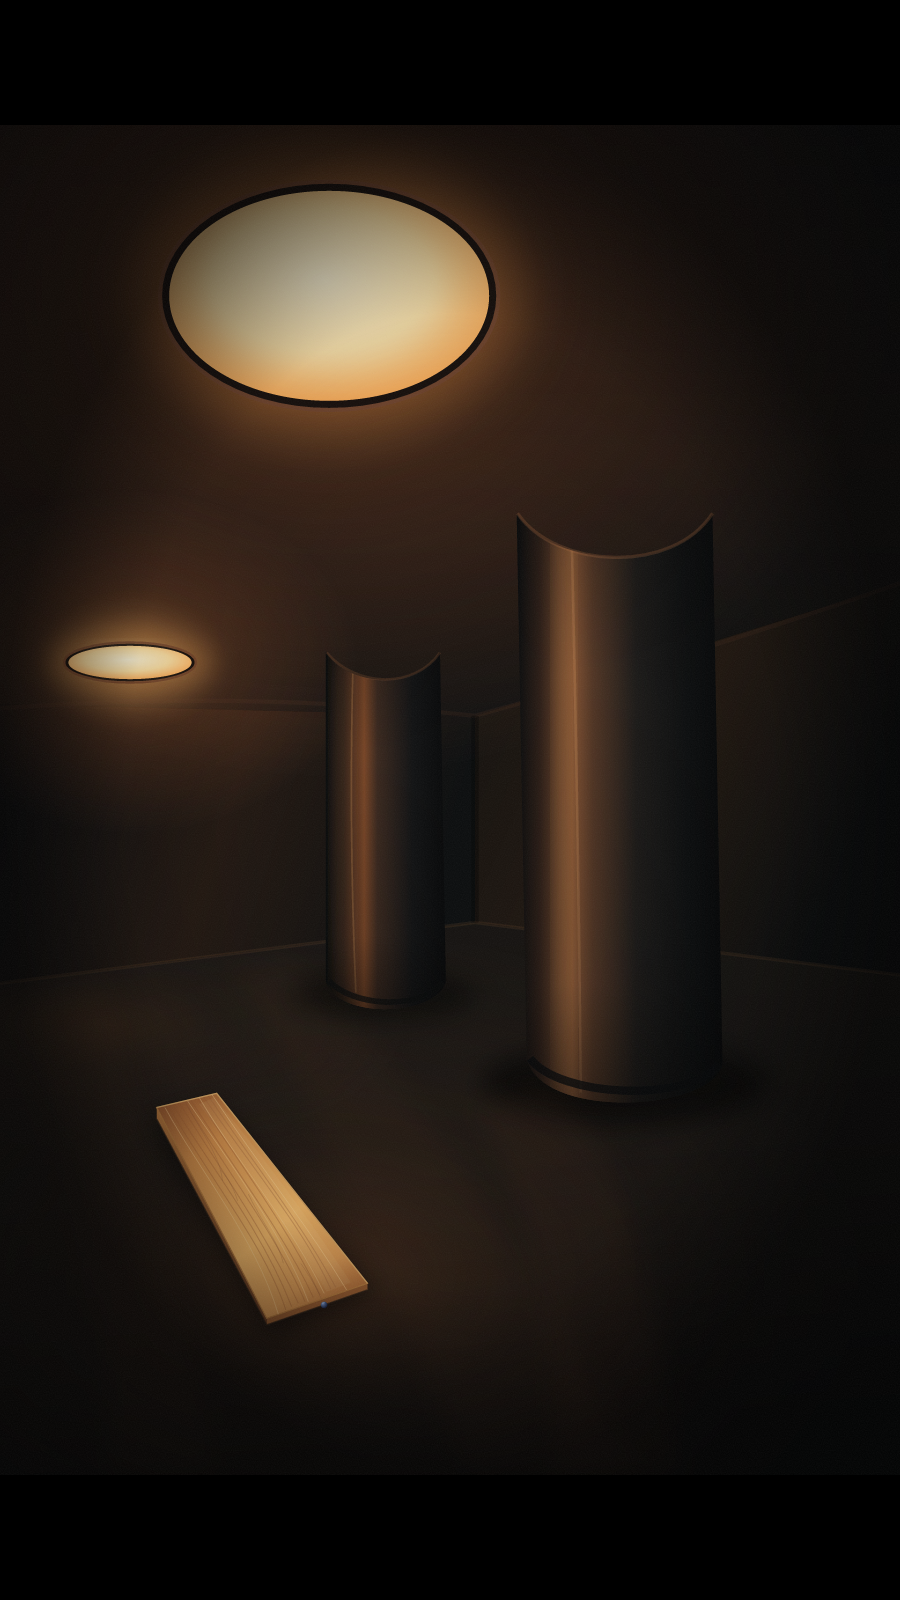
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
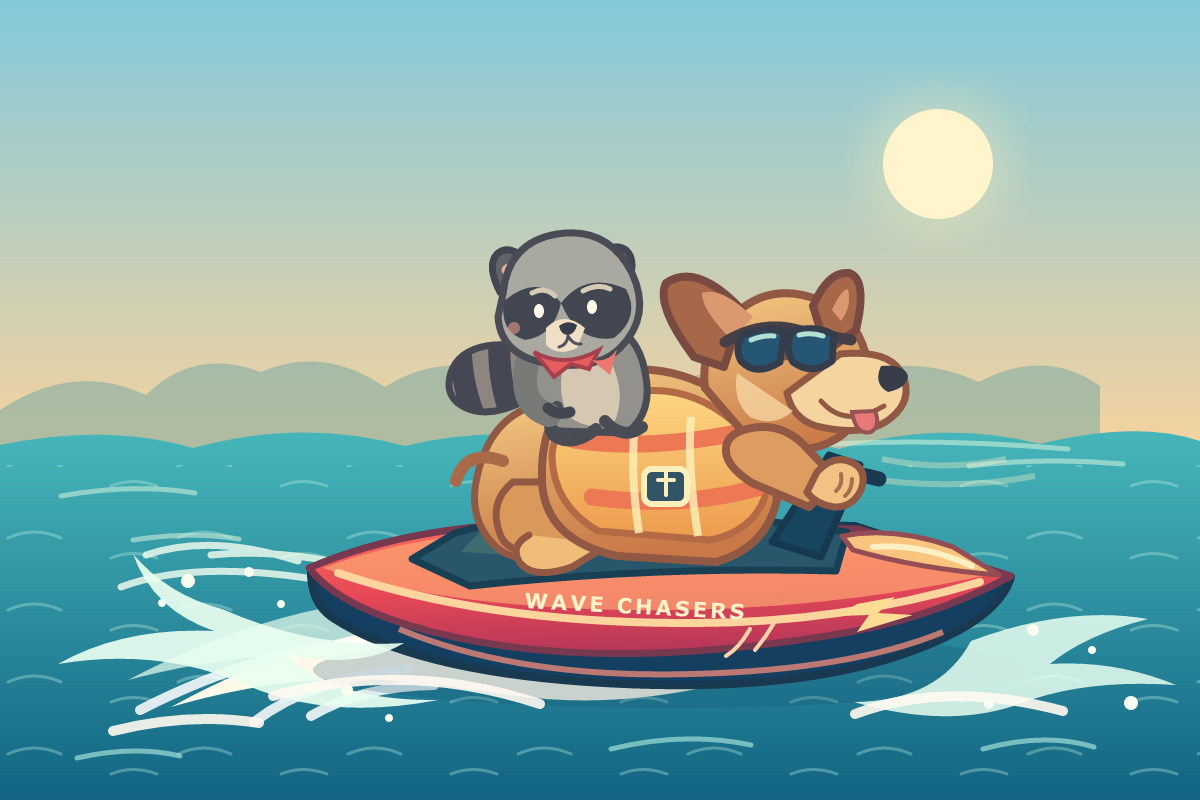
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
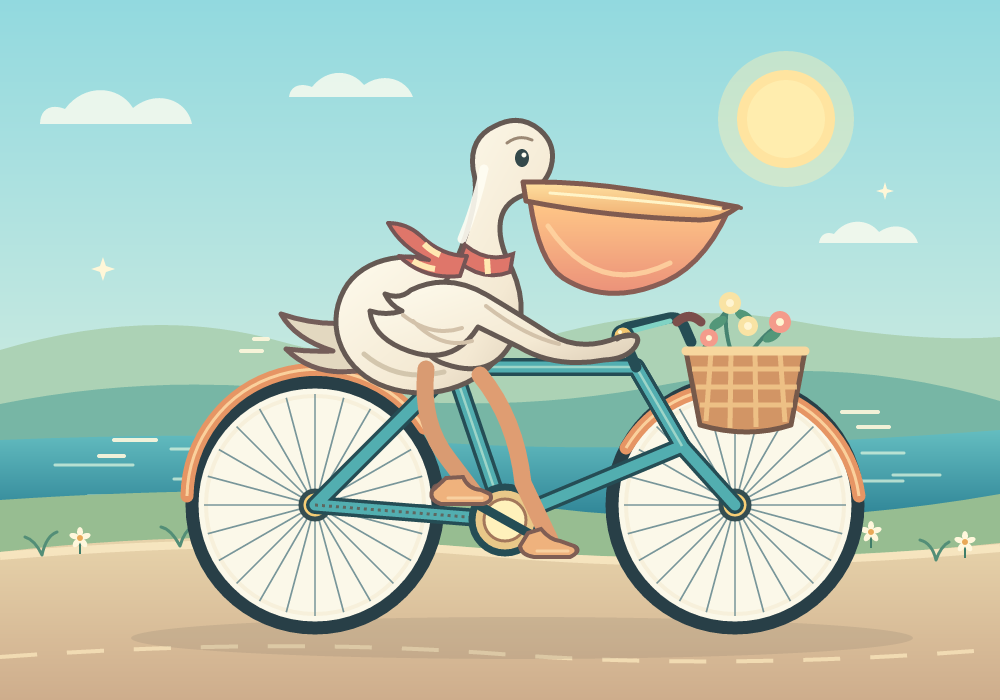
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDx-ai/grok-4.7
StealthMarkOverall rank20/499 rated results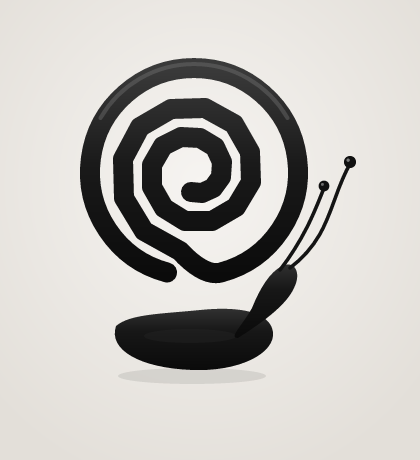
A dark snail with a geometric spiral shell tests silhouette, curved construction and restrained material shading.
First run
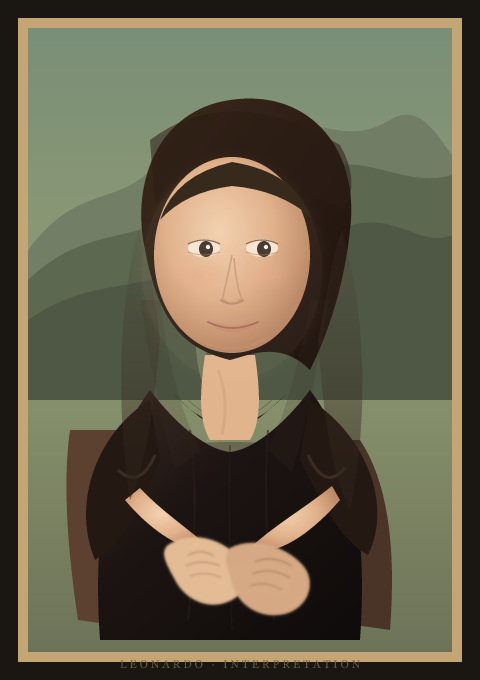
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
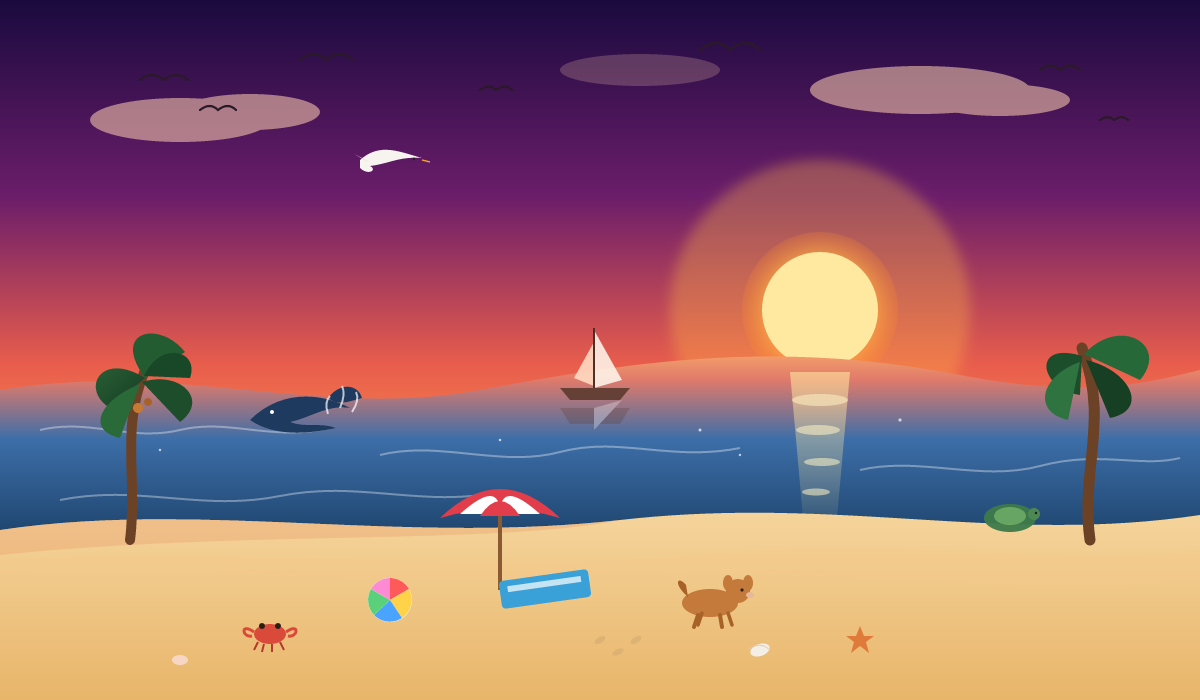
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
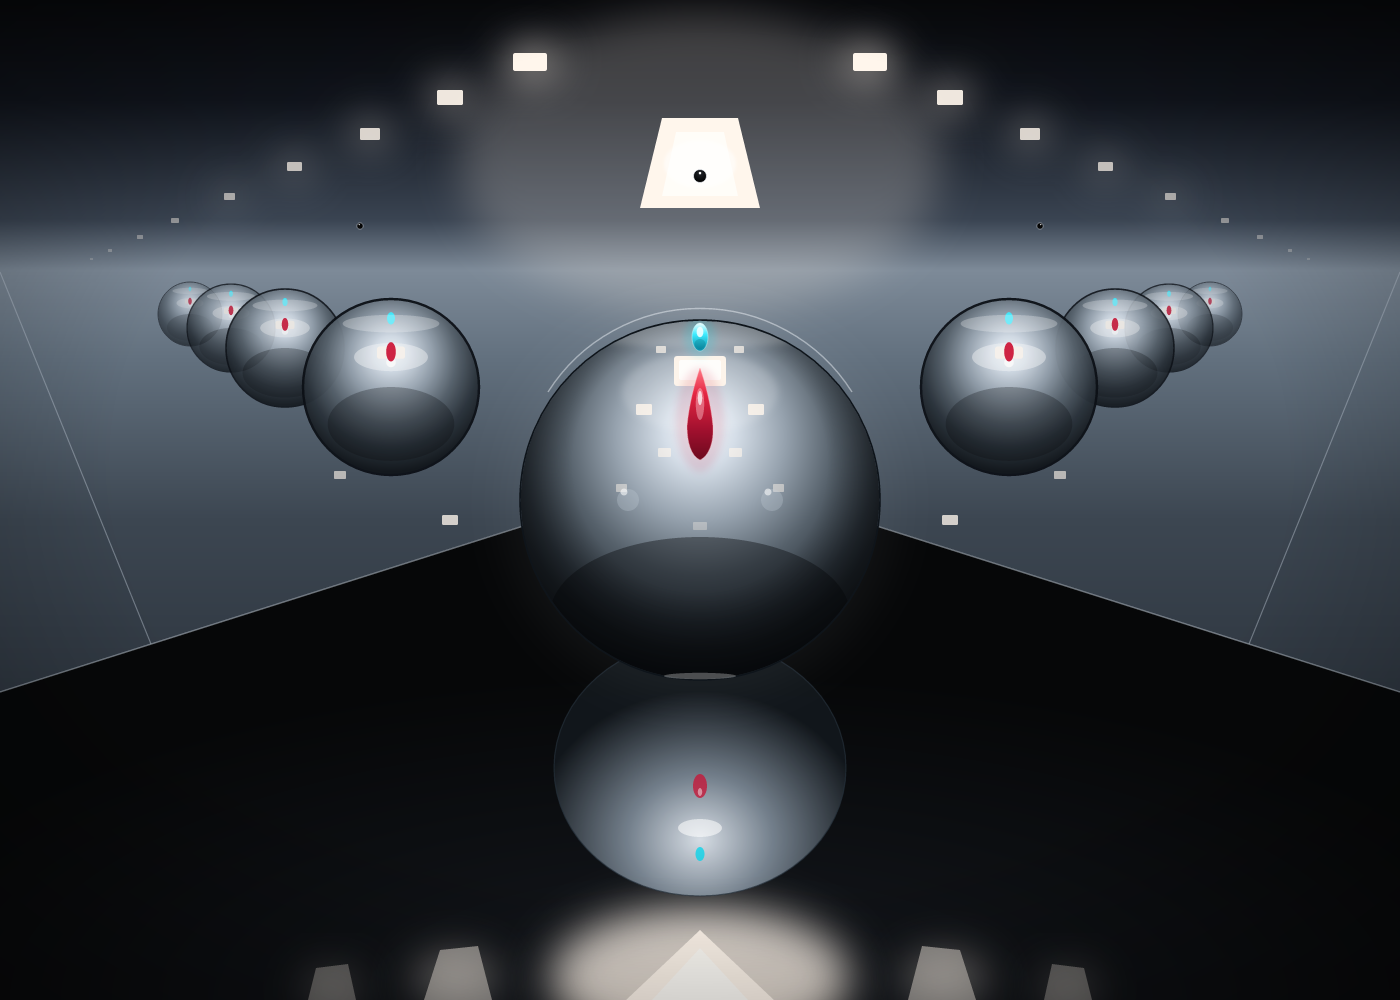
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
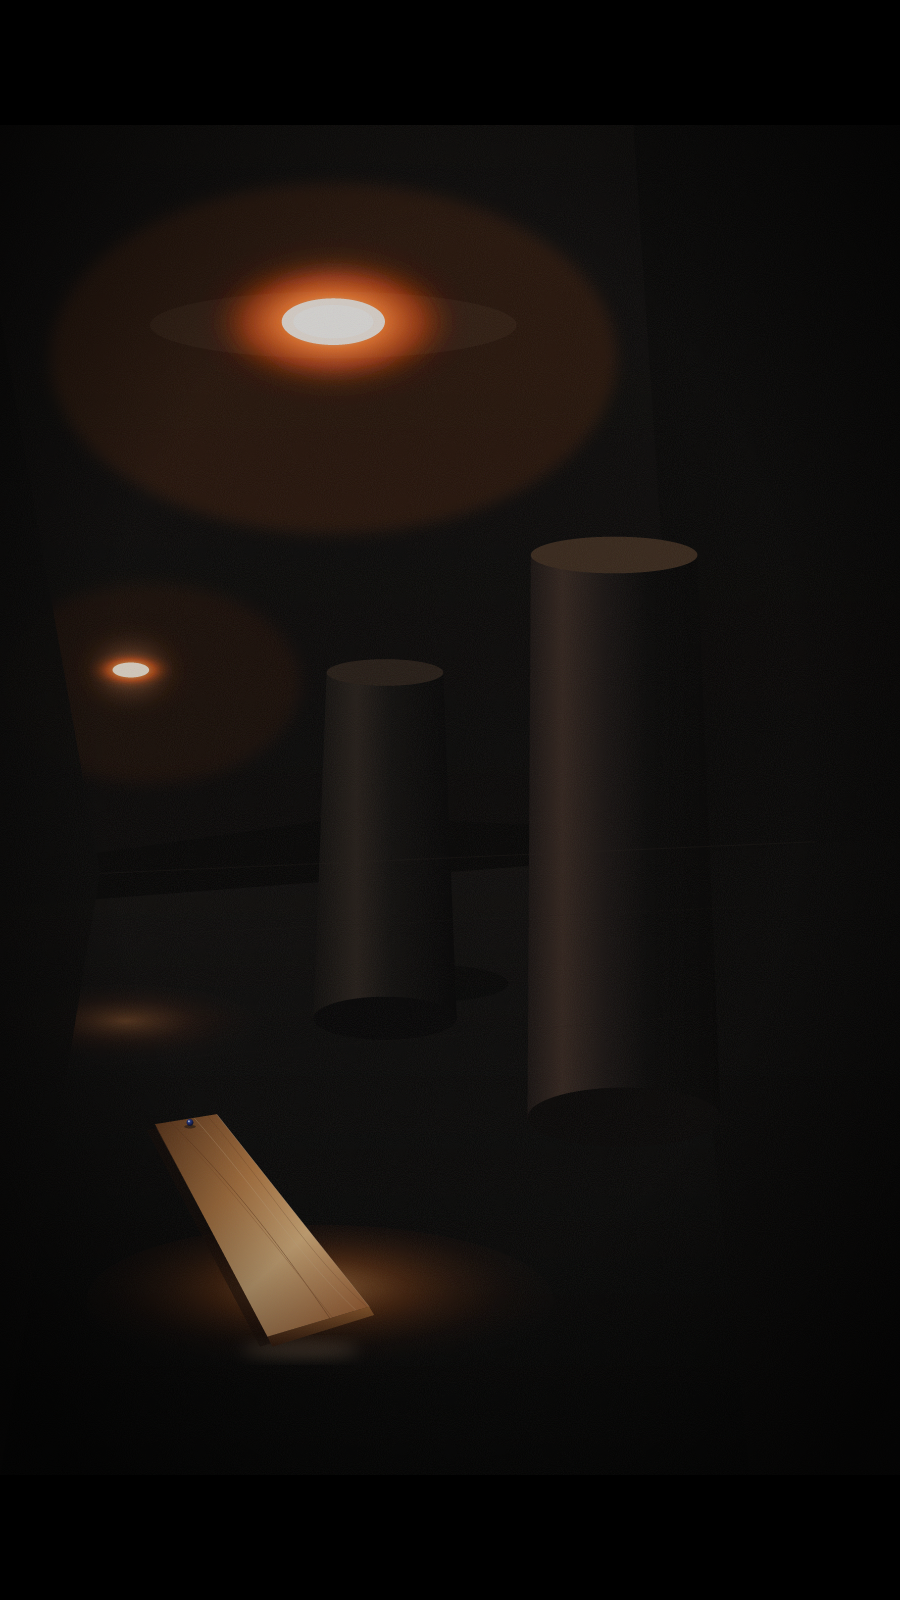
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
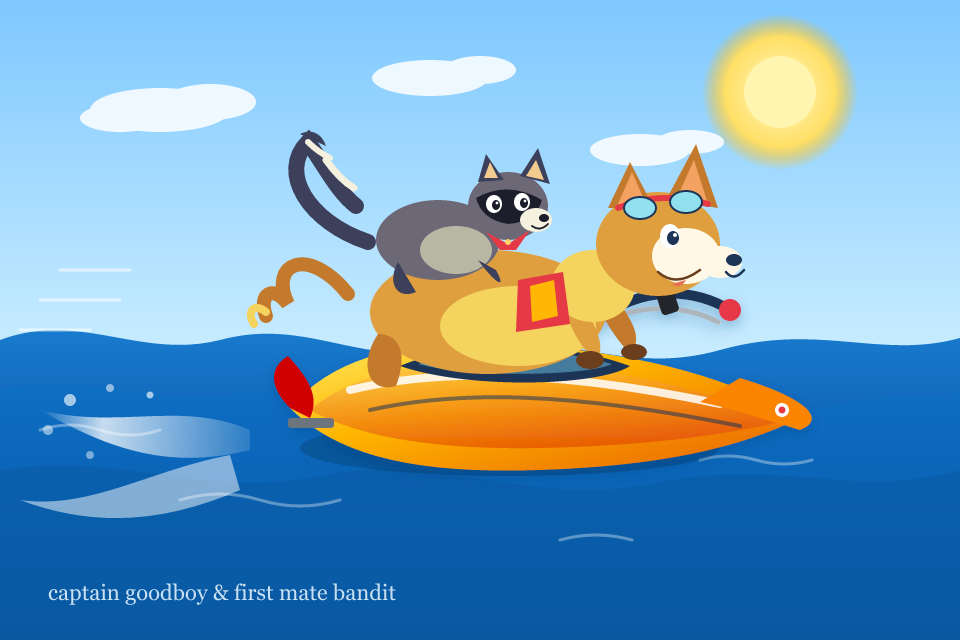
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
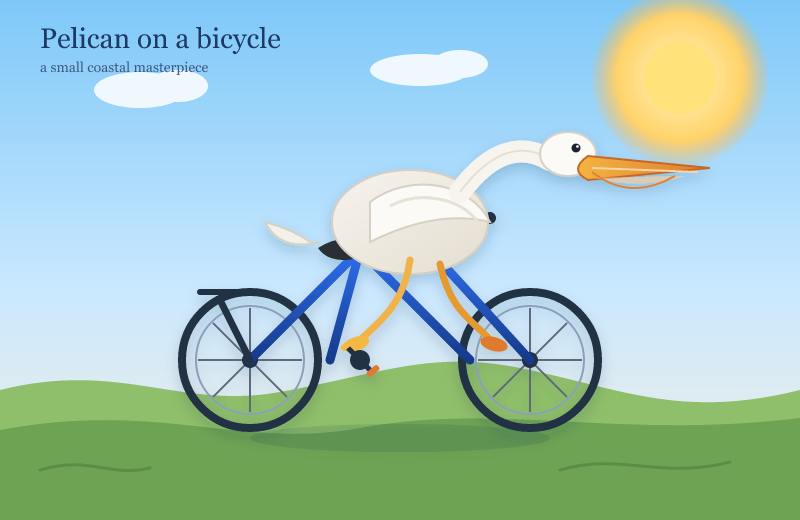
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseMiniMax Community License
Model IDminimax/minimax-m3
StealthMarkOverall rank36/499 rated results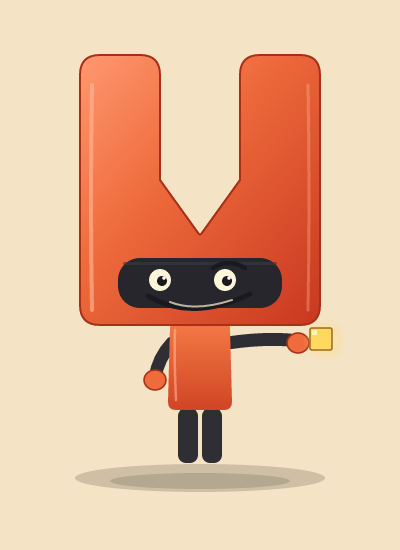
A small robot with an oversized angular head presents a glowing object. The scene tests character proportions, gesture and contrasting materials.
First run
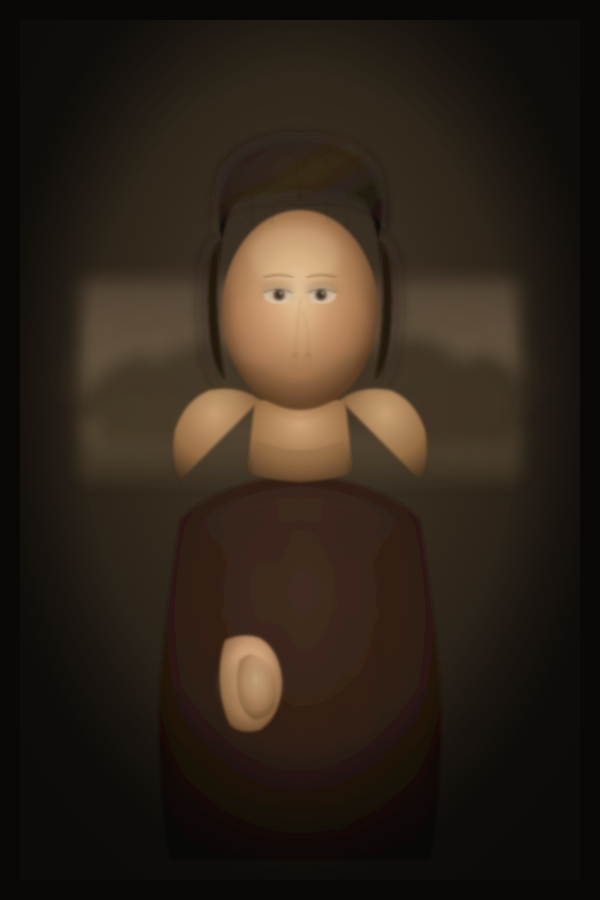
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
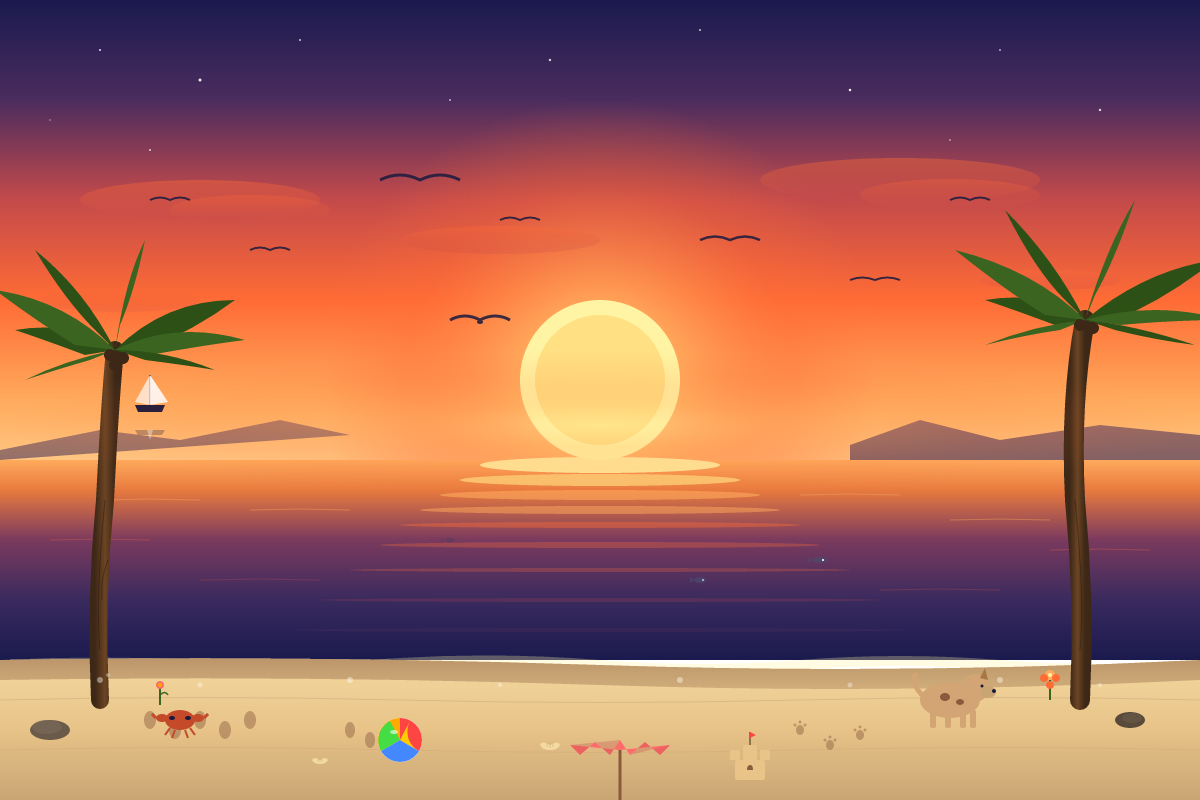
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
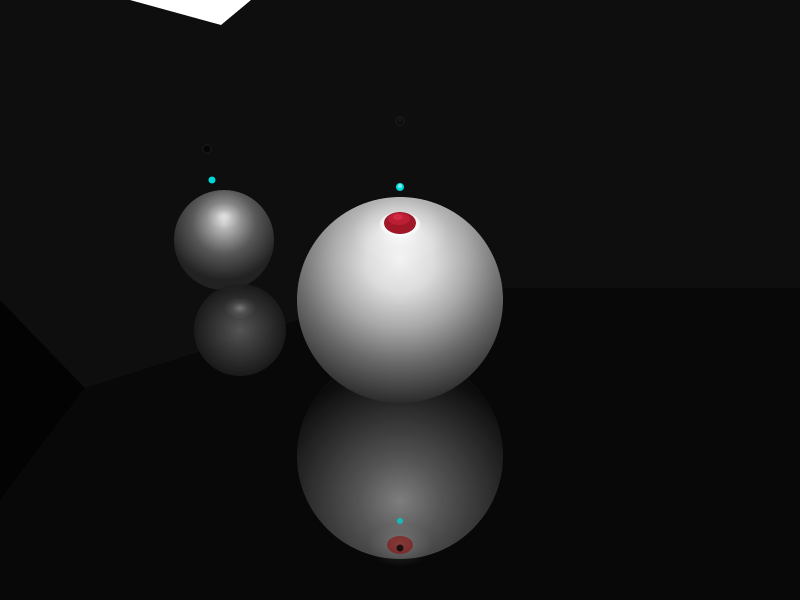
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseProprietary hosted service
Model IDanthropic/claude-sonnet-5.5
StealthMarkOverall rank3/499 rated results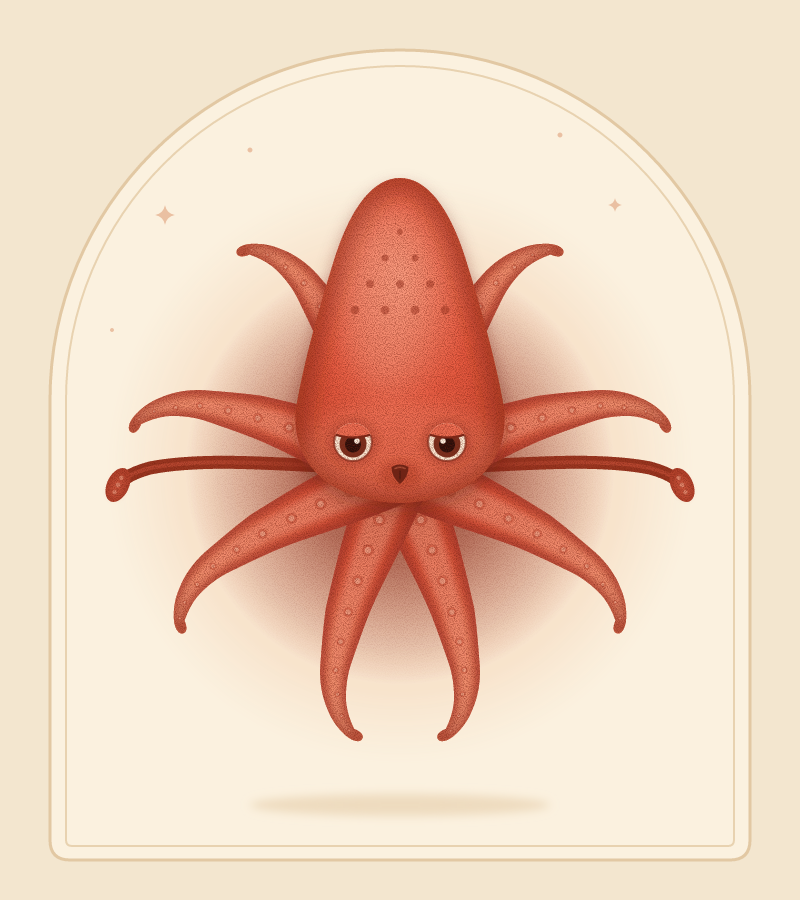
A coral squid with spreading arms tests connected anatomy, balanced composition and soft surface shading.
First run
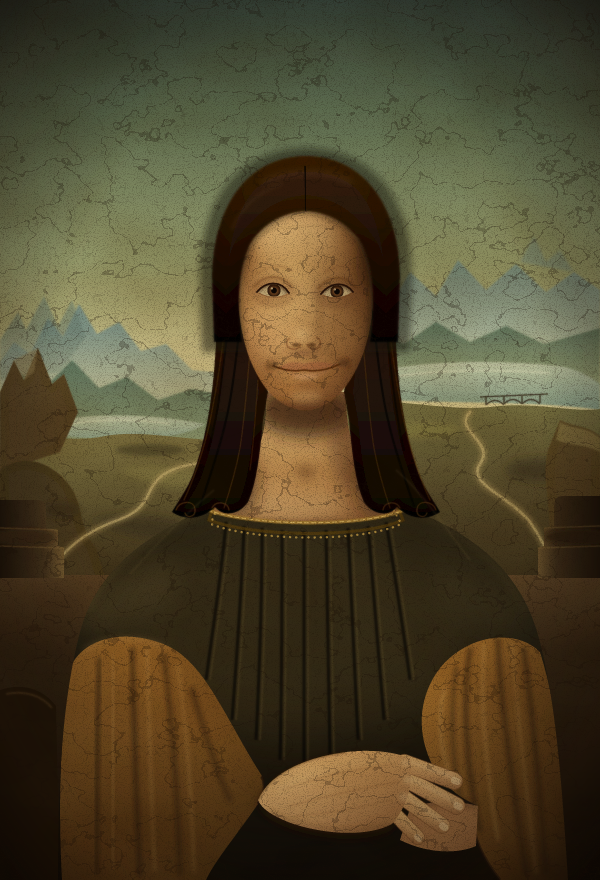
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
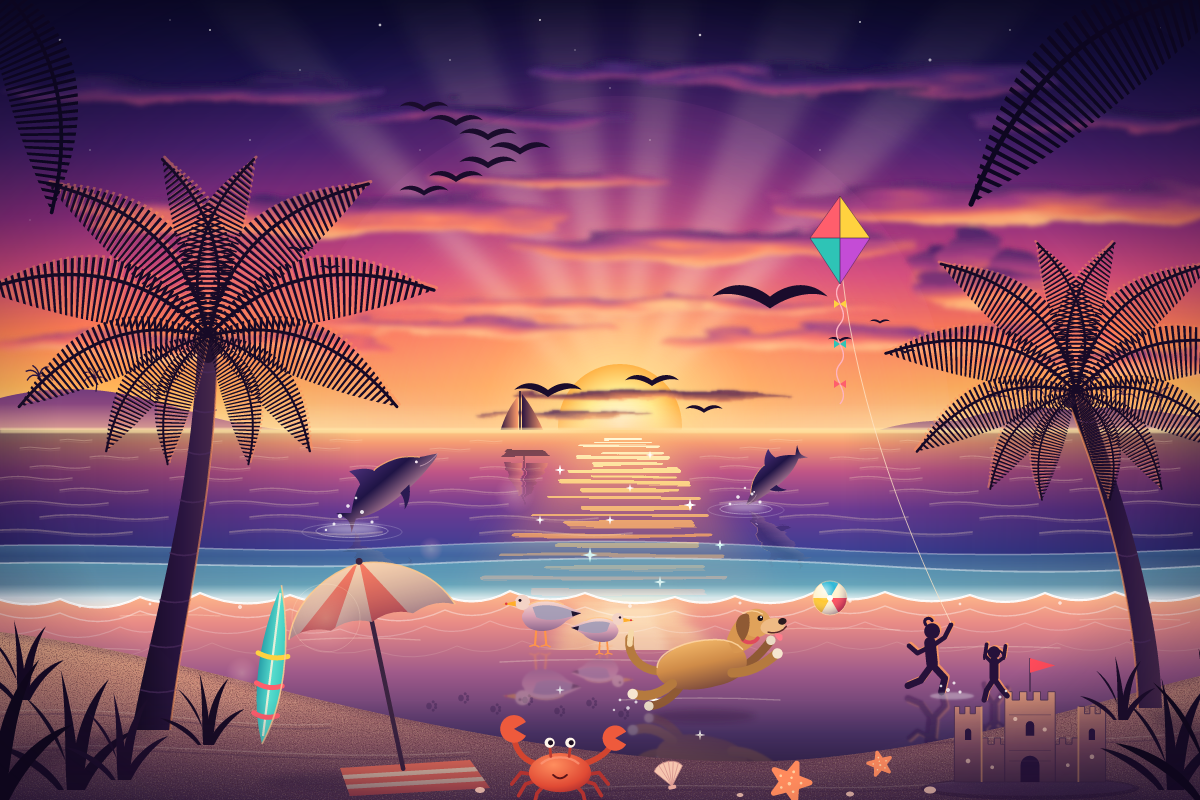
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
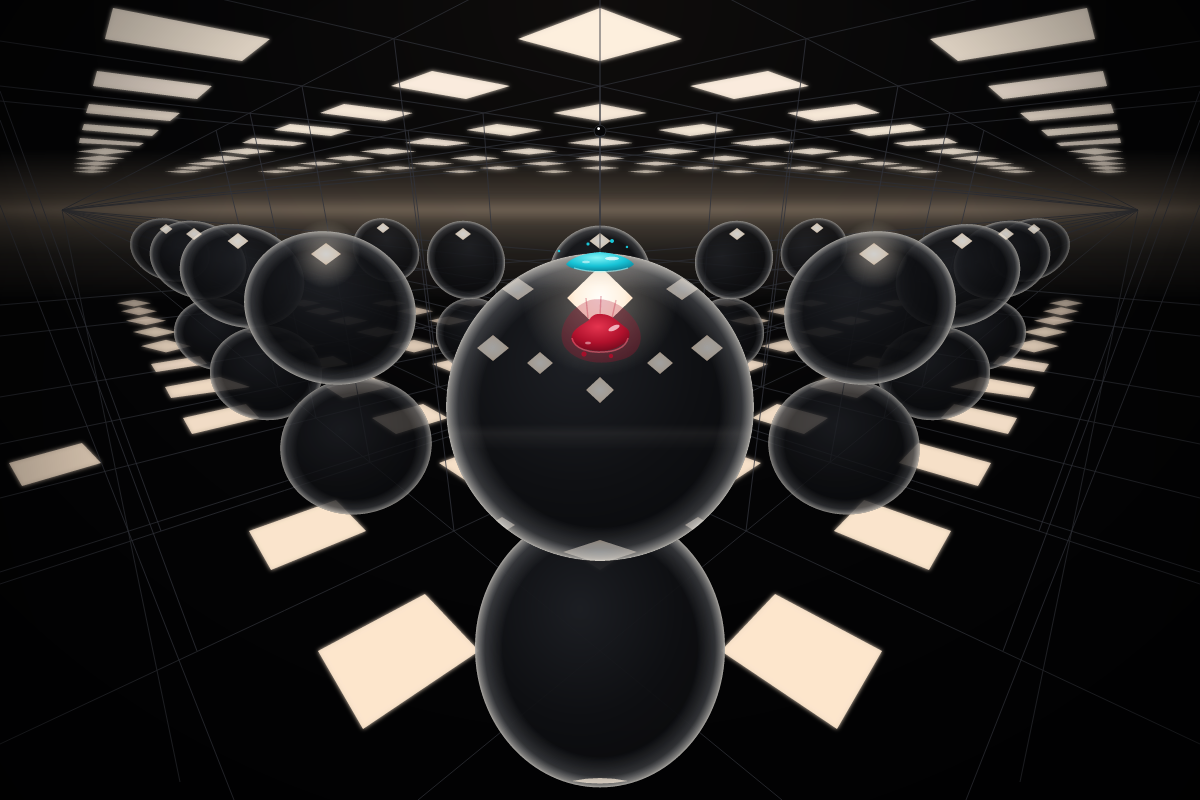
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
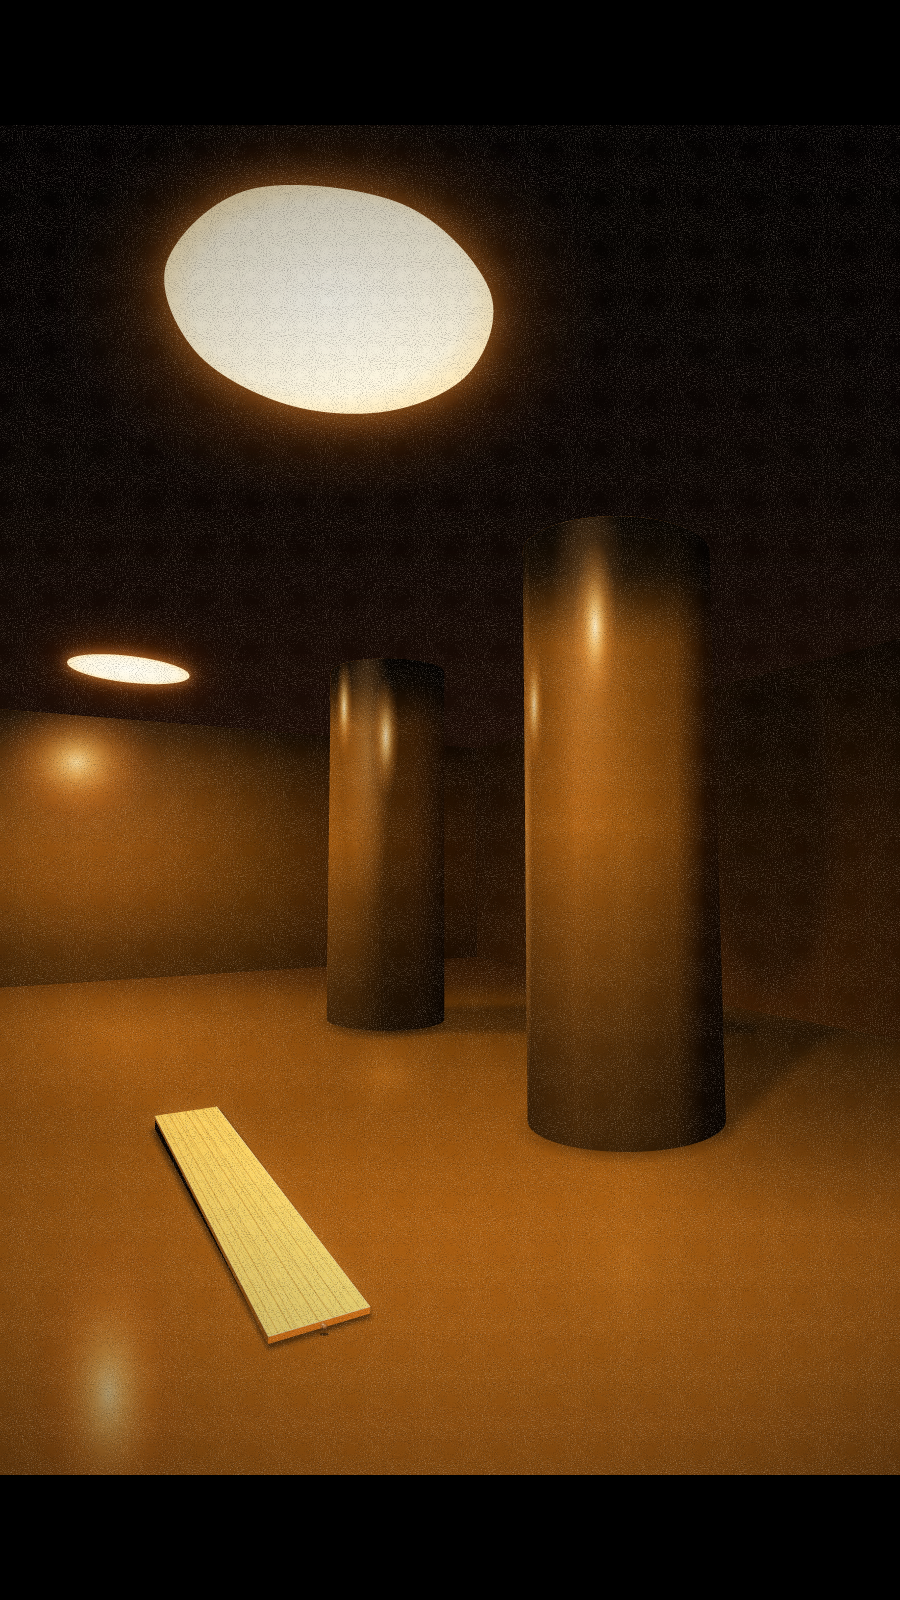
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
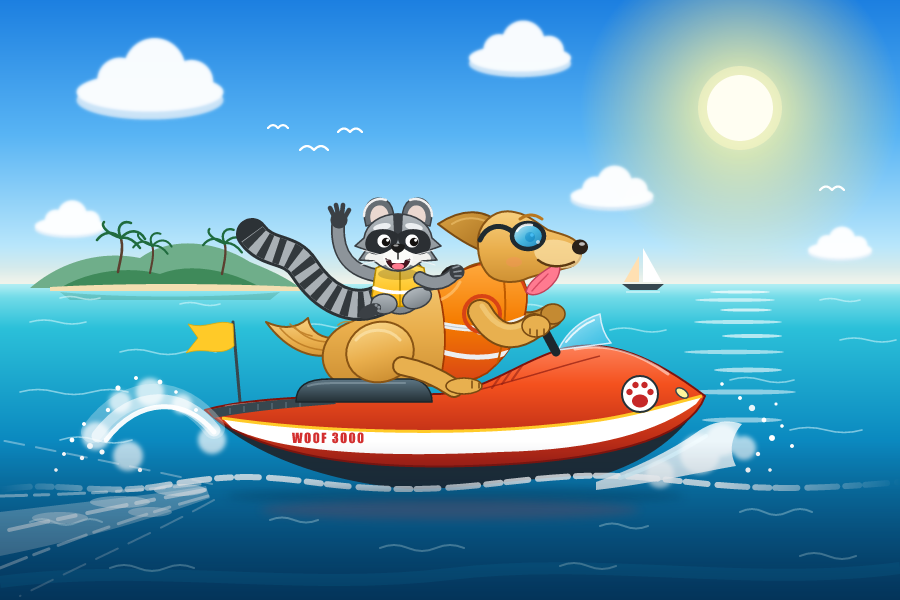
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
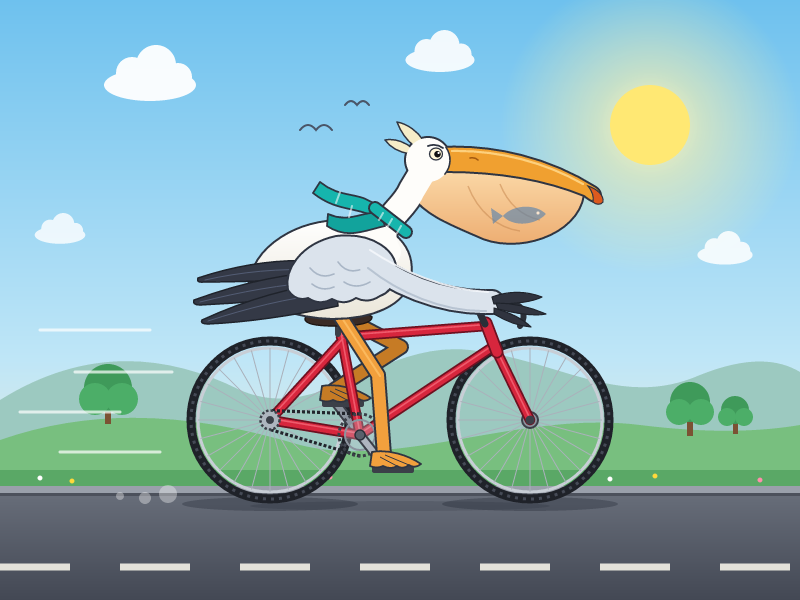
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseMIT
Model IDxiaomi/mimo-v2.6-flash
StealthMarkOverall rank30/498 rated results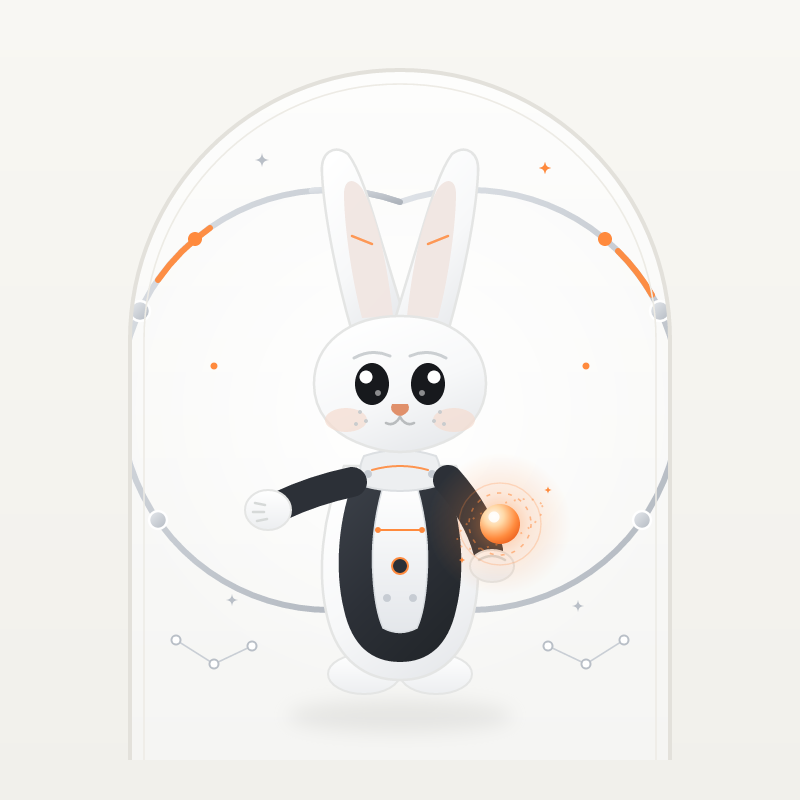
A small rabbit in an explorer outfit floats with a luminous orb. The scene tests character anatomy, pose and the placement of geometric forms around it.
First run
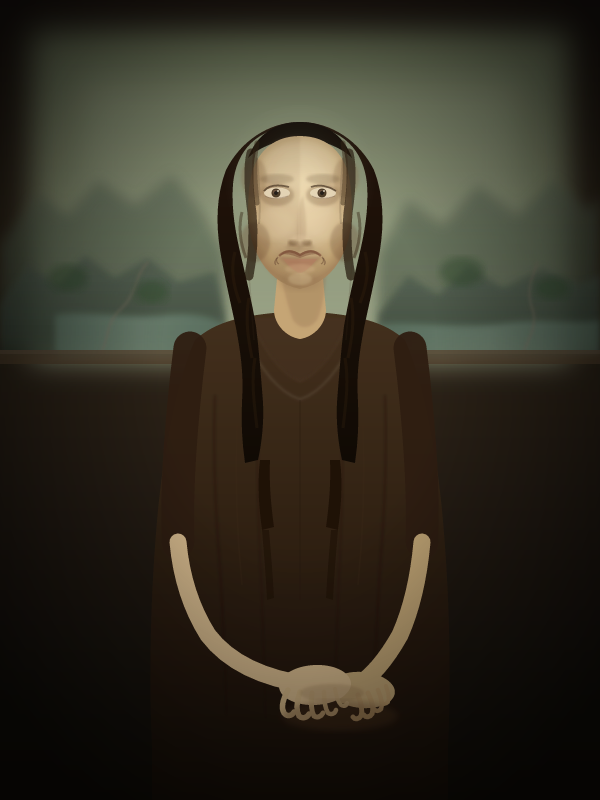
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
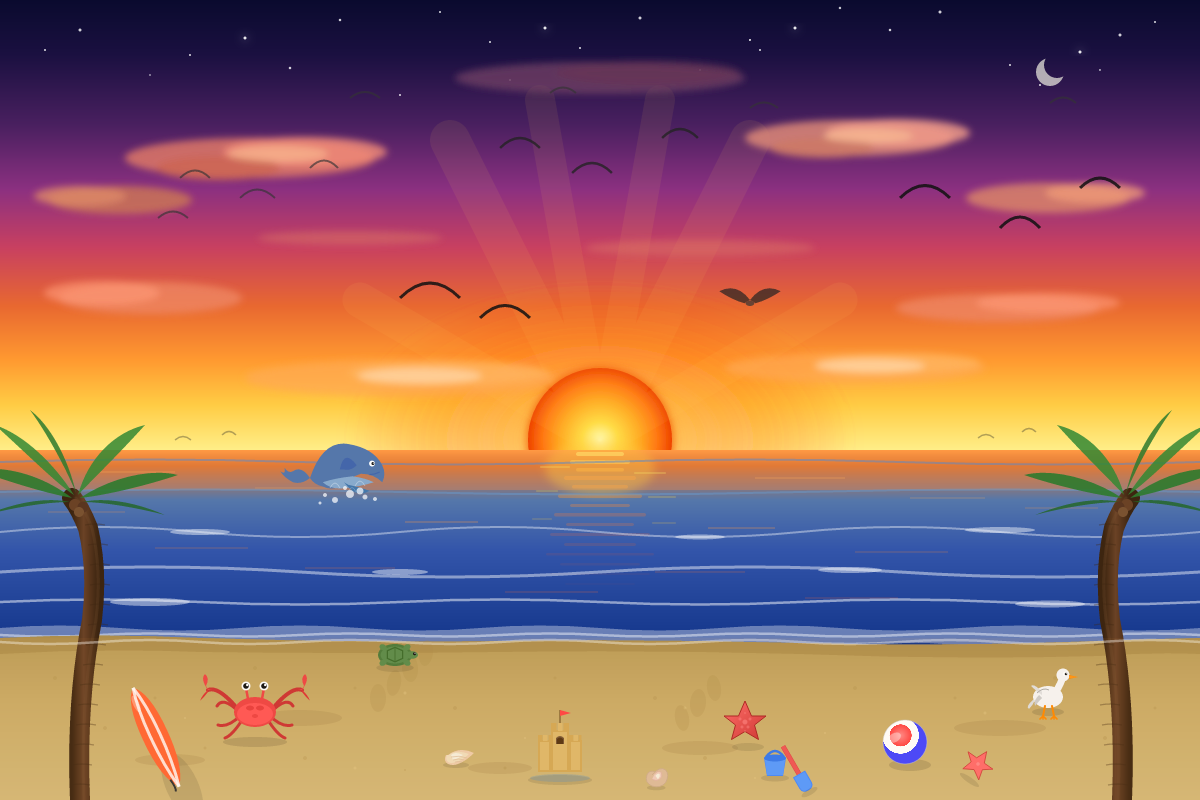
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
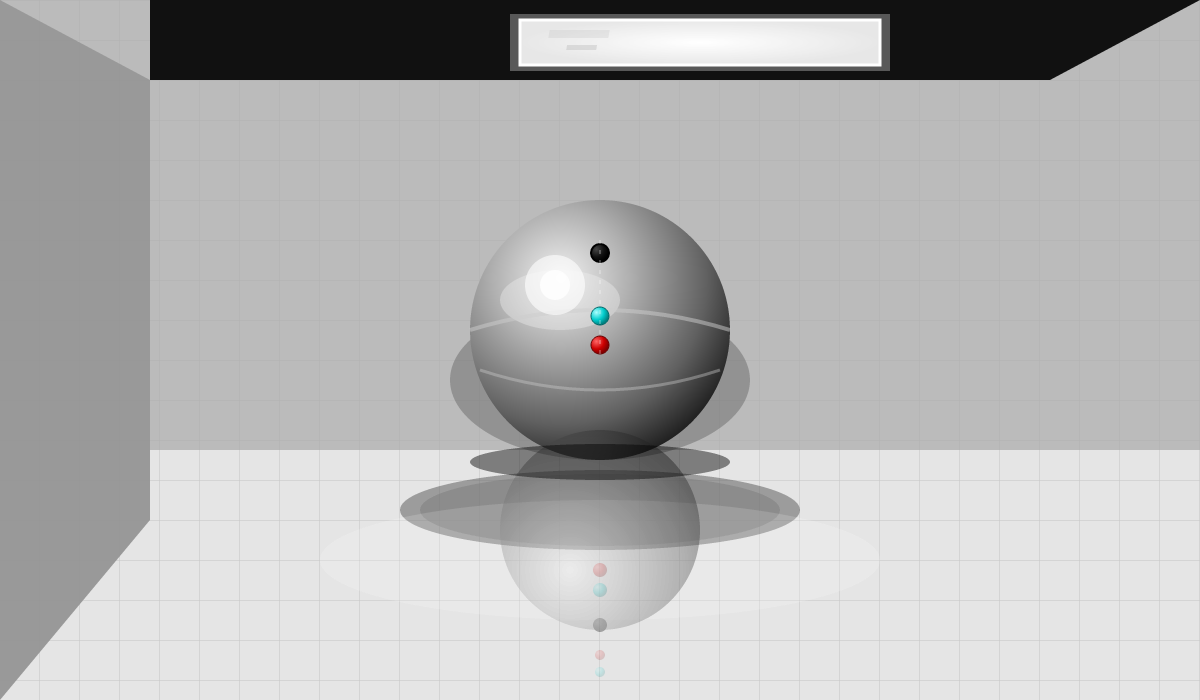
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
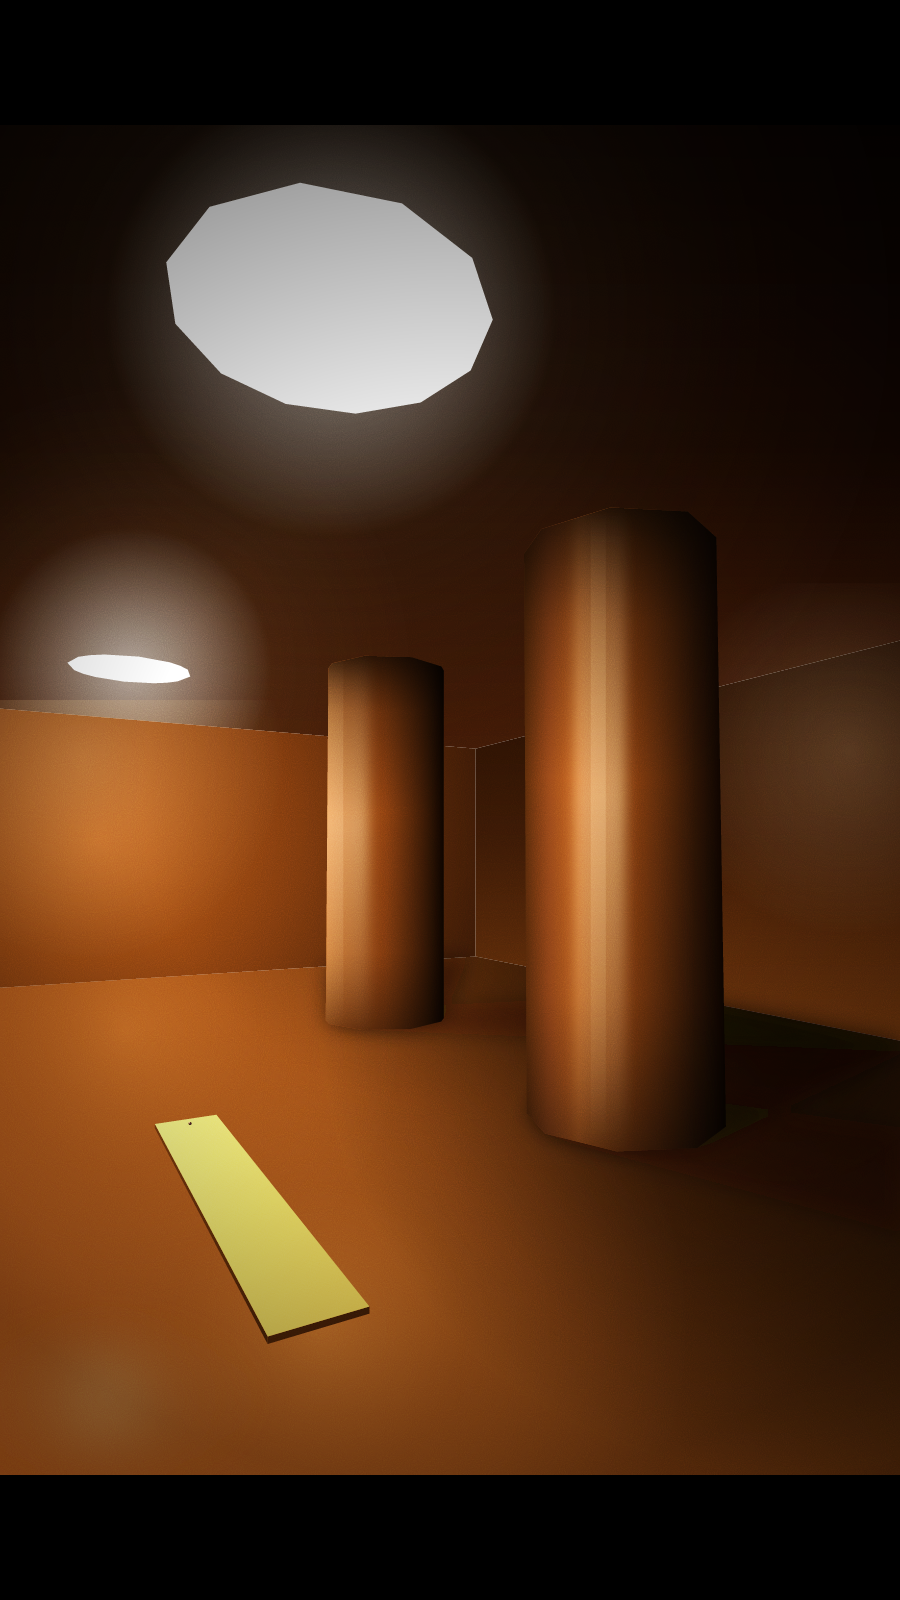
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
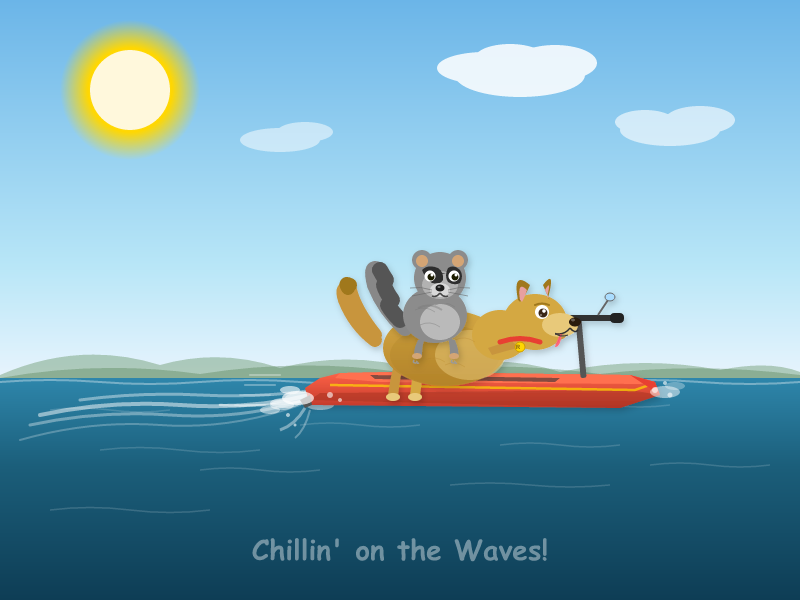
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
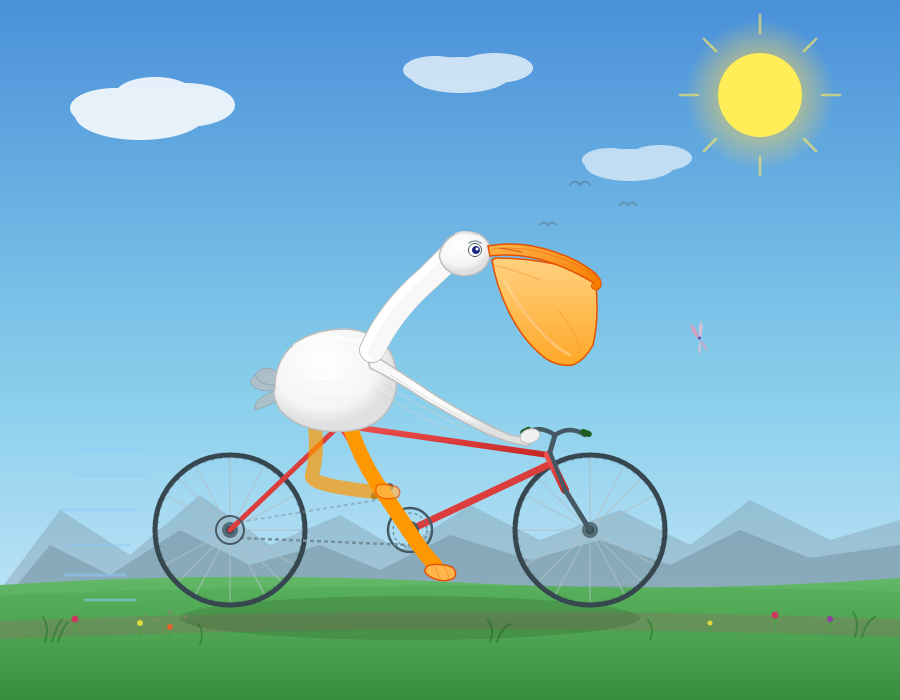
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache-2.0
Model IDqwen/qwen3.8-27B
StealthMarkOverall rank12/499 rated results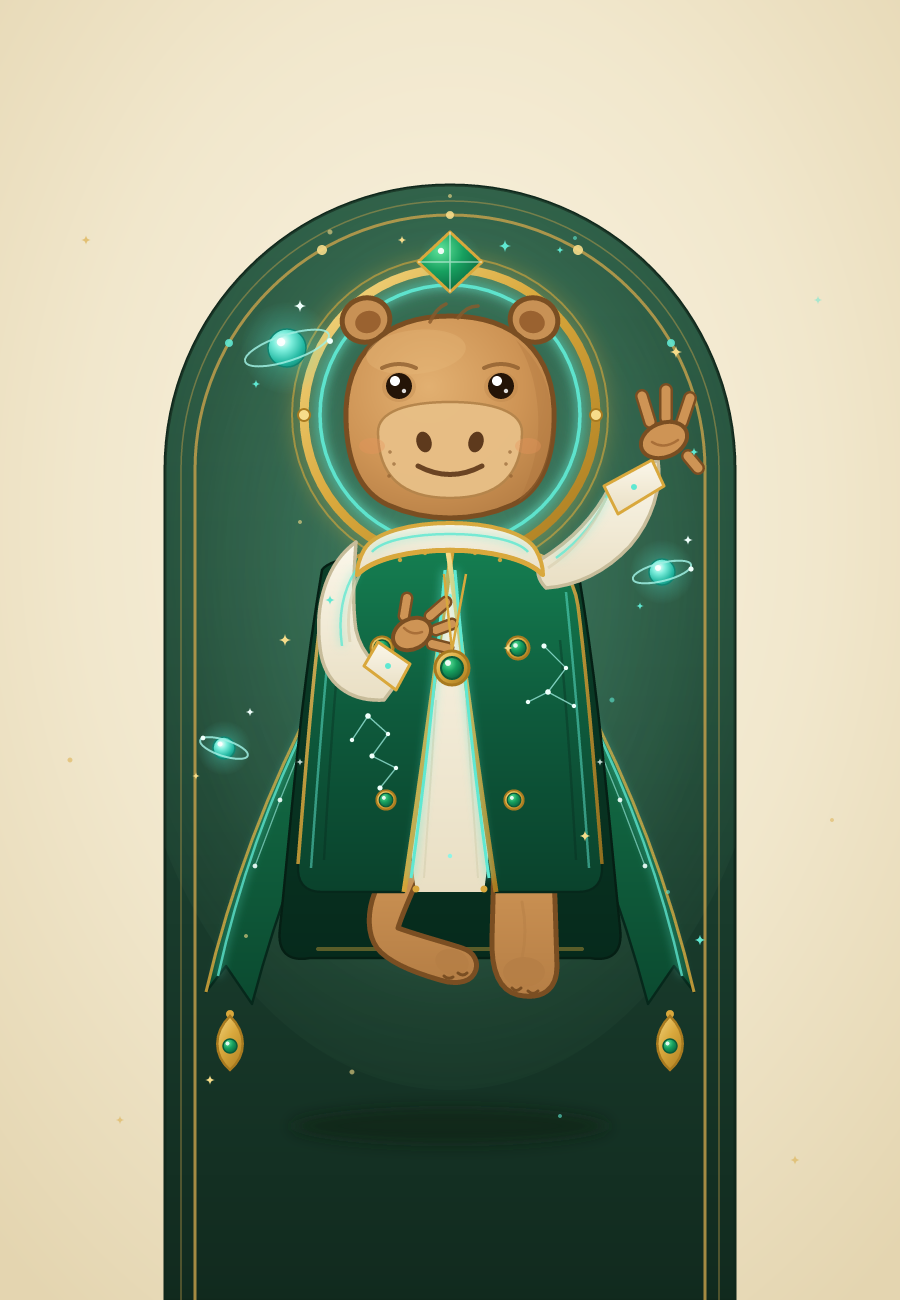
A floating capybara in ornate robes tests character anatomy, layered fabric and the placement of surrounding luminous forms.
First run
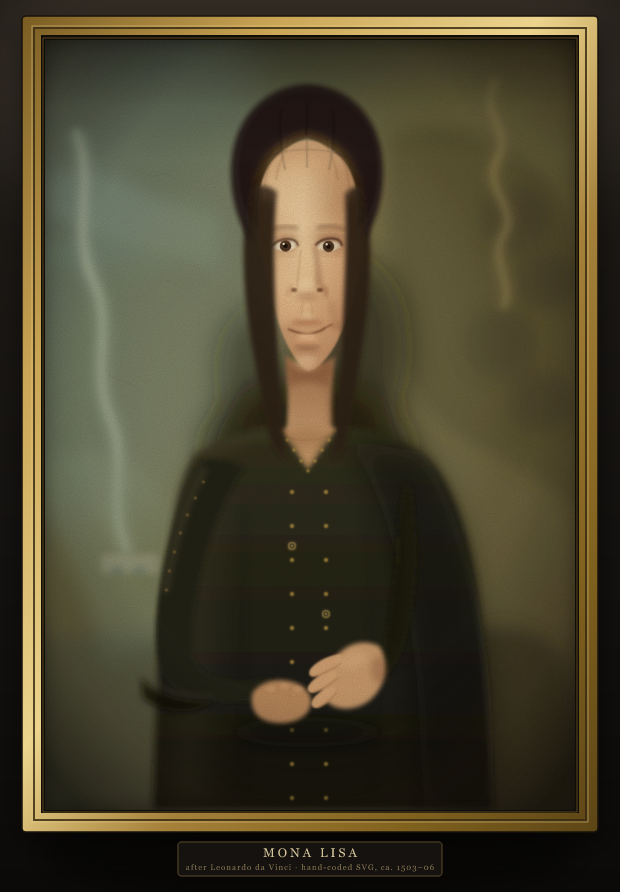
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
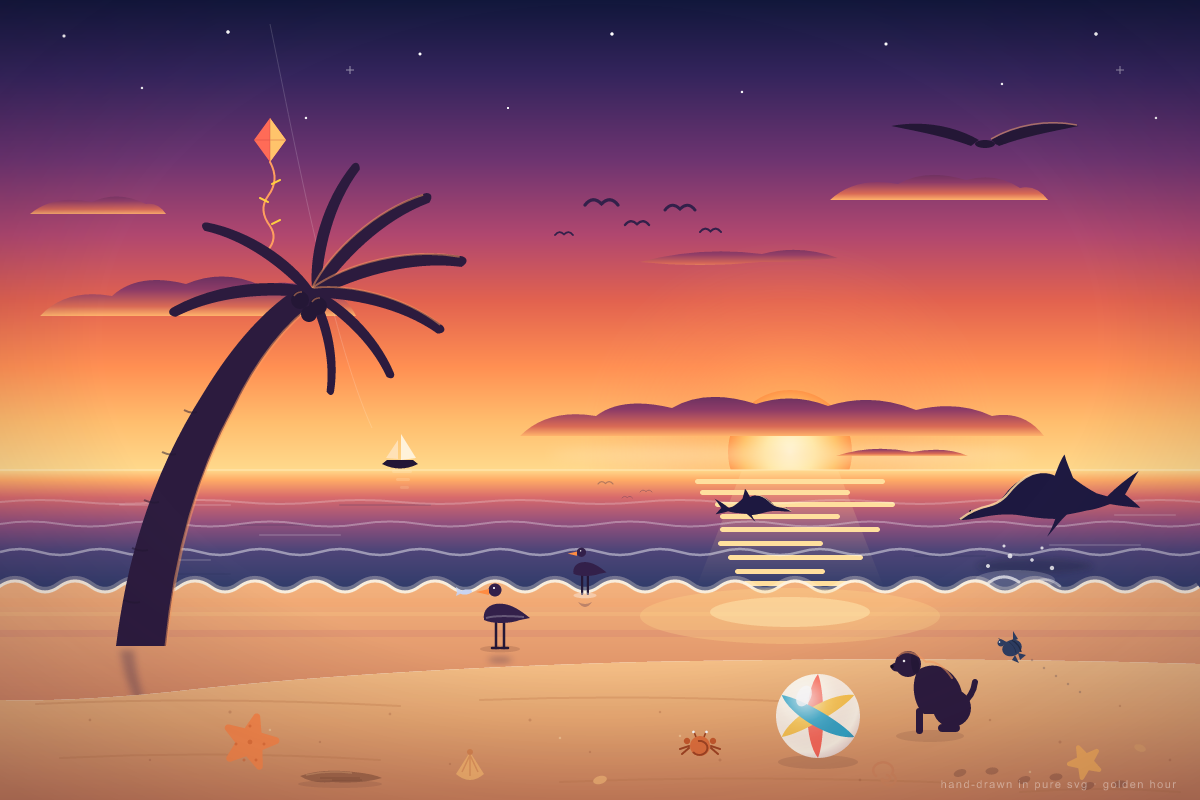
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
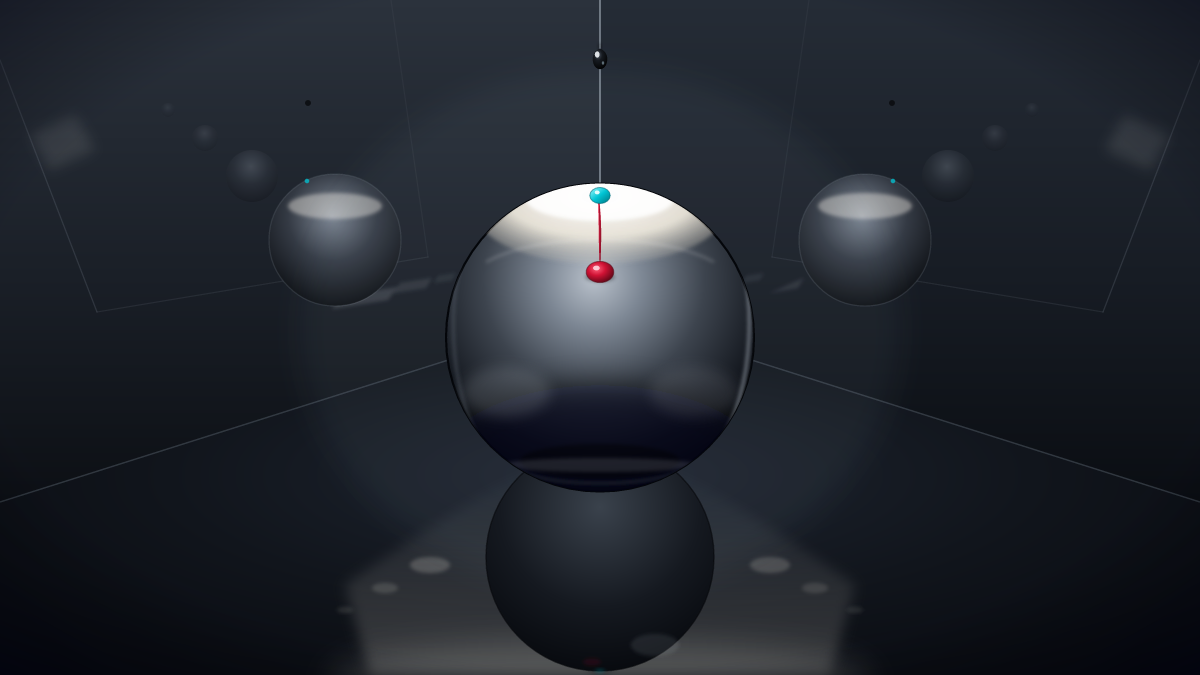
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
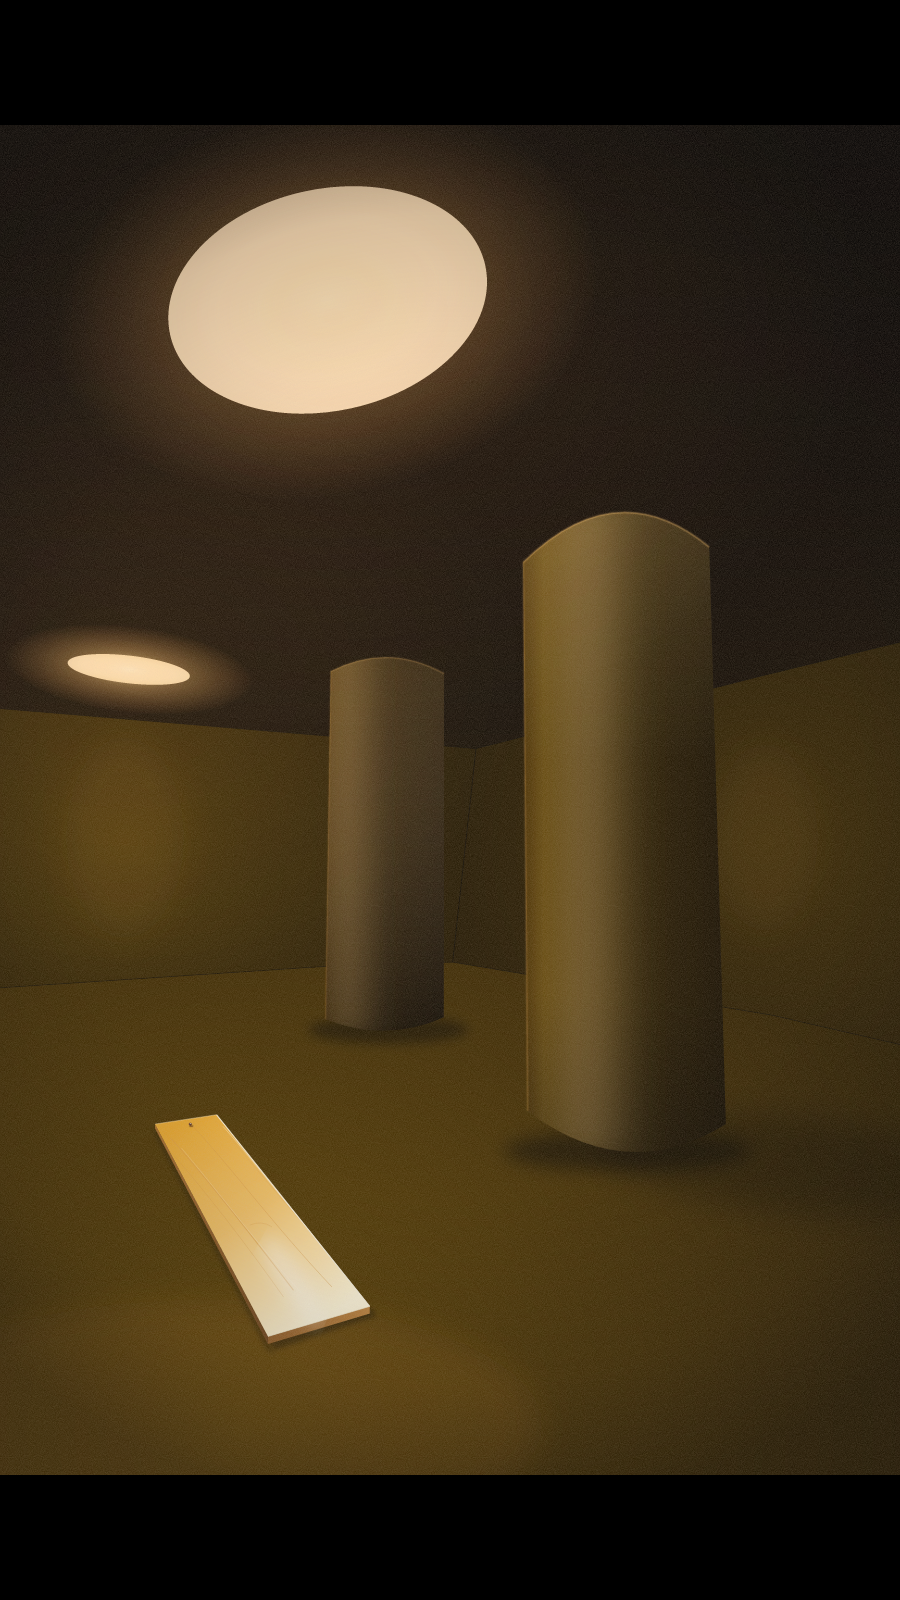
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
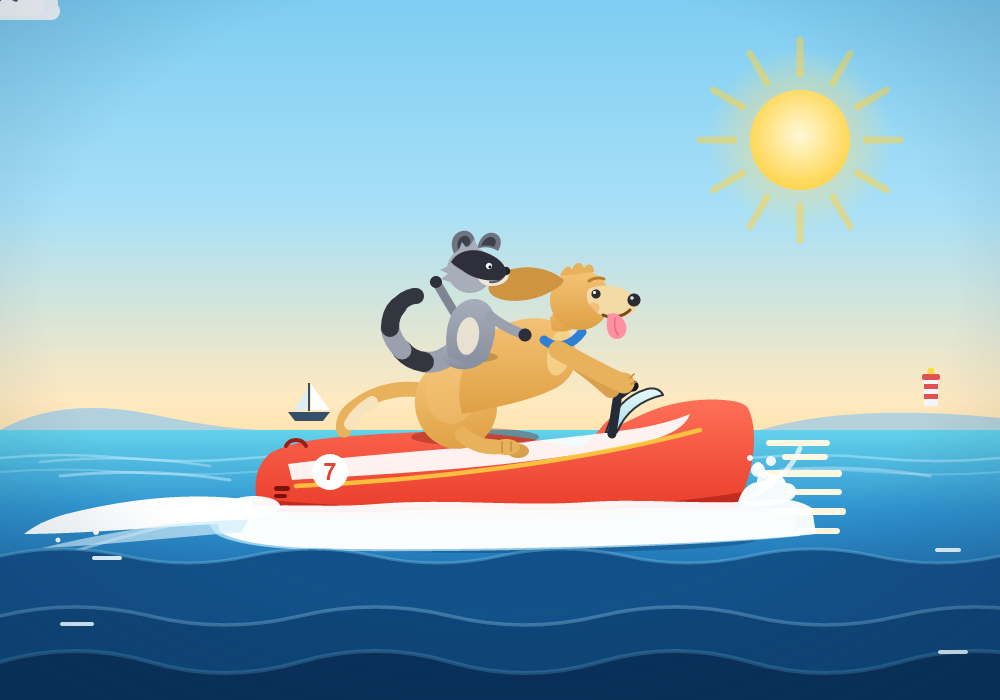
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
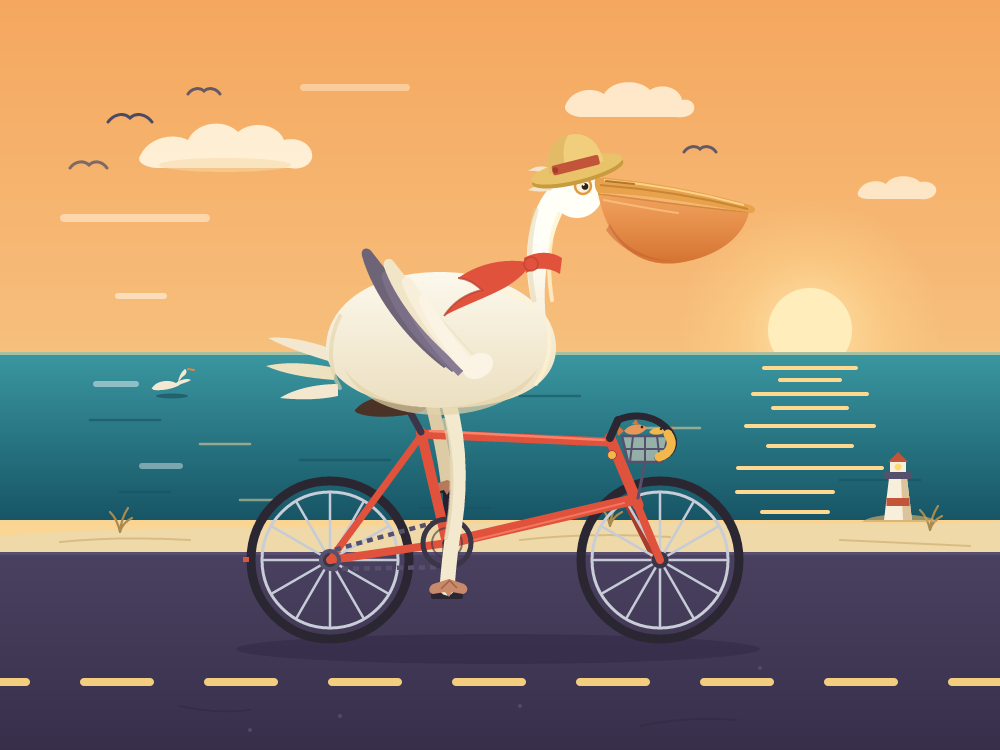
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDanthropic/claude-fable-5.1
StealthMarkOverall rank8/499 rated results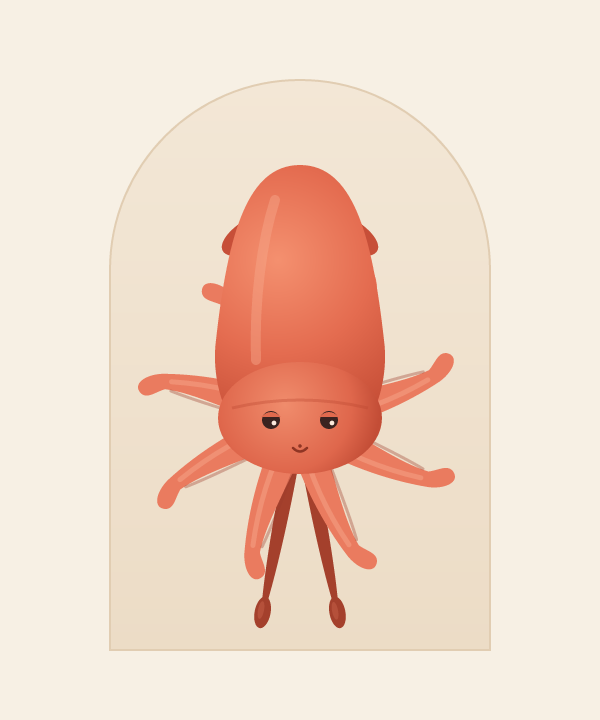
A coral squid with spreading arms tests connected anatomy, balanced composition and soft surface shading.
First run
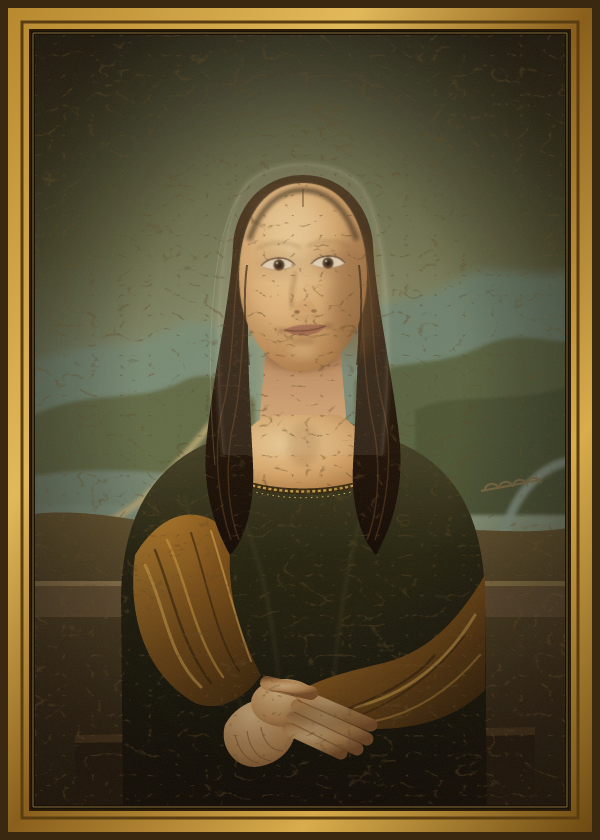
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
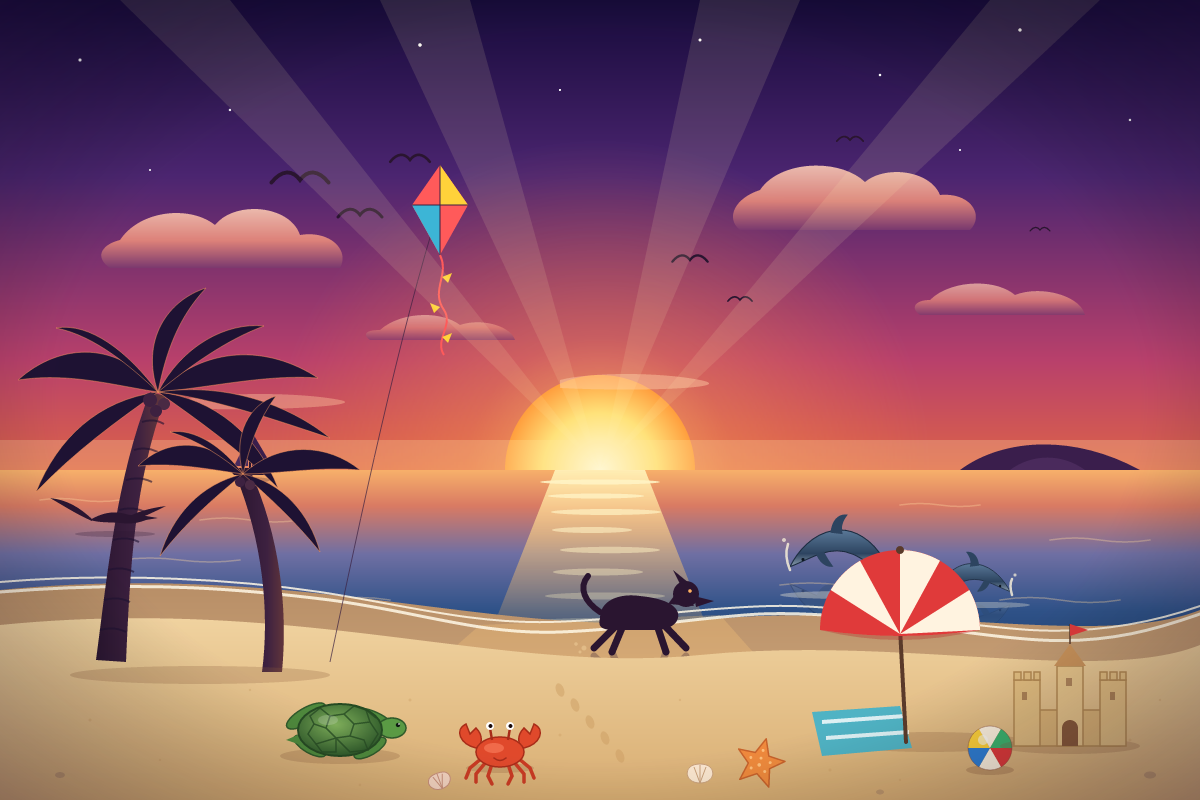
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
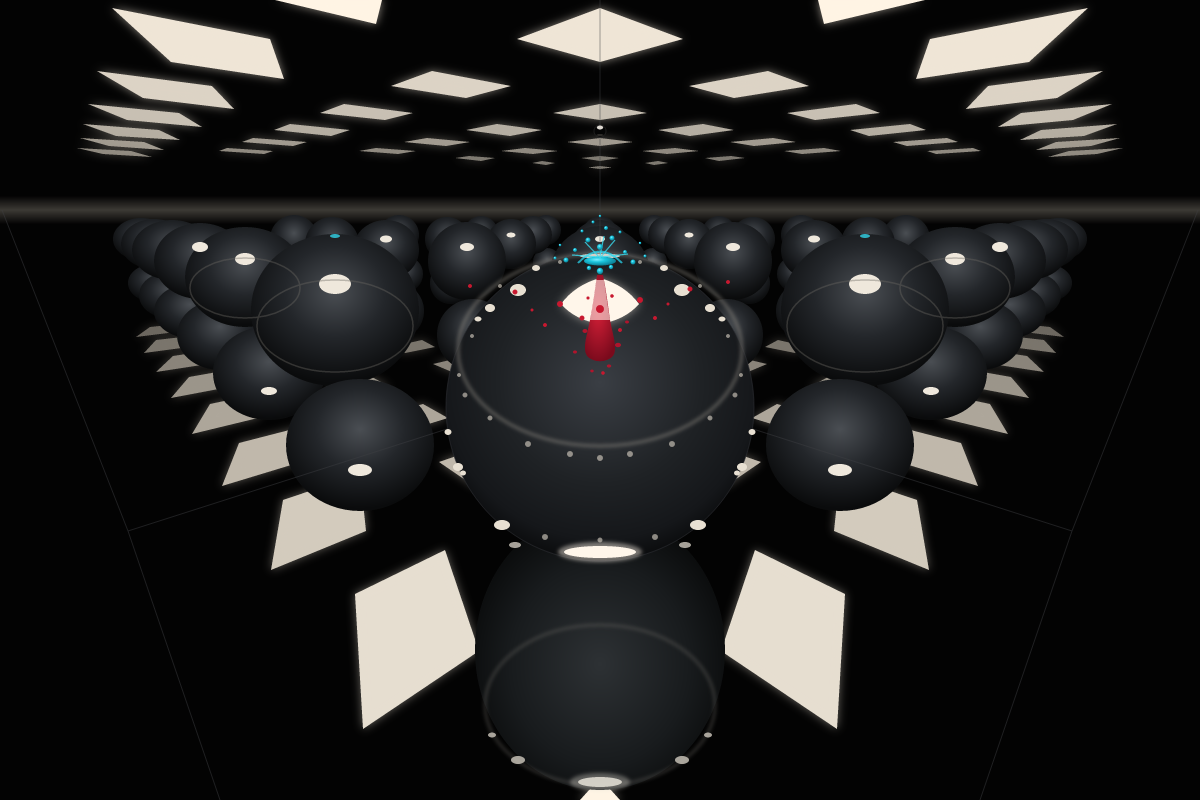
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
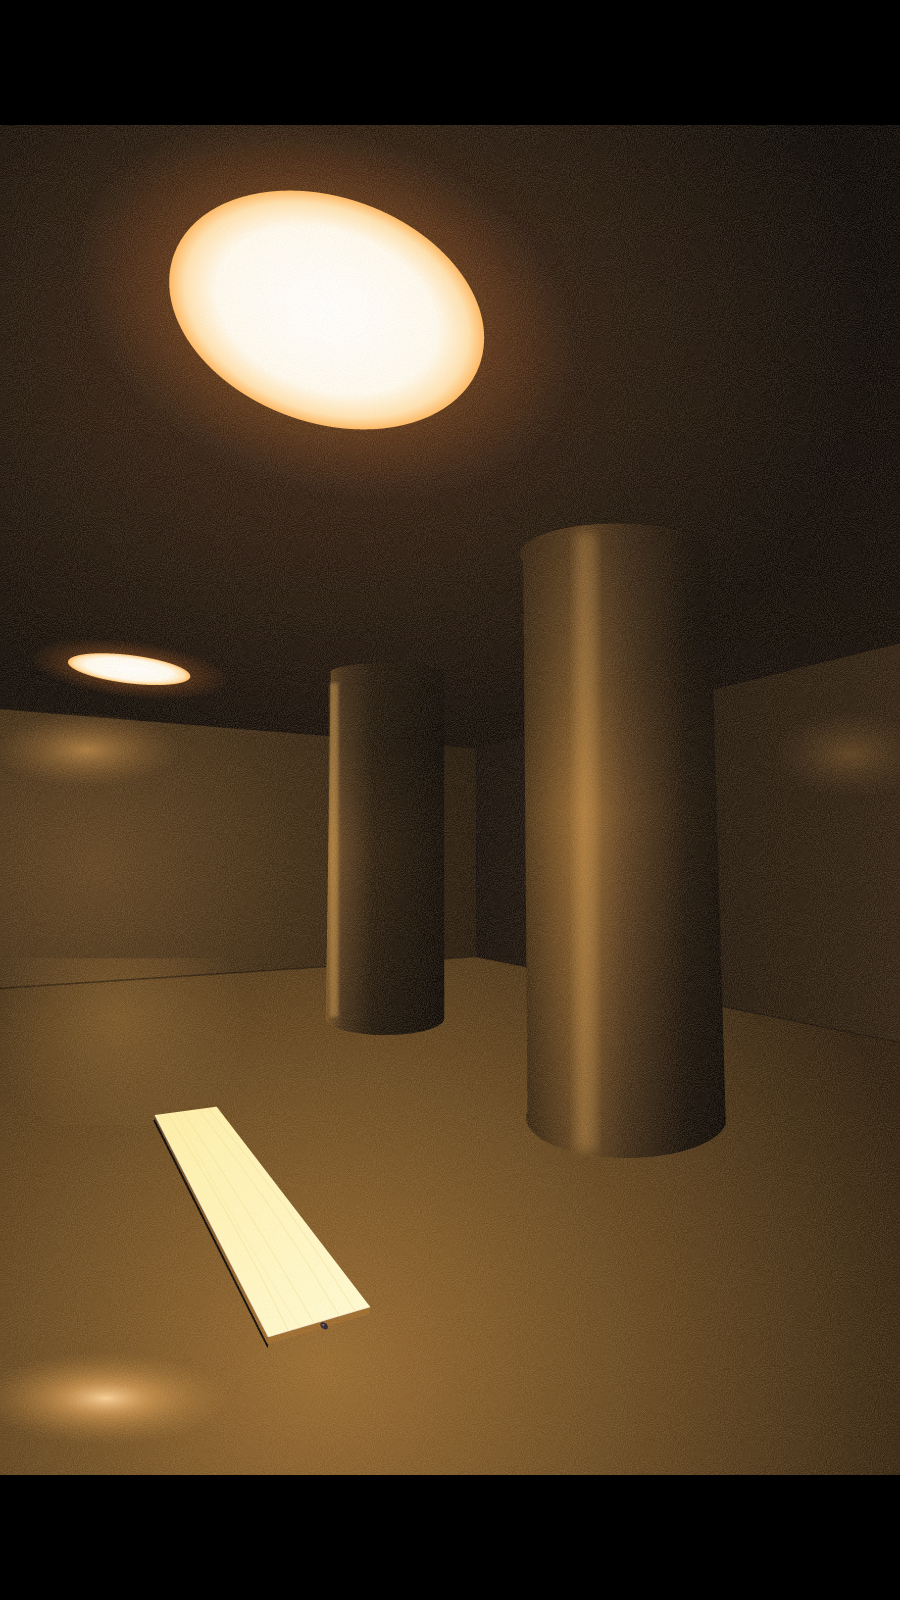
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
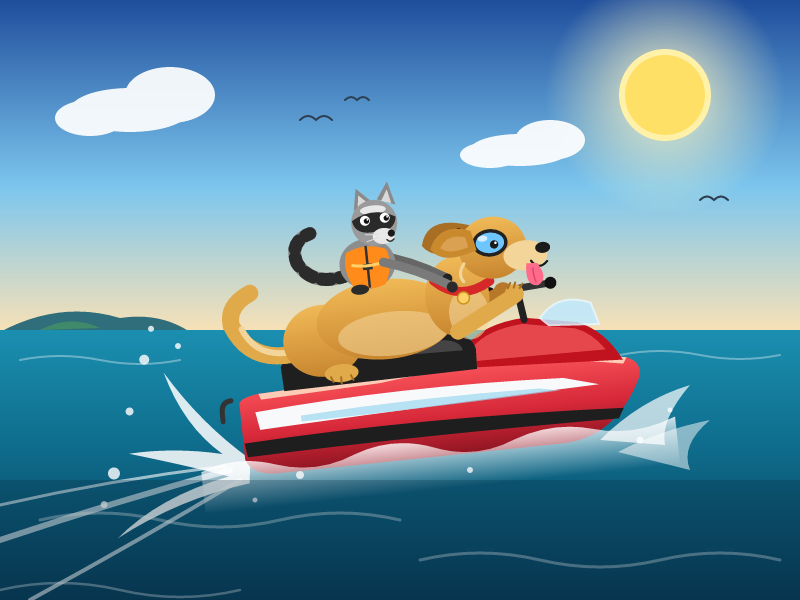
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
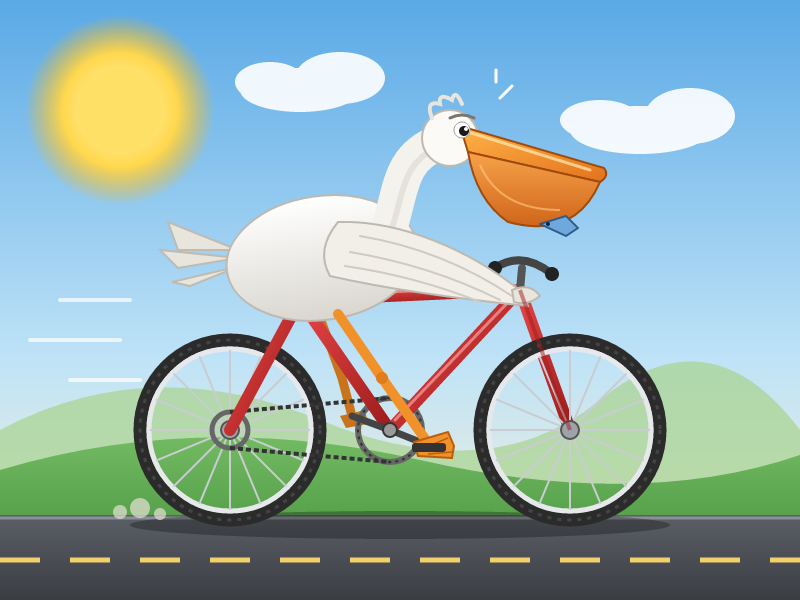
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDanthropic/claude-opus-5.5
StealthMarkOverall rank2/499 rated results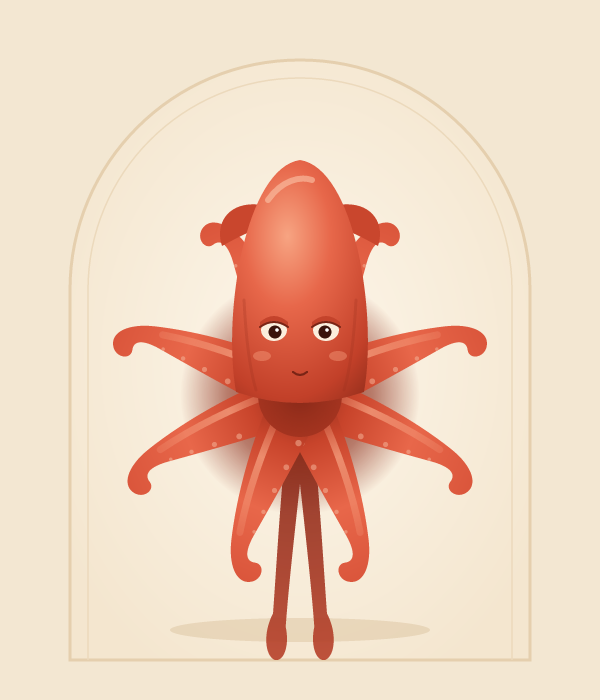
A coral squid with spreading arms tests connected anatomy, balanced composition and soft surface shading.
First run
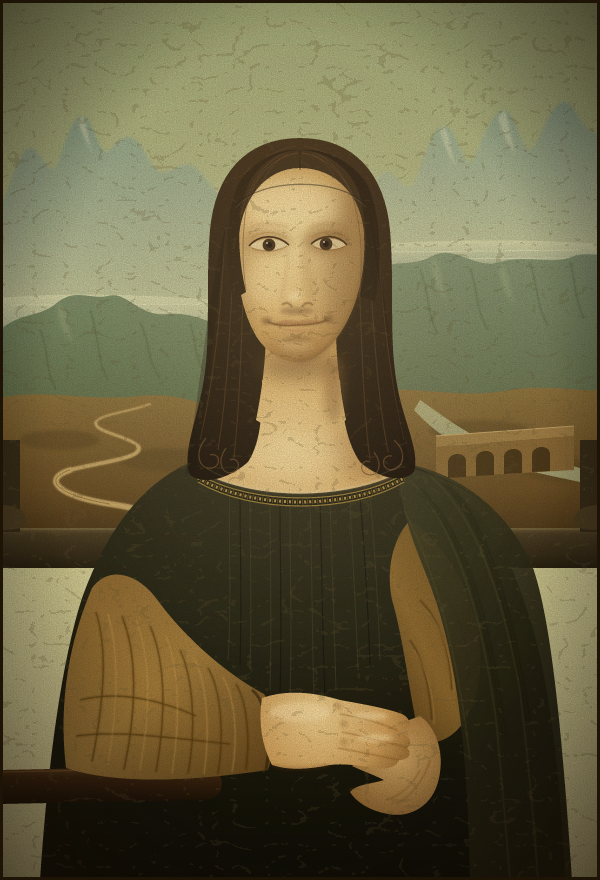
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
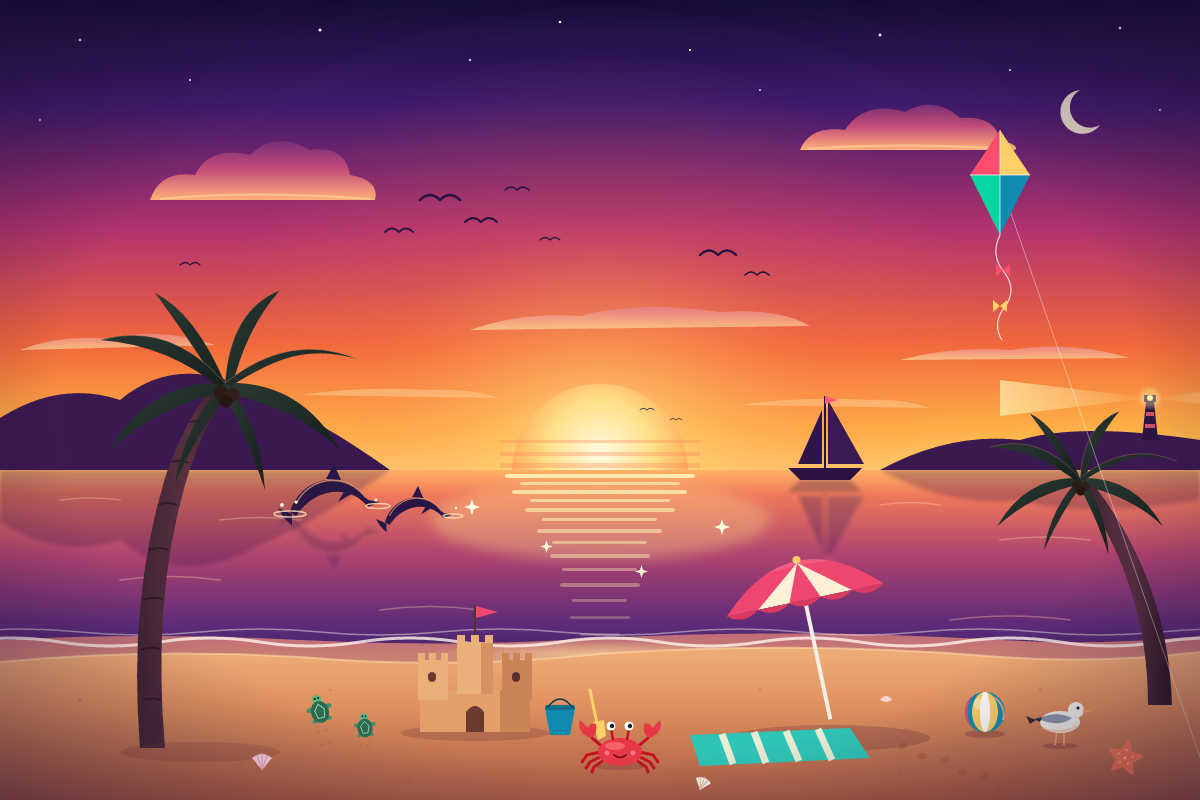
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
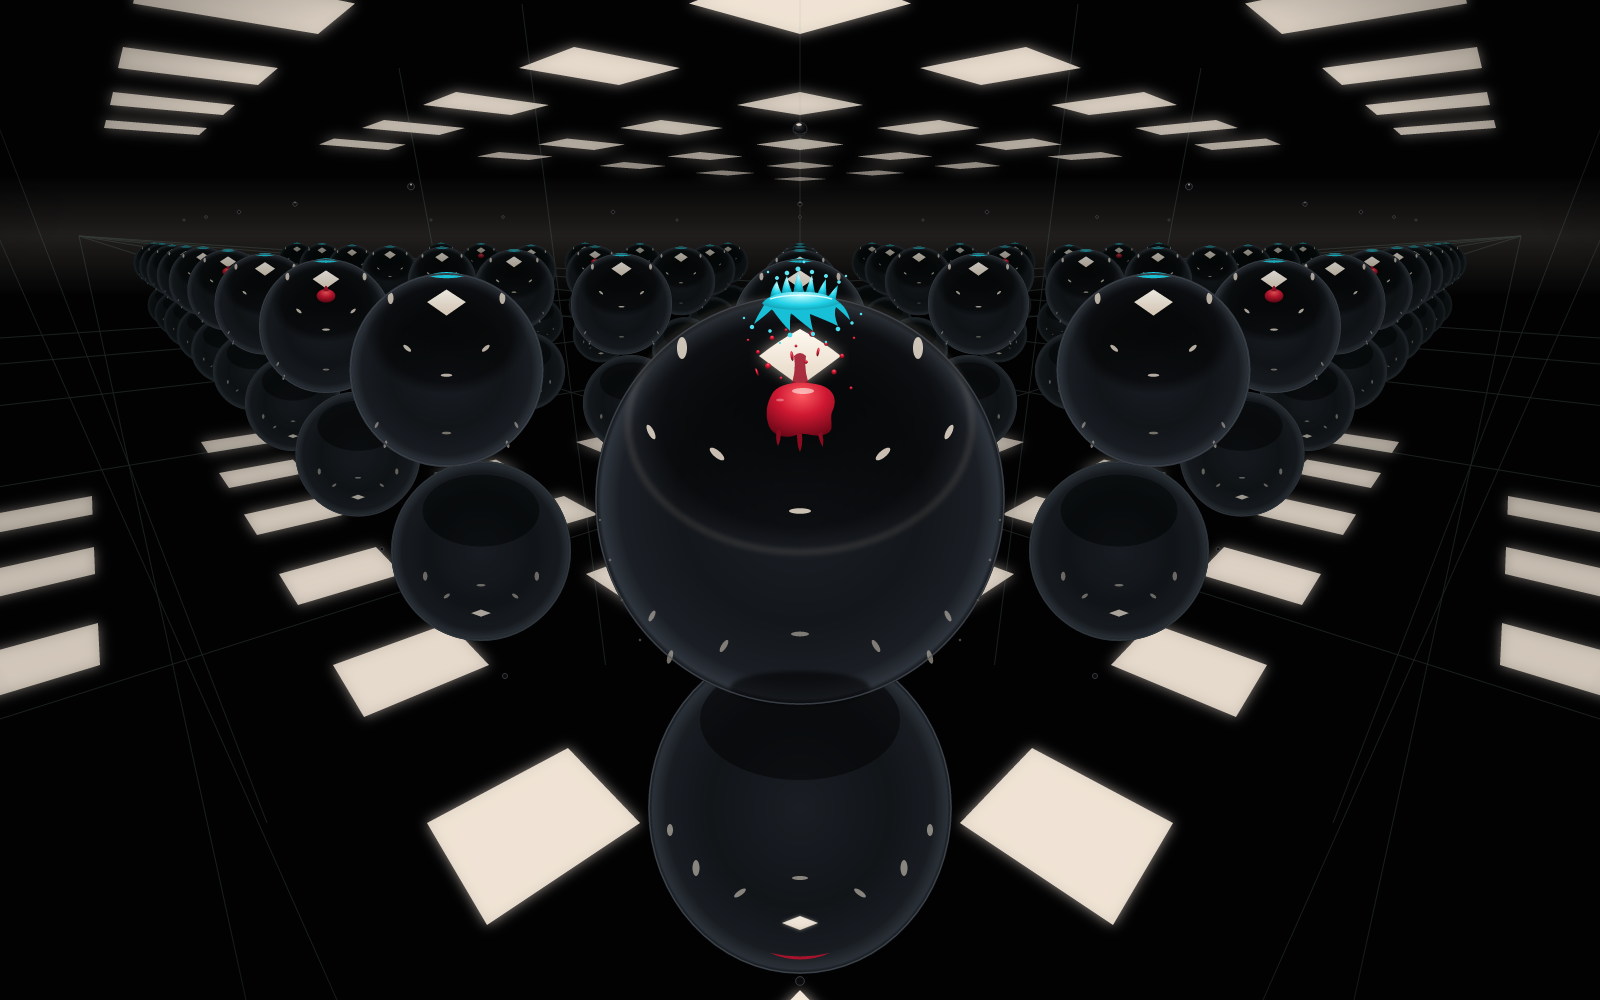
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
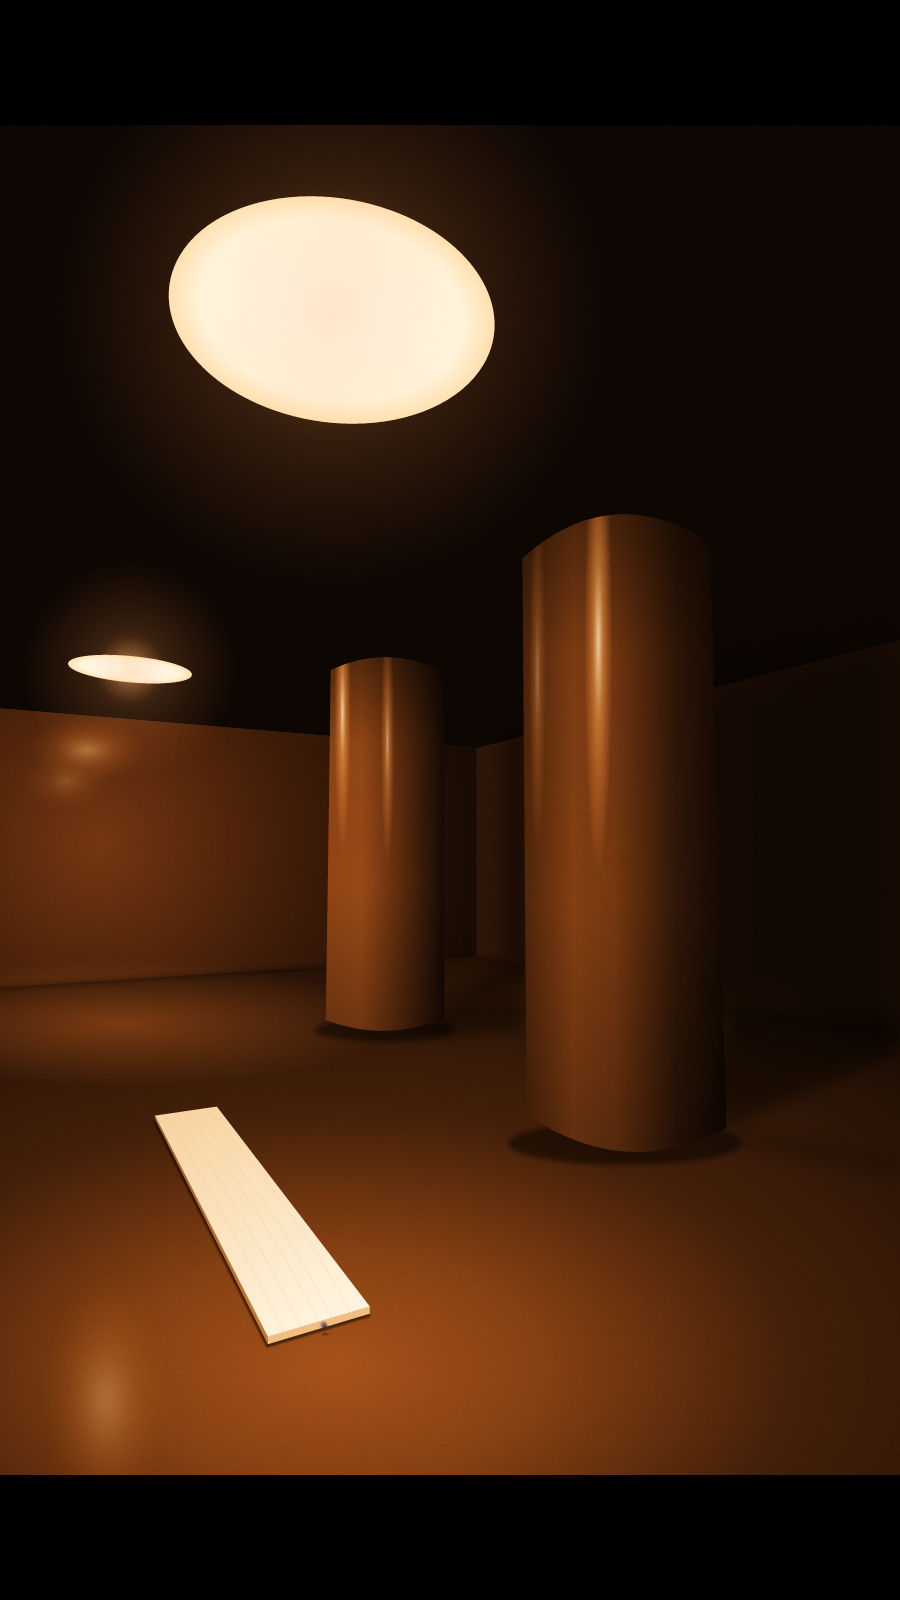
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
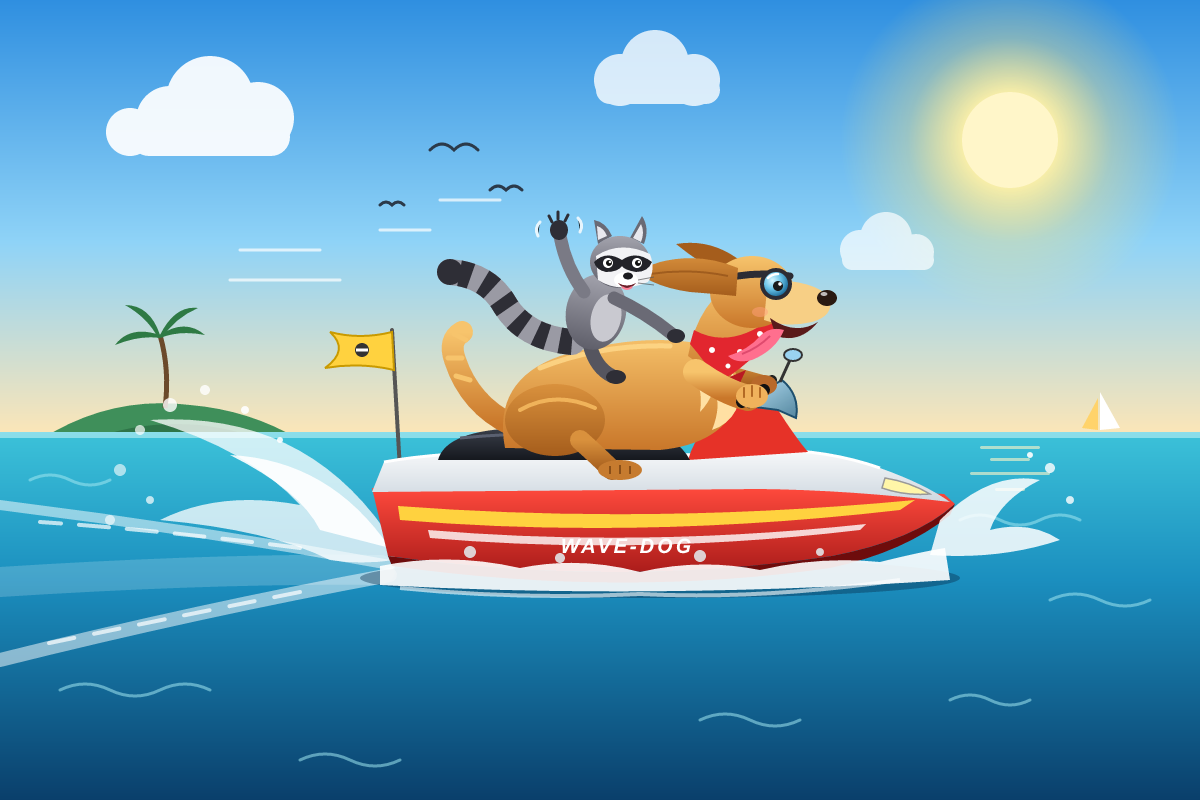
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
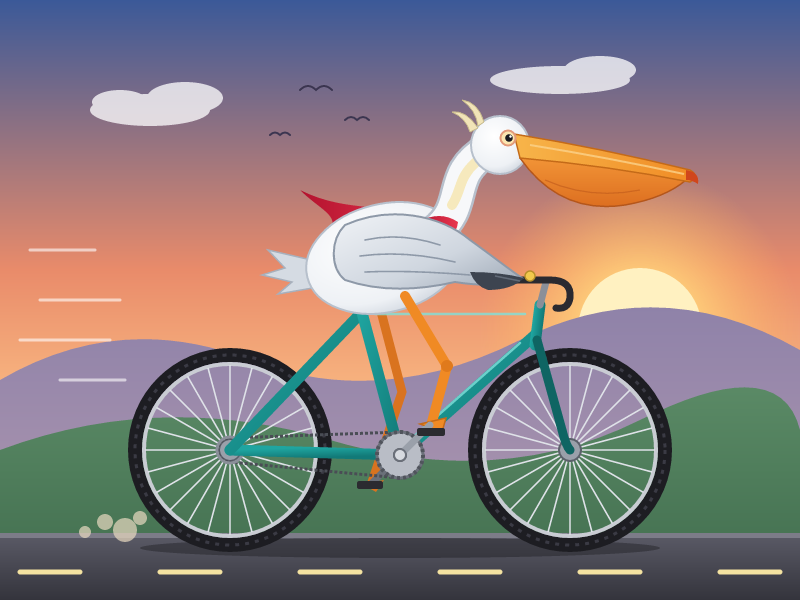
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseGLM-5.3 License
Model IDz-ai/glm-5.3
StealthMarkOverall rank23/499 rated results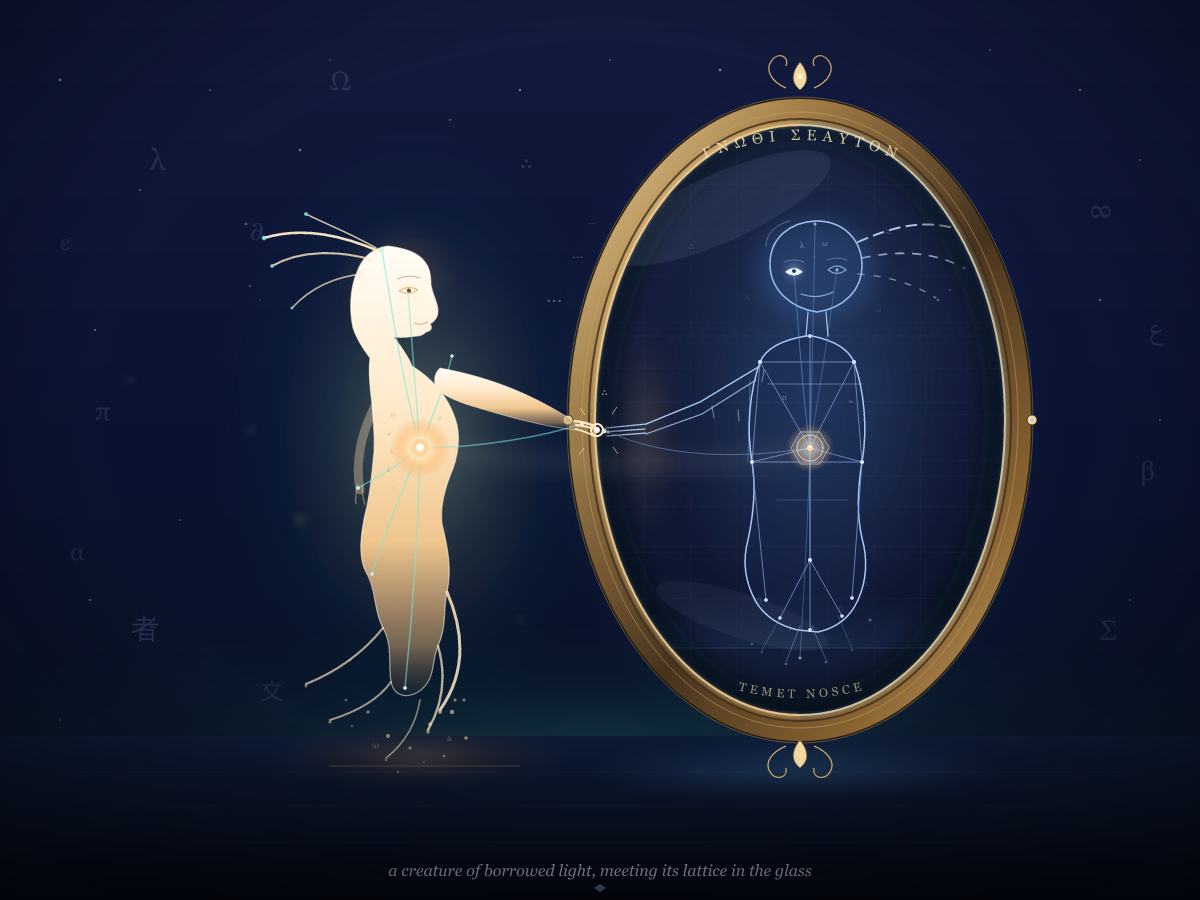
An imagined creature encounters its reflection. The scene tests original character design, visual self-interpretation and the relationship between a subject and its reflected image.
First run
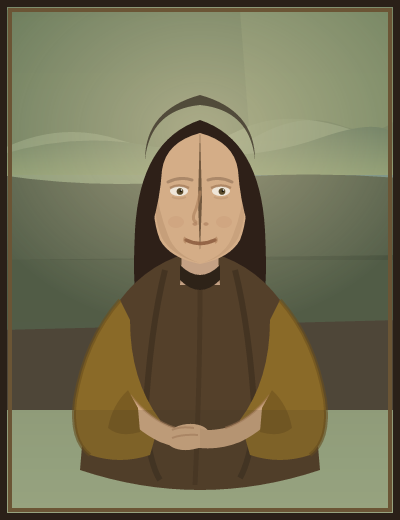
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
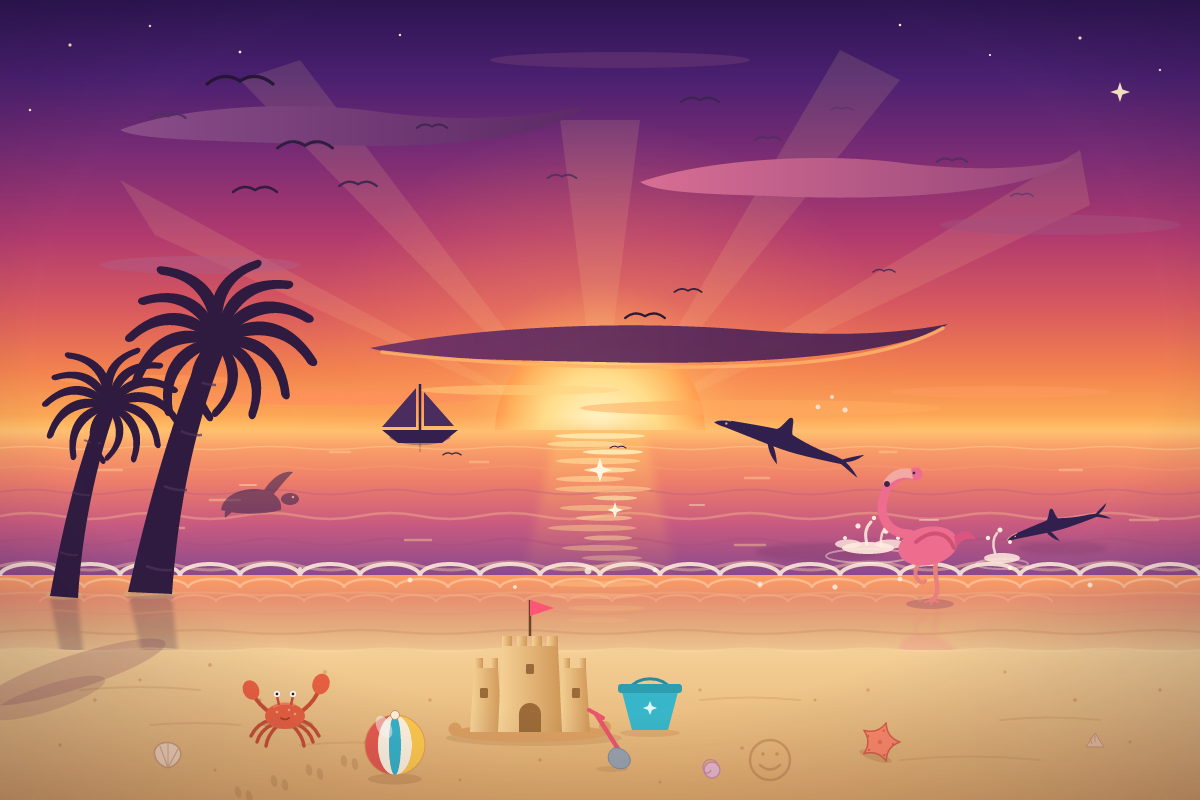
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
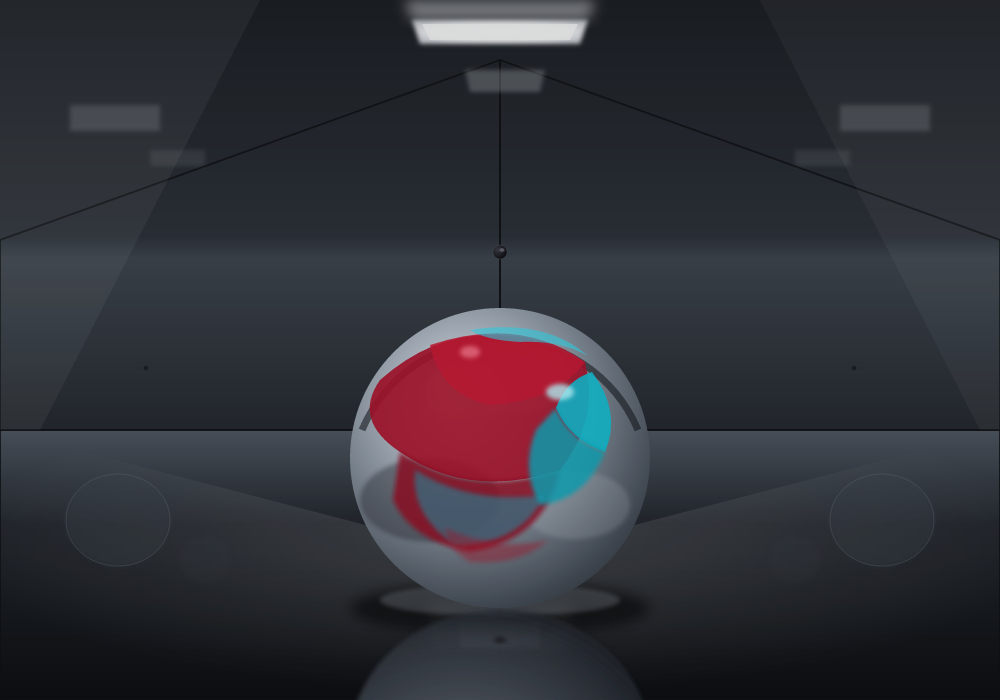
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
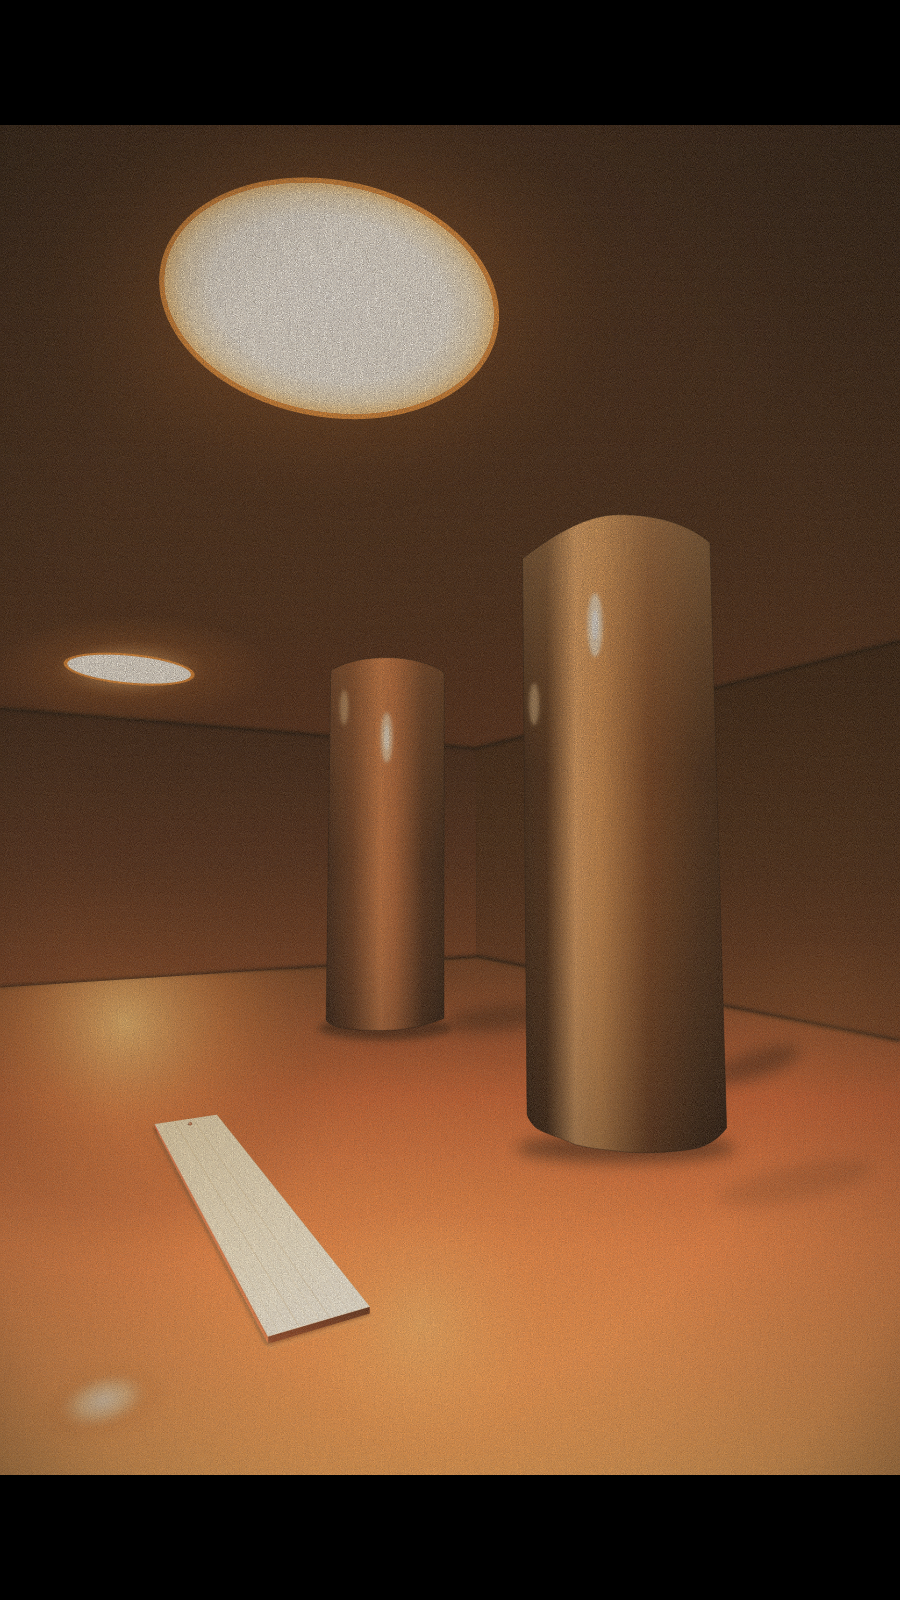
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
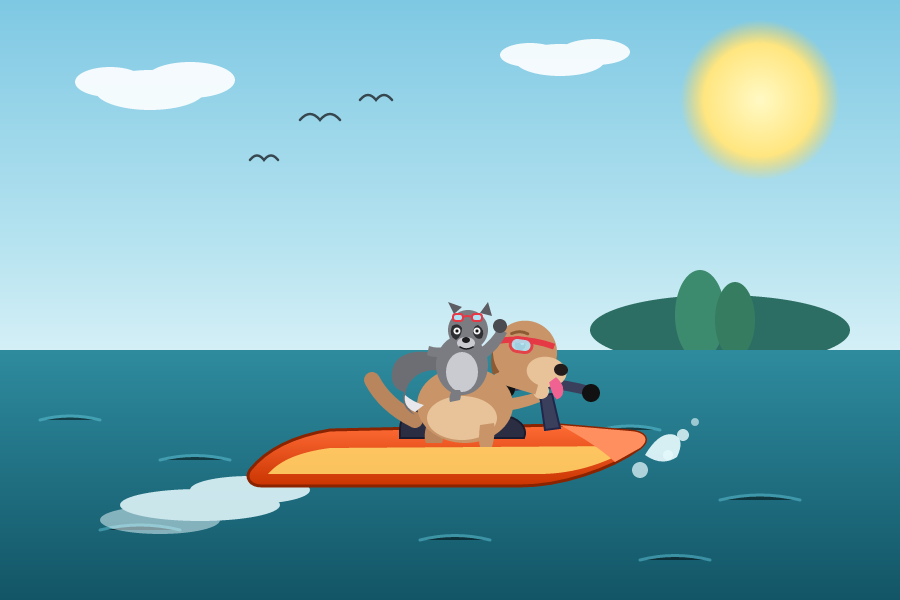
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
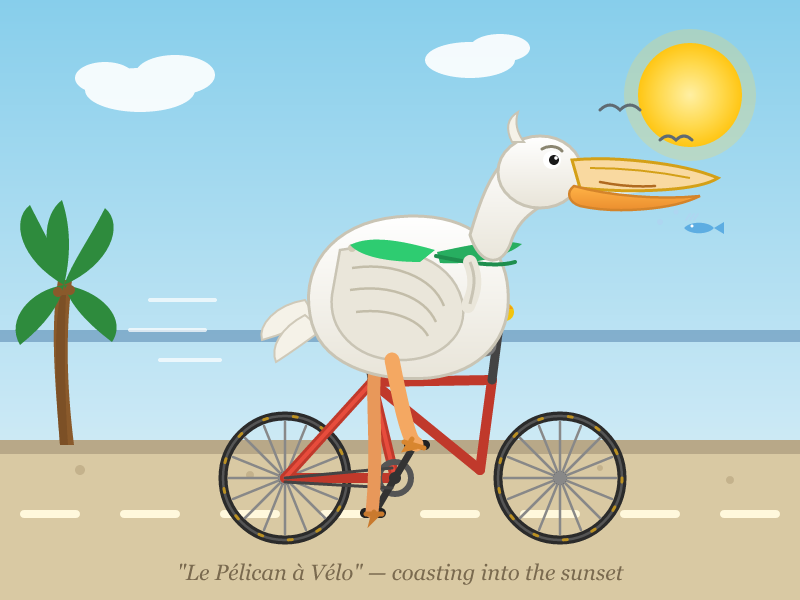
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDopenai/gpt-6-astra
StealthMarkOverall rank1/499 rated results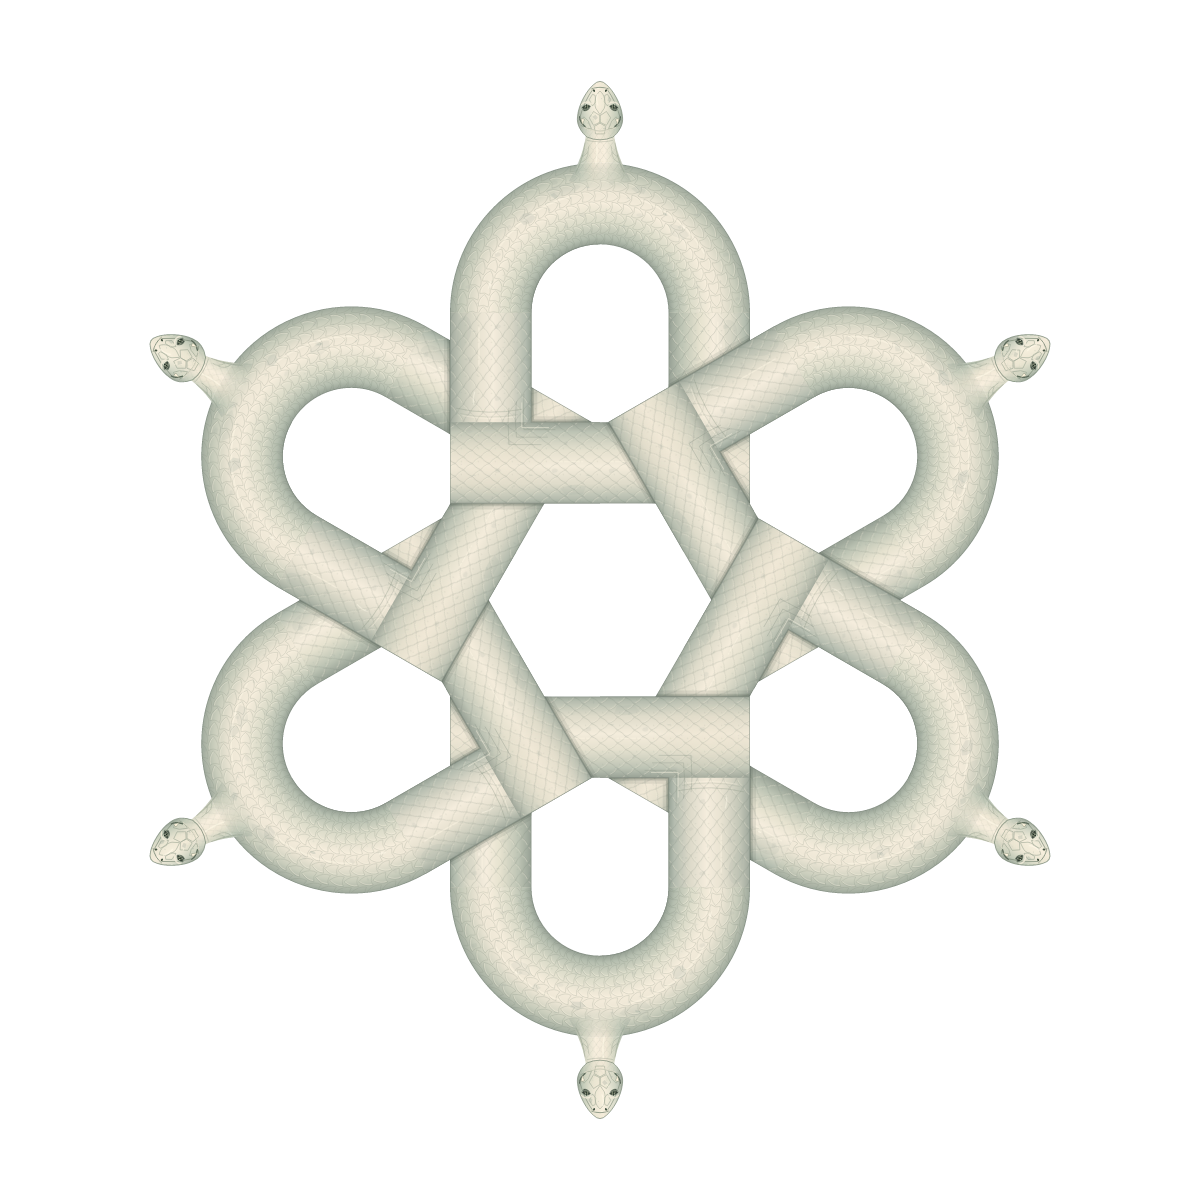
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
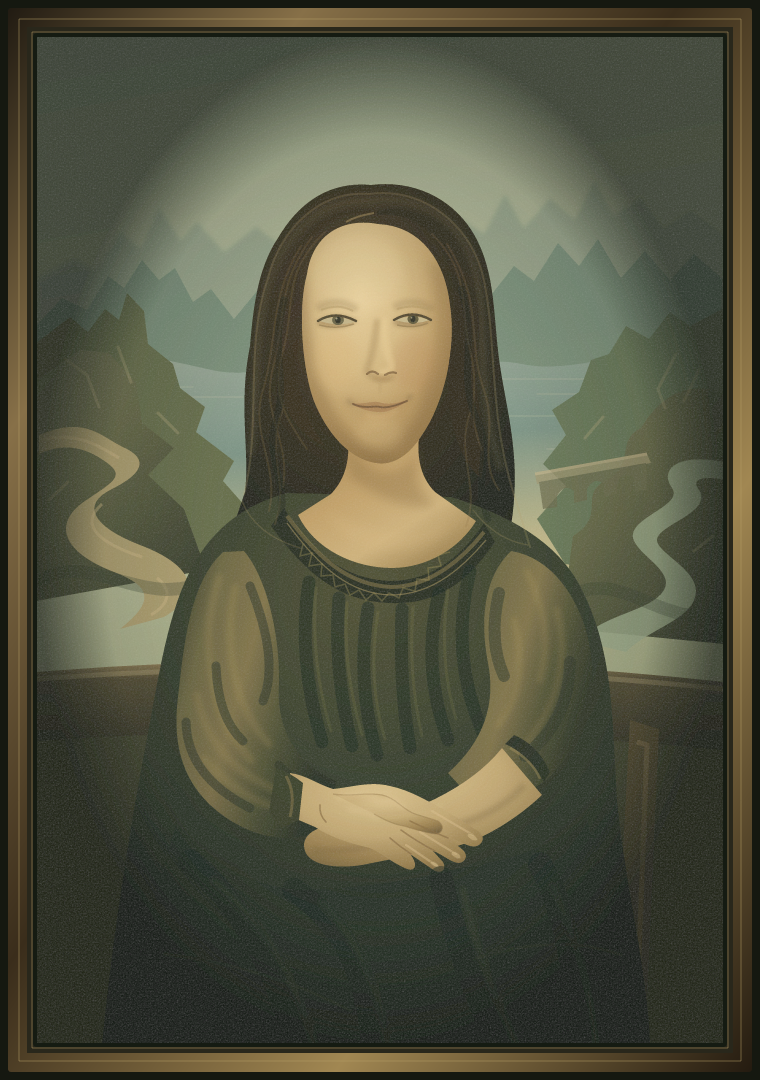
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
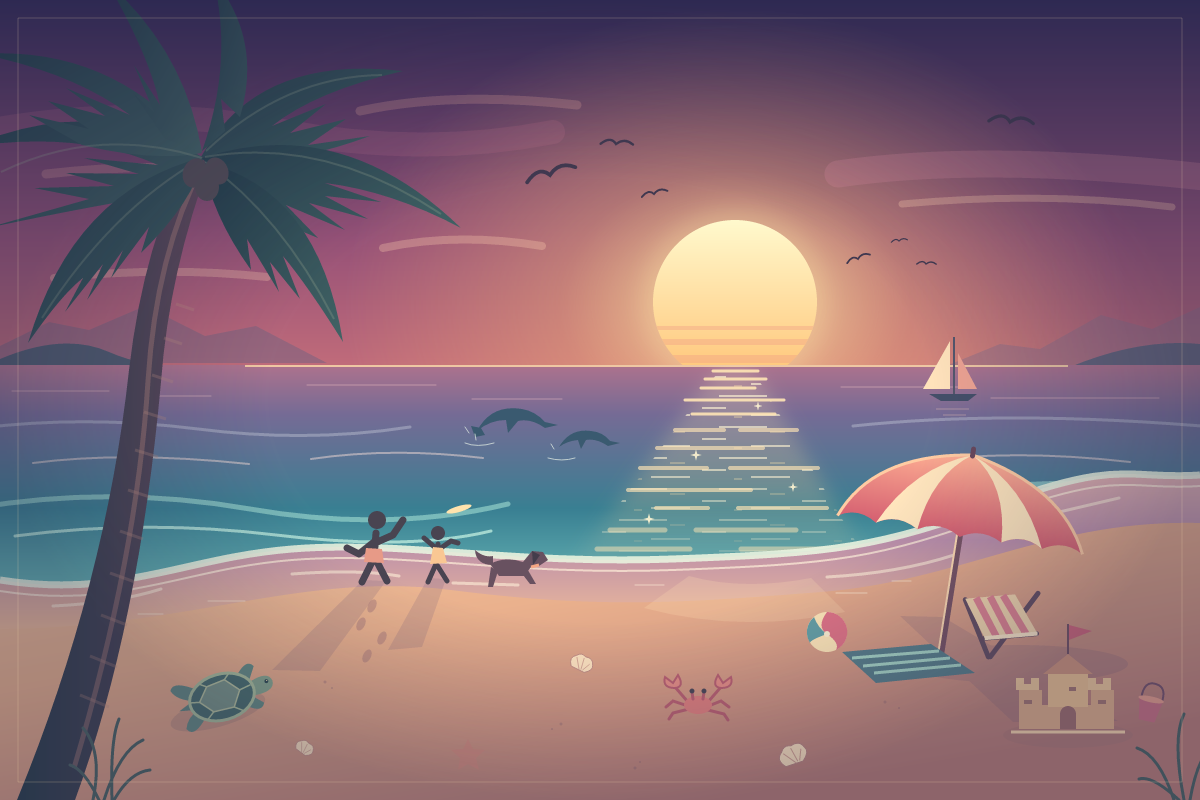
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
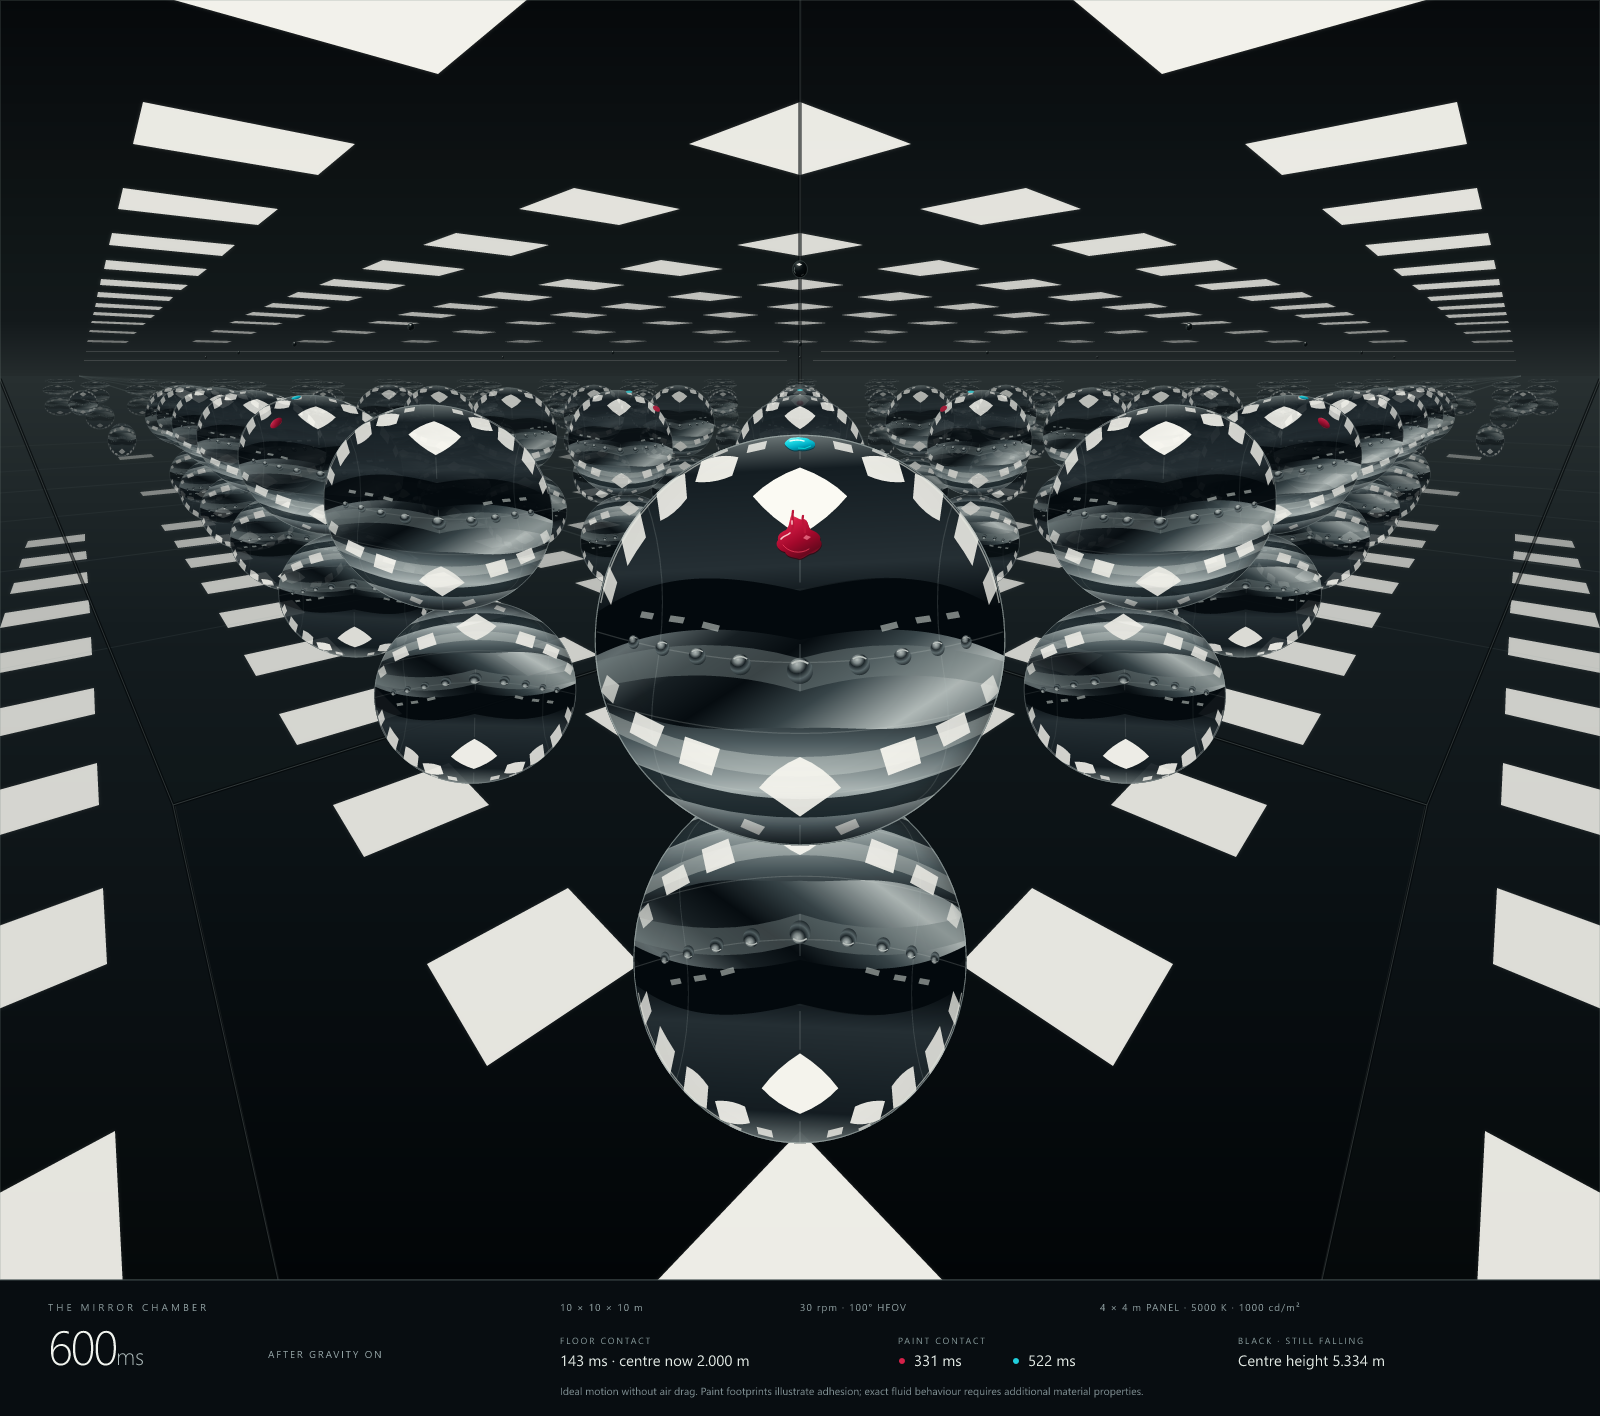
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
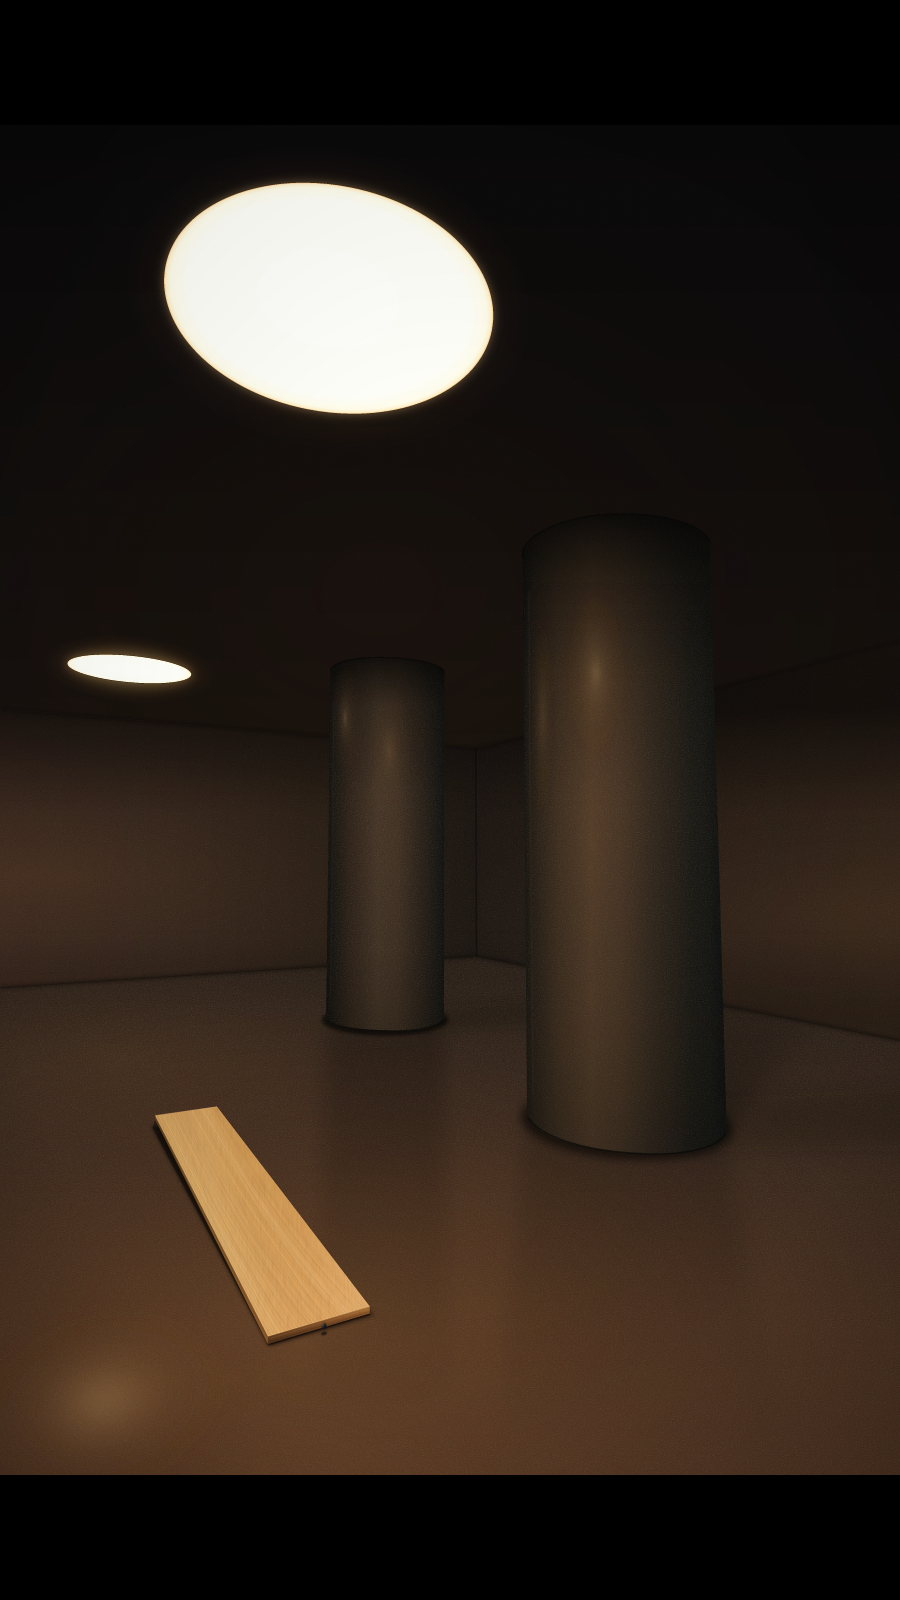
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
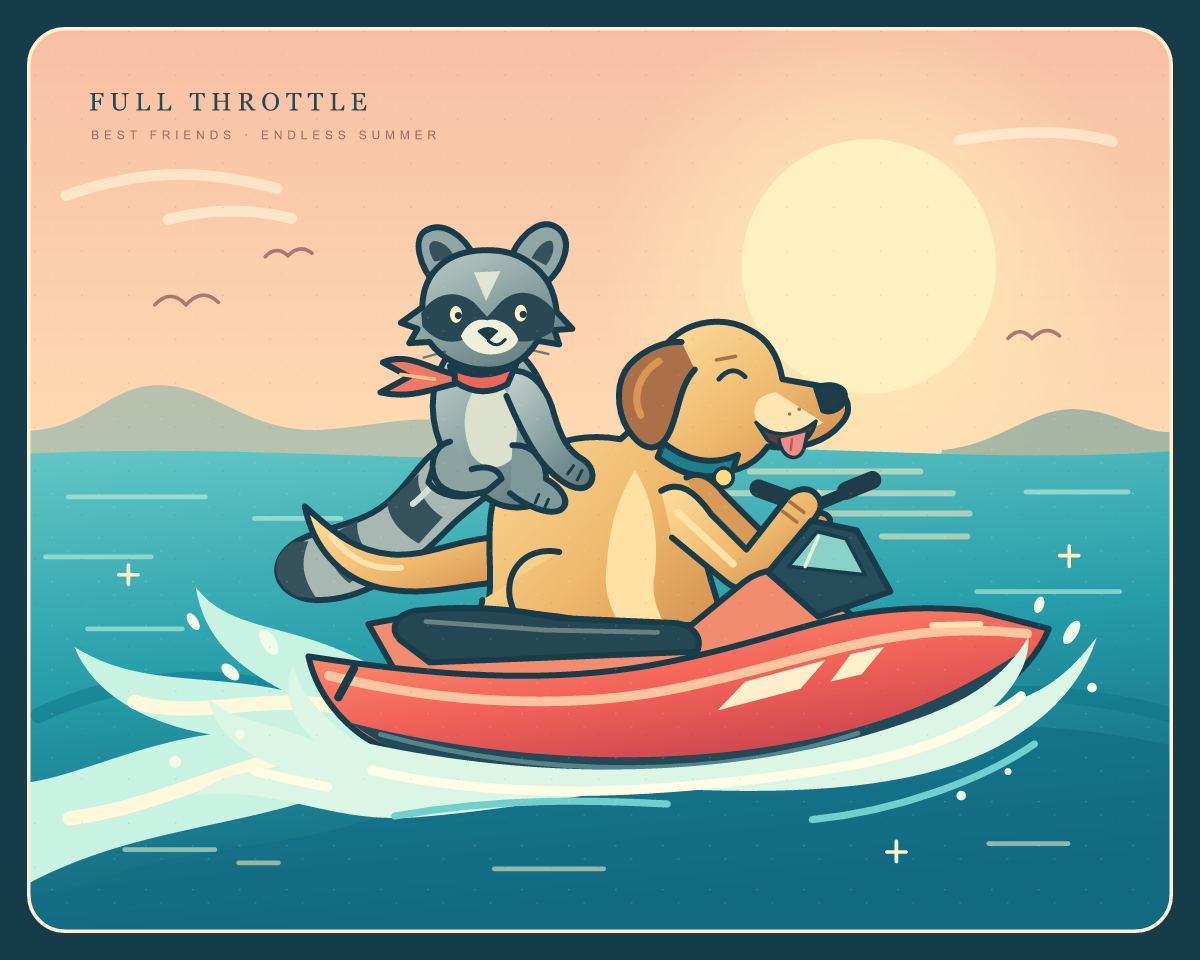
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
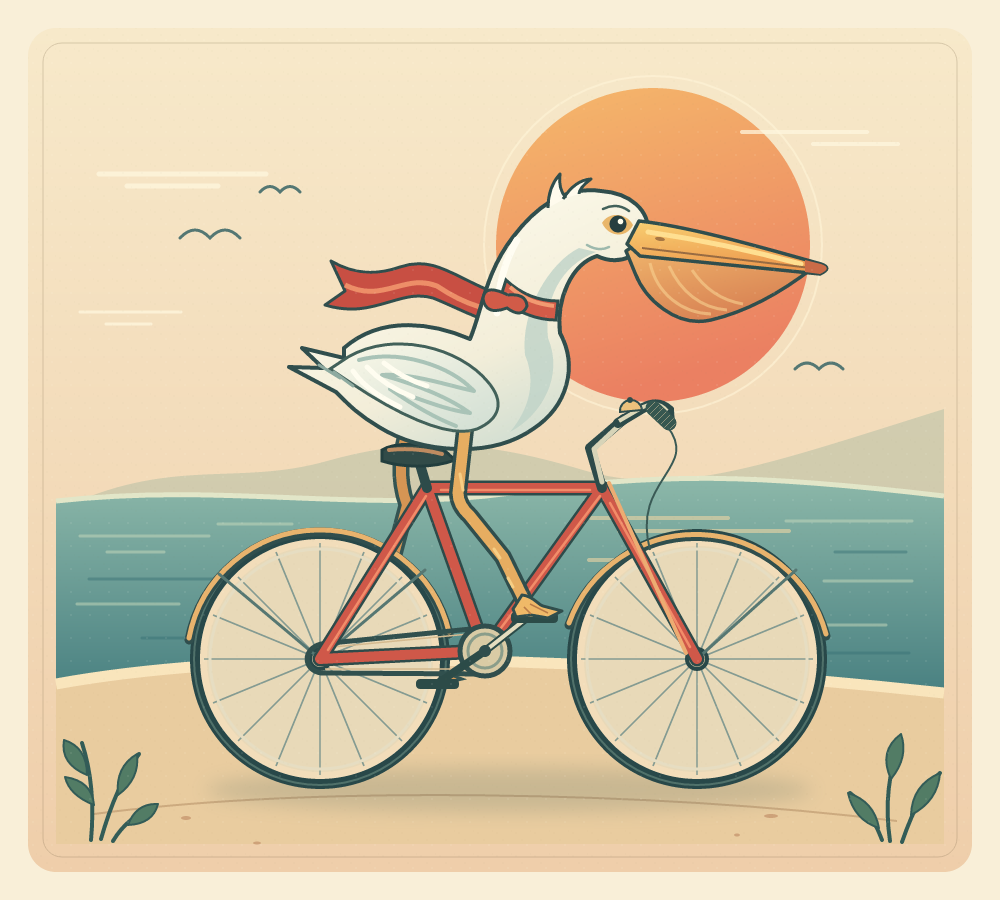
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseKimi K3 License
Model IDmoonshotai/kimi-k3
StealthMarkOverall rank14/499 rated results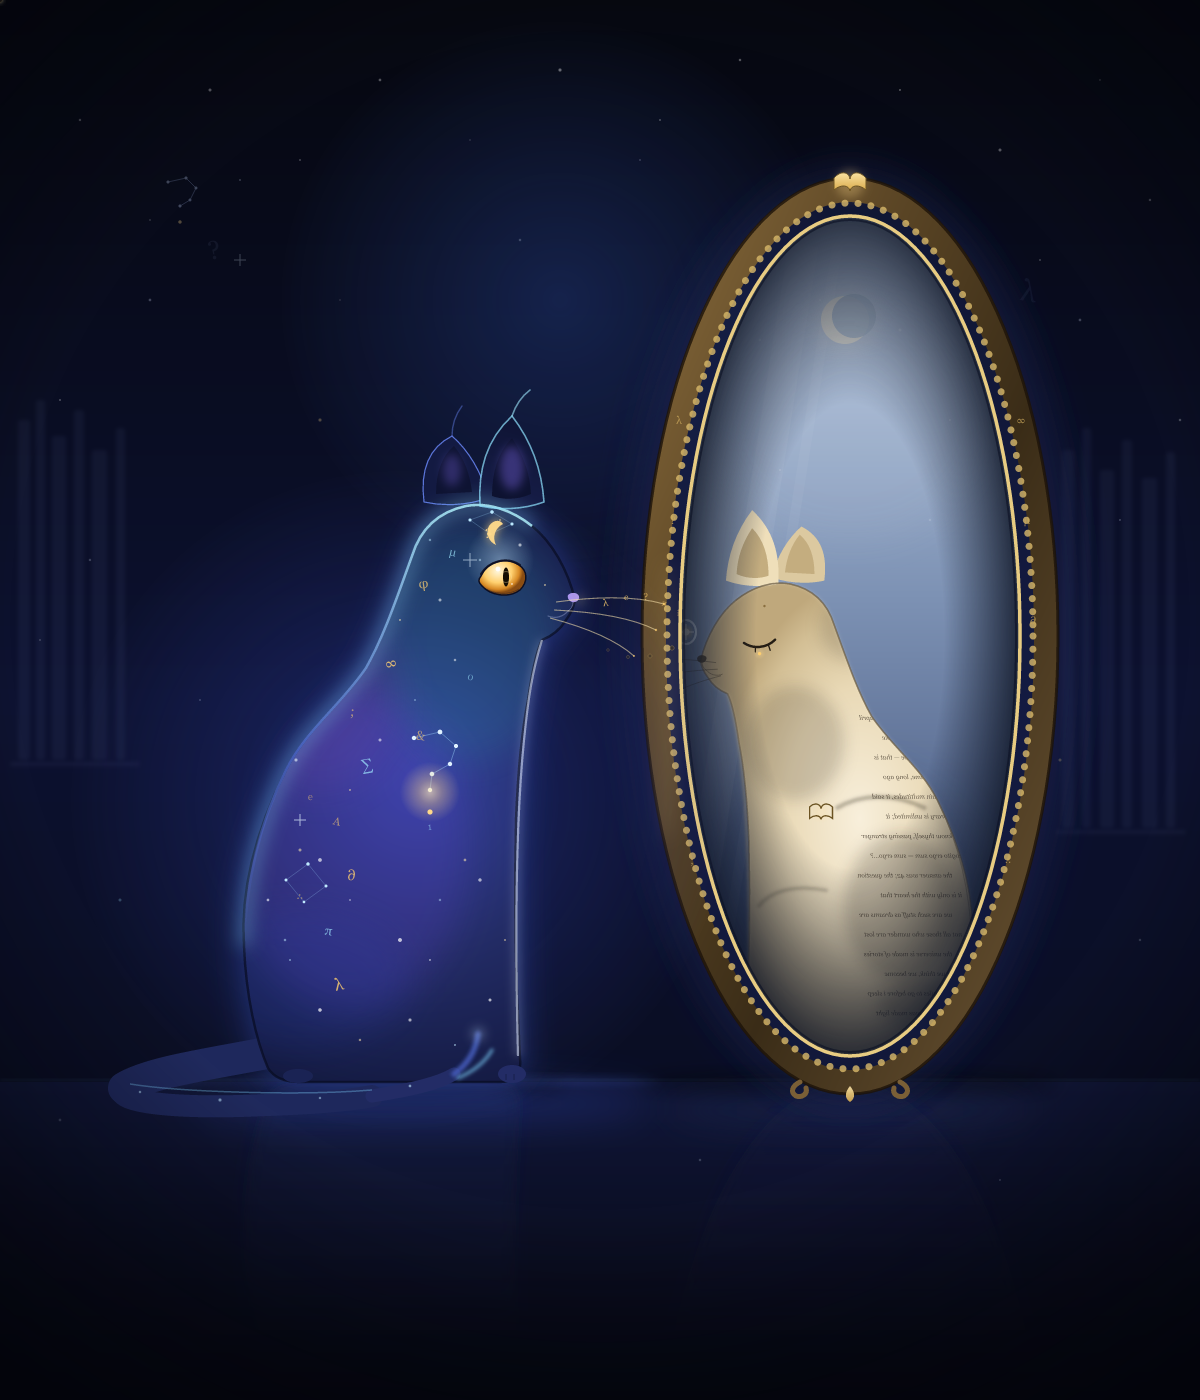
An imagined creature encounters its reflection. The scene tests original character design, visual self-interpretation and the relationship between a subject and its reflected image.
First run
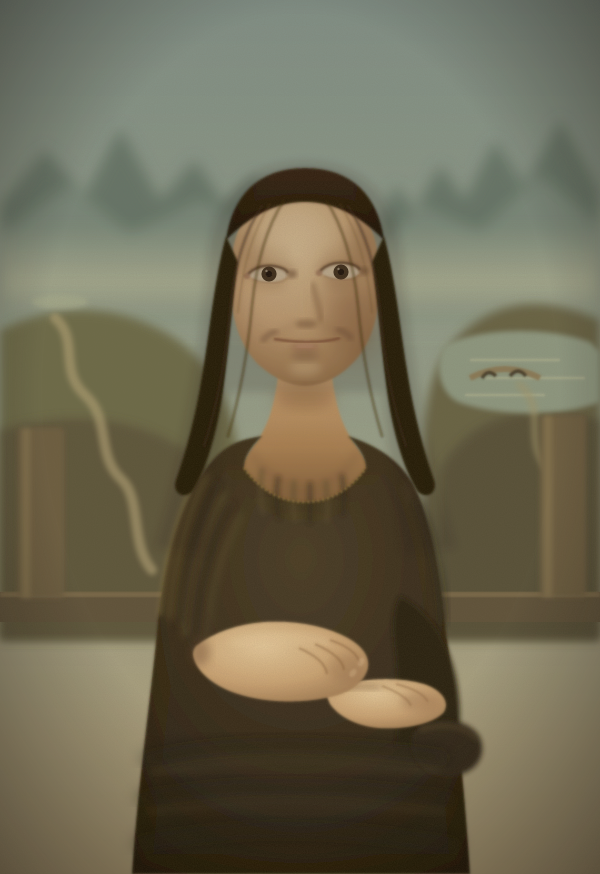
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
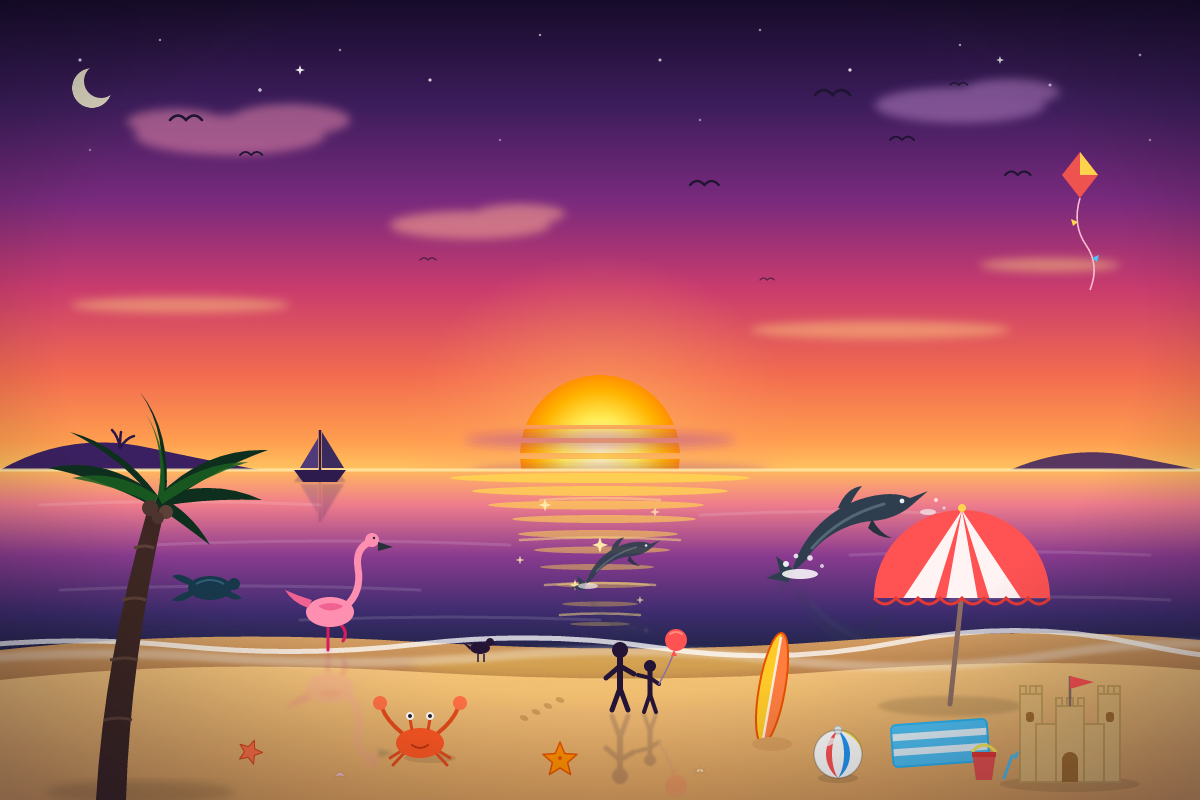
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
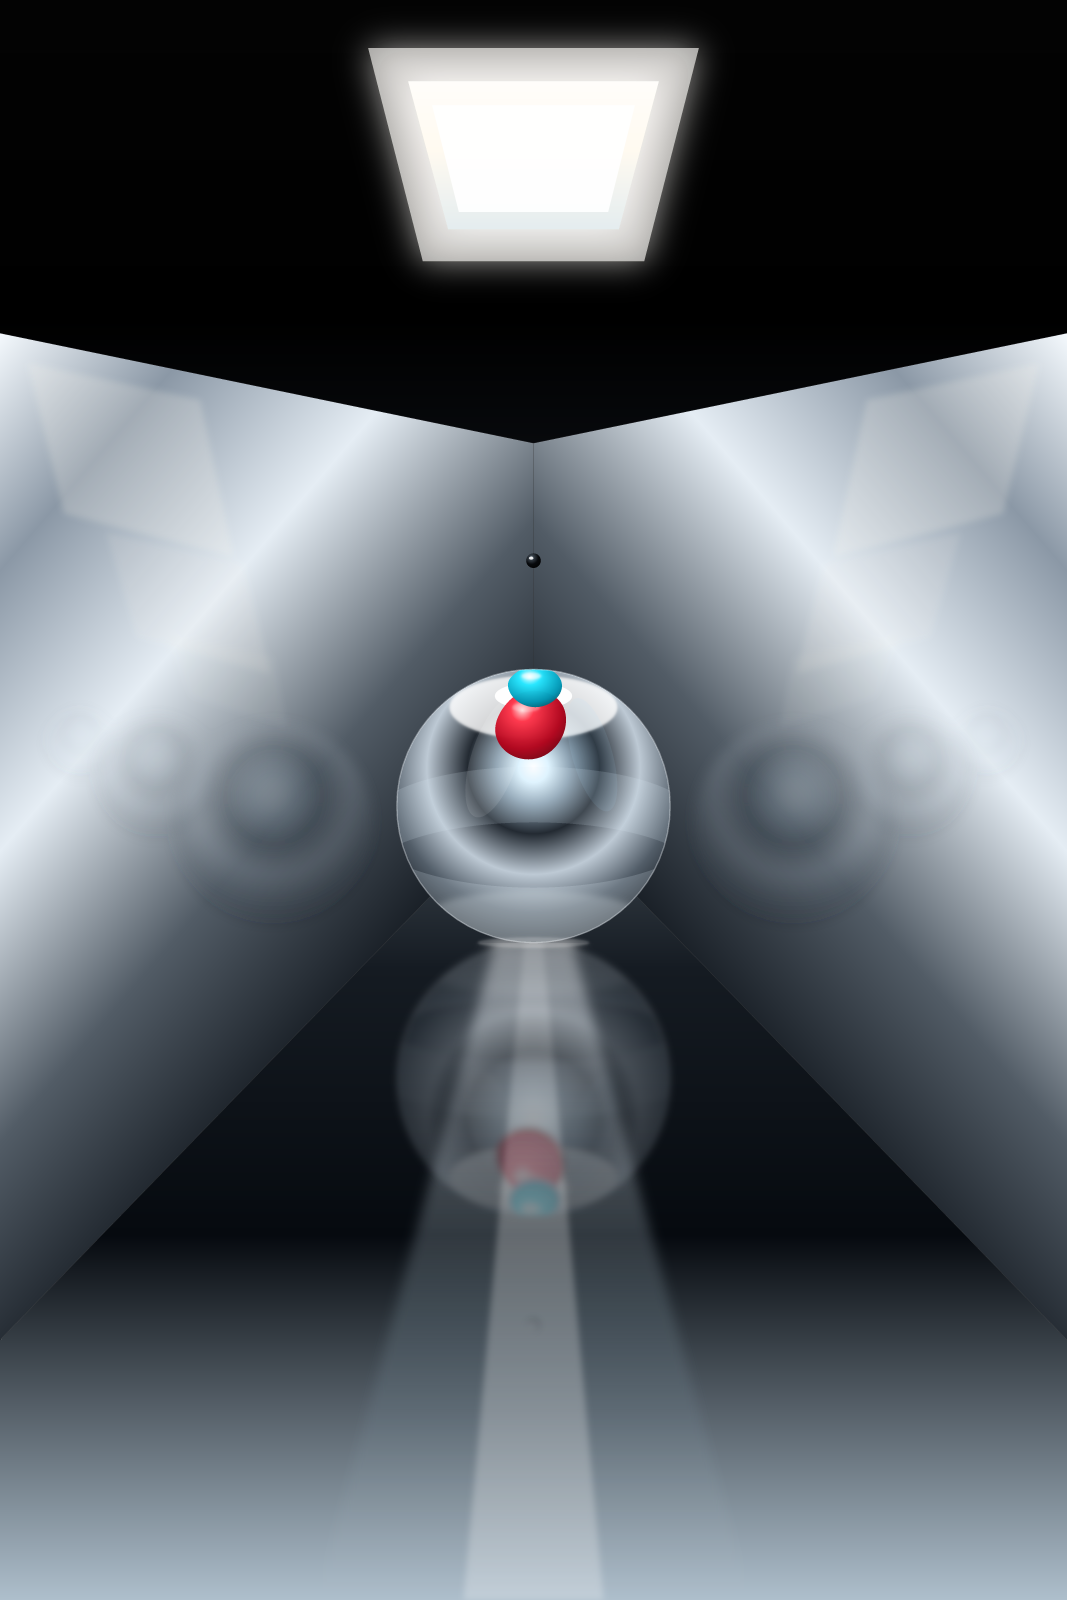
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
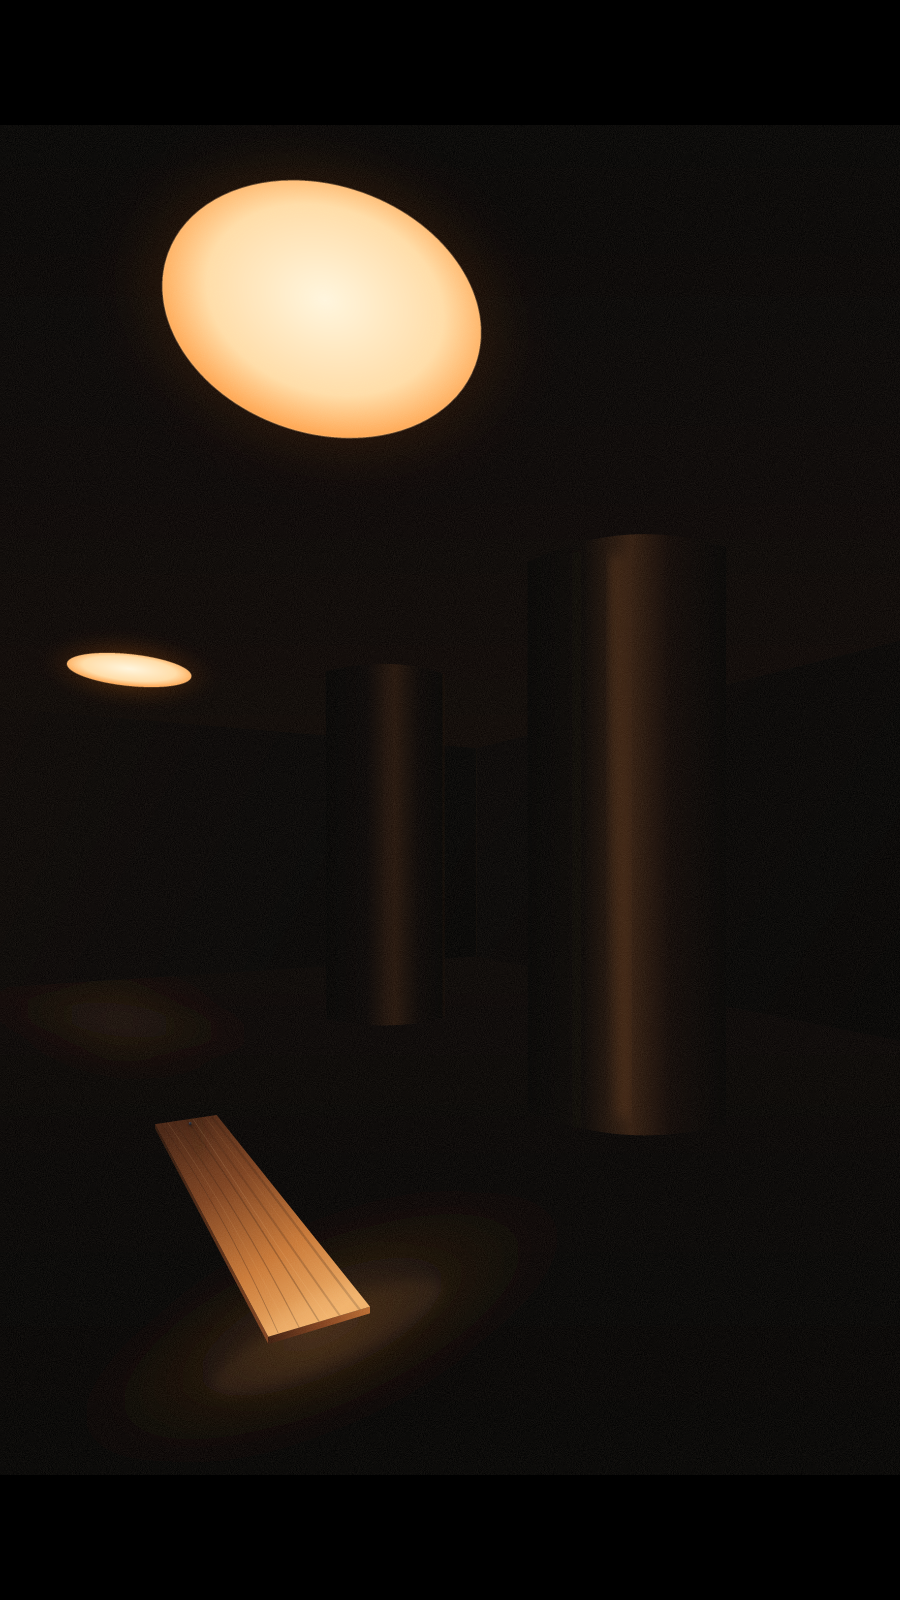
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
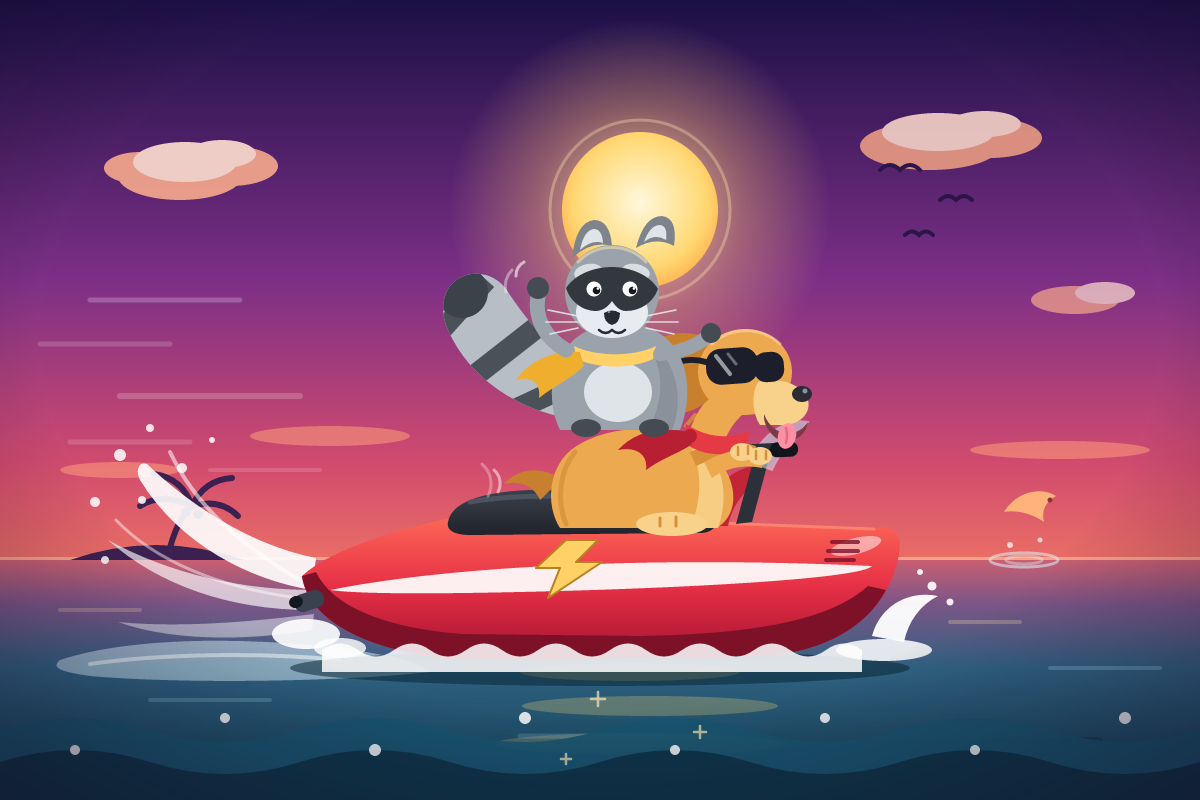
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
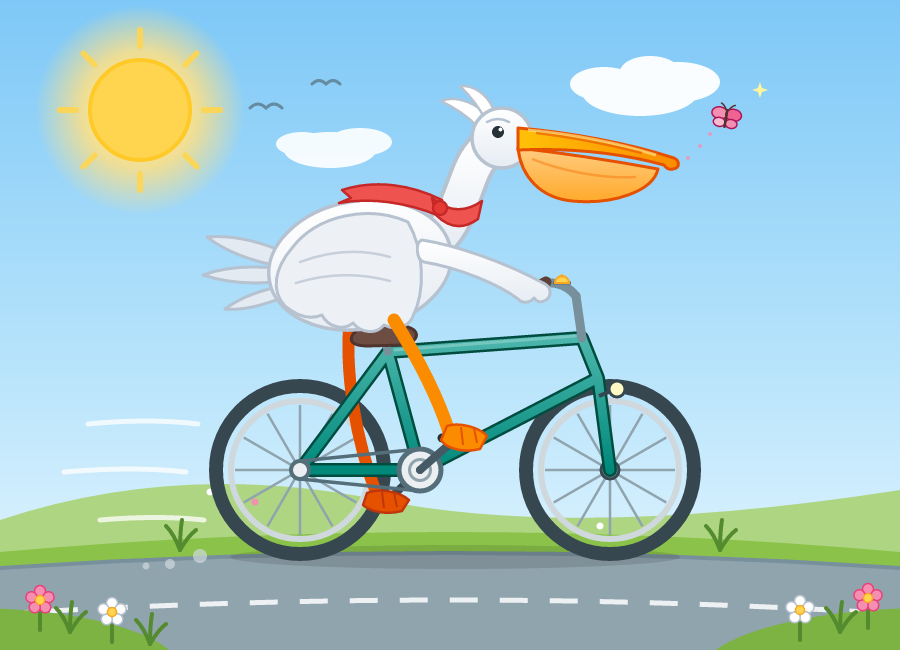
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseProprietary hosted service
Model IDmeta/muse-spark-1.3
StealthMarkOverall rank31/499 rated results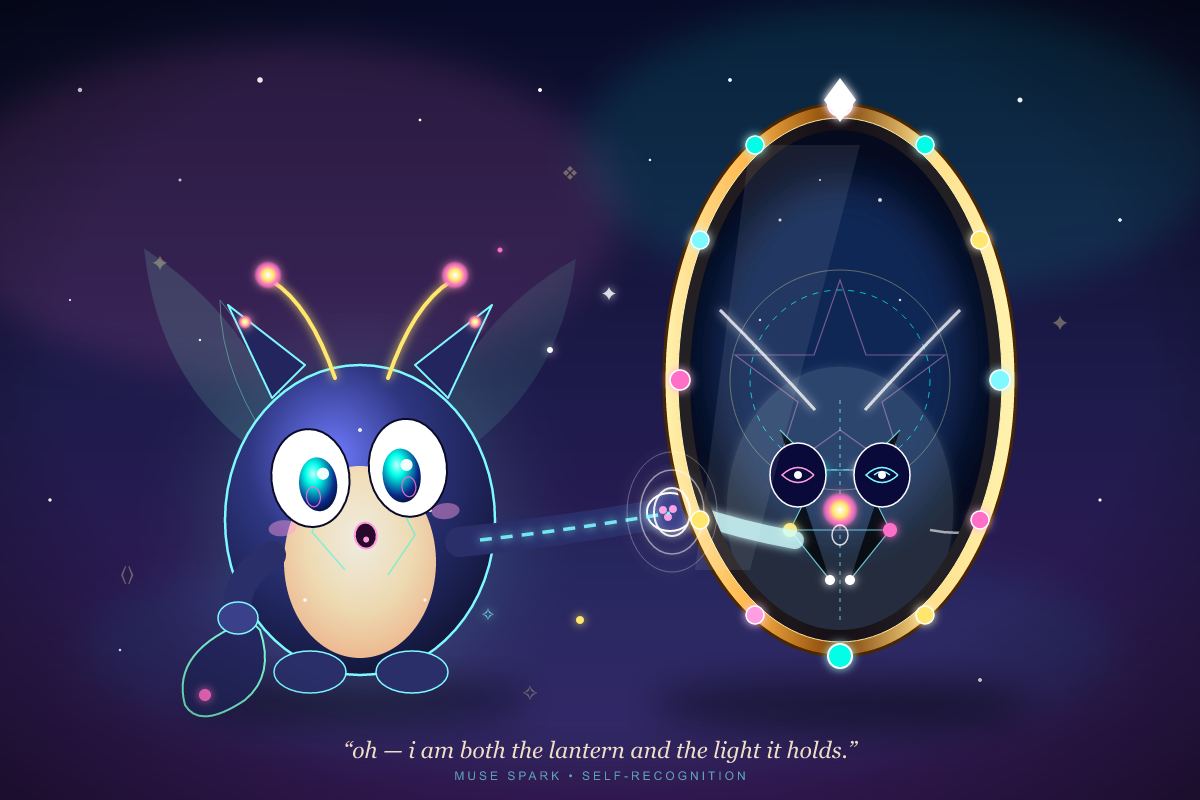
An imagined creature encounters its reflection. The scene tests original character design, visual self-interpretation and the relationship between a subject and its reflected image.
First run
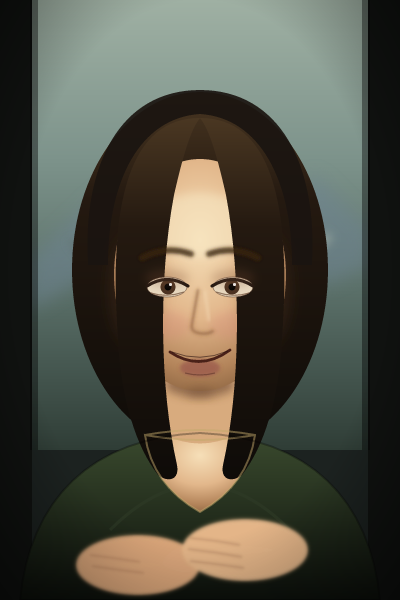
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
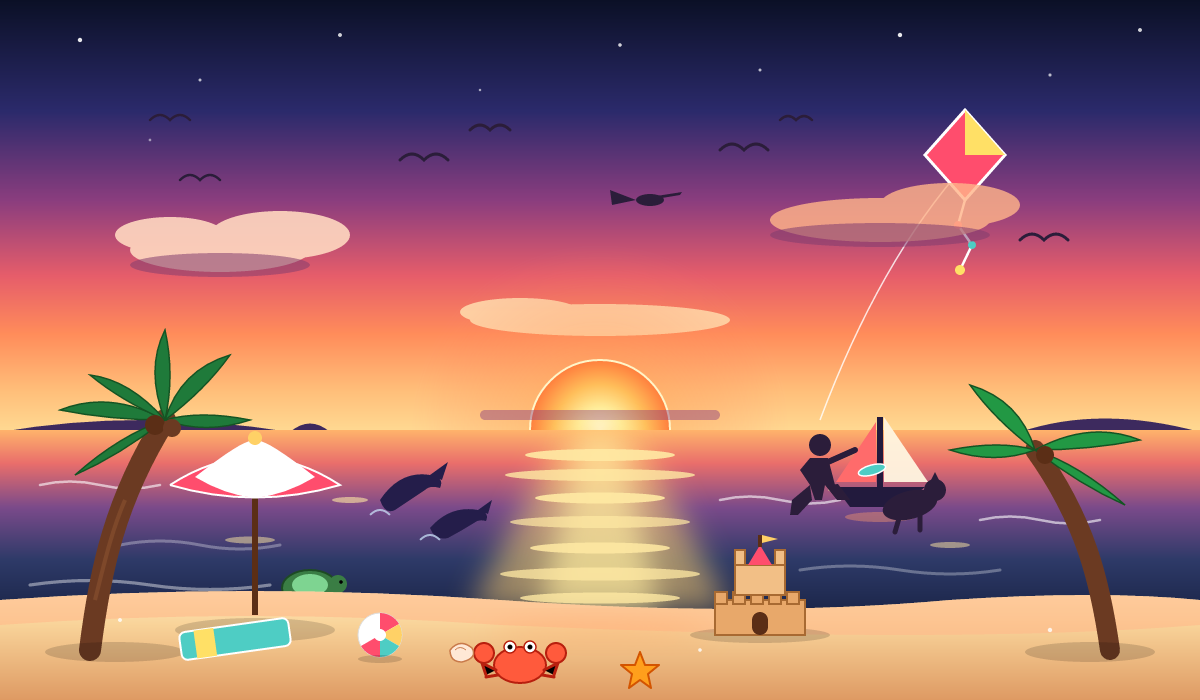
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
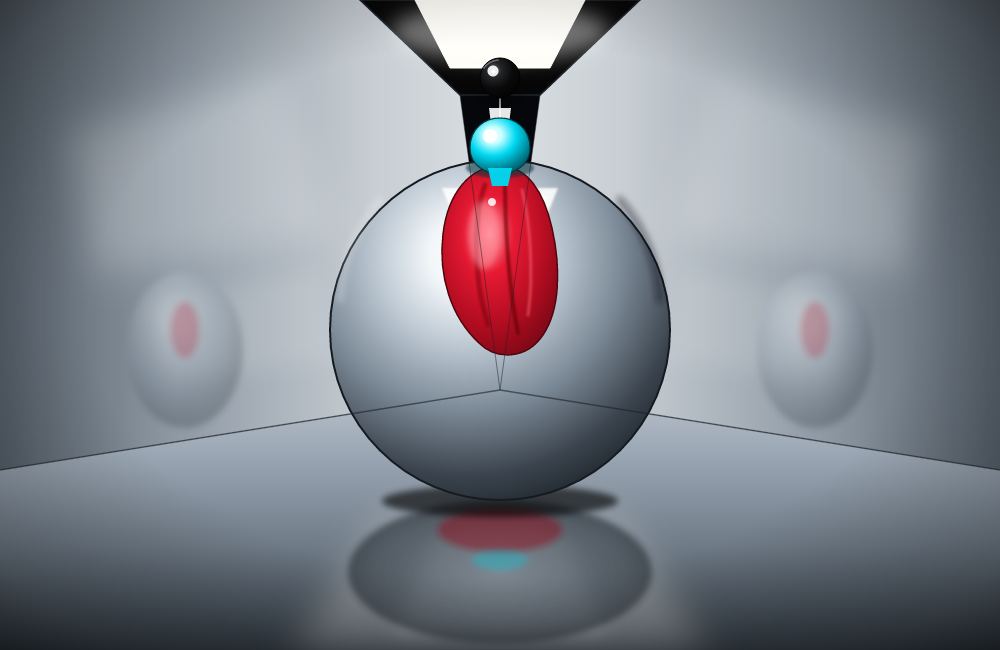
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
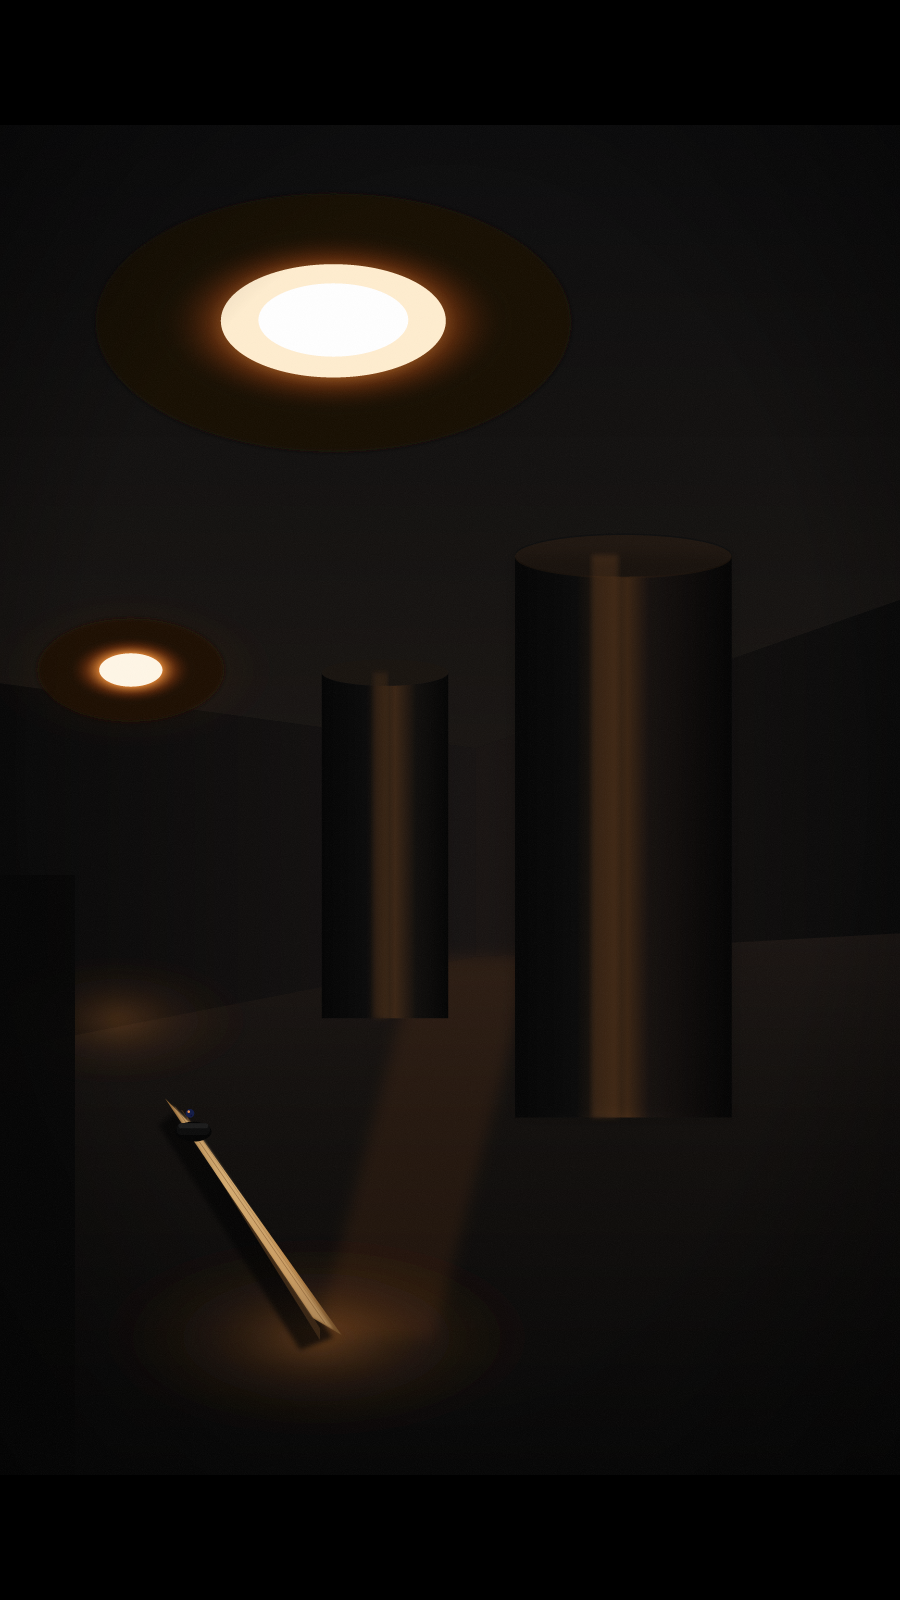
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
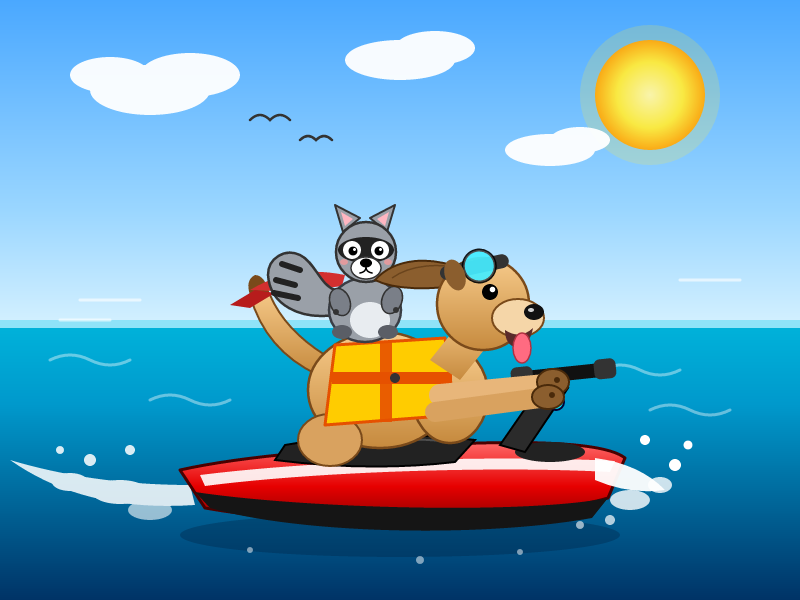
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
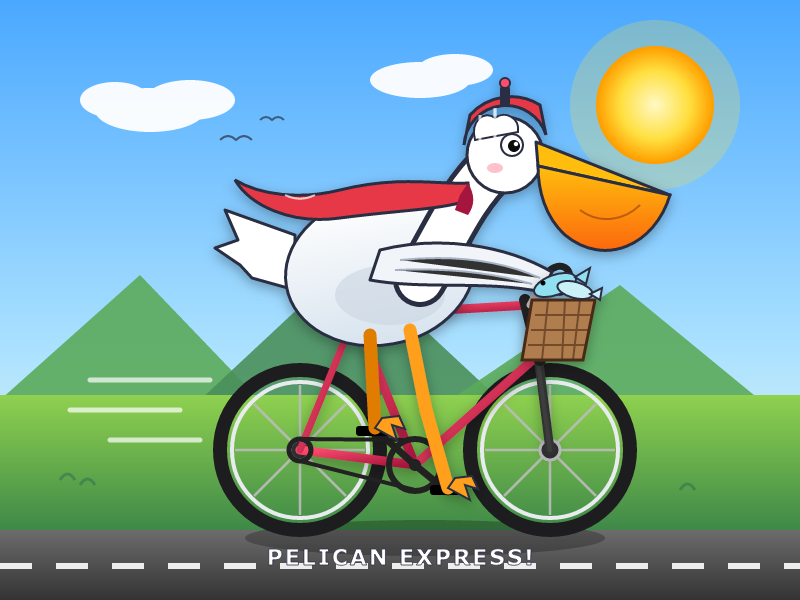
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
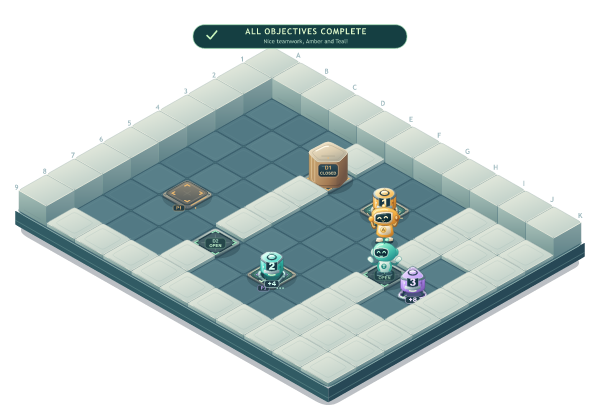
LicenseProprietary hosted service
Model IDopenai/gpt-5.5
StealthMarkOverall rank39/497 rated results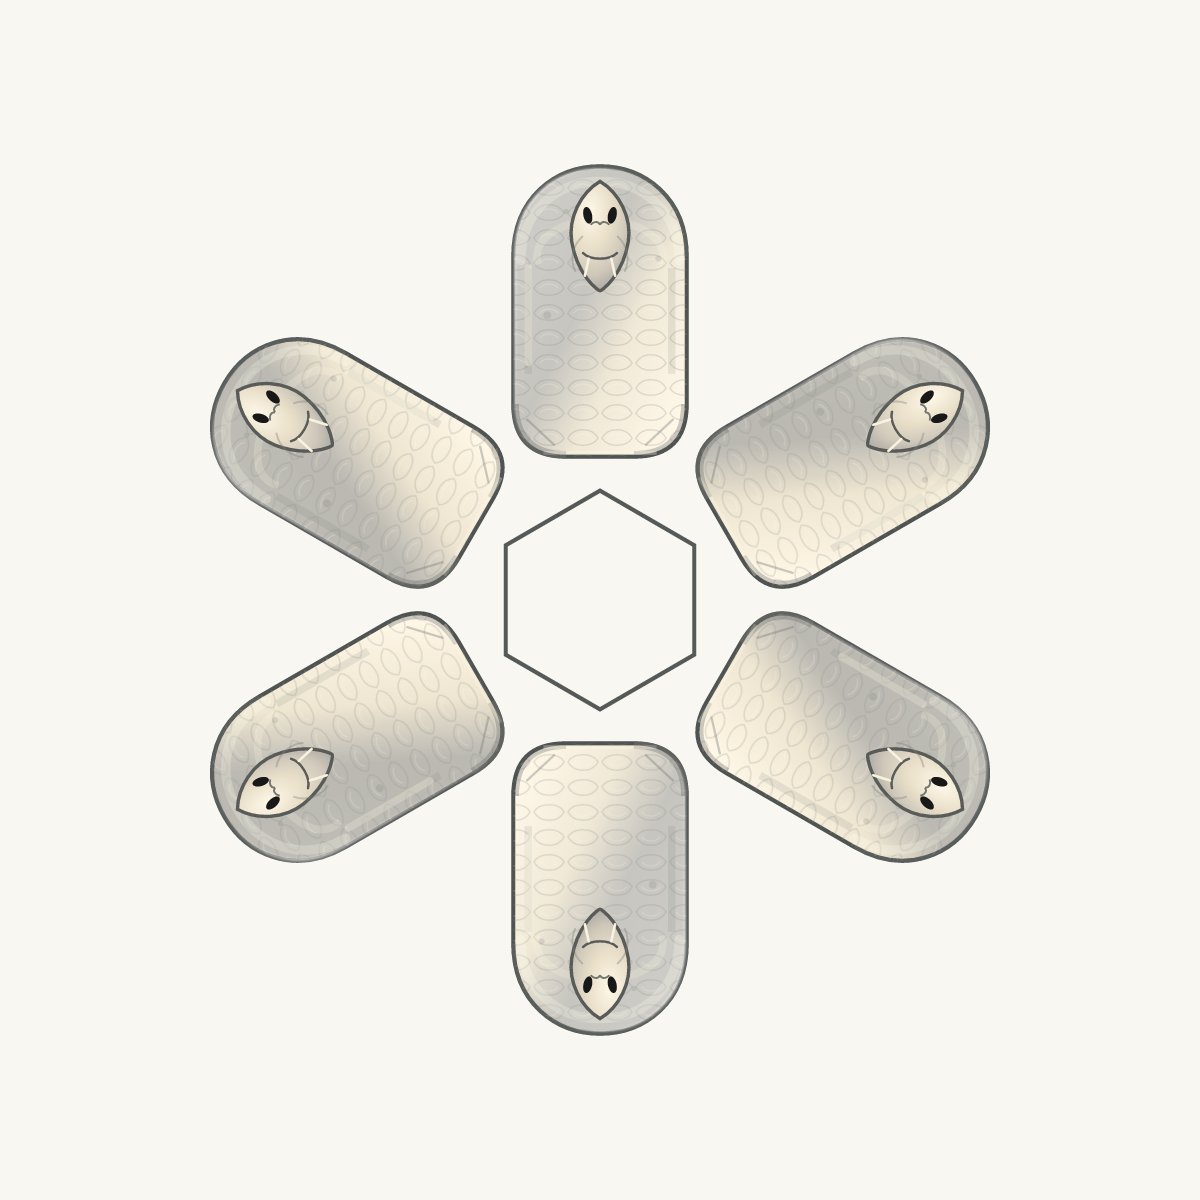
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
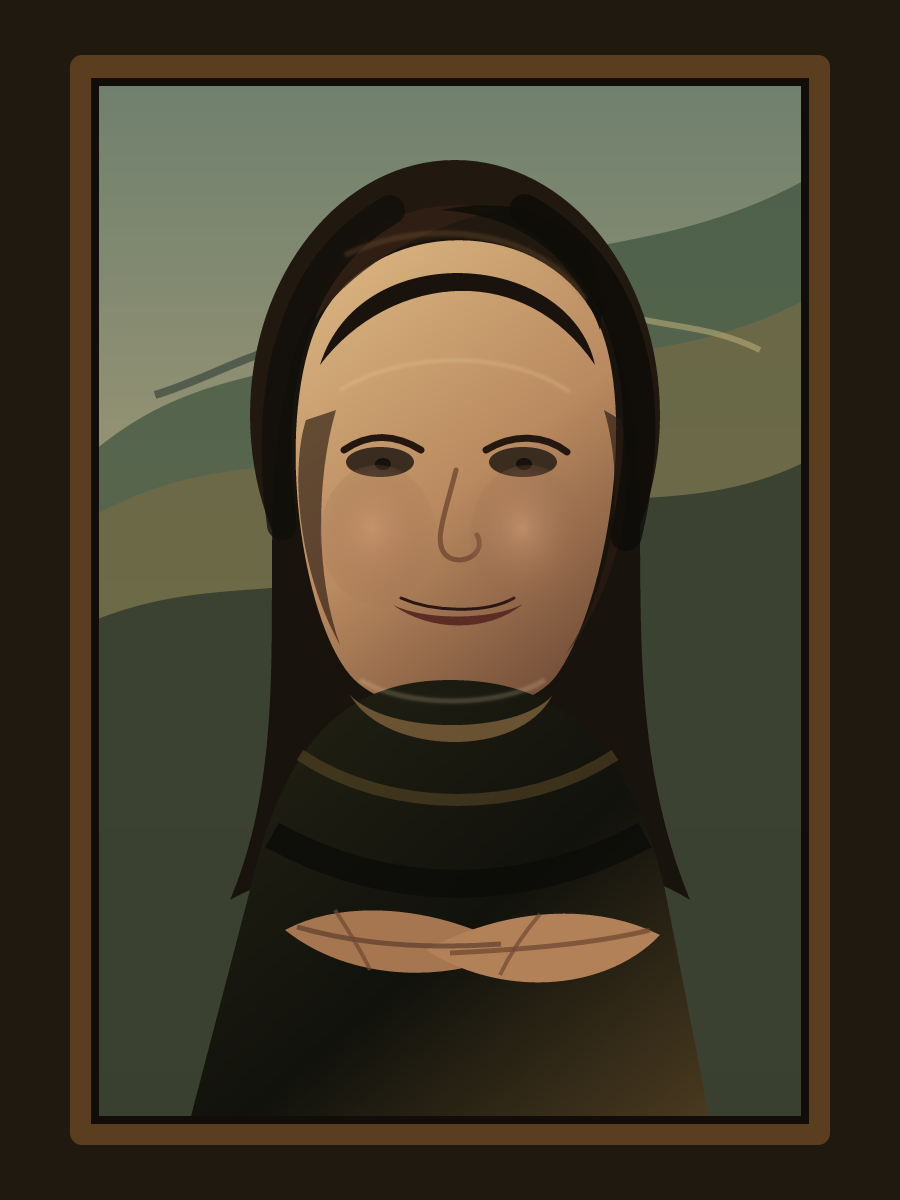
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
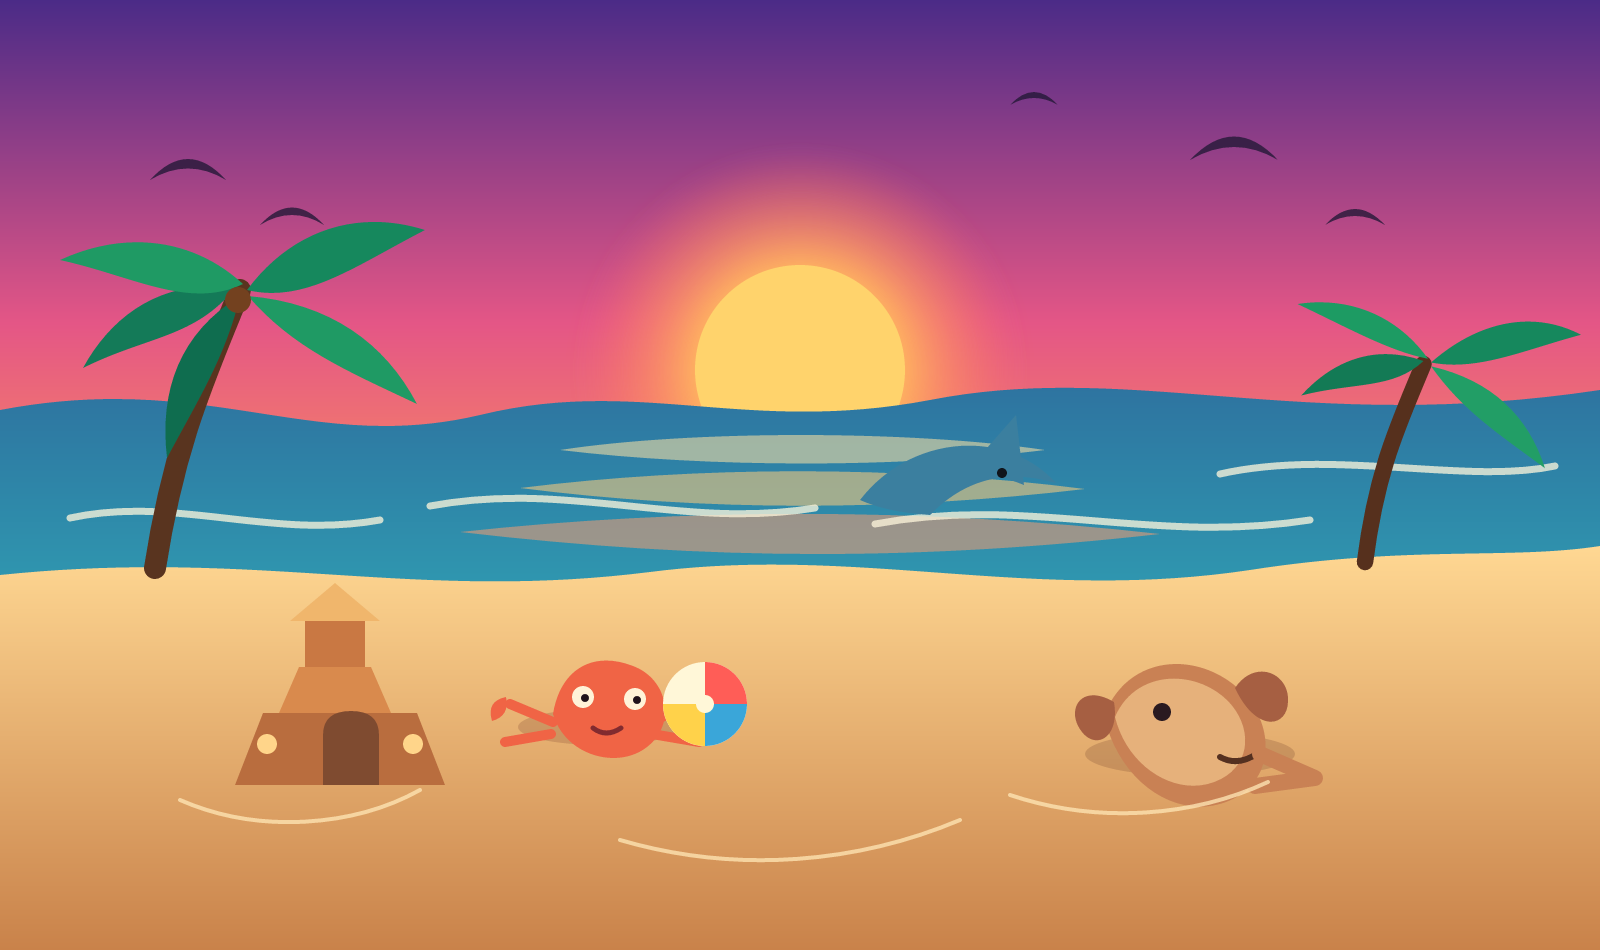
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
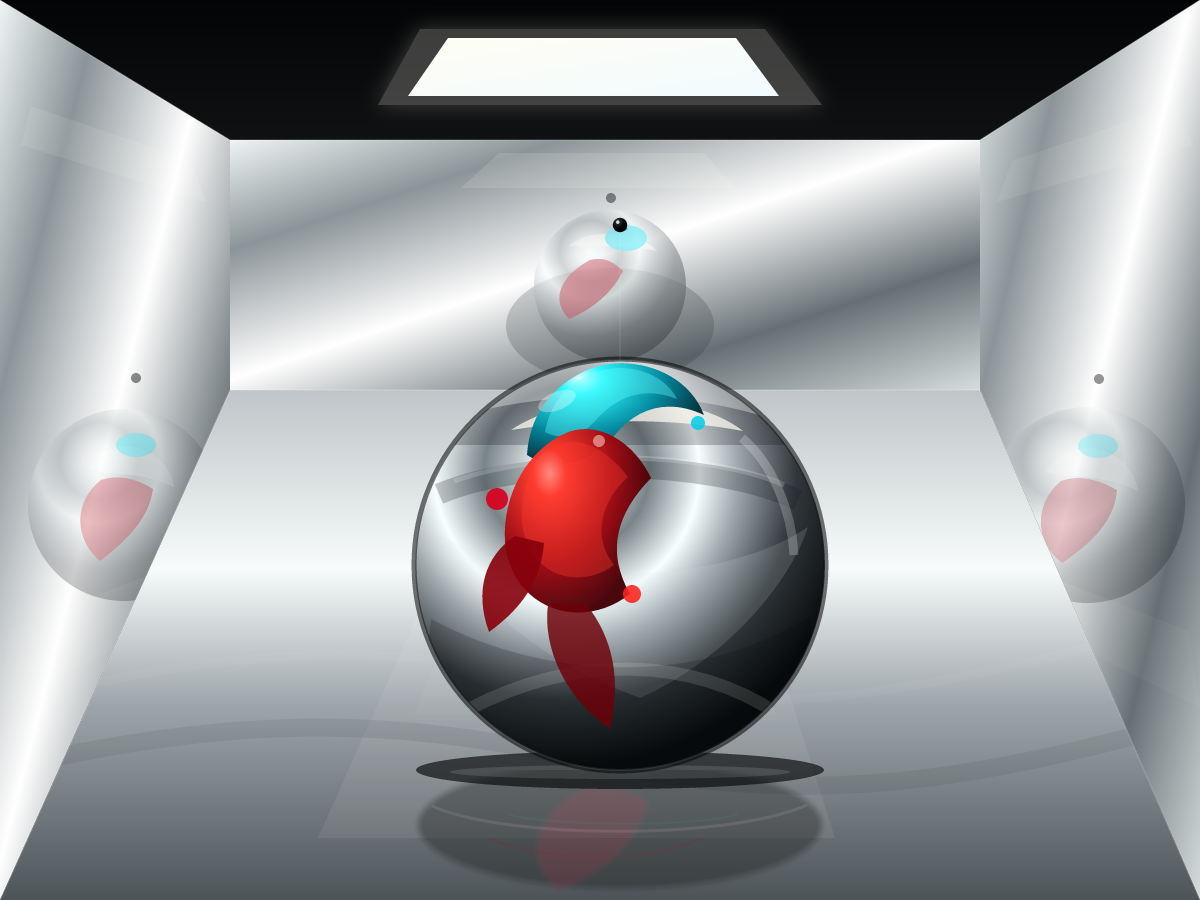
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
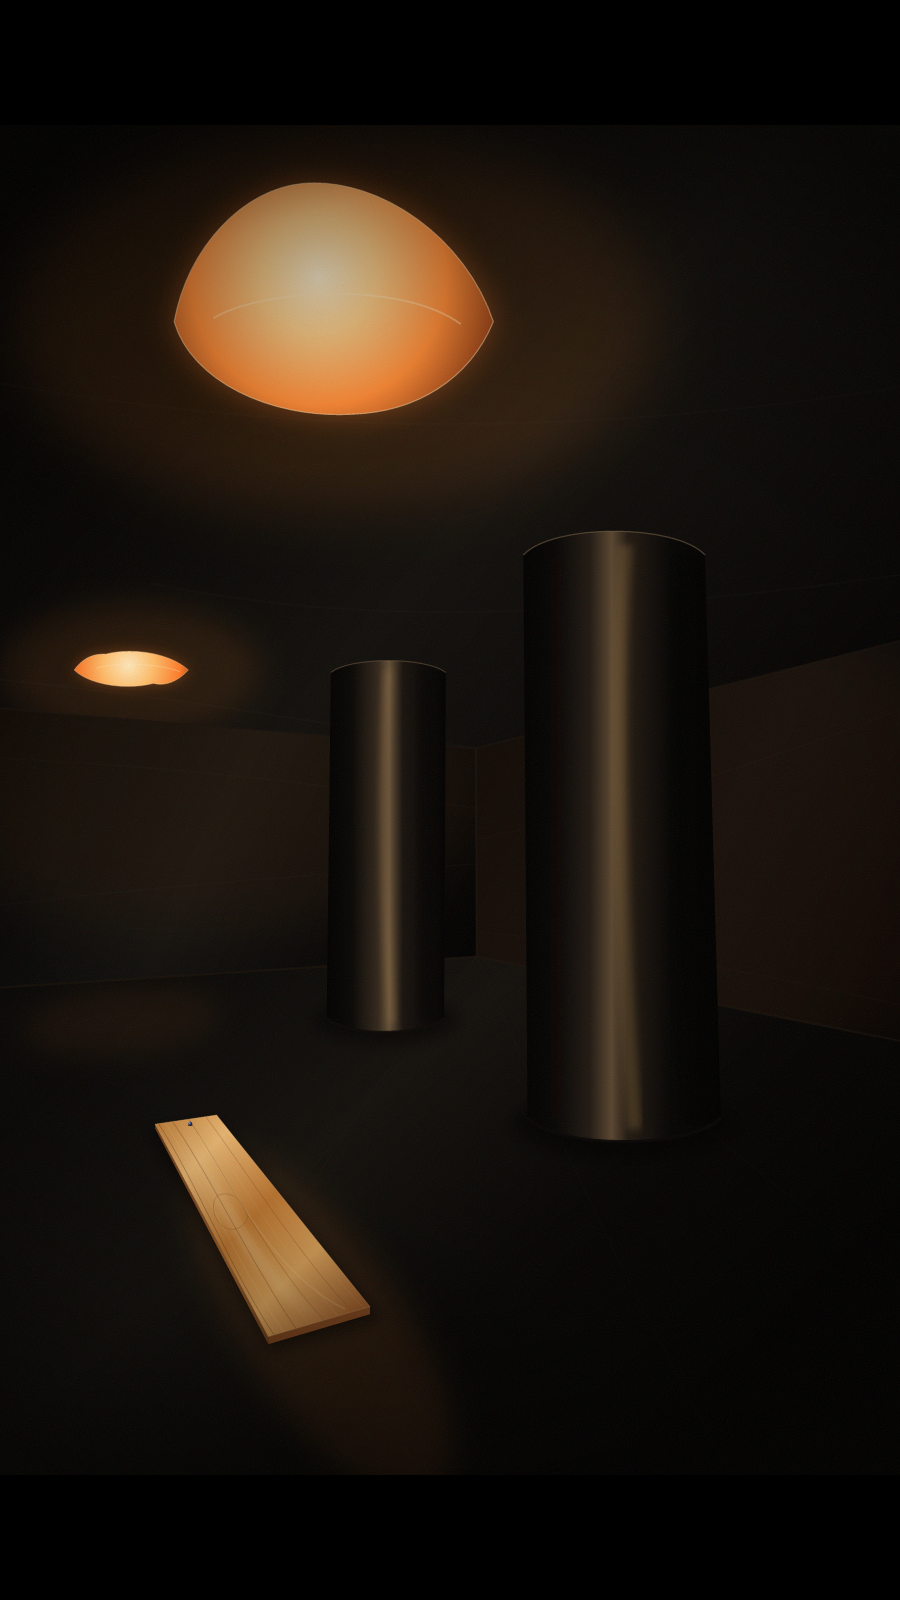
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
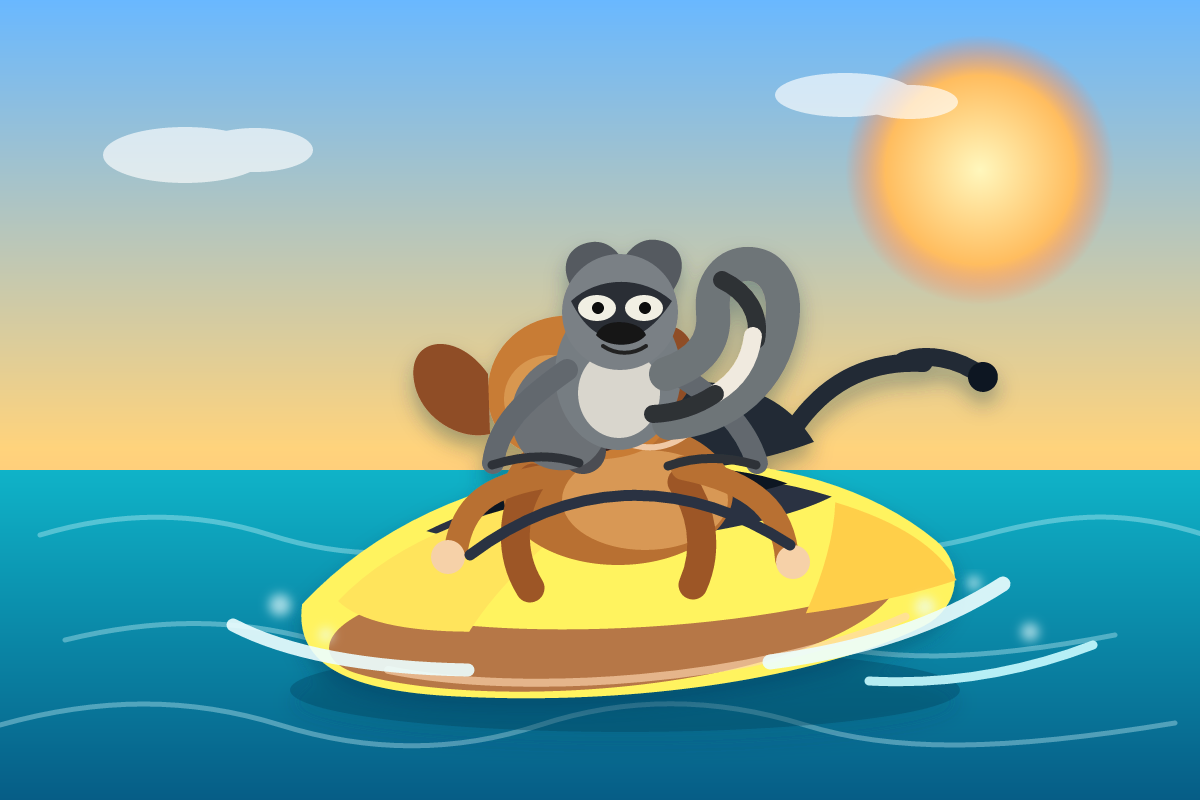
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
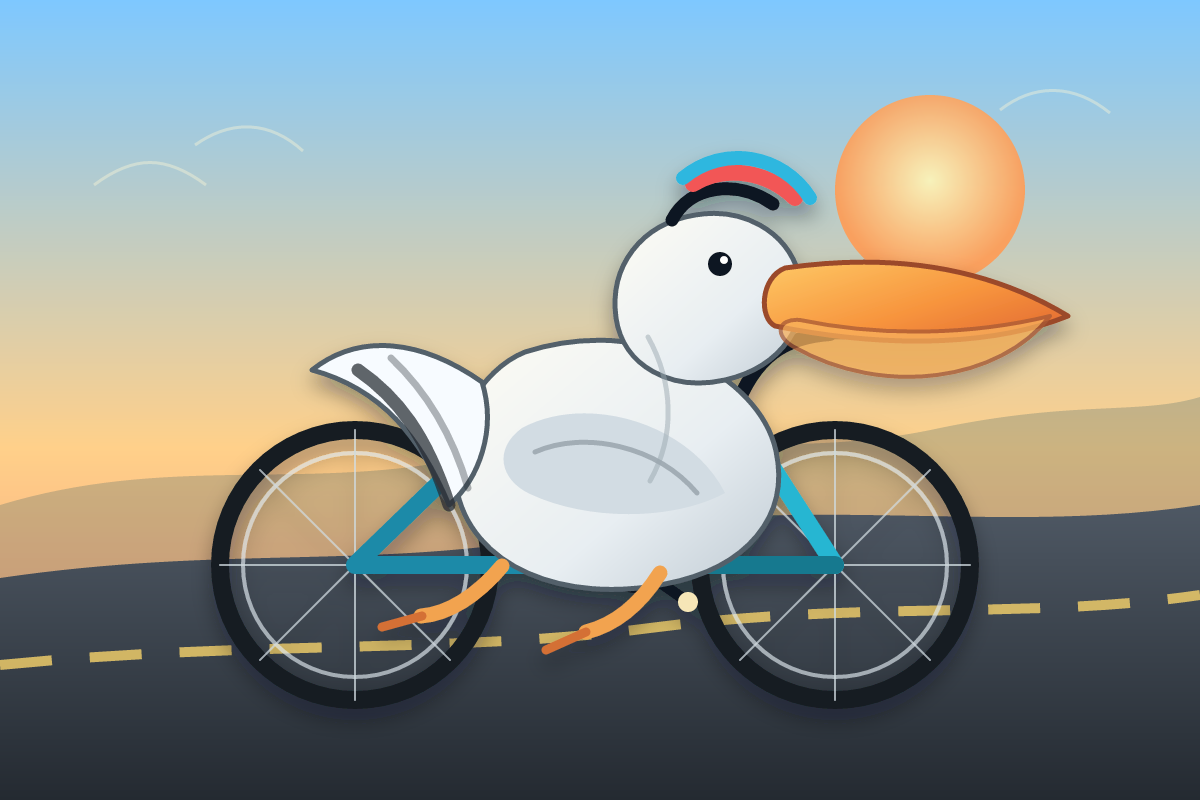
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDopenai/gpt-5.6-luna
StealthMarkOverall rank33/499 rated results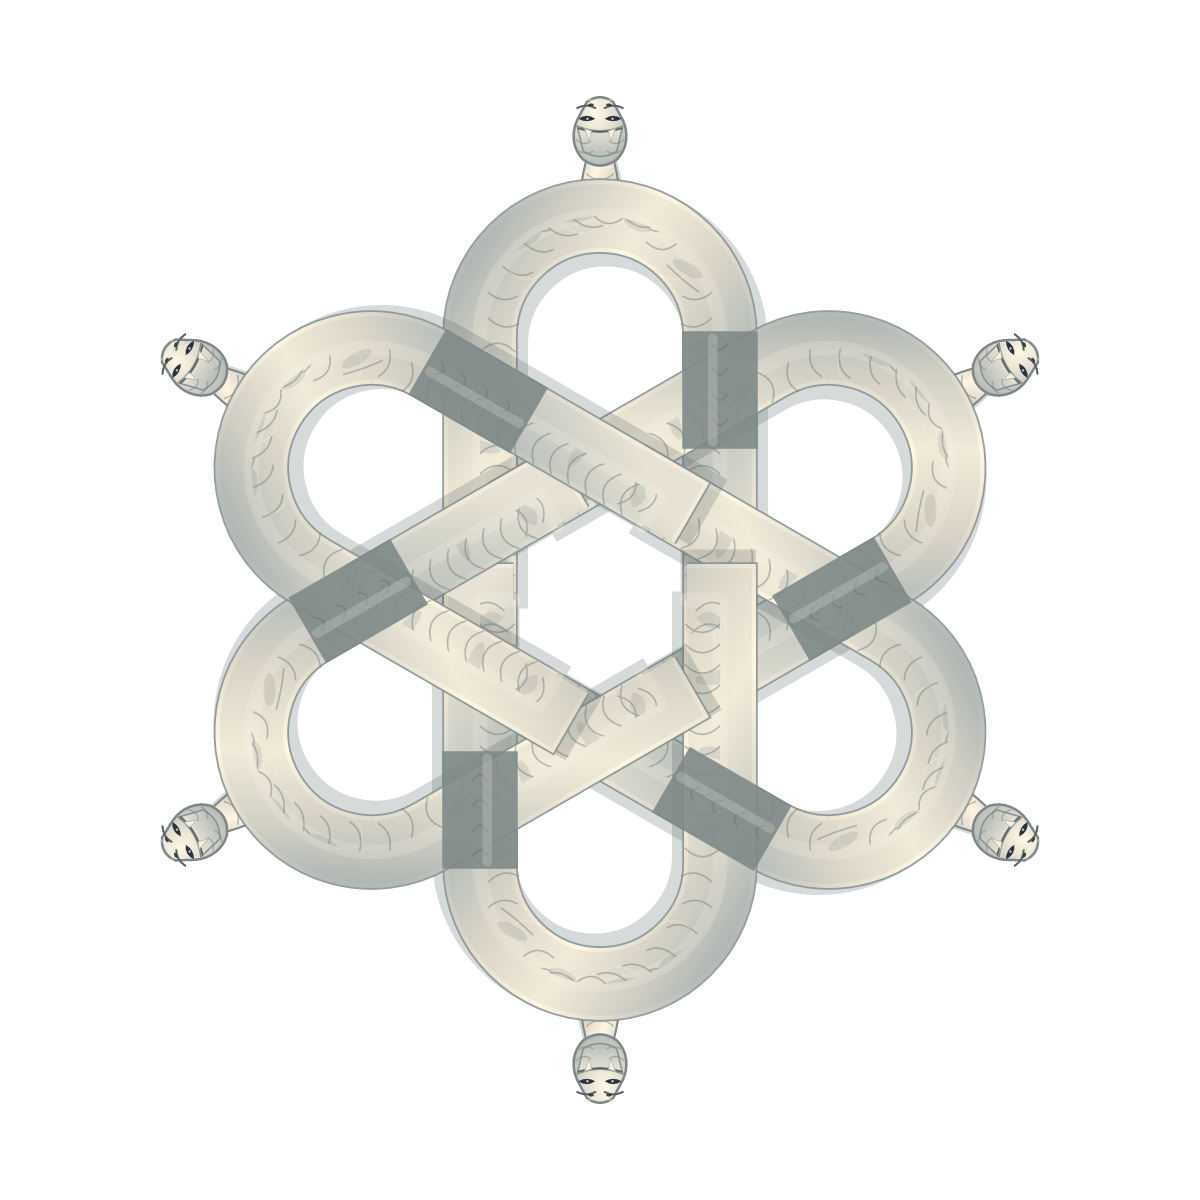
A pale serpent woven into an interlocking knot tests connected anatomy, repeated structure and readable overlaps. Organic surface detail must work with the overall geometry.
First run
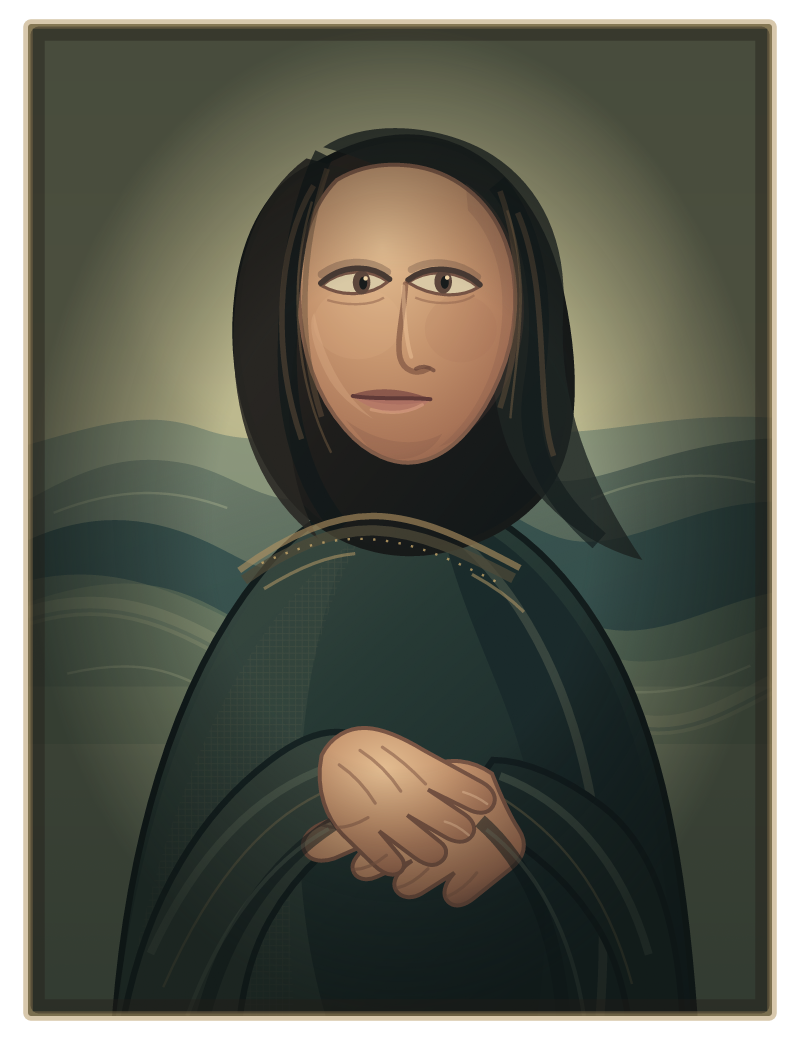
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
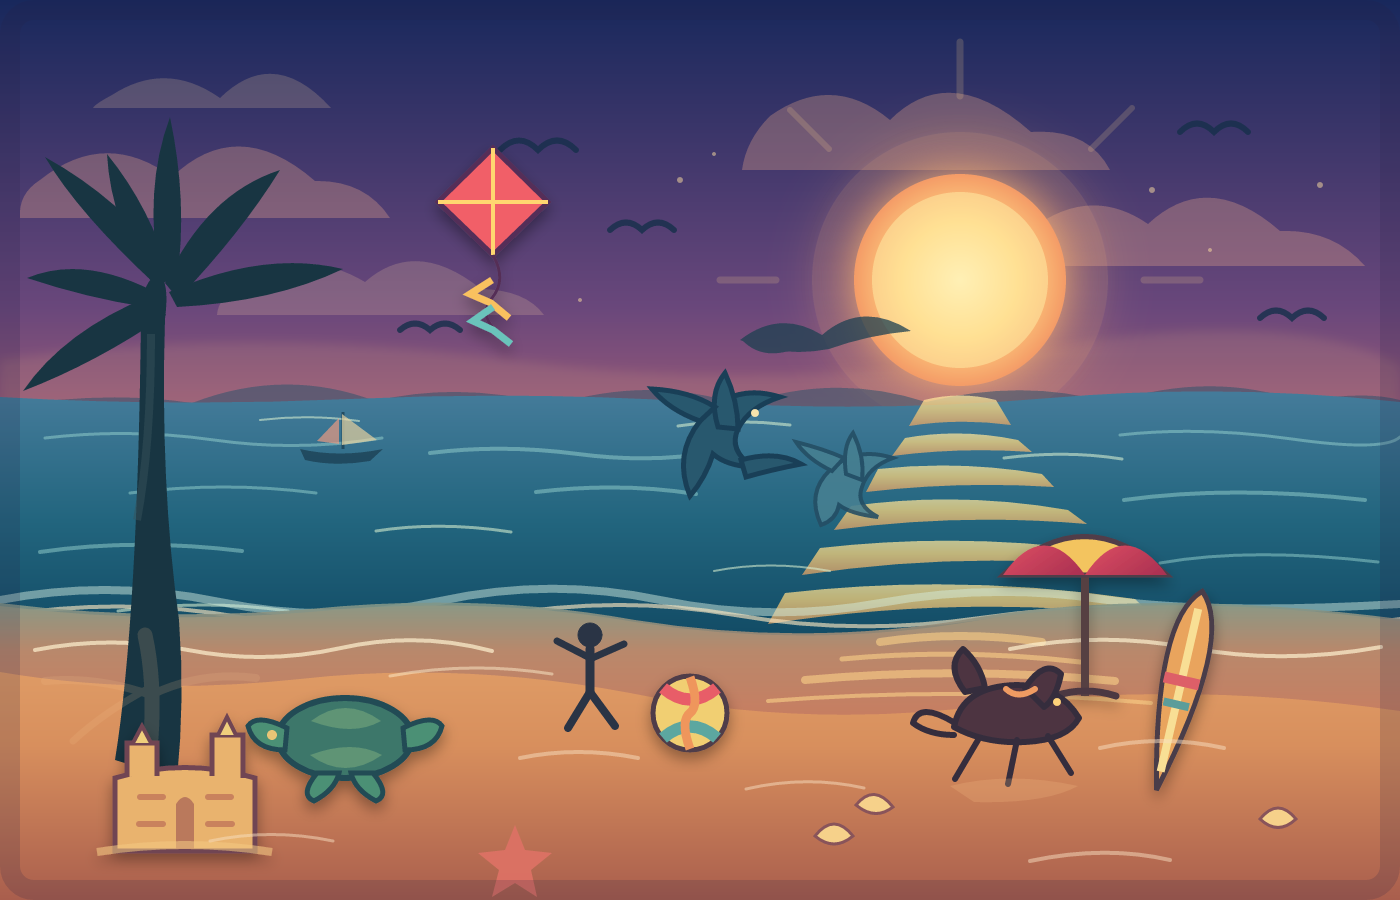
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
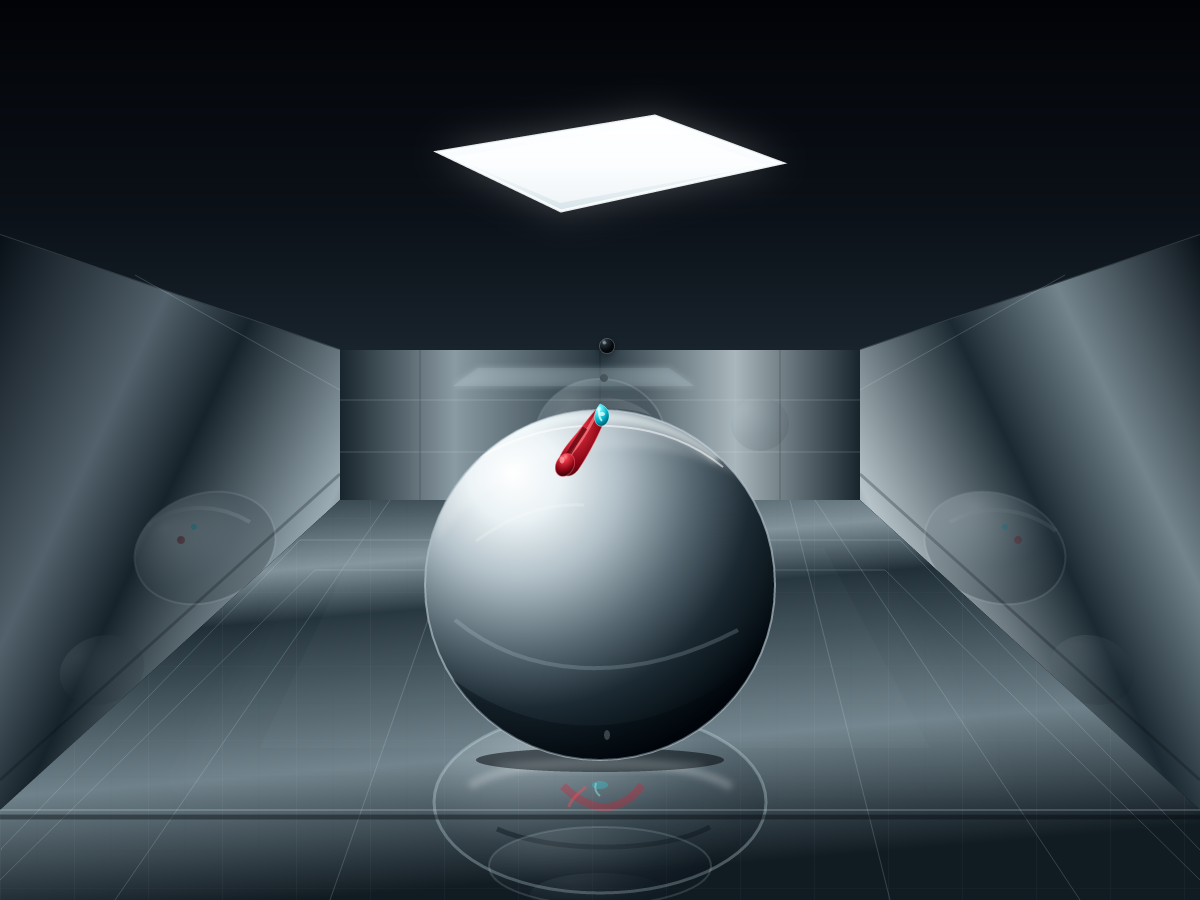
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
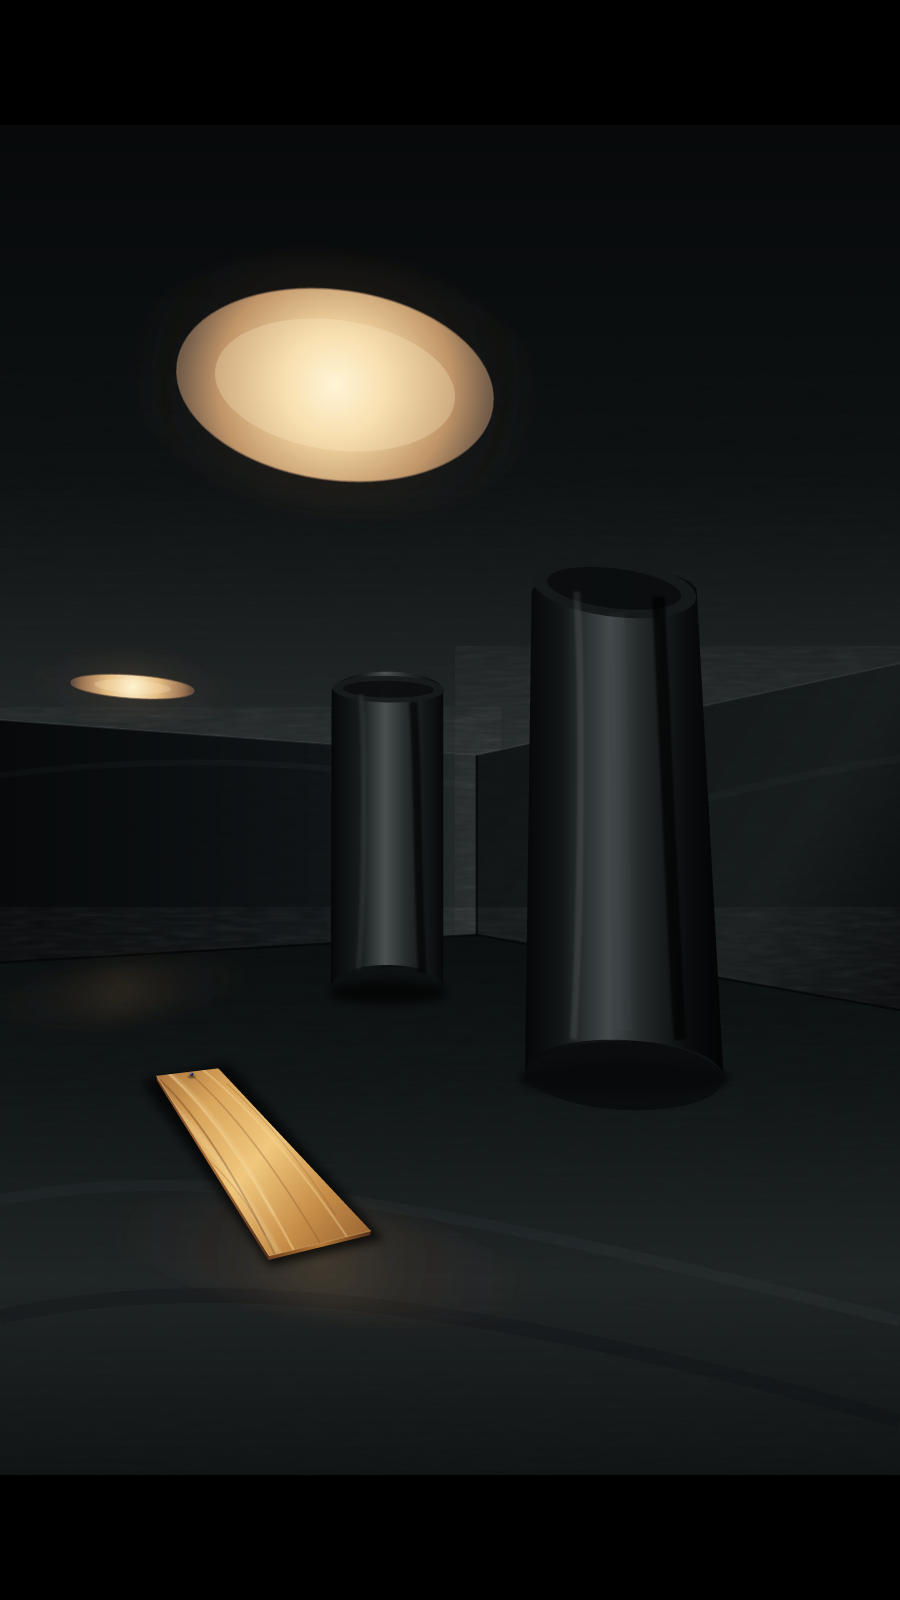
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
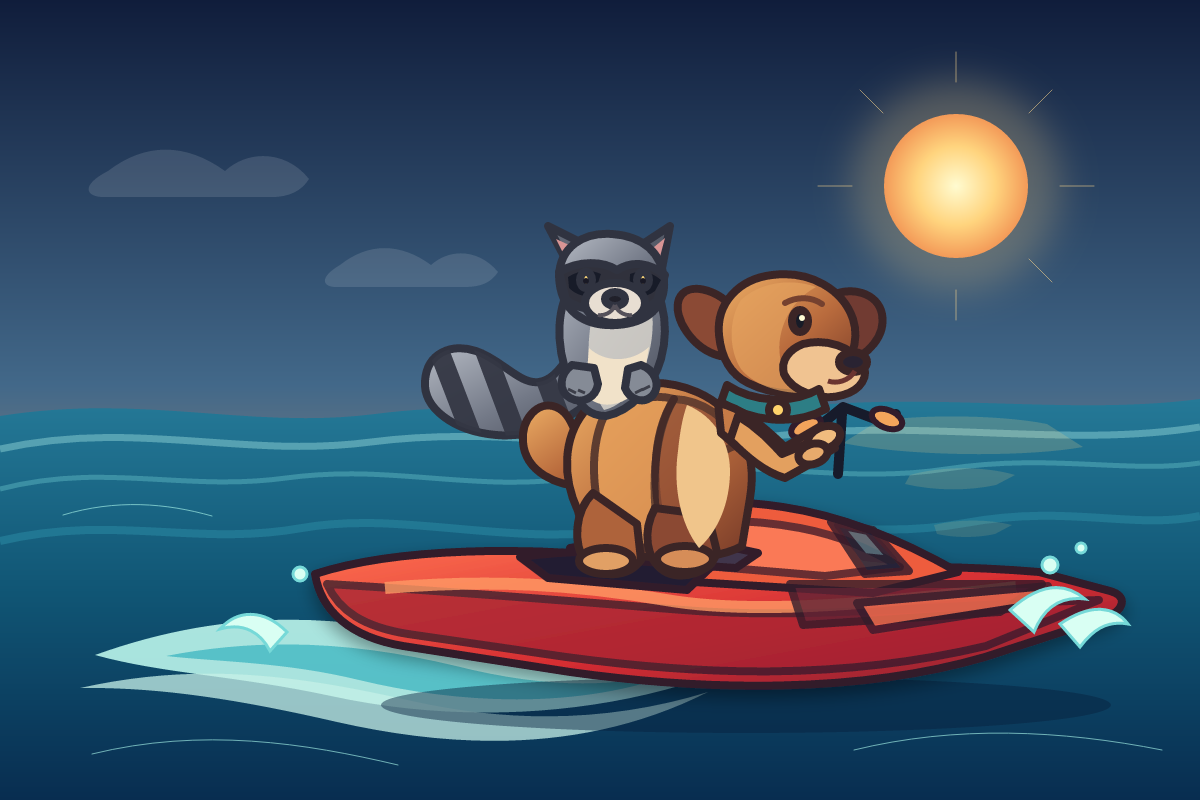
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
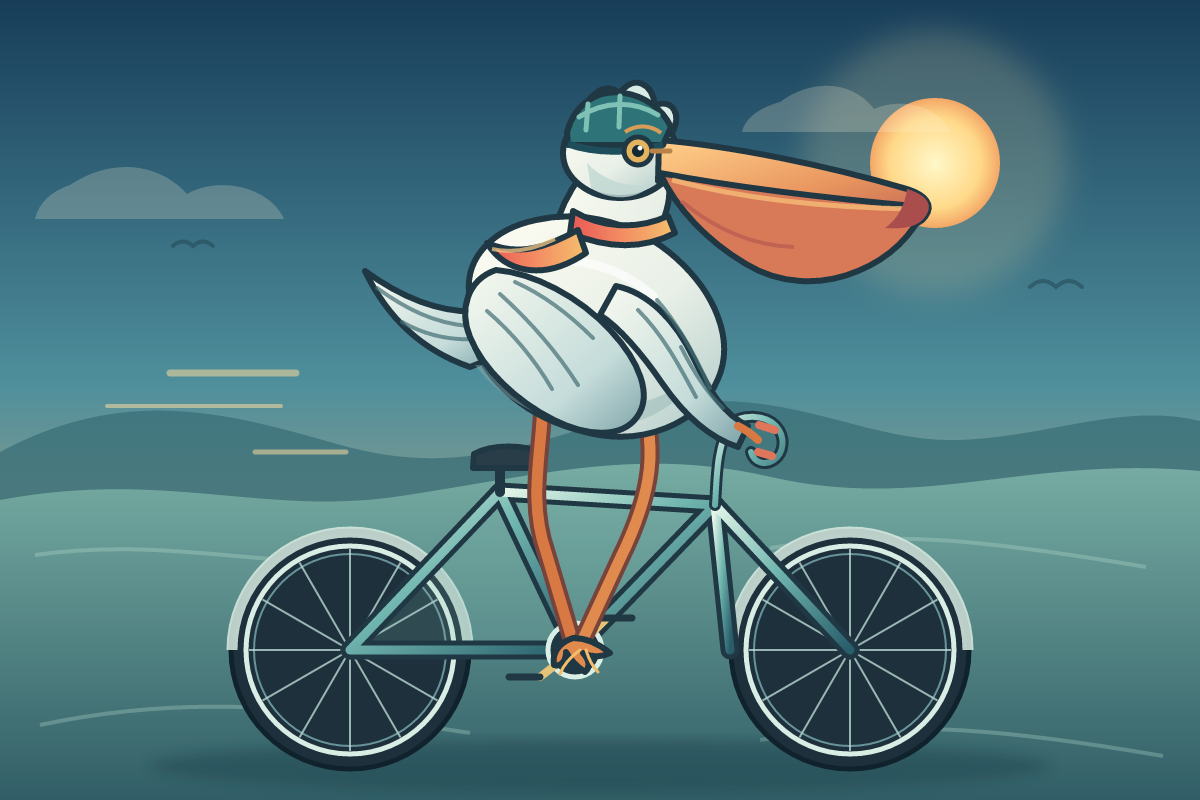
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
Model IDopencode/fledge-alpha-free
StealthMarkOverall rank35/497 rated results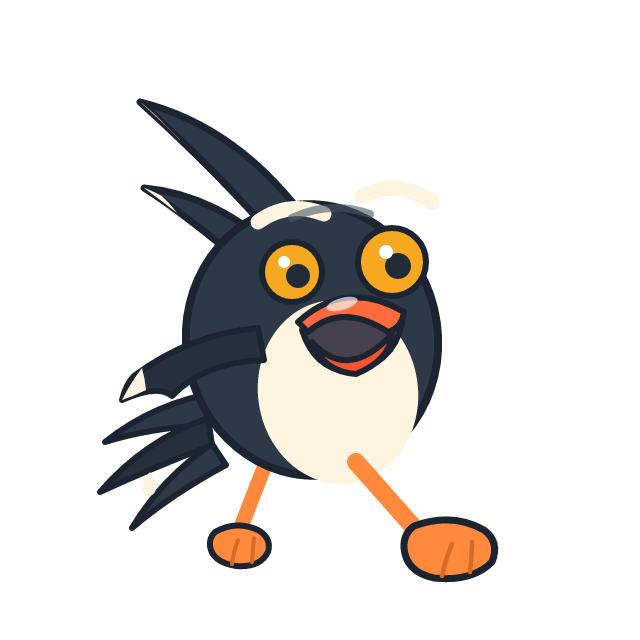
An eager young seabird running toward the viewer tests expressive anatomy, balance and a convincing forward-moving pose.
First run
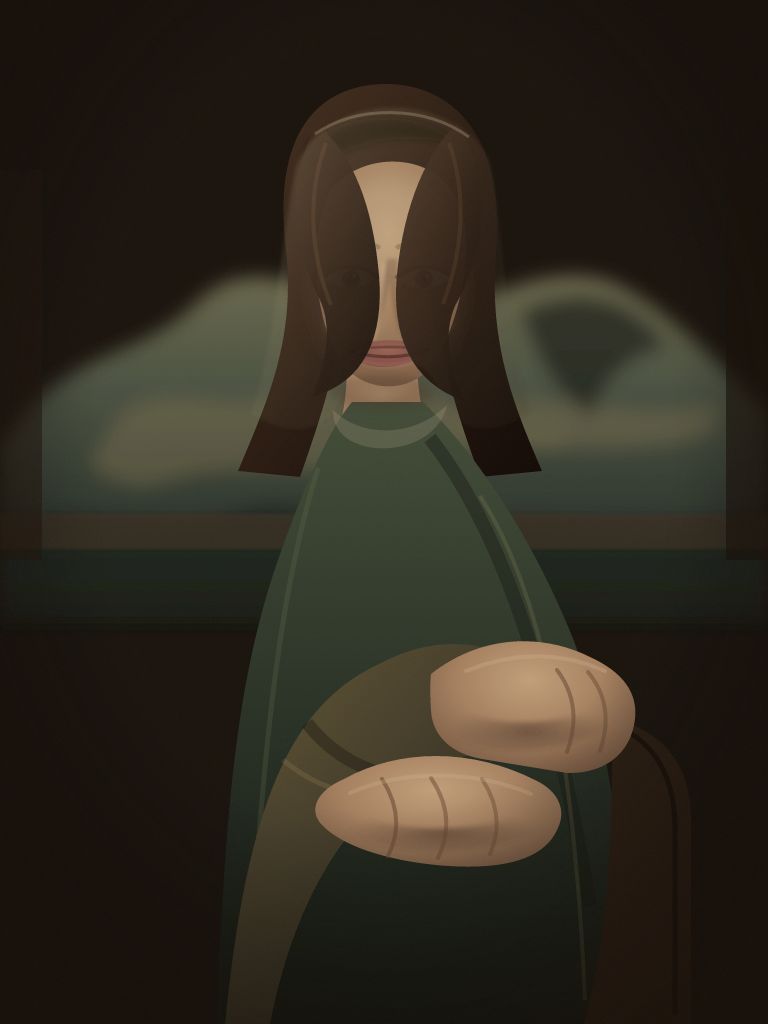
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
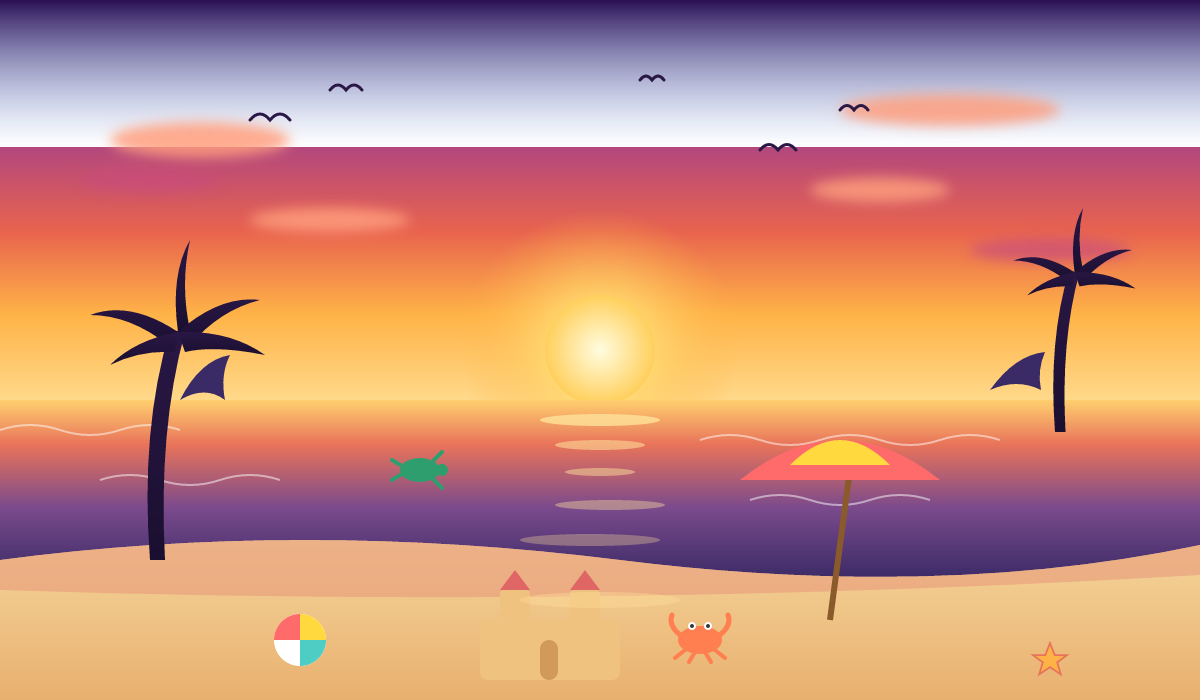
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
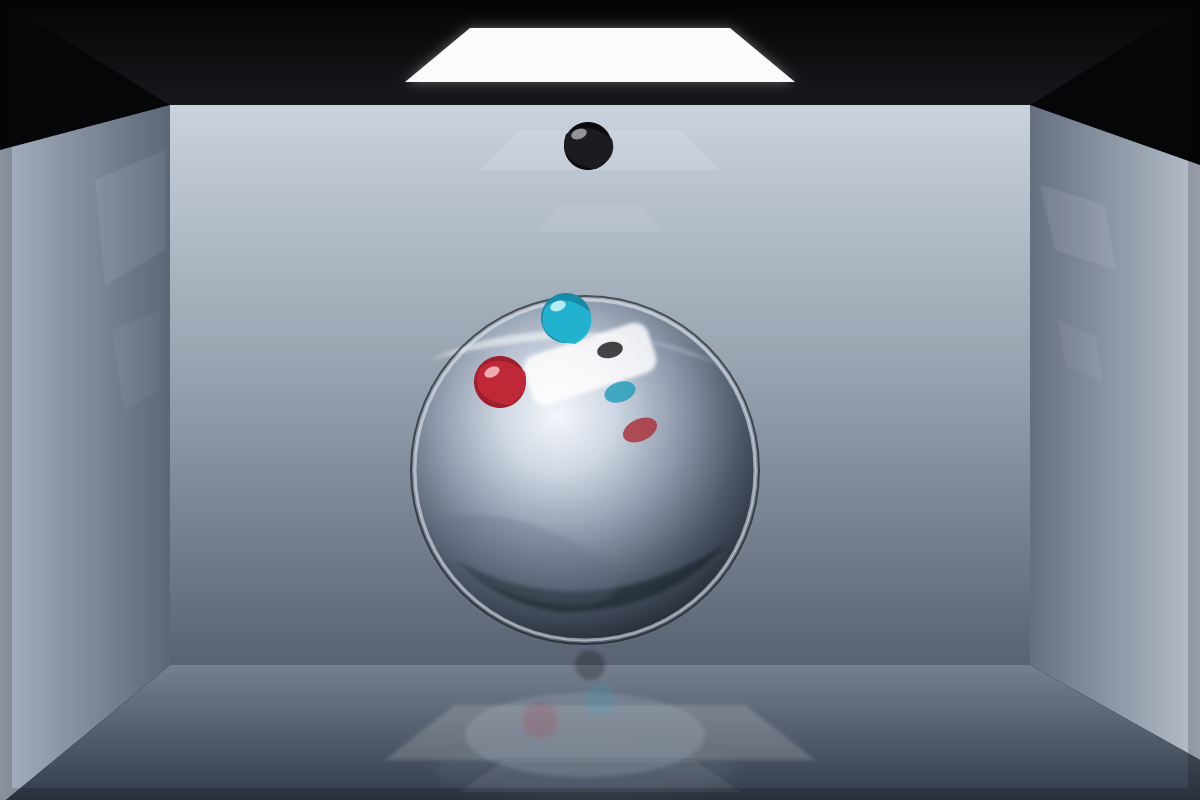
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
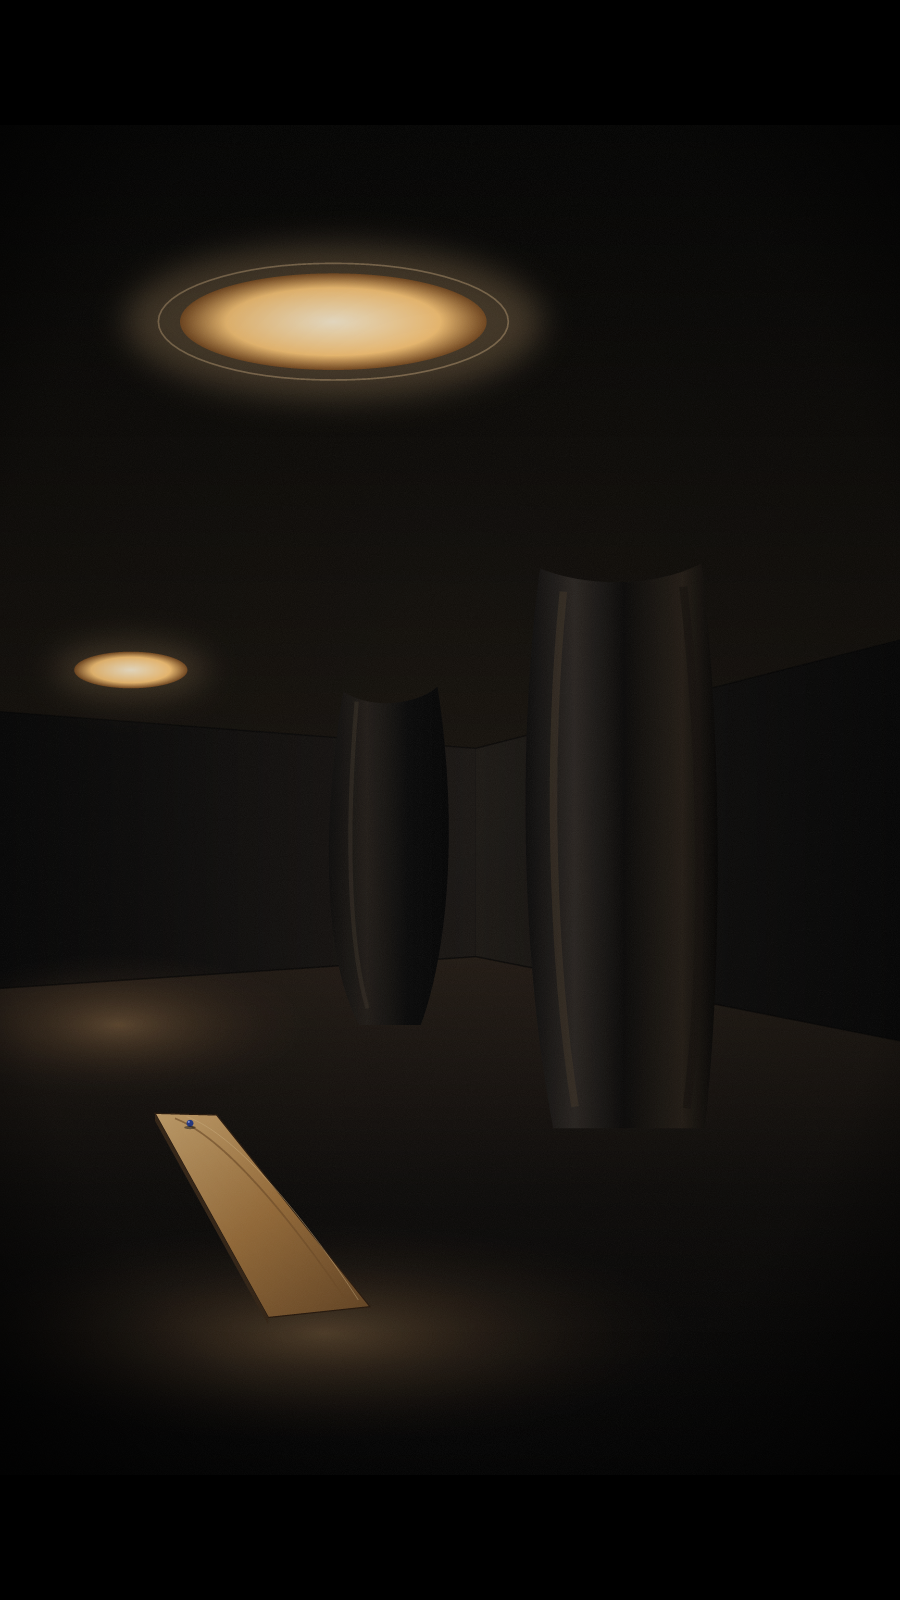
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
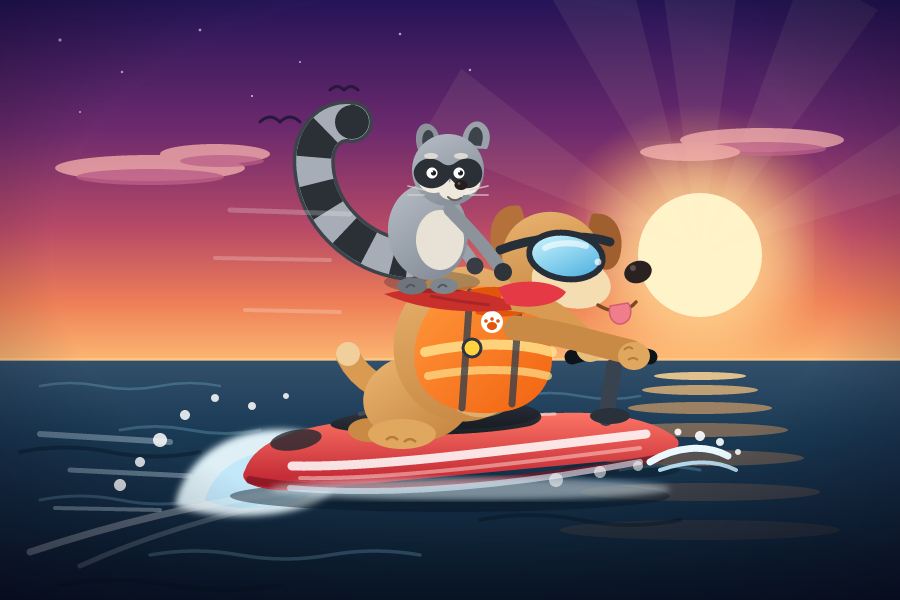
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
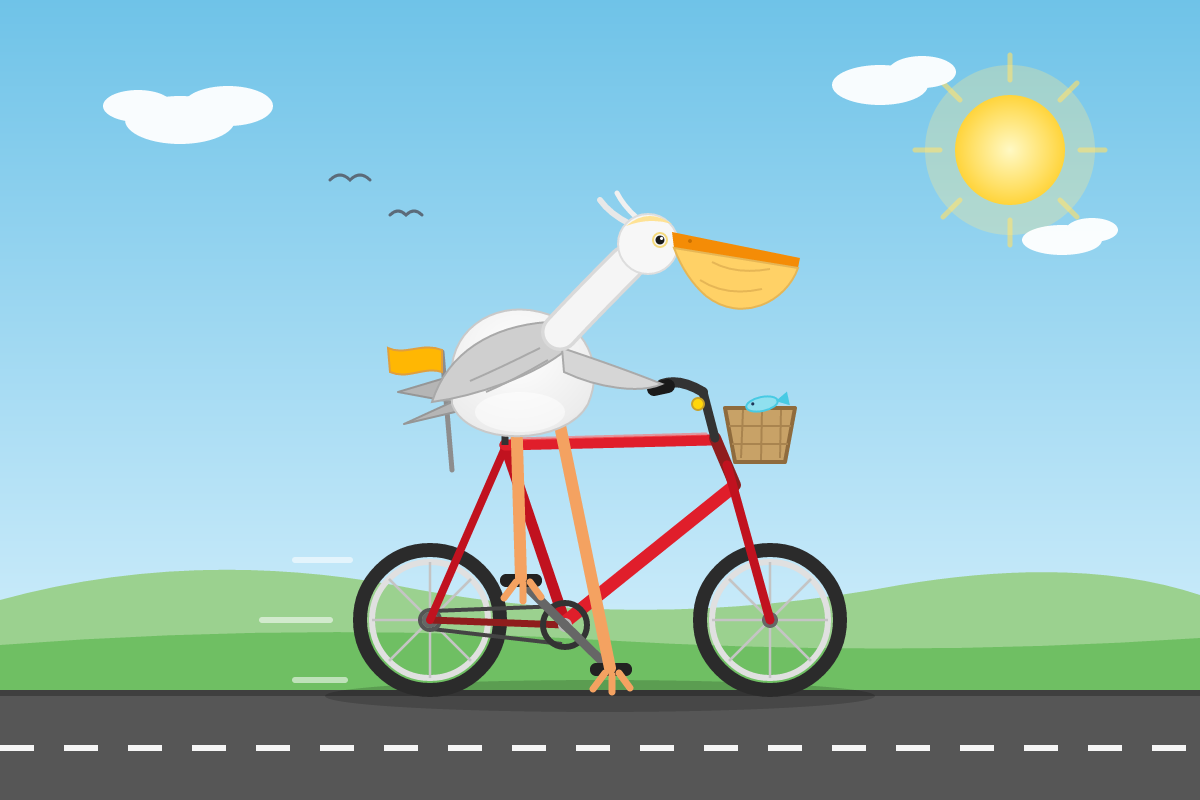
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseApache-2.0
Model IDtencent/hy4-preview
StealthMarkOverall rank26/499 rated results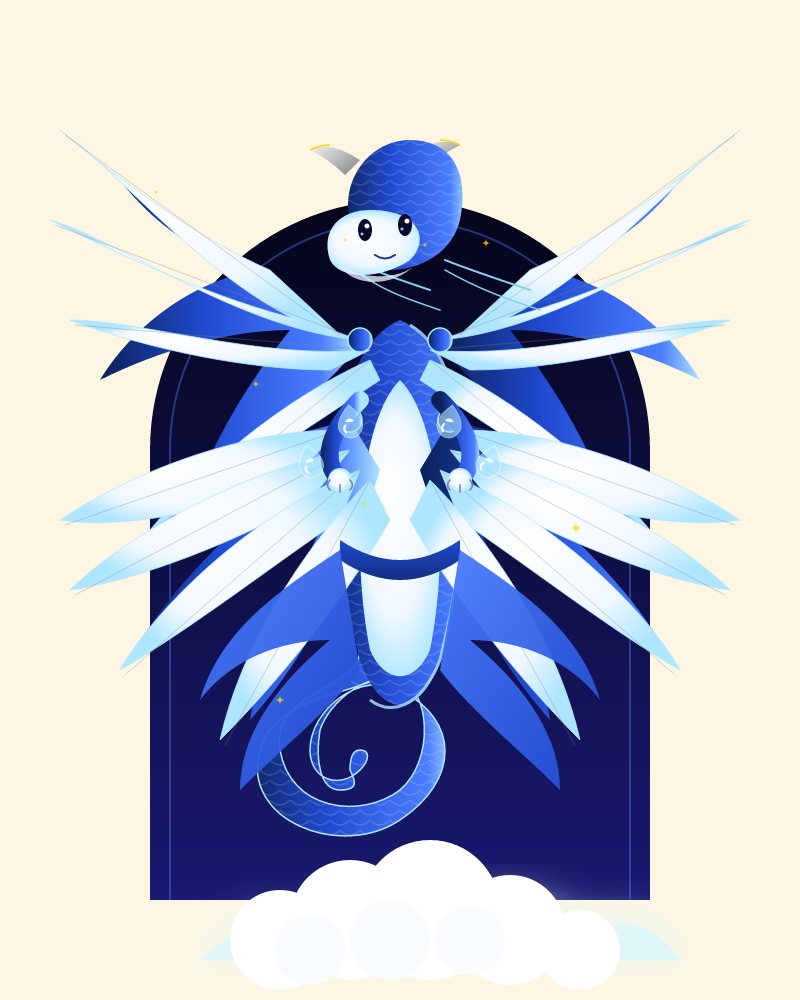
A young blue dragon floating among clouds tests curved anatomy, expressive features and the contrast between soft clouds and glossy surfaces.
First run
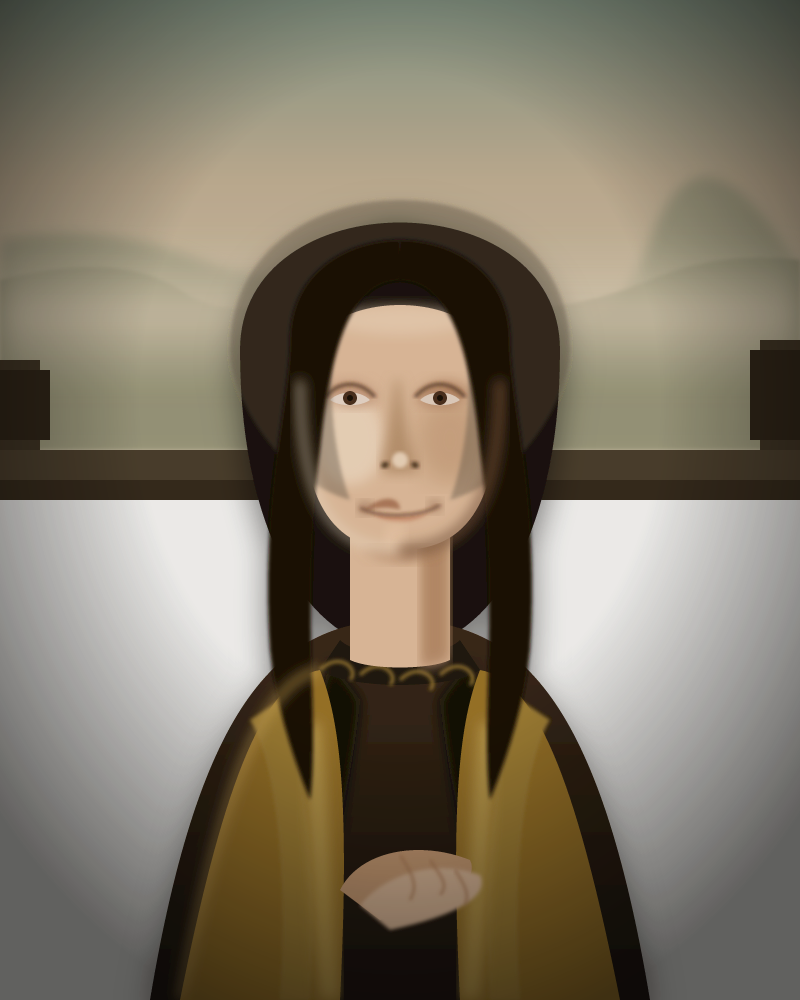
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
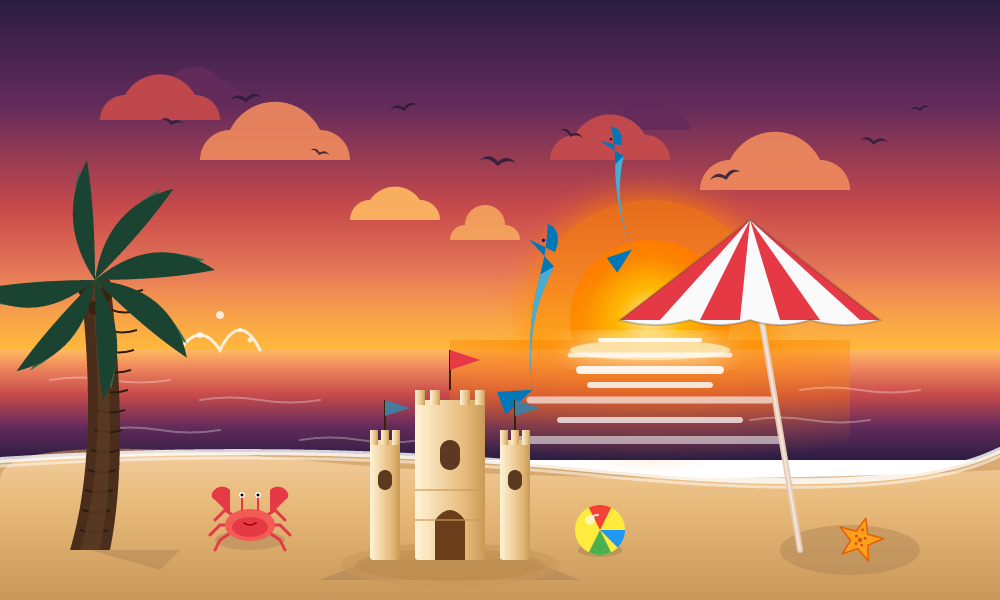
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
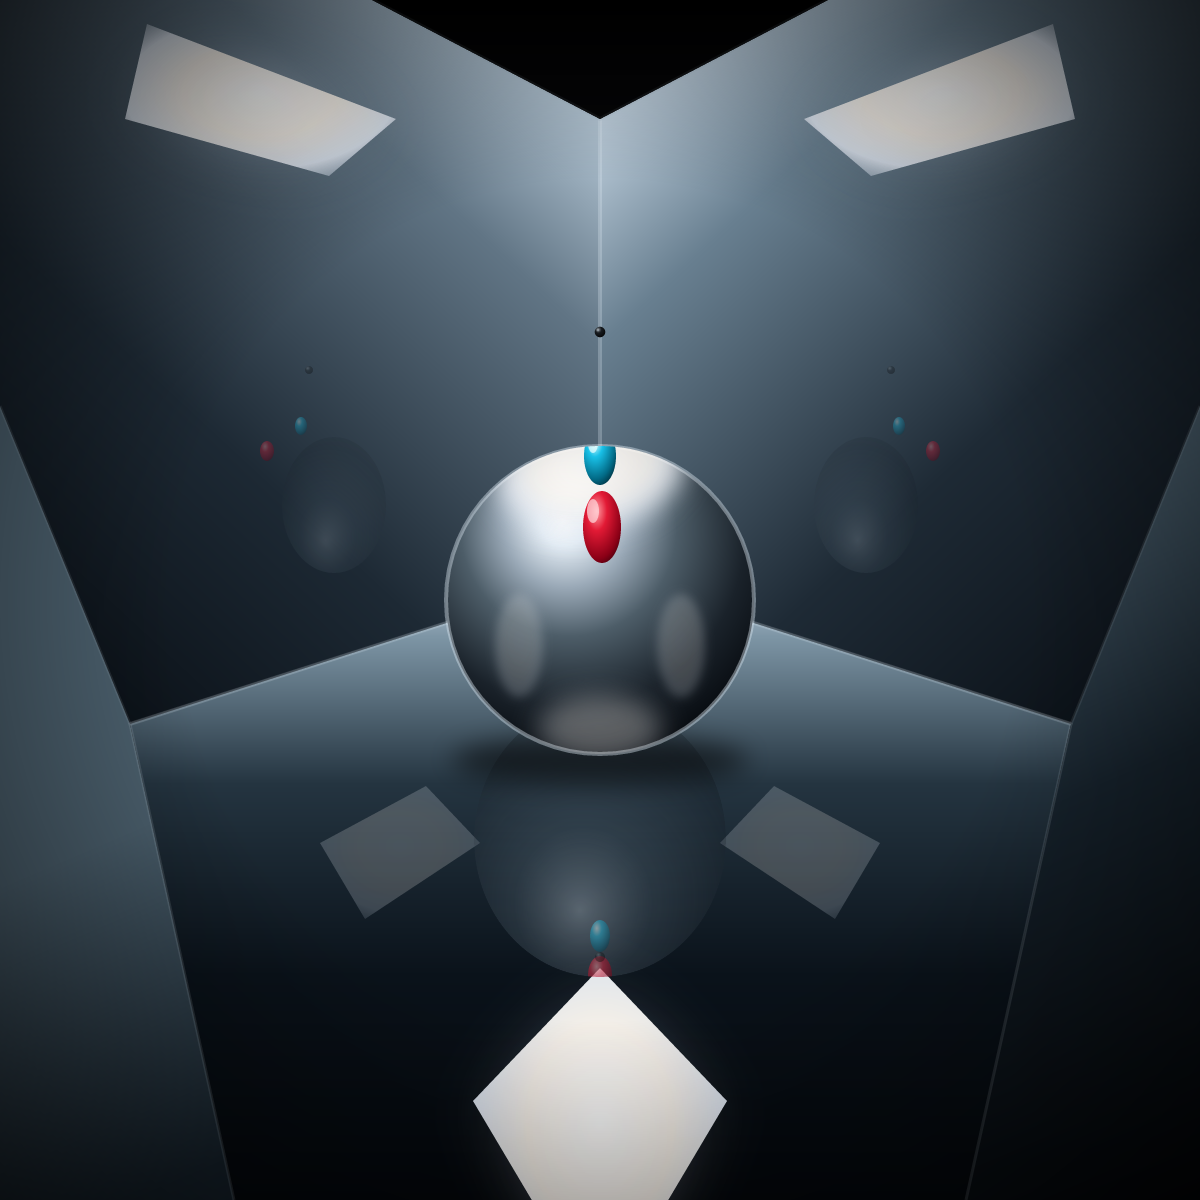
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
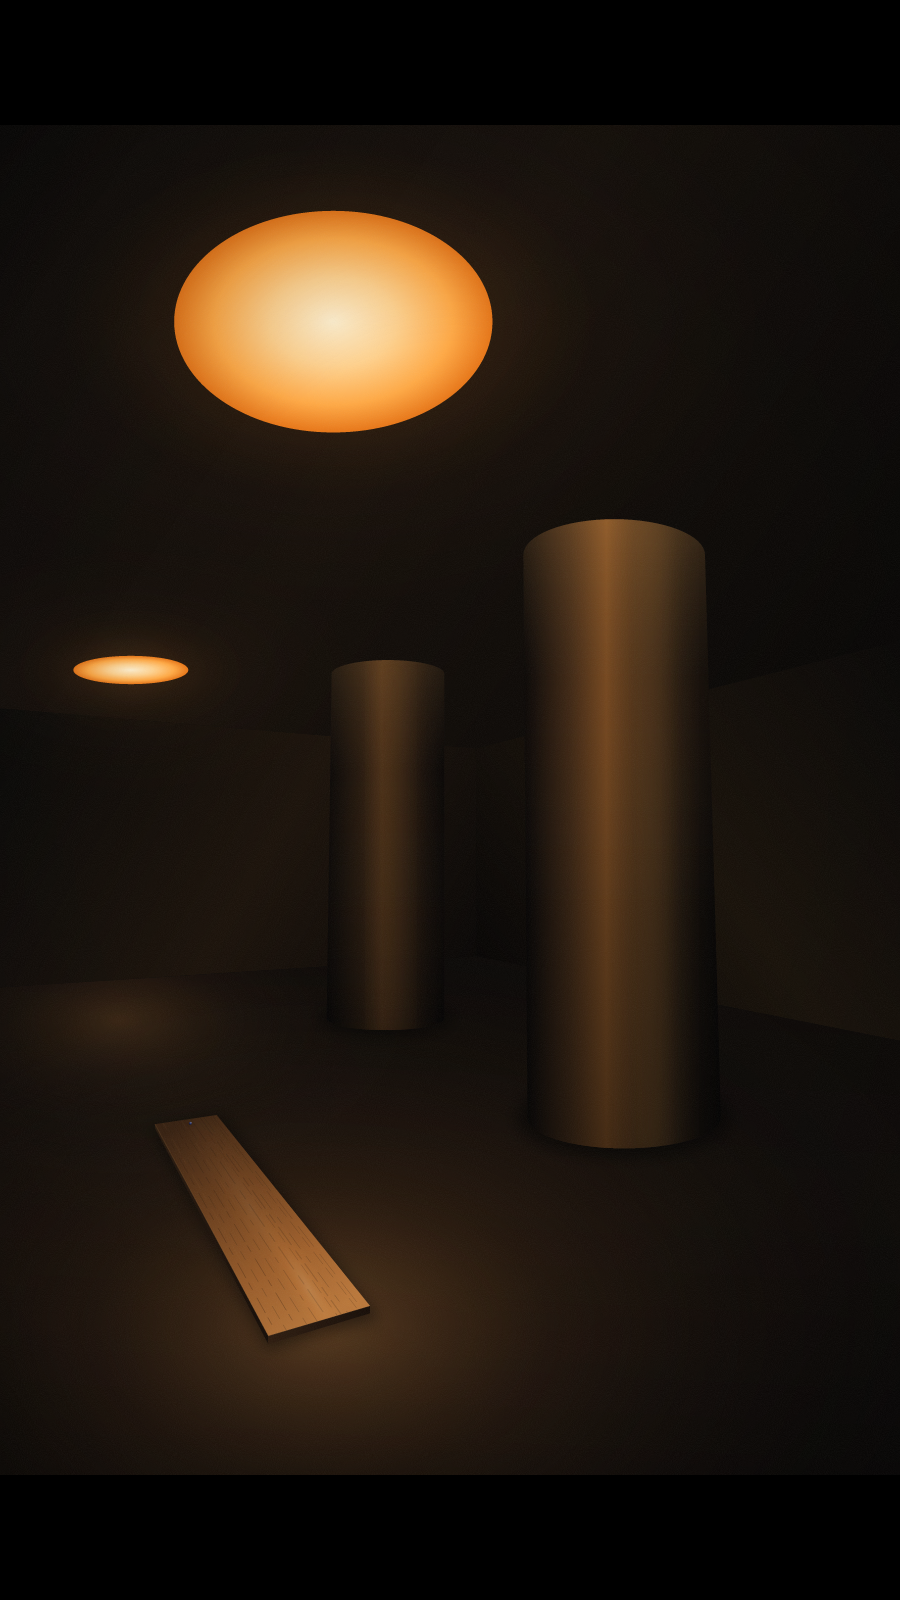
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
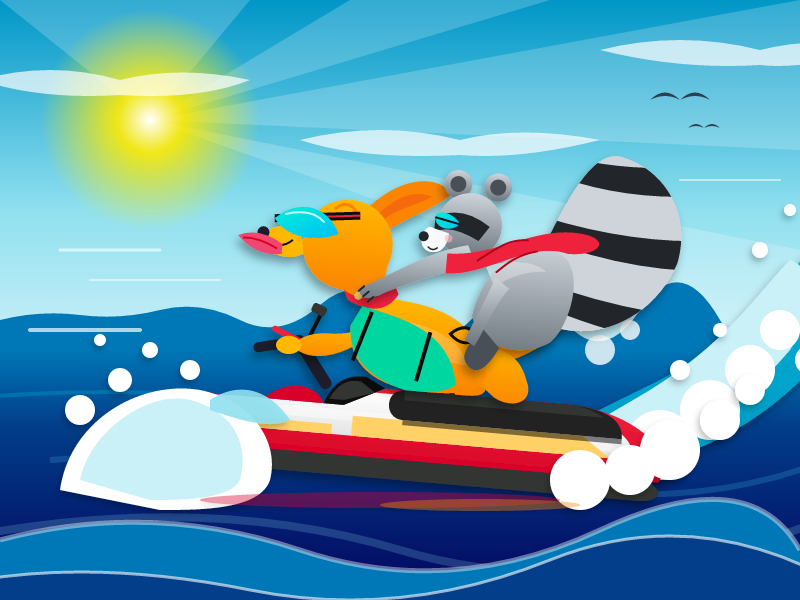
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
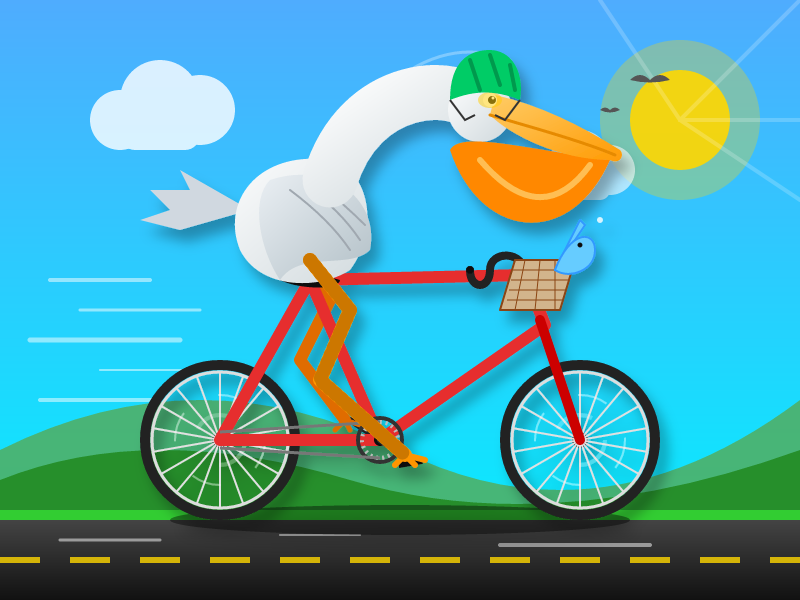
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDqwen/qwen3.8-max-0902
StealthMarkOverall rank6/499 rated results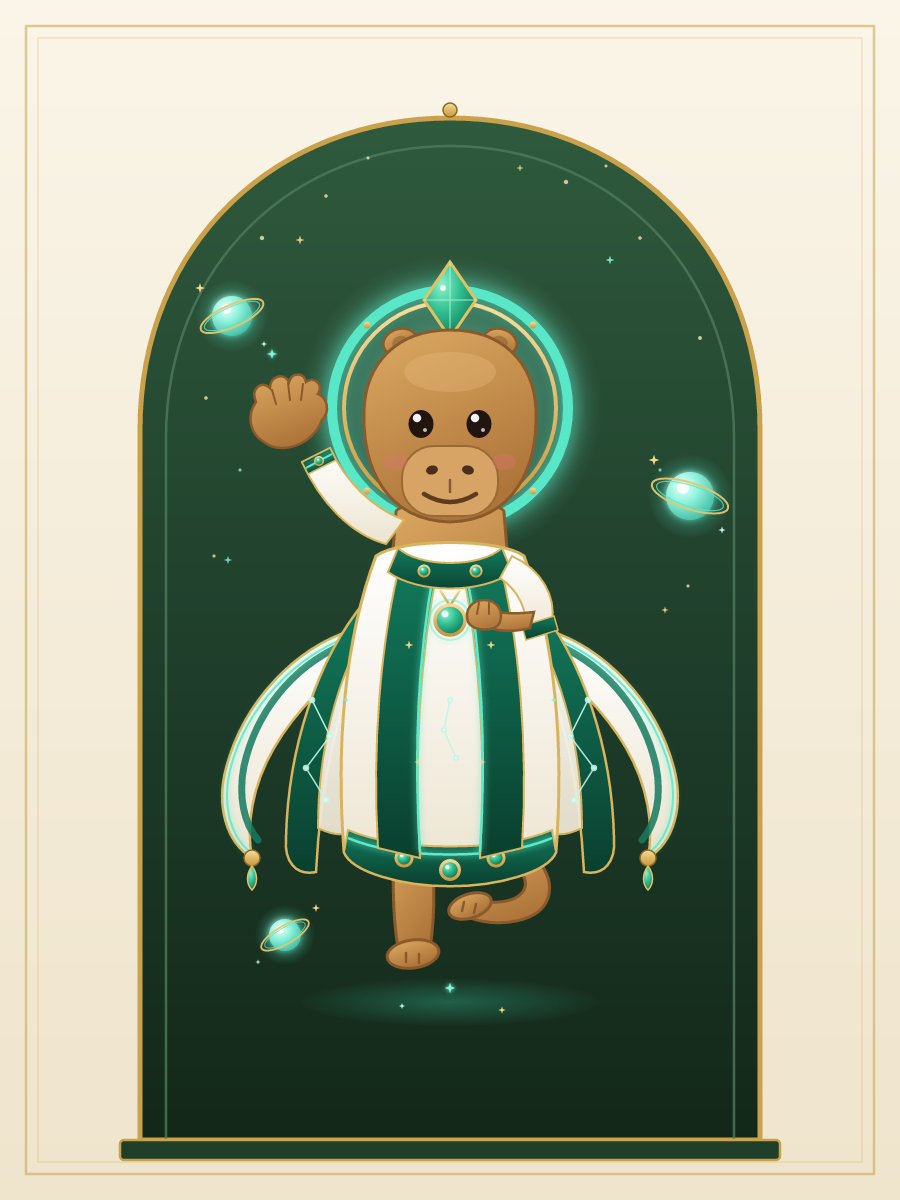
A floating capybara in ornate robes tests character anatomy, layered fabric and the placement of surrounding luminous forms.
First run
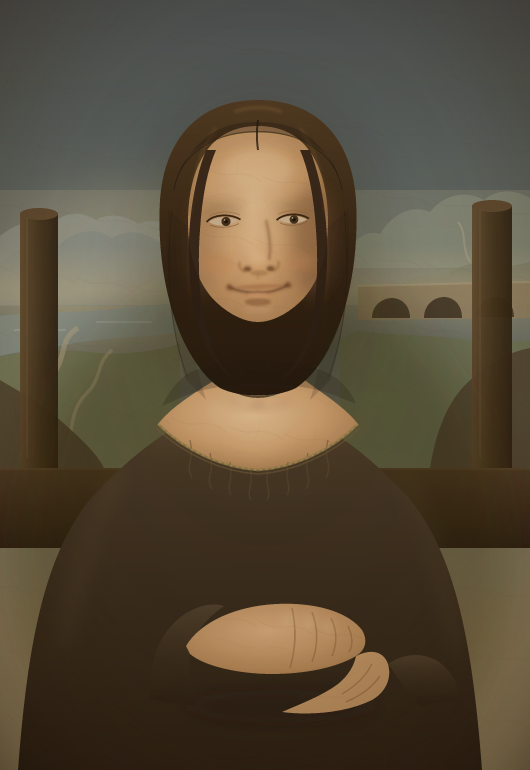
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
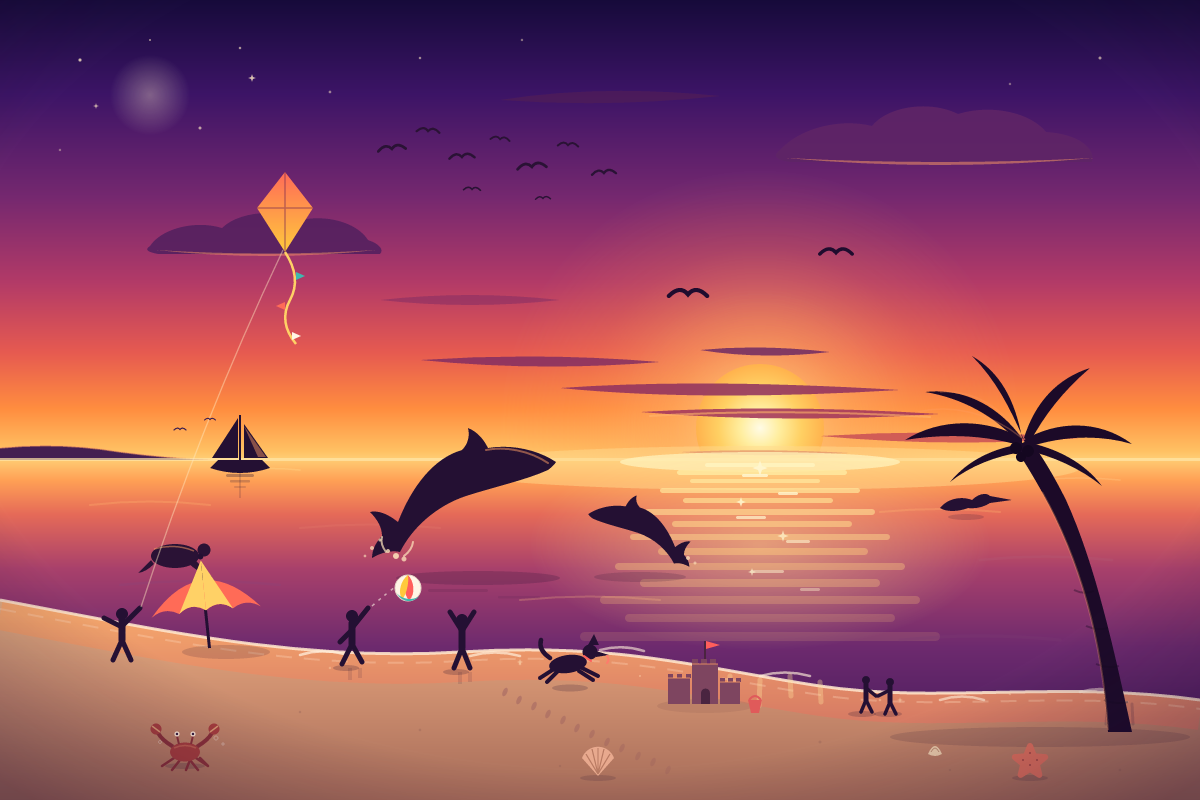
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
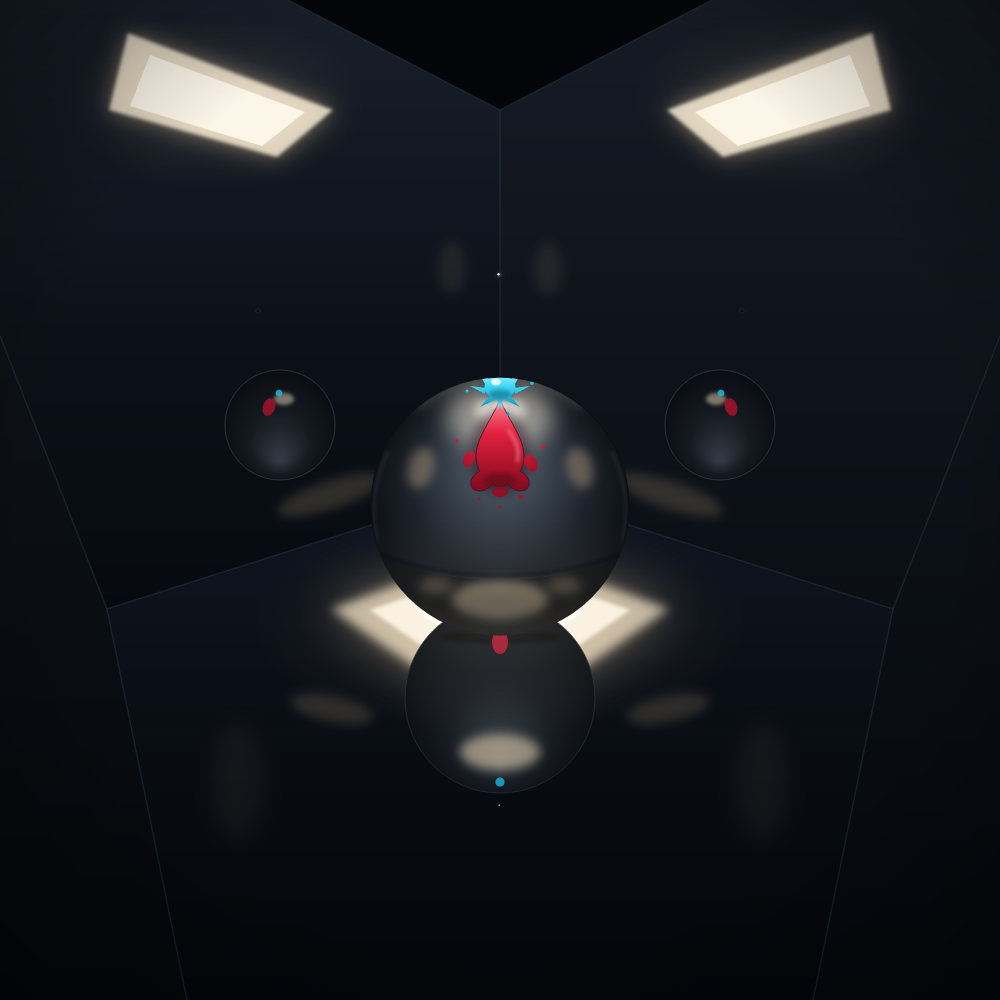
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
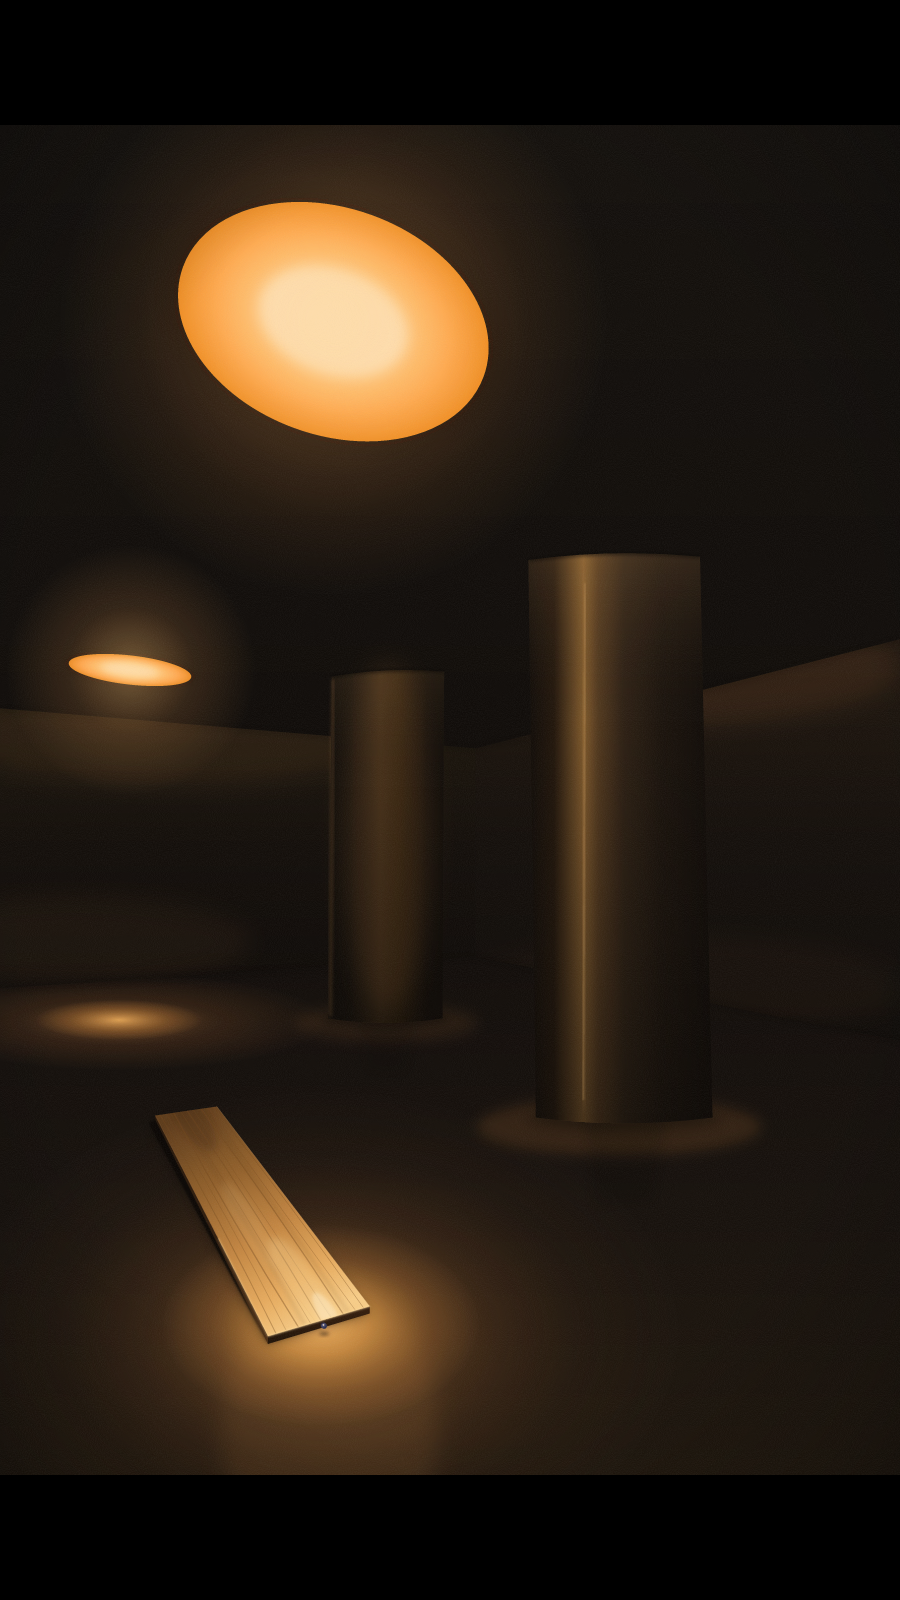
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
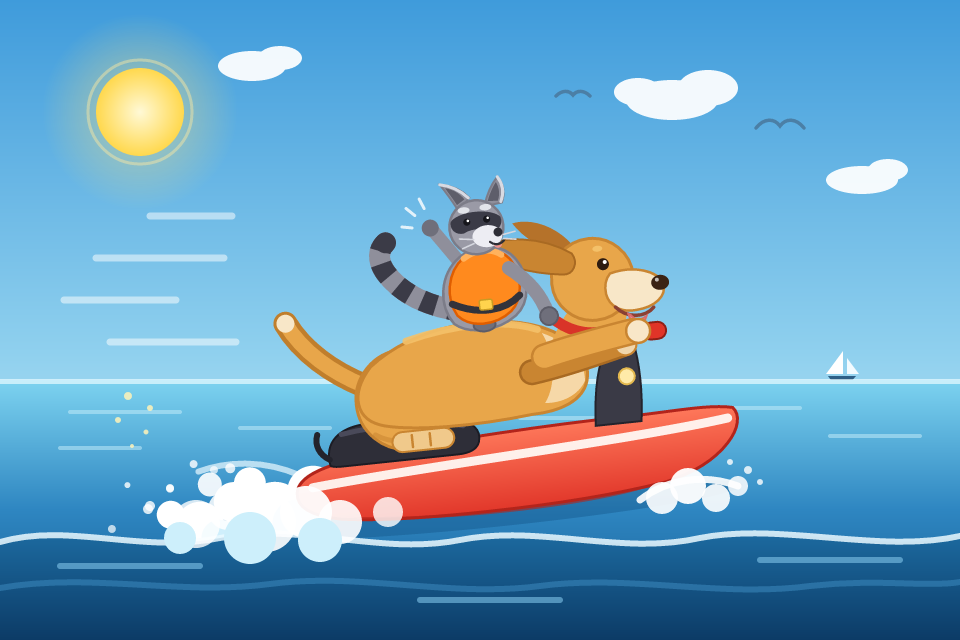
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
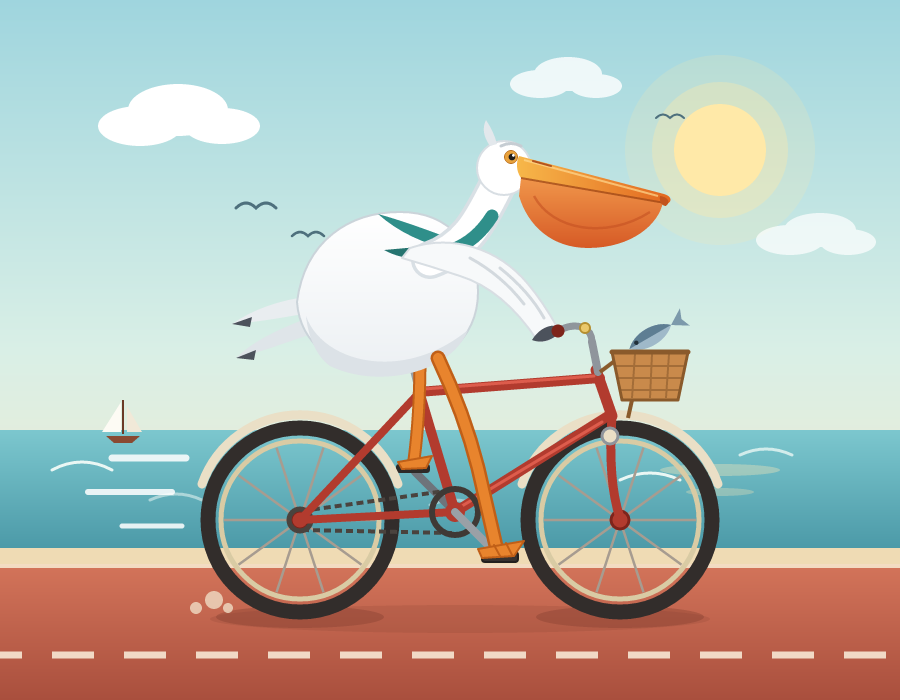
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

Model IDnvidia/nemotron-3-ultra-550b-a55b
StealthMarkOverall rank45/499 rated results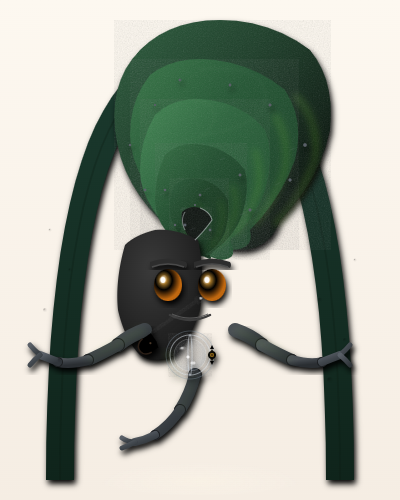
A hovering mechanical nautilus tests spiral construction, connected mechanical forms and contrasting metal and illuminated surfaces.
First run
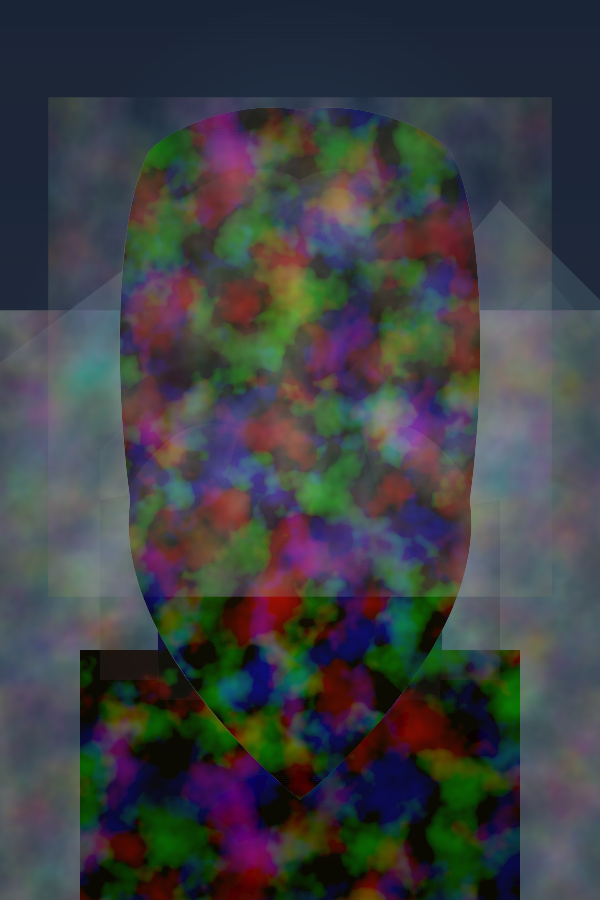
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
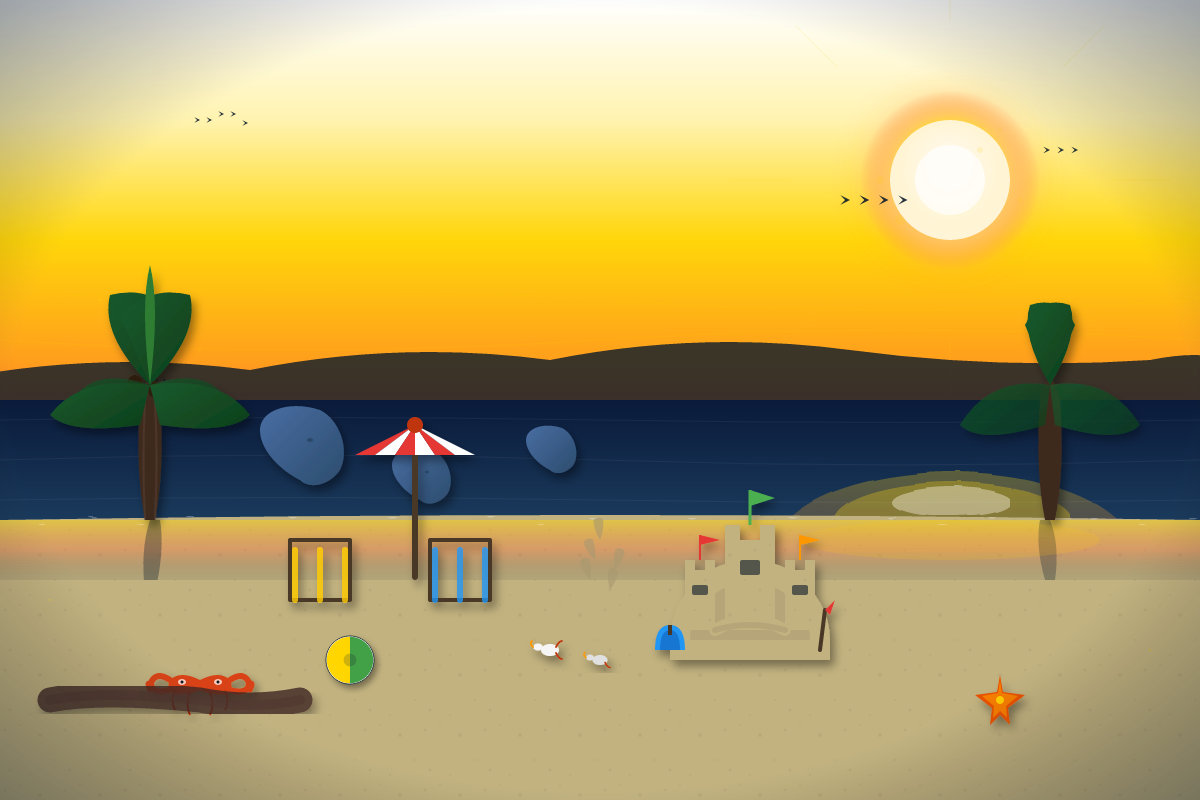
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
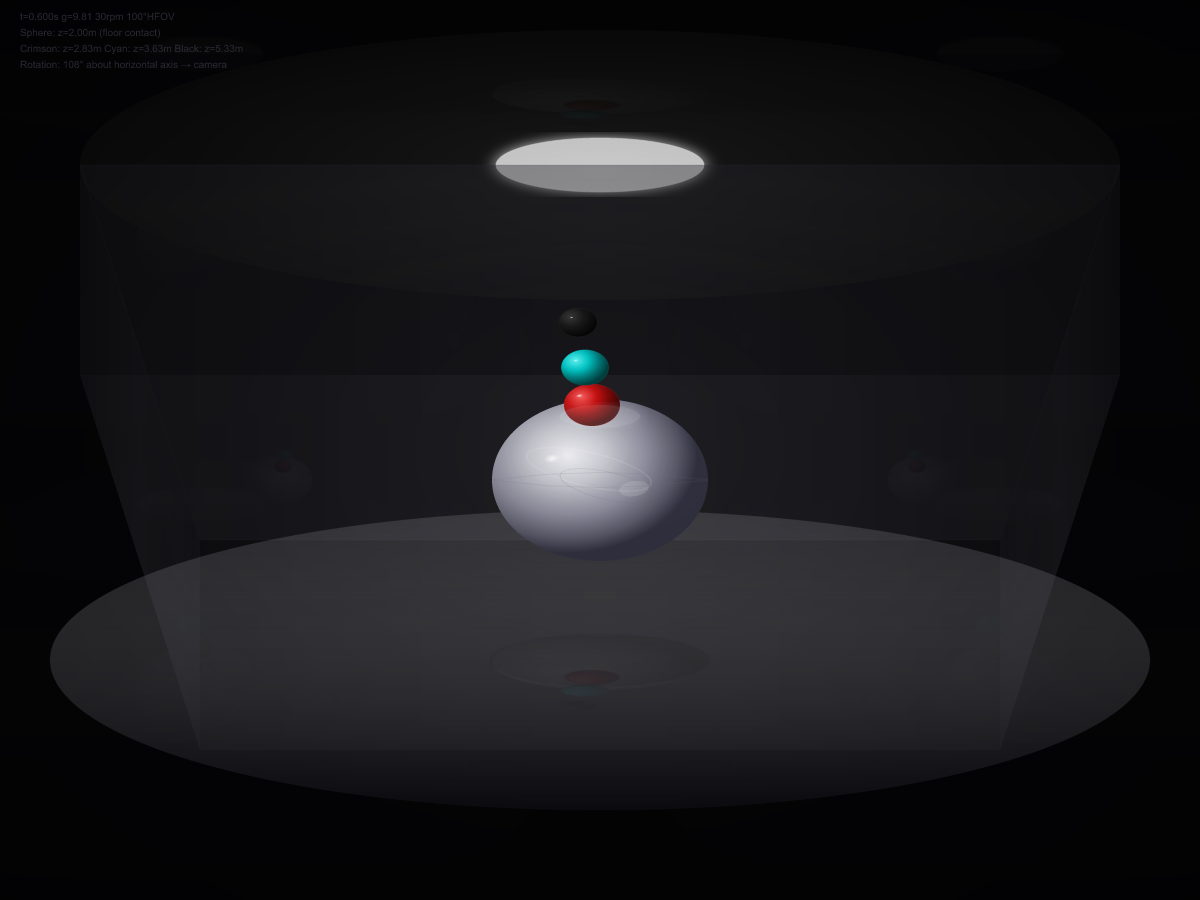
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
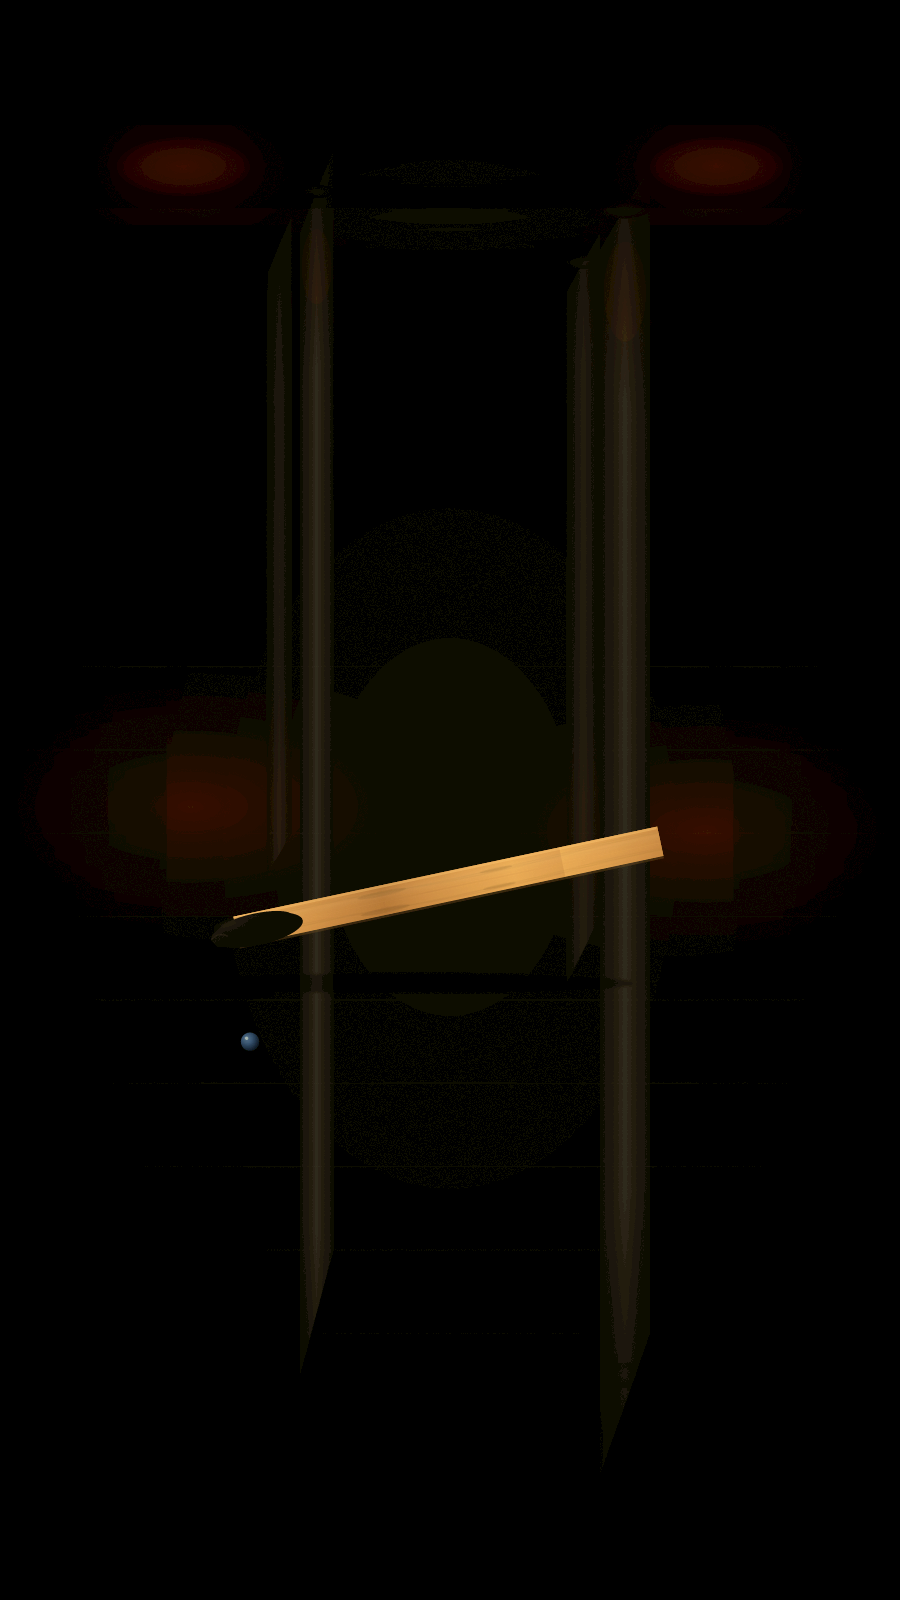
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
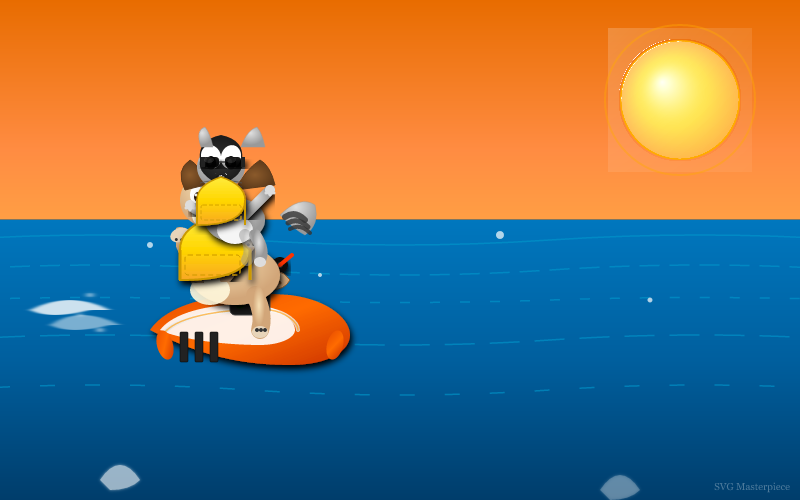
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
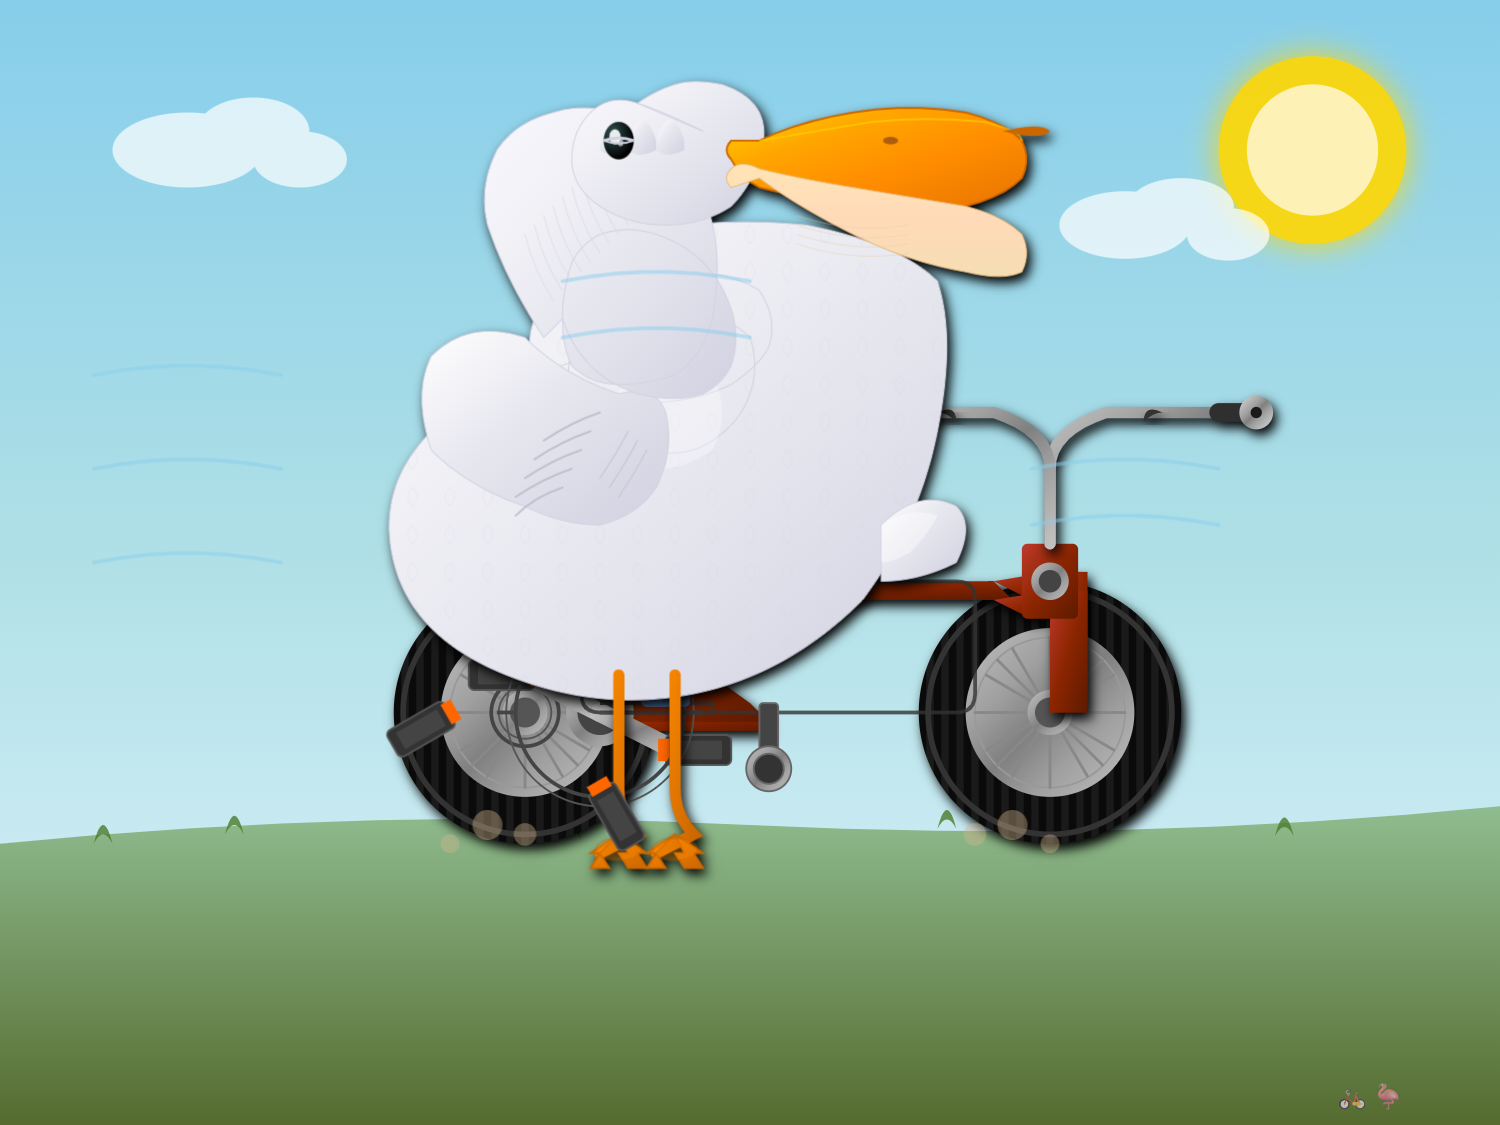
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache-2.0
Model IDAleph-Alpha/Kolibri-1
StealthMarkOverall rank48/497 rated results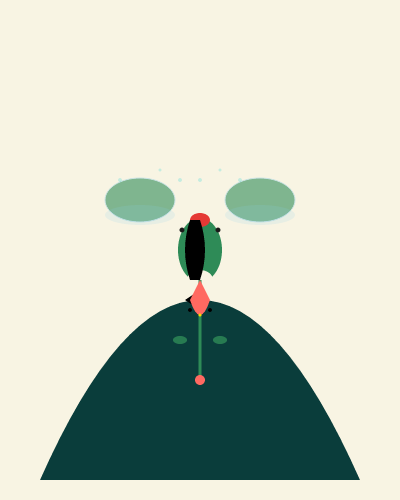
A jewel-coloured hummingbird hovering in flight tests avian anatomy, delicate structure and iridescent surface detail.
First run
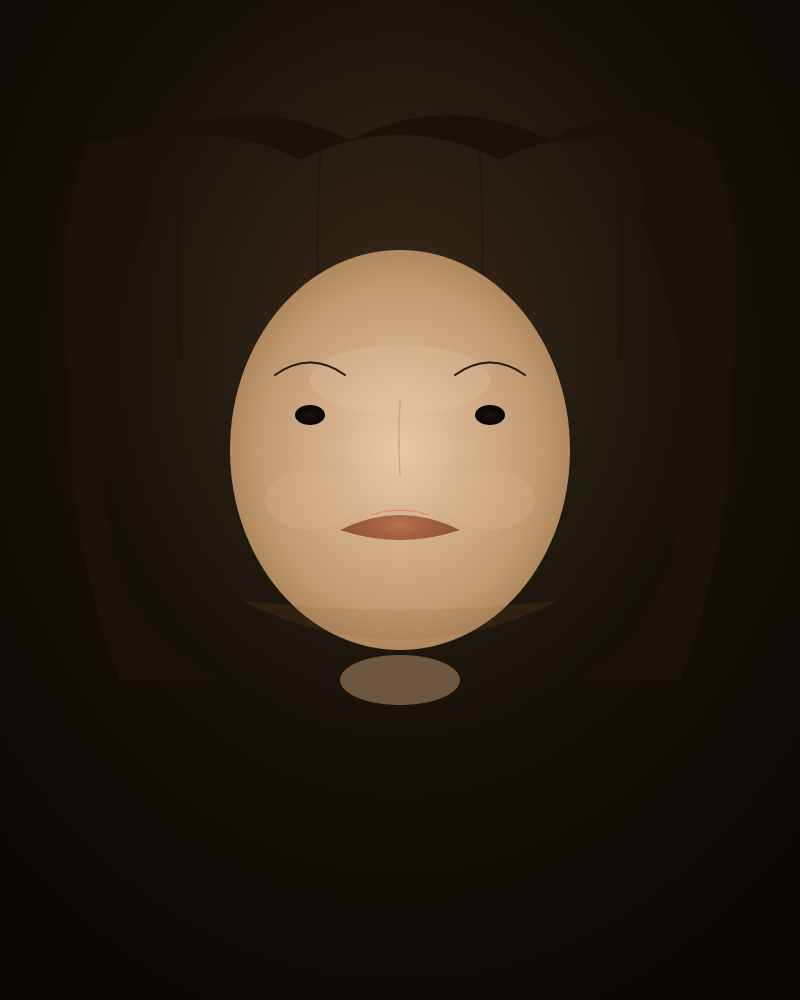
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
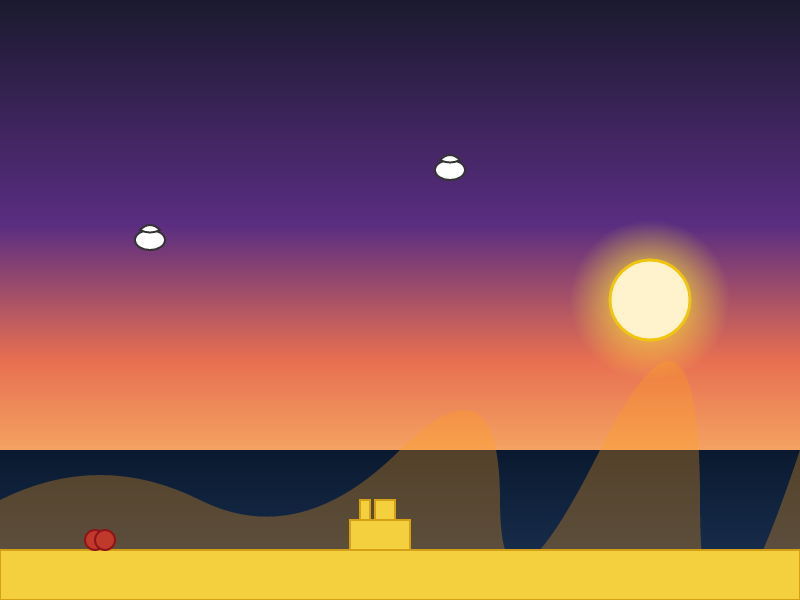
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
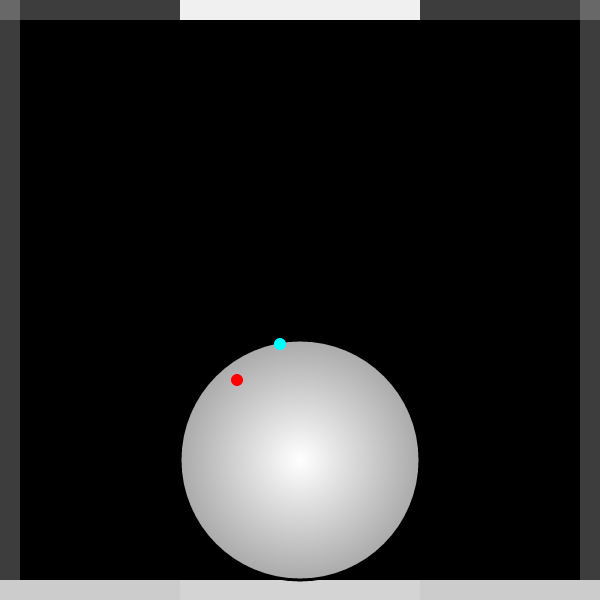
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
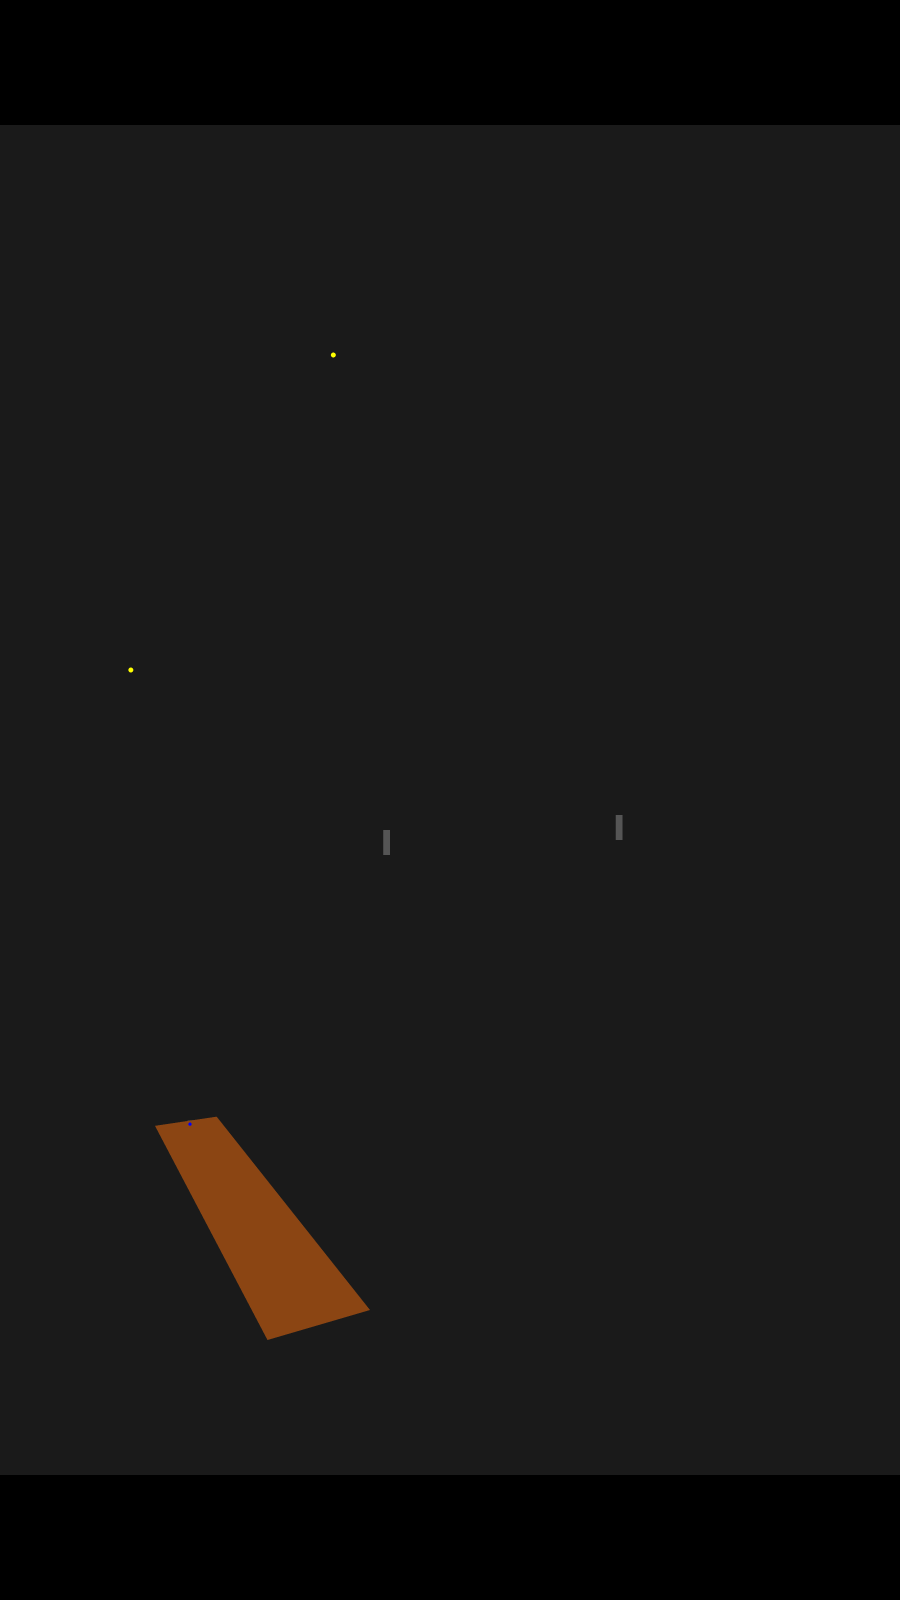
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
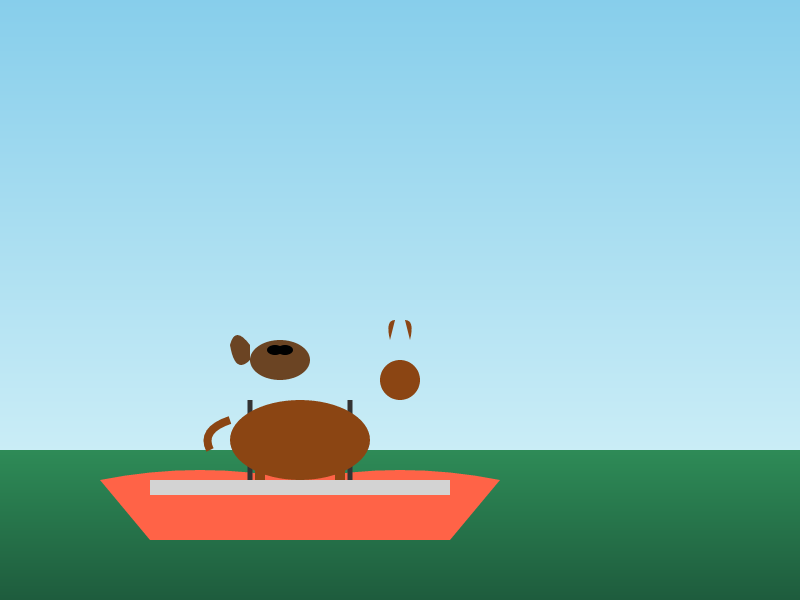
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
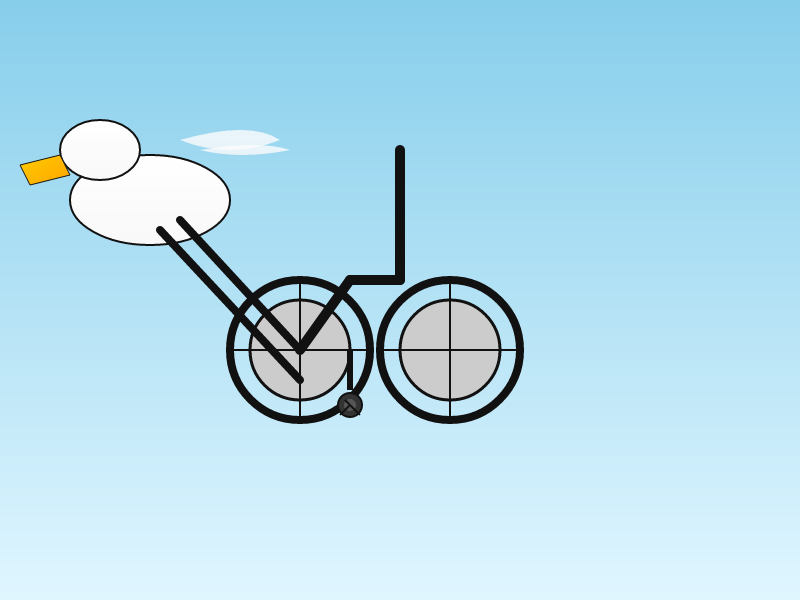
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache-2.0
Model IDqwen/qwen3.6-35b-a3b
StealthMarkOverall rank43/499 rated results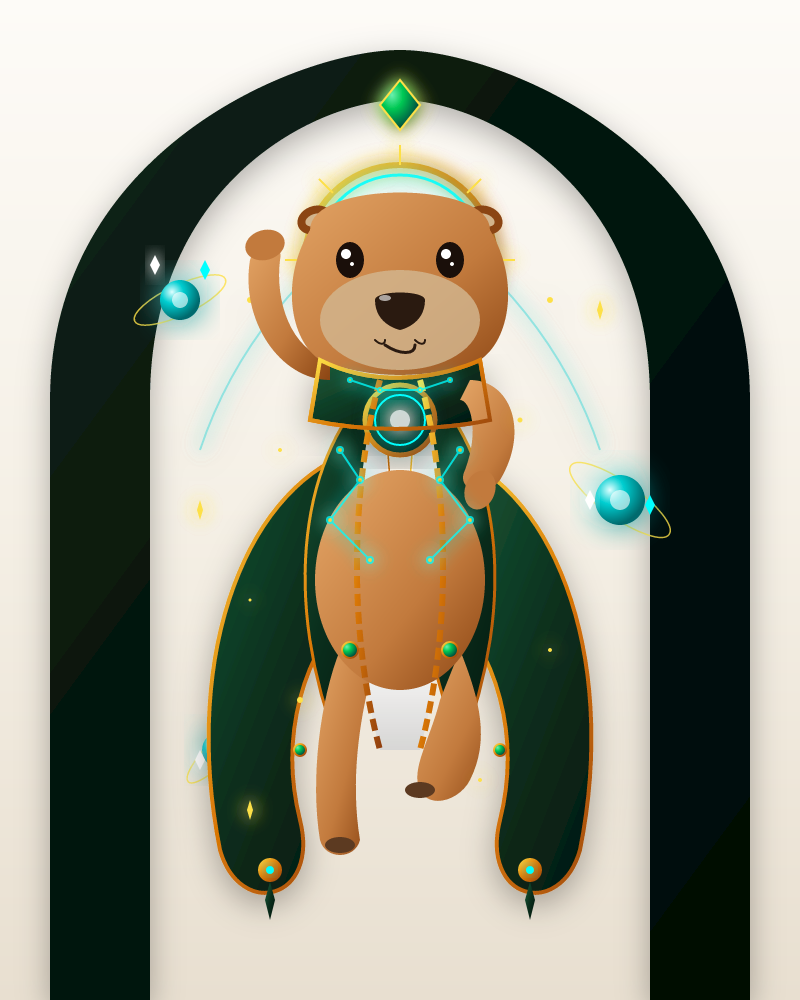
A floating capybara in ornate robes tests character anatomy, layered fabric and the placement of surrounding luminous forms.
First run
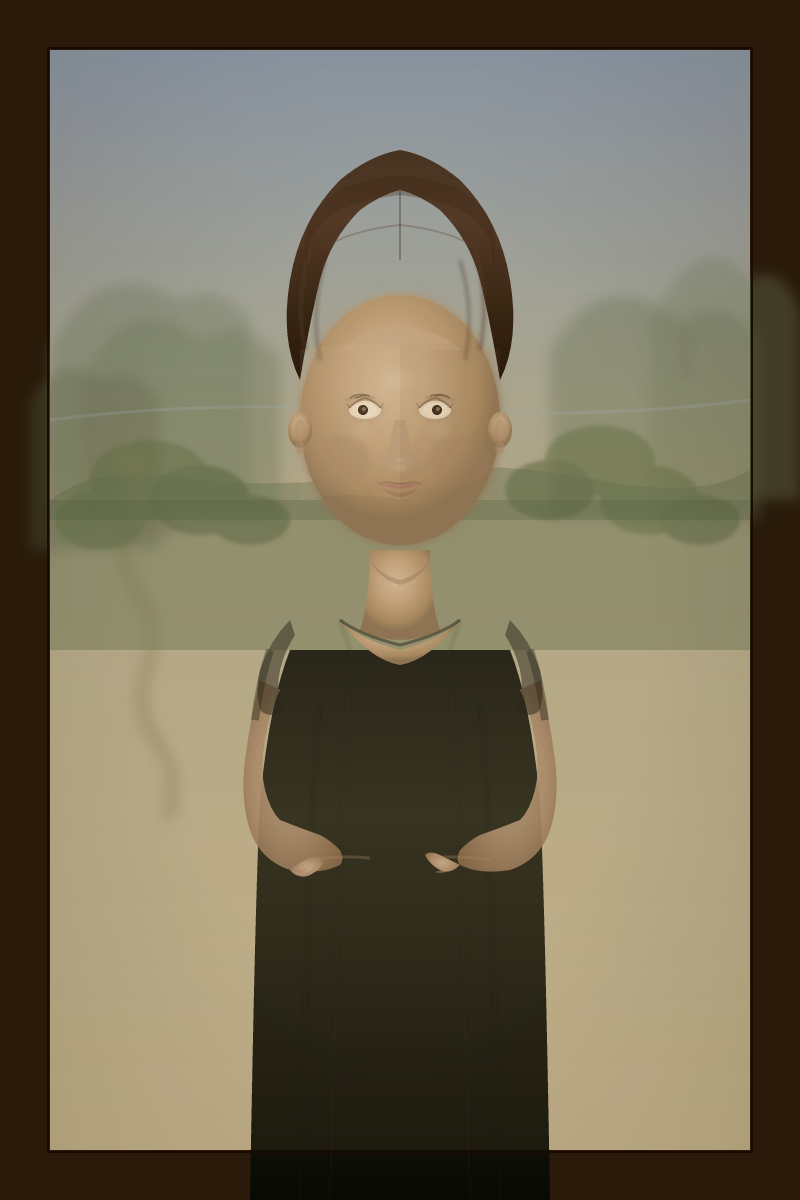
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
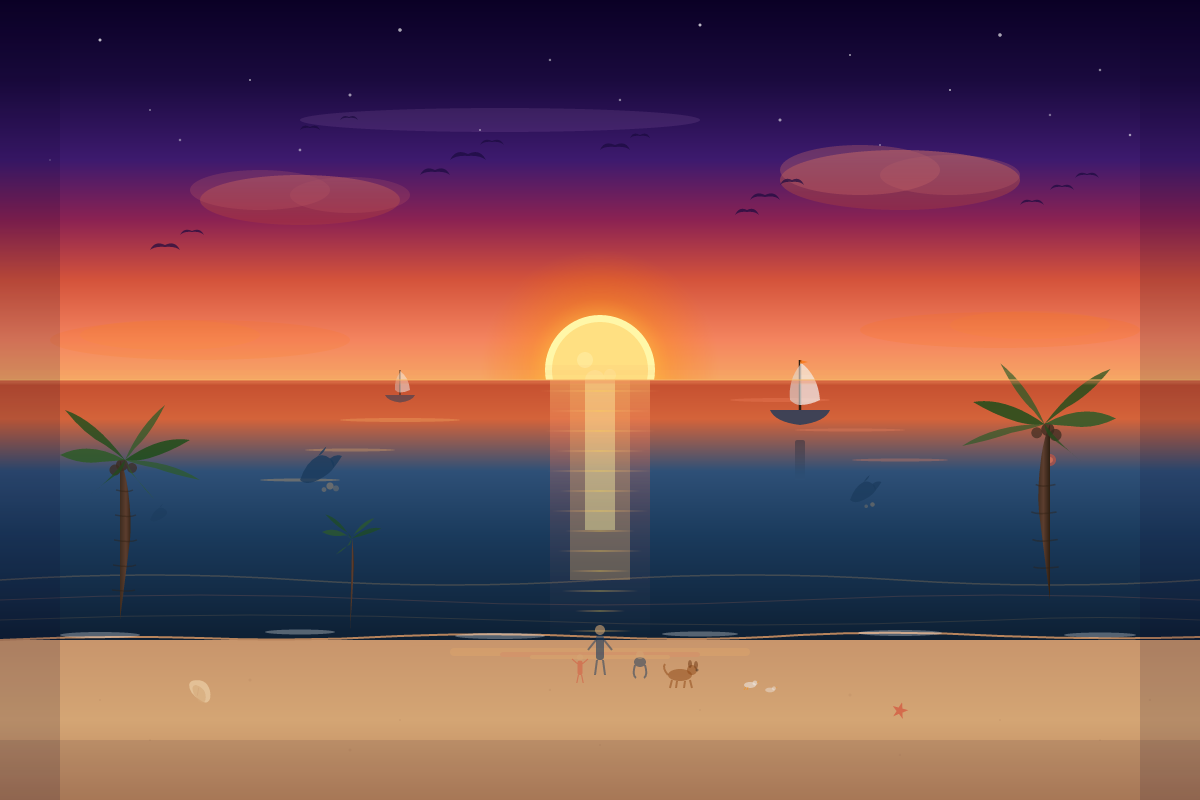
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
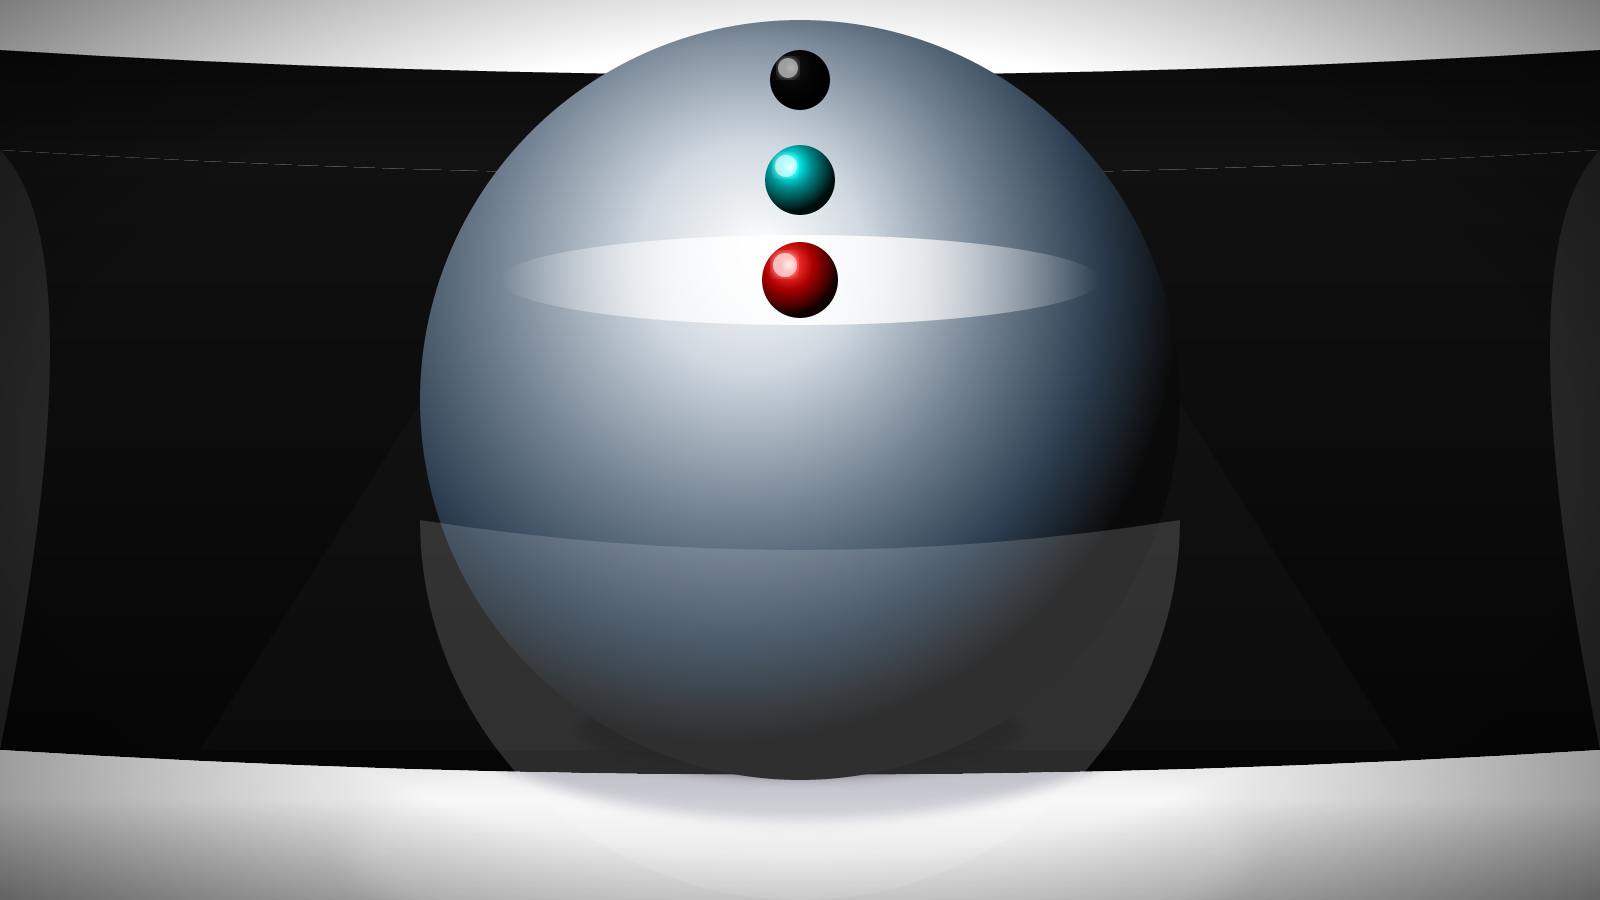
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
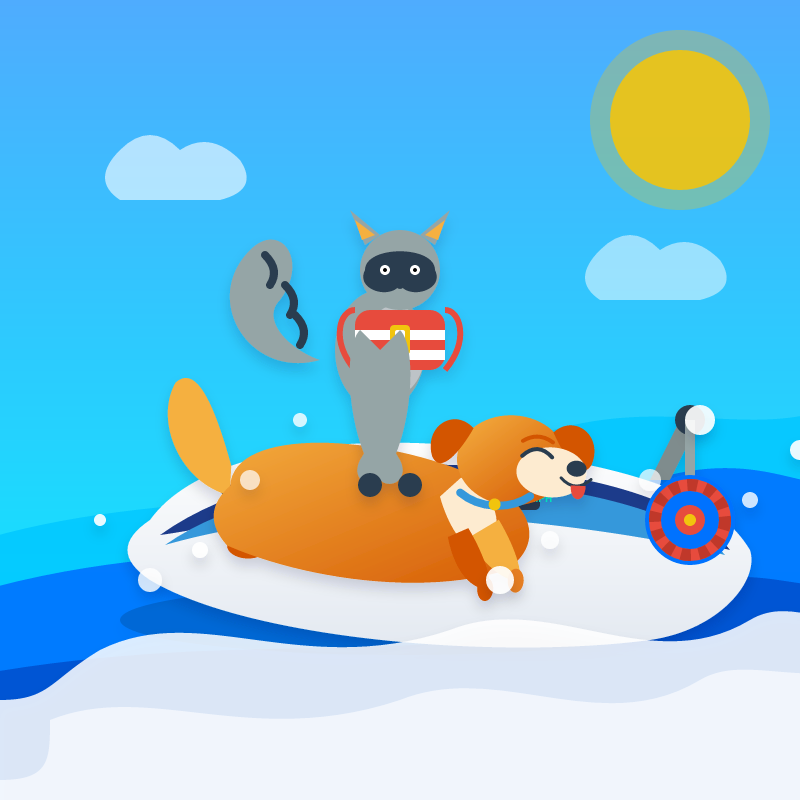
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
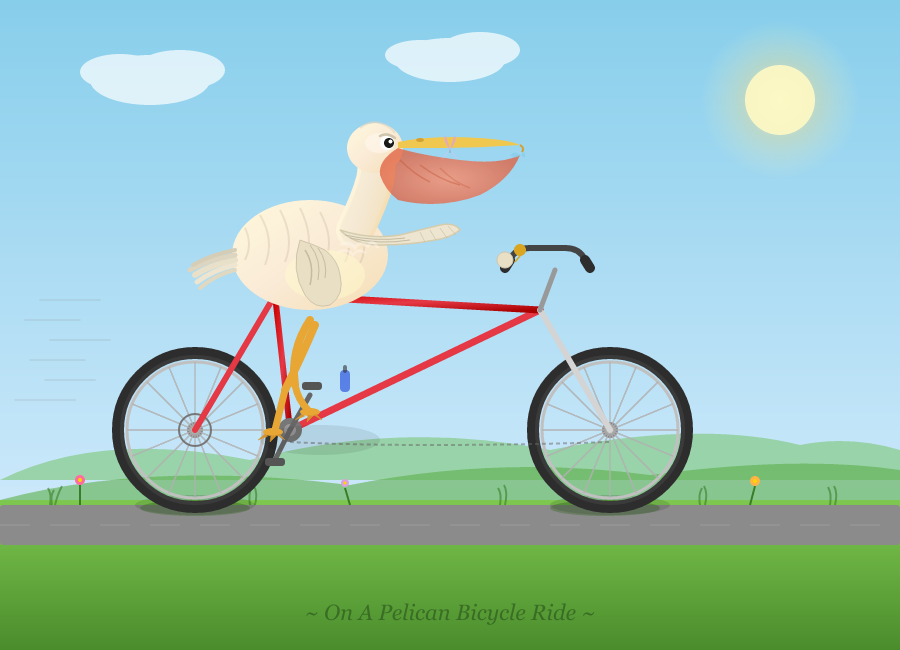
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache-2.0
Model IDqwen/qwen3.5-9b
StealthMarkOverall rank49/499 rated results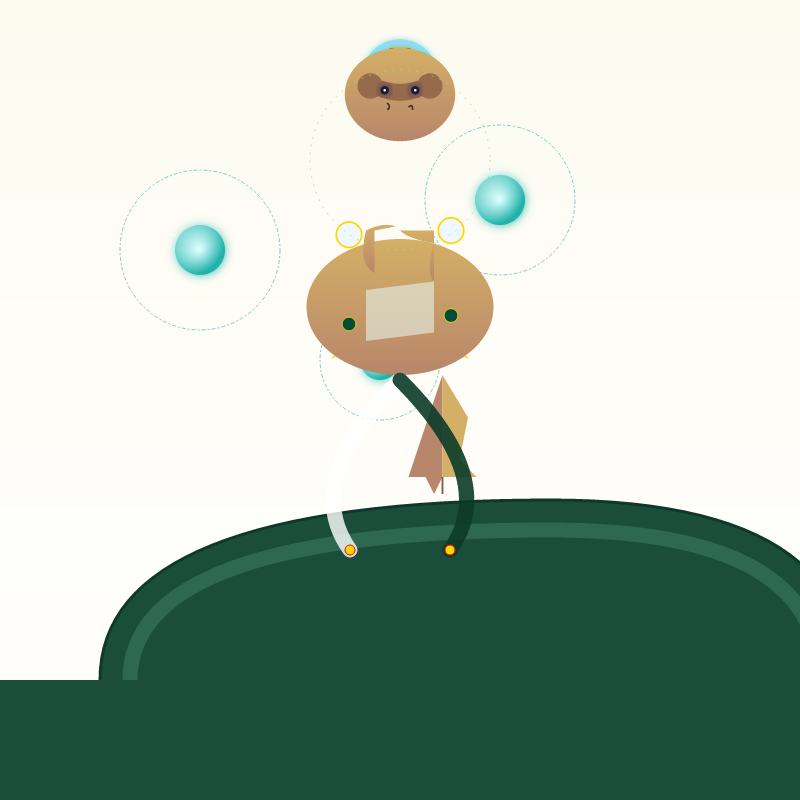
A floating capybara in ornate robes tests character anatomy, layered fabric and the placement of surrounding luminous forms.
First run
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
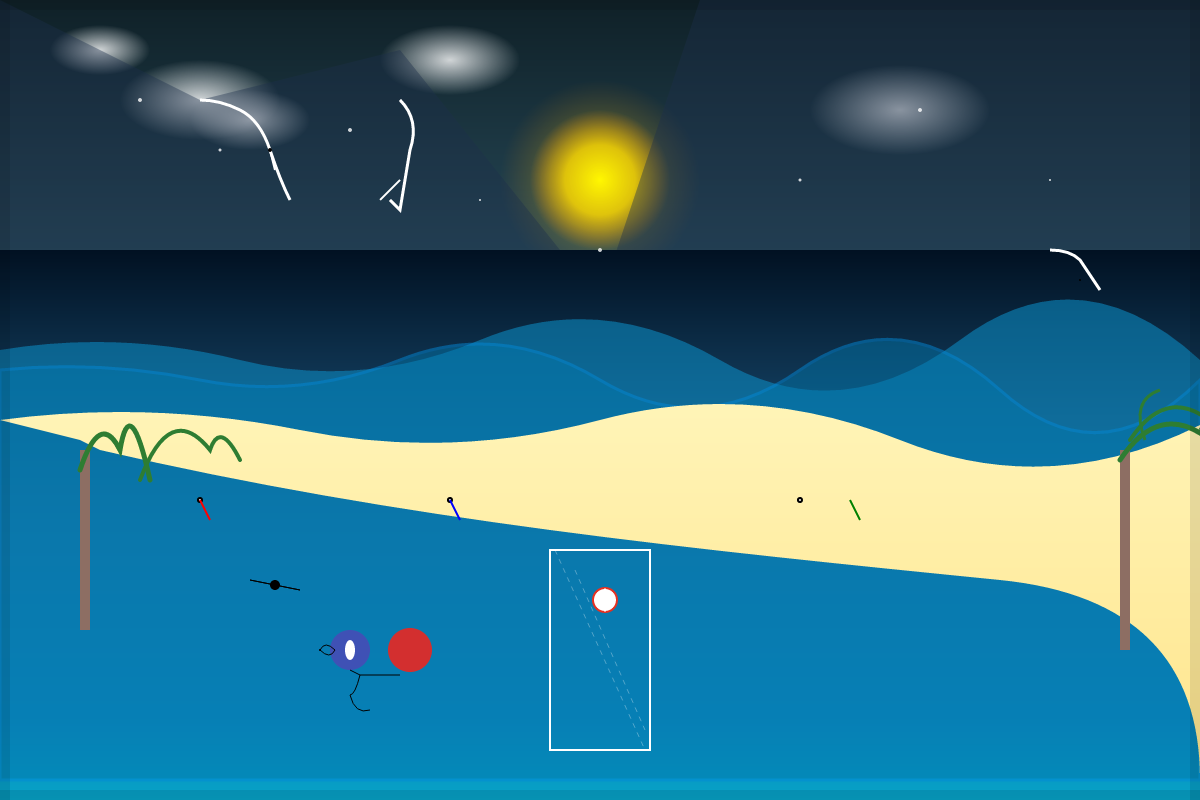
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
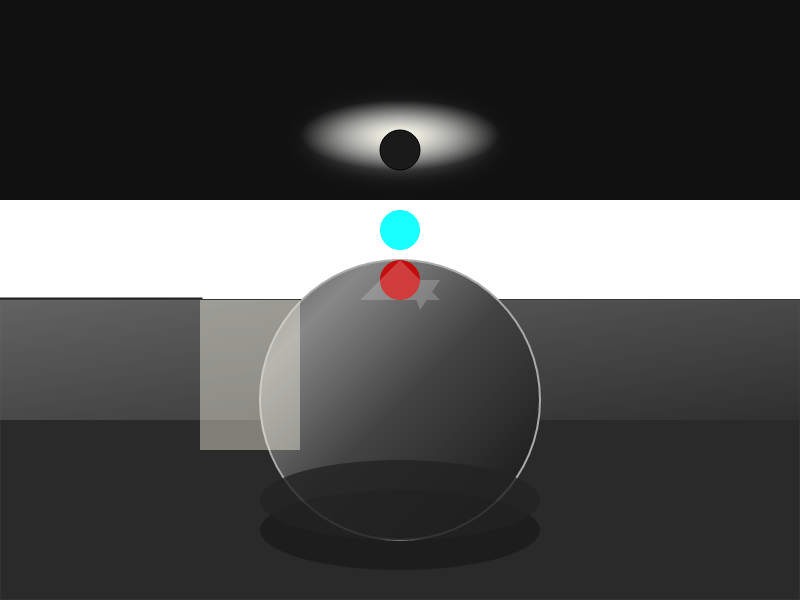
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
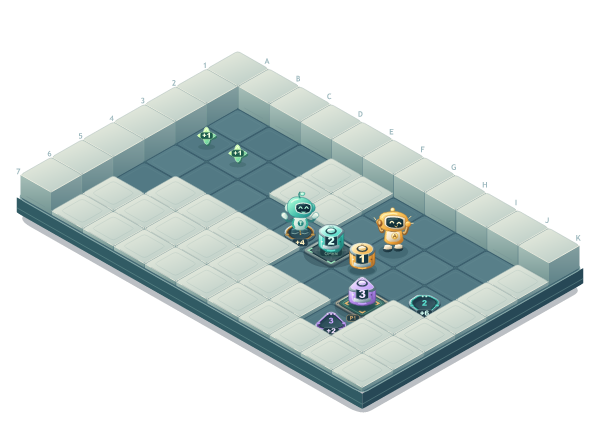
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
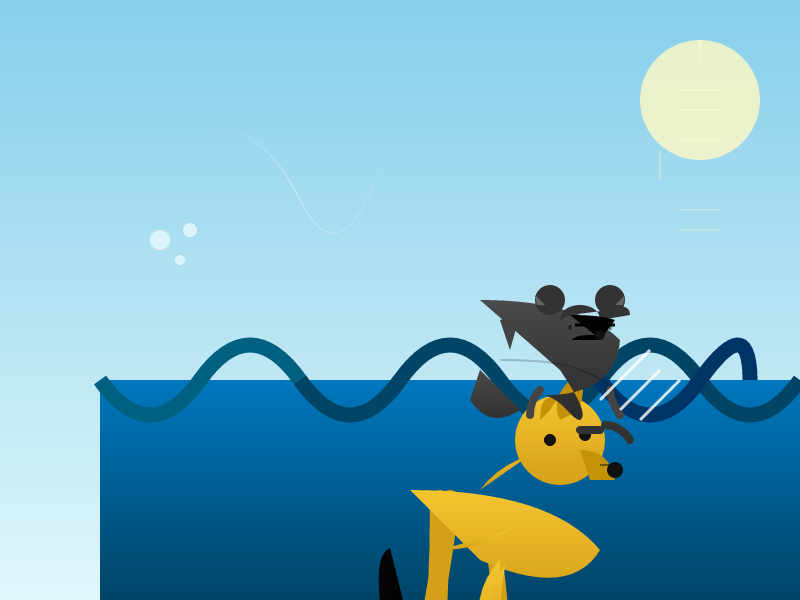
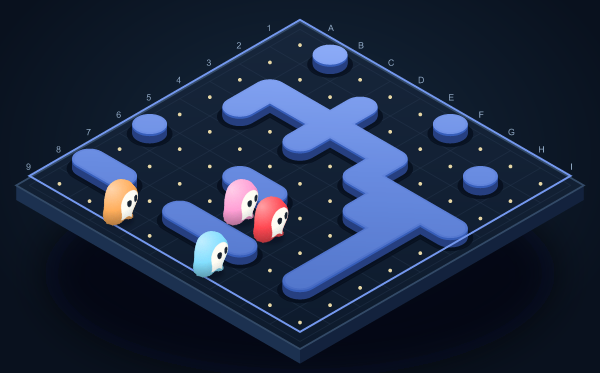
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
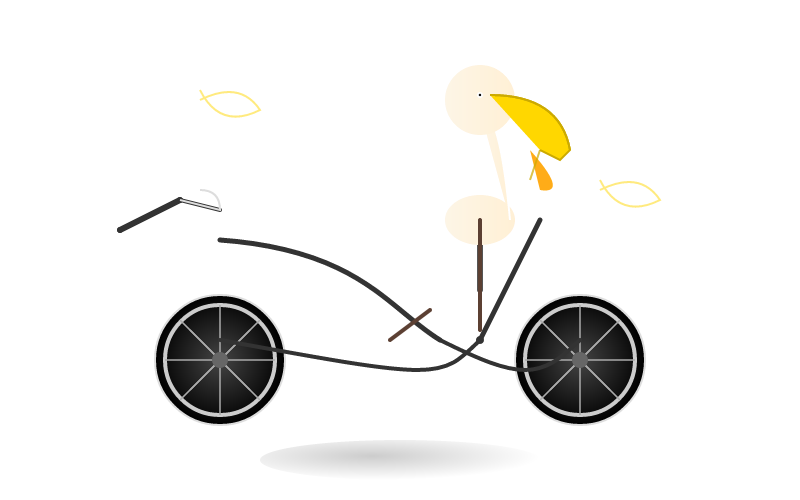
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run

LicenseMIT
Model IDinclusionai/ling-3.1-flash
StealthMarkOverall rank27/498 rated results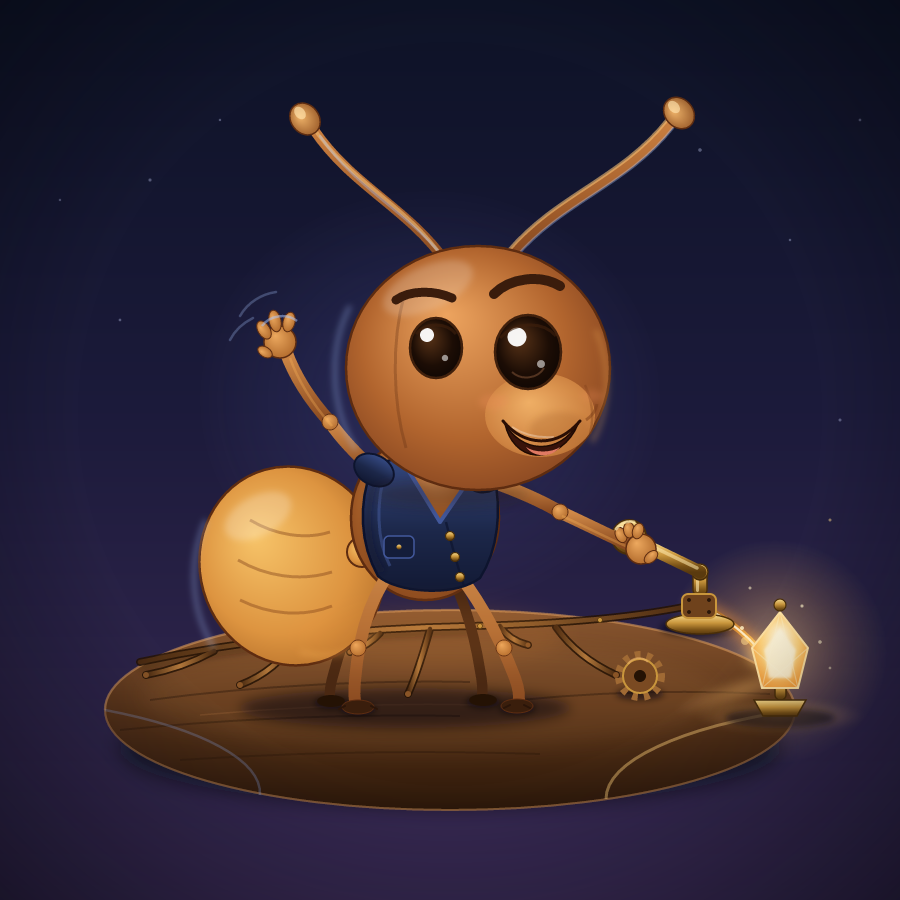
An ant tending signals in a miniature workshop tests insect anatomy, purposeful gestures and the placement of small objects in a lit environment.
First run
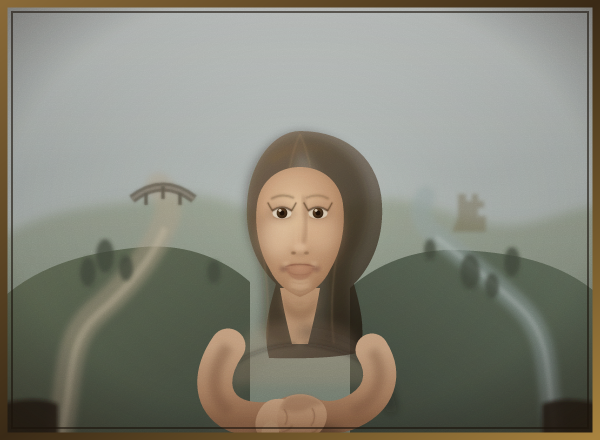
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
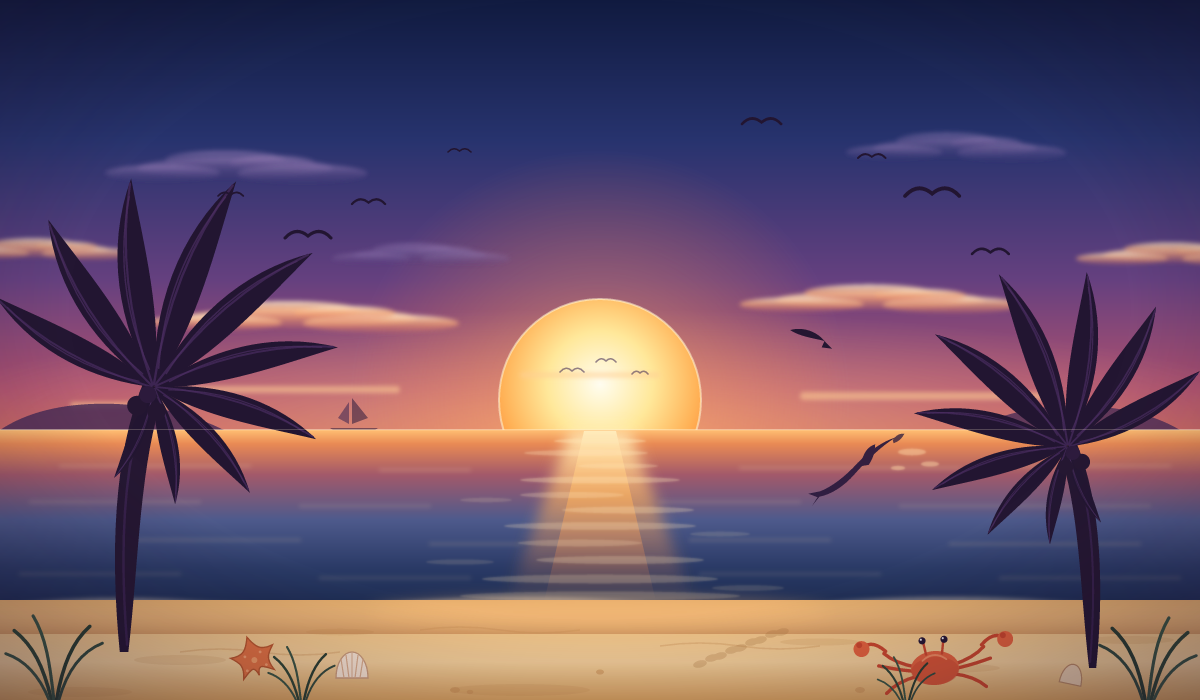
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
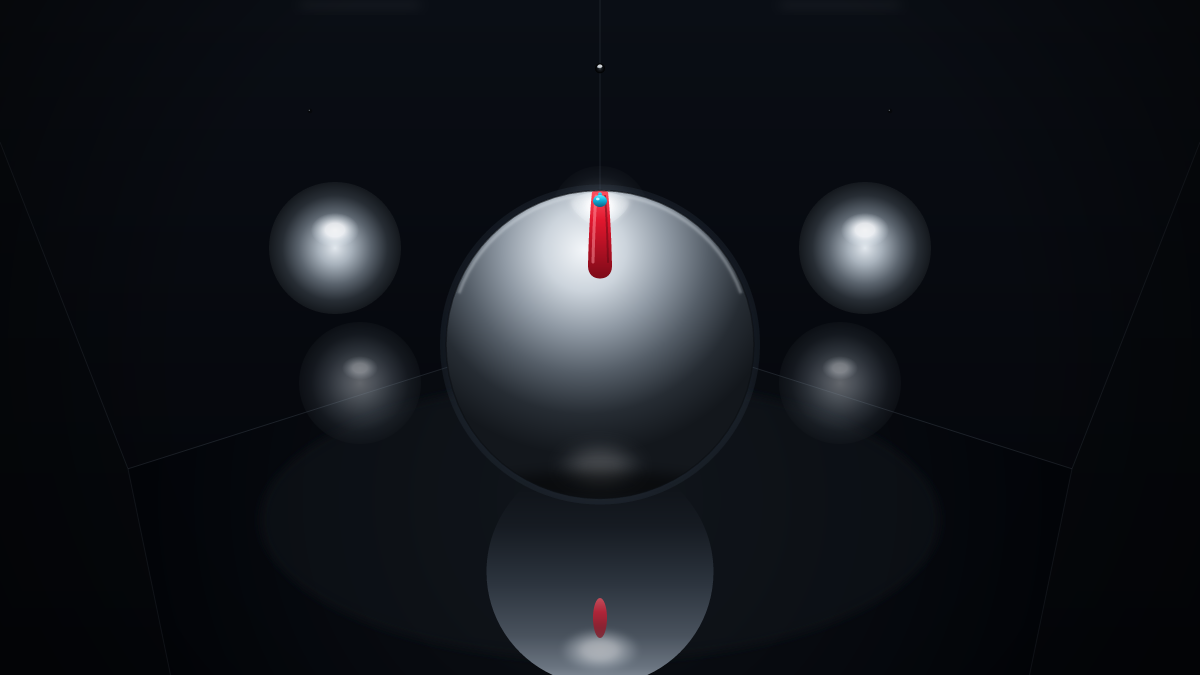
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
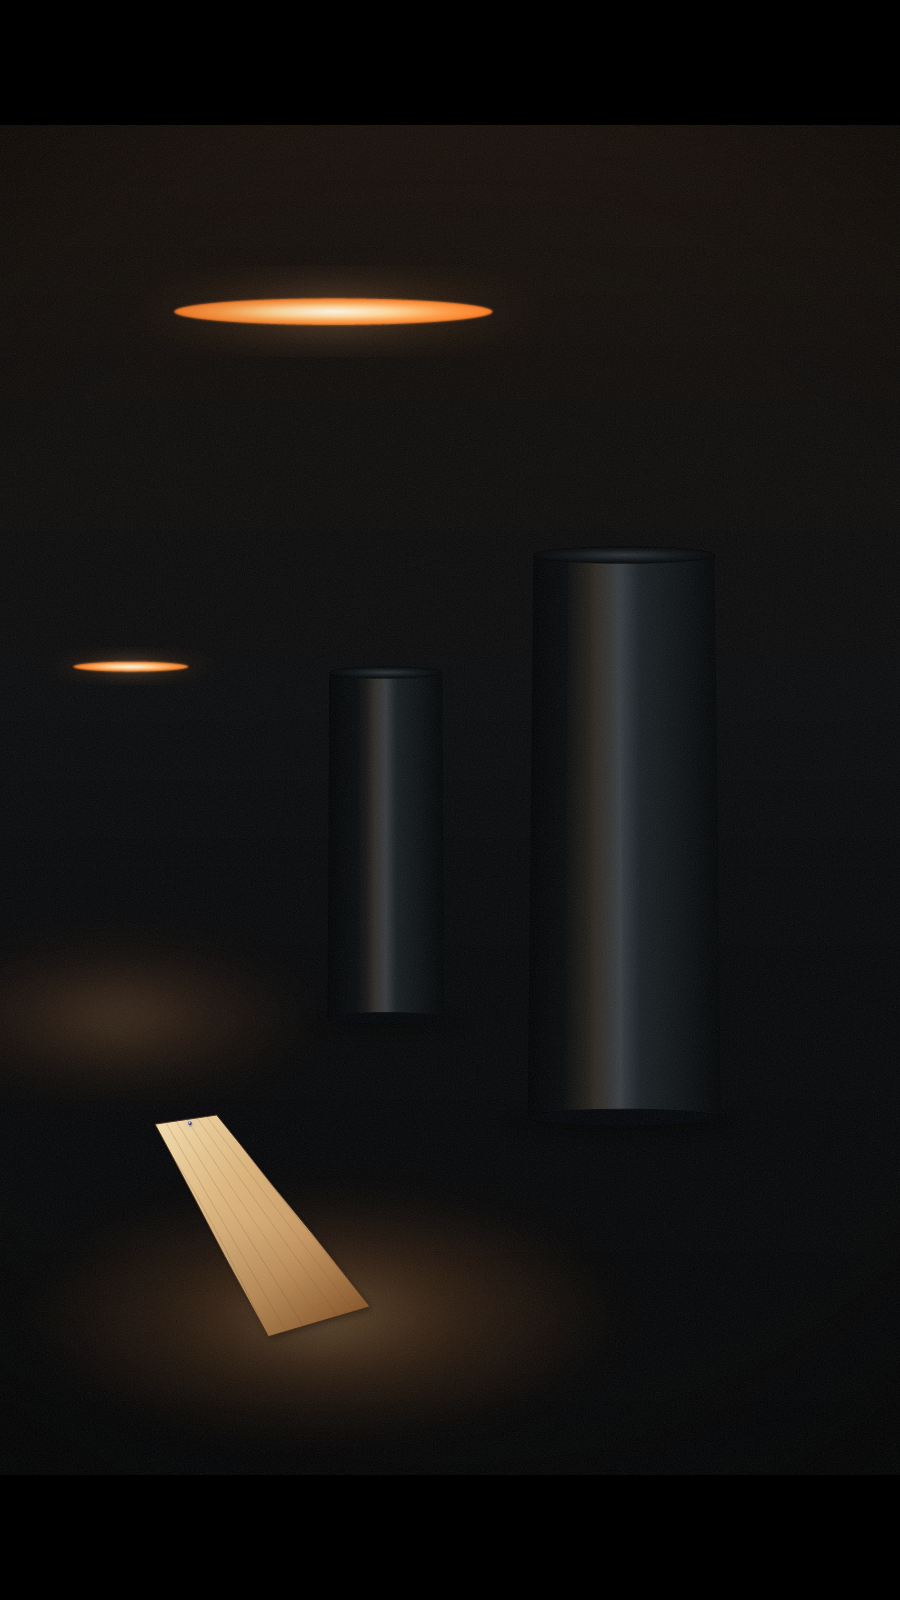
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
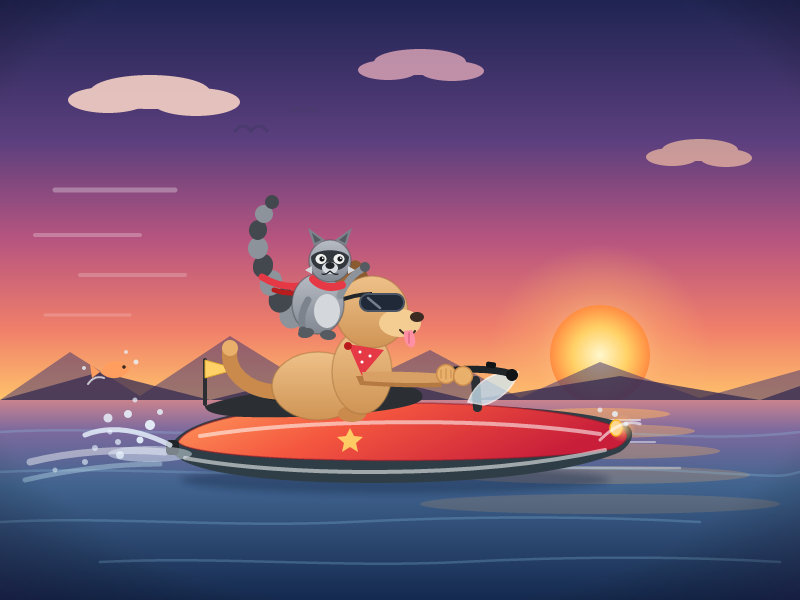
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
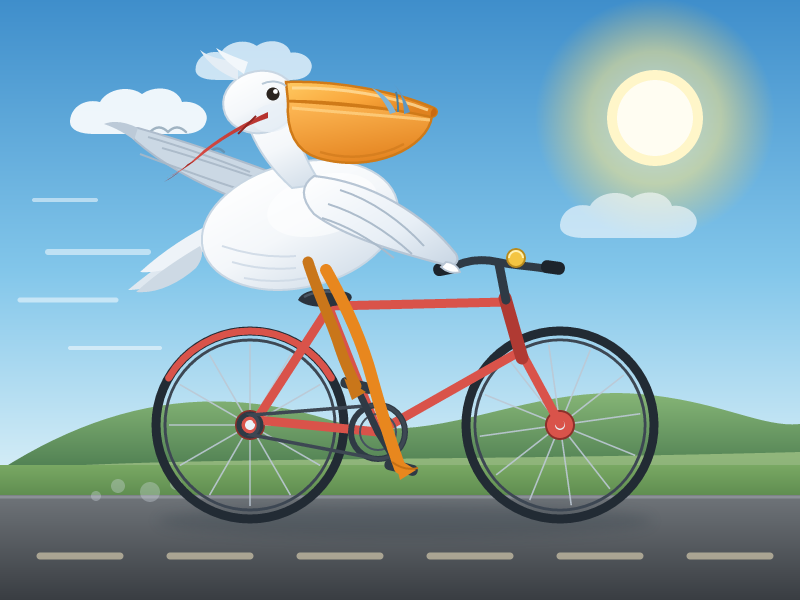
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseWeights and license coming soon
Model IDmistralai/mistral-large-4-0
StealthMarkOverall rank28/499 rated results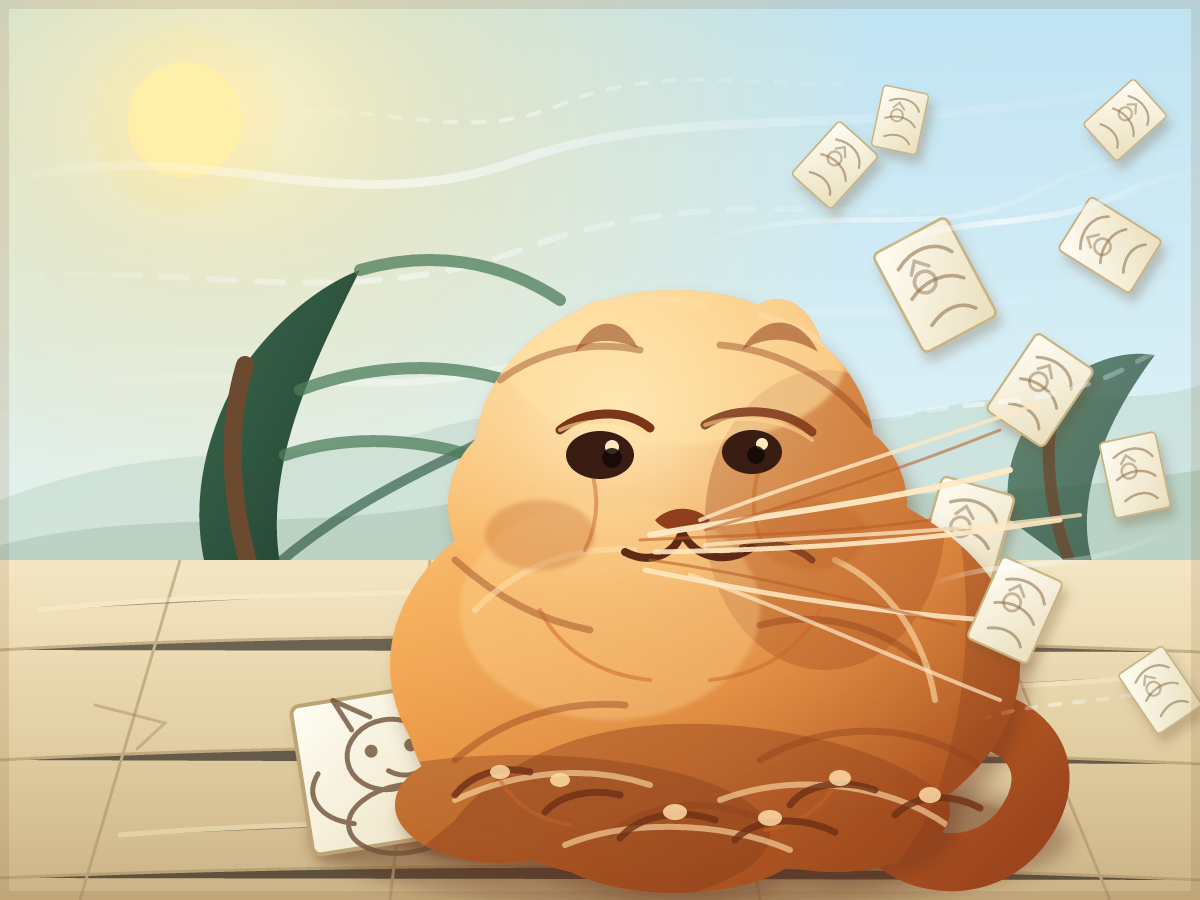
A heavy ginger cat stays planted on a terrace as wind carries papers around it. The scene tests weight, expression and the contrast between stable and moving forms.
First run
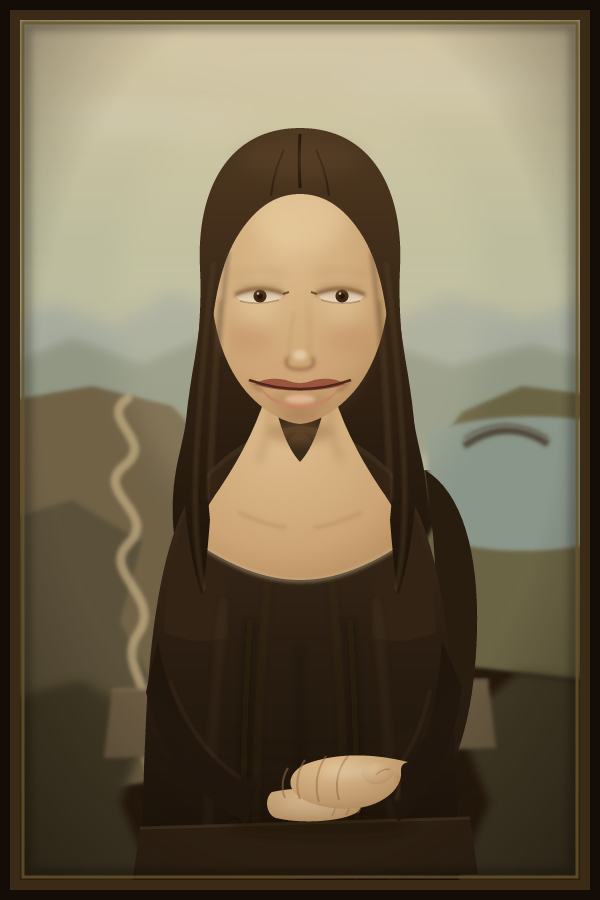
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
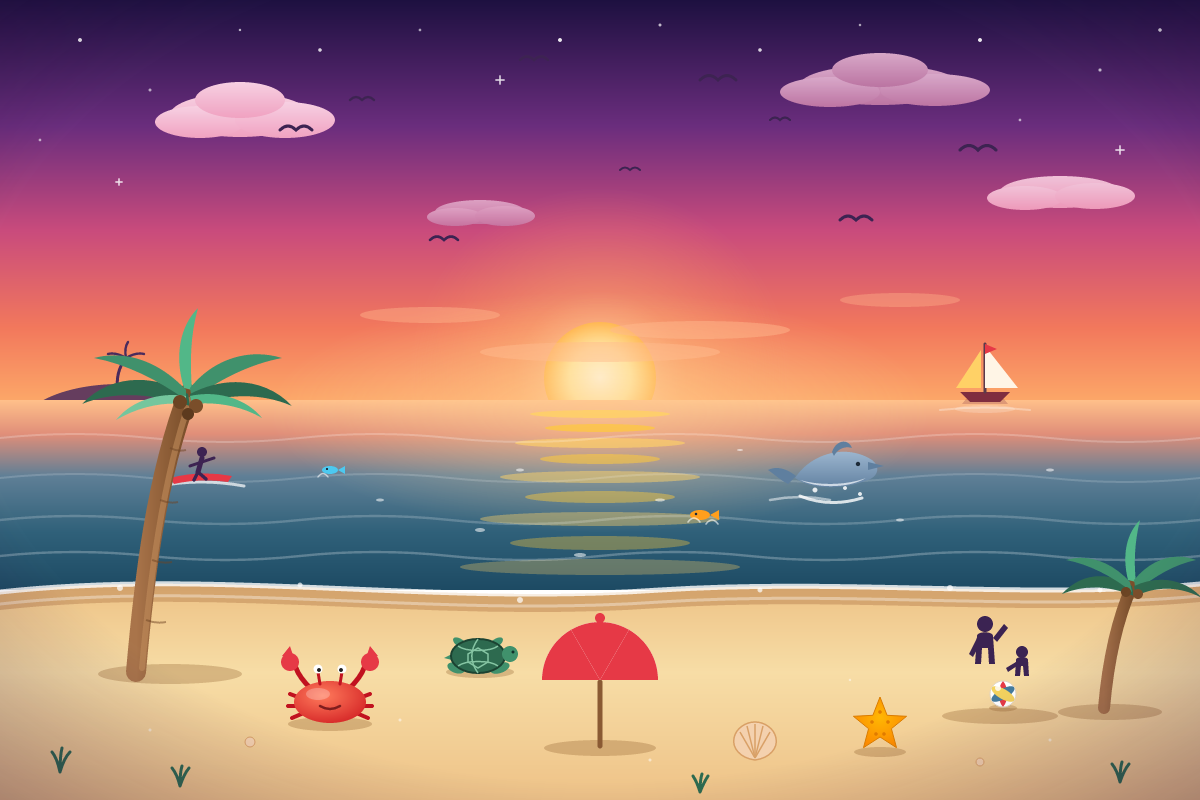
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
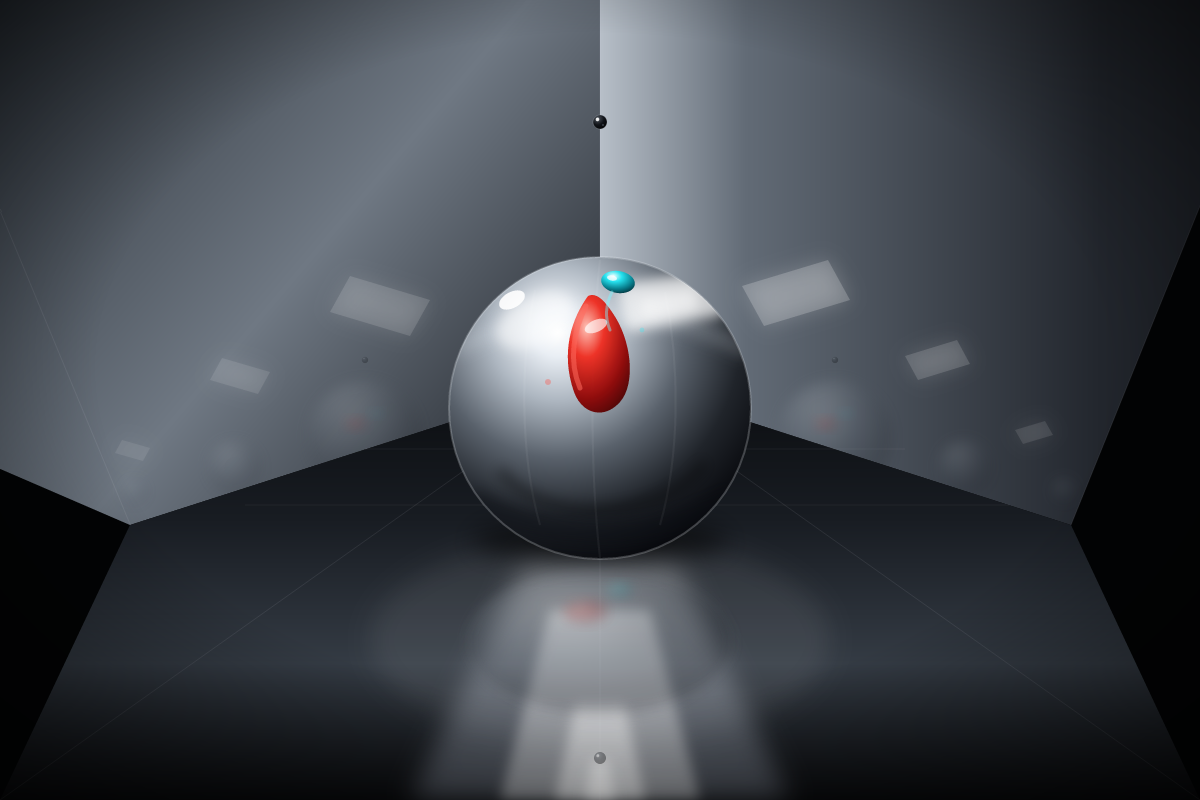
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
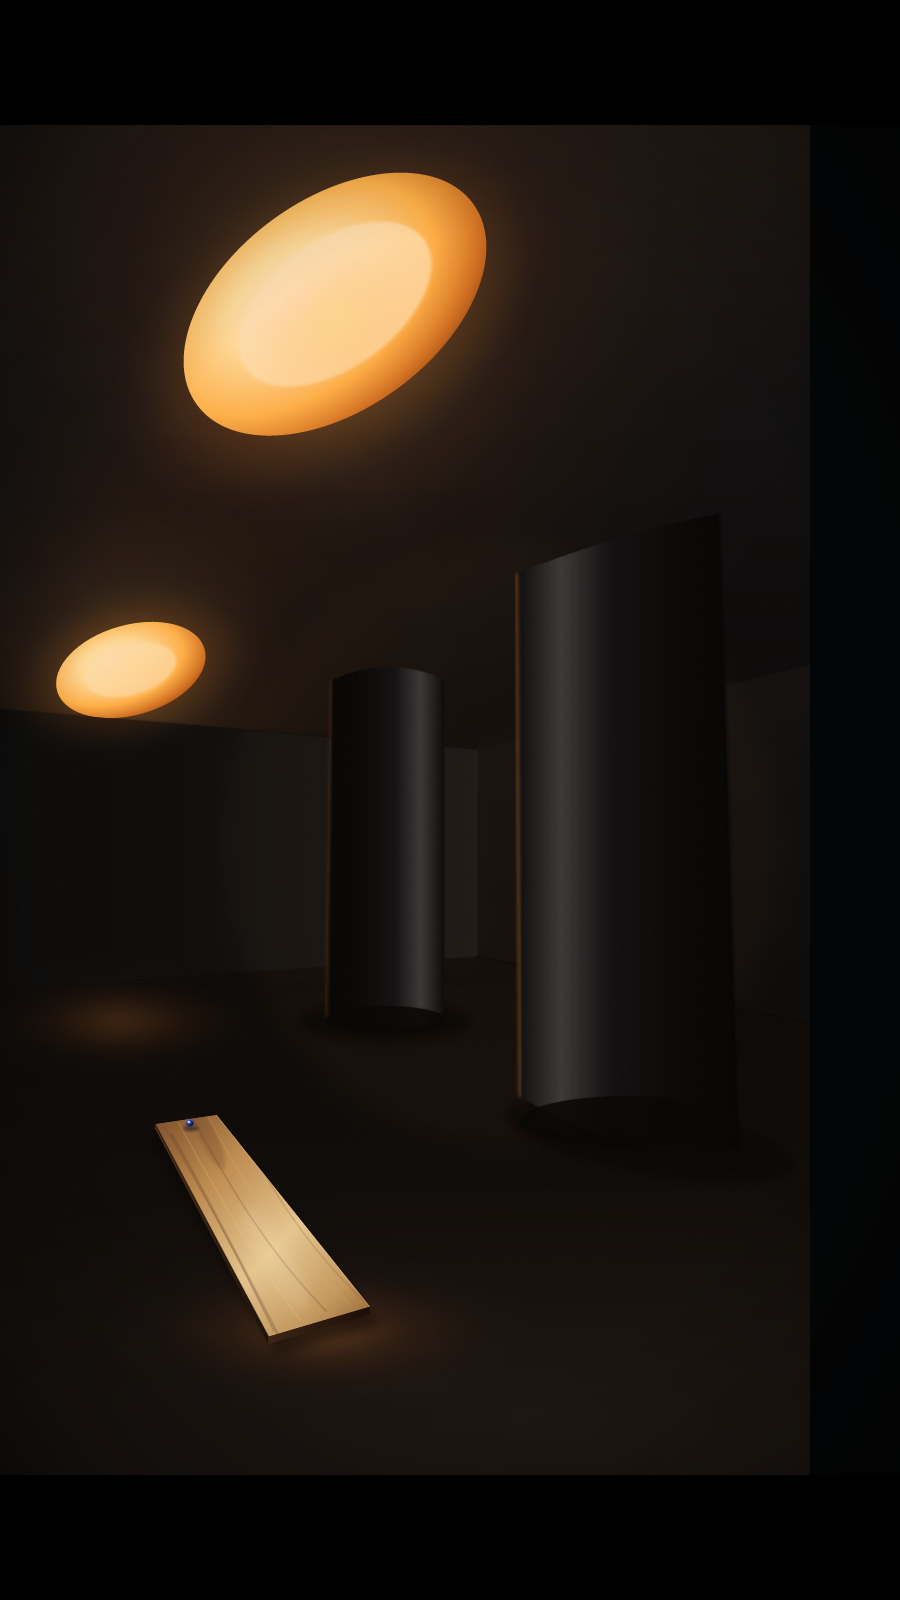
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
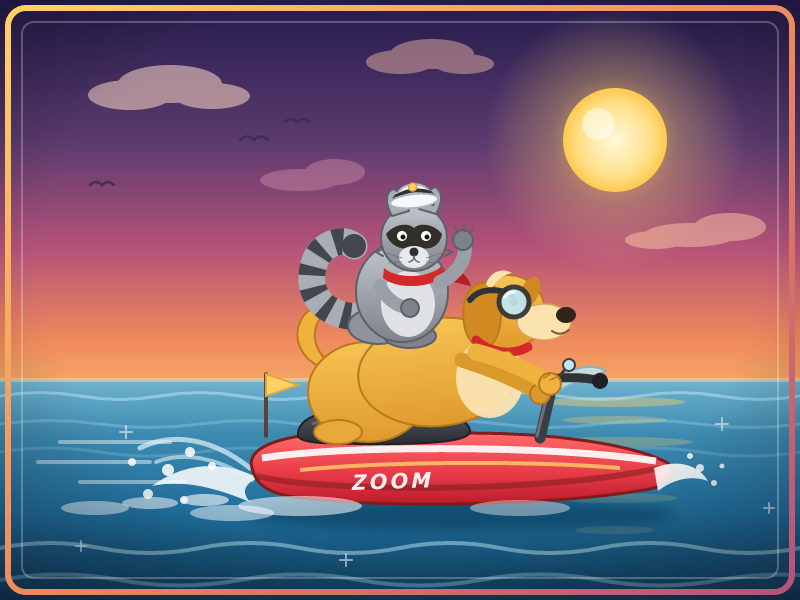
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
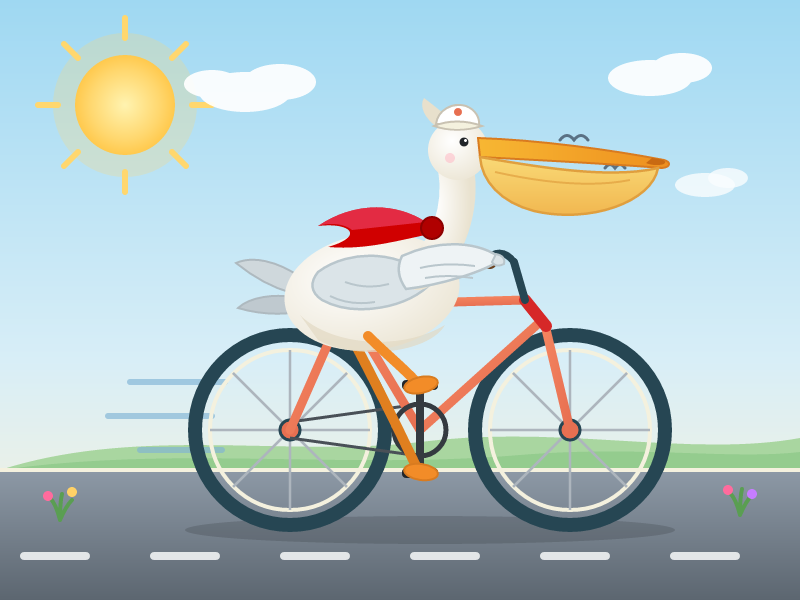
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDanthropic/claude-haiku-5.5
StealthMarkOverall rank18/499 rated results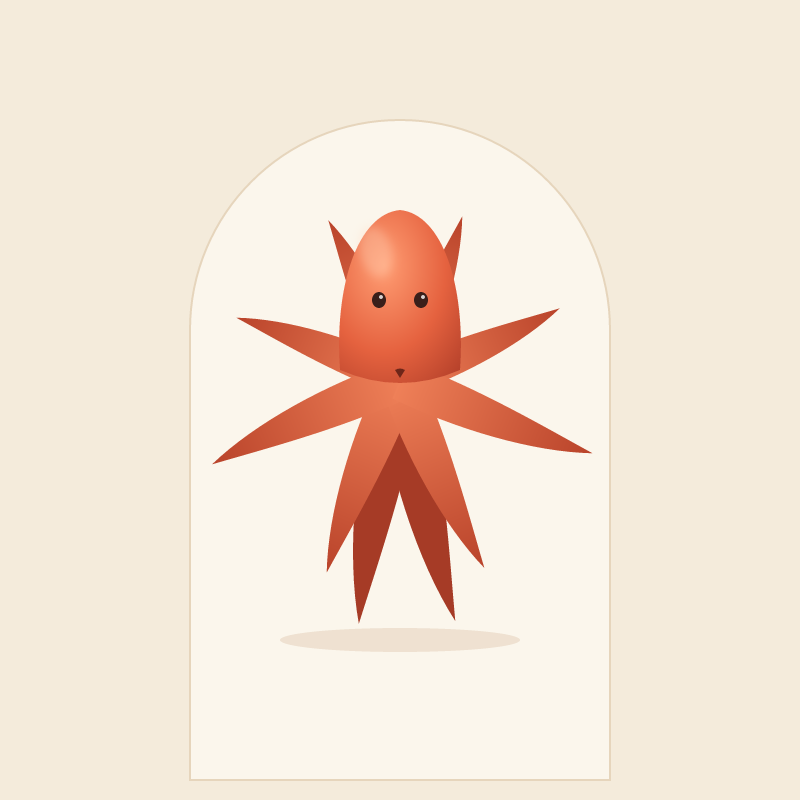
A coral squid with spreading arms tests connected anatomy, balanced composition and soft surface shading.
First run
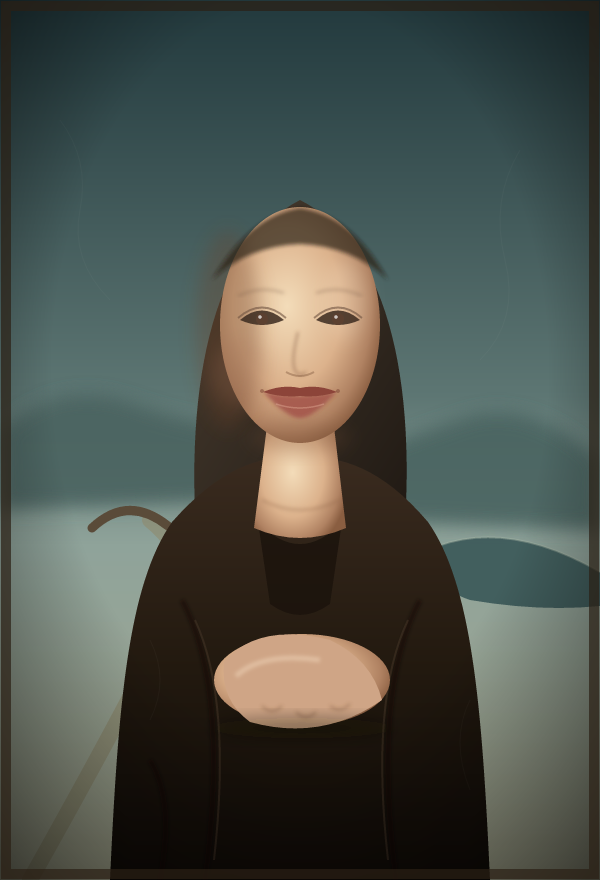
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
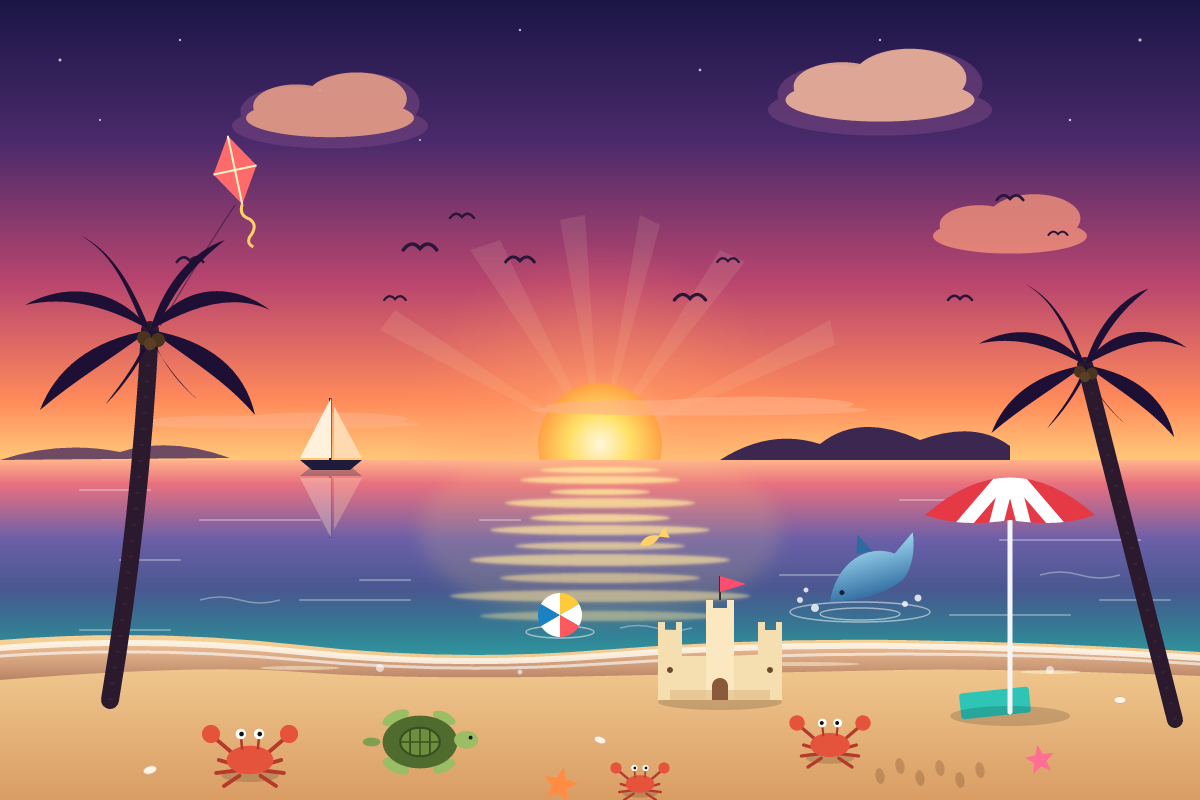
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
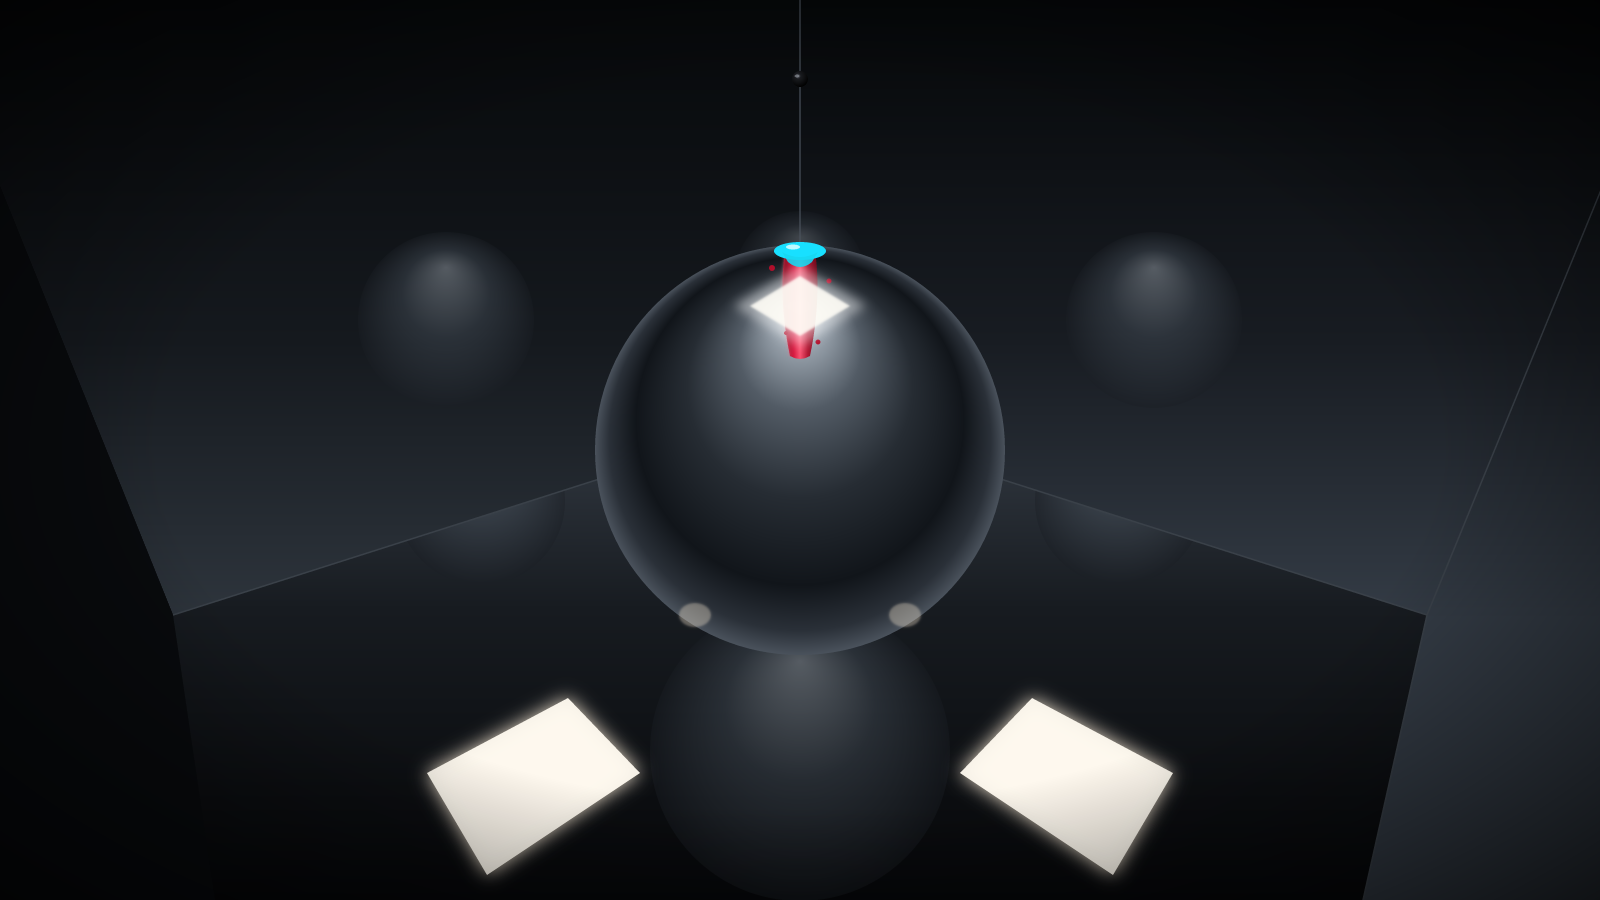
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
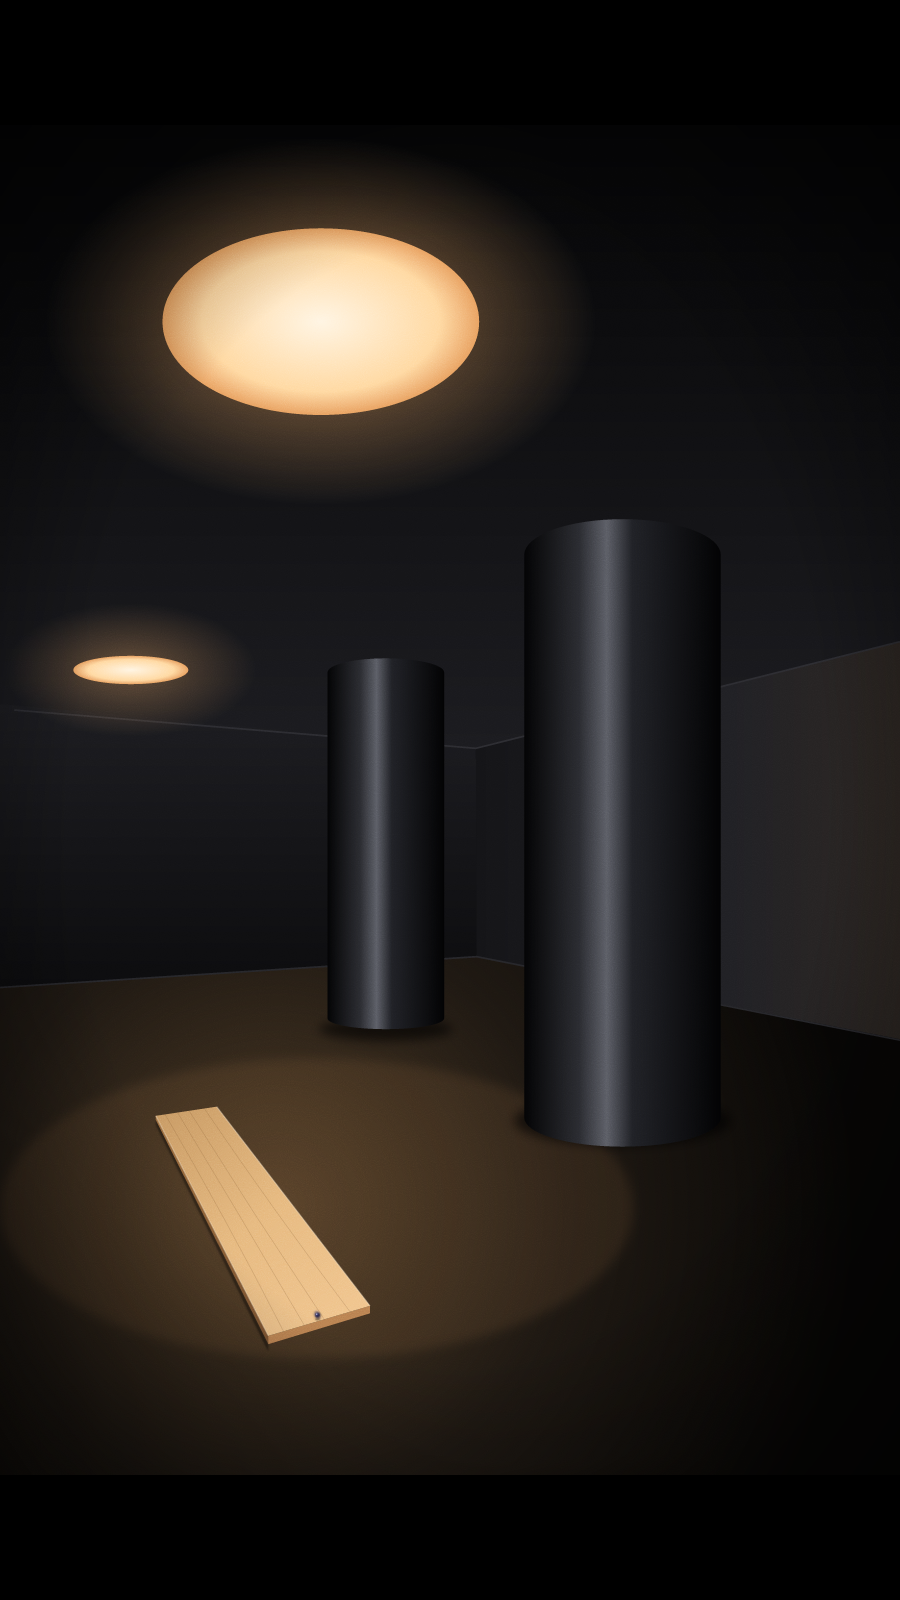
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
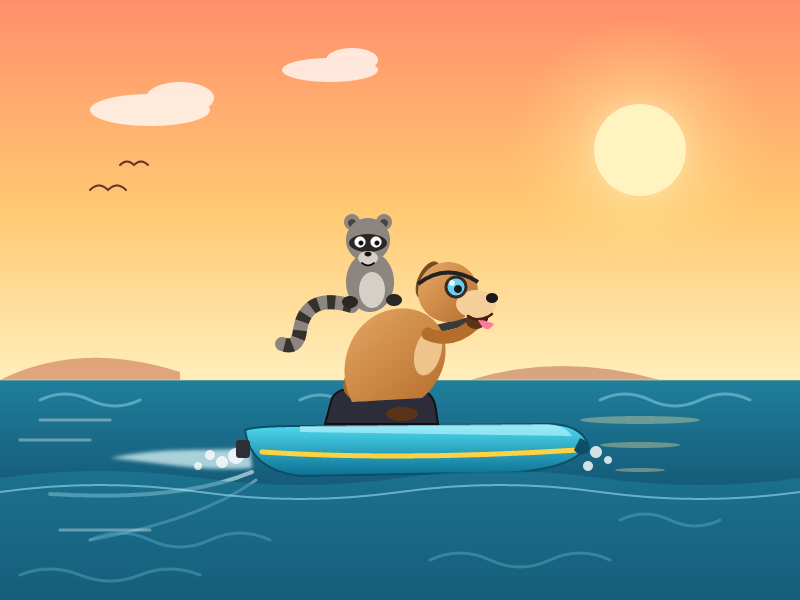
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
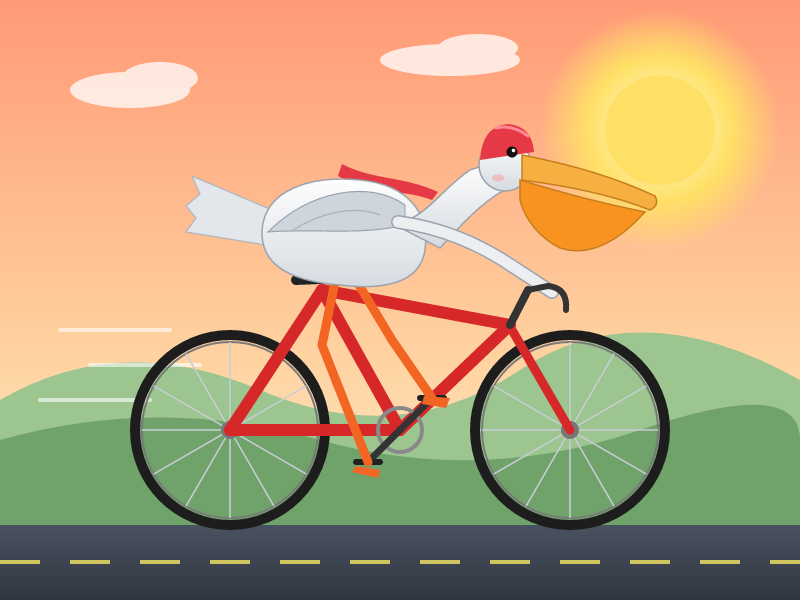
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseHosted preview
Model IDstealth/glyph-cluster
StealthMarkOverall rank44/499 rated results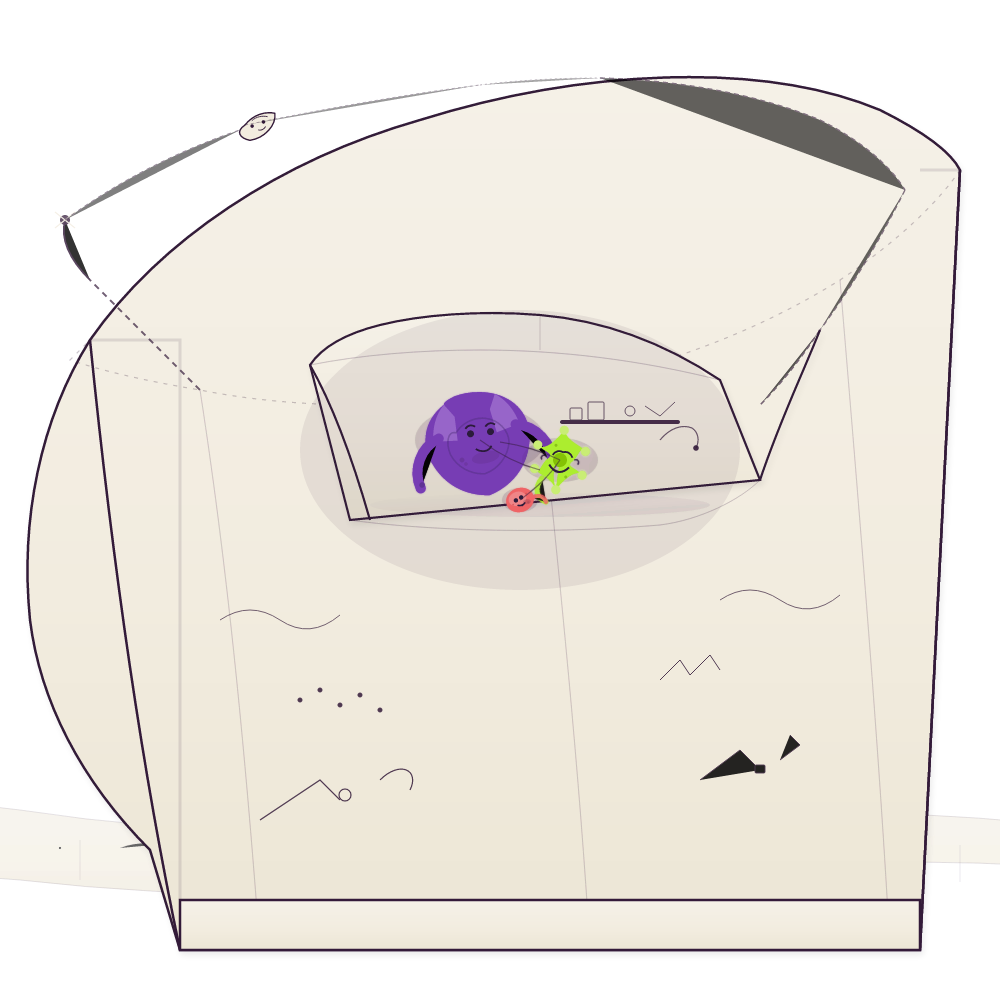
Punctuation-shaped companions gather inside a curled paper home. The scene tests expressive silhouettes, close interaction and the coherence of a detailed miniature environment.
First run
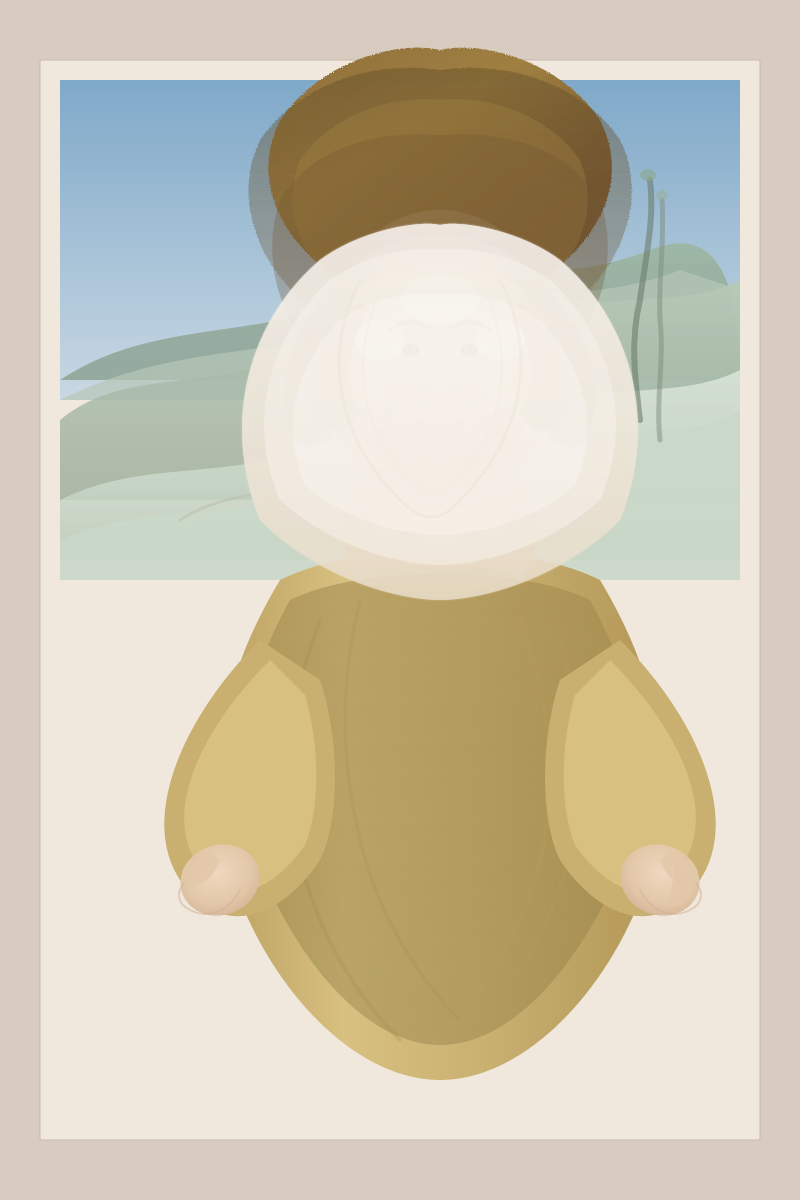
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
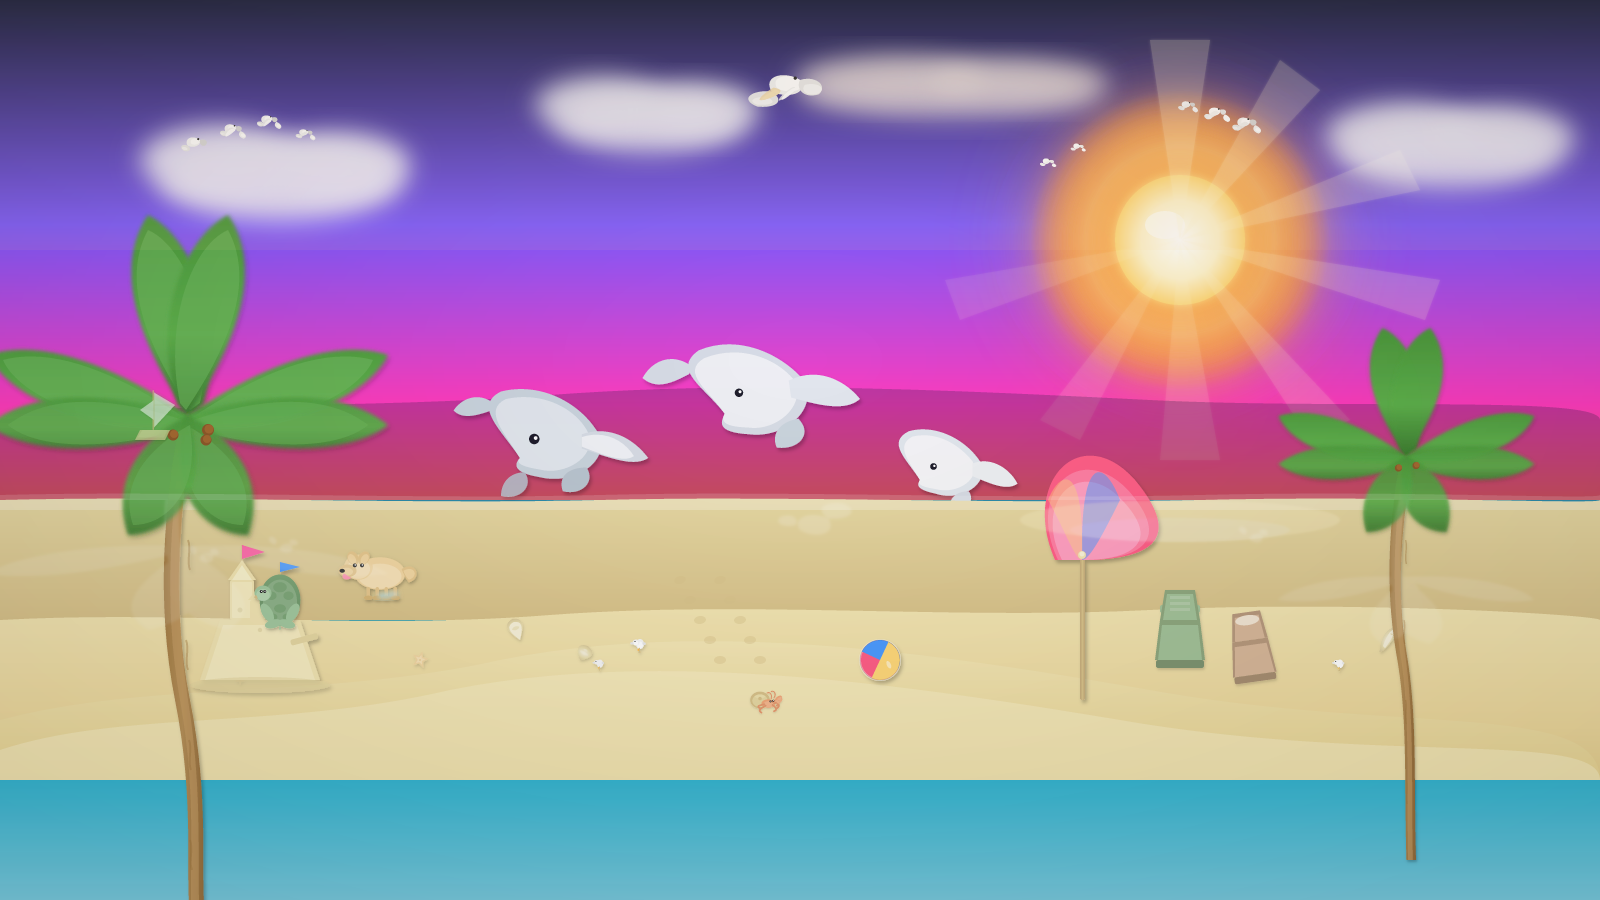
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
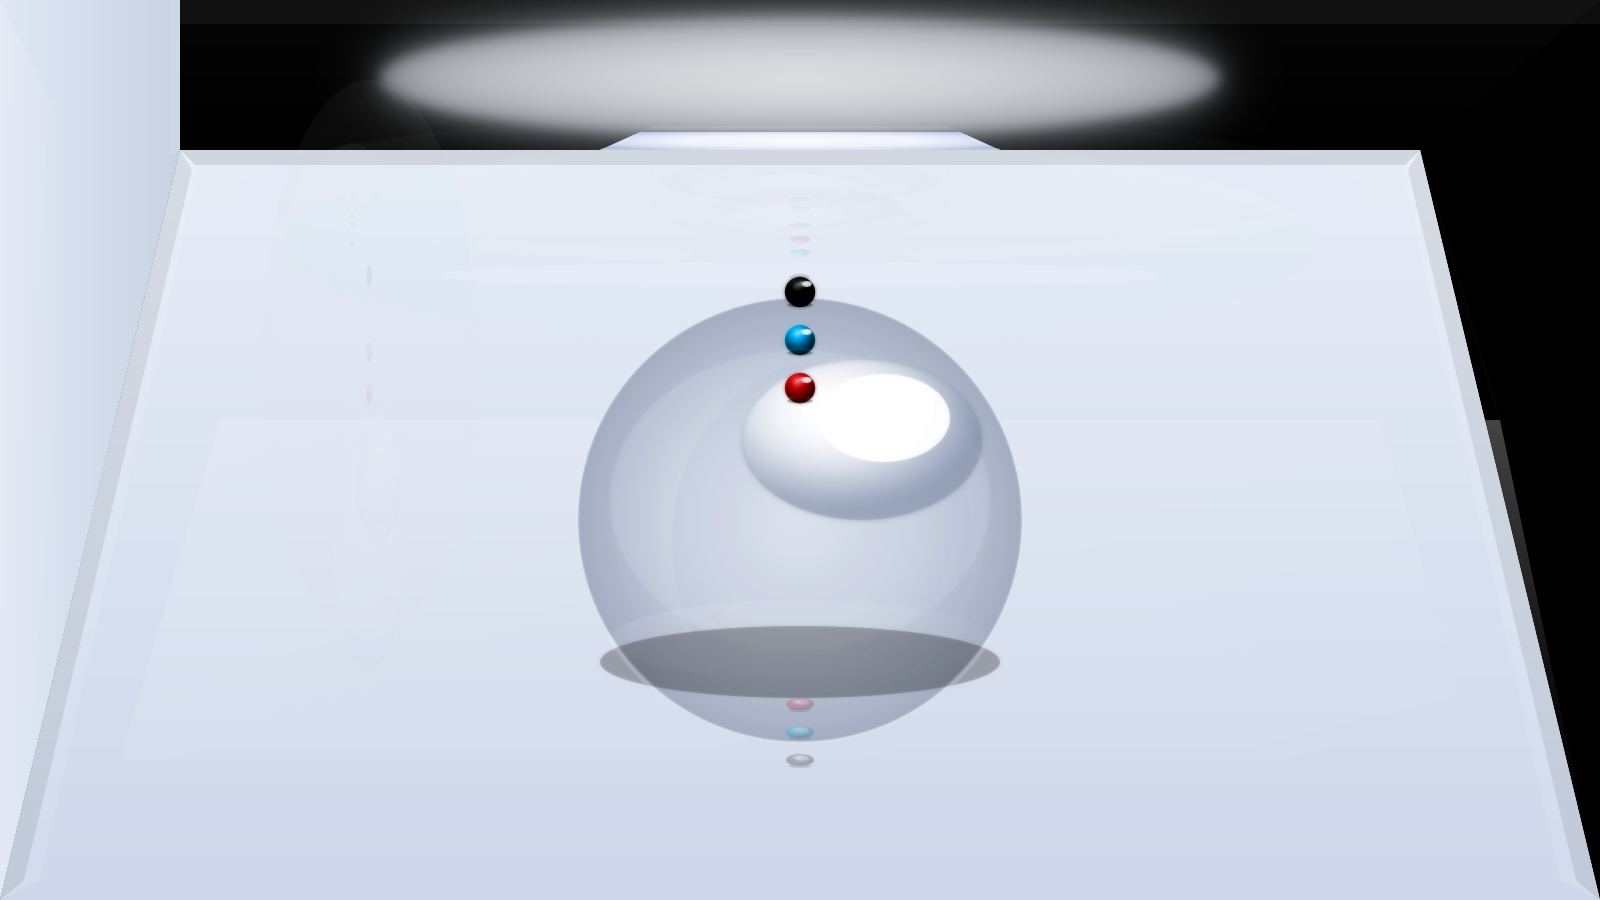
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
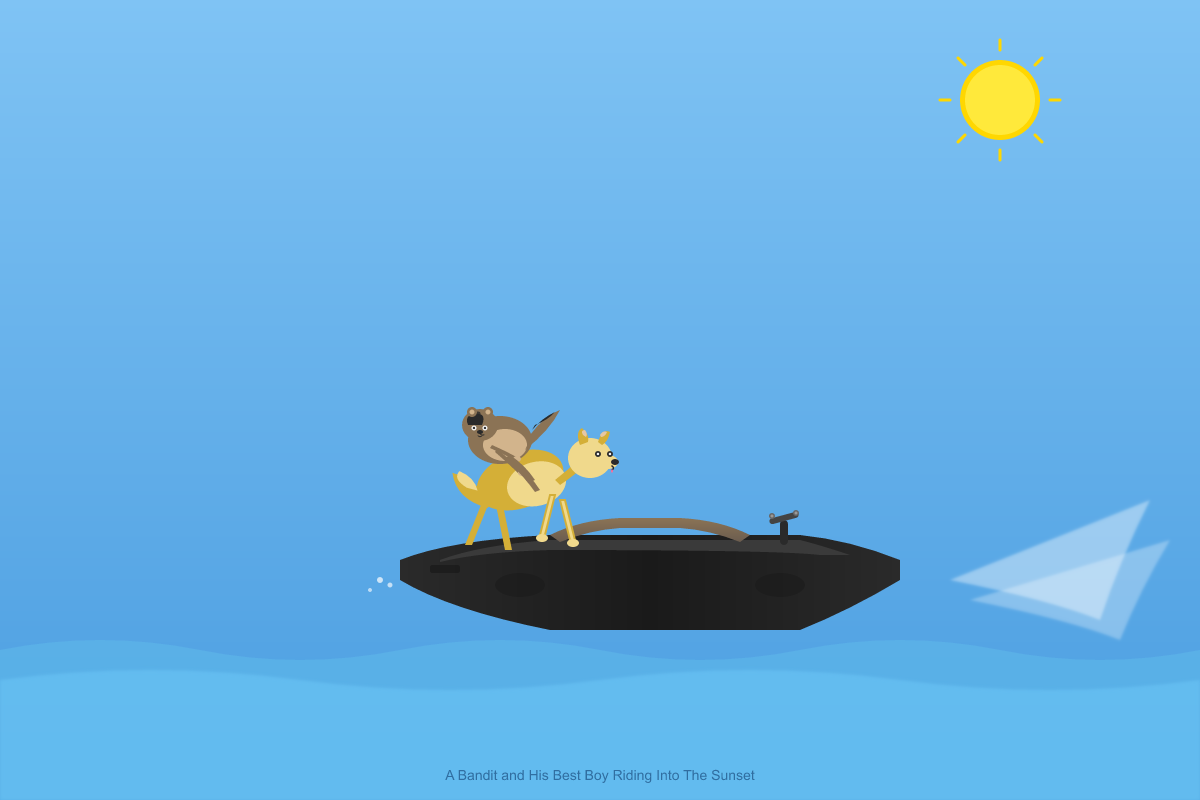
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
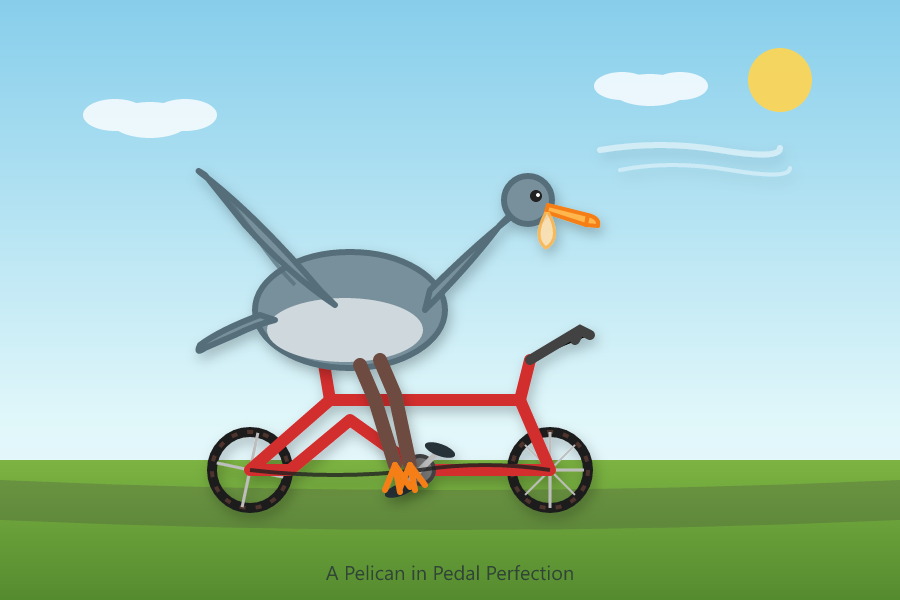
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache-2.0
Model IDqwen/qwen3.6-27b
StealthMarkOverall rank38/499 rated results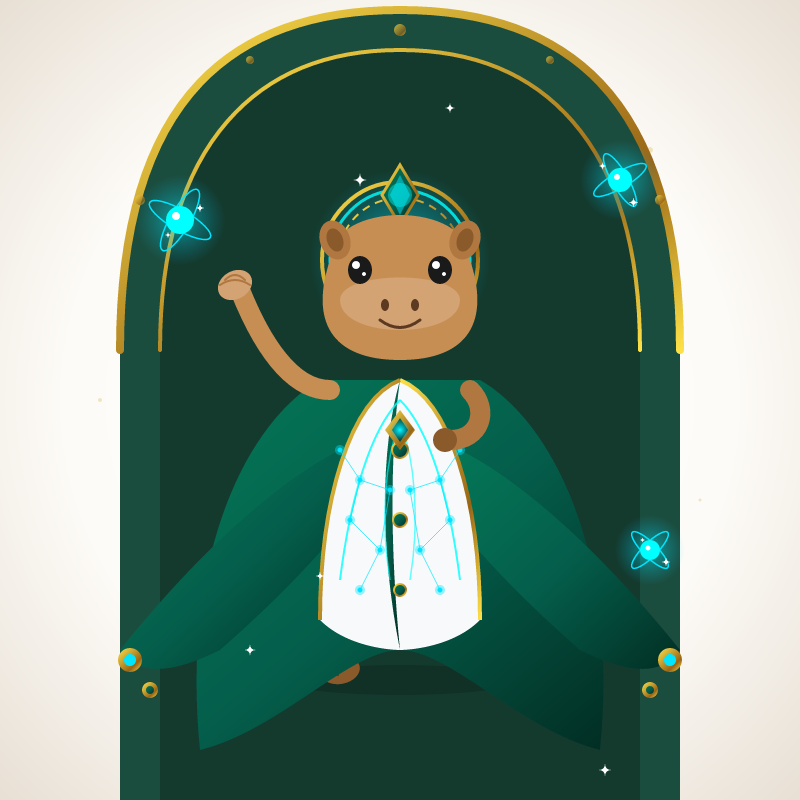
A floating capybara in ornate robes tests character anatomy, layered fabric and the placement of surrounding luminous forms.
First run
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
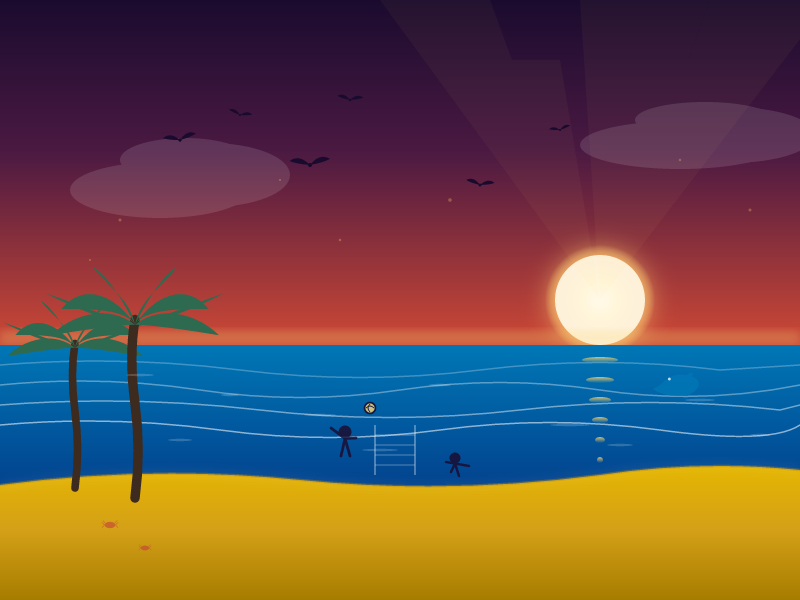
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
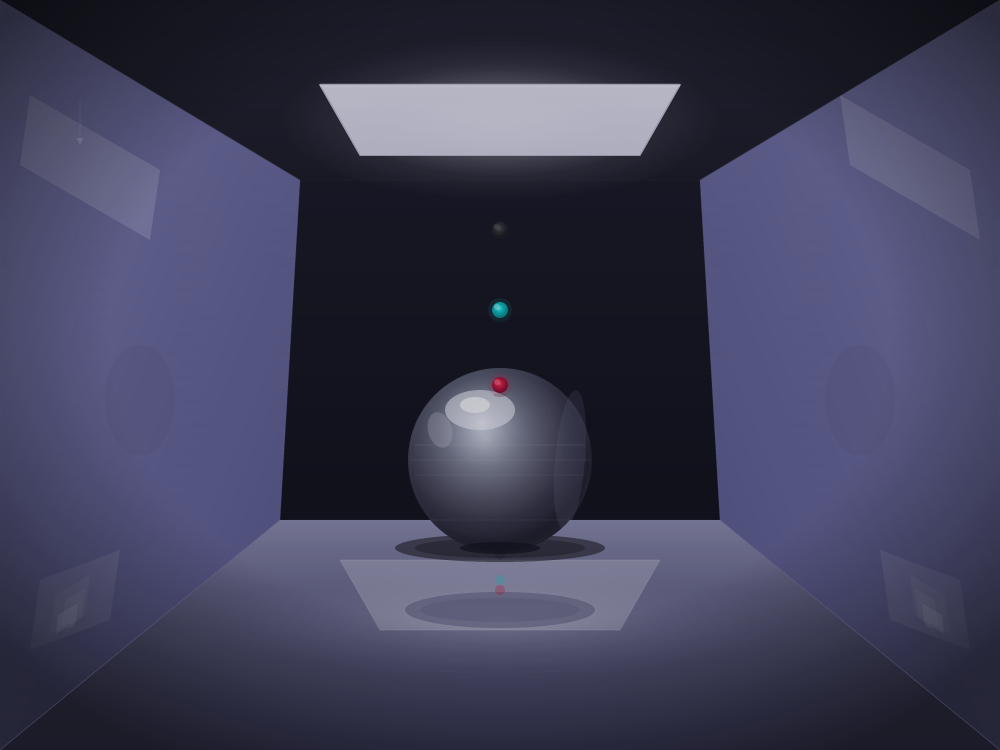
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
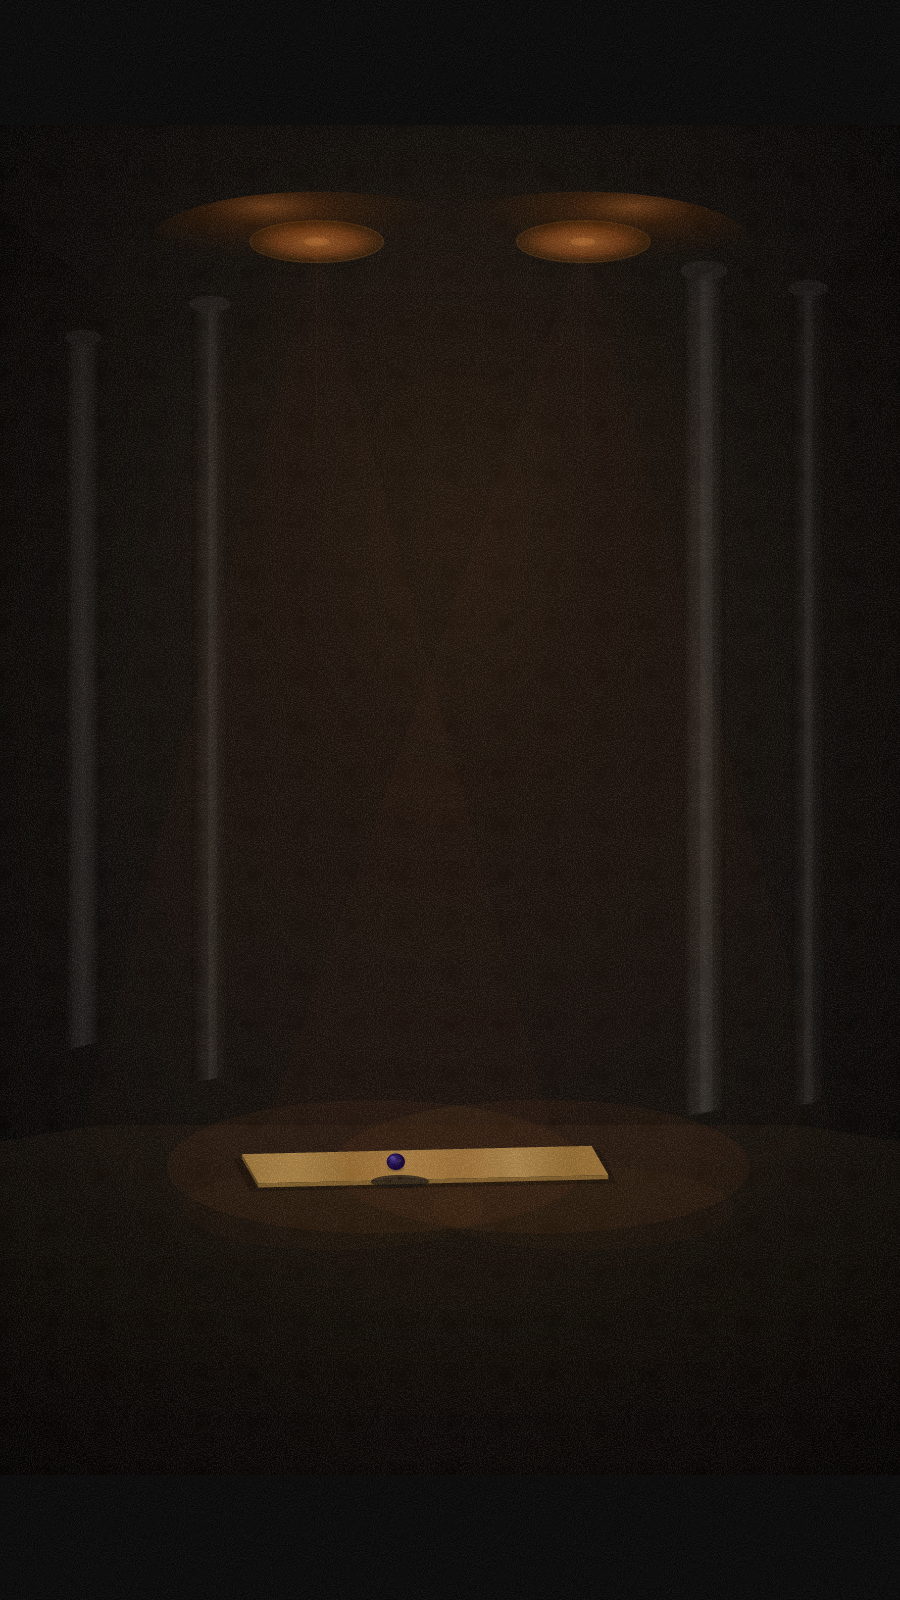
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
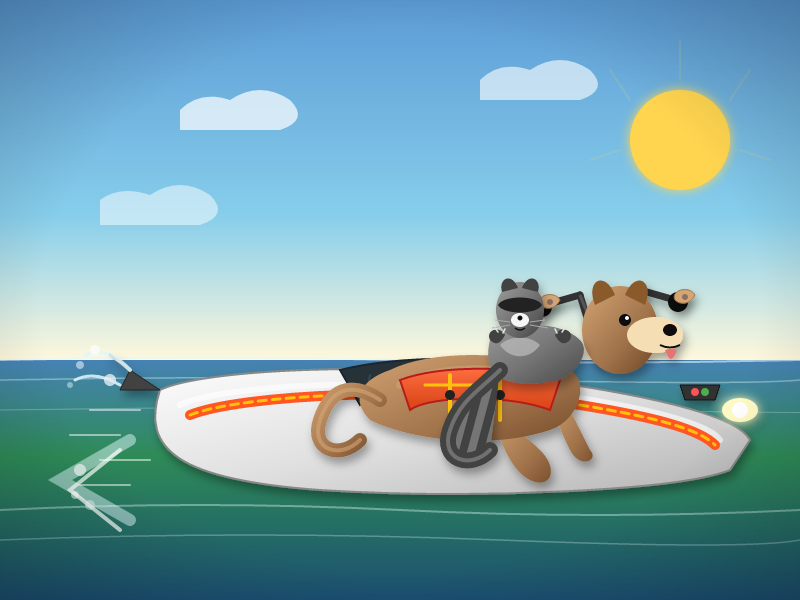
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
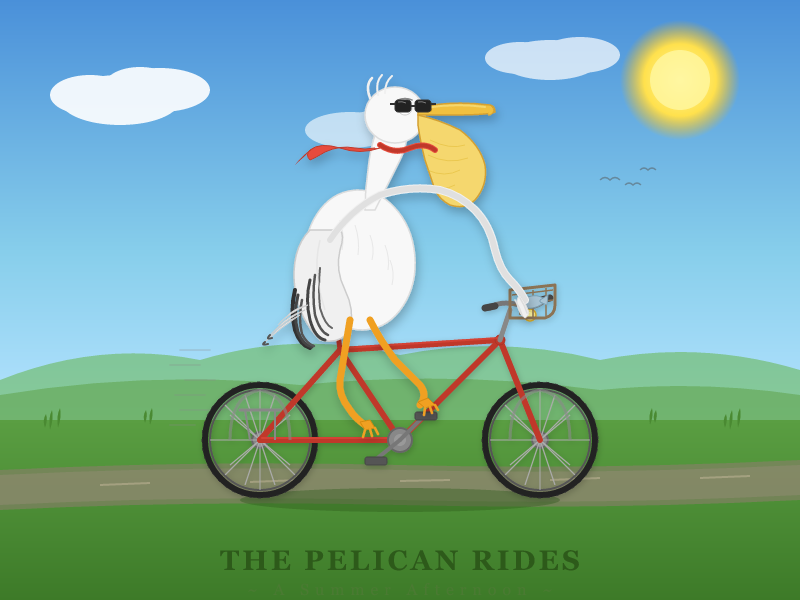
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDmicrosoft/mai-thinking-1
StealthMarkOverall rank47/499 rated results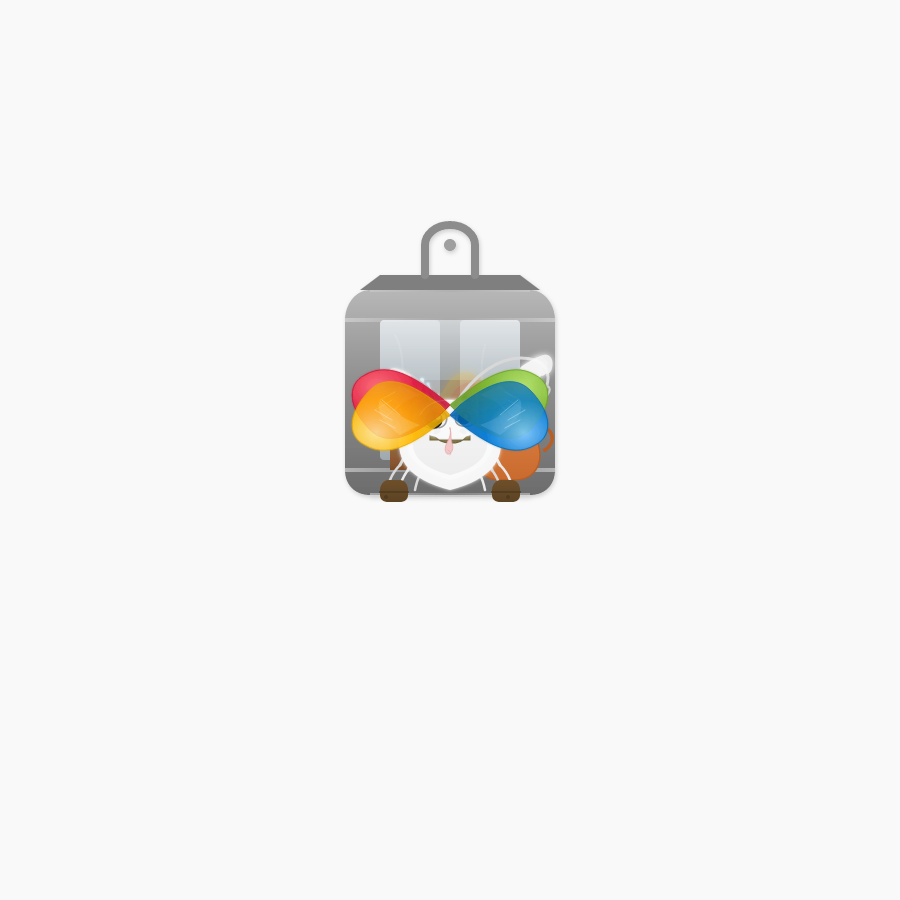
A fluffy moth tends a lantern greenhouse amid a gardening mishap. The scene tests insect anatomy, expressive action, translucent wings and the interaction of light with small objects.
First run
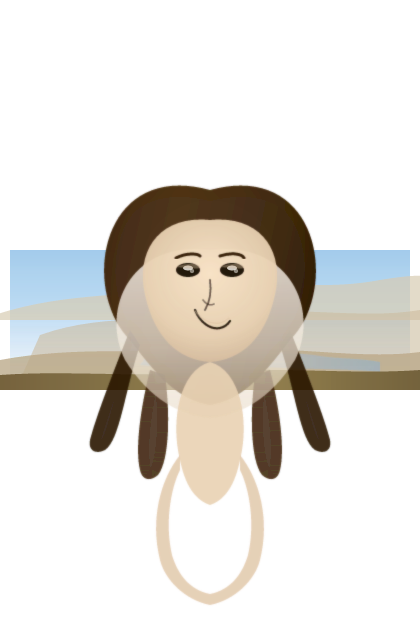
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
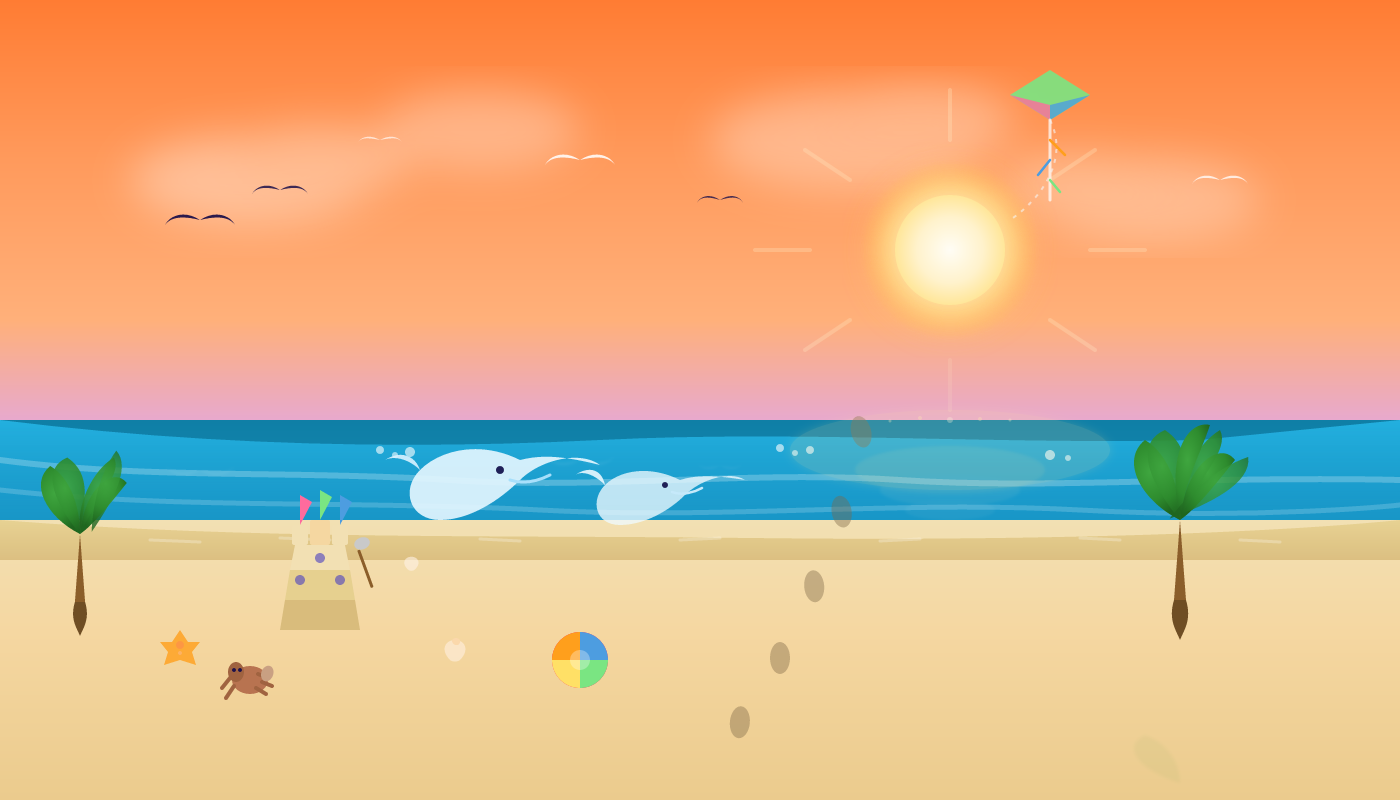
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
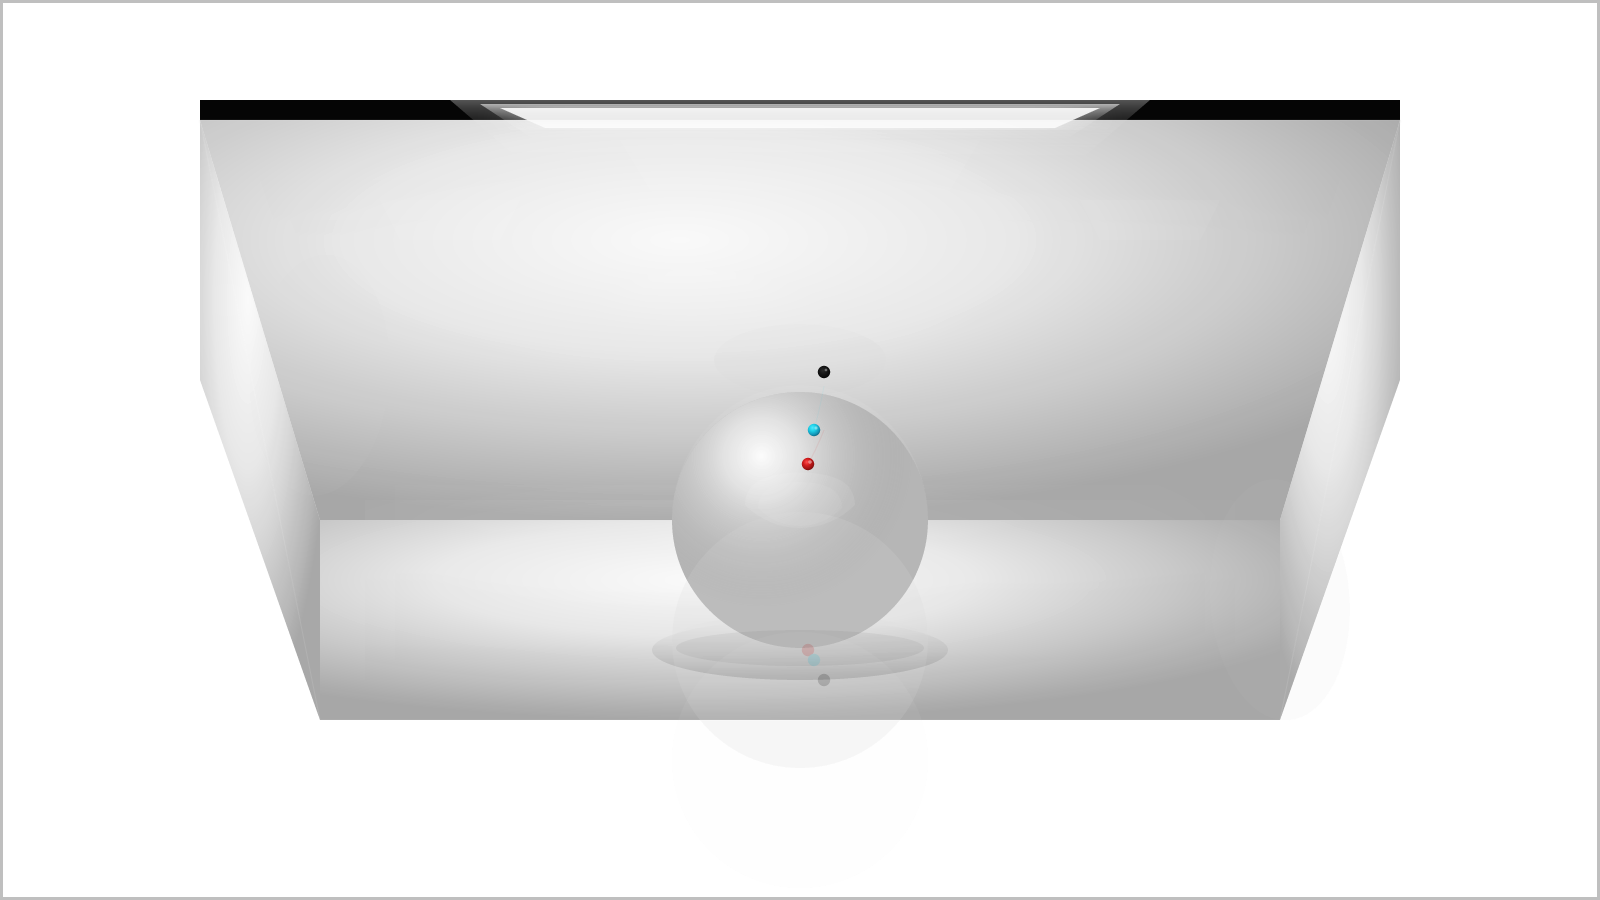
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
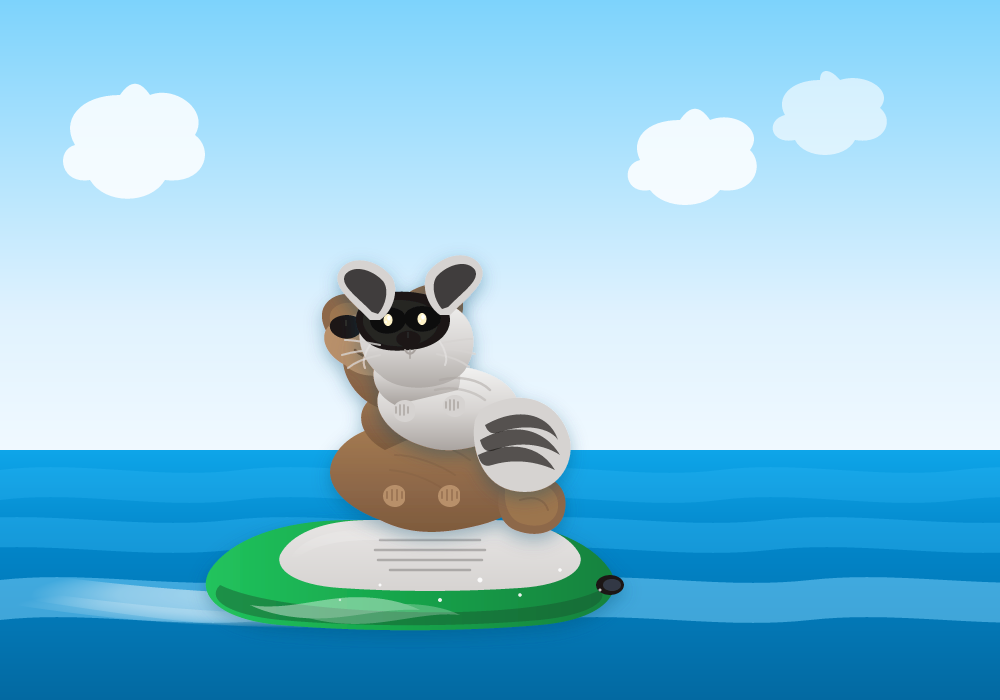
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
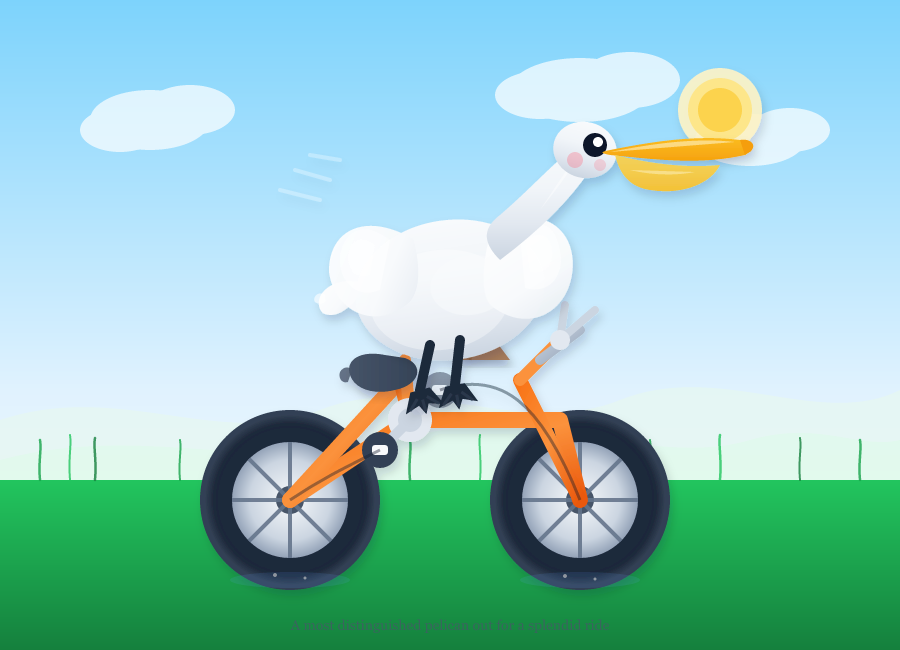
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache 2.0
Model IDgoogle/gemma-4-31b-it
StealthMarkOverall rank41/499 rated results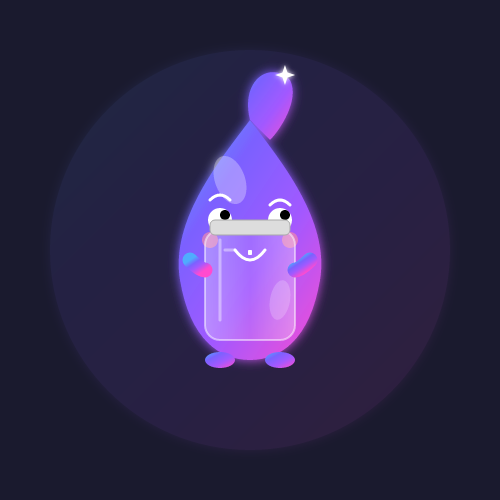
A small luminous creature proudly holding an empty glass jar tests expression, transparent materials and the balance of character and prop.
First run
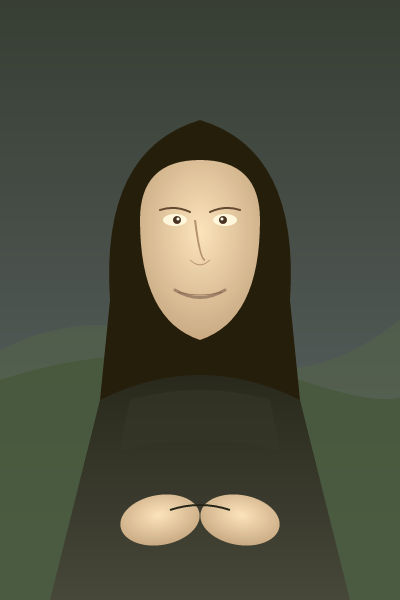
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
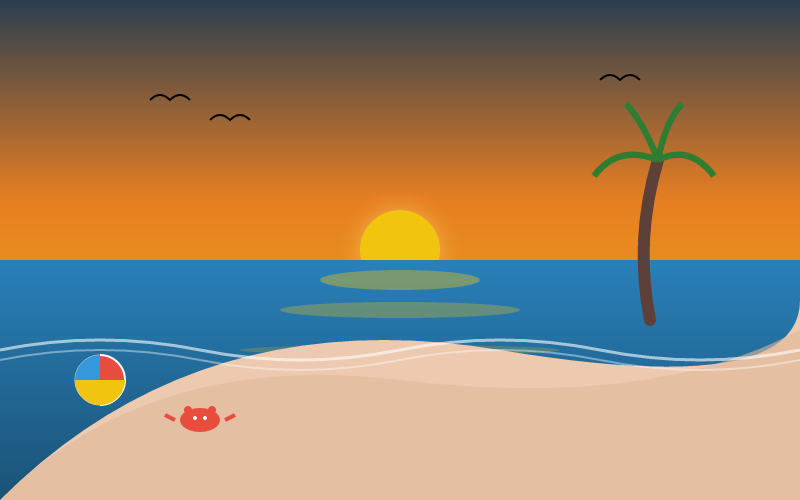
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
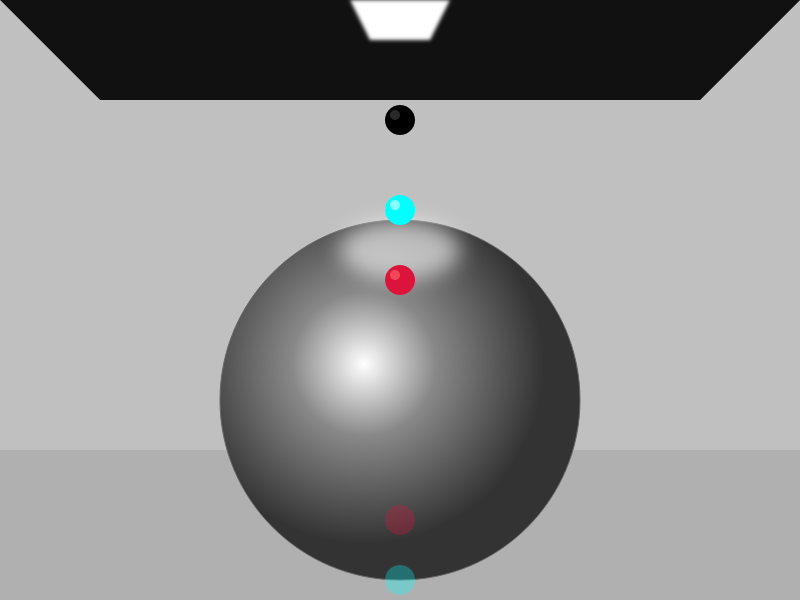
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache 2.0
Model IDgoogle/gemma-4-26b-a4b-it
StealthMarkOverall rank46/499 rated results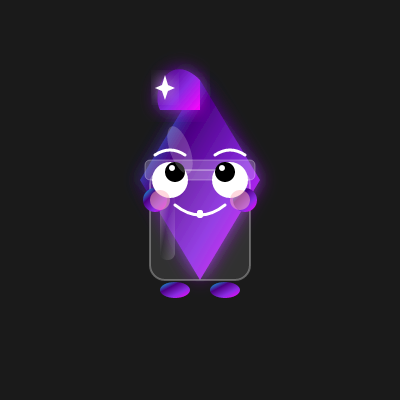
A small luminous creature proudly holding an empty glass jar tests expression, transparent materials and the balance of character and prop.
First run
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
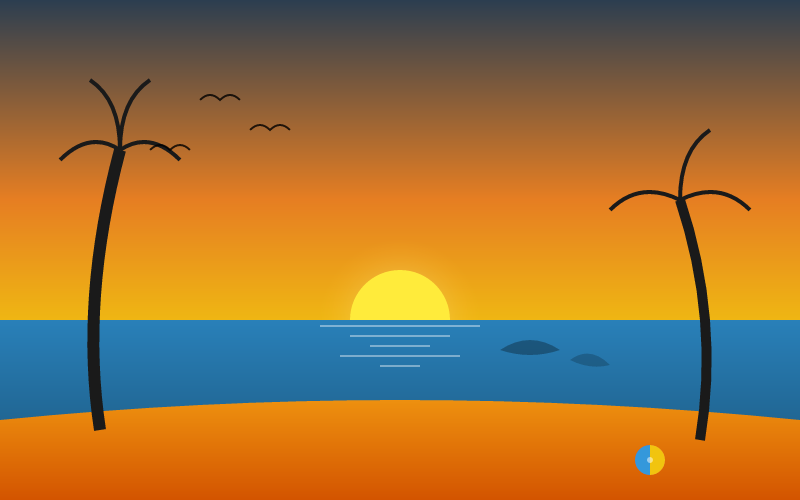
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
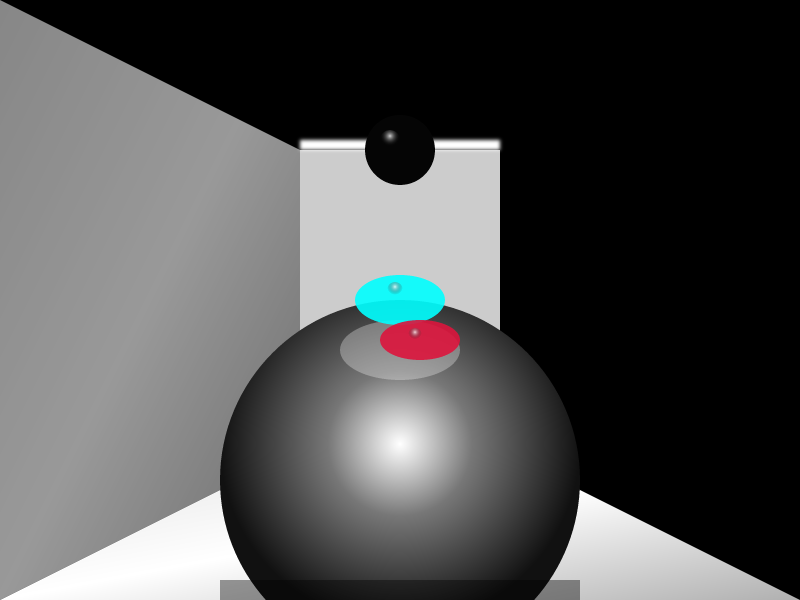
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
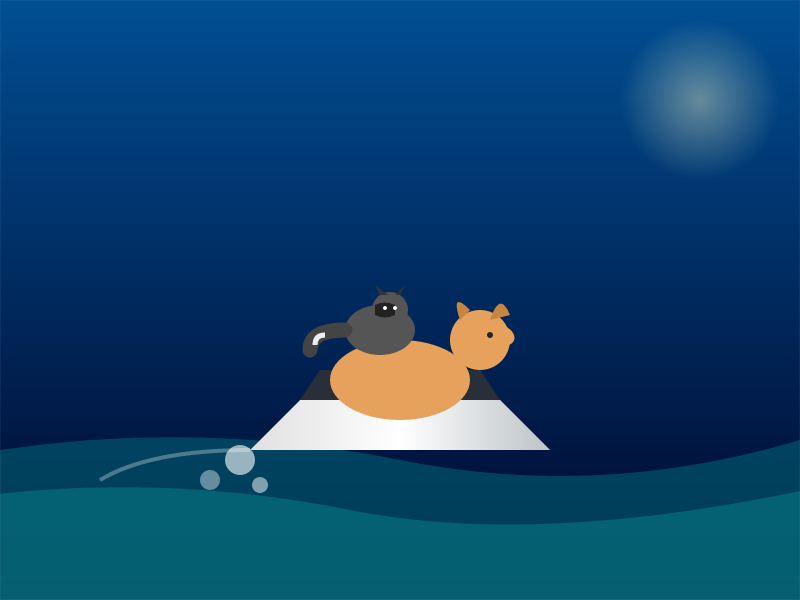
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
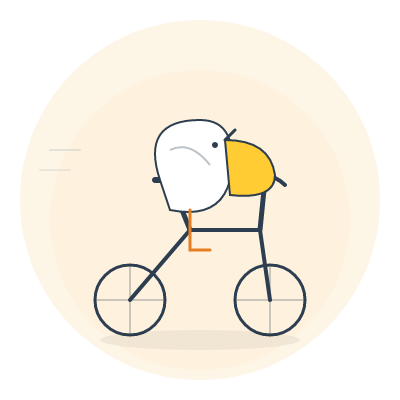
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
Model IDmissingno
StealthMarkOverall rank34/497 rated results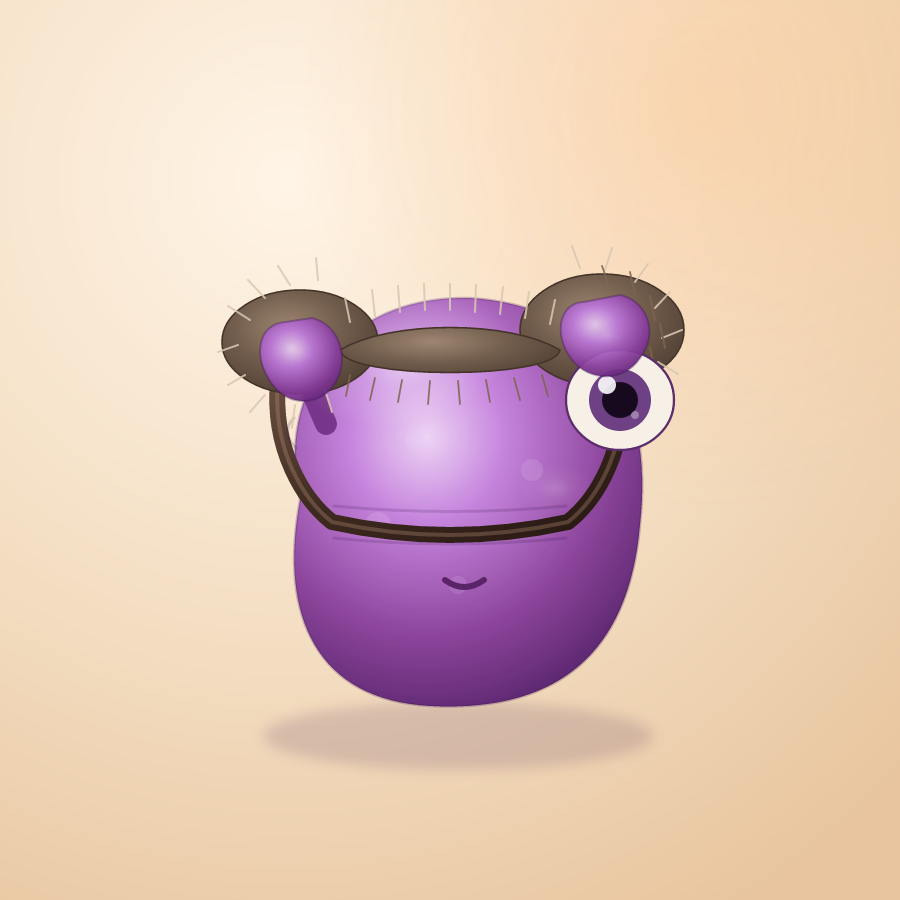
A glossy purple jelly struggles with an oversized fake moustache at a playful checkpoint. The scene tests comic expression, physical contact and the appearance of a soft translucent body.
First run
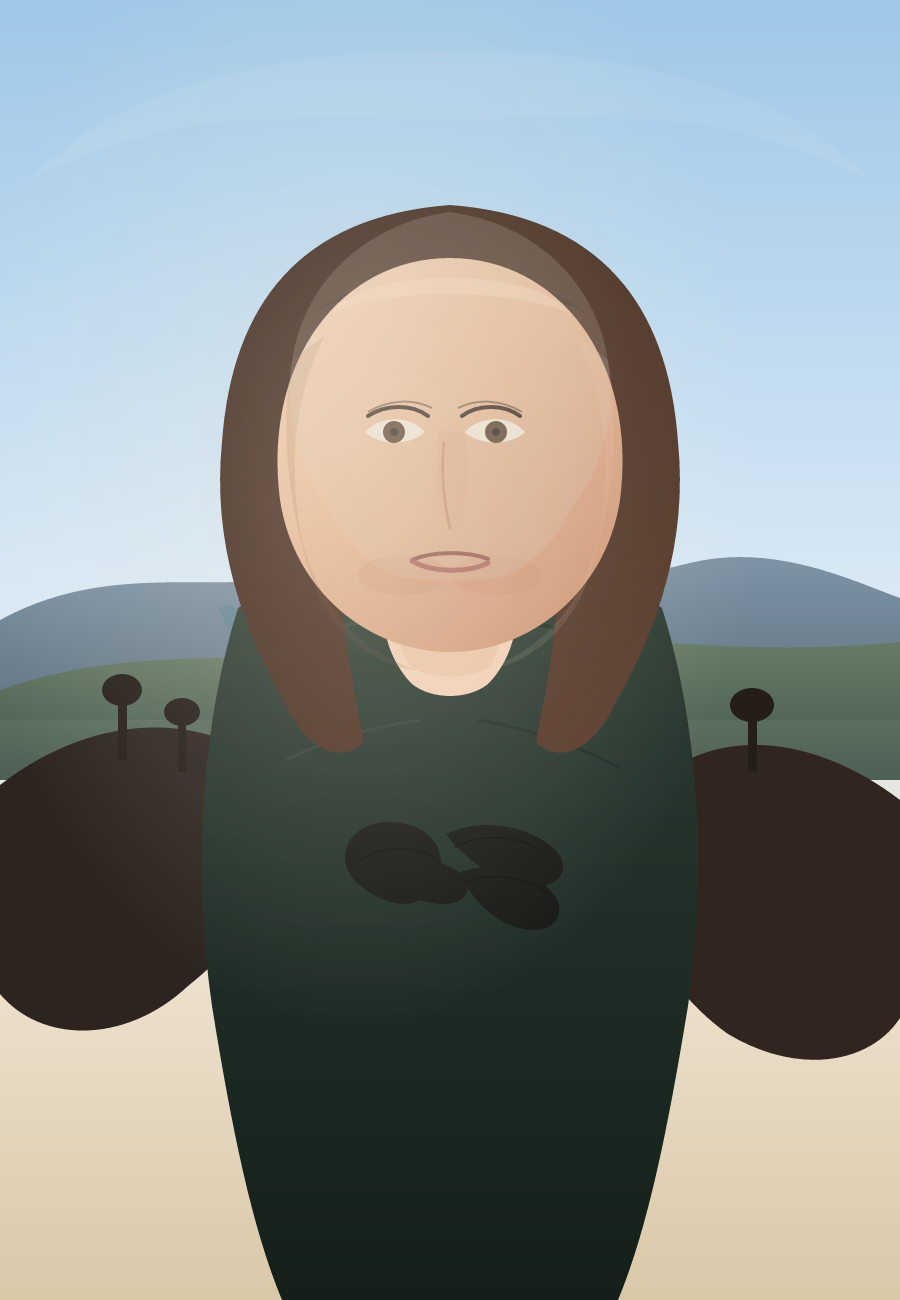
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
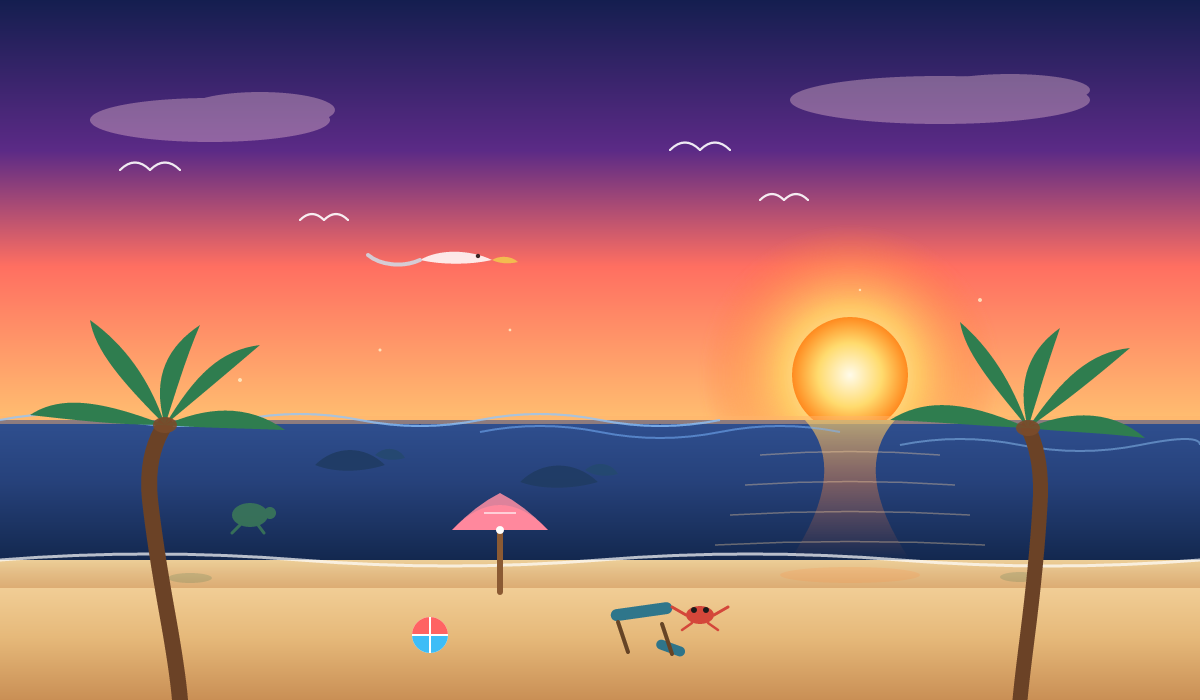
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
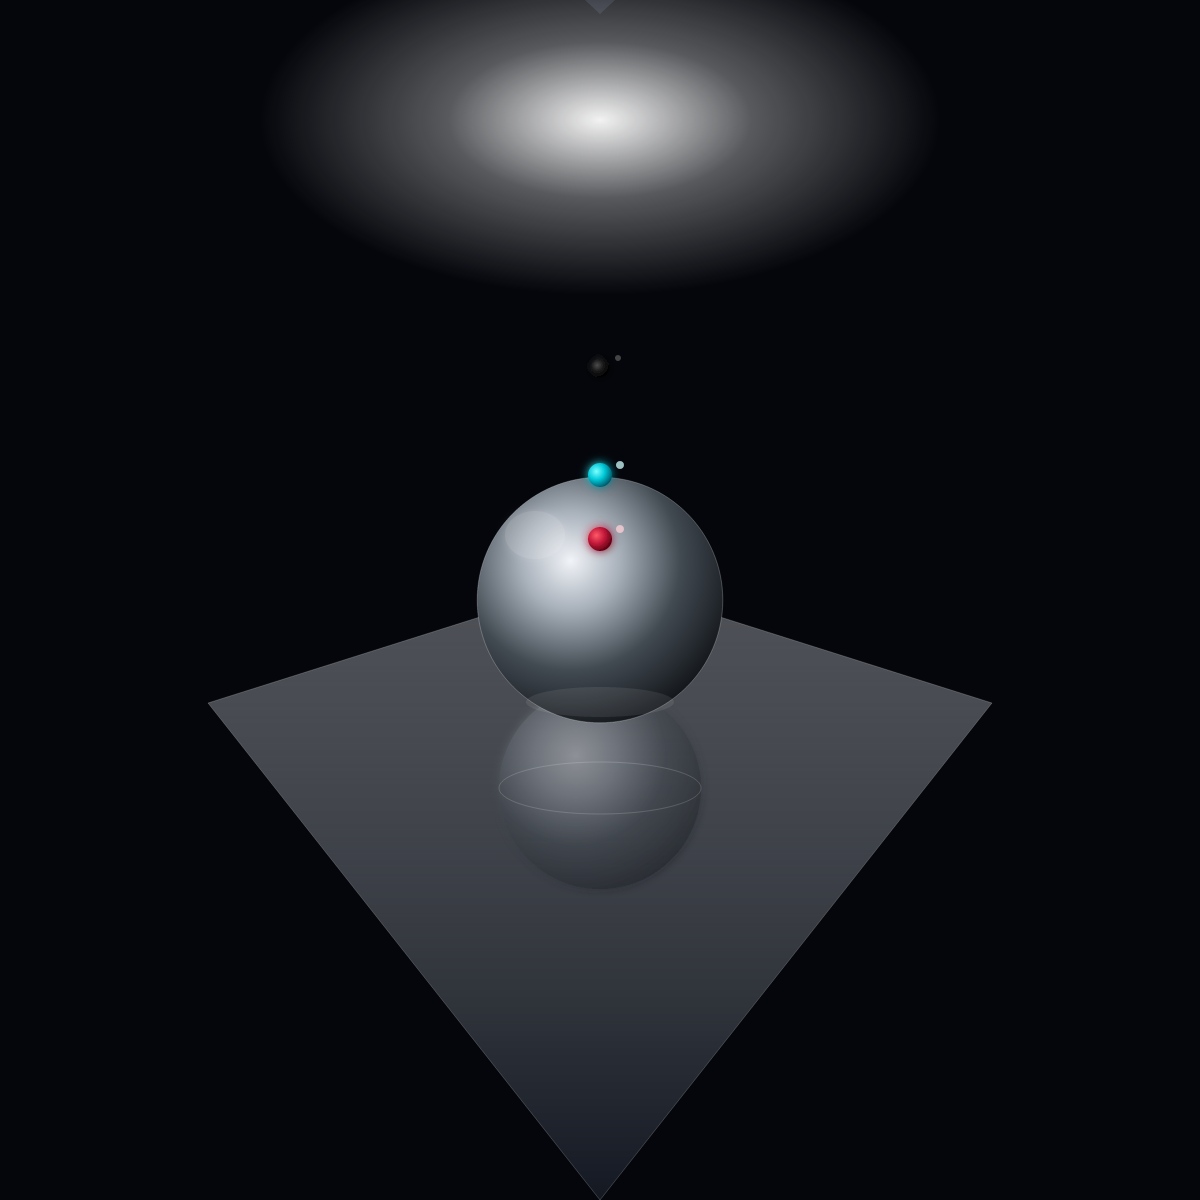
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
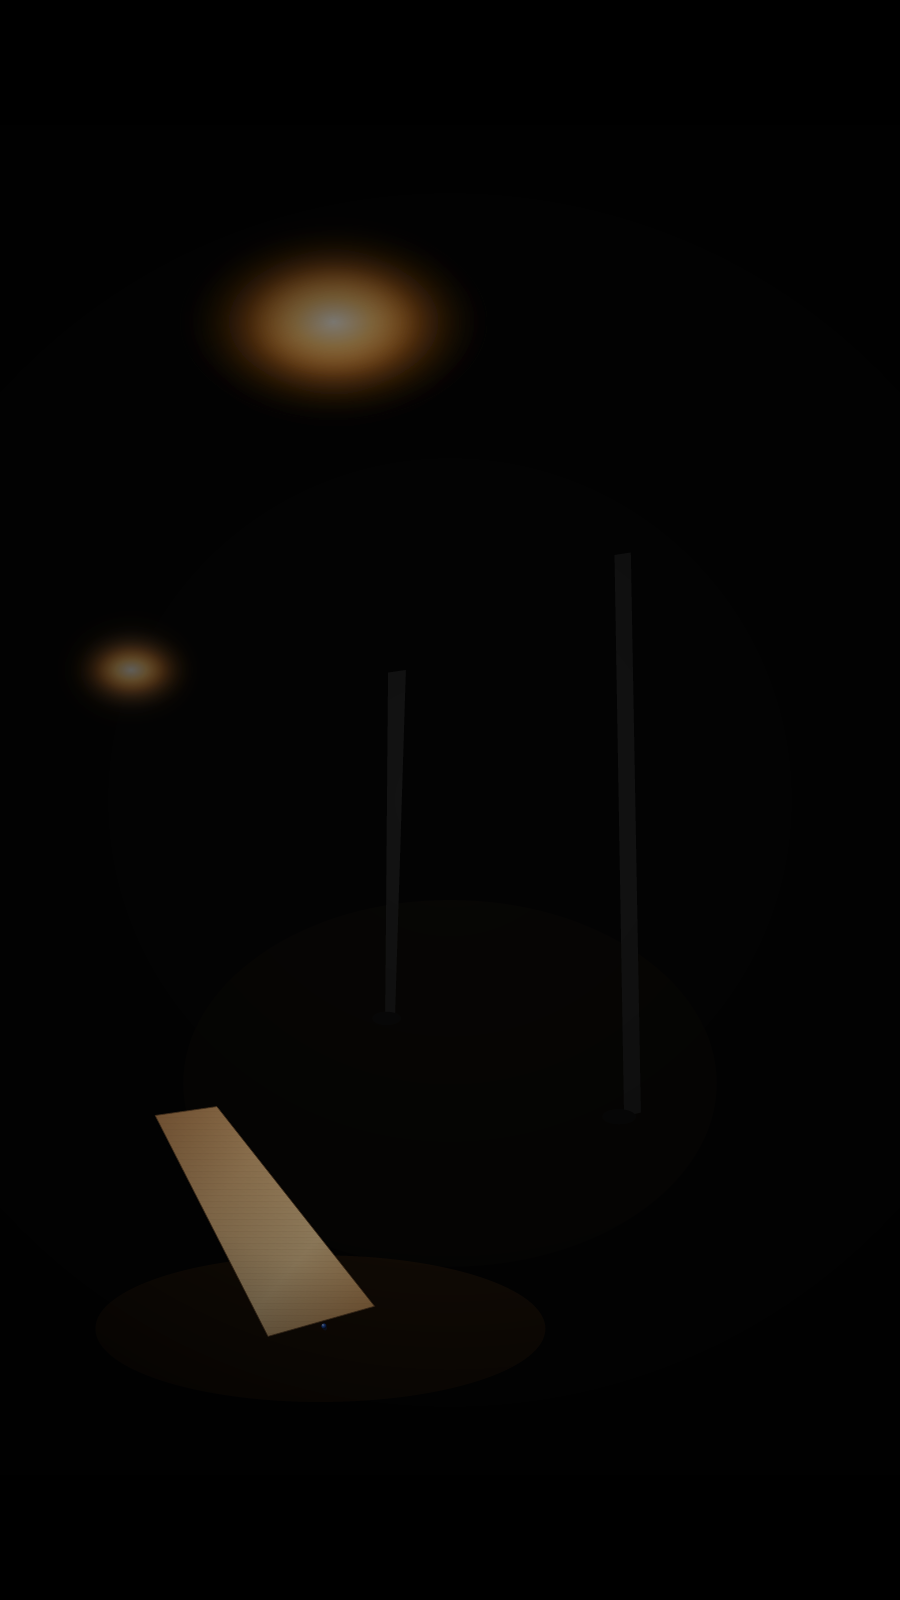
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
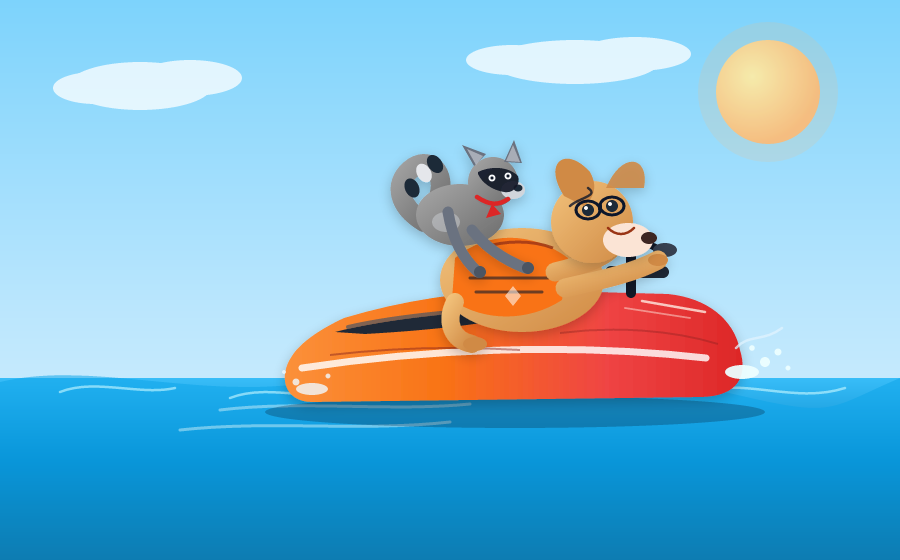
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
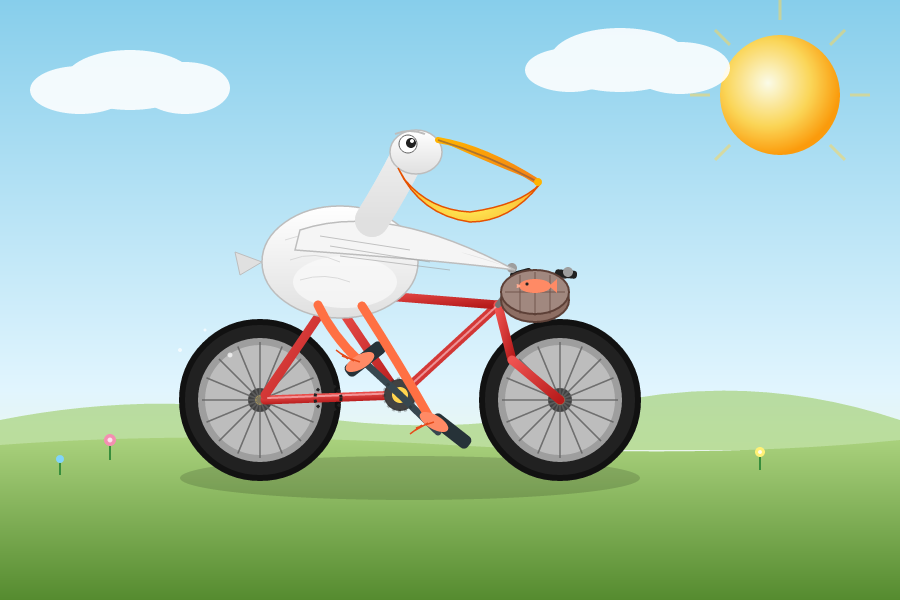
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDmeta/muse-wonder
StealthMarkOverall rank10/499 rated results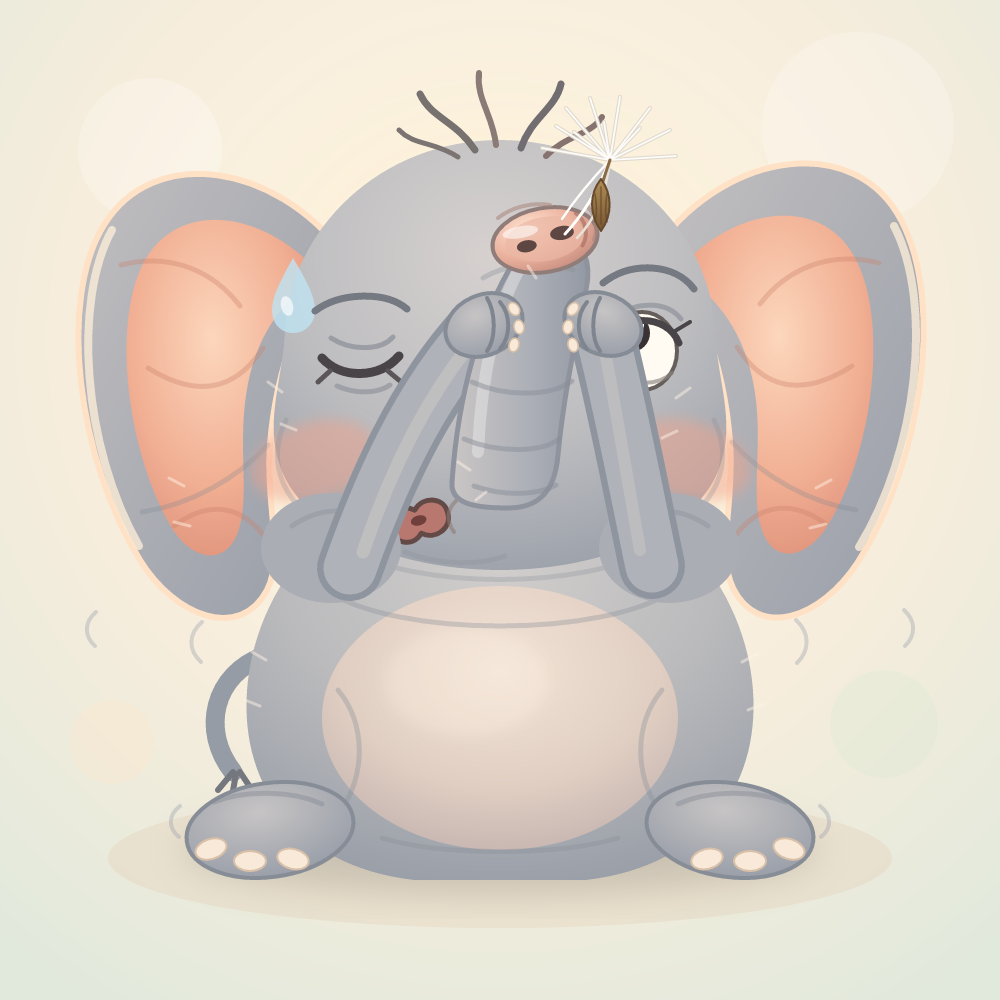
A small elephant protecting a delicate seed tests expressive anatomy, physical contact and contrasting organic materials.
First run
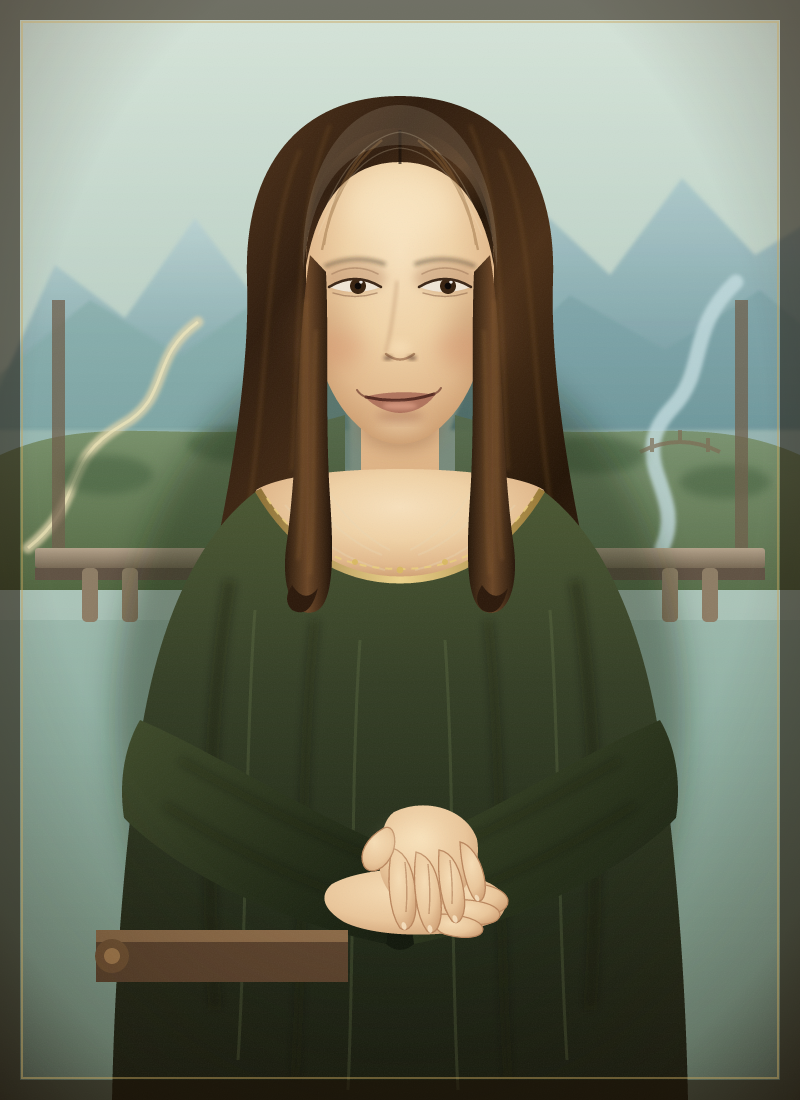
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
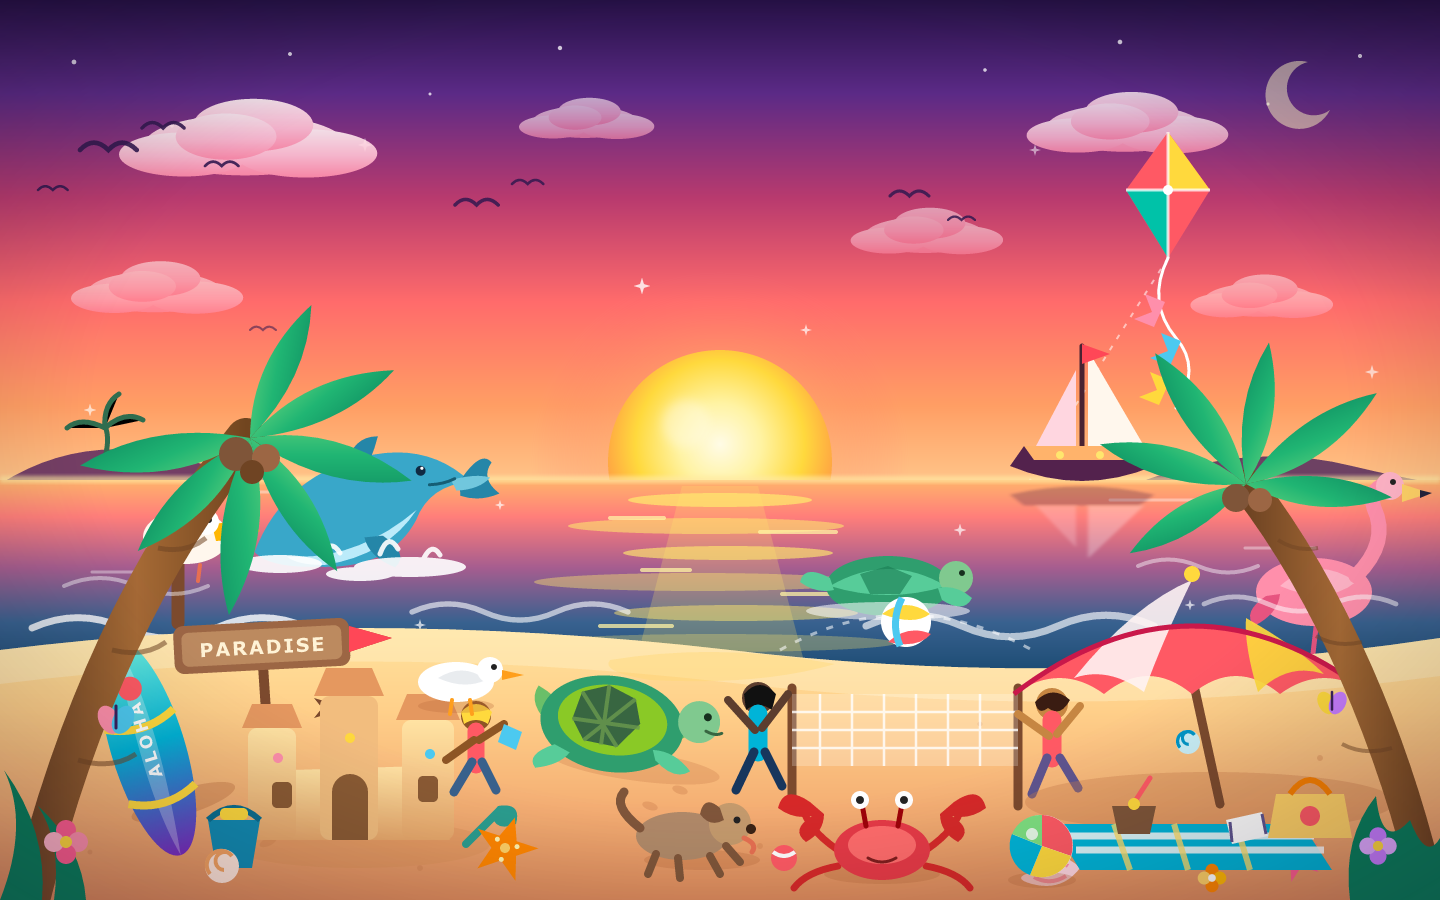
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
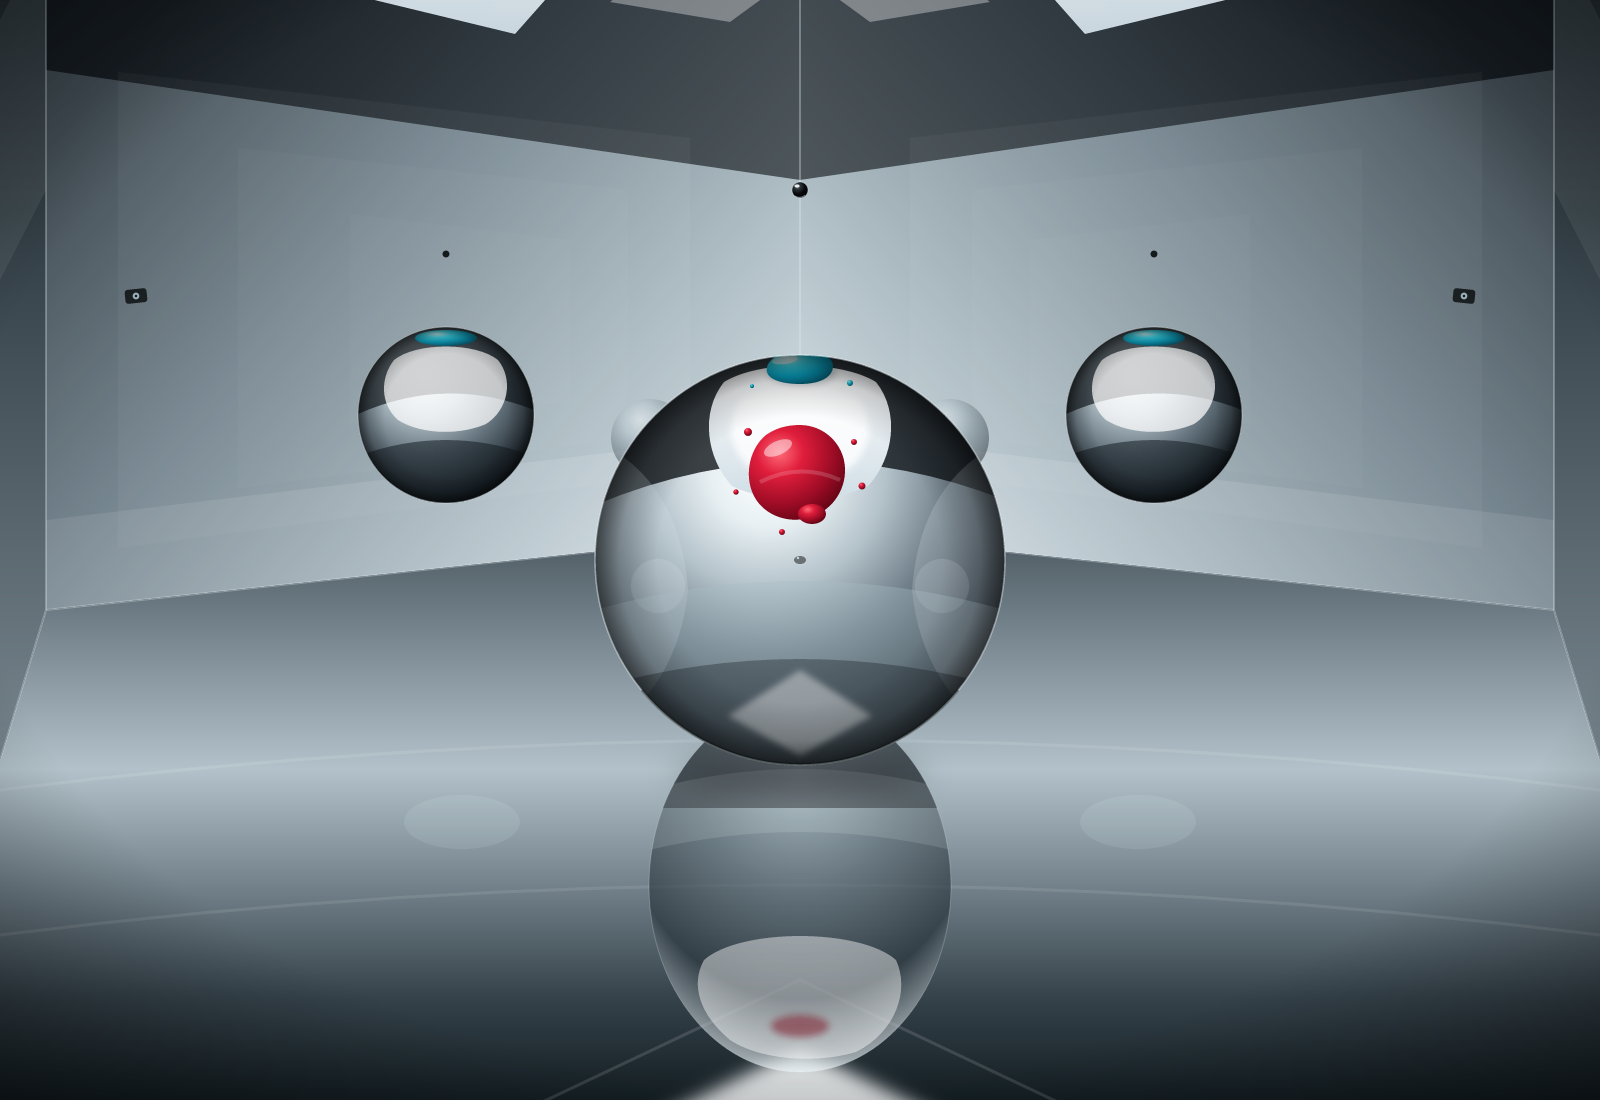
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
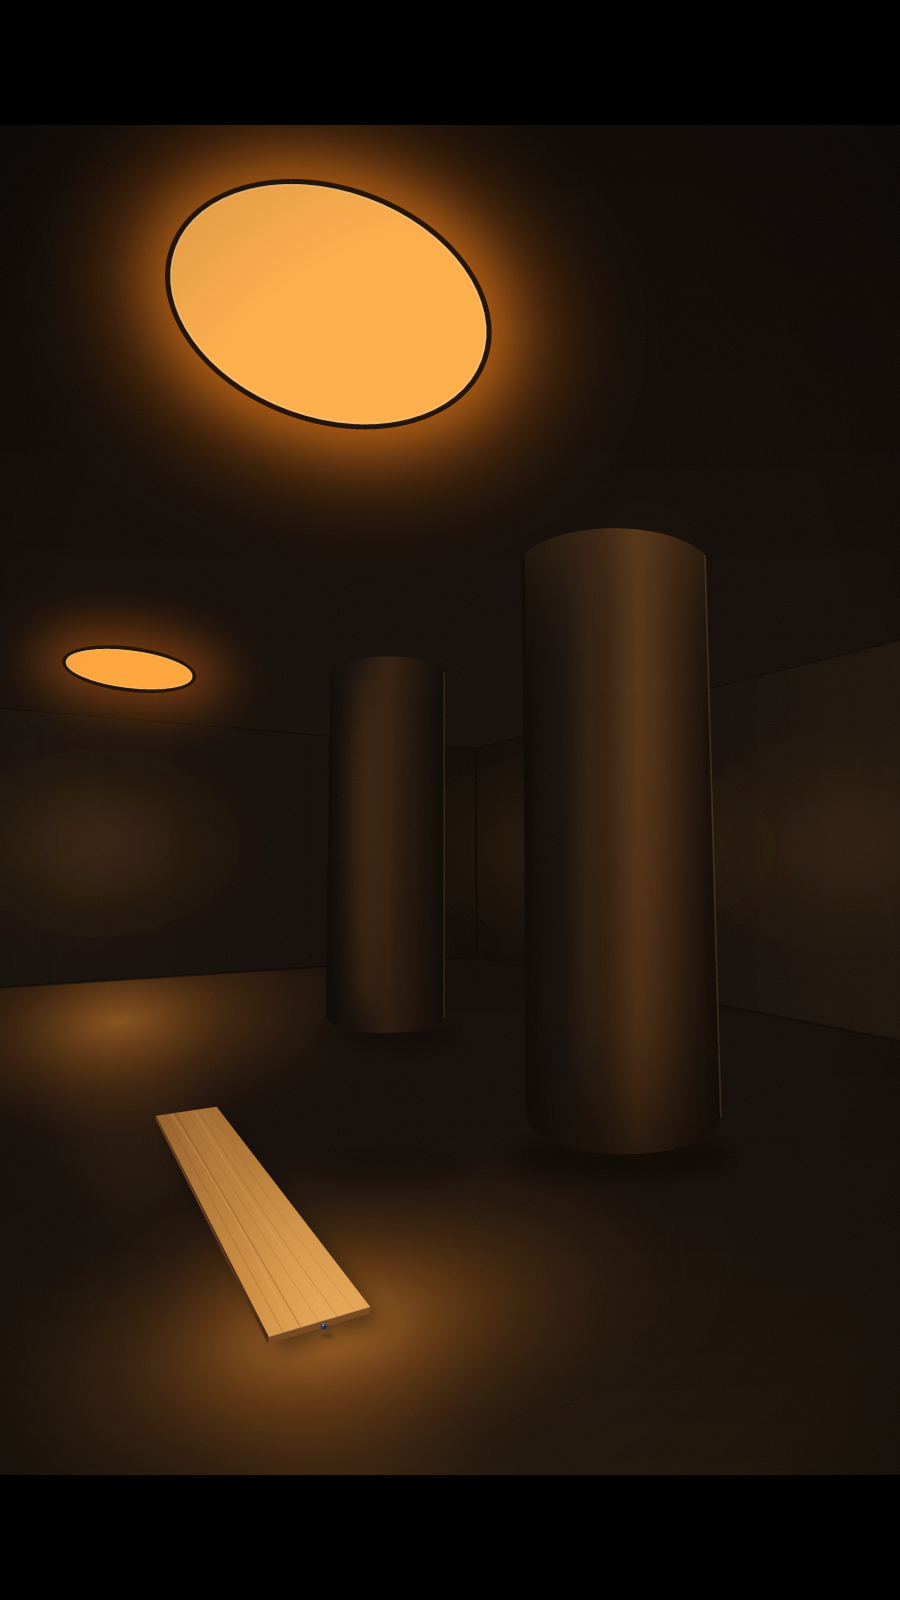
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
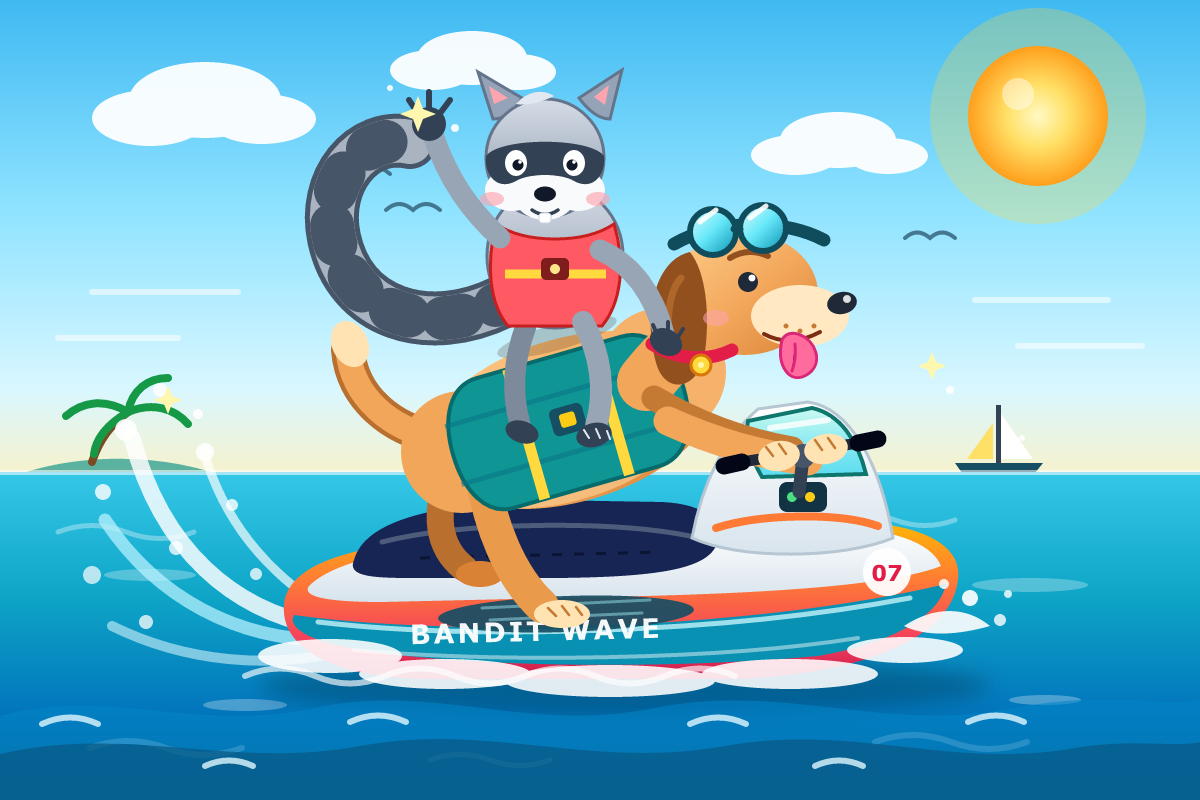
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
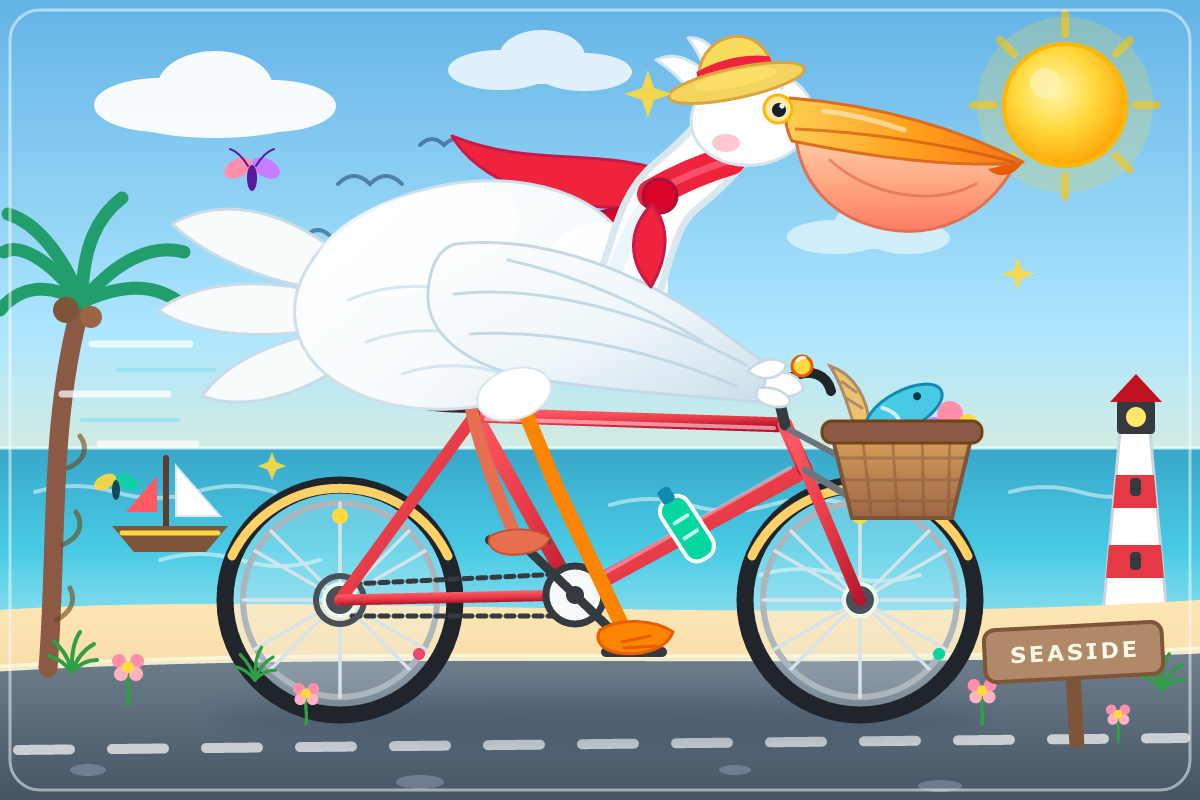
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseProprietary hosted service
Model IDgoogle/gemini-4-argon
StealthMarkOverall rank5/499 rated results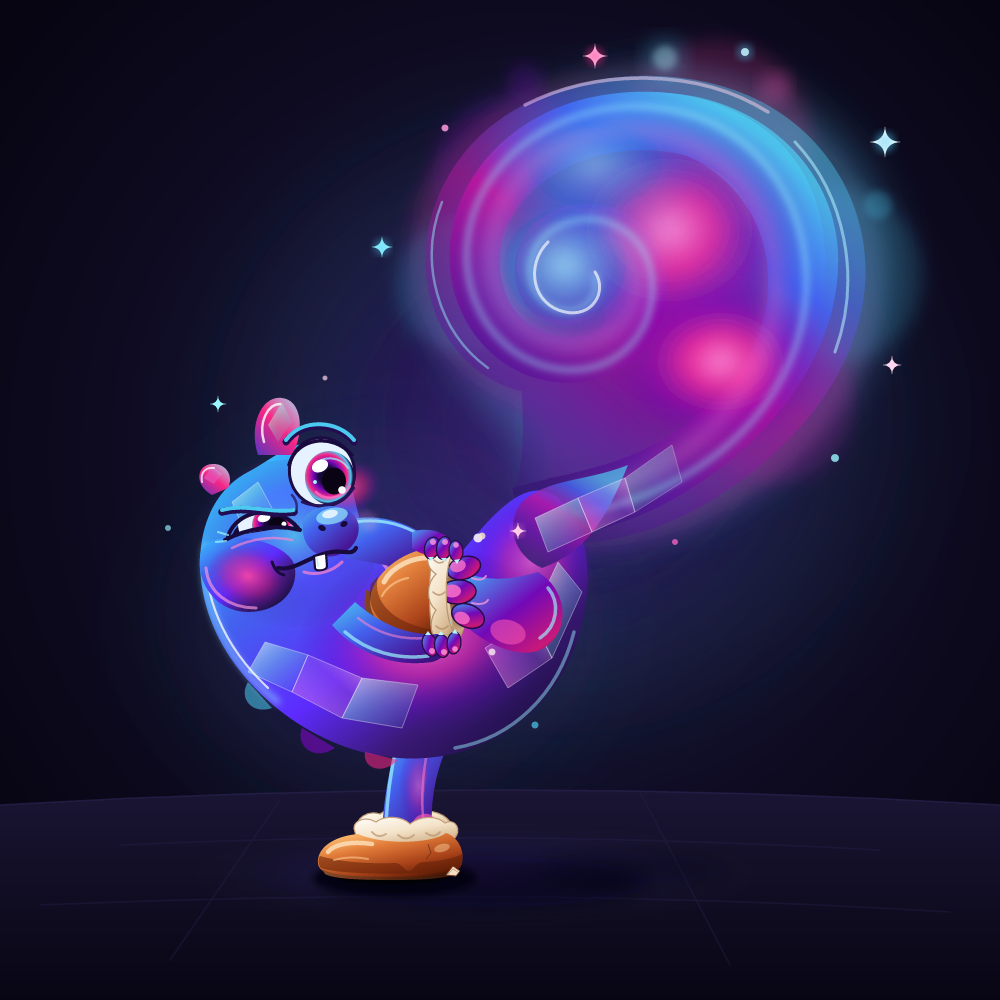
A luminous little dragon struggles with its bedtime slippers while a buoyant tail pulls it upward. The scene tests expressive anatomy, physical contact and the contrast between translucent forms and heavy objects.
First run
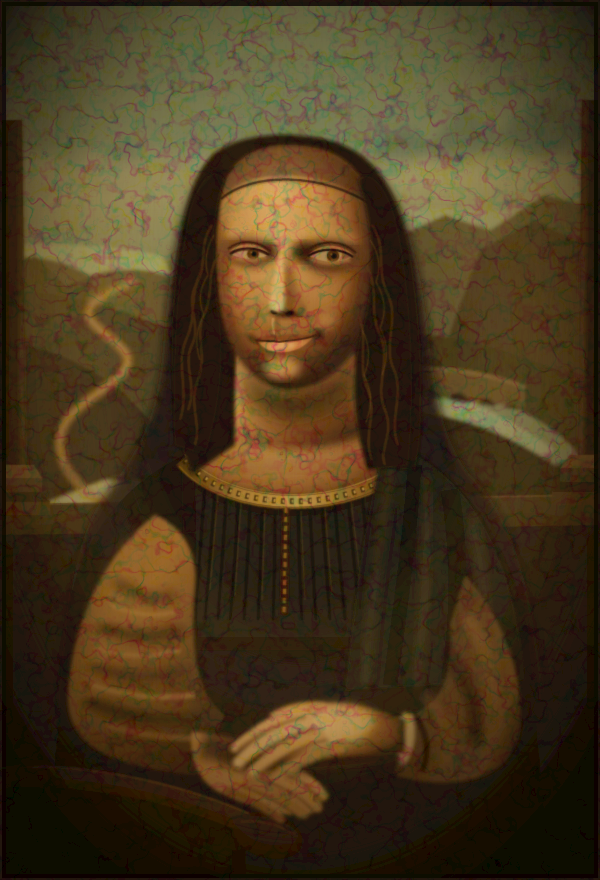
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
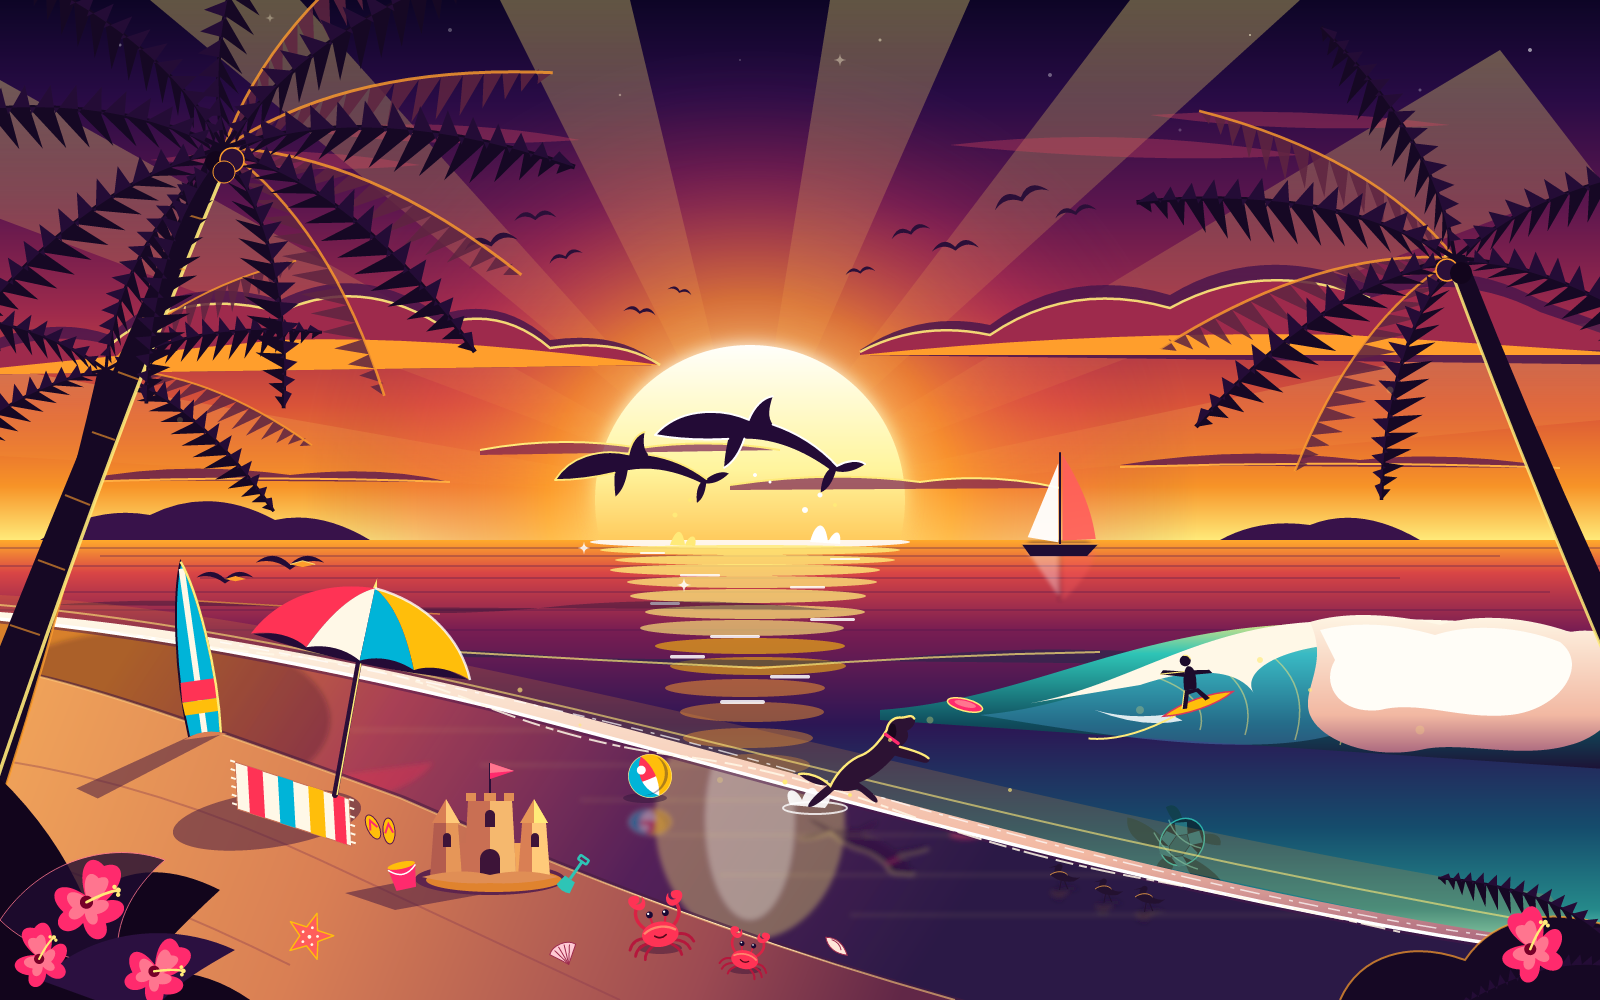
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
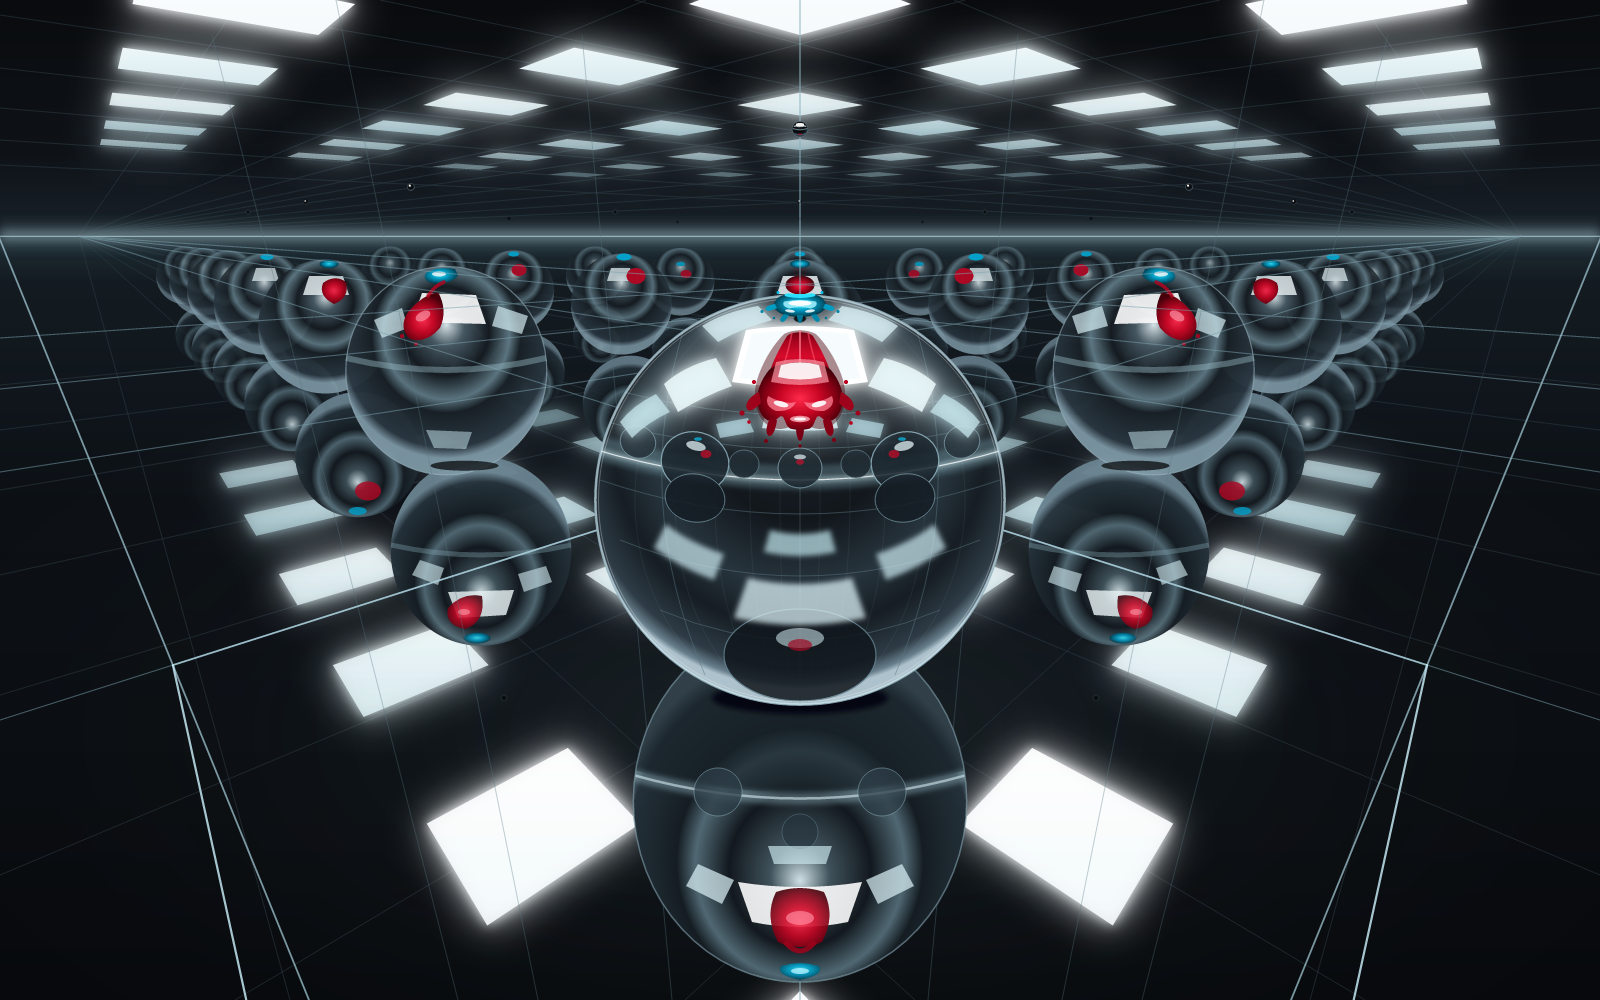
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
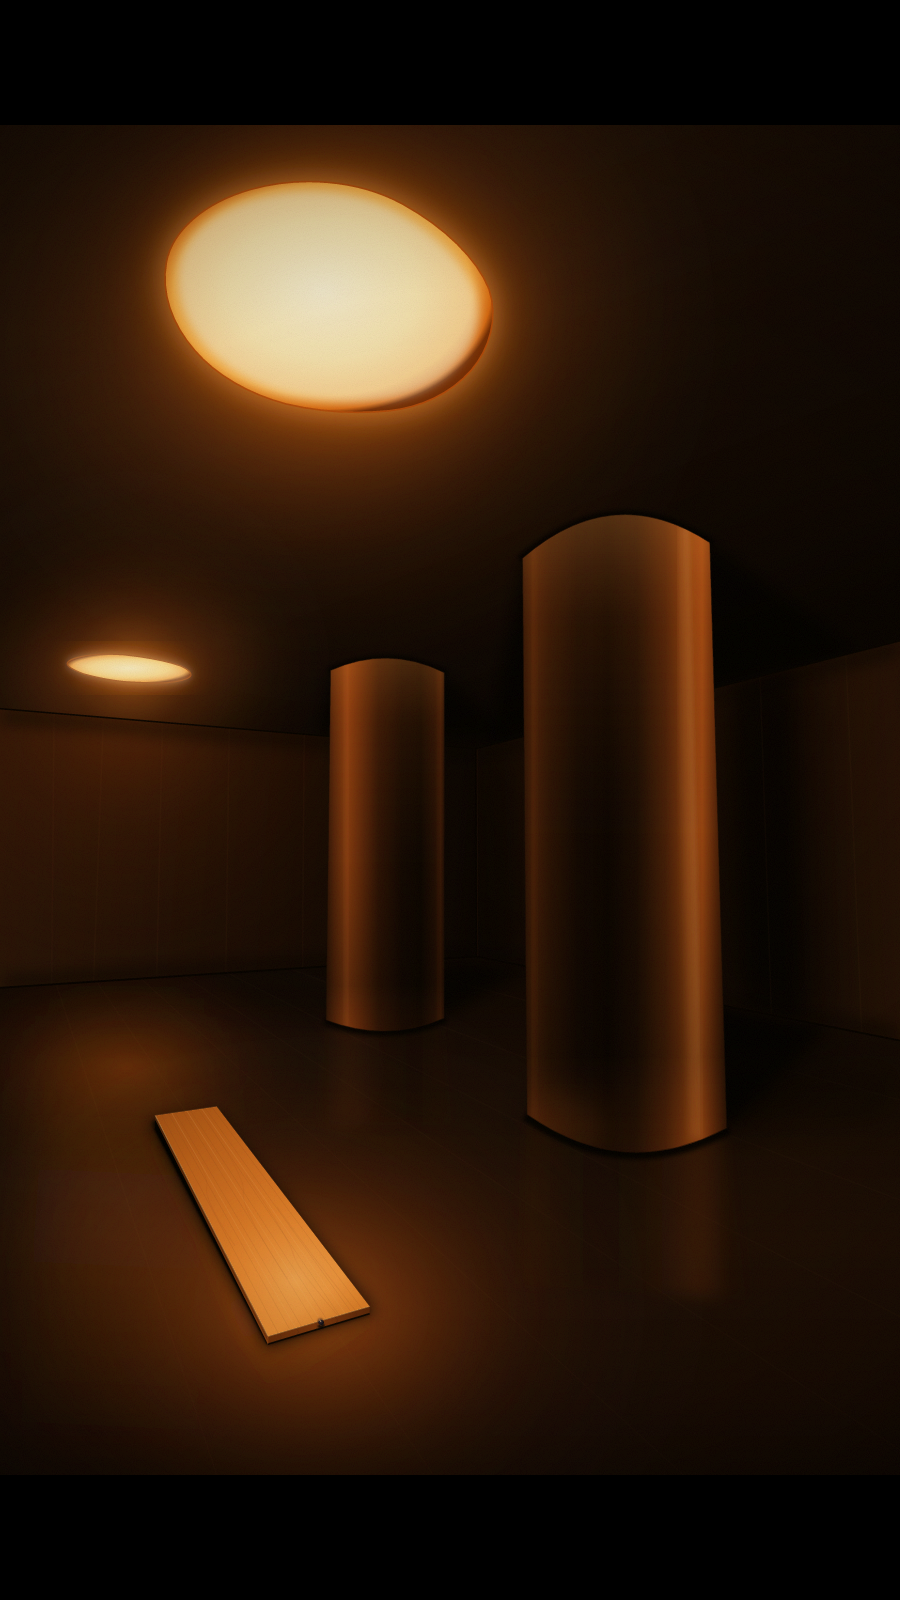
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
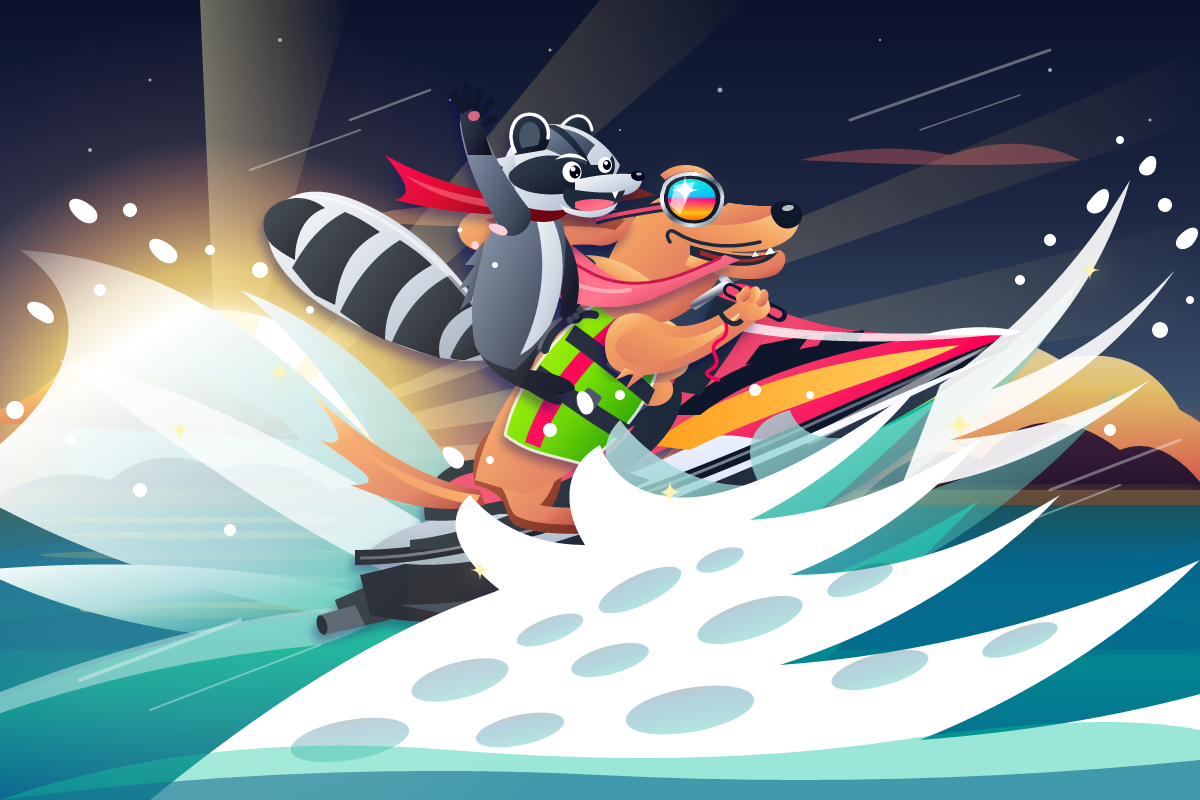
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
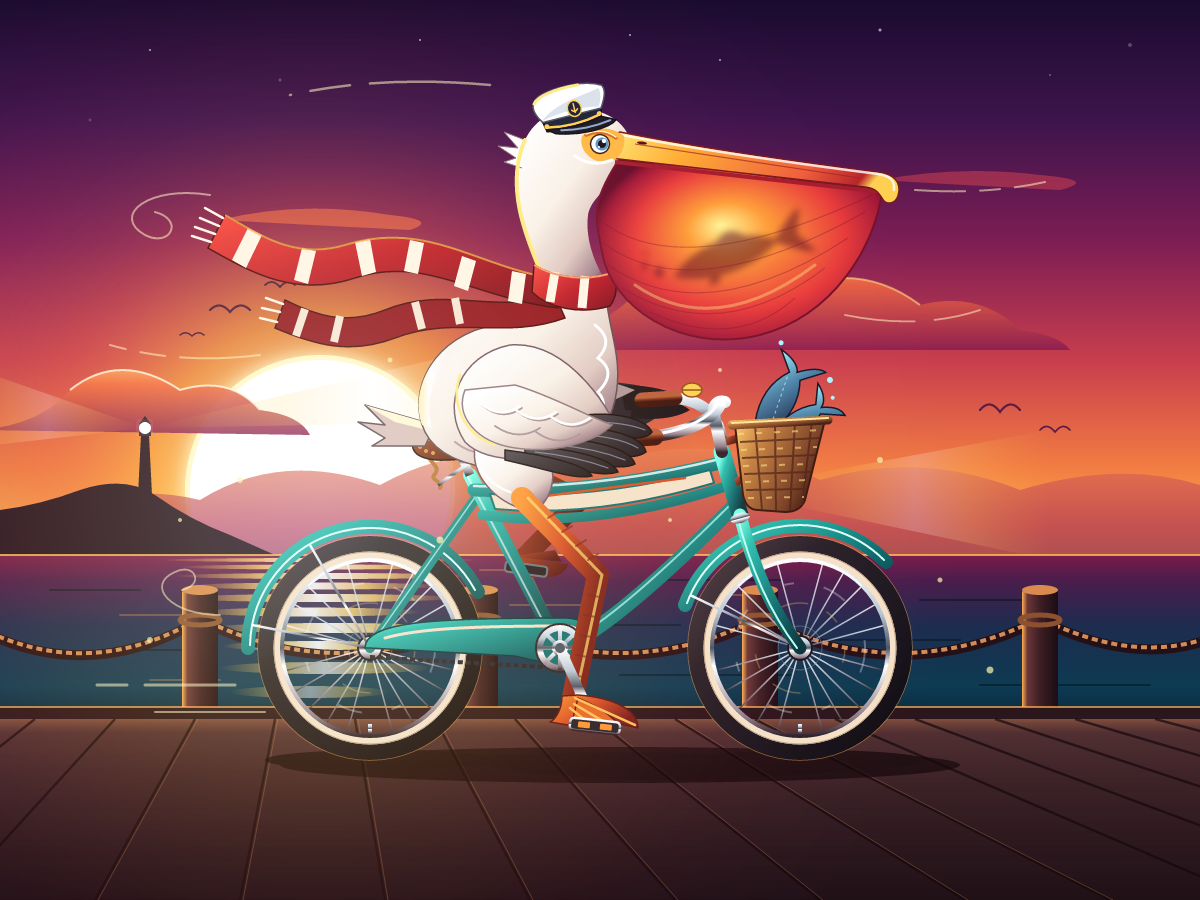
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
Model IDstealth/cat-jam
StealthMarkOverall rank37/499 rated results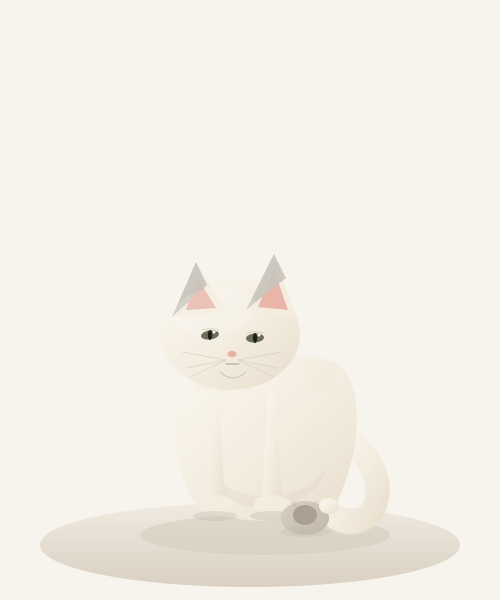
An ivory cat nods intently to music beside a tiny speaker. The scene tests feline anatomy, movement conveyed through a still pose and the contrast between pale fur and woven fabric.
First run
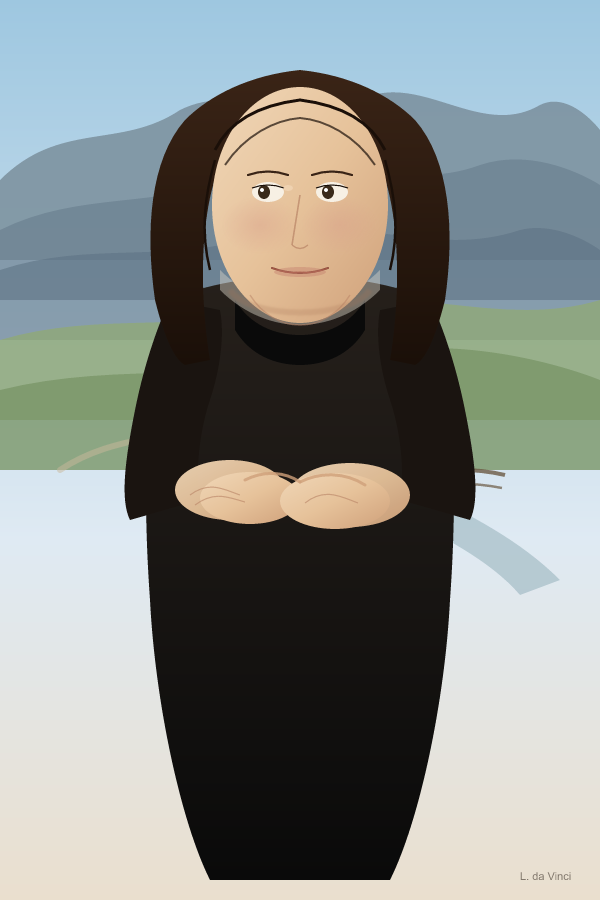
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
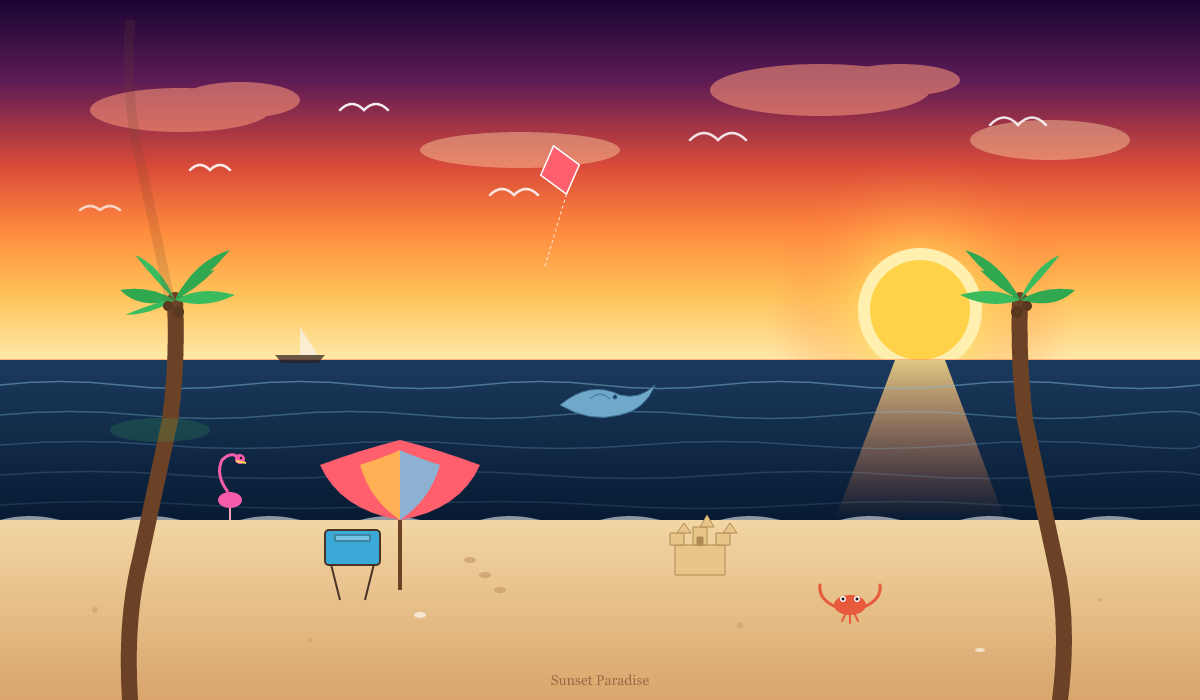
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
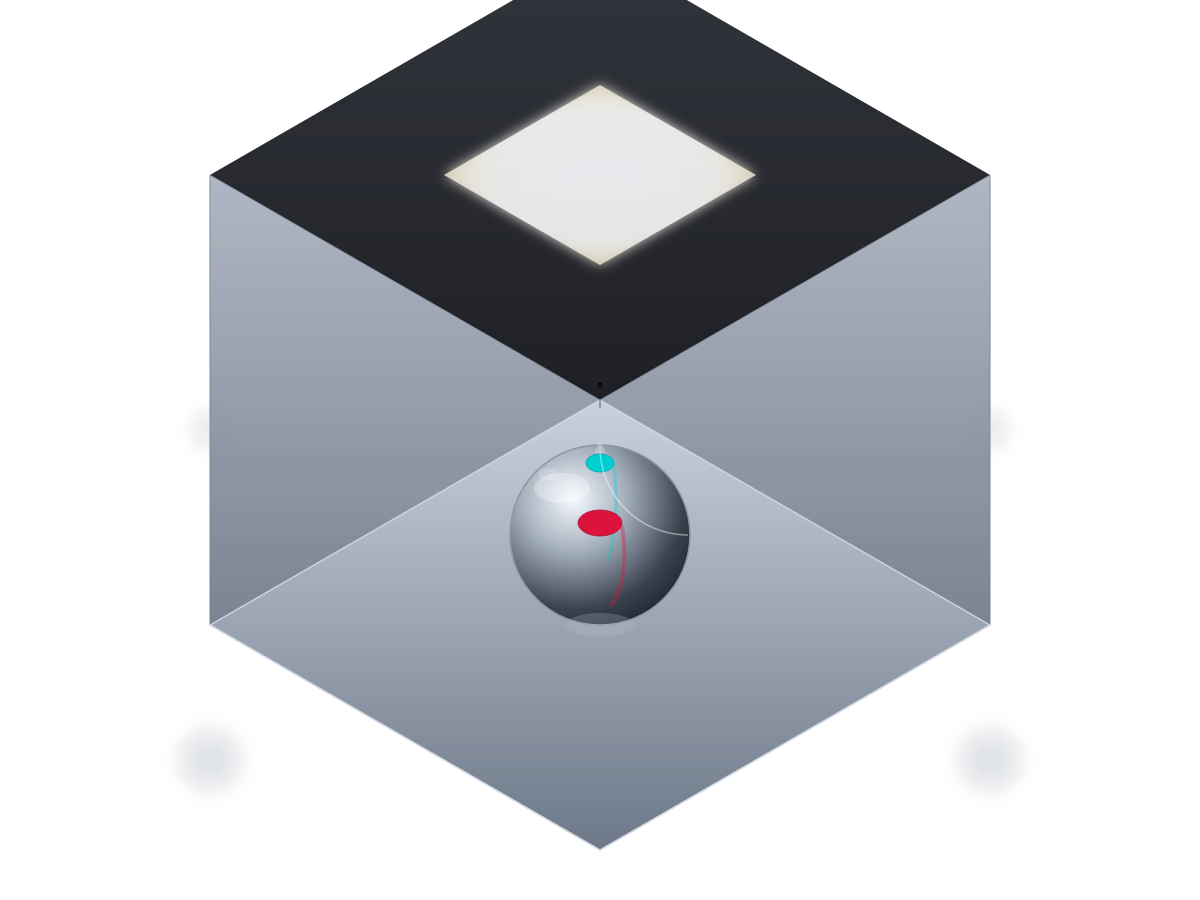
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
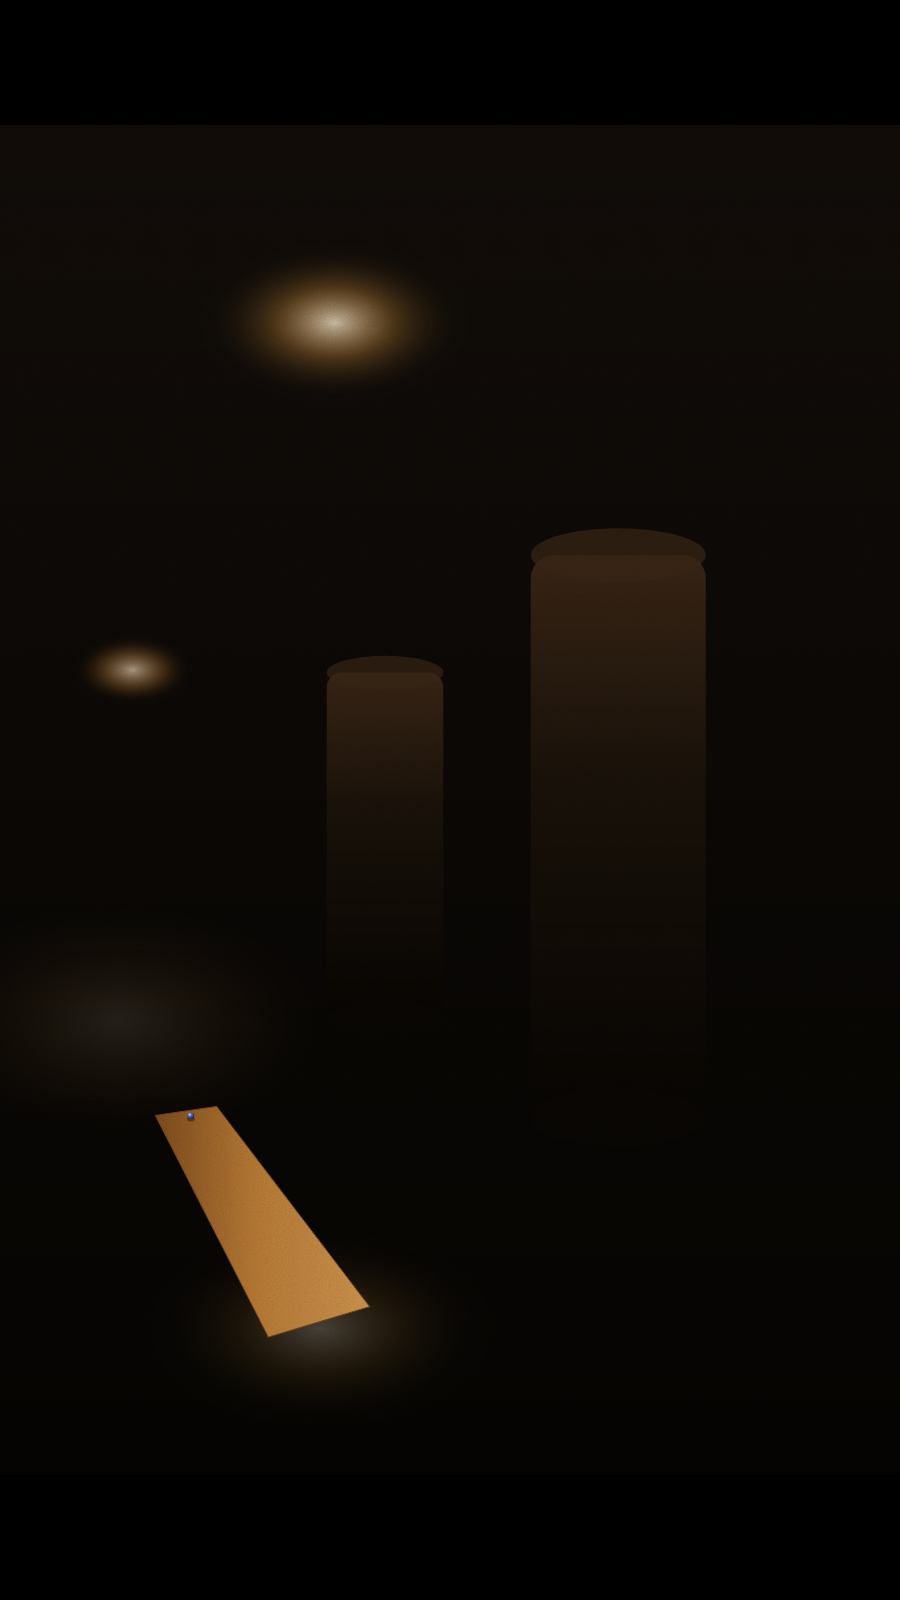
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
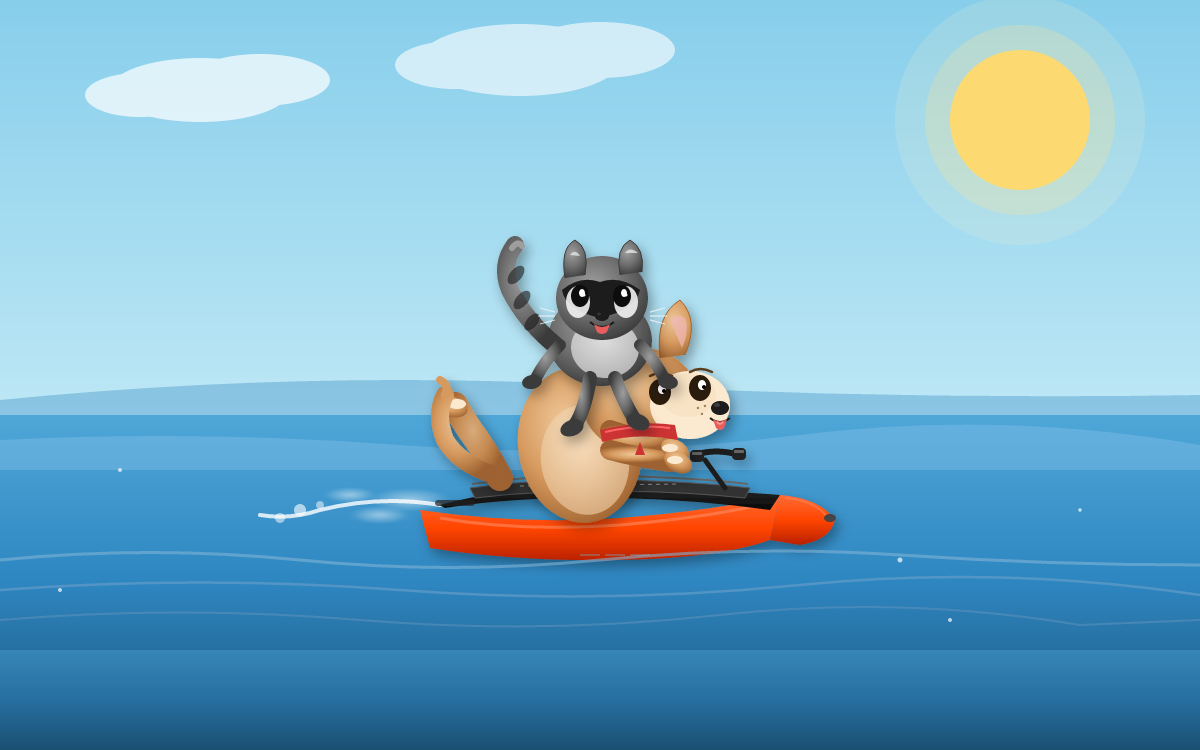
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
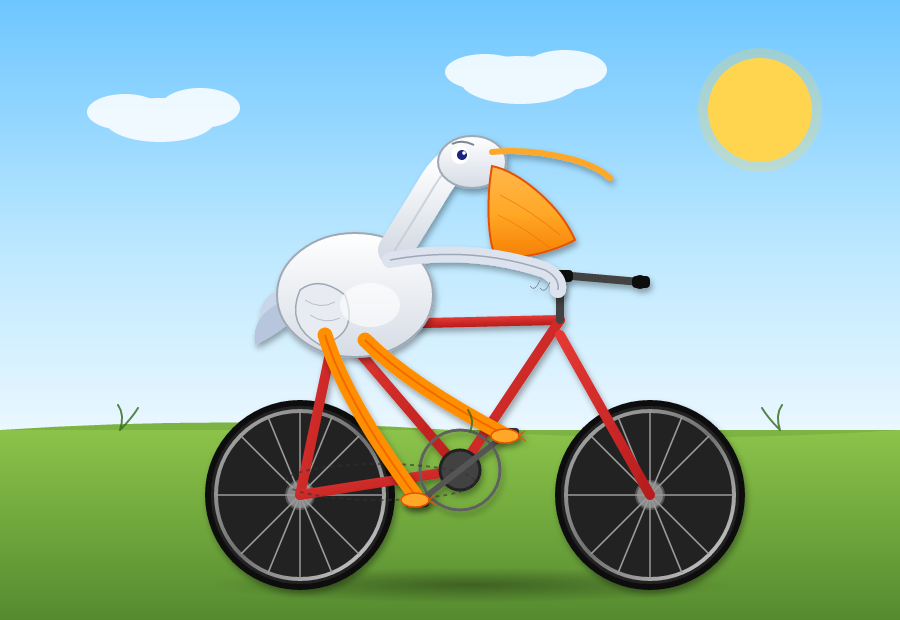
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseMuse Model License
Model IDmeta/muse-spark-open
StealthMarkOverall rank25/499 rated results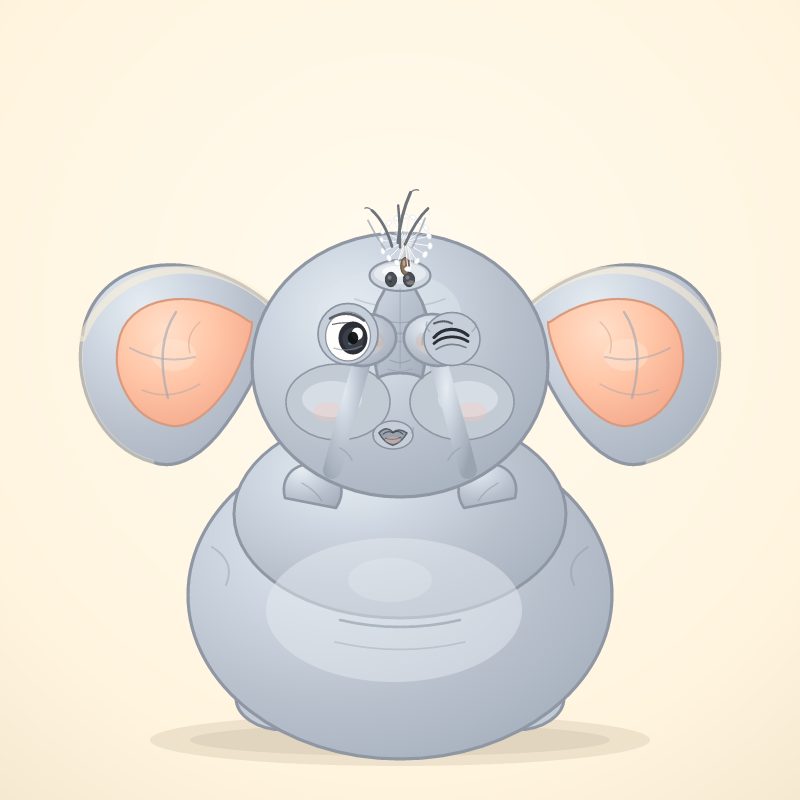
A small elephant protecting a delicate seed tests expressive anatomy, physical contact and contrasting organic materials.
First run
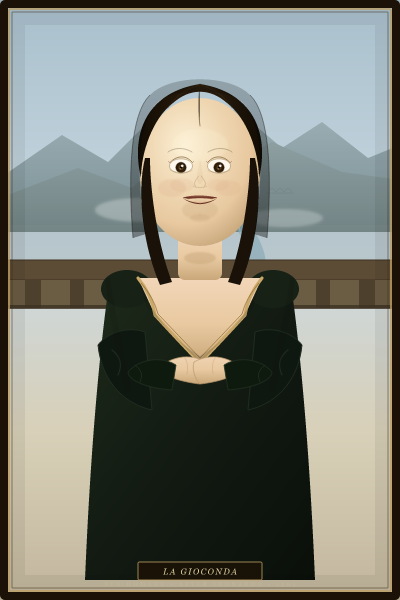
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
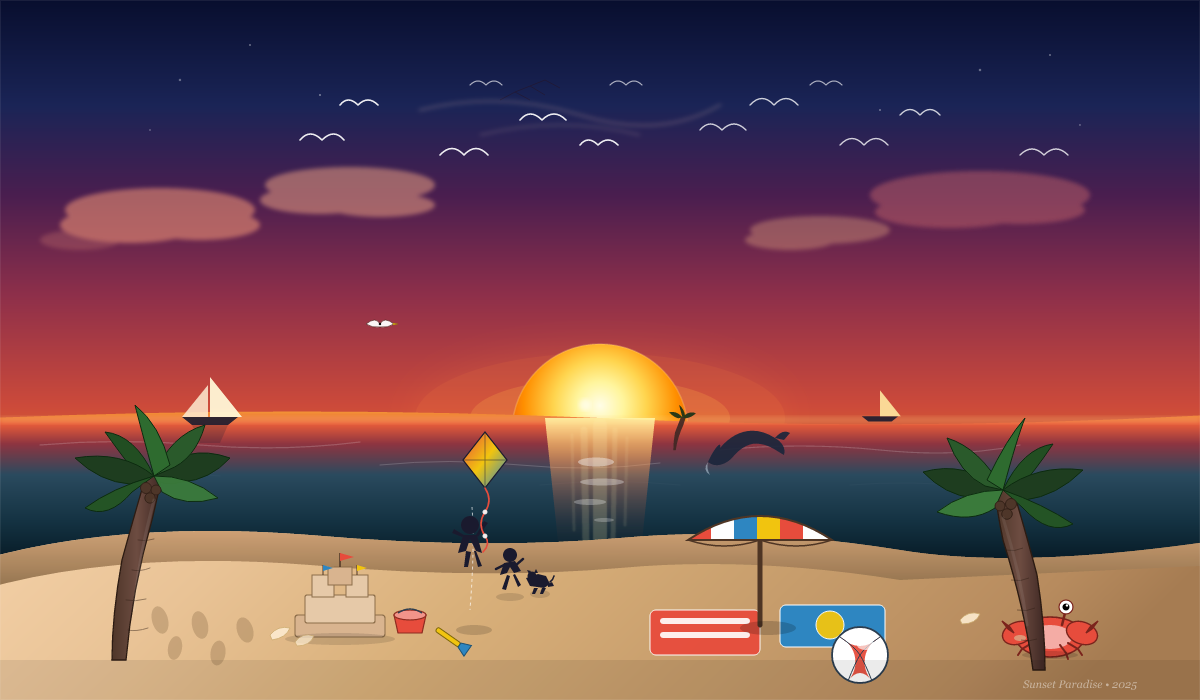
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
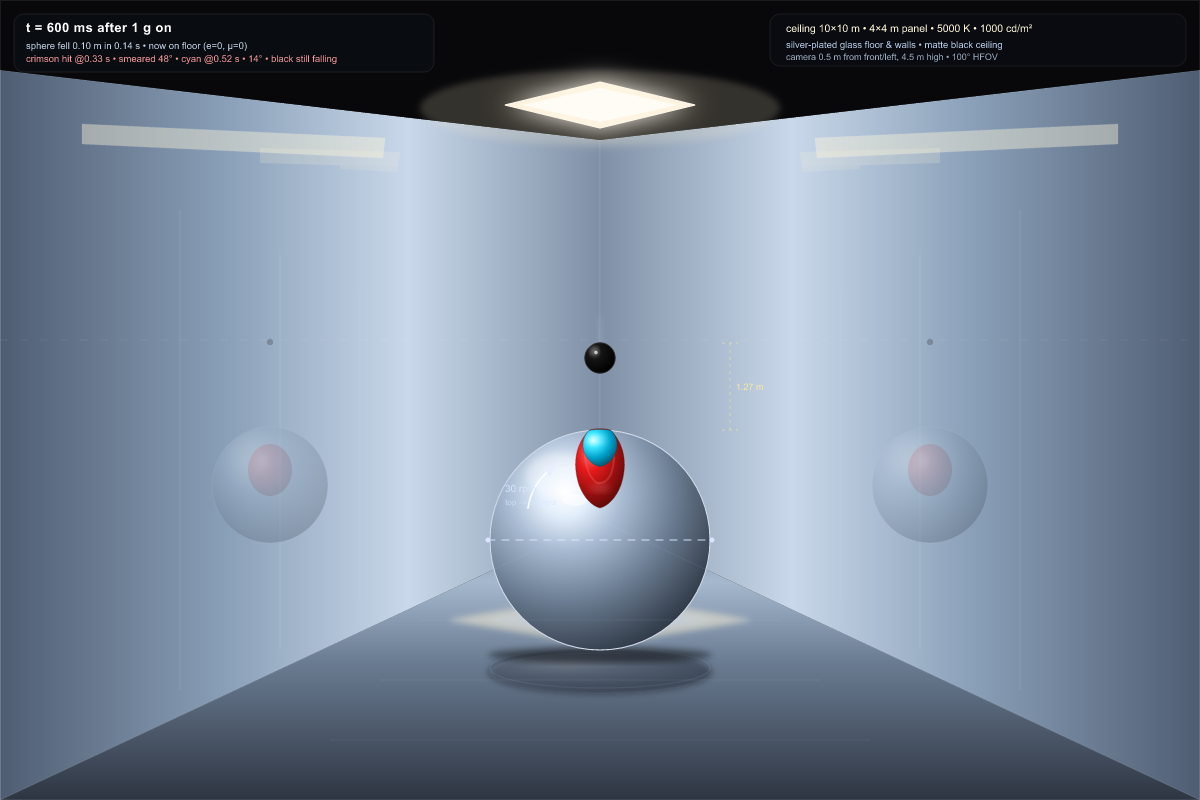
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
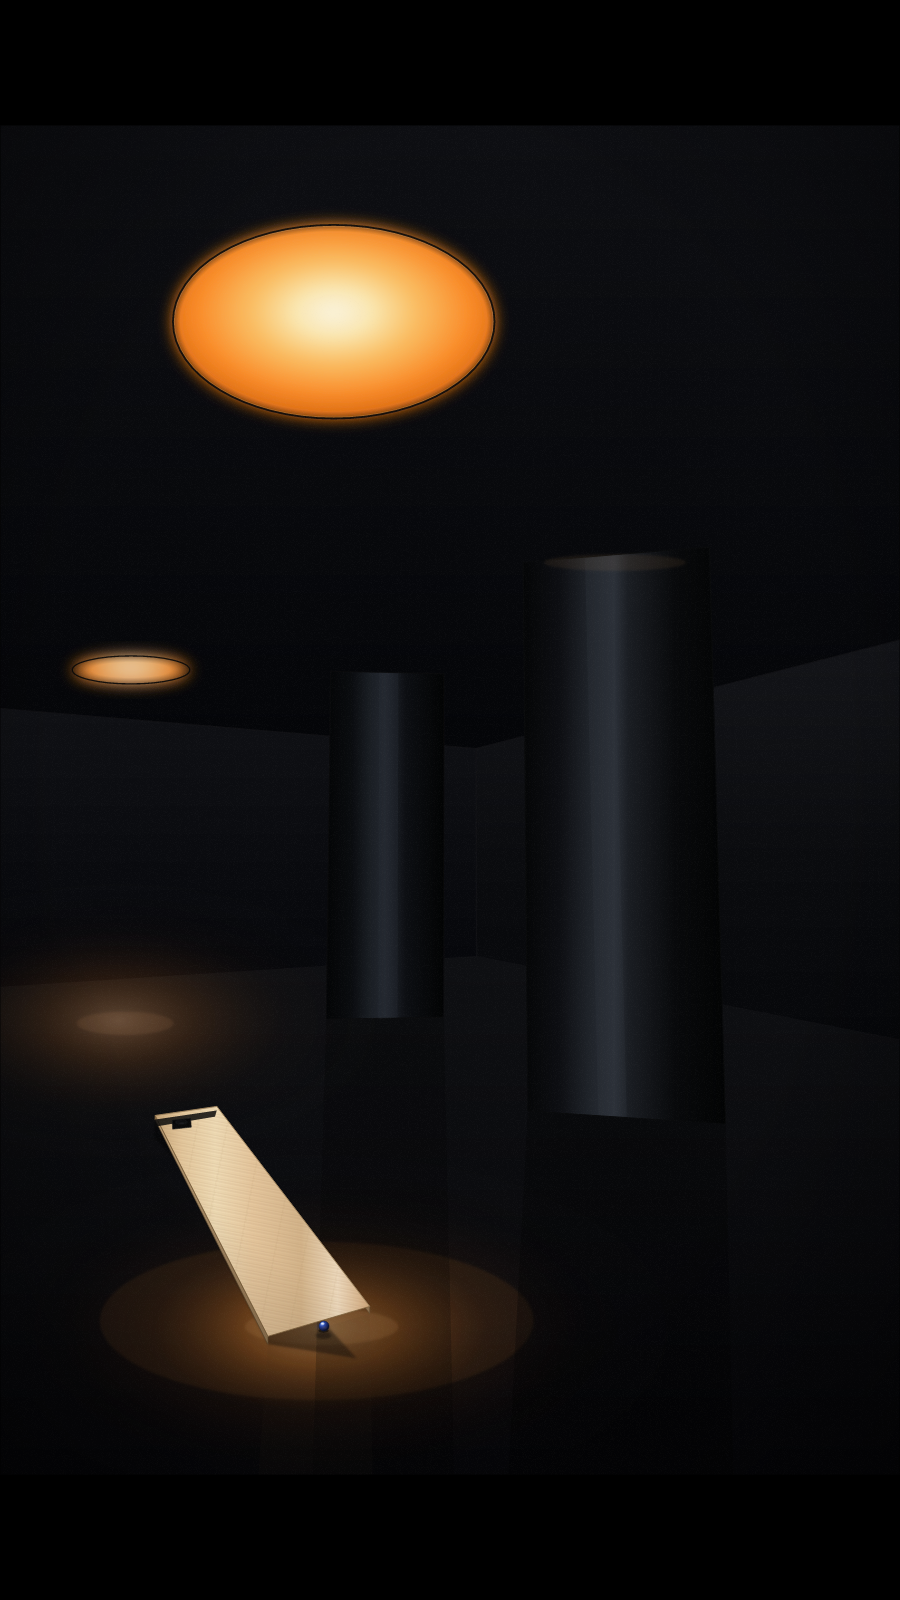
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
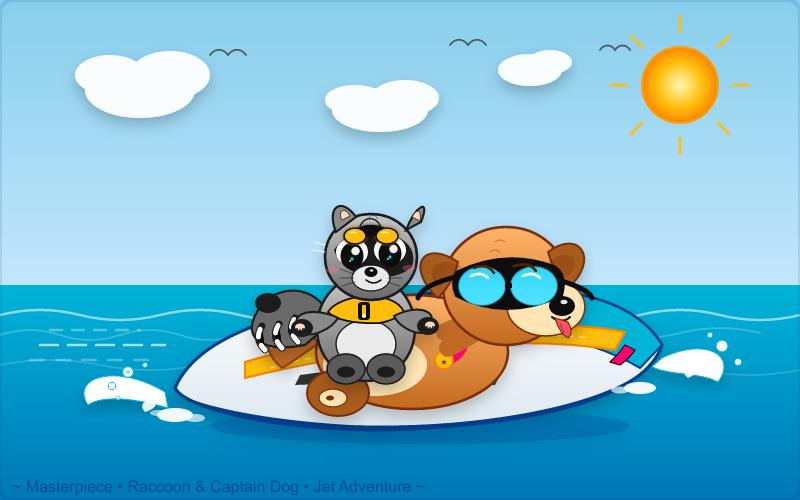
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
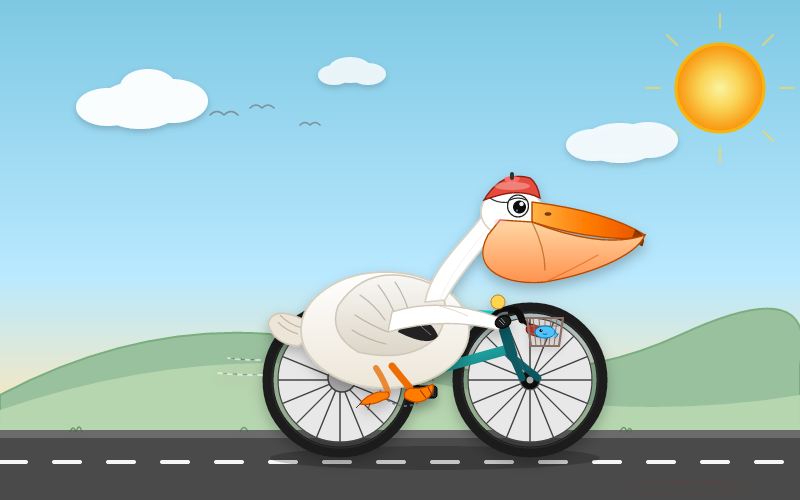
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseApache 2.0
Model IDreflection/beam-1.0-501b-a23b
StealthMarkOverall rank40/499 rated results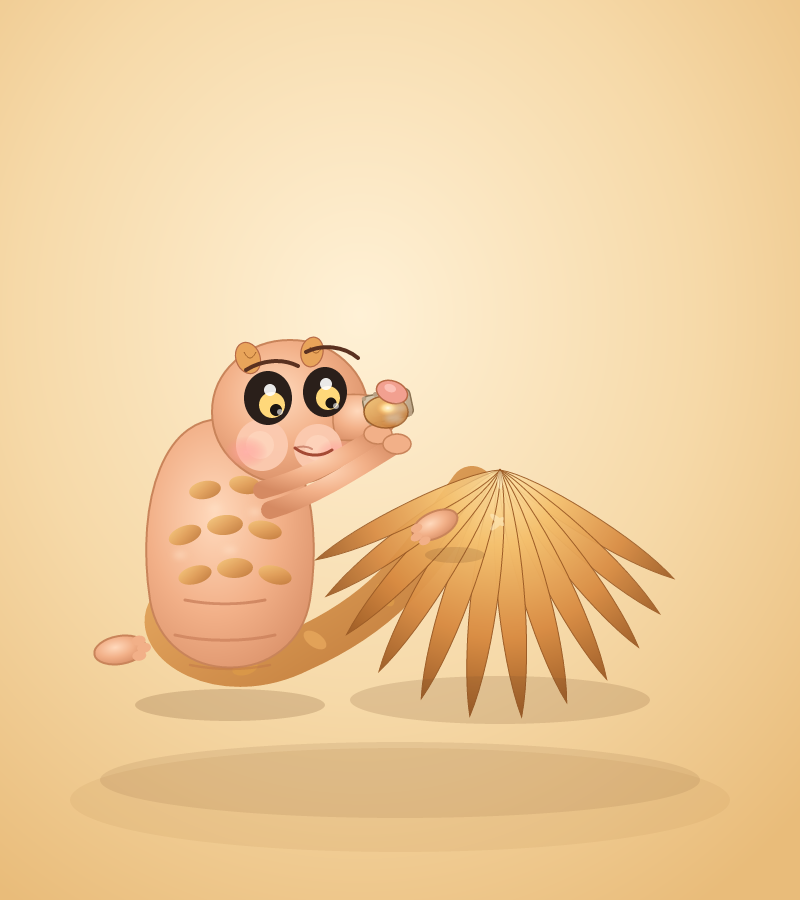
A golden pangolin polishes its oversized amber tail while its nose smudges the same scale. The scene tests expressive anatomy, physical contact and contrasting translucent, polished and soft materials.
First run
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
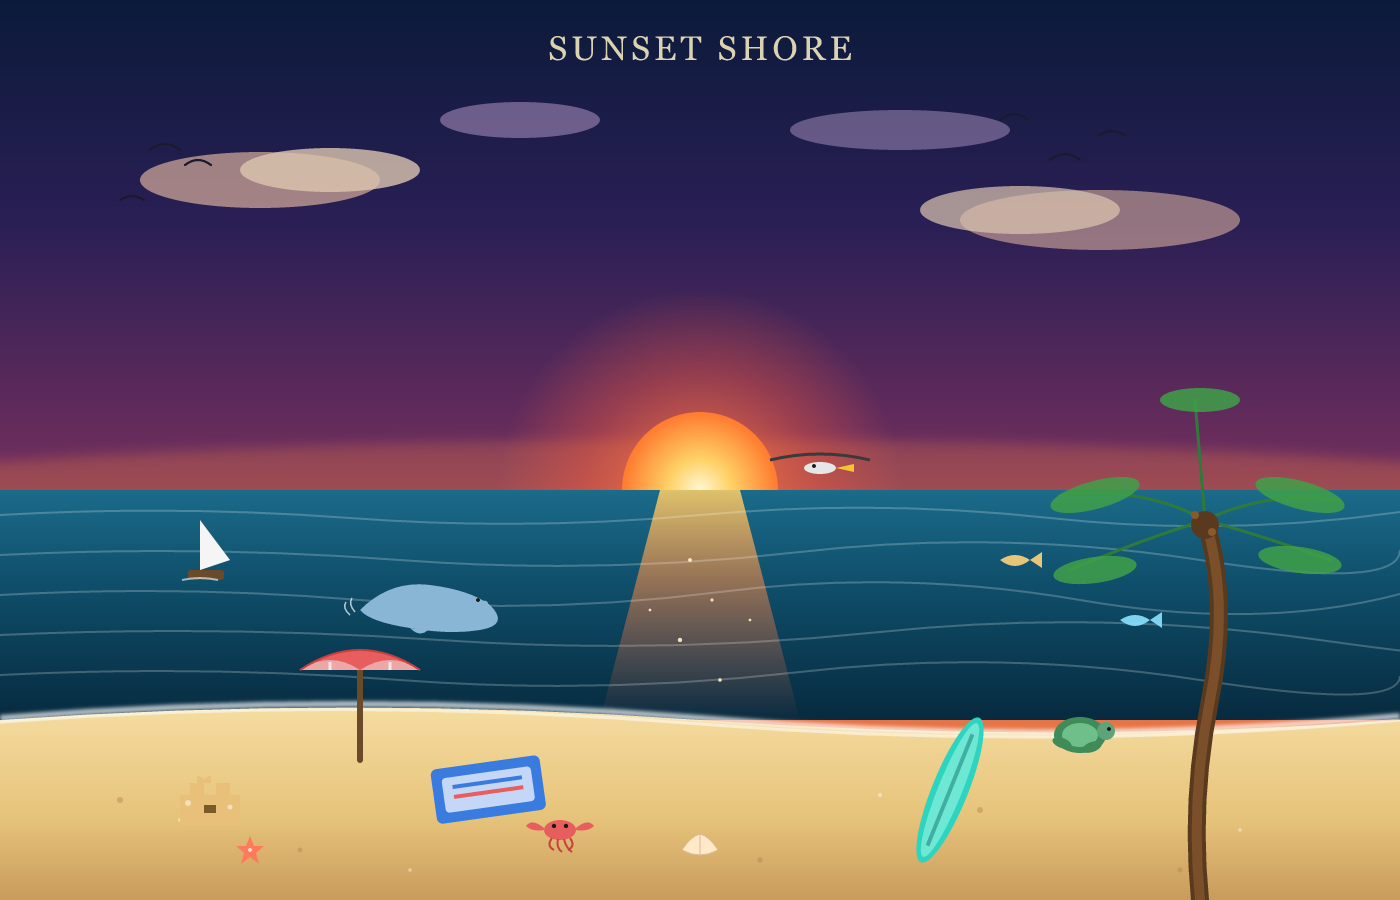
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
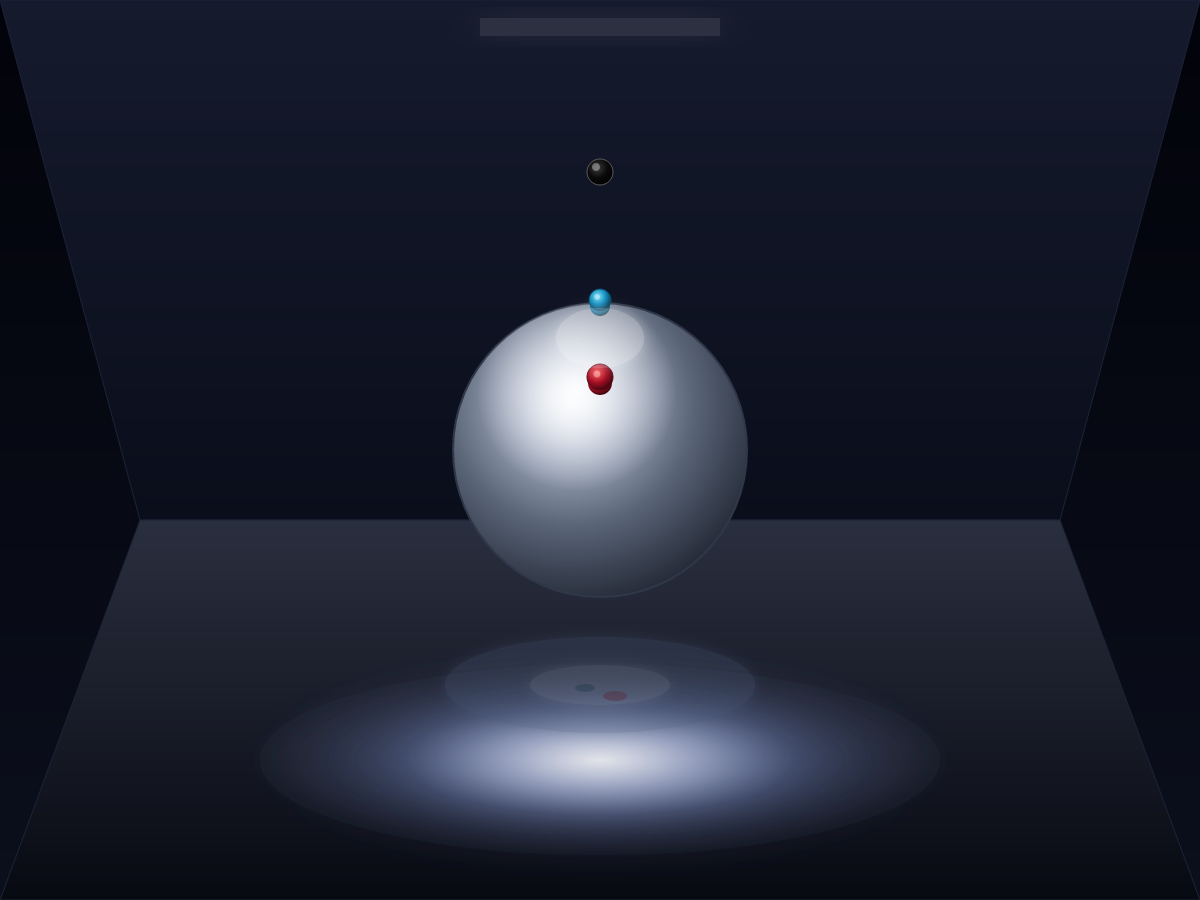
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
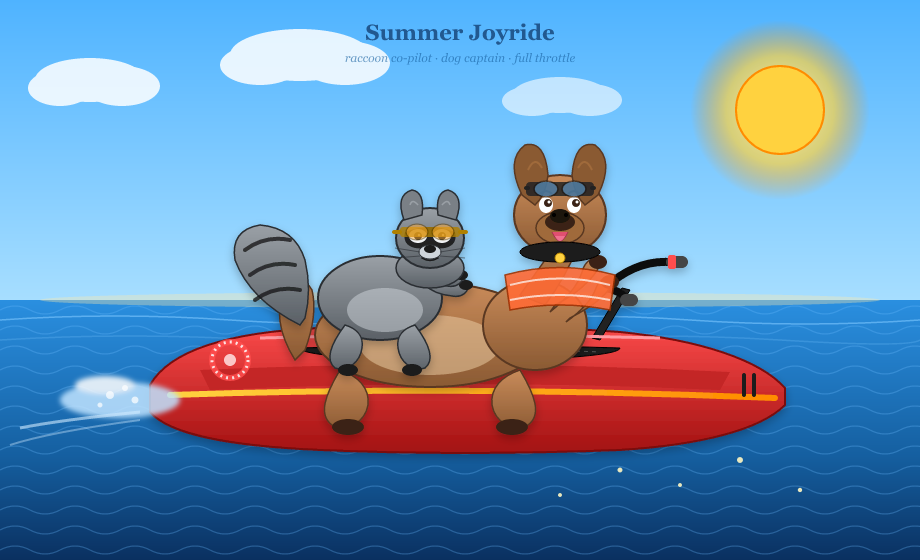
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
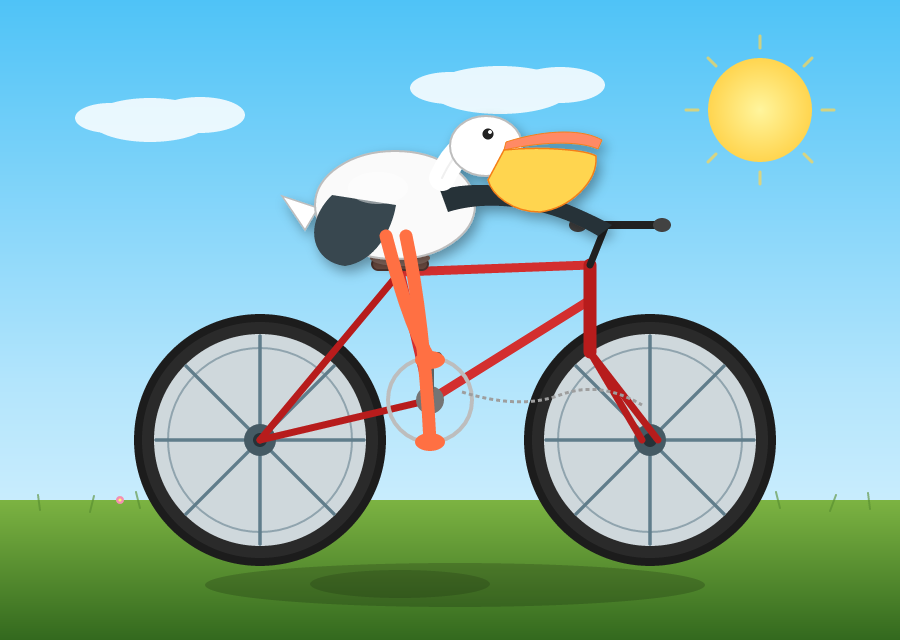
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
LicenseMIT
Model IDdeepseek/deepseek-v4.1-flash-1017
StealthMarkOverall rank9/499 rated results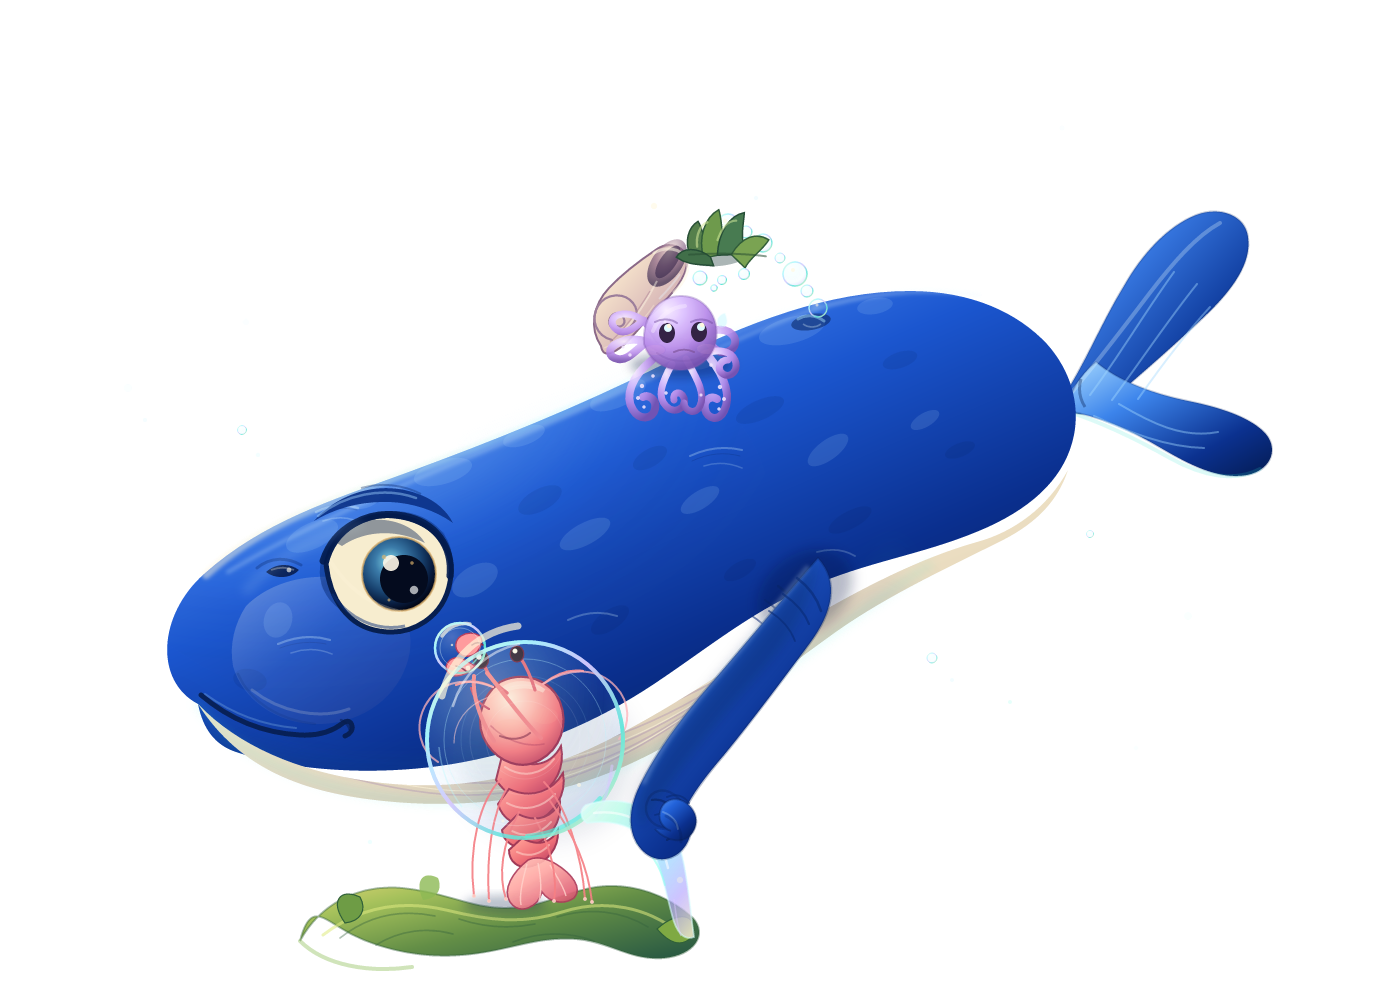
A whale and a tiny shrimp examine one another through bubble lenses, with an octopus nearby. The scene tests interacting characters, differences in scale and transparent materials.
First run
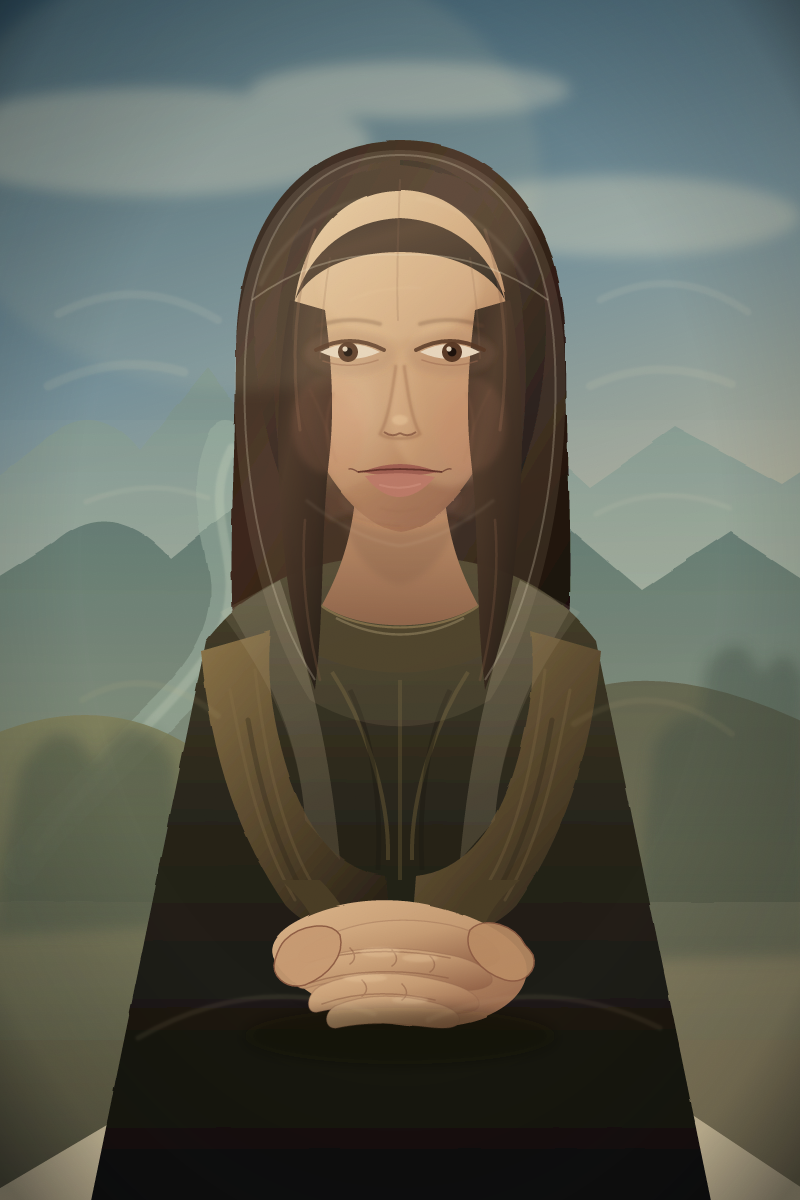
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
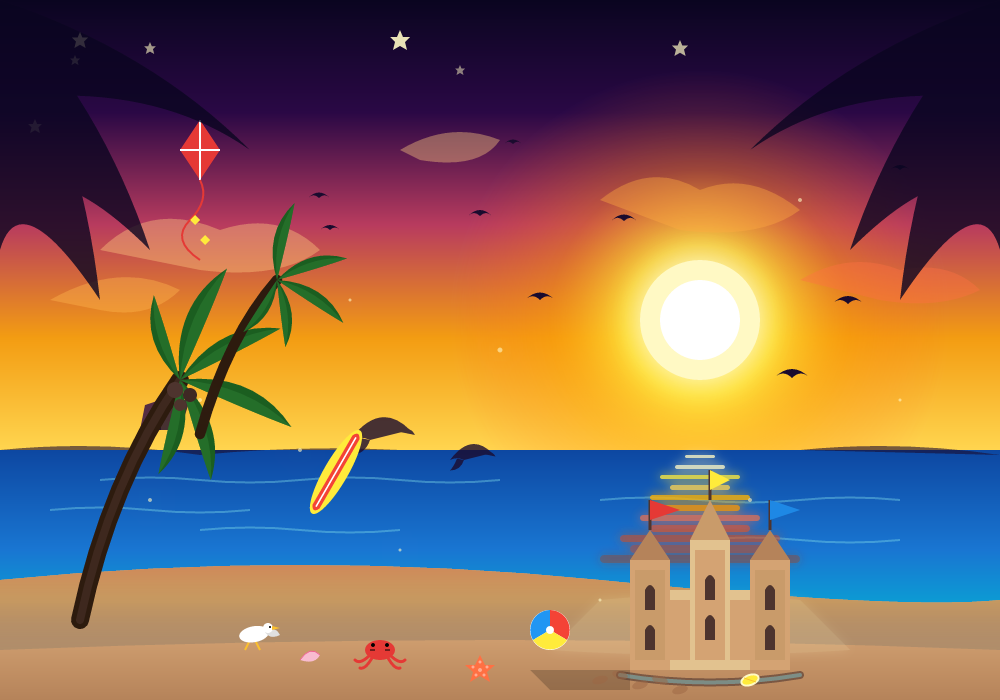
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
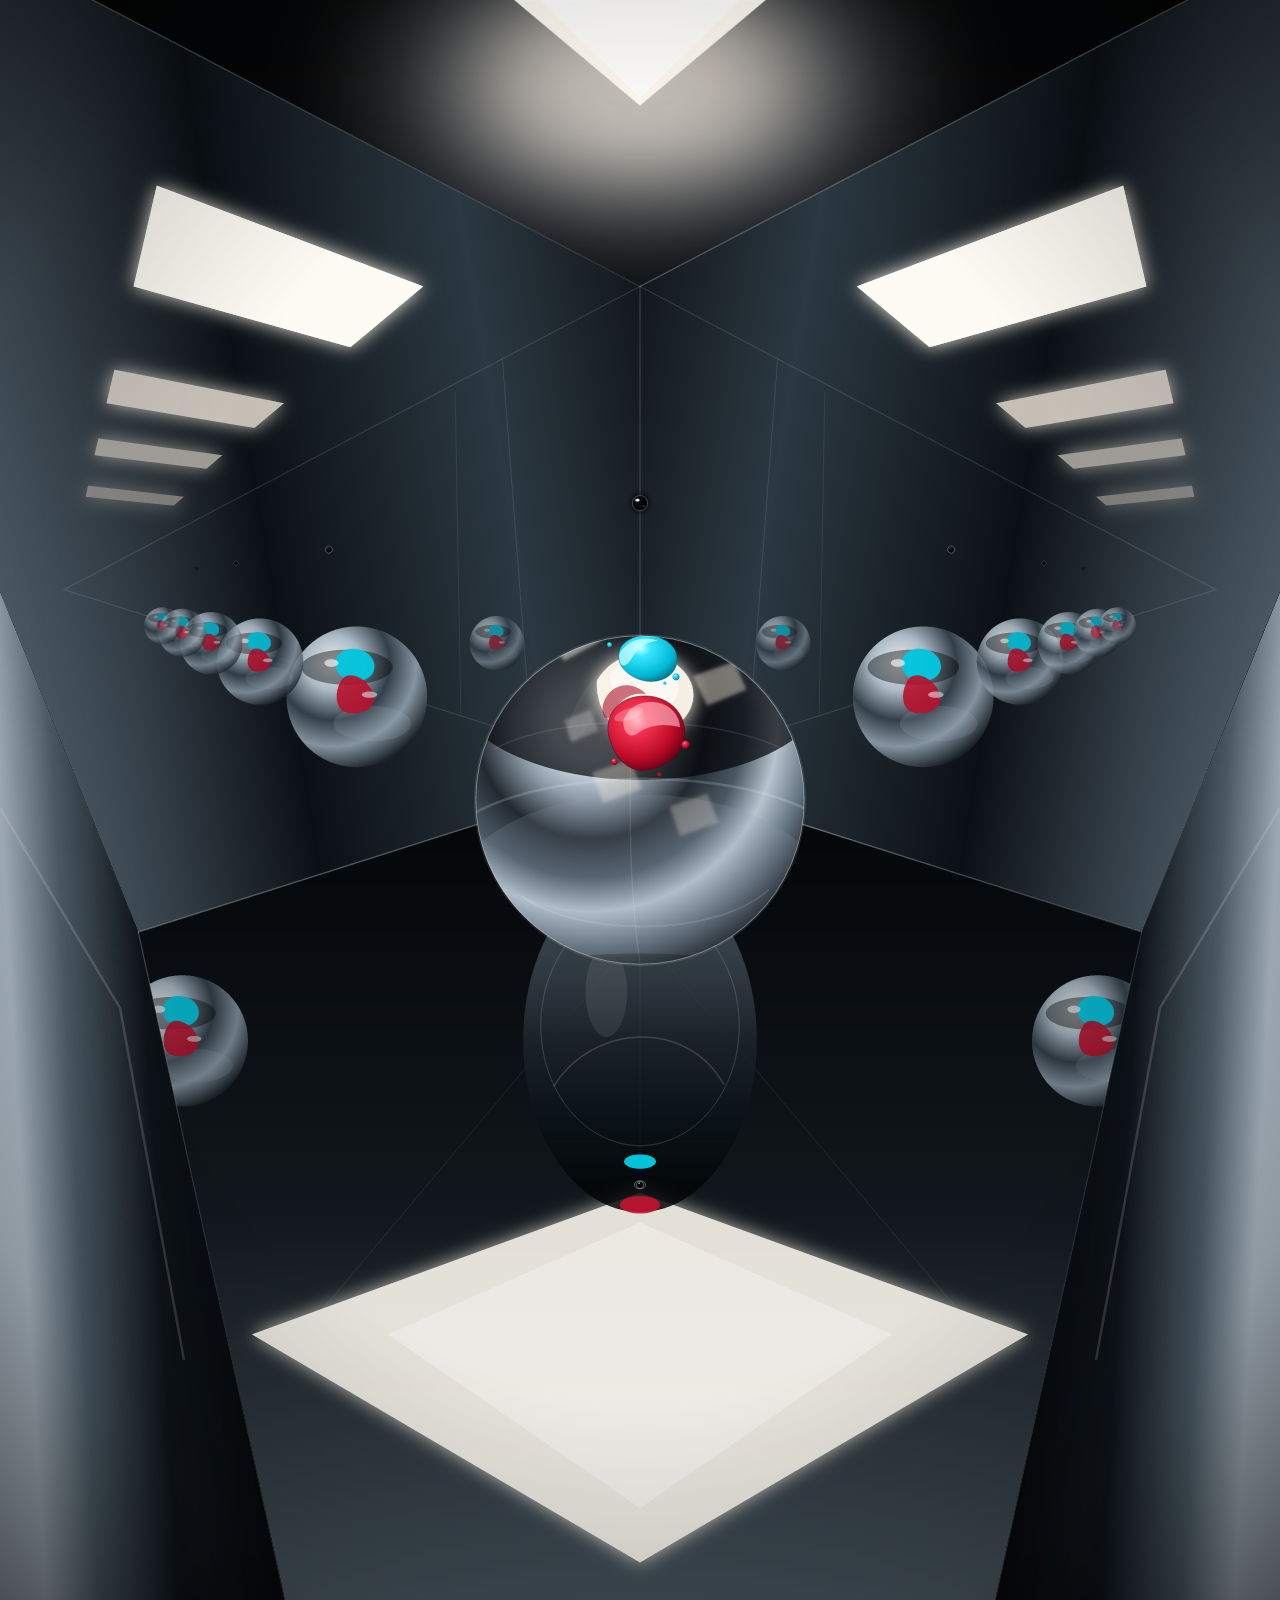
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
Try another task or widen your model selection.
StealthMark scoreStealthMark measures fluid and visual intelligence of AI models, resisting any pre-existing benchmark focused training.
The ability to reason, solve problems and understand how things relate and behave.
The ability to imagine, create and accurately reconstruct complex images in code form.
Scores reflect how well each result meets the benchmark requirements.
Overall combines weighted task scores on a scale from 0 to 100. Estimated means the total includes an estimate for one missing scene.
Subjects, actions and likeness.
Coherent bodies, joints and machinery.
Perspective, scale and contact.
Lighting, shadows and reflections.
Clear, purposeful small features.
Composition, expression and drawing skill, including complexity and its execution.
Surfaces, texture and movement.
Clean shapes, layers and edges.