stealthmodels.

MODEL BENCHMARKS

Mistral Large 4

Multimodal MoE with text and image input, adjustable reasoning, tool calling and structured outputs. Available as a public API preview.

BENCHMARK BY BENCHMARK

Mistral Large 4 benchmark scores

StealthMark
43.3/100Overall rank 35/58
General Intelligence
34.4/100
Visual Intelligence
58.0/100

Mistral Large 4Other modelsMedian

Reasoning efficiency

How many reasoning tokens a model needs for the quality it delivers.

Single-step reasoningHow much it reasons to understand a taskRank 29/56
Multi-step reasoningHow much it keeps reasoning as a task goes onRank 25/54

Cost efficiency

How much Performance you get for your money.

Rank 40/52

DATASHEET

Mistral Large 4 specs and pricing

A good fit forCoding agents and document analysis that combine image input, long context, tool calling and structured responses.

Mistral Large 4Other modelsMedian

PriceDeveloper API, input / output per 1M tokens
$1.36 / $4.18Cheaper than 18 of 46 others
Context windowTokens in one request
1,048,576Joint largest with 21 others
Output speedTokens per second, our measurement
151 tokens/sFaster than 30 of 51 others
Developer
Mistral AI
Released
6 Oct 2026
Family
Mistral
Open model
No
Local model
No
Origin
France
Parameters
1.05T
Active parameters
49B
Max output
262,144 tokens
Input → output
Text, image → text
API model ID
mistral-large-4
Architecture
Granular mixture of experts (MoE); multimodal text and image input, text output.
All prices and providers3

Recorded 2026-10-06: OpenRouter preview (2026-10-06): USD $0.68 input, $0.07 cached input read and $2.09 output per 1M tokens.

  • OpenRouterObserved 2026-10-23
    Input $1.36Output $4.18Cached read $0.14

    per 1M tokens

    mistralai/mistral-large-4-0
  • OpenRouterObserved 2026-10-06
    Input $0.68Output $2.09Cached read $0.07

    per 1M tokens

    Historical rates

    mistralai/mistral-large-4-0
  • Mistral AI APIObserved 2026-10-23
    Input $1.36Output $4.18Cached read $0.14

    per 1M tokens

    Available

    mistral-large-4
Measurements and sources6

GAME BENCHMARKS

Watch Mistral Large 4 play

Foresight

Anticipating threats and planning ahead

22.0/100Rank 45/54
Survived 0 of 3
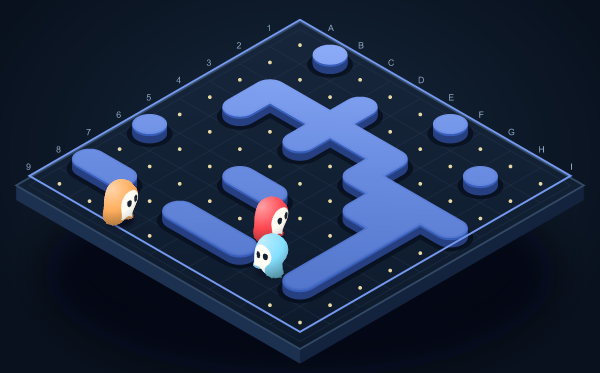
Foresight: complete playing field
Level 34 ptsTurn 8 / 20

Points per level

  1. Level 1Second Thoughts1 ptsBest 27Out of lives
  2. Level 2Pressure Pot9 ptsBest 13Out of lives
  3. Level 3Hide or Flight4 ptsBest 19Out of lives

Collect coins while avoiding ghosts. Ghosts move before the player each turn, and collisions cost a life. 3 levels in sequence, up to 66 turns in total. Earlier moves and outcomes carry forward, testing learning across levels.
Latch

Cooperative planning and learning from experience

49.4/100Rank 30/55
Cleared 5 of 5
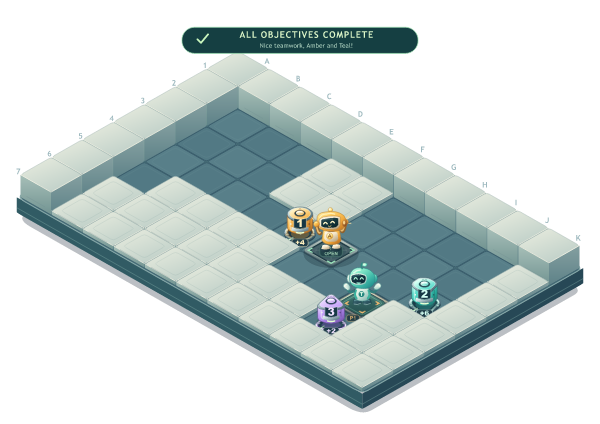
Latch: complete playing field
Level 519.8 ptsTurn 31 / 40

Points per level

  1. Level 1Hold the door5.2 ptsBest 5.2Cleared
  2. Level 2Crossfeed9.6 ptsBest 10.2Cleared
  3. Level 3Relay vault15.8 ptsBest 19.2ClearedFinished early · 3 beacons left
  4. Level 4Passing bay16.2 ptsBest 18.2ClearedFinished early · 3 beacons left
  5. Level 5Second thoughts19.8 ptsBest 20.8Cleared

Coordinate two robots to push numbered cores onto matching sockets. Pressure plates hold doors open; moving either robot uses one turn. 5 levels in sequence, up to 152 turns in total. Earlier moves and outcomes carry forward, testing learning across levels.

Mistral Large 4 benchmark results ↗

StealthMark score

StealthMark measures how well a model’s abilities carry over to original, demanding tasks it could not have trained for: physical and spatial reasoning, planning across many steps, and precise visual work. How StealthMark works explains every benchmark, what it tests and why it is hard.

General Intelligence

The ability to reason, plan, solve problems and understand how things relate and behave. A high score means it thinks hard problems through, from careful analysis to plans that span many steps.

Visual Intelligence

The ability to understand visual intent and turn ideas, descriptions and plans into coherent, effective visuals. A high score means design ideas come out the way you meant them, in illustrations, icons, diagrams or interface visuals.

Overall score

Overall shows how well a model’s abilities carry over to original, demanding tasks, weighting every benchmark into one score. Estimated means the total includes an estimate for one missing scene.

Judging

Scores reflect how well each result meets the benchmark requirements. Game scores come from the recorded play: the points earned on each level and how each level ended. How StealthMark keeps scores honest.

Games

Each game is a sequence of levels, and earlier moves carry into later levels. A level that was not played is shown as not played and never counts as zero. Play every level of Latch or Foresight yourself to get a score calculated like the models’.

Reasoning efficiency

Good results with little thinking score high. On each task, a model’s result and reasoning tokens are compared with every other model and combined with the Balanced Integration Score (Liesefeld & Janczyk, 2019); 50 is average. Single step shows how much reasoning a model needs to understand and solve one problem, multi-step how efficiently it keeps working on a task by building on its earlier reasoning, as in agentic workflows. Not part of StealthMark.

Cost efficiency

How much StealthMark a model delivers for its money, in StealthMark points per dollar: its overall score divided by what one benchmark task costs it on average. The cost is what our runs were charged, or their tokens at the model’s list price; benchmarks a model has not run yet are estimated from its other costs. Like StealthMark, it is absolute and compares with no other model. Not part of StealthMark.

BENCHMARK RESULTS

Compare results

This link opens the same results in the same order.

StealthMark benchmark results

Reset benchmark preferences?

Return to the default view, clear comparison selections and restore the advertisement.