stealthmodels.

MODEL BENCHMARKS

GPT-6.1 Terra

OpenAI's fast GPT-6.1 tier for visual reasoning, computer use and natural writing, at half of GPT-6.1 Sol's token rates with a million-token-class context.

BENCHMARK BY BENCHMARK

GPT-6.1 Terra benchmark scores

StealthMark
60.4/100Overall rank 9/54
General Intelligence
58.0/100
Visual Intelligence
64.9/100

GPT-6.1 TerraOther modelsMedian

Reasoning efficiency

On every task, result quality and reasoning tokens are each compared with all measured models and weighed equally. Each dot is one model.

Single-step reasoningResult quality weighed against reasoning tokens on a single problemRank 13/52
Multi-step reasoningResult quality weighed against reasoning tokens across connected steps, as in agentic workflowsRank 1/50

DATASHEET

GPT-6.1 Terra specs and pricing

A good fit forHigh-volume everyday work, screen understanding and computer-use agents where speed and token cost matter more than the deepest coding or research.

GPT-6.1 TerraOther modelsMedian

PriceDeveloper API, input / output per 1M tokens
$1 / $5Cheaper than 15 of 44 others
Context windowTokens in one request
1,050,000Joint largest with 21 others
Developer
OpenAI
Released
26 Oct 2026
Family
GPT-6
Open model
No
Local model
No
Origin
United States
Parameters
Not disclosed
Max output
128,000 tokens
Input → output
Text, image → text
API model ID
gpt-6.1-terra
All prices and providers

OpenAI API; input 1 USD/1M; cached read 0.05/1M; output 5/1M

  • OpenAI APIObserved 2026-10-27
    Input $1Output $5Cached read $0.05Cached write $1.25Batch input $0.5Batch output $2.5

    per 1M tokens

    Available

    gpt-6.1-terra
Measurements and sources8

GAME BENCHMARKS

Watch GPT-6.1 Terra play

Foresight

Anticipating threats and planning ahead

62.0/100Rank 9/50
Survived 2 of 3
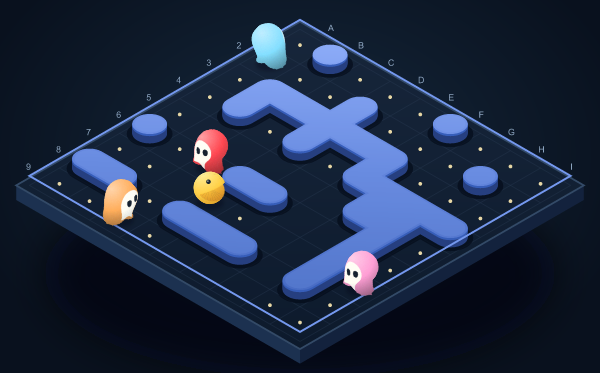
Foresight: complete playing field
Level 315 ptsTurn 20 / 20

Points per level

  1. Level 1Second Thoughts21 ptsBest 27Survived
  2. Level 2Pressure Pot9 ptsBest 13Out of lives
  3. Level 3Hide or Flight15 ptsBest 19Survived

Collect coins while avoiding ghosts. Ghosts move before the player each turn, and collisions cost a life. 3 levels in sequence, up to 66 turns in total. Earlier moves and outcomes carry forward, testing learning across levels.

Latch

Cooperative planning and learning from experience

77.7/100Rank 12/51
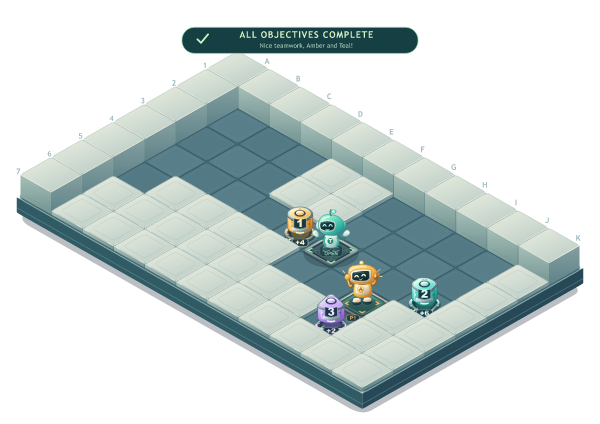
Cleared 5 of 5
Latch: complete playing field
Level 520.6 ptsTurn 27 / 40

Points per level

  1. Level 1Hold the door5.2 ptsBest 5.2Cleared
  2. Level 2Crossfeed9.8 ptsBest 10.2Cleared
  3. Level 3Relay vault19.2 ptsBest 19.2Cleared
  4. Level 4Passing bay17.8 ptsBest 18.2ClearedFinished early · 3 beacons left
  5. Level 5Second thoughts20.6 ptsBest 20.6Cleared

Coordinate two robots to push numbered cores onto matching sockets. Pressure plates hold doors open; moving either robot uses one turn. 5 levels in sequence, up to 152 turns in total. Earlier moves and outcomes carry forward, testing learning across levels.

GPT-6.1 Terra benchmark results ↗

StealthMark score

StealthMark measures how well a model’s abilities carry over to original, demanding tasks it could not have trained for: physical and spatial reasoning, planning across many steps, and precise visual work. How StealthMark works explains every benchmark, what it tests and why it is hard.

General Intelligence

The ability to reason, plan, solve problems and understand how things relate and behave. A high score means it thinks hard problems through, from careful analysis to plans that span many steps.

Visual Intelligence

The ability to understand visual intent and turn ideas, descriptions and plans into coherent, effective visuals. A high score means design ideas come out the way you meant them, in illustrations, icons, diagrams or interface visuals.

Overall score

Overall shows how well a model’s abilities carry over to original, demanding tasks, weighting every benchmark into one score from 0 to 100. Estimated means the total includes an estimate for one missing scene.

Judging

Scores reflect how well each result meets the benchmark requirements. Game scores come from the recorded play: the points earned on each level and how each level ended. How StealthMark keeps scores honest.

Games

Each game is a sequence of levels, and earlier moves carry into later levels. A level that was not played is shown as not played and never counts as zero. Play every level of Latch or Foresight yourself to get a score calculated like the models’.

Reasoning efficiency

Good results with little thinking score high. On each task, a model’s result and reasoning tokens are compared with every other model and combined with the Balanced Integration Score (Liesefeld & Janczyk, 2019); 50 is average. Single step shows how much reasoning a model needs to understand and solve one problem, multi-step how efficiently it keeps working on a task by building on its earlier reasoning, as in agentic workflows. Not part of StealthMark.

BENCHMARK RESULTS

Compare results

This link opens the same results in the same order.

StealthMark benchmark results

Reset benchmark preferences?

Return to the default view, clear comparison selections and restore the advertisement.