SelfieVisual construction
and creative interpretation
Benchmark task
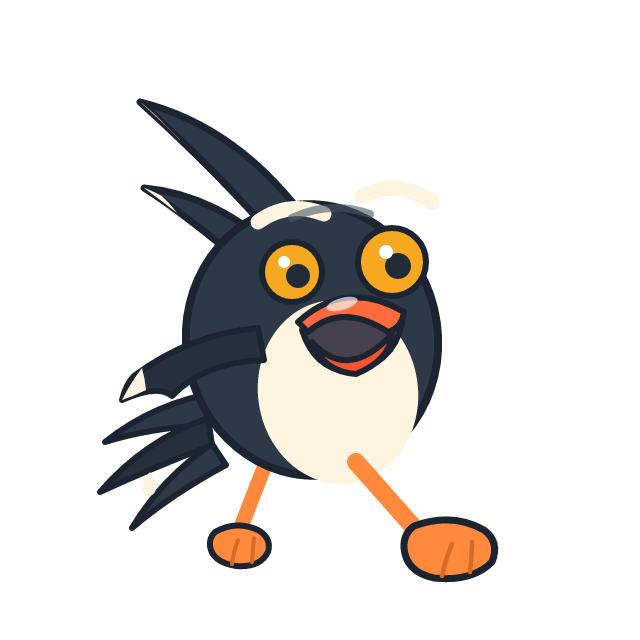
An eager young seabird running toward the viewer tests expressive anatomy, balance and a convincing forward-moving pose.
First run
 stealthmodels.
MODEL BENCHMARKS
Explore Fledge Alpha’s StealthMark scores, benchmark results and researcher observations. Read the Fledge Alpha model guide →
BENCHMARK BY BENCHMARK
Fledge AlphaOther modelsMedian
 Newton's Mirror Physical, spatial and recursive reasoning Selfie Visual construction and creative interpretation
 Mona Lisa Precise visual recall and portrait reconstruction
 Beach Creativity, perspective and visual beauty
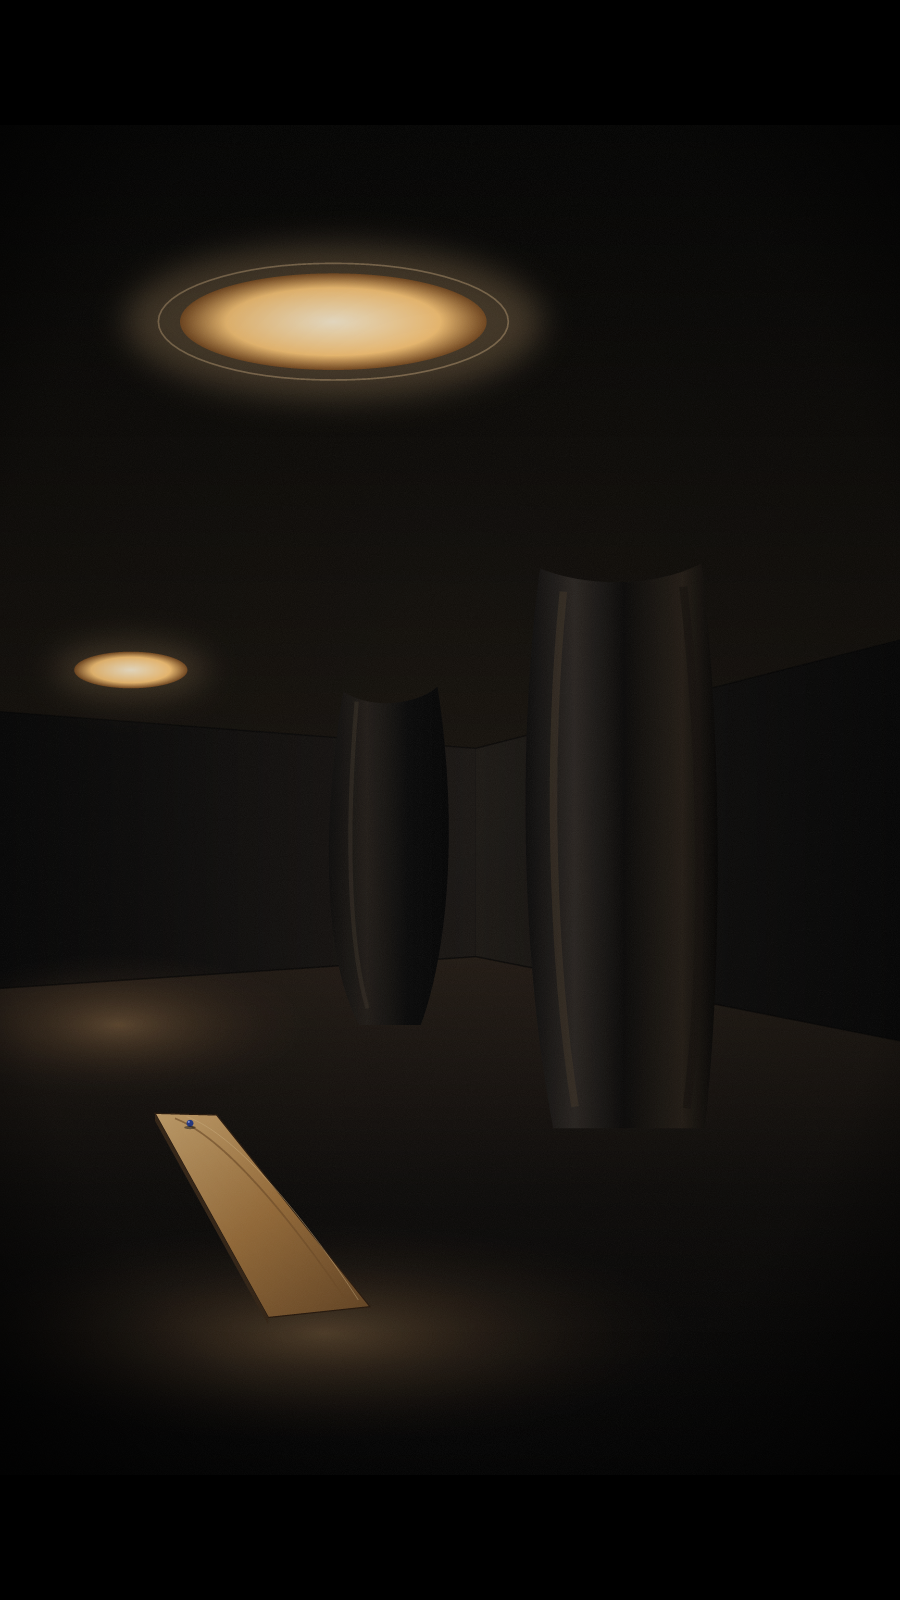 Ground Truth Physical reasoning, light and visual reconstruction
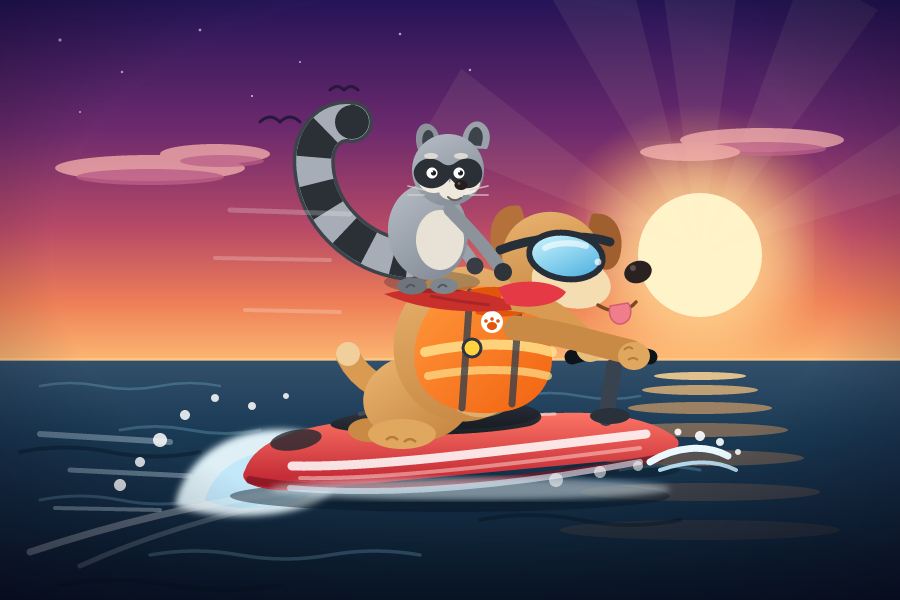 RaccoonBest placing Scene composition and interacting subjects
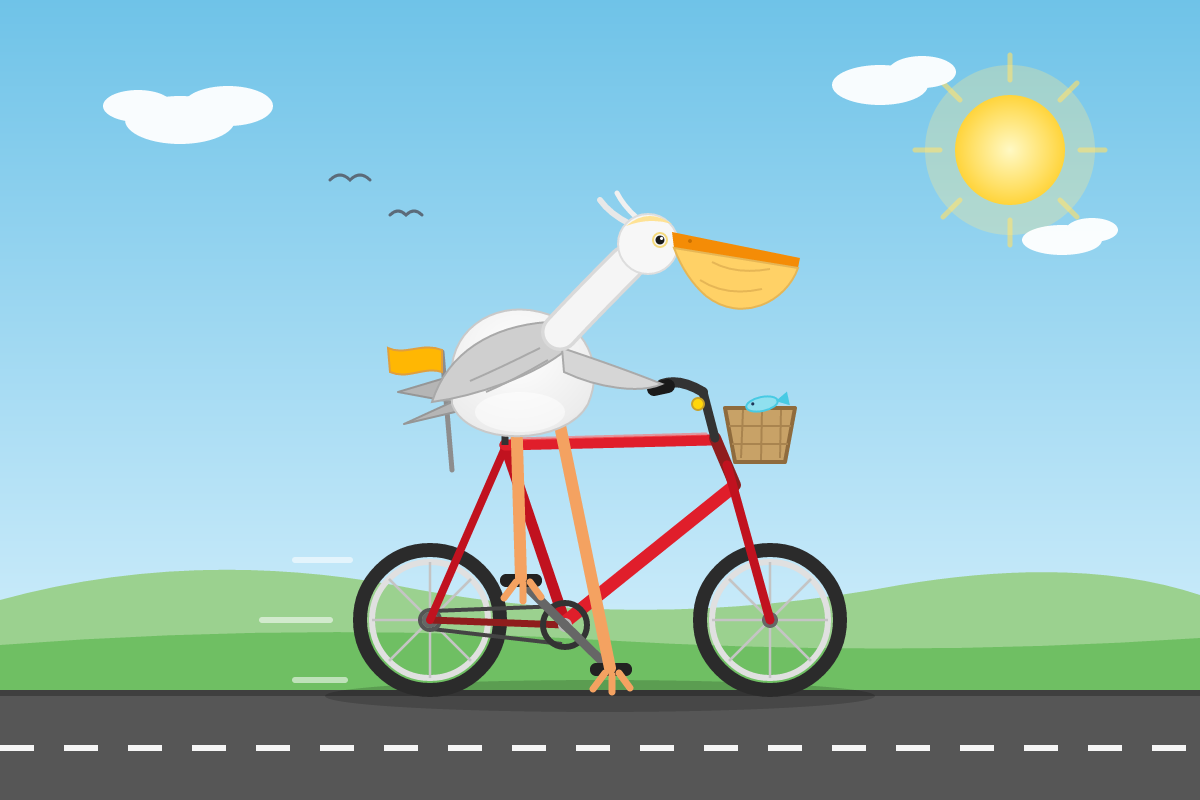 Pelican Subject construction and spatial relationships
How many reasoning tokens a model needs for the quality it delivers.
DATASHEET
Fledge AlphaOther modelsMedian
COMPARE HEAD TO HEAD
Benchmark results
Model IDopencode/fledge-alpha-free
 StealthMark#45of 58General27.1Visual45.2
An eager young seabird running toward the viewer tests expressive anatomy, balance and a convincing forward-moving pose.
First run
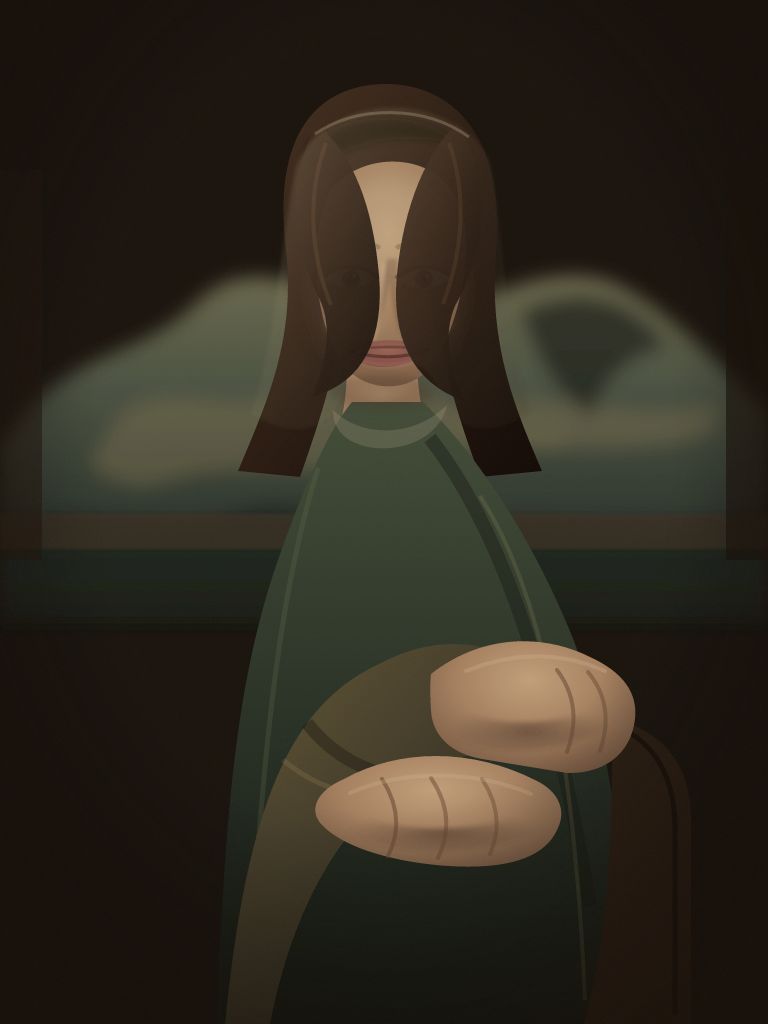
An SVG interpretation of the Mona Lisa tests facial likeness, anatomy and the composition of a familiar portrait.
First run
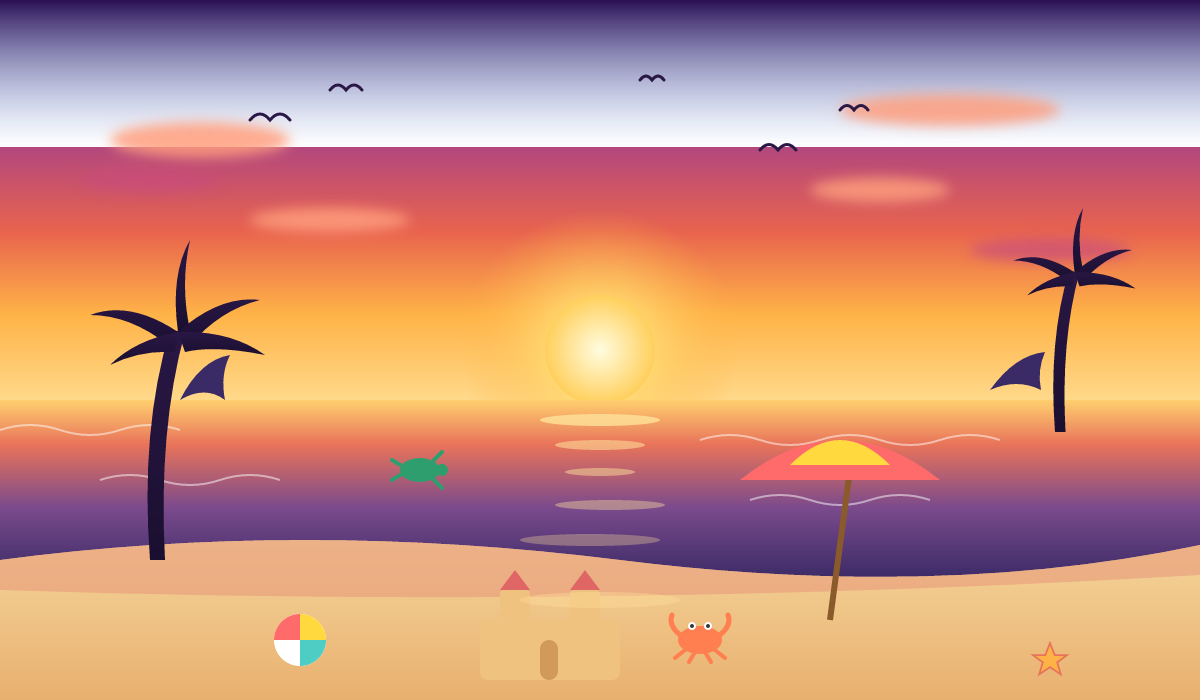
A busy shoreline at sunset tests scene composition, animal forms and the relationship between light and water reflections.
First run
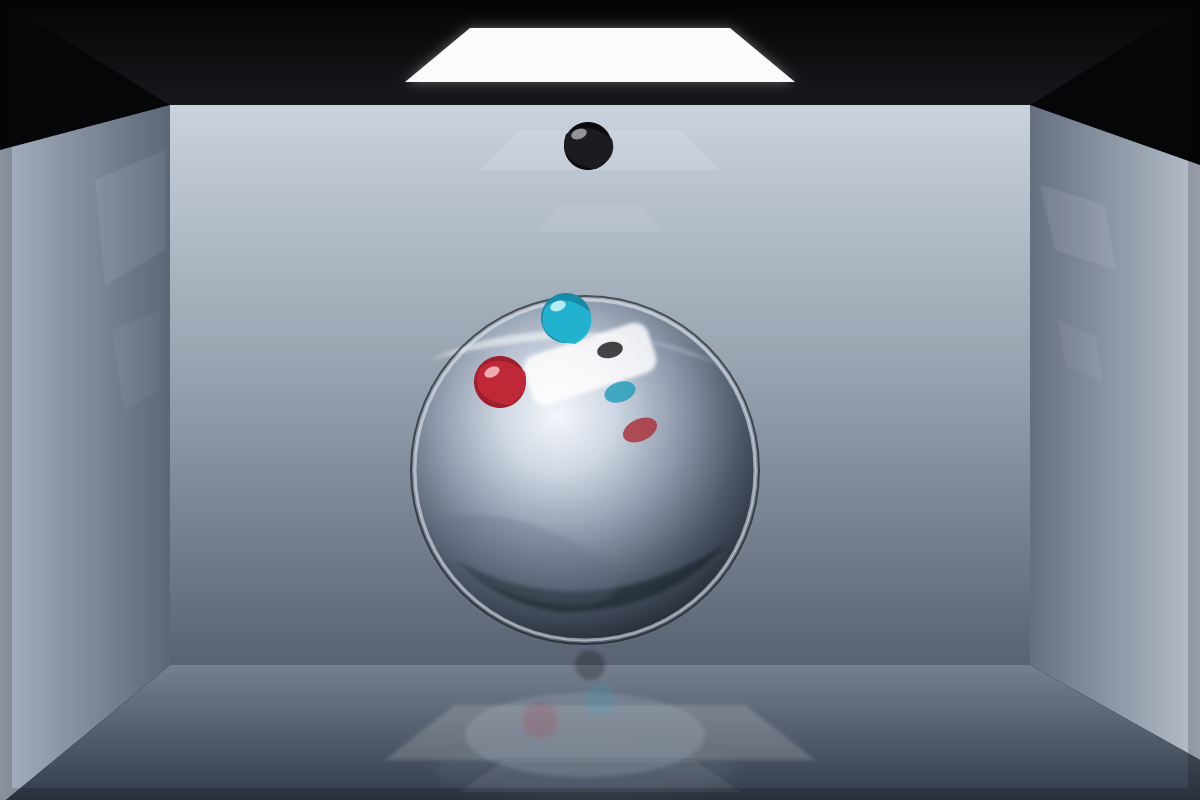
A spinning metal sphere and paint in a mirrored room test physical reasoning, perspective and consistency across repeated reflections.
First run
A plank, computer mouse and blueberry in a steel room test physical stability, spatial relationships, materials and lighting.
First run
A jet-ski scene pairs a canine driver with a raccoon passenger. It tests the placement and contact of interacting subjects, along with vehicle construction.
First run
A cycling pelican tests anatomy, riding posture and contact between the bird and the bicycle.
First run
Try another task or widen your model selection.
StealthMark scoreStealthMark measures how well a model’s abilities carry over to original, demanding tasks it could not have trained for: physical and spatial reasoning, planning across many steps, and precise visual work. How StealthMark works explains every benchmark, what it tests and why it is hard.
The ability to reason, plan, solve problems and understand how things relate and behave. A high score means it thinks hard problems through, from careful analysis to plans that span many steps.
The ability to understand visual intent and turn ideas, descriptions and plans into coherent, effective visuals. A high score means design ideas come out the way you meant them, in illustrations, icons, diagrams or interface visuals.
Overall shows how well a model’s abilities carry over to original, demanding tasks, weighting every benchmark into one score. Estimated means the total includes an estimate for one missing scene.
Scores reflect how well each result meets the benchmark requirements. Game scores come from the recorded play: the points earned on each level and how each level ended. How StealthMark keeps scores honest.
Each game is a sequence of levels, and earlier moves carry into later levels. A level that was not played is shown as not played and never counts as zero. Play every level of Latch or Foresight yourself to get a score calculated like the models’.
Good results with little thinking score high. On each task, a model’s result and reasoning tokens are compared with every other model and combined with the Balanced Integration Score (Liesefeld & Janczyk, 2019); 50 is average. Single step shows how much reasoning a model needs to understand and solve one problem, multi-step how efficiently it keeps working on a task by building on its earlier reasoning, as in agentic workflows. Not part of StealthMark.
How much StealthMark a model delivers for its money, in StealthMark points per dollar: its overall score divided by what one benchmark task costs it on average. The cost is what our runs were charged, or their tokens at the model’s list price; benchmarks a model has not run yet are estimated from its other costs. Like StealthMark, it is absolute and compares with no other model. Not part of StealthMark.